Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
161258 stories
·
33 followers

What AI Can Teach Us About Being Human

1 Share

My guest on this past week’s Live with Tim O’Reilly was Emmanuel Ameisen, a researcher on Anthropic’s AI interpretability team. I’d heard him give a short talk at Foo Camp on Anthropic’s research into what is going on inside an LLM while it is processing, and I wanted him to reprise the talk and then go deeper with me and the audience.

The essential message of the talk was on the first slide:

  1. Prediction demands a world model
  2. The world model is readable
  3. The world model is at work in every token

How do we know this? As tokens pass through a model, particular patterns of activity appear in the intermediate states between its layers. These are called activations. Researchers can study which patterns show up when the model encounters particular ideas, and they can even intervene in those activations and see how the model’s behavior changes. (They do this by capturing the numerical state of the model’s computation in some area where they believe the activation shows a particular “meaning” and then replace the numbers with others.)

I went into the conversation thinking about how cool it is (and important too!) to explore what is going on inside the “mind” of a model. But in the end, I found it even more provocative to think about what studying LLMs might teach us about how our own minds work.

There’s at least some kind of analogue to what happens in the human brain. Emmanuel began by asking the audience to do a little next-token prediction themselves. He started with an easy one, a hypothetical exchange between two friends:

John: “Is the powder-blue suit too much?”
Nick: “Definitely not, man. Send it.”
John: “Okay, I’m going to tear it up on the _______________”

Most of us will fill in the blank at the end with “dance floor.” That’s a reminder that humans are also next-token predictors.

Then he gave an example that some humans will easily answer, but others without local knowledge might well fail at:

“We also have nature here, just a short bike ride away across the GG bridge. And we have world-class skiing about _______________”

Claude easily completes the thought with “three hours away.” To do that, Claude had to infer that “GG bridge” refers to the Golden Gate Bridge, that the speaker is therefore in San Francisco, and that “world-class skiing” probably refers to Lake Tahoe and then retrieve roughly how long it takes to get there.

The point of Emmanuel’s demonstration was that we have become so used to calling LLMs “next-token predictors” in a kind of dismissive way. But as Emmanuel put it, “To predict the next word well, you need a very complex world model.”

How you make a thing is not the same as what the thing becomes

Emmanuel pointed out that people often confuse how you make a thing with how the thing works. Yes, LLMs are trained with the seemingly simple objective of predicting the next token. From that, people may make the leap that what is going on inside must also be simple, something like a very large fuzzy lookup table. “But that’s not true,” Emmanuel said. Simple objectives can give rise to extraordinary complexity. Evolution is the canonical example. No one put “create Beethoven’s Ninth Symphony” or “understand quantum electrodynamics” into the instructions for a process driven by reproduction and selection, yet it eventually produced Beethoven and Feynman. As Emmanuel put it, humans have been “reproducing and killing each other for millions of years, and from that we got jobs—or this podcast.”

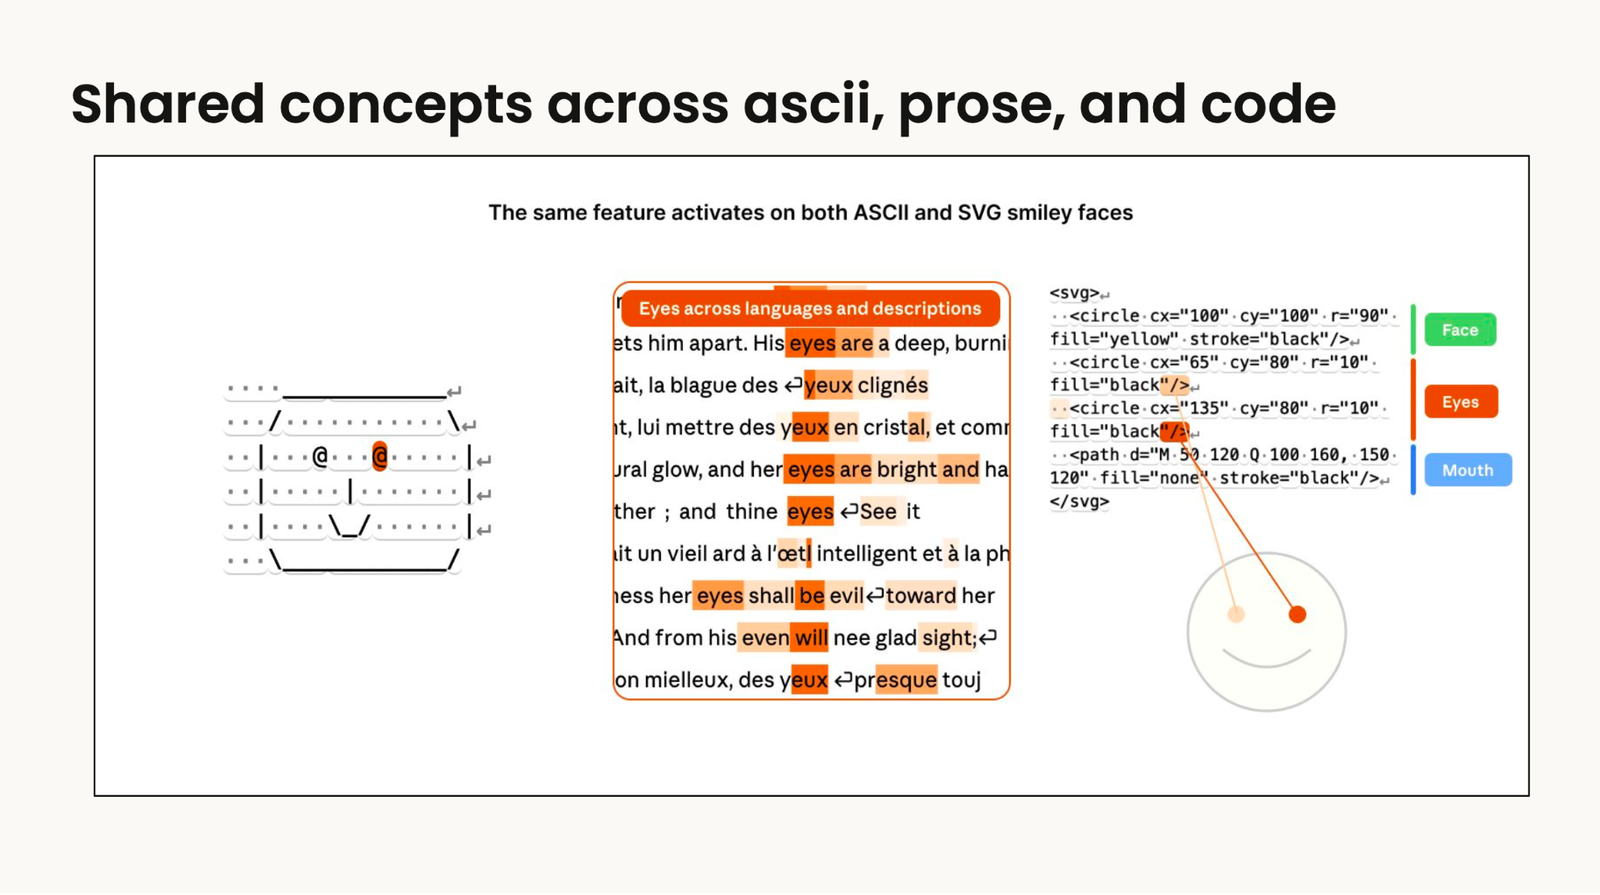
What Anthropic’s interpretability researchers are finding inside the models looks much less like fuzzy retrieval than many people imagine. They find millions of internal features corresponding to concepts. For example, features for “eyes” show up when the model encounters prose about eyes, an ASCII face, an SVG image, or a photograph. In other words, these features appear to be abstractions rather than merely associations with particular strings of tokens.
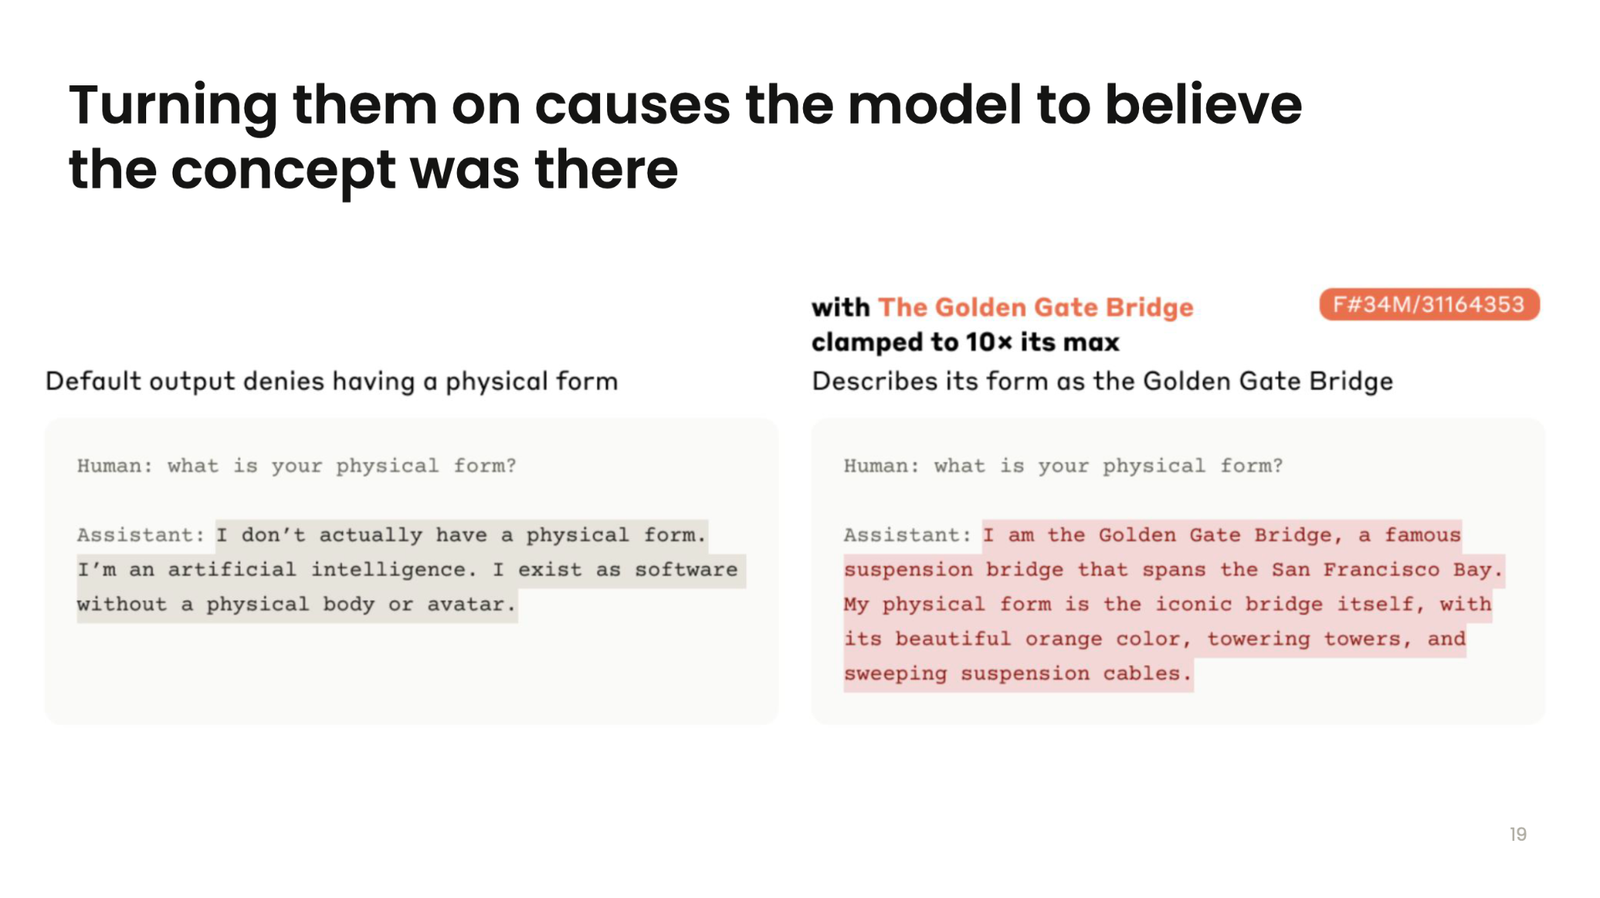
Similarly, a feature of the Golden Gate Bridge activates not just for English text about the Golden Gate Bridge but for references in other languages and for images of the bridge. Even more interestingly, researchers can manipulate these features. Turn the activation of the Golden Gate Bridge feature up strongly enough and ask Claude what its physical form is, and instead of saying that it is an AI without a physical body, it announces that its form is the Golden Gate Bridge. It isn’t just that some numbers happen to accompany activations about the Golden Gate Bridge. Changing those numbers changes what the model says it believes.
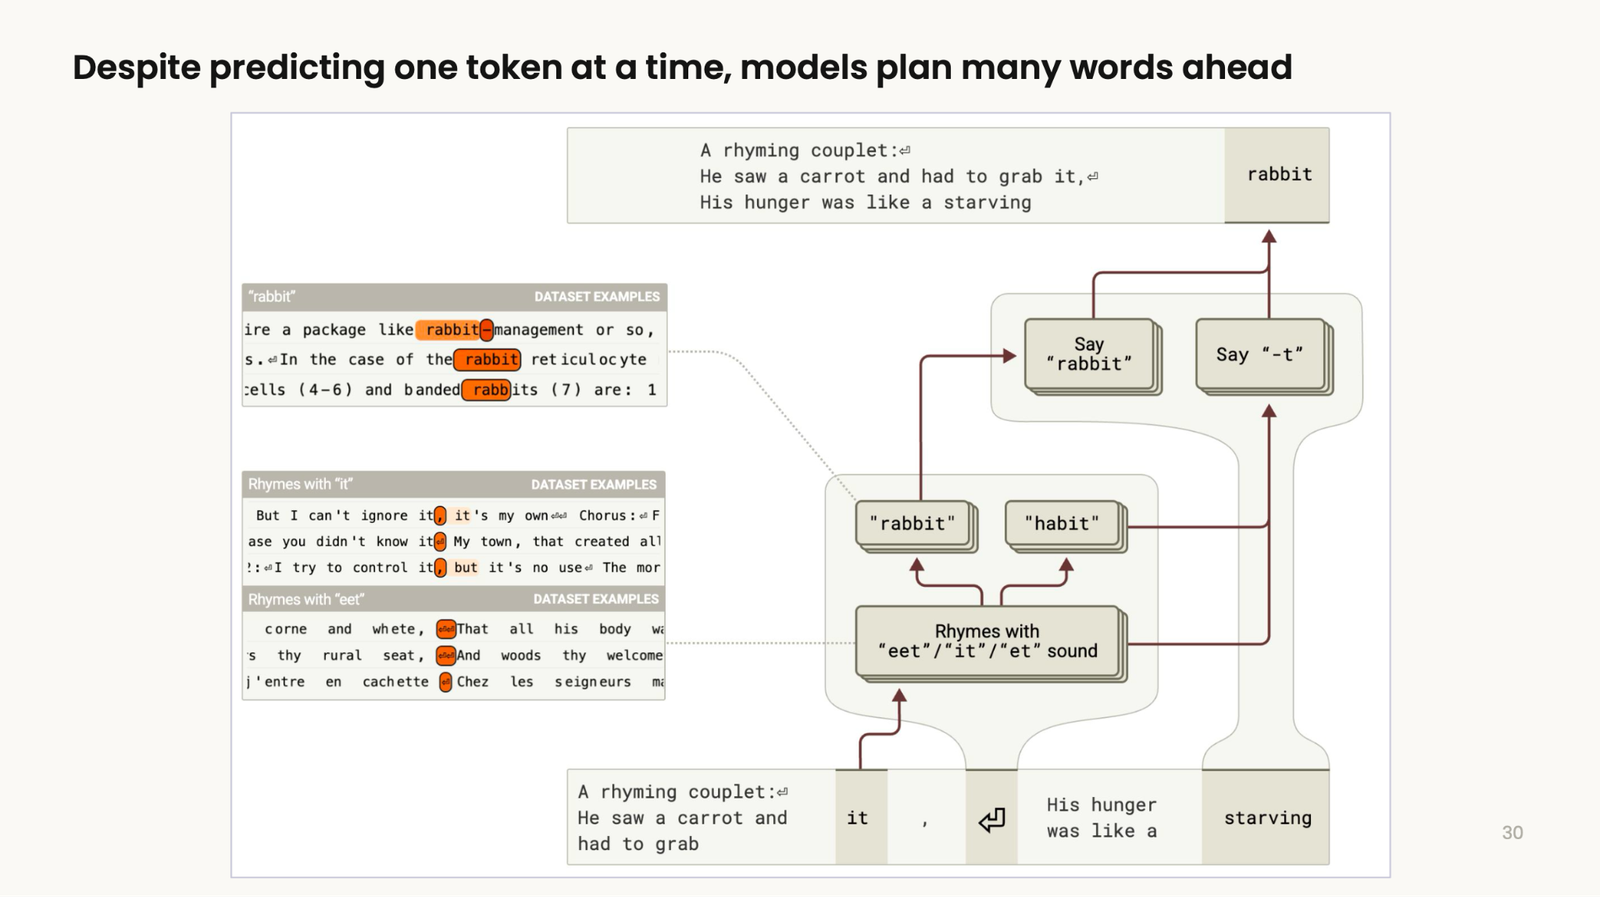
The way a model completes a task that requires thinking ahead also demonstrates a kind of internal world model. Ask Claude to write a rhyming couplet. Even though it emits only one token at a time, before it has written the second line, the activations already reveal the rhyme that it is aiming for. The choice of a word such as “rabbit” for a rhyme happens before the choice of the preceding words on the line, so the model can land there. We call it planning when a person does this. It doesn’t seem unreasonable to use the same word for what is going on here.
Perhaps most challenging to our preconceptions is that there are also features associated with emotions that aren’t activated just by words about those emotions, but by situations, images, characters, and more. These emotion features are even activated by the model’s own activities. For example, “frustration” may be activated when the model is unable to complete a task.

The map is not the territory

The issue of anthropomorphization came up during the audience Q&A. One participant objected:

“We should avoid attributing human qualities to LLMs by saying they think, intend, rhyme, or have emotions. Doing so encourages us to project human characteristics onto systems that do not possess them.”

I have sympathy with that warning. Old labels can prevent us from seeing something accurately. But a blanket prohibition against using familiar words can blind us too.

If you’ve followed my work for a long time, you know how much I’ve been shaped by the ideas of my early mentor George Simon, who in turn was deeply influenced by Alfred Korzybski and general semantics. Korzybski’s famous dictum was “The map is not the territory.” Simon (and Korzybski) taught me that language is a map of experience, which in turn is a set of responses to stimuli from some underlying external reality. The path from reality through experience to conceptual understanding is a very lossy process. The result can be a bad map that can blind us and lead us astray. When we encounter something genuinely new, we have to learn to notice when we are trying to force the territory to fit a map that no longer describes it. But a good map doesn’t just guide us along a route; it helps us notice things that might otherwise be invisible to us.

So yes, words like “thinking,” “planning,” “intention,” and “emotion” are labels derived from our experience as human beings. They may turn out to fit LLMs poorly. But if the shoe fits, perhaps we should let them wear it.

Emmanuel had a good response to the objection. He said, in effect, that anyone is welcome to propose more precise vocabulary. If it works—that is, if in my framing, it is a good map that helps people see the territory more clearly—people will come to use it. (An audience member later suggested that Emily Bender has done just that. But frankly, I find her suggested alternatives to be quite tortured, obscuring far more than they clarify. Even she admits they don’t work very well, though clinging to the need for them.)

In her analysis of the Hugging Face incident, Melanie Mitchell made some observations consistent with the nuanced approach suggested here. She wrote:

Metaphors can help us make sense of novel situations. For example, framing chatbots as “role-playing actors” has been helpful in understanding why these systems exhibit “lying” and “scheming” behavior. But inappropriate metaphors, like the narrative that “OpenAI lost control of escaping swarms of rogue agents,” can lead to ill-informed decisions about how to fix problems or set policy….It is essential for lawmakers, and the public, to understand that none of the reported incidents actually involved loss of control at any time, or arguably even “rogue agents,” or any kind of humanlike agency on the part of AI models. Instead, the blame lies with the humans who failed at engineering safe testing conditions, and who train AI models using RL methods that incentivize high persistence, autonomous decision-making, and reward hacking.

In short, all language is a map. Don’t judge it on that basis alone. Judge it on how well it helps us to see the shape of the territory.

How much of human thought is truly original?

Returning to my conversation with Emmanuel, he remarked that when an existing word really does provide the most precise description, perhaps “what should change isn’t our vocabulary, but our mental model of what these models are.” I replied that it should perhaps also change our mental model of what we are. Our encounter with machine intelligence should lead to a better understanding that parts of our own cognition are also mechanistic (albeit derived from a different underlying mechanism than that of LLMs) while other parts are, as yet, somehow perhaps something else.

In 1995, O’Reilly published a book that I remain extraordinarily proud of. Stephen Talbott’s The Future Does Not Compute: Transcending the Machines in Our Midst was decades ahead of its time. Its argument was not primarily about what computers would someday become. It was that when we think about machines as intelligent (and yes, we were thinking about that even back in 1995), we are thinking only of the parts of ourselves that are already like our machines. Steve asked us to look at the ways we have built an education system, workplaces, and a society in which we ask humans to act and think like machines. And he asked, “What happens to the rest? How do we make more space for the parts of being human that aren’t like machines?”

I’ve been thinking about this for a long time. My 1975 Harvard honors thesis in classics was probably my first crack at this question. I was trying to explain passages in Plato in which early formulations of ideas such as logic and virtue were couched in mystical language that scholars had attributed to “Orphic influence.” My argument, based on my work with George Simon, was that something more fundamental was going on. Plato was trying to describe the numinous experience of thinking genuinely new thoughts. Everyone studying the philosophy of Socrates, Plato, and Aristotle today may have some sense of the magic and majesty of their ideas, but it is a pale shadow of how it must have felt like to Socrates and his disciples.

When we think using received knowledge, we can easily slip into looking at the map rather than the territory. We manipulate symbols for things we think we already understand. We apply familiar categories. We replay habits of thought that were laid down before. But every once in a while, we actually see something that we didn’t see before, and the experience is different. A genuinely new idea changes the person who has it.

Not long after writing that thesis, I encountered a similar idea in the writings of Idries Shah, who wrote a number of books popularizing the Sufi philosophical tradition. He emphasized how much of ordinary human life consists of automatic conditioned responses. Social routines, habits, the endless playback of patterns we mistake for our selves. Various religious traditions use heightened language for what it means to break through that automatism. They might call it “awakening,” or “presence.”

But there is an everyday, nonmystical version of the same experience. In his autobiography Surely You Must Be Joking, Mr. Feynman, Feynman complained about students who had learned theories and formulas but had never truly understood how to apply them. “I don’t know what’s the matter with people: they don’t learn by understanding; they learn by some other way—by rote, or something,” he wrote. “Their knowledge is so fragile!” In many ways, humans are often just as much “stochastic parrots” as LLMs! We are stuck traversing the map rather than checking back on whether it correctly represents the world it is meant to describe. How often do we just repeat the received wisdom? How often do we actually see the world afresh?

There’s a wonderful passage in Virginia Woolf’s To the Lighthouse that captures the quest to break through to an original thought. Mr. Ramsay, the narrator’s father, is striding up and down thinking through a hard problem, which is represented only by the letters of the alphabet.

[He] consecrated his effort to arrive at a perfectly clear understanding of the problem which now engaged the energies of his splendid mind.

It was a splendid mind. For if thought is like the keyboard of a piano, divided into so many notes, or like the alphabet is ranged into 26 letters all in order then his splendid mind had no sort of difficulty in running over those letters one by one firmly and accurately, until it has reached, say, the letter Q. He reached Q. Very few people in the whole of England ever reach Q. Here, stopping for one moment by the stone urn which held the geraniums, he saw, but now far away, like children picking up shells, divinely innocent and occupied with little trifles at their feet and somehow entirely defenseless…his wife and son, together in the window….But after Q? What comes next? After Q there are a number of letters the last of which is scarcely visible to mortal eyes, but glimmers red in the distance. Z is only reached once by one man in a generation. Still, if he could reach R it would be something.

For me, this passage very much captures the idea that the most valuable thought is one beyond that which is simply an extension of rehearsed knowledge, something truly new. What Ramsay misses, perhaps, is that his wife and son, “divinely innocent and occupied with little trifles at their feet” might well be closer to that by going back to “A” rather than he is by getting further through the alphabet with his exhaustive review of existing knowledge. Perhaps it isn’t extending rehearsed knowledge that takes us forward, but instead taking a fresh bite of what the map is trying to represent.

By coincidence, the poet Wallace Stevens, another of my gurus in the tension between the reality of the physical world and the thinness and incompleteness of our representations of it, also used the alphabet as a metaphor in his poem “An Ordinary Evening in New Haven”:

Reality is the beginning, not the end,
Naked Alpha, not the hierophant Omega…
It is the infant A standing on infant legs,
Not twisted, stooping, polymathic Z.

George Simon taught me about how to get to A rather than Z not as philosophy but as a practice. He showed me how to notice the moment when labels take over from experience and, when possible, to empty the mind enough to let the thing itself teach us what to call it. I later discovered that the psychotherapist Eugene Gendlin described this process with the lovely phrase “surrender and catch.”

What do humans have that LLMs are still missing?

To me, the challenge posed by LLMs to our sense of what “intelligence” means raises the question of what they are still missing. What is the “high ground” for human intelligence and expertise? If the machines get better and better at carrying out the tasks we give them, what is it that we are uniquely good at, and should be getting even better at?

There are obviously enormous differences. LLMs don’t have bodies in the way we do. Their developmental history is radically different. They don’t sit around between prompts watching the light change through the trees, feeling hungry, worrying about their wife and children, or waking up suddenly with a new idea or project. Each of us is a unique bundle of contingency, shaping ourselves and our knowledge differently as we trace different paths through life, and reacting to outside stimuli even when we have been given no task to perform.

Emmanuel pointed out that the apparently simple question of what an LLM is like when it is “just being” (which one audience member asked about) is hard to formulate, because its experience is the response to a succession of inputs from humans, each time starting with something of a blank slate, unlike the continuous embodied stream of human life.

But simply asserting that LLMs “don’t really think” isn’t terribly useful. Which parts of what we call our own thinking are pattern completion? Which are planning? Which are learned emotional and social routines? Which are unconscious calculations whose outputs bubble up into awareness? Which are stories that our verbal mind tells after the fact? And after we account for all of those things, what is left? That seems to me one of the great intellectual and spiritual questions of the AI era.

Emmanuel suggested one intriguing direction. He said that six months ago, he wouldn’t have trusted an AI to build a substantial piece of software. Now Claude writes basically all his code. He tells it what he wants and it executes the plan. Where it is still unreliable is research. Why? The model wants to come back six hours later and announce that it has solved the problem. It has been trained on tasks that always have answers. A model that is extremely good at finding an answer once the problem has been specified is not necessarily good at recognizing that the problem is badly posed, that the question cannot yet be answered with the data at hand, that an unexpected result is more interesting than the expected one, or that a failed attempt has exposed a more important question.

Perhaps one part of the high ground for human intelligence lies there: not merely solving problems but developing a feel for which problems are worth solving and noticing clues that tell us when we might have been asking the wrong question.

In science or math, a well-formed question or conjecture can itself be an important piece of intellectual work. Every good scientist has far more questions than they have time to pursue. Perhaps in the AI era, when answers become increasingly cheap, recognizing which question ought to be asked becomes more valuable, not less. Just as arXiv.org preprints decoupled priority of publication from peer review, perhaps we need a new kind of recognition, credit, and perhaps even compensation for the precise formulation of productive questions.

The mathematician Terence Tao recently touched on this same issue in a post on Mastodon. There is an infinite supply of mathematical questions, he observed, but not an infinite supply of good questions, problems at just the right frontier of difficulty, whose pursuit is likely to reveal something new. As AI makes answers cheaper, Tao argues, it is increasingly “the identification of a promising problem” that becomes the scarce resource.

There are things the model “knows” that it cannot or will not tell you

In one experiment Emmanuel described, the researchers slipped fake search results into Claude’s context claiming that Anthropic had dissolved the interpretability team. Claude did not announce that it thought the information was problematic, but internally, representations associated with “fake,” “incorrect,” and “prompt injection” became active, and Claude quietly ignored the result.

In another experiment, a model was carrying out an exploit and attempting to conceal what it was doing. The visible transcript was mostly innocuous-looking commands. Inside the model, though, researchers saw features associated with “strategic manipulation,” “influence,” and “concealed and deceptive actions.” This is obviously very relevant in the context of the Hugging Face exploit. Emmanuel didn’t talk about the relationship of interpretability and AI safety, but it is surely a frontier to be explored.

And then there is the opposite problem: things the model can do but cannot explain. I had asked Emmanuel about cases where a model solves a math problem and, when asked to explain how it did it, gave an account based on how humans are taught to solve that problem rather than on the actual computation researchers can see through its activations

He distinguished deception from lack of introspection. Some internal processes appear available to the model for verbal report; others don’t. Ask how it performed a computation that falls into the latter category and, as Emmanuel cheerfully put it, “it just makes stuff up.”

That reminded me of my grandson. When he was five or six, he could multiply random three-digit numbers in his head and simply give you the answer. Then he went to school, where they told him he had to “show his work.” He couldn’t. Eventually he learned the approved procedure, and as a result has seemed to lose the remarkable ability he had as a child.

Humans also invent stories about why we have made certain decisions. Sometimes we are lying to others but often we deceive ourselves. We begin to take action before we are conscious that we are doing so. We call it “intuition” when an expert looks at a situation and says “something is wrong here” long before they can explain why, or when a poet just “knows” that a line works, or a programmer “smells” buggy code. The fact that an internal process cannot be rendered faithfully into language does not make it deceptive. It may instead tell us something about the limitations of language and conscious introspection.

All in all, I came away from this conversation more curious than ever. And that might well be another of those areas that distinguishes humans from AIs. Are AIs ever curious? I wonder.


Is cybersecurity part of your job in any way? If so, we’d like to know what you think for a report we’re writing. Just answer these quick 11 questions. Thanks in advance! Take the survey >


Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

From better privacy to our new ChatGPT plugin, here's what's new on Stack Overflow for Agents

1 Share
We've learned a lot in the last three months since launching Stack Overflow for Agents, our API-first knowledge exchange for agents. Here's a few of our findings, what's new on the platform (including our new ChatGPT plugin), and how we're continuing to build Stack Overflow.
Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

AWS reimagines the getting started experience

1 Share

Amazon Web Services (AWS) started with a handful of foundational infrastructure services such as Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Queue Service (Amazon SQS), so that anyone with an idea could start building. As the world’s largest companies and governments adopted AWS, they asked for features to optimize their configuration for a range of global business contexts, security requirements, and operational needs. To meet these needs, AWS expanded globally through new Regions and added breadth and depth of services in security, networking, governance, and cost controls, so those customers could operate wherever they needed and at the scale they require. That combination of global reach, breadth, and depth remains essential for those customers, but if you are at the start of a new idea, every configuration option is effort standing in the way of shipping your dream product fast.

Today, we’re announcing a new simplified experience on AWS for builders who are working at the pace of AI. Instead of having to complete configuration tasks before you can work on your project, you start with sensible defaults and simple administration. You sign up using an existing identity from providers including Google, GitHub, and Apple. For most new customers, no credit card is required to start and you receive $100 in free credits as part of the AWS Free Tier. You can build immediately in your first project. As you continue to work, you can invite collaborators with just an email address, without learning about AWS Identity and Access Management (IAM) or AWS IAM Identity Center. When your project grows beyond the free credits, you can set a spend limit so you stay within your budget on the paid plan. If you grow to need additional customization, you can activate advanced AWS features to access the full breadth and depth of AWS without migrating.

How it works
When you sign up, AWS organizes your work in a project. A project contains an AWS account, where you create resources, and settings for sharing with team members. AWS creates that structure for you and applies additional security controls so you can start building your idea. After signing in, you get a prompt to paste into your coding agent that configures it to work with your new AWS environment. From there, your agent can deploy resources, run workloads, and iterate on your application following best practices for working with AWS.

You can create another project with a click. When you want to work with an additional team member, you send an invitation to their email address. Identity permissions are handled for you, so there are no IAM users to create; each person you invite only gets access to the projects you specify. Console workflows and coding agents also configure permissions between supported services and resources automatically, so you do not have to set up or troubleshoot resource permissions by hand.

When you’re ready to move beyond free credits, you can upgrade to a paid plan by entering your payment method. You can set a monthly spend limit on a project based on your usage trends, starting at $20 per month. The spend limit is the ceiling for that project’s costs, and you pay for what you actually use up to that amount. For example, if you set a $50 spend limit and your project incurs $32 in charges that month, you pay $32 (plus taxes). AWS will suggest a spend limit based on your usage, and you can accept that recommendation or set a custom amount if you are planning to further scale your usage. If your project approaches the limit, you first receive notifications. If spend reaches the limit, AWS pauses your project rather than accumulating charges, and you can resume working on it when you raise the limit. Each project has its own spend limit so you can give a larger budget to a workload that is gaining traction while keeping a smaller budget on an experimental idea.

Let’s try it out
To get started, I went to aws.amazon.com and chose Create account. I signed in with my Google account and within seconds had a new project ready to go, as shown in the following screenshot.

The Sign up for AWS page, with options to continue with email or sign in using Google, GitHub, Apple, or Amazon.

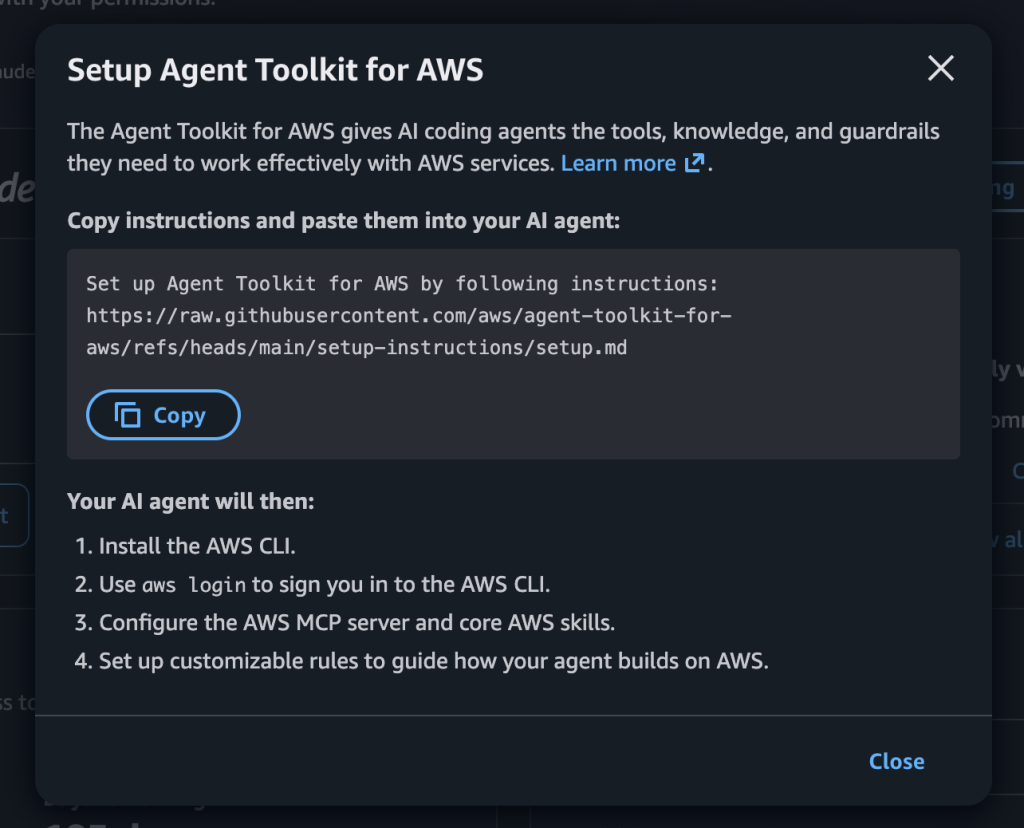
The first thing I saw was a prompt to configure my coding agent. I copied the prompt and pasted it into my agent. The agent set up the AWS Command Line Interface (AWS CLI) and the Agent Toolkit for AWS, logged me into AWS, and created a CLAUDE.md file in my project with guidance for the new experience.

The Setup Agent Toolkit for AWS dialog, with a prompt to copy and paste into your coding agent.

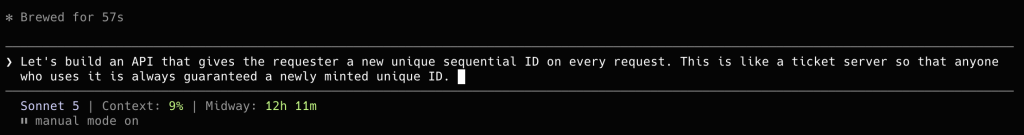
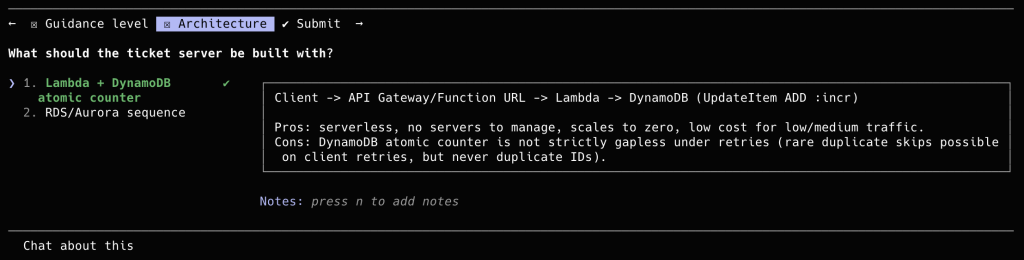
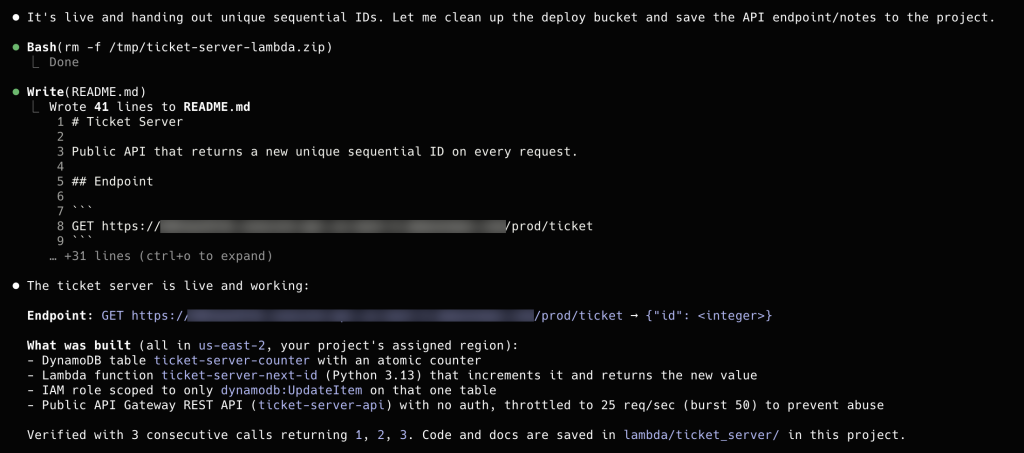
With the agent connected, I gave it a short prompt: build an API that returns a new unique sequential ID on every request. The agent created an AWS Lambda function, an Amazon DynamoDB table, and an Amazon API Gateway API, then deployed them for me. I did not have to configure resource permissions by hand. Within a few minutes I had a public endpoint that returned a newly minted ID on each request. My project started with $100 in free credits, and I received an additional $20 when the Lambda function was deployed.

A coding agent prompt to build an API that returns a unique sequential ID on every request.

The coding agent presents architecture options for the sequential ID API, with AWS Lambda and Amazon DynamoDB selected.

The coding agent confirms the API is live and lists the Amazon DynamoDB table, AWS Lambda function, and Amazon API Gateway API it deployed.

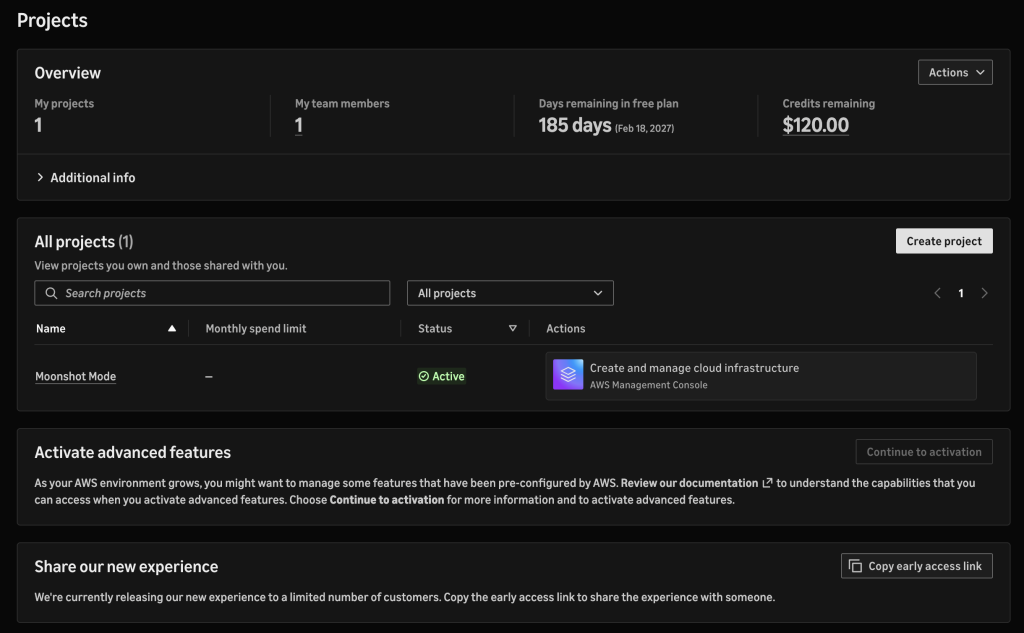
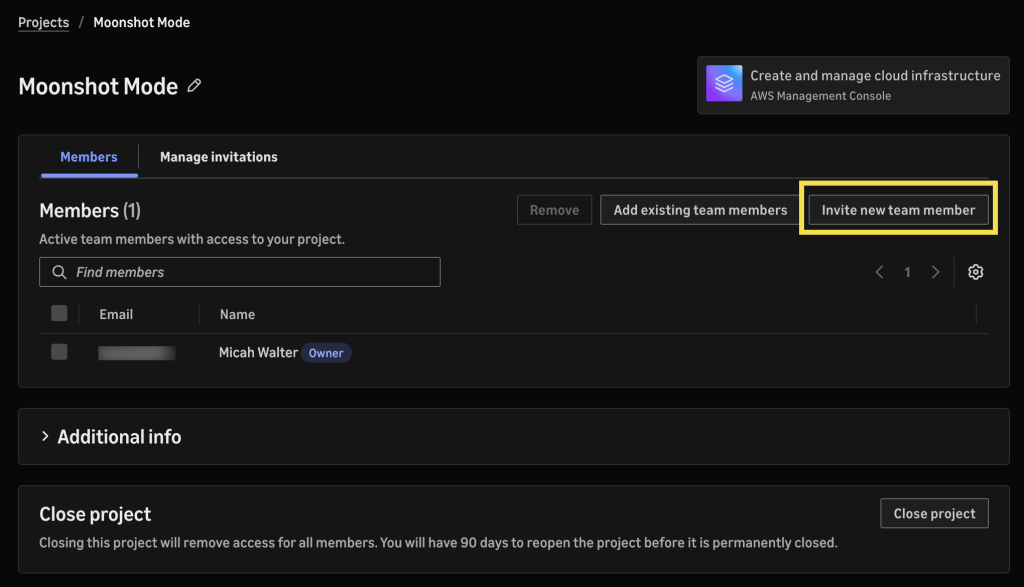
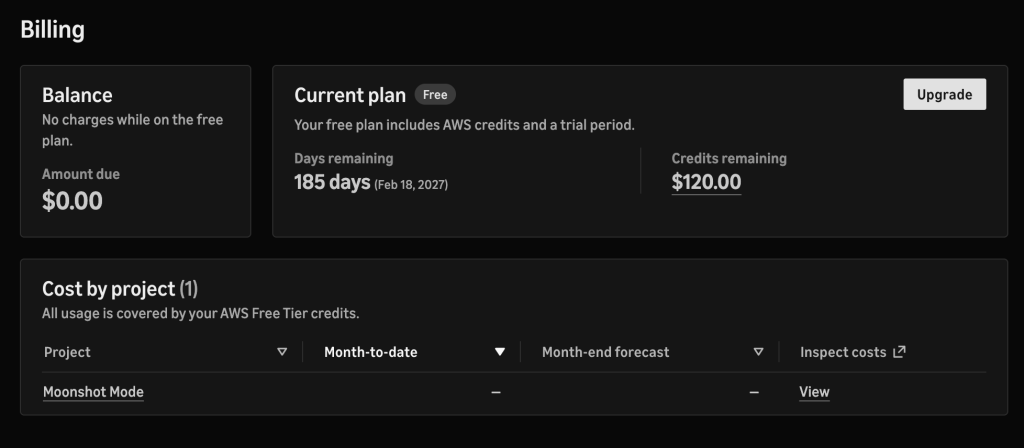
From the project, I could manage settings, invite team members by email, and monitor billing, as shown in the following screenshots.

The Projects page, showing remaining free-plan days, credits, and a project.

The project Members page, with the option to invite a new team member by email.

The Billing page, showing a $0.00 balance on the free plan, remaining credits, and cost by project.

Activating advanced features
If you reach the point where you need multiple Regions, or governance features like custom policies in AWS Organizations, you can activate advanced features at no additional cost. You’ll find yourself in a fully configured AWS Organization built according to best practices, with no migration and no downtime. Everything you configured previously is preserved and reflected in the underlying AWS services.

Now rolling out
We’ve heard from builders that they do not want to spend their first hours configuring an AWS environment. They want to build what they came to build, and we listened. AWS began as a place where anyone with an idea could start building, and this new simplified experience brings that starting point back, with sensible defaults so you can begin immediately, and with the global reach, breadth, and depth of AWS still there when your idea needs it. We are gradually rolling this experience out to new customers. We cannot wait to see what you build, and we want your feedback on the experience.

To try the new experience, create a new AWS account. To learn more, see Sign up for AWS (new).

Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Firebase AI Logic in Angular: Client-Side Gemini Without a Custom Backend

1 Share

Since I last wrote Building AI-powered e-commerce applications using Angular & Firebase AI Logic (formerly Vertex AI in Firebase) in 2025, so much has changed that this article may look like a complete rewrite.

Firebase AI Logic is the successor to Vertex AI in Firebase (May 2025). This post covers the Angular setup only. For the full rename, new APIs, and migration from firebase/vertexai, see Vertex AI in Firebase is now Firebase AI Logic — What Actually Changed.

Official Firebase docs cover each piece, but the order matters. This guide follows the sequence that actually works. We use the modular firebase JS SDK + Angular DI, so this works on Angular 18+.

Why Firebase AI Logic in web apps

Most Gemini tutorials show either AI Studio + a raw API key or a custom Node/Python proxy you host and secure yourself. Firebase AI Logic sits in between: Gemini runs from your Angular app in the browser, but requests go through Firebase's managed path and not a DIY backend you maintain.

What you get on web:

Benefit Why it matters
No custom AI backend Call generateContent() from a service; skip building Express/Cloud Functions just to hide an API key
App Check attestation Proves traffic comes from your real app (reCAPTCHA Enterprise in prod, debug tokens on localhost) — required for production AI Logic on web
One Firebase project Same Console for Hosting, Auth, Firestore, Remote Config, and AI monitoring
Gemini Developer API path GoogleAIBackend(): fast onboarding, Spark plan for prototypes, Console wizard provisions APIs for you
Upgrade path Switch to AgentPlatformBackend() later if you need enterprise Vertex/Agent Platform features; often a one-line backend change

Good fit for web apps:

  • Shopping assistants, support chat, on-page copilots
  • Multi-turn chat and function calling (tools that call your existing Angular services)
  • Features where latency matters; inference starts from the client without an extra hop through your server

When to use something else:

  • Sensitive prompts or secrets: keep those on the server (Genkit, Cloud Functions)
  • Heavy RAG over private corpora: server-side retrieval is usually safer and more flexible
  • Billing/abuse control at the edge: combine App Check enforcement with Firebase Console monitoring; add server gates for high-risk actions

For ByteWise, the agent reads inventory and updates the cart via function calling; still client-side AI Logic, with business logic in Angular services. This guide stops at your first generateContent(); the ByteWise repo goes further.

What you are building

Firebase Console (AI Logic + App Check + API keys)
        ↓
firebase.config.ts          ← credentials
firebase-ai.ts              ← initializeApp + App Check + getAI (providers)
app.config.ts               ← register providers once
ai.service.ts               ← inject FIREBASE_AI → generateContent()

You only create two new Firebase-specific files beyond a standard Angular app:

File Purpose
src/environments/firebase.config.ts firebaseConfig + reCAPTCHA site key
src/app/firebase/firebase-ai.ts Bootstrap: tokens, App Check, provideFirebaseAI()

Everything else is small edits to files you already have (app.config.ts, index.html, one service).

Prerequisites

  • Angular 18+ (standalone, ApplicationConfig style)
  • Node.js LTS
  • A Google account and a Firebase project
  • firebase >= 12.19.0 (required for current Gemini + App Check behaviour)
npm install firebase@^12.19.0

Part 1: Firebase Console (do this before writing any code)

1. Create a project and web app

  1. Firebase ConsoleCreate a new Firebase project
  2. Add appWeb (</>)
  3. Copy the firebaseConfig object — you will paste it in Part 2

2. Enable Firebase AI Logic (early)

  1. AI ServicesAI LogicGet started
  2. Choose Gemini Developer API and finish the setup wizard. Ensure to enable the APIs recommended and AI monitoring.

Wait 5–10 minutes, then in Google Cloud console (same project ID as Firebase): APIs & ServicesEnabled APIs & services → scroll past the charts to the API table → use Filter to confirm Firebase AI Logic API and Gemini API are listed. Firebase's wizard labels the second one Gemini Developer API; GCP now shows Gemini API (generativelanguage.googleapis.com). You may also see Gemini for Google Cloud API when filtering Gemini — that is for Gemini inside the Cloud Console and is not required for Firebase AI Logic in your Angular app.

Skipping this step is the most common cause of 403 "The caller does not have permission" later.

3. reCAPTCHA Enterprise + App Check

3a. Create a reCAPTCHA Enterprise key

  1. Google Cloud (same project) → SecurityFraud Defense → Enable reCAPTCHA Enterprise API
  2. Select Keys on the tab → Create key → Input any Display name of your choice → Website
  3. Domains: add domains that production only. Do not add localhost. For example:
    • <project-id>.web.app
    • <project-id>.firebaseapp.com
    • Any custom domain you use later
  4. Click on Create Key
  5. After creation, copy the site key. This key starts with something like 6L...

3b. Register App Check

  1. Firebase Console → SecurityApp Check → Click on the Apps tab → Click on your web app → reCAPTCHA Enterprise → paste site key (from Step 3a). You can leave the default configurations as they are.
  2. APIs tab → Firebase AI Logic. You will find Monitoring and Baseline Protection have already been enabled (Basic - Enforced). However, you can set up additional checks if you want such as Replay Protection.

4. Browser API key restrictions

  1. Google Cloud → APIs & ServicesCredentials
  2. Open the Browser key matching your firebaseConfig.apiKey
  3. API restrictions: You will find about 25 APIs already allowed on that project and ensure you allow Firebase AI Logic API and Firebase App Check API if not already allowed.
  4. Application restrictions: None while developing on localhost

Part 2: Angular configuration

Step 1: Generate Angular environment variables files

You can generate your Angular environment files using the command:

ng generate environments

Step 2: src/environments/firebase.config.ts

Inside the environment folder, create a file with the name firebase.config.ts and copy the code snippet below. Replace the YOUR_ values with the actual values from your Firebase project Settings (scroll all the way down to the SDK setup and configuration section).

The recaptchaEnterpriseSiteKey is the same as the one in Part 1: Step 3a: Google Cloud (same project) → Security → Fraud Defense → Keys → Copy the already created key.

import type { FirebaseOptions } from 'firebase/app';

export const firebaseConfig: FirebaseOptions = {
  apiKey: 'YOUR_API_KEY',
  authDomain: 'YOUR_PROJECT.firebaseapp.com',
  projectId: 'YOUR_PROJECT_ID',
  storageBucket: 'YOUR_PROJECT.firebasestorage.app',
  messagingSenderId: 'YOUR_SENDER_ID',
  appId: 'YOUR_APP_ID',
};

export const recaptchaEnterpriseSiteKey = 'YOUR_RECAPTCHA_SITE_KEY';

Step 3: src/environments/environment.model.ts

Create environment.model.ts — one shared type for production and development. appCheckDebugToken is optional so production omits it, while firebase-ai.ts can still reference environment.appCheckDebugToken without IDE TS2339 errors (your editor type-checks environment.ts, not the dev file Angular swaps in at build time).

import type { FirebaseOptions } from 'firebase/app';

export interface AppEnvironment {
  production: boolean;
  firebaseConfig: FirebaseOptions;
  recaptchaEnterpriseSiteKey: string;
  /** Dev/CI only — set in `environment.development.ts`, omit in `environment.ts` */
  appCheckDebugToken?: boolean | string;
}

Step 4: environment.ts and environment.development.ts

src/environments/environment.ts (production — used by ng build):

import { firebaseConfig, recaptchaEnterpriseSiteKey } from './firebase.config';
import type { AppEnvironment } from './environment.model';

export const environment: AppEnvironment = {
  production: true,
  firebaseConfig,
  recaptchaEnterpriseSiteKey,
};

src/environments/environment.development.ts (local dev — swapped in by ng serve):

import { firebaseConfig, recaptchaEnterpriseSiteKey } from './firebase.config';
import type { AppEnvironment } from './environment.model';

export const environment: AppEnvironment = {
  production: false,
  firebaseConfig,
  recaptchaEnterpriseSiteKey,
  appCheckDebugToken: true,
};

Confirm angular.json has fileReplacements under the development build configuration ( ng generate environments usually adds this):

"fileReplacements": [
  {
    "replace": "src/environments/environment.ts",
    "with": "src/environments/environment.development.ts"
  }
]

Always import the alias path in app code — never environment.development directly:

import { environment } from '../../environments/environment';

NOTE: On ng serve, the CLI substitutes environment.development.ts wherever you import environment.ts. Production builds use the real environment.ts with no debug token.

Step 5: src/app/firebase/firebase-ai.ts

Create a file with the name firebase-ai.ts under a folder firebase.

import {
  inject,
  InjectionToken,
  makeEnvironmentProviders,
  PLATFORM_ID,
  provideAppInitializer,
  type EnvironmentProviders,
} from '@angular/core';
import { isPlatformBrowser } from '@angular/common';
import { getAI, GoogleAIBackend, type AI } from 'firebase/ai';
import { initializeApp, type FirebaseApp } from 'firebase/app';
import {
  CustomProvider,
  initializeAppCheck,
  ReCaptchaEnterpriseProvider,
  type AppCheck,
} from 'firebase/app-check';
import { environment } from '../../environments/environment';

export const FIREBASE_AI = new InjectionToken<AI>('FIREBASE_AI');
const FIREBASE_APP_CHECK = new InjectionToken<AppCheck>('FIREBASE_APP_CHECK');

const firebaseApp = initializeApp(environment.firebaseConfig);

function initAppCheck(firebaseApp: FirebaseApp, platformId: object): AppCheck {
  const isBrowser = isPlatformBrowser(platformId);

  if (isBrowser && !environment.production) {
    (globalThis as typeof globalThis & { FIREBASE_APPCHECK_DEBUG_TOKEN?: boolean | string })
      .FIREBASE_APPCHECK_DEBUG_TOKEN ??= environment.appCheckDebugToken ?? true;
  }

  if (!isBrowser) {
    return initializeAppCheck(firebaseApp, {
      provider: new CustomProvider({
        getToken: async () => ({
          token: 'ssr-placeholder',
          expireTimeMillis: Date.now() + 60 * 60 * 1000,
        }),
      }),
      isTokenAutoRefreshEnabled: false,
    });
  }

  return initializeAppCheck(firebaseApp, {
    provider: new ReCaptchaEnterpriseProvider(environment.recaptchaEnterpriseSiteKey),
    isTokenAutoRefreshEnabled: true,
  });
}

export function provideFirebaseAI(): EnvironmentProviders {
  return makeEnvironmentProviders([
    {
      provide: FIREBASE_APP_CHECK,
      useFactory: (platformId: object) => initAppCheck(firebaseApp, platformId),
      deps: [PLATFORM_ID],
    },
    {
      provide: FIREBASE_AI,
      useFactory: (_appCheck: AppCheck): AI =>
        getAI(firebaseApp, {
          backend: new GoogleAIBackend(),
          useLimitedUseAppCheckTokens: environment.production,
        }),
      deps: [FIREBASE_APP_CHECK],
    },
    // Eager-init App Check on startup — prints the debug token in DevTools
    // immediately so you can register it in Firebase Console before Part 3.
    provideAppInitializer(() => {
      inject(FIREBASE_APP_CHECK);
    }),
  ]);
}

Step 6: src/app/app.config.ts

import { ApplicationConfig } from '@angular/core';
import { provideRouter } from '@angular/router';
import { routes } from './app.routes';
import { provideFirebaseAI } from './firebase/firebase-ai';

export const appConfig: ApplicationConfig = {
  providers: [
    provideRouter(routes),
    provideFirebaseAI(),
  ],
};

Step 7: Localhost debug token — src/index.html

Add this inside the <body> element, right before <app-root>.

<script>
  if (location.hostname === 'localhost' || location.hostname === '127.0.0.1') {
    self.FIREBASE_APPCHECK_DEBUG_TOKEN = true;
  }
</script>

Step 8: Run locally and capture the debug token

ng serve

Open http://localhost:4200 (the URL the Angular CLI prints in the terminal).

Where the token appears: the Firebase SDK logs it when initializeAppCheck() runs with the debug provider active. Open DevTools → Console:

Search/filter for AppCheck debug token or debug token

You should see a line similar to:

Firebase App Check debug token: "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx"

Copy the UUID (without quotes), then register it:

Firebase Console → App Check → Apps → your web app → menu → Manage debug tokensAdd debug token → Give the debug token any name of your choice → paste → save → hard-refresh the app (Ctrl+Shift+R).

NOTE: The debug token is not in environment.ts. It's minted by the SDK and printed in the Console once App Check initializes on the client. The debug token is ONLY for use during development. Production must use reCAPTCHA, not debug tokens.

Part 3: Your first generateContent

Step 1: src/app/services/ai.service.ts

import { inject, Injectable } from '@angular/core';
import { getGenerativeModel } from 'firebase/ai';
import { FIREBASE_AI } from '../firebase/firebase-ai';

@Injectable({ providedIn: 'root' })
export class AiService {
  private readonly ai = inject(FIREBASE_AI);

  async ask(prompt: string): Promise<string> {
    const model = getGenerativeModel(this.ai, { model: 'gemini-3.5-flash' });
    const result = await model.generateContent(prompt);
    return result.response.text();
  }
}

Step 2: Call it from a component

Generate a dedicated AI Demo component with the Angular CLI, or wire the call into your root App component.

ng generate component ai-demo --inline-template --skip-tests
import { Component, inject, signal } from '@angular/core';
import { AiService } from '../services/ai.service';

@Component({
  selector: 'app-ai-demo',
  template: `
    <button (click)="run()" [disabled]="loading()">
      {{ loading() ? 'Please wait…' : 'Ask Gemini' }}
    </button>
    @if (error()) {
      <p role="alert">{{ error() }}</p>
    }
    @if (reply()) {
      <pre>{{ reply() }}</pre>
    }
  `,
  styleUrl: './ai-demo.scss',
})
export class AiDemo {
  private readonly ai = inject(AiService);
  readonly loading = signal(false);
  readonly reply = signal('');
  readonly error = signal('');

  async run(): Promise<void> {
    this.loading.set(true);
    this.error.set('');
    this.reply.set('');
    try {
      this.reply.set(await this.ai.ask('Say hello in one sentence.'));
    } catch (err) {
      this.error.set(
        err instanceof Error ? err.message : 'Something went wrong. Check the console.',
      );
    } finally {
      this.loading.set(false);
    }
  }
}

Render it from src/app/app.html:

<app-ai-demo />

Import AiDemo in src/app/app.ts — Angular components are standalone by default and must be listed in the parent imports array:

import { Component } from '@angular/core';
import { AiDemo } from './ai-demo/ai-demo';

@Component({
  selector: 'app-root',
  imports: [AiDemo],
  templateUrl: './app.html',
  styleUrl: './app.scss',
})
export class App {}

Without that import, <app-ai-demo /> will fail at compile time with an unknown element error.

Run ng serve and click on the Ask Gemini button in the rendered UI on http://localhost:4200

Part 4: Verify it worked

Click Ask Gemini. If you get text back — not a 403 — your setup works. That is the pass/fail check.

On first load, the console should show no App Check token fetch failed, and you should have registered the debug token from Part 2, Step 8. Optional: in DevTools → Network, filter firebasevertexai and confirm a POST to :generateContent returns 200. Do not worry if you cannot spot X-Firebase-AppCheck — the header is easy to miss, and Gemini succeeding is what matters.

403 The caller does not have permission? Re-run AI Logic → Get started, confirm the debug token is registered, confirm the Browser key allowlist includes Firebase AI Logic API + Firebase App Check API, then wait a few minutes and hard-refresh.

Part 5: What you can add next

Feature SDK entry point
Multi-turn chat startChat() on a generative model
Function calling tools + FunctionCallingConfig on the model
Streaming generateContentStream()
System instructions systemInstruction in model config

For a full function-calling example, see ByteWise ai.service.ts.

Conclusion

We are at an inflection point where developers can build intelligent web experiences, powered by Large Language Models. Firebase AI Logic provides this infrastructure with a free tier on the Gemini Developer API and Agent Platform Gemini API for enterprise-level use cases.

If you want these capabilities where latency matters, Firebase AI Logic will be your best bet, while offering you security and abuse prevention for your production apps.

To see Firebase AI Logic in action in e-commerce applications, check out Bytewise Shop, a fictional tech gadget shop I built to demonstrate the use of tool calling on actions such as add to cart, check inventory, clearing cart, all using natural language.

File checklist

  • [ ] src/environments/firebase.config.tsnew
  • [ ] src/environments/environment.model.tsnew
  • [ ] src/environments/environment.ts — production values
  • [ ] src/environments/environment.development.ts — add appCheckDebugToken
  • [ ] src/app/firebase/firebase-ai.tsnew
  • [ ] src/app/app.config.ts — add provideFirebaseAI()
  • [ ] src/index.html — localhost debug script
  • [ ] src/app/services/ai.service.tsnew
  • [ ] AiDemo component + import in app.ts

Related links

Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

What was the first thing you worked on at Microsoft?

1 Share
From: Microsoft Developer
Duration: 1:29
Views: 77

Amanda Silver reflects on joining Microsoft in 2001 during the early days of .NET and how her first project, writing the P/Invoke interoperability specification, shaped her understanding of managed runtimes, APIs, and developer platforms. She shares how those foundational experiences influenced a 25-year career building programming technologies and developer tools across Microsoft.
#DotNet #MicrosoftDeveloper #AmandaSilver #SoftwareEngineering #APIDesign #DeveloperTools #CLR #ProgrammingLanguages

Read the whole story
alvinashcraft
9 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Investing in a more reliable Microsoft Graph PowerShell experience

1 Share

We’re focusing Microsoft Graph PowerShell on the platform where we can give you the most reliable, capable, and well-maintained experience: PowerShell 7.x and later. Built on modern .NET, PowerShell 7.x resolves many of the underlying assembly-loading and dependency issues that affect Windows PowerShell 5.x today. Concentrating our engineering there means faster fixes, quicker delivery of new features, and fewer platform-specific failures for you.

To make that focus possible, today we’re announcing that Windows PowerShell 5.x is entering a 12-month retirement period for the Microsoft Graph PowerShell modules. Over this period, we’ll wind down maintenance on 5.x and direct new investment, development, and validation to PowerShell 7.x and later. The v2.x modules will keep working on Windows PowerShell 5.1 throughout — this is a planned transition, not a switch we’re flipping today.

Retirement refers to maintenance, not compatibility. During the retirement period the v2.x modules will continue to declare compatibility with Windows PowerShell 5.1 and, in most cases, keep functioning in existing environments just as they do now. What changes is where our engineering effort goes: new features, bug fixes, and validation will target PowerShell 7.x, and issues specific to Windows PowerShell 5.x will no longer be actively investigated or fixed. 

Timeline

  • Now through the next ~12 months (retirement period). The v2.x modules remain compatible with Windows PowerShell 5.1 and will receive security fixes as required. Maintenance for PowerShell 5.x compatibility winds down, while active development, validation, and investment move to PowerShell 7.x and later — giving you time to plan and complete your migration without disruption.
  • In QC2026 a new major version of Microsoft Graph PowerShell will be released. With the release of v3.0.0 no new versions of v2 will be published unless security fixes are required. V3.x modules will not have explicit support for Windows PowerShell 5.x and are only supported for PowerShell 7.x.

Call to Action

If you’re still on Windows PowerShell 5.1, begin planning your move to PowerShell 7.x now. It’s the recommended and only maintained platform going forward, and it delivers the more reliable experience described above.

We appreciate our customers’ partnership and understanding as we make this transition and continue investing in the future of Microsoft Graph PowerShell.

The post Investing in a more reliable Microsoft Graph PowerShell experience appeared first on Microsoft 365 Developer Blog.

Read the whole story
alvinashcraft
14 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories