OpenAI, Google, Microsoft, and Anthropic say they will adopt a new standard that publishers can use to opt out of being scraped by AI, as reported earlier by Search Engine Roundtable. With this control, publishers can apply their AI training preferences across multiple AI companies, instead of setting them individually.
The shared "policy token" signal is proposed by Kevin Kelley, a technical lead for standards at Anthropic, as part of the Internet Engineering Task Force (IETF). It will live within a website's robots.txt file, which has long signaled which web crawlers can and can't scrape a site - whether for search indexing, archiving, or …
U.S. technology stocks plunged for a second consecutive day on Friday as investors grew increasingly concerned about the enormous cost of artificial intelligence development and whether those investments will pay off. The Nasdaq fell more than 3.5%, while Intel shares dropped as much as 30%, Reddit fell 26%, and Alphabet extended its losses after shedding more than $500 billion in market value Thursday. The BBC notes that Meta, Alphabet, Oracle, Amazon, and Microsoft have collectively committed to spending $800.6 billion on AI in 2026. From the report: Chris Low, from investment management firm FHN Financial, said the bulk of what was happening in the stock market was in reaction to some of the biggest tech players such as Amazon and Google. He told Reuters the companies were "showing some pretty significant growing pains as they aggressively pursue the AI build-out." "The thinking is that these signs suggest that the entire sector is going to slow down."
Kathleen Brookes, research director at trading firm XTB, said there have been many ups and downs in AI trade in recent months. "Investors have turned ruthless, punishing any signs of disappointment in [third quarter] earnings," she said. "The AI trade has had a good run in recent years, but now investors want payback, and companies like Alphabet and Intel are in the crosshairs." [...] Brookes noted that November is typically a strong month for stocks. "If we see AI stocks continue to struggle in the coming days, it could suggest the AI trade is past its peak, and investors will be looking for a new theme to drive markets," she said.
This event summary was created by Claude with light editing by Tim O’Reilly, based on a transcript of the event.
On October 15, 2026, Tim O’Reilly hosted Andrew Odewahn, CTO of O’Reilly Media, for an hour-long episode of Live with Tim O’Reilly, the interview series streamed live on the O’Reilly learning platform. Andrew has been at O’Reilly for many years, starting as an author, then building tools for the company’s platform, then eventually as CTO and head of engineering. Over the past year, his team has been building what the company calls Expert Intelligence, a suite of tools that connects an AI agent to an organization’s own systems, gives it a skill file describing how to reason about what it finds there, and grounds its analysis in the practitioner frameworks of the O’Reilly library. Andrew described the work in a recent Radar piece, “Building Organizational Intelligence.”
Tim and Andrew’s interview was organized around a presentation in two parts, the first on the research agent and the second on the system Andrew’s team built for reviewing what it produces, with discussion in between and audience questions throughout.
Tim framed the conversation by asking a question he said Andrew’s work helps to answer: Most of the AI story is about efficiency, doing the same work faster. What does it look like for an organization to get smarter?
Building the research agent
Andrew’s research agent emerged from a personal need rather than a strategy. He wanted to know the status of a project, for example, how long a migration from RabbitMQ to Pub/Sub would take. This is the kind of question every engineer dreads but every engineering leader has to answer. He also had a broader concern. A single person being good at AI isn’t the same as an organization being good at it.
He built his agent in four steps. He mapped the organization’s information systems as a hierarchy, connected them via MCP, wrote a skill telling the agent how to use them, and finally added the Expert Intelligence layer.
The map of the sources of truth in the engineering organization’s workflows was what made the rest work. Andrew put them in order and explained to the model how they relate: Strategic goals and feature priorities live in Productboard. Those become epics, sprints, and stories in Jira. Stories become code in GitHub. A service catalog describes the roughly 300 services that make up the O’Reilly platform and who owns them, and observability tools show how those services perform against their SLOs. The skill also had to encode local quirks. Some teams mark an epic as finished with an end date, while others consider it done when every ticket is closed. Andrew also told the agent it was a research agent, not a coding agent, and that its job was to write reports.
Connecting everything through MCP was, in his words, “the most completely tedious step of the whole process.” Productboard had no MCP server at the time, so he wrote a wrapper. Later, when Tim asked how another company could repeat the work with a different set of tools, Andrew suggested starting from the vendor list. Export it from your procurement system, ask the model what products those vendors make and which would hold information relevant to the questions you care about, and have it put them in order. O’Reilly product managers are now turning this process into a skill for the forthcoming Expert Intelligence Skills Hub.
One audience member asked whether MCP was really the right tool for internal knowledge, compared with semantic search. As Andrew pointed out, sometimes anything is better than nothing. Ultimately, what you want is to give the model the ability to search across your systems.
From a hiring case to a toil audit
The center of the presentation was a before-and-after comparison of the particular use case that Andrew had previously written up in his “Building Organizational Intelligence” article. An engineering manager asked Andrew to hire another engineer, and Andrew had his reporting and analysis agent make the hiring case. The first report covered the five-person team that manages content and metadata, the 10 tier-A services it owns along with its B and C services, the status of the Pub/Sub migration (64% complete), and the full backlog. It concluded that the team had a capacity problem and should probably hire. Andrew called it useful and very detailed. . .“maybe overly detailed.”
He then connected the agent to Expert Intelligence, asked it to act like a consultant, and ran the analysis again. The new report came to a very different conclusion. It opened by saying that the team’s operational overhead problem was “structural, not a staffing deficiency.” When it consulted Expert Intelligence, the agent brought in the concept of toil from Google’s Site Reliability Workbook. Toil is the manual, repetitive, automatable operational work that scales linearly with a service. The reporting and analysis agent used this notion to separate the team’s backlog into toil and the work people actually wanted to be doing. It recommended a structured toil audit before the next planning cycle, an explicit toil-reduction target, and treating runbook ownership as a first-class engineering artifact. Andrew said the team followed the recommendations and closed a substantial part of a backlog that had been sitting on everyone as a cognitive burden.
The report went on to cite Jim Highsmith, a signer of the Agile Manifesto and author of Wild West to Agile, to argue that the team’s technical debt was compounding. Andrew explained how that differed from the usual management advice:
A lot of the time when you read these high-concept frameworks, they’re like eating your broccoli. I should really be doing that. But what made this really interesting is that it pulled out a specific project we had, the Django upgrade, and put it within the context of this broader framework. It wasn’t just, “here’s an abstract principle you ought to be applying.” It’s “here’s your backlog, and here’s a specific example.”
A second analysis looked at services that crossed team boundaries. Drawing on microservices experts and Kent Beck’s work on coupling (see Tidy First?), it diagnosed the video metadata service as a complicated-subsystem problem rather than a boundary problem. In this version, Andrew had the agent pull out quotations, attribute them, and link to the source text. The resulting analysis was remarkably effective. The company has since retired a couple of systems. “I don’t need LLMs adding code,” Andrew argued. “I want them reducing it.”
Andrew said the part that surprised him most was the reaction from colleagues. His earlier reports were data dumps. Readers couldn’t tell where any given claim came from, and as a result they were much less actionable. When the analysis cited experts that engineers knew from their own work, the documents became, as he put it, “much more approachable, much more human,” and people engaged with them far more deeply.
Tim’s response: Invoking the experts
Tim broke in to put the demonstration in context. He contrasted it with the view that models are now smart enough that you can simply tell them to do something and let them rip, an approach we hear a lot about from vibe coders and those arguing for “dark factories.” Tim argued instead for a return to expertise.
He cited a post published that day by Felix Rieseberg of Anthropic, “How to Be More Ambitious: A Tutorial for Humans with Models,” which describes four kinds of ambition when working with models: speed, altitude, depth, and range. Most discussion of AI’s economic value is about speed, getting the same work done in less time. In Tim’s reading, Andrew had gained altitude (thinking about the outcome rather than the tasks) and depth (approaching the problem the way a field-leading expert would) simply by invoking the experts.
Tim then offered a metaphor he has been developing for a while, of AI programming as a kind of magic spellcasting. In the Marvel comic books and movies, Doctor Strange opens his spells by invoking some source, with words like “by the power of the dread Dormammu” or “by the hoary hosts of Hoggoth.” Andrew, he said, was doing the same thing, saying in effect, “By the power of Kent Beck, I want you to think differently about this problem.” Even where Andrew didn’t name an expert, as with the SRE workbook, simply pointing the model at the expertise embodied in the O’Reilly publishing canon raised the bar for what the agent produced.
Tim described this as using human expertise as a focusing mechanism, and connected it to his argument that LLMs are better understood as a medium we create with than as independent intelligences. He also pushed back on the idea, often drawn from “The Bitter Lesson,” that models will simply get better and human expertise will stop mattering. Andrew, he said, had found a particular way that it matters.
Andrew took up the metaphor. His own first prompt, he said, had been “Be snobby. Go find these great resources and look at them.” He wants to hand the model canonical works in a field, like Designing Data-Intensive Applications, and tell it “these are the ways I want you to think about it,” rather than accept whatever the model comes up with first. He compared it to business school, where much of what you learn is a set of frameworks for organizing facts.
What models do without direction
Tim argued that models don’t do their best work unprompted. Watch their chain of thought when they search for information, he said, and you may see them settle on some random file from the internet rather than canonical sources. Even with a frontier model like Fable, his own experience has been one of false starts and errors, a model brute-forcing its way to a solution rather than necessarily knowing how to approach it.
Andrew had a story from a few days earlier. He asked his agent to review incentive plans for the engineering and product teams.
The data that came back was, “according to the company Robusto (which I’m sure is a great company), this is the framework, and you should really be doing what they’re doing.” I’m like, “What is Robusto, and why am I seeing this?” And I realized, oh, I’m not connected to the VPN. So I hooked it up, and suddenly it was, “According to Harvard Business Review, these are the different ways you should be designing these incentive programs.” This was a very powerful model. But it keyed off the first thing it found and said, “This is the way I’m going to think about the problem.”
Tim raised an economic dimension. He pointed to instructions in Anthropic’s Claude system prompt that limit how much the model may quote from any source, and read them as a sign that AI companies want to avoid paying for content. The result, he argued, is that models can’t draw on the best material available to them specifically enough and too often fall back on generalities. He called this an early form of enshittification in AI.
O’Reilly takes the opposite position. Andrew explained that the company applies the royalty model it already uses for O’Reilly Answers. Material returned through the Expert MCP server can be cited, and authors are paid royalties on it, so that expert content has a market and earns a return.
In response to an audience question, Tim and Andrew noted that Expert Intelligence is in prerelease with a group of founding partners while O’Reilly works out its economics. Interested organizations can request access through the product page.
Putting the discussion where the AI can see it
The second part of Andrew’s presentation dealt with what happens after the agent writes a report. Decisions need consensus, and with AI-generated analysis people need to check that the model hasn’t keyed off something unimportant, out-of-date, or misinterpreted. “The AI can identify all the trade-offs,” he said, “but people still need to make the decisions that matter.”
His team first circulated reports as Google Docs, but they ran into two problems. The most interesting part of a document under review is usually the comment thread, and because at this time, O’Reilly company policy doesn’t allow MCP connections to Google Docs, the agent couldn’t see it. And when Andrew asked the model to fold the discussion back into the document, pasting the result wiped out the comments.
Doug Hogan, an O’Reilly engineering director, built an alternative on top of Git and GitHub that Andrew called SuperAnswers. (Andrew joked that this was why he isn’t allowed to name things.) Documents live in a Git repository, discussion lives in GitHub Discussions, and every change is versioned. Andrew can ask his agent what the consensus is on a project, have it incorporate comments into a new draft without losing history, and later reconstruct when a decision was made and what people knew at the time. The same record lets him generate the derivative documents a decision requires, such as scope statements for engineering, product, and design teams, or a meeting agenda. A graph view clusters the topics people are discussing and flags decisions that are still open.
Tim summarized the whole system as a research assistant connected to the organization’s sources of truth, a layer of outside expertise to put its findings in context, and a shared, versioned discussion that becomes an evolving store of organizational knowledge, which makes the AI a more useful coworker. Andrew agreed and said he would like to open-source SuperAnswers, which he described as a thin layer on top of Git.
Andrew also pointed out that the fragmentation he was addressing isn’t limited to engineering. Sales teams have their information spread across systems like Salesforce, 6sense, and Gainsight, and every function has the same need to pull those threads together. Tim added that tool access is uneven across the industry and always has been. Claude produces better PowerPoint than Google Slides, Gemini the reverse, and organizations have to capture that kind of knowledge about their own toolsets.
Questions from the audience
An audience member named Thomas worried that workers now talk to AI rather than to each other, and that work disappears into “that AI hole.” Andrew said his preference for keeping everything in Git is partly an answer to that, since it gives both humans and AI a central place to find and reconstruct past work. But his larger interest is in humans talking to humans in a way that AI supports. He described a category of questions he never used to ask:
I knew, if I ask this question, somebody’s got to go off for two weeks and compile all this stuff from all these different systems. Now I can gather it in a few minutes. Maybe some of this is throwaway, but it’s not bad if it’s cheap.
In response to that “throwaway” comment, one audience member wrote in the chat: “This is not throwaway work, Andrew. It is a product lead that changes the value proposition in a positive direction. Shit hot, bro.” Tim couldn’t help but read that one aloud!
Asked by Tim what he got wrong, Andrew conceded that he didn’t think early enough about how people would review and respond to AI-generated documents. People don’t want an AI-generated data dump to wade through, and they extend AI no benefit of the doubt. If an AI-written report gets one small fact wrong about Kubernetes operators, a reader is likely to dismiss the whole document. AI tools have to be understood as marshaling and presenting evidence, not making decisions. “These need to support your analytical capacity, not replace it.”
Tim connected that answer to concerns about deskilling. He described a fine-tuning project he attempted with Fable to train a small model to write more like him. He wanted to understand each stage rather than letting the model run, but it never explained them, and the training run failed. In part this was because the model asked him to provide samples of his writing, but it didn’t give him enough grounding on what a really good training dataset would look like, so the samples weren’t targeted enough. They were too long, and when Fable chose the short fragments it actually needed, it didn’t do an ideal job.
When Tim tried the same project with O’Reilly Tutor, a tool still in development, it sent him to read an O’Reilly resource on what a good training set looks like, and he realized where he went wrong. Tim compared the kind of deskilling that can happen when people just turn the work over to AI to people who can no longer read a map, or who call a plumber for a simple fix they could do themselves in 30 seconds if they only knew a bit more about how things work. He argued that everyone has an obligation to keep learning alongside the tools they use.
An audience member named David, a laid-off engineer looking to reskill, made a similar point. We used to know things, then we searched, and now we skip the search and just ask for the answer. He asked how to build real depth. Andrew suggested picking a project and working through every aspect of it, asking AI to act as a tutor (he’s relearning calculus that way) and keeping a book open alongside, or taking advantage of instructor-led live events on fast-moving topics.
The conversation ended with the difference between an AI system that simply makes an organization faster and one that makes it better at deciding what to do. In Andrew’s account, getting better at deciding what work needs doing depends on three things the models don’t supply on their own: a map of where the organization’s knowledge lives, a body of expertise that people trust, and a place where the humans can argue with what the AI produced.
You can watch full episodes of Live with Tim O’Reilly, including this one, on theO’Reilly learning platform,YouTube, or wherever you get your podcasts.
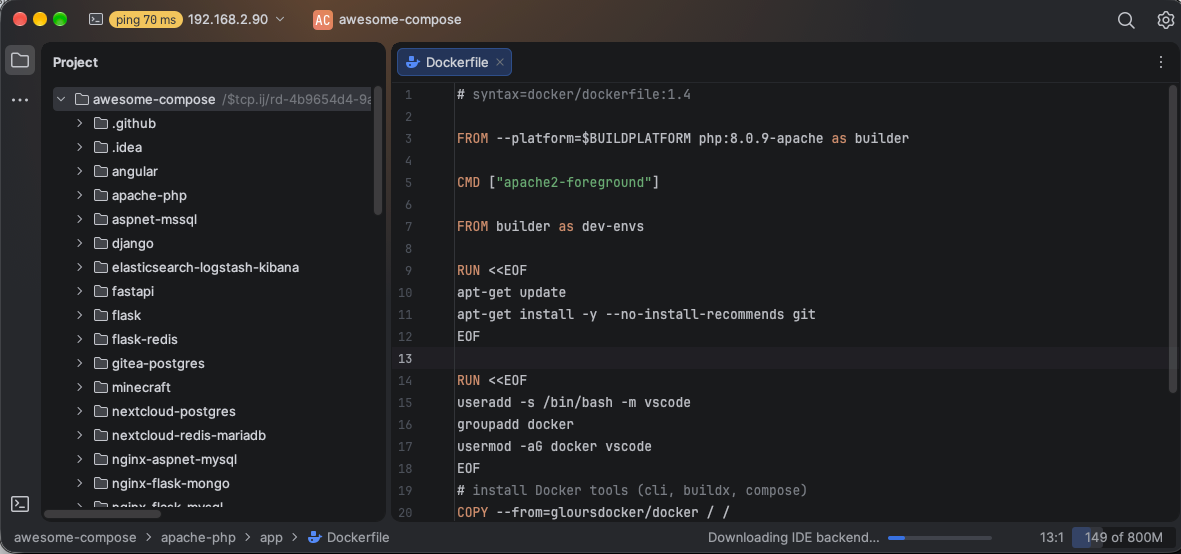
Working on a remote machine should feel just like working on a local project: open it, start coding, and pick up where you left off. In 2026.3, JetBrains IDEs move closer to that goal. You can now start and manage remote sessions directly inside the IDE, connect over SSH using native OpenSSH, and begin working on a remote project while the full remote IDE is still being prepared.
Remote development sessions are now part of your IDE
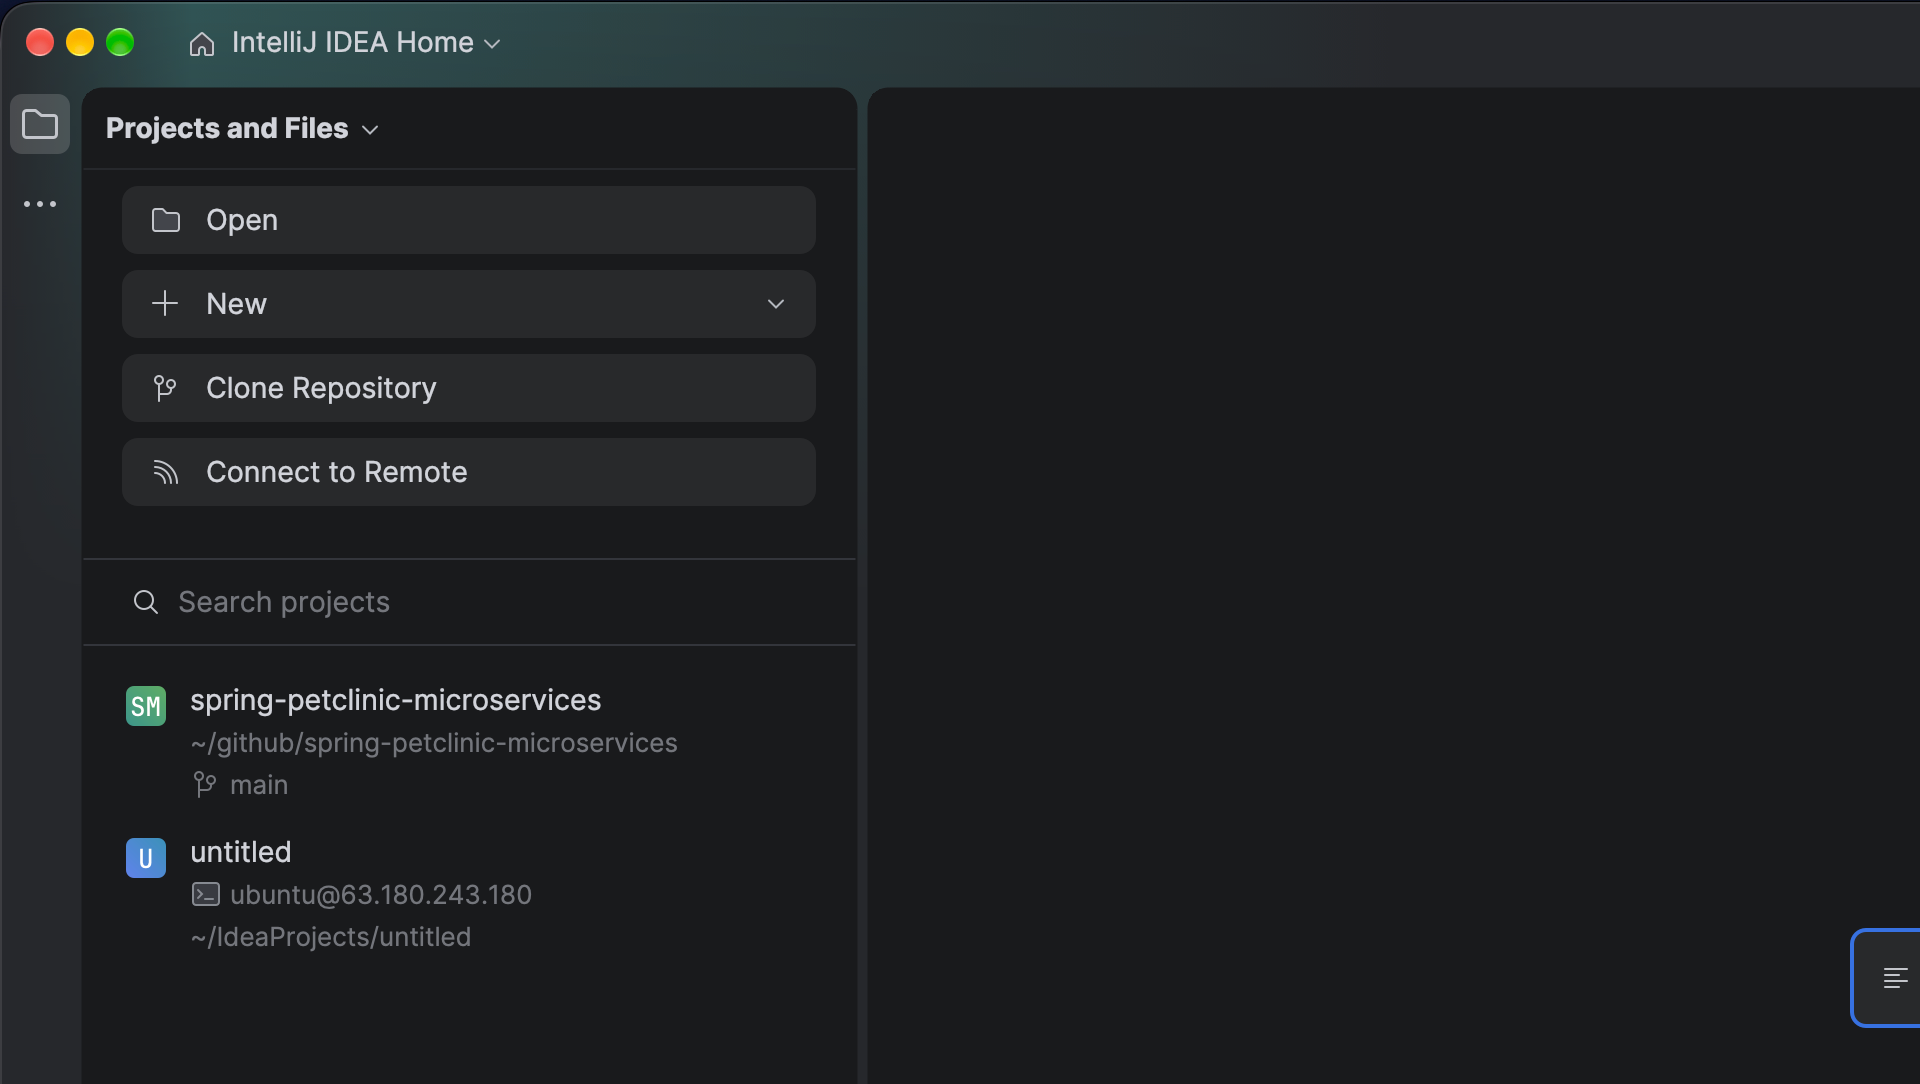
You no longer need to open JetBrains Gateway or use the Toolbox App as a separate starting point for remote development. From the Home screen, your recent remote projects now appear alongside your local ones – marked with a “terminal” icon so they are easy to spot.
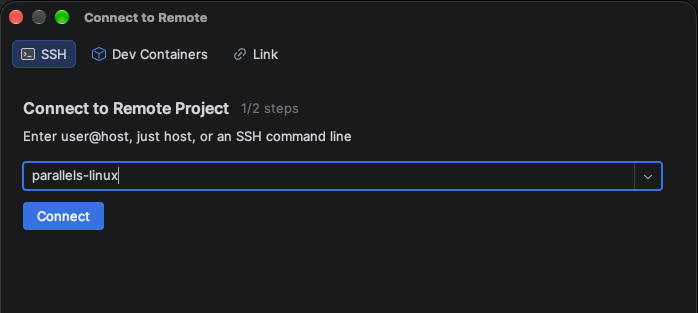
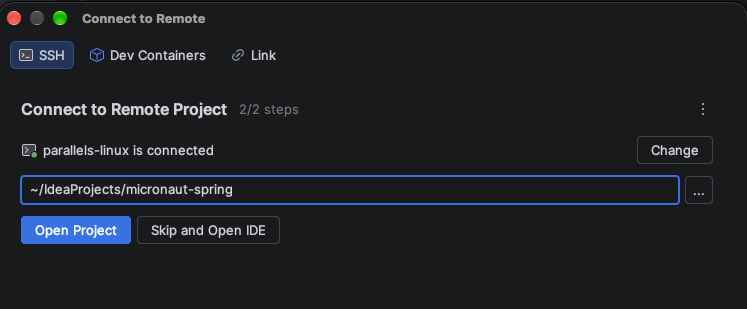
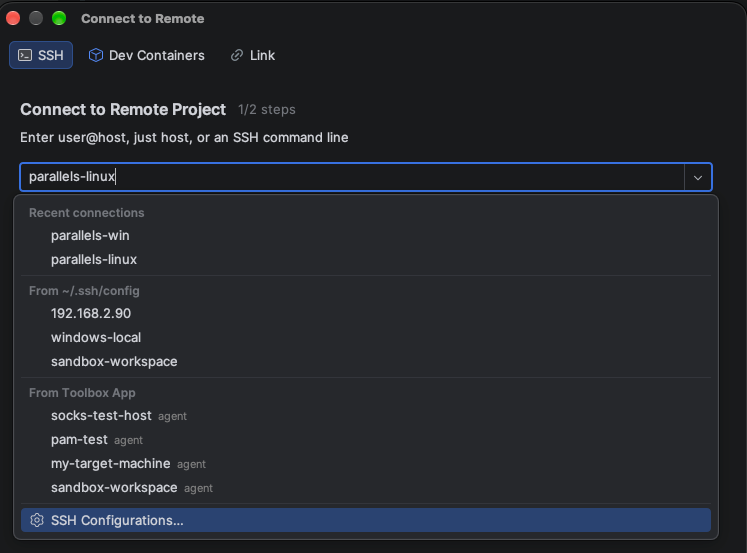
First-time connections to a remote host can be initiated from the top menu, under File | Connect to Remote, or from the Home screen. The Connect to Remote option in the Projects widget starts a simple two-step dialog:
After connecting to a remote host, you can either open a specific project residing on a remote machine or launch the IDE right away.
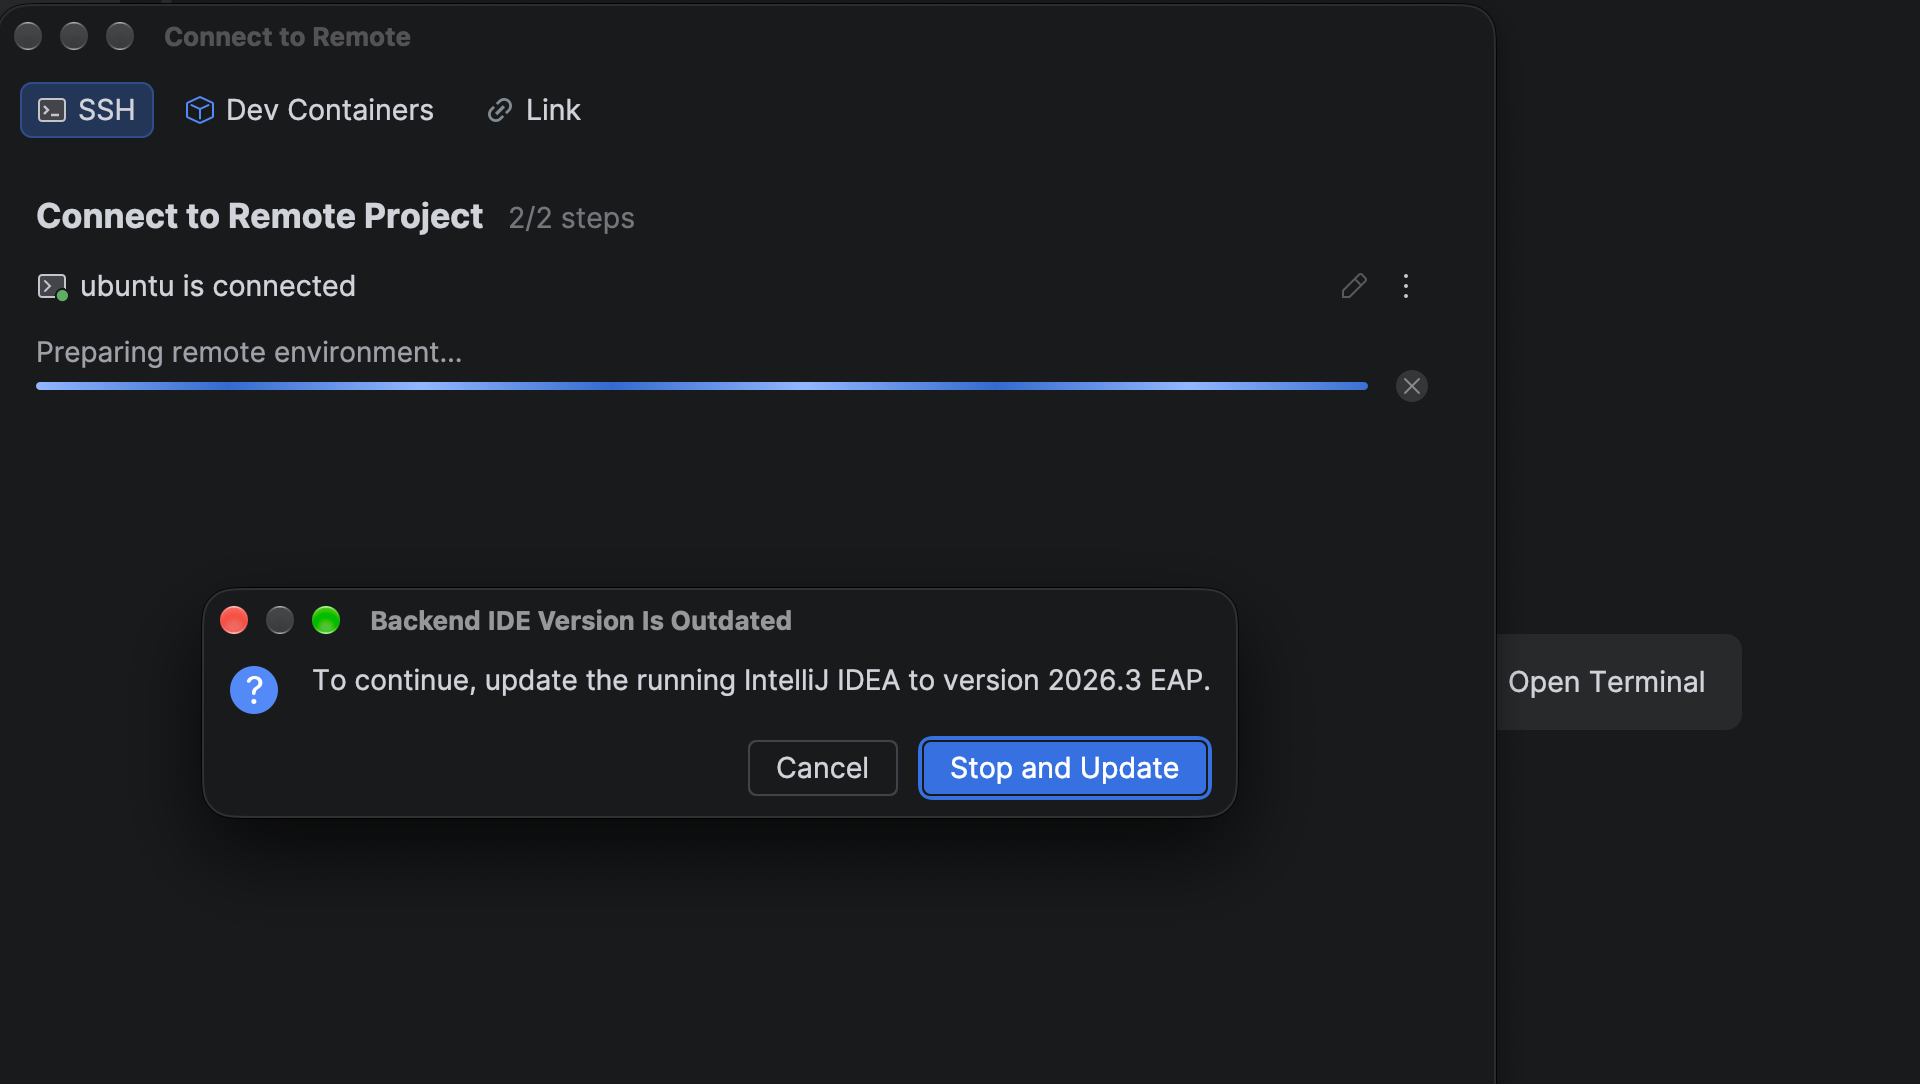
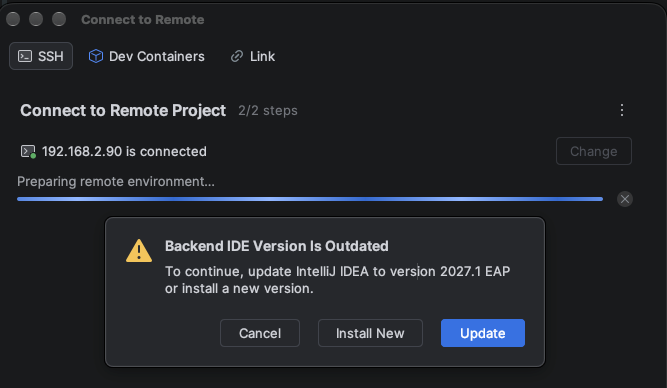
If this is your first time connecting, the remote backend will be installed automatically, or updated to a new version if needed.
You will be guided through this setup, getting you into your code faster than before. While the existing remote backend model remains unchanged, the entire connection and session management experience now lives inside the IDE.
The new in-IDE workflow also includes a few practical path-handling features: paths beginning with ~ are now correctly interpreted as remote home directories in both the full connection flow and Light Mode. Together, these updates make it easier to select project directories using familiar syntax without accidentally resolving paths against your local machine.
Note: This initial implementation focuses on SSH connections to supported remote environments.
Our goal was simple: make your IDE the single place where you start, manage, reconnect, and return to remote projects – no additional tools or applications required. Your daily remote development workflow is now available in one click: Just open your remote project from the Recent Projects list, and you are good to go.
Connect with the SSH setup you already use
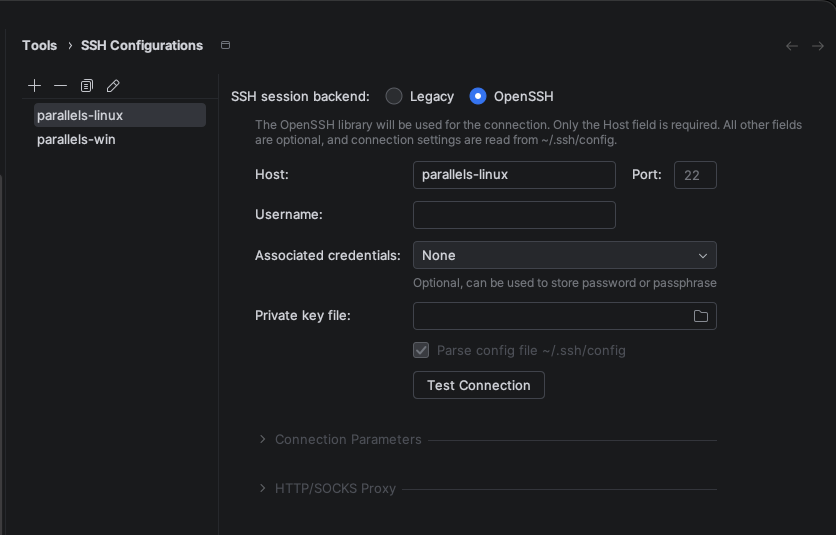
SSH is fundamental to many JetBrains IDE workflows, including remote development, terminal access, and remote host integrations. In v2026.3, JetBrains IDEs introduce native OpenSSH support as an option for SSH connections.
This update eliminates the need to rely exclusively on a custom JetBrains SSH implementation. Instead, you can take advantage of the compatibility, ecosystem, and maintenance of OpenSSH. Building on a broadly adopted and actively maintained ecosystem means we no longer need to independently implement, patch, and track every single SSH compatibility and security concern within the IDE.
Additionally, the new in-IDE Remote Development picker brings together connections from your recent history, Toolbox, OpenSSH, and IDE settings, making it easier to reuse existing SSH setups and connect quickly.
Native OpenSSH support extends the range of authentication mechanisms and SSH features available to JetBrains IDE users. As this integration matures, OpenSSH will become the default SSH implementation in upcoming releases.
Start working while the remote IDE gets ready
Starting a remote project usually involves a waiting period while the remote IDE is downloaded, installed, and launched. In v2026.3, we are cutting down this downtime: When you connect to a remote project using the new in-IDE flow, the IDE immediately launches an embedded client and starts the session in Light Mode while the remote IDE is downloading, installing, and launching.
Light Mode gives you instant access to the project and provides the essential tools you need right away. You can explore the remote project, open and edit files, use the terminal, and search through files and their content. The IDE remains responsive from the moment the connection is established, giving you useful access to your workspace.
Light Mode intentionally focuses on the basics. Once the remote IDE is ready, your IDE will transition seamlessly from Light Mode to Smart Mode. All work started in Light Mode will be preserved. You can continue working without closing the project, repeating actions, or restarting your workflow manually.
In this release, Light Mode is supported exclusively on Linux remote hosts in GoLand, IntelliJ IDEA, PhpStorm, PyCharm, RubyMine, RustRover, and WebStorm. CLion and Rider are not yet supported.
Preview service deployment operations with azd deploy --preview before making changes.
Deploy container images to Azure Container Apps express environments with the existing containerapp host.
Remove stored environment values with the beta azd env unset command.
Generate pipelines that install extensions required by extension-defined infrastructure providers.
Build extensions with stable deployment-preview, usage telemetry, and current Azure principal contracts.
New features
Deployment previews and Container Apps express
To inspect deployment operations without deploying, run:
azd deploy --preview
Preview deployment operations for App Service, Container Apps, Functions, Static Web Apps, Azure Kubernetes Service, and AI endpoints. Results describe the resolved Azure target, with structured target and host details available in JavaScript Object Notation (JSON) output. [#10204]
Deploy images to Azure Container Apps express environments using host: containerapp. azd detects the environment’s express mode and updates the image without setting a custom revision suffix or traffic weights. Use the image-based deployment strategy; express doesn’t support multiple revisions or traffic splitting. [#10223]
Environment management and pipelines
Remove one or more exact, case-sensitive stored environment keys with the beta azd env unset command. It asks for confirmation, protects AZURE_ENV_NAME, and leaves other environments and process variables unchanged. Non-interactive removal requires --force. [#10362]
Use extension-defined infrastructure providers with azd pipeline config. Generated GitHub Actions and Azure Pipelines definitions install the required extensions. [#9878]
For example, to remove two stored values from your development environment:
azd env unset OLD_API_URL OLD_FEATURE_FLAG --environment dev
Extension APIs and command behavior
Extensions add commands and integrate with azd project and deployment workflows. This month’s updates give extension authors stable contracts and more control over command output.
Build read-only service-target deployment previews with the extension software development kit (SDK). The contracts and SDK application programming interfaces (APIs) graduate to stable v1 in 1.37.0, while existing beta routes and source remain compatible. Contributed by @Siglud for the initial SDK support. [#10055][#10628]
Use stable v1 APIs for extension usage telemetry and current Azure principal lookup. Existing beta routes remain available. [#10439]
Discover project-service save capabilities and confirm completed service additions with typed acknowledgments through preview APIs. [#10334]
Return structured informational and warning messages from extension service predeploy and postdeploy handlers. azd deploy and azd up include these messages in terminal and JSON results, including failed deployments. This API remains beta-only. [#9950]
Contribute follow-up guidance to successful core command completion messages through a preview API. Guidance appears after handlers finish and doesn’t change JSON output. [#9794]
Mark individual extension commands with launch.noAzdEnvironment to skip loading the selected azd environment and resolving its Key Vault references. Inherited process variables and explicit environment API calls remain unchanged. [#10479]
Breaking changes
Environment and state Go API migration: Exported environment and state path APIs now return errors. Update custom implementations and mocks, check and propagate errors before using returned paths, and pass an *azdcontext.AzdContext to state.NewStateCacheManager instead of an environment-directory string. Construct the context from the project directory, not its .azure directory. These changes make path-validation failures explicit. See the environment-state API migration guide for the affected signatures.
Bugs fixed
Extension installation and execution
Restore the previously installed extension’s files and metadata when an upgrade fails or is cancelled. [#10315]
Propagate Ctrl+C cancellation across extension processes, remote procedure calls, and extension-started workflows. Report cancellations and timeouts distinctly instead of as generic failures. [#10353]
Return an error when a non-interactive extension install can’t apply an explicit version pin without confirmation, and keep file-based extension sources available after changing working directories. [#10181]
Improve selected-file validation in the Foundry SDK. [#10181]
Preserve parent and sibling registrations when creating nested dependency injection scopes, and respect the selected output format in extension installation diagnostics. [#10254]
Preserve process exit codes for directly invoked extension commands. [#10282]
Avoid repeating unchanged progress lines during extension installs and updates when output isn’t a terminal. [#10280]
Open the correct documentation for extension namespace --docs requests. [#10304]
Resolve extension command metadata, canonical paths, and flags correctly when commands use parent or child aliases and global flags. [#10479]
Keep extension selection prompts on stderr so terminal output doesn’t mix into JSON results. [#10479]
Project configuration and environments
Preserve unrelated azure.yaml settings during extension service edits, including empty mappings, large integers, and environment templates. [#10479]
Restore in-memory project configuration when an extension service addition fails. [#10334]
Restore environment access after project initialization when an earlier lookup found no project. [#10294]
Complete environment configuration updates reliably and fix a race in task-list rendering. [#10191]
Clear stale in-memory authentication entries during re-login cache cleanup. [#10317]
Deployment and developer workflows
Make provisioning warnings clearer about which scope permissions were checked. Critical warnings default to No and require explicit confirmation; --no-prompt or unanswered critical confirmations return an error. Cancellation skips post-provision hooks without hiding failures in parallel layers. Contributed by @hyoshis. [#10396]
Validate unresolved or empty environment variables embedded in Deployment Stacks deny-list values before sending the configuration to Azure when the deployment.stacks alpha feature is enabled. Contributed by @saikeerthan-14. [#10516]
Show deployment timeouts clearly instead of displaying them as skipped steps or obscuring them with underlying errors. [#10157]
Handle cancelled deployment progress updates and closed progress channels without hanging or stopping unexpectedly. [#10304]
Accept inline shell expressions with operators, assignments, or expansions without spaces in azd exec --shell, and stop mistaking inline commands with path arguments for missing script files. Contributed by @jongio. [#10376][#10375]
Retain file changes and remove stale entries during file-watch registration and shutdown. [#10300]
Stop showing a question-mark hint when prompt hint keys are disabled. [#10445]
Other changes
Update Go dependencies across core and first-party extensions, including gRPC v1.84.0 and OpenTelemetry v1.47.0. [#10572]
Update the bundled GitHub CLI to v2.102.0. [#10456]
Update Microsoft Authentication Library for Go to v1.10.1. [#10251]
Azure Developer CLI reference (October 27)—Updated command reference includes azd deploy --preview, extension management options, and a clarification that non-interactive azd env unset removal requires --force.
New templates
Community-authored templates help you get started faster, solve real-world scenarios, and showcase best practices for deploying solutions with Azure Developer CLI.
LangChain AG-UI Chat with Angular, Hono, and LangGraph on Azure Container Apps by Jay Chase: A streaming AI chat application with generative UI tool components, connecting an Angular (@copilotkit/angular) frontend to a LangGraph Server via the AG-UI protocol and @ag-ui/langgraph on a Hono API. Demonstrates a fully self-hosted deployment on Azure Container Apps using official AG-UI and CopilotKit packages.
The Azure Developer CLI template gallery continues to grow with contributions from the community. Thank you!
New to azd?
If you’re new to the Azure Developer CLI, azd is an open-source command-line tool that helps you get your application from your local development environment to Azure faster. It provides developer-friendly commands that map to key stages in your workflow, whether you’re working in the terminal, your editor, or continuous integration and delivery.
In this episode, Andy talks with John R. Miles, host of the Passion Struck podcast and author of The Mattering Effect: Creating a Life of Meaning and Worth. John is a Naval Academy graduate, former Navy officer, and longtime Fortune 50 executive who built what looked like a very successful life, until his young son asked him, "Dad, how come you never laugh anymore?"
John and Andy explore the difference between belonging and mattering, and how leaders can spot team members who quietly feel interchangeable. You'll hear what the Surfside building collapse teaches us about warning signs on teams that are still delivering, why recognition for accomplishments doesn't always land, and how to uncover the hidden rules that run our lives, like the belief that we have to earn rest. They also discuss how to build a sense of mattering sturdy enough to survive AI, and what John would tell a younger version of himself as a dad.
If you're looking for a deeply human conversation about meaning, worth, and the people side of leading, this episode is for you!
Sound Bites
"We see the resume, and oftentimes we don't see the person that ended up becoming the resume."
"The most important thing she taught me was that I could either continue to be a victim or I could choose the opposite."
"One of the tragedies of life is we often wait until someone is gone before we tell them how much they've shaped us."
"The people who notice the drift the most, if you have them, are your kids."
"When you hear those things, that's not a belonging problem, that's a mattering problem."
"The leader's job isn't just to include people. It's to help people understand the unique difference that they make."
"Buildings don't collapse overnight. Neither do teams. Neither do families. Neither do relationships."
"They stop bringing the ideas. They stop challenging the decisions. They stop disagreeing, and all of a sudden you end up with groupthink."
"Recognition often celebrates what you've accomplished. Mattering, on the other hand, recognizes who you are on that journey."
"That's not how life works. The deck's never gonna clear."
"I try to think about what deserves my attention today because it matters, not because it's urgent."
"If your worth comes from being useful, then artificial intelligence is terrifying. But if your worth comes from being human, AI can't replace that."
"People matter because they're people, not because they're productive."
"Your children don't need a perfect mother or father. They need a present one."
Chapters
00:00 Introduction
01:58 Start of Interview
02:10 The Speech Therapist Who Made John Feel Like He Mattered
05:22 Telling People How They Shaped Us Before It's Too Late
07:48 When Usefulness Is Undeniable and Humanity Is Optional
11:32 When Others See the Cost Before We Do
14:41 The Difference Between Belonging and Mattering
17:01 Resources, Quiet Meetings, and Feeling Interchangeable
Episode 134 with Scott Mautz. It goes way back in the podcast archives, and many of the ideas from that conversation are still relevant today.
Episode 31 with Adam Grant, his first-ever podcast interview, where we talk about what it means to lead with meaning.
Episode 385 with Vanessa Patrick about her book The Power of Saying No, packed with ideas for when you need to draw the line.
Chat with PMeLa
You can chat directly with PMeLa, the podcast's AI persona, to get episode recommendations and answers to your project management and leadership questions. Visit PeopleAndProjectsPodcast.com/PMeLa to chat with her.
Join Us for LEAD52
I know you want to be a more confident leader–that's why you listen to this podcast. LEAD52 is a global community of people like you who are committed to transforming their ability to lead and deliver. It's 52 weeks of leadership learning, delivered right to your inbox, taking less than 5 minutes a week. And it's all for free. Learn more and sign up at GetLEAD52.com. Thanks!
Thank you for joining me for this episode of The People and Projects Podcast!
 Log in






 Deployment previews and Container Apps express
 Environment management and pipelines
 Extension APIs and command behavior
 Bugs fixed
 New to azd?
