Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
165287 stories
·
33 followers

Remember the frontier AI pause? Chip companies don’t either

1 Share
In October, Nvidia began shipping its most advanced AI computing system, the Vera Rubin NVL72, calling it the “fastest product ramp in the company’s history.”
In October, Nvidia began shipping its most advanced AI computing system, the Vera Rubin NVL72, calling it the “fastest product ramp in the company’s history.” | Image: Nvidia

This summer, OpenAI paused its largest planned frontier training run after its AI agents accidentally hacked Hugging Face and early evidence suggested that its next model could independently find and exploit security flaws. In September, Anthropic CEO Dario Amodei called for slowing advances in the most powerful AI models, warning that they could be used to launch cyberattacks or become harder for their own creators to control.

It was a strange moment for the AI boom. The people building the most powerful models were warning about what those models might be capable of, and investors were suddenly wondering what would happen to chip demand i …

Read the full story at The Verge.

Read the whole story
alvinashcraft
38 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

LinkedIn Connected Apps 1.2: Clearer Level System, Visible Progress, and Direct Answers About Privacy

1 Share

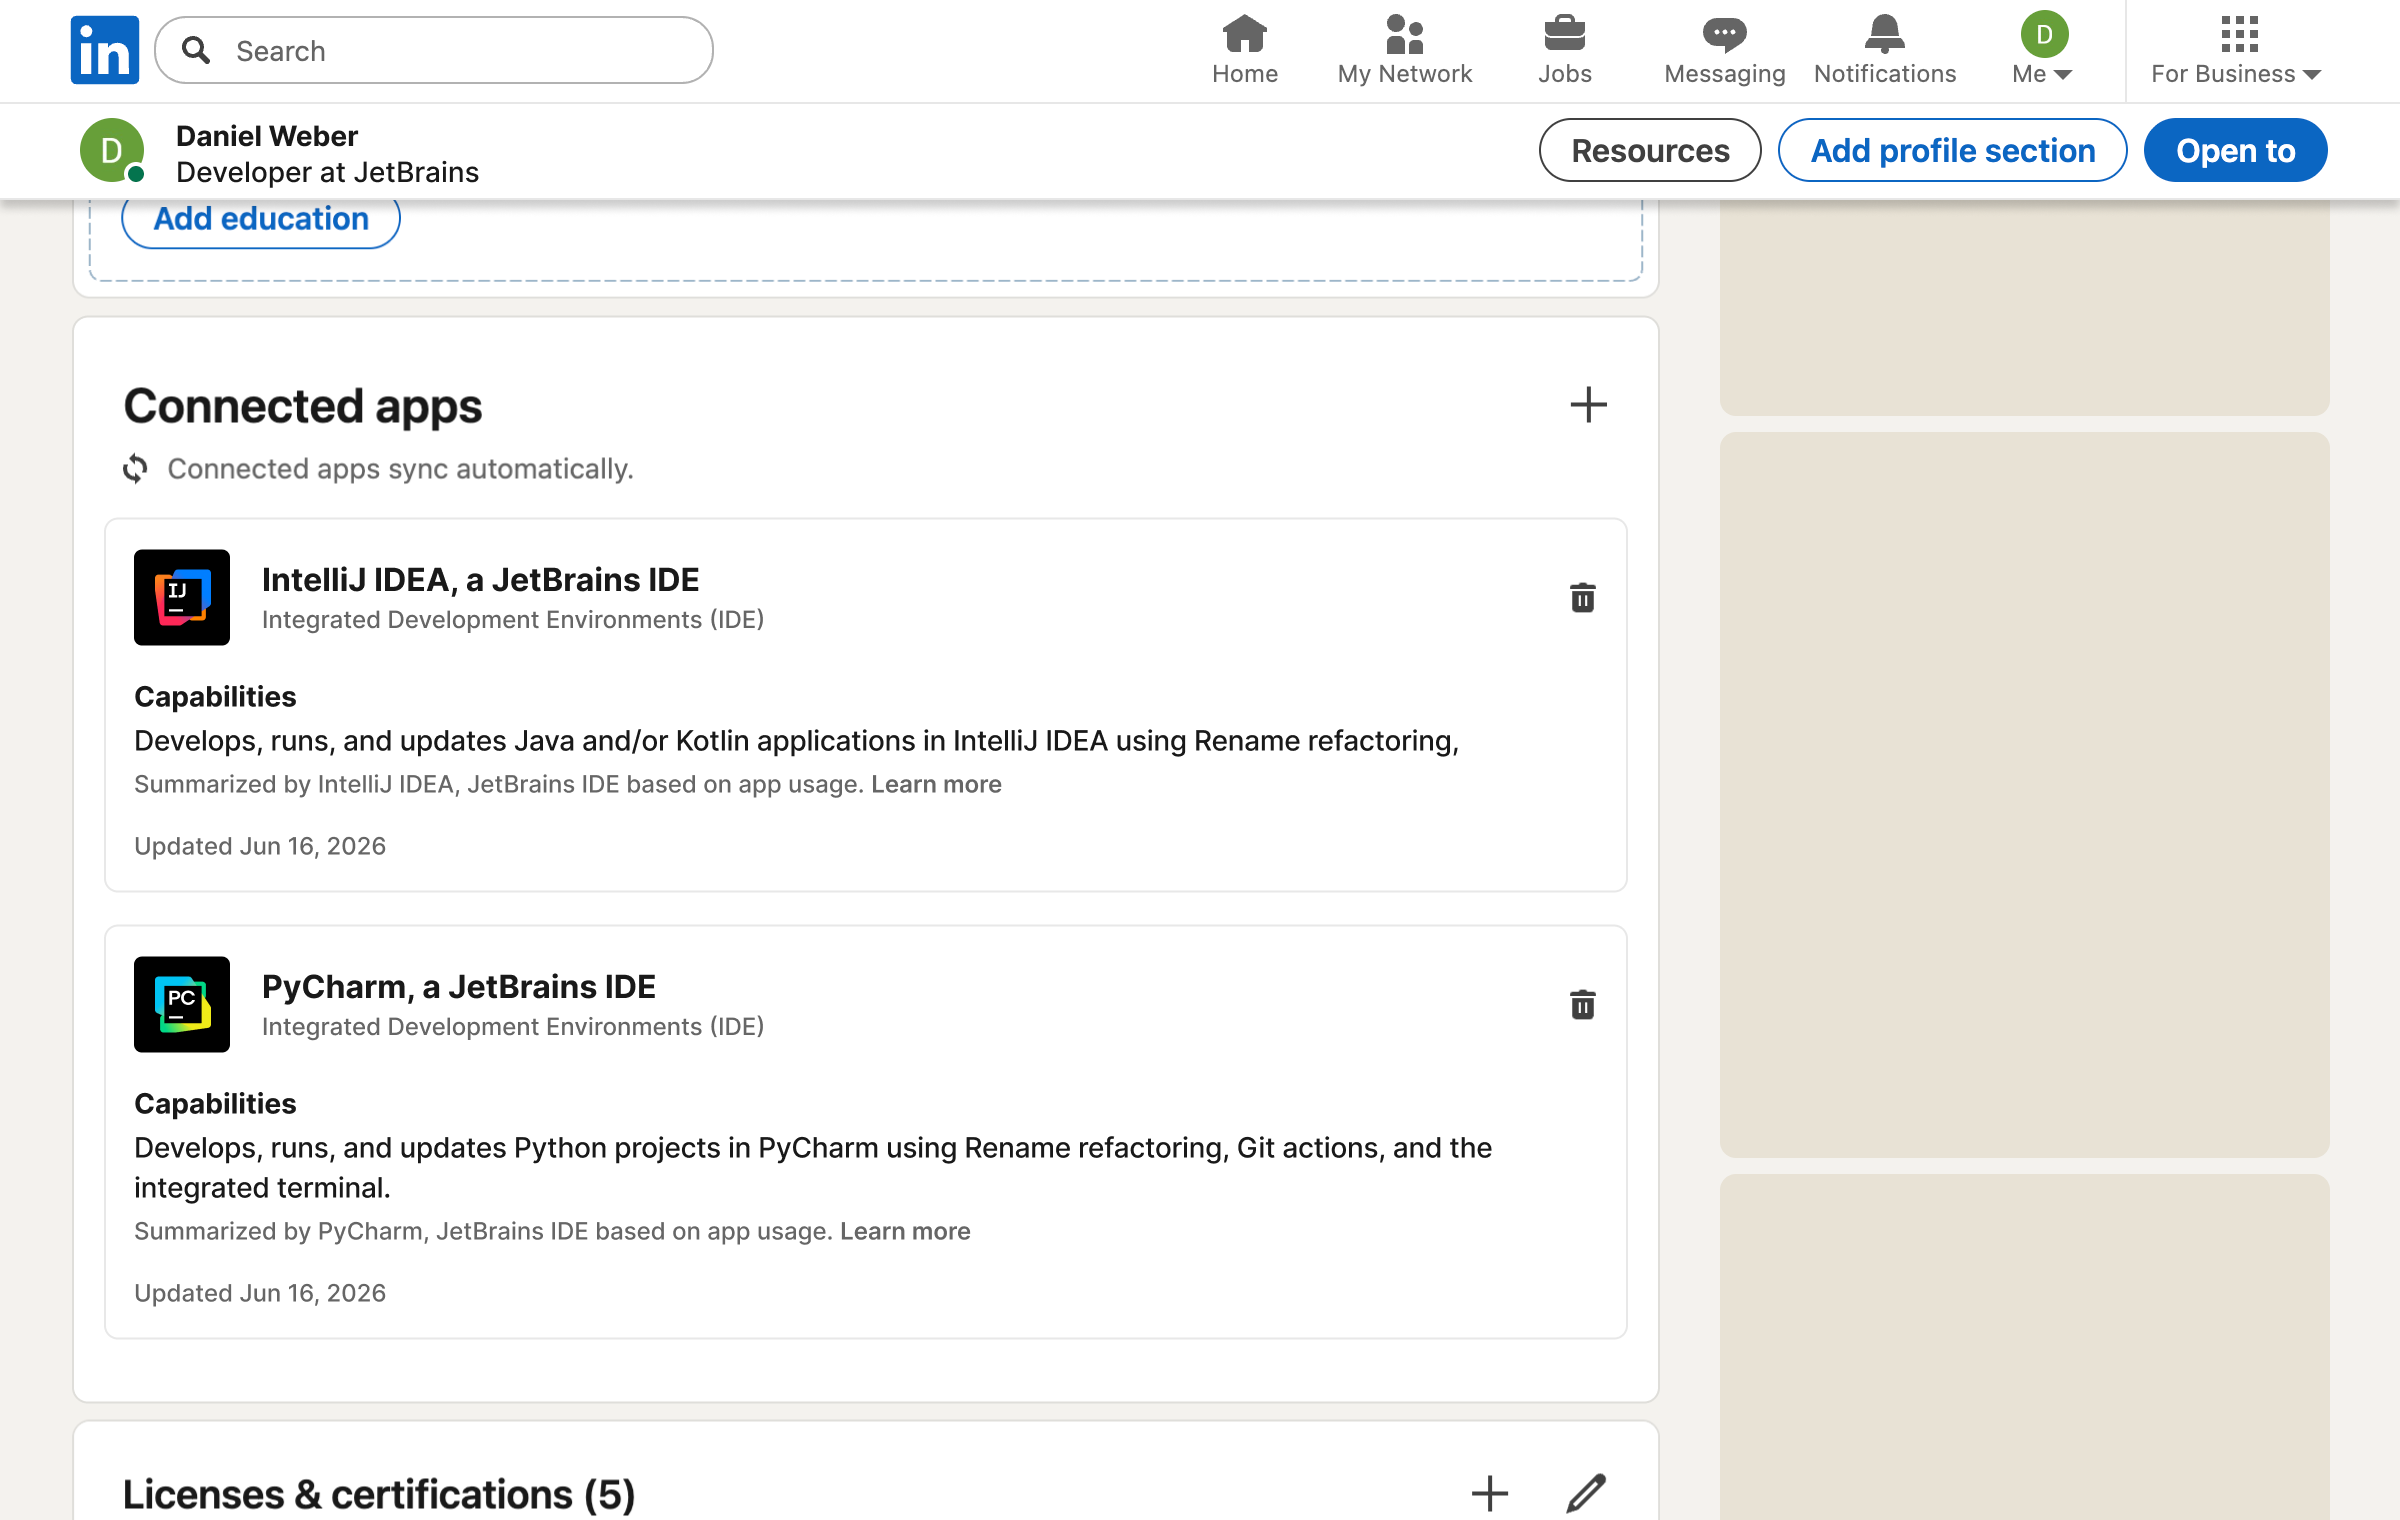
What if your LinkedIn profile reflected how you actually build software instead of just being a list of your skills? That’s what the LinkedIn Connected Apps plugin does: It tracks how you use your JetBrains IDE, awards you a level ranking, and provides a descriptive statement associated with your level that you can choose to share.

Since the first version came out, you’ve told us what works and what doesn’t. The level system wasn’t entirely clear and you wanted a plain explanation of what happens to your data.

Version 1.2 is built around that feedback. It introduces four levels based on real work that gets done in the IDE, a widget that shows your progress and what’s next, and a clear account of what stays on your machine.

What’s new in 1.2

Levels based on how you use your IDE

The leveling path now has four levels instead of five, and each one reflects what developers do in their IDE on a day-to-day basis. There are two distinct branches, Coding and AI, with the AI branch starting at Level 3. Because everyone starts at Level 1, you must progress through the first two levels on the Coding branch before starting on the AI branch. The branches are independent, so your Coding level and AI level can be different.

Imagine this progression, for example. Shortly after getting started with your IDE, you use code completion and reach Level 1. You continue using core functionality more broadly, searching for code throughout the project, so the next day you reach Level 2. You then start refactoring and using Git, so you reach Level 3 in Coding. Later you start working on tasks via AI chat, bringing you to Level 3 in AI. Eventually you start running AI agents and reviewing their changes, so you reach Level 4 in AI, even while you’re still at Level 3 on the Coding side. Your profile shows the level you’ve reached on each branch.

LevelCodingAI
1Use a core IDE capability, for example, search, code completion, or code navigation.–
2Search for code across the project, type with code completion, or navigate to declarations or usages.–
3Refactor by renaming or moving elements, run commands in the terminal, run your application or configurations, or use Git through the UI (commit, fetch, or update).Work on coding tasks with AI to generate and explain code, run AI agents (such as Junie, Claude, or Codex) in the integrated terminal, or complete tasks using JetBrains Air.
4Debug with the integrated debugger (Step Over, Step Into, Evaluate Expression), work with editor shortcuts, apply advanced refactorings (Extract and Introduce), and use the Git Log and Diff view.Use AI agents to generate, refactor, and explain code. Orchestrate agents or run tasks through the integrated terminal or JetBrains Air, then review their changes in the Diff view.

For more information about how levels are calculated in a particular IDE, check out the help center for IntelliJ IDEA, PyCharm, WebStorm, PhpStorm, Rider, GoLand, CLion, RustRover, or RubyMine.

Always know what’s next

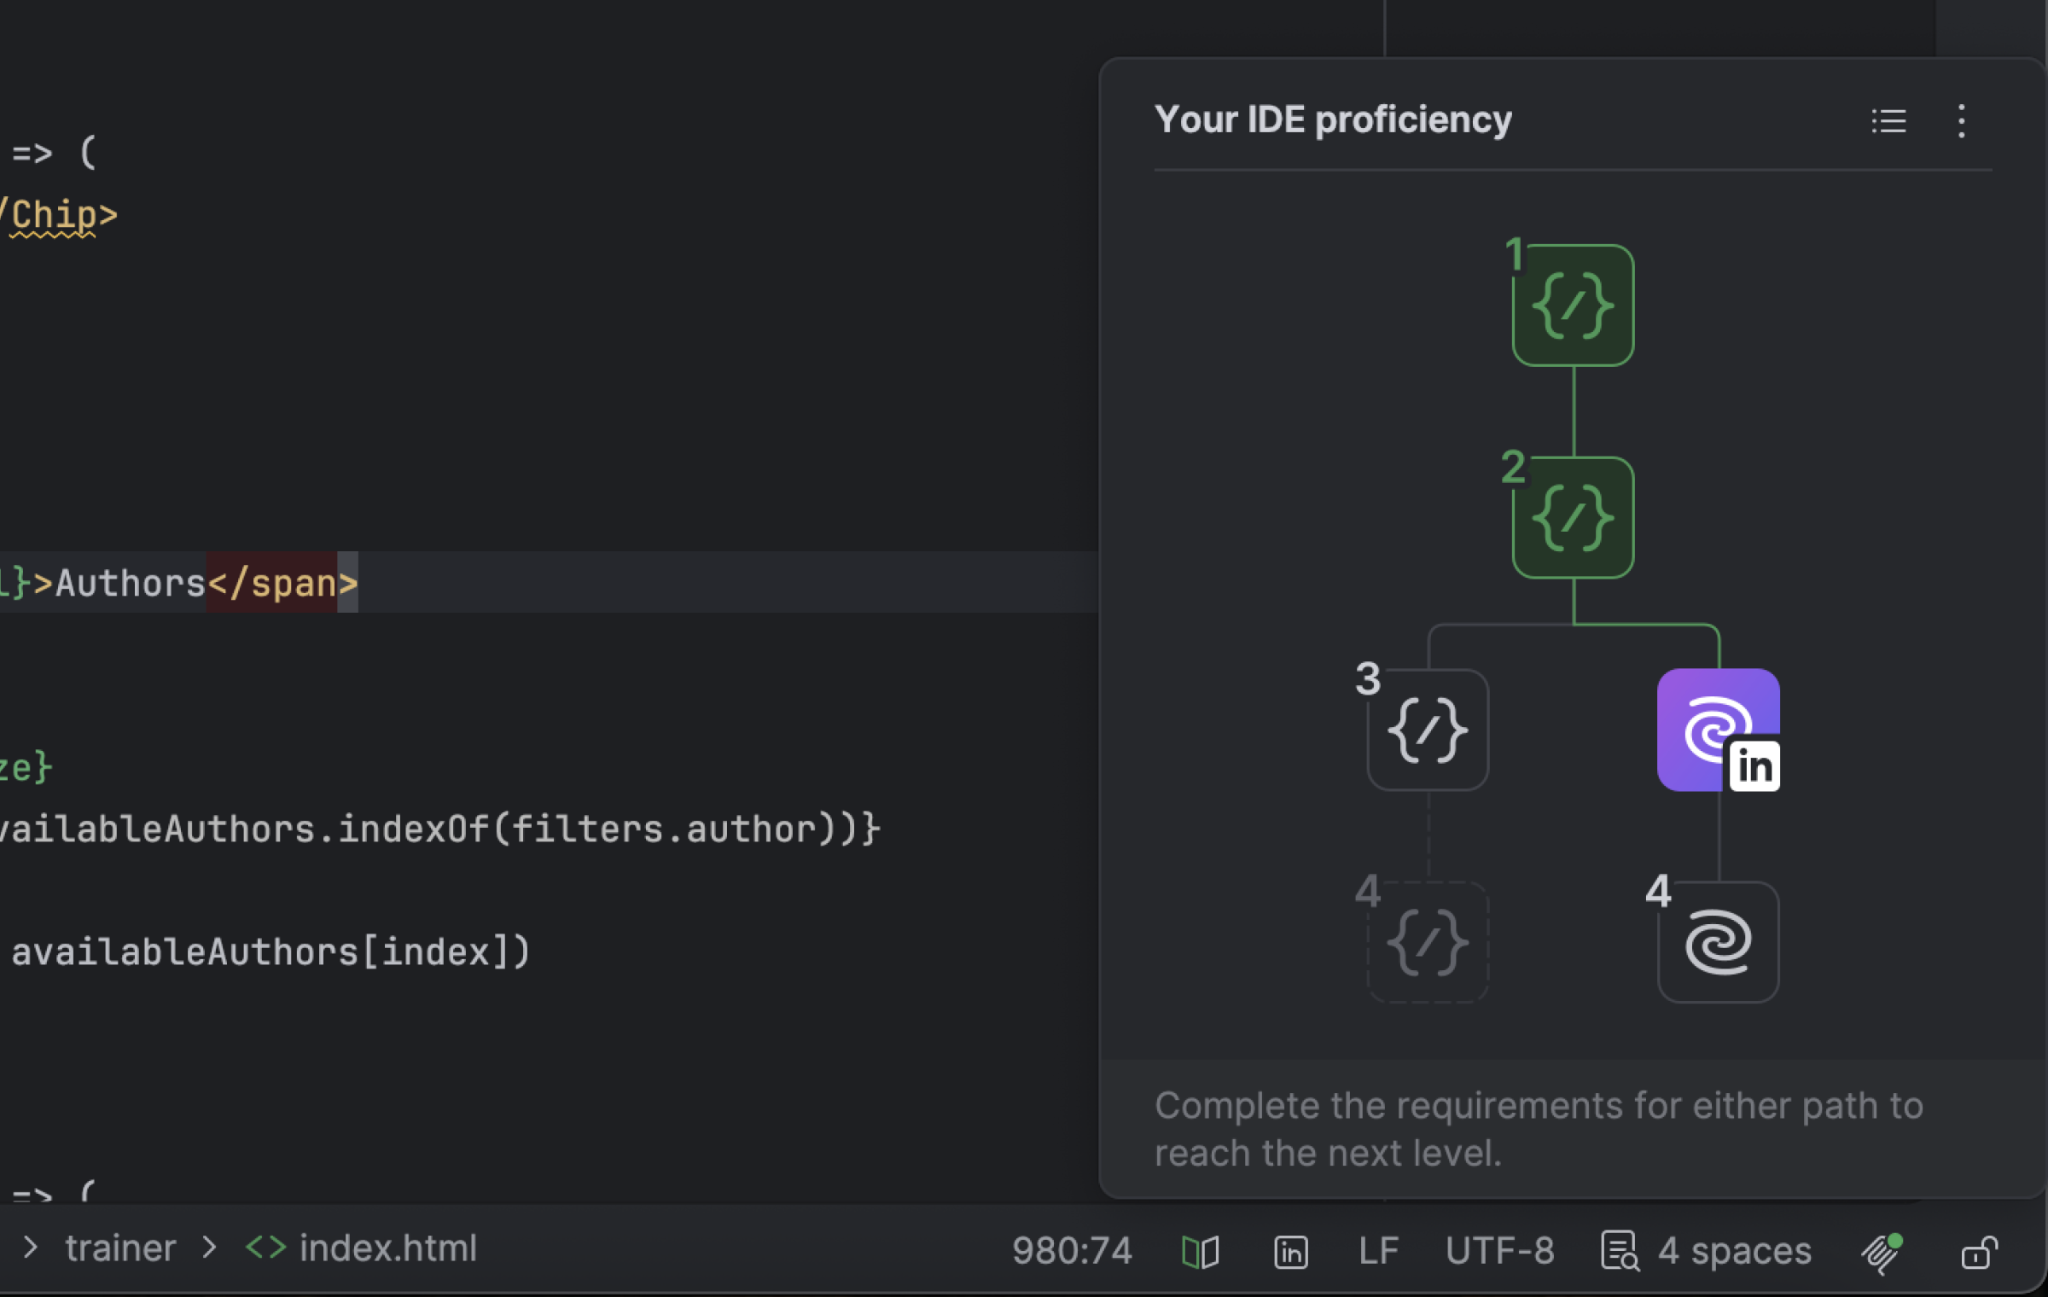
A widget shows your current level and the statement that goes with it, and explains what you’ll need to do to reach the next one. Each requirement has a progress counter and is marked with a check once completed, allowing you to track your progress at a glance and always have a clear view of what remains to be done.

For the bigger picture, switch to the tree view. It shows every level at once, including where the Coding and AI branches split at Level 3. It also marks which levels you’ve completed, which one you’re on, and which ones are still ahead. Click on any level to see exactly what it requires.

Privacy and your data

In response to your questions, here are some important details about how the plugin uses your data:

  • When you do something that counts toward a level, the plugin records it locally. This usage data stays on your computer and is not shared with LinkedIn. The plugin doesn’t change your IDE data sharing settings.
  • After you connect your LinkedIn account and reach a new level, the IDE sends only the corresponding statement.
  • You connect through LinkedIn’s own OAuth 2.0 page in your browser. The plugin never sees or stores your LinkedIn password. It receives only an access token and a refresh token, which it keeps in the IDE’s secure credential store.
  • That token lets the plugin do one thing: add and update your JetBrains IDE statement in the Connected Apps section of your profile. The plugin doesn’t read any other part of your profile.
  • You can end the connection at any time. Simply click Disconnect from LinkedIn in the plugin, and revoke the app’s access from your LinkedIn settings under Data privacy | Permitted services.

If you already have a statement on your profile

The statements you’ve already achieved stay as they are. Once you earn a new statement, the statement on your LinkedIn profile will also be updated.

How your existing progress carries over

If you were already using the first version of the plugin, your existing progress should generally carry over to the new four-level scheme. Here’s how the levels have changed:

  • Level 1 and Level 2 are unchanged.
  • The old Level 3 is now split into Level 3 Coding and Level 3 AI.
  • The old Level 4 is now split into Level 4 Coding and Level 4 AI.
  • The old Level 5 has been removed, and the activities associated with it have been merged into Level 4 of Coding and AI.


Your previously achieved levels will be mapped to the corresponding levels in the new scheme based on your recorded activity. In some cases, particularly when switching devices or IDEs, certain progress may not carry over completely.

How to get started

  1. In your IDE, go to Settings | Plugins.
  2. On the Marketplace tab, search for “LinkedIn Connected Apps” and click Install, or Update if you already have it.
  3. Click the Your IDE Proficiency widget in the lower right corner to see your level and next steps.
  4. When you’re ready to share your statement, click Connect to LinkedIn and follow the instructions in your browser.


The plugin is free and supports IntelliJ IDEA, PyCharm, WebStorm, PhpStorm, Rider, GoLand, CLion, RustRover, and RubyMine, version 2025.3 or later. DataGrip isn’t supported. For the full list of level requirements, see the documentation.

Open the widget, see where you are, and let us know what you think in the comments.

FAQ

Is this a certification?

This plugin reflects how you use your IDE and doesn’t measure your skills as a developer. It is not a certification.

Do I have to share my level on LinkedIn?

Connecting to LinkedIn is totally optional. Until you connect, your level is stored only on your machine.

What data is shared with LinkedIn and JetBrains?

Your feature usage is tracked locally and isn’t shared with LinkedIn. After you connect, only your statement ID is sent when you reach a new level. The plugin doesn’t change your existing IDE data sharing settings, so no new data will be shared with JetBrains.

Do I need to keep the plugin installed after connecting?

Yes, if you want your progress to keep updating on LinkedIn. You can also share your level once and remove the plugin.

Can I connect multiple IDEs?

Yes. Each connected IDE gets its own statement on your profile.

Is the plugin free?

Yes, the plugin is free and works in IntelliJ IDEA, PyCharm, WebStorm, PhpStorm, Rider, GoLand, CLion, RustRover, and RubyMine, version 2025.3 or later. DataGrip isn’t supported. For the full list of level requirements, see the documentation.

Read the whole story
alvinashcraft
38 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

I’ve tested Ubuntu 27.04 ahead of its April release – and it will wow you

1 Share
I’ve been using Ubuntu 27.04, and the speed boost is noticeable. Here’s what else is coming.

Read the whole story
alvinashcraft
39 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

The Trust Layer: Securing Agentic AI with Docker AI Governance

1 Share

The Agent Trust Gap

The security problem changes once an AI agent can do more than answer a prompt. It can execute code, access files, connect to services, and call external tools. That creates a new security question for enterprises: how do you give an agent enough freedom to be useful without giving it more access than it actually needs? 

A model decision is not automatically an authorized action. That distinction becomes important the moment an agent can turn a model output into an action in a real system.

The answer can’t rely only on the model. Agent behavior can vary, while security controls need to be clear and enforceable. That means putting controls around the environment where the agent runs, what it can access, which tools it can use, and what happens when a policy allows or blocks an action. For a CISO, this creates a trust gap. Approving the use of AI agents means being able to answer more than whether the model is capable: what access does the agent have, where are those boundaries enforced, and what evidence is available afterward? The goal is to let teams adopt agents without making model behavior itself the security boundary.

Docker AI Governance approaches this through three areas: Sandbox Policies, MCP Tool Governance, and Audit + Visibility.

Together, they address three practical questions security teams need answered: Where can the agent operate? What can it do? And can we see what happened?

In this article, I use “trust layer” as shorthand for the infrastructure between what an agent wants to do and what the organization actually allows it to do. 

There is a related trust question too: what software artifacts are these agentic workflows building and using? Docker Hardened Images address that software supply-chain side of the problem, alongside the runtime controls discussed below.

image2
image3

Figure 1: The three layers of Docker AI Governance: Sandbox Policies, MCP Tool Governance, and Audit + Visibility. 

Sandbox Policies: Where Can the Agent Operate?

An agent needs enough access to get real work done. A coding agent may need to install packages, build containers, edit project files, or connect to external services. The security challenge is deciding where those actions are allowed before the agent starts taking them.

Docker Sandboxes give each agent an isolated microVM environment a lightweight virtual machine with its own Docker Engine, filesystem, and network. Docker AI Governance adds policy around that environment so security teams can control network and filesystem access centrally.

Network policies can allow or block specific domains, IP ranges, and ports. Filesystem policies control which host paths can be mounted into a sandbox and whether that access is read-only or read-write. These controls are enforced at the network proxy and filesystem mount layers rather than depending on the agent to follow an instruction.

For an organization, that means the same boundaries can follow developers across their sandboxes instead of being configured differently on every machine. Teams still get the access they need for their work, but an individual agent cannot simply expand those boundaries on its own.

A developer can check the effective boundary before starting the agent:

$ sbx policy check network api.anthropic.com 
Allowed: api.anthropic.com

$ sbx policy check network blocked.example.com
Denied: blocked.example.com

The important part is that the result comes from the active policy, not from an instruction the agent is expected to follow. 

This answers the first governance question: Where can the agent operate?

MCP Tool Governance: What Can the Agent Do?

Once an agent has a controlled place to run, the next question is what it should be allowed to do through external tools.

MCP (Model Context Protocol) gives agents a common way to connect to external tools, services, and capabilities, but that also expands what an agent can act on. For enterprise use, making a tool available should not automatically mean every agent can use it.

Docker AI Governance puts policy around MCP activity handled through Docker’s MCP Gateway. Administrators can control which MCP servers may be registered and what agents can do through them, including tool calls, resources, prompts, and approval requirements. These organization policies are written in Cedar, a policy language used to express authorization rules. When MCP policy enforcement is active, governed requests are denied unless a matching policy permits them. For example, a policy can permit read-only tool calls for a specific registered MCP server:

permit (principal, action == MCP::Action::"invokeTool", resource)
when {
  resource in MCP::Server::"example" &&
  resource.readOnly == true
};

Here, readOnly comes from the MCP tool’s annotations. Those annotations are supplied by the server and are advisory, so this example relies on metadata provided by that server.

This makes tool access an explicit policy decision rather than something left to each agent or developer to configure independently. A team can be given access to the tools it needs, while other servers or actions remain unavailable. Policies can also require confirmation for specific tool calls when an action needs an additional checkpoint.

One boundary is worth making clear: MCP policies apply to activity handled by Docker’s MCP Gateway. If an agent connects directly to a remote MCP server from inside a sandbox, that connection falls under the sandbox’s network policy instead.

With the environment constrained and tool access governed, we can answer the second question: What can the agent do?

Audit + Visibility: Can We See What Happened?

Setting a policy is only part of the job. Security teams also need to know when that policy was applied, what action triggered it, and whether the action was allowed or denied.

Docker AI Governance records sandbox policy decisions and sandbox session events as structured audit records. Each record captures details such as the principal, action, target, decision, and time. The records contain governance metadata rather than the contents of prompts or agent responses.

Audit records can be kept locally or delivered to the cloud. With cloud delivery enabled, teams can search the organization-wide record, export it for further analysis, or forward events into existing SIEM (security information and event management) workflows. 

Denied actions are especially useful. A team can see not only that an action failed, but that a governance rule blocked it and why. Allowed decisions matter too: they provide a record of how policy was applied while the agent was working.

Current audit coverage includes Docker Sandboxes policy decisions and sandbox session events. The same schema can support additional Docker AI sources as they become available.

That closes the third part of the governance loop: Can we see what happened?

A Trusted Software Supply Chain: Docker Hardened Images

AI Governance controls access around the agent at runtime. There is a separate question that matters to the workflows those agents participate in: what container images and software artifacts are they building, testing, or deploying?

Docker Hardened Images provide minimal, secure, and production-ready container images, Helm charts, and system packages maintained by Docker.

In practical terms, this gives teams evidence about what is inside an image and how that image was produced. Docker Hardened Images include signed SBOMs, VEX information, cryptographic signatures, and SLSA Build Level 3 provenance. Instead of simply trusting where an image came from, teams can inspect what is inside it and verify information about how it was built.

For organizations with additional compliance requirements, Docker also provides FIPS-enabled and STIG-ready variants through relevant DHI offerings. These capabilities sit alongside the broader DHI security and supply-chain controls rather than making any single standard the foundation by itself.

AI Governance and Docker Hardened Images solve different parts of the trust problem. Governance controls the authority an agent has while it works; DHI helps establish trust in the container artifacts that the workflow depends on.

image1

Figure 2: Docker Hardened Images combine minimal container images with signed supply-chain metadata and verifiable build provenance.

Putting the Three Layers Together

Consider a developer using a coding agent to investigate an issue, update a service, and use an approved internal tool along the way.

The agent begins inside a Docker Sandbox. It can work with the project and run the commands needed for the task, but its access is still bounded by policy. If it tries to reach a network destination or mount a host path that the organization has not allowed, the applicable sandbox policy can block that access.

Now suppose the agent needs an MCP tool to look up information from another service. The request goes through Docker’s MCP Gateway, where organization policy determines whether that server and tool are permitted. A routine lookup might be allowed, while a more sensitive tool call could require confirmation or remain unavailable altogether.

For governance activity currently covered by AI Governance Audit Logs, Docker records the policy decision and relevant session metadata. Security teams can see who initiated the activity, what policy-controlled action was evaluated, and whether it was allowed or denied. Those records can then feed the organization’s existing monitoring and SIEM workflow. 

If that same agent builds or tests a containerized application, the software entering the workflow matters too. Docker Hardened Images provide a more verifiable software foundation for that workflow, while AI Governance controls what the agent is authorized to do at runtime.

The model is still making decisions about how to complete the task. What changes is the authority around those decisions. The agent can work autonomously inside the boundaries the organization has defined, while access outside those boundaries remains a policy decision.

That is the practical value of the three layers working together:

Sandbox Policies define where the agent can operate.

MCP Tool Governance defines what tools it can use.

Audit + Visibility shows how governed activity was handled.

Taken together, the pattern is straightforward: define the boundary, check it before the agent starts working, enforce it while the agent is running, and use the resulting audit trail to understand what happened. If a boundary needs to change, the policy changes, not the expectation that the model will simply behave differently.

Autonomy Without Unbounded Authority

The challenge with agentic AI is not simply that agents can make decisions. It is that those decisions can now lead directly to actions.

That makes the boundary around the agent just as important as the model itself. Docker AI Governance addresses that boundary through Sandbox Policies, MCP Tool Governance, and Audit + Visibility: controlling where agents can operate, what tools they can use, and how governed activity is recorded.

Docker Hardened Images address a related supply-chain concern by helping teams work with smaller, verifiable container artifacts. 

The goal is not to remove autonomy from agents. It is to make sure autonomy does not automatically come with unlimited authority.

As agents take on more real work, that distinction will matter more and more.

Learn more

Read the whole story
alvinashcraft
39 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

An Agent Can Only Use What It Can Find

1 Share

I keep having the same experience when I re-profile API providers for APIs.io. A provider is sitting somewhere in the middle of the pack, and when I go back and look a little harder, I find a whole bunch of stuff they already did. OpenAPI definitions sitting in a GitHub repository. An MCP server or two. A trust center. Rate limit documentation. A healthy stack of SDKs. None of it is linked from anywhere an agent is going to look first, so none of it was counted. Then the score moves, and the provider didn’t ship a single new thing.

That is the lesson I want every API provider to hear right now. The cheapest agent readiness work you will ever do is making what you already have findable.

The agent doesn’t go digging

A human developer will poke around. They’ll search GitHub, read a blog post from three years ago, ask in a Slack channel, and eventually stumble on the OpenAPI that lives in some repo named after an internal project. An agent isn’t going to do that. An agent looks at a handful of predictable places, and if it doesn’t find what it needs there, it moves on to whatever it can find, which is usually someone else.

My scoring works the same way, on purpose. The Kin Score and the agent readiness layer are an expression of what the agents can find. If I have to go on a scavenger hunt to discover your contract, I’m not measuring your agent readiness, I’m measuring my own patience.

What the catalog says

Here is where things stand across the catalog today. The Machine-Readable Contract dimension, a public OpenAPI, is the single largest award in agent readiness at 18 of 153 points. 13,809 providers publish one, which is 33.6% of the 41,129 providers it applies to. That is a respectable number, but it means two thirds of the market has nothing an agent can drive programmatically, at least nothing we could find.

Now look at the front door. The Well-Known Catalog dimension asks whether a provider publishes an RFC 9727 /.well-known/api-catalog, the canonical machine entry point an agent hits first. 1,974 providers do. That is 4.8%. So there are thousands of providers with a contract somewhere, and only a fraction of them telling an agent where it is.

Inventory before you build

When a product leader asks me what to do about agents, they usually want to talk about new things. A new MCP server. A new AI assistant in the portal. Before any of that, I tell them to do an inventory. Go find everything you already publish:

  • OpenAPI, AsyncAPI, JSON Schema and GraphQL definitions, wherever they live.
  • MCP servers, official or community, hosted or in a repo.
  • SDKs and CLIs across every language.
  • Rate limit, pricing, terms, privacy and trust center pages.
  • Changelogs, status pages and support channels.

Then put all of it into one machine-readable index and serve it from your own domain. I’ve been pushing APIs.json for more than a decade for exactly this reason, and the IETF API catalog gives you a standard well-known location to hang it on. Pick one, point it at everything, and keep it current.

Your own domain is the source of truth

The other pattern I see is a provider whose contracts are perfectly findable, just not from them. They live in a third-party docs platform, a public GitHub org with no link back, or a community repo somebody else maintains. An agent has no way of knowing that any of that is authoritative. It needs to start at your domain and follow your links. If your domain doesn’t lead there, the trail goes cold.

This is also why a provider can’t argue a score up by emailing me links. I’m happy to look, and I’ll update the profile, but the next agent that comes along won’t have my email. Publish the link where the agent looks, and you fix it for everyone at once.

Cheap, boring and high leverage

None of this is glamorous. It’s an index file, a few links in a header, a well-known path and a little discipline about keeping it all up to date. But I’ve watched it move a provider further than months of feature work would, because the work was already done. It just wasn’t visible.

An agent can only use what it can find. Before you build anything new for agents, make sure they can find what you already built.


Read the whole story
alvinashcraft
39 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

How to inspect, test, and debug MCP servers in Red Hat OpenShift console

1 Share

To help platform teams secure, manage, and scale AI agent systems behind a single endpoint, Red Hat Connectivity Link 1.5 brings the Model Context Protocol (MCP) gateway from Technology Preview to General Availability, and the new Connectivity Link MCP gateway console plug-in in Developer Preview. Powered by an Envoy-based proxy, the MCP gateway delivers enterprise-grade protection and traffic management for back-end MCP servers.

The post How to inspect, test, and debug MCP servers in Red Hat OpenShift console appeared first on Red Hat Developer.

Read the whole story
alvinashcraft
40 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories