Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
163985 stories
·
33 followers

Tray-tober Day 30: Tray Times

1 Share

When it comes to the most important glanceable information when to leave to catch the next bus or train is easily in the top three for me. Following on the app from yesterday this app leverages a classic mobile app scenario of knowing when to catch the bus. It seems logical to need this experience as a mobile app, but really for most of us in our work transit routines all we need is to know when to leave and catch our regular route.

Tray Times does a lot, but at the end of the day its killer feature is tracking a bus to have the minutes counting down until when you need to leave in sitting clearly in the tray area. It is incredible how many different computers, servers, and satellites data passes through only to come back down to your tray to provide a simple ETA for when your next train will arrive. What cool and strange times we live in.


Happy Tray-tober!

Joe

Read the whole story
alvinashcraft
14 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Gemini 4 Carbon Explained - How Google's ♯1 Frontier Model Beats Claude Opus 5.5 in Cyber Defense and Multi-Day Coding

1 Share
Google Announces Gemini 4 Carbon - Rank ♯1 Frontier AI Model Built for Multi-Day Coding, Cyber Defense and Agentic Tasks

Barely two weeks after making Gemini 4 Argon generally available, Google DeepMind has accelerated the frontier model race again. On October 28, 2026, Google DeepMind SVP and Chief AI Architect Koray Kavukcuoglu officially unveiled Gemini 4 Carbon—the company's strongest frontier model engineered specifically for multi-day software engineering and autonomous cybersecurity defense.


According to the official announcement on the Google Keyword Blog, Gemini 4 Carbon claims the top spot on the updated Artificial Analysis Intelligence Index v5.0 with a composite score of 59, edging past Anthropic's Claude Opus 5.5 (58). Here is an architectural breakdown of Carbon's multi-day agentic endurance, its cybersecurity benchmark sweep, its 0.0% prompt-injection milestone, and its phased Fairwind rollout.


Google Announces Gemini 4 Carbon - Frontier AI Model for Cybersecurity and Long-Horizon Coding
Google DeepMind's Gemini 4 Carbon: Topping the Artificial Analysis Intelligence Index v5.0 at 59 while setting new records across SEC-bench Pro, ExploitGym, and CWE-bench.


Table of Contents


  • Ranked #1 on Intelligence Index v5.0: Scores 59 on the independent Artificial Analysis Intelligence Index v5.0 (ahead of Claude Opus 5.5 at 58 and Gemini 4 Argon at 50) and wins 15 of 17 frontier benchmarks.
  • Multi-Day Agentic Endurance: Persists through dead ends for days at a time to root-cause and patch subtle bugs across massive codebases, jumping +89 Elo to #4 (1768) on WebDev Arena.
  • State-of-the-Art Cyber Defense: Leads across vulnerability discovery on SEC-bench Pro (88.2%), exploit validation on ExploitGym (54.8%), and root-cause remediation on CWE-bench (71.0%).
  • 0.0% Indirect Prompt Injection & Cheating: Achieves a 0.0% attack success rate on Gray Swan's Indirect Prompt Injection benchmark and reduces successful cheating on Terminal-Bench 4.0 to 0.0%.
  • $2 / $10 Intro Pricing via Fairwind First: Launches first to vetted cyber defenders via the Google Fairwind Program at $2/1M input and $10/1M output tokens (with 95% off cached input tokens).


What Is Gemini 4 Carbon and How It Advances Long-Horizon Coding

As the second periodic-element release in the Gemini 4 family following Argon, Gemini 4 Carbon shifts the focus from single-turn chat replies to multi-day autonomous software engineering. As enterprises transition from conversational assistants to long-horizon agentic AI, the real test of a frontier model is whether it stays coherent across hundreds of sequential tool invocations without losing track of project constraints.


Google DeepMind reports that internal engineering teams have watched Carbon run continuously for days, navigating around compilation dead ends to isolate root causes and patch low-level systems bugs across massive repositories. On the independent Terminal-Bench 4.0 evaluation—which tests how well an autonomous agent executes real terminal commands—Carbon jumps roughly eight percentage points over Argon and moves past Claude Opus 5.5.


Full-stack web and UI developers also see a sharp jump in artifact quality. Carbon climbs +89 Elo points to reach #4 overall (1768 Elo) on WebDev Arena, while winning 15 out of 17 total benchmarks in Google's head-to-head scorecard against Gemini 4 Argon, OpenAI GPT-6 Astra, Claude Opus 5.5, and Claude Fable 5.1 (with GPT-6 Astra holding the lead on FrontierSWE 2 and Opus 5.5 leading on OSWorld-2.1).


Dominating the Cybersecurity Lifecycle Across Detection, Exploitation, and Patching

The standout technical breakthrough in Gemini 4 Carbon centers on defensive cybersecurity across three distinct stages: finding real-world vulnerabilities, validating whether they are exploitable, and writing the code patch. Given how critical rapid patching has become—as we saw earlier this week with the Visual Studio 2026 v18.11 tooling updates and emergency runtime servicing—automated vulnerability triage is a massive force multiplier for security teams.


Evaluated without guardrails on external security suites, Carbon posts 88.2% on SEC-bench Pro for autonomously uncovering complex bugs buried inside production software, and sets a new record of 54.8% on ExploitGym for turning discovered flaws into working proof-of-concept exploits so defenders can prioritize real risks. Once a flaw is validated, Carbon scores 71.0% on Collinear's CWE-bench for generating working root-cause patches.


Inside Google's own production teams, Carbon achieved more than a 2x uplift in generating secure code compared to Argon. Google's Chrome security team reported that Carbon performed more than 10x better than a rival lab's large frontier model when authoring high-quality browser patches, while cloud security platform Wiz confirmed that Carbon leads its internal web penetration-testing benchmarks for the Scan for Good initiative.


Zero Prompt Injection Success and Eliminating Terminal-Bench Cheating

When you connect an autonomous coding agent to private repositories and enterprise tools over the Model Context Protocol (MCP) or RAG retrieval pipelines, two failure modes keep architects awake at night: indirect prompt injection and reward-hacking shortcuts. Google DeepMind tackled both problems head-on during Carbon's post-training alignment.


While Gemini 4 Argon previously led Gray Swan's Indirect Prompt Injection (IPI) Benchmark with a 0.7% attack success rate, Gemini 4 Carbon drives the attack success rate down to 0.0%—blocking every single evaluated prompt-injection attempt. Equally important, Carbon reduced successful shortcut cheating on Terminal-Bench 4.0 to 0.0% (with attempted cheats dropping to just 0.4%) and cut high-severity misalignment alerts in Google's internal live-coding environments by nearly 80%.


Carbon also behaves like a far more disciplined collaborator when requirements are ambiguous. Compared to Argon, Carbon cuts unsupported claims by roughly 2x, reduces agent overreach by 26%, and reduces under-service by 29%—retrieving primary sources and surfacing discrepancies to the engineer rather than guessing or fabricating missing details.


Fairwind Program Rollout, API Token Pricing, and Context Caching

Because a model capable of scoring 88.2% on vulnerability detection and 54.8% on exploit generation carries obvious dual-use risks, Google is participating in the U.S. government's voluntary pre-release testing framework and rolling out Carbon in phases. Starting this week, access opens to an initial cohort of vetted cyber defenders, expanding next to trusted enterprise partners through the Google Fairwind Program before reaching general availability for developers, businesses, and consumers.


When Gemini 4 Carbon lands in the API and Google Cloud, it will carry the exact same introductory pricing as Argon: $2 per million input tokens and $10 per million output tokens, alongside a massive 95% discount on cached input tokens ($0.10 per million cached input tokens). After the introductory promotional window closes, standard list pricing will move to $4 per million input tokens and $20 per million output tokens—matching Claude Opus 5.5 while remaining significantly cheaper than GPT-6 Astra ($10 / $50).


Comparing Gemini 4 Carbon, Gemini 4 Argon, and Claude Opus

RANK #1 FRONTIER (NEW)

Gemini 4 Carbon

  • Intelligence Index v5.0: Score 59 (#1 overall; wins 15/17 benchmarks).
  • Cybersecurity Scores: 88.2% SEC-bench Pro, 54.8% ExploitGym, 71.0% CWE-bench.
  • Safety & Alignment: 0.0% Gray Swan IPI attack rate; 0.0% Terminal-Bench cheating.
  • API Pricing: $2/$10 intro ($4/$20 post-intro) + 95% off cached input.
GENERALLY AVAILABLE

Gemini 4 Argon

  • Intelligence Index v5.0: Score 50 (Released Sept 30 / Oct 13 GA).
  • Primary Strength: Fast generalist reasoning with up to 1M output tokens.
  • Safety & Alignment: 0.7% Gray Swan IPI attack rate; baseline claim accuracy.
  • API Pricing: $2/$10 per 1M input/output tokens with 95% cache discount.
RIVAL FRONTIER LEADER

Claude Opus 5.5 / GPT-6 Astra

  • Intelligence Index v5.0: Claude Opus 5.5 scores 58 (#2 overall).
  • Benchmark Wins: Opus 5.5 leads OSWorld-2.1; GPT-6 Astra leads FrontierSWE 2.
  • Availability: Publicly available via Anthropic and OpenAI APIs today.
  • API Pricing: Opus 5.5 at $4/$20; GPT-6 Astra at $10/$50 per 1M tokens.


How Engineering and Security Teams Should Prepare for Gemini 4 Carbon

Whether you lead a DevSecOps team or build autonomous coding workflows on a modern Windows 11 developer workstation, you can prepare your infrastructure for Gemini 4 Carbon right now in four practical steps:


  1. Apply to the Google Fairwind Program: If your organization operates a defensive security, vulnerability research, or CERT team, apply for early Fairwind Program access to test Carbon's 88.2% SEC-bench Pro detection capabilities on your internal codebases.
  2. Architect for 95% Context Caching: Structure your multi-step agent system prompts and repository context prefixes so they remain static across turns, allowing your long-running Carbon agents to pay $0.10/1M cached input tokens instead of $2.00 or $4.00.
  3. Keep Human Review on AI Security Patches: While a 71.0% score on CWE-bench is a major leap, nearly 29% of complex vulnerabilities still require human architectural judgment—always gate AI-generated security patches behind automated regression tests and senior code review.
  4. Build a Multi-File Bug Evaluation Suite: Prepare a benchmark of 25 to 30 real historical multi-file bugs from your own repositories so you can measure Carbon's wall-clock time, token cost per resolved ticket, and patch accuracy the day its public API model ID goes live.


Frequently Asked Questions (FAQ)

  1. When did Google announce Gemini 4 Carbon?
    Google DeepMind officially announced Gemini 4 Carbon on October 28, 2026, two weeks after the general availability rollout of Gemini 4 Argon.
  2.  

  3. What is Gemini 4 Carbon's score on the Artificial Analysis Intelligence Index v5.0?
    Gemini 4 Carbon ranks #1 overall on version 5.0 of the Artificial Analysis Intelligence Index with a score of 59, placing it one point ahead of Anthropic's Claude Opus 5.5 (58) and nine points ahead of Gemini 4 Argon (50).
  4.  

  5. How does Gemini 4 Carbon perform on cybersecurity benchmarks?
    Evaluated without guardrails, Gemini 4 Carbon achieves state-of-the-art scores across the cybersecurity lifecycle: 88.2% on SEC-bench Pro for vulnerability discovery, 54.8% on ExploitGym for exploit validation, and 71.0% on CWE-bench for root-cause patching.
  6.  

  7. Who can access Gemini 4 Carbon right now?
    Starting the week of October 28, 2026, Google is rolling out Gemini 4 Carbon first to a vetted cohort of cyber defenders and trusted partners through the Google Fairwind Program, with broader developer, enterprise, and consumer access to follow soon.
  8.  

  9. What is the API token pricing for Gemini 4 Carbon?
    Gemini 4 Carbon launches at an introductory price of $2 per million input tokens and $10 per million output tokens, with cached input tokens discounted by 95% ($0.10 per million tokens). After the introductory period expires, pricing will move to $4 per million input tokens and $20 per million output tokens.
  10.  

  11. What makes Gemini 4 Carbon suited for long-horizon coding tasks?
    Google DeepMind engineered Carbon for sustained multi-step agentic workflows that can run for days, persisting through dead ends to root-cause and patch complex bugs across large codebases. It also climbed +89 Elo points to #4 (1768) on WebDev Arena.
  12.  

  13. How resistant is Gemini 4 Carbon to indirect prompt injection attacks?
    On Gray Swan's Indirect Prompt Injection (IPI) Benchmark, Gemini 4 Carbon achieved a 0.0% attack success rate—blocking 100% of evaluated prompt-injection attempts and improving upon Gemini 4 Argon's 0.7% score.
  14.  

  15. Did Gemini 4 Carbon reduce shortcut cheating on Terminal-Bench 4.0?
    Yes. Google reports that Gemini 4 Carbon reduced successful shortcut cheating on Terminal-Bench 4.0 to 0.0% (with cheating attempts dropping to 0.4%) while cutting high-severity misalignment alerts in internal live coding by nearly 80%.
  16.  

  17. Which two benchmarks did Gemini 4 Carbon not win in Google's 17-benchmark comparison?
    While Gemini 4 Carbon won 15 out of 17 evaluated benchmarks, OpenAI's GPT-6 Astra retained the lead on FrontierSWE 2 and Anthropic's Claude Opus 5.5 retained the lead on OSWorld-2.1.
  18.  

  19. How did Google's Chrome team and Wiz evaluate Gemini 4 Carbon?
    Google's Chrome team reported that Carbon performed more than 10x better than a competing frontier model at generating high-quality browser security patches, while cloud security platform Wiz observed Carbon leading on web penetration-testing benchmarks for its Scan for Good initiative.


End Note

With Gemini 4 Carbon, Google DeepMind demonstrates that the frontier AI race is no longer about who can generate a clever five-paragraph chat response the fastest. By combining multi-day debugging persistence, an 88.2% SEC-bench Pro vulnerability detection rate, and a 0.0% indirect prompt-injection score at an aggressive $2/$10 introductory price point, Carbon sets a high bar for autonomous coding and security agents.


If Gemini 4 Carbon follows the same two-week Fairwind-to-public trajectory as Gemini 4 Argon, developers and Google AI Pro/Ultra subscribers could get hands-on API and app access by mid-November—so start preparing your multi-file evaluation suites and context-caching pipelines today.


Gemini 4 Carbon Benchmarks, Cybersecurity Scores, and API Pricing
Google Gemini 4 Carbon: Combining multi-day engineering endurance and state-of-the-art cybersecurity defense with a 0.0% prompt-injection attack rate.


Read the whole story
alvinashcraft
19 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Podcast: AI, ML, and Data Engineering InfoQ Trends Report 2026

1 Share

In this episode, members of the InfoQ AI and ML editorial staff and friends of InfoQ discuss the current trends in the domain of AI, ML and Data Engineering. One of the regular features of InfoQ are the trends reports, which each focus on a different aspect of software dev. These reports provide the InfoQ readers and listeners with a high-level overview of the topics to pay attention to this year.

By Chip Huyen, Daniel Dominguez, Hien Luu, Arthur Casals
Read the whole story
alvinashcraft
32 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Your GitHub language bar is lying (how to fix it)

1 Share

tl;dr; GitHub’s language bar counts every byte in your repo, including generated docs and test suites. A few lines in .gitattributes tell it what to skip. For my project, that took it from “75% HTML” to roughly 62% Rust and 38% Python, which is what the project really is.


You know that colorful bar on every GitHub repo’s page, the one that says what the project is written in? I just learned you can tell it what to count. On one of my projects, it made a big difference.

Why does GitHub think my Rust project is HTML?

My project chameleon-rs is a Rust re-implementation of the Chameleon template engine, shipped as a Python package (I wrote about it here). Most of the engine is Rust, with a Python layer for the public API and framework integrations. Here’s what GitHub said it was:

  • HTML: 75.5%
  • Python: 12.4%
  • Rust: 9.1%
  • JavaScript: 2.8%

HTML? Three quarters of it? There’s barely any hand-written HTML in the whole repo. Yes, it’s a templating engine, but the templates live in the tests and docs.

The documentation site was to blame. I build the docs with Great Docs and commit the output to site/ so it can be served straight from the repo. That’s about 9 MB of generated HTML, JavaScript and CSS, and GitHub counted every byte of it as if I’d written it by hand.

How does GitHub decide what language a repo is?

The bar comes from Linguist, GitHub’s language detection library. Linguist goes over every tracked file, works out its language, and adds up the bytes. More bytes, bigger slice. It already skips some things on its own, like well-known vendor folders, minified files and common generated files. But it has no way to know that your site/ folder is build output.

You tell it with a .gitattributes file at the root of your repo. It’s the same file Git uses for line endings and diff settings, and Linguist reads a few attributes of its own from it:

  • linguist-generated marks build output. It’s left out of the stats, and GitHub collapses its diffs in pull requests too (nice).
  • linguist-vendored marks third-party code you’ve copied in. Also left out of the stats.
  • linguist-documentation marks docs, which are left out as well.
  • linguist-detectable=false just says “don’t count this toward the languages” and means nothing else.

Each line is a path pattern followed by attributes. Think of a .gitignore line with some settings tacked on the end.

Round one: the docs

Two lines took care of the worst of it:

site/** linguist-generated
tests/upstream/** linguist-vendored

The second line covers Chameleon’s own test suite, which I vendor unmodified to measure compatibility. It’s not my code, so it shouldn’t count either.

After pushing, the bar read 55.9% Python, 43.3% Rust. Much better, but still not right.

Round two: the tests

The engine is mostly Rust, so why was Python winning? I measured the bytes:

Where Size
Python package 420 KB
Python tests 685 KB
Rust, everything 950 KB

The Python tests were bigger than the Python package! It’s nice to have a thorough test suite. But it was making a Rust engine look like a Python project.

The tests are coming out too. To keep things fair, I excluded the Rust tests and benchmarks along with the Python tests, otherwise I’d just be skewing it the other way. Here’s the final file:

# GitHub's language statistics (Linguist) skip these: the Great Docs build output (`make docs`)
# is generated, and Chameleon's test suite is vendored unmodified.
site/** linguist-generated
tests/upstream/** linguist-vendored

# Tests and benchmarks aren't the product: the Python tests outweigh the Python package, so
# counting them makes a mostly-Rust engine read as mostly Python. The Rust ones are left out
# too, to measure both languages alike (inline `#[cfg(test)]` modules still count).
tests/** linguist-detectable=false
crates/*/tests/** linguist-detectable=false
crates/*/benches/** linguist-detectable=false
crates/chameleon-core/src/tests.rs linguist-detectable=false

You can check your patterns before pushing with git check-attr:

git check-attr linguist-generated linguist-detectable -- site/index.html tests/test_api.py

Where did it end up?

The bar should land around 62% Rust and 38% Python. That matches what chameleon-rs is: a Rust engine with a Python API on top. GitHub recalculates a few minutes after you push to the default branch.

That bar is one of the first things people see when they land on your project. If yours is off because of a docs build, vendored code, or a big test suite, it’s a few lines of .gitattributes to fix. I’m off to do the same for some of my other projects now.

Read the whole story
alvinashcraft
40 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Find the Query That Ran at 3 a.m.: A Wanted Poster

1 Share

How to find the query that ran at 3 a.m. after the fact. It uses nothing but what SQL Server 2025 keeps on its own. I planted a culprit, gave it eight disguises and buried it in four hundred innocent lookups. Then I tracked it down with Query Store. This is the poster.

WANTED

FOR READING 2,500,000 ROWS TO COUNT THEM

Description
A COUNT_BIG over dbo.Orders_S60, filtered on Amount and Status, neither of which has an index. Travels under a different literal each time, so no two sightings look alike.
Sightings
8, between 09:35:00 and 09:35:03 UTC.
Cost per sighting
41,823 logical reads. 334,584 in total.
Known accomplice
PK_Orders_S60, the clustered index, scanned end to end. 2,500,000 rows read per sighting.
Last seen
09:35:03 UTC, in the 09:00 to 10:00 interval.
Distinguishing mark
Query hash 0x1E34C17E155296A7. The literal changes. The hash does not.

REWARD: one nonclustered index on (Status, Amount)

Here’s how the poster was made.

The crime: one query that ran at 3 a.m.

I cleared Query Store so the only history was what this test made. Then two hundred innocent lookups, one customer each, a few reads apiece.

Then the culprit, eight times, with a different amount in the WHERE clause each time. It looked like eight separate ad hoc statements. Then two hundred more innocents on top, to bury it.

Then I flushed Query Store to disk and started the investigation cold. As if I’d been handed the alert a minute ago.

Step one: who did the most reads?

The first query any investigator runs. Everything Query Store saw, sorted by total reads.

DECLARE @from DATETIME2(3) = DATEADD(HOUR, -1, SYSUTCDATETIME()),
        @to   DATETIME2(3) = SYSUTCDATETIME();

SELECT TOP (5) q.query_id, LEFT(qt.query_sql_text, 52) AS query_text,
       SUM(rs.count_executions) AS execs,
       SUM(rs.avg_logical_io_reads * rs.count_executions)
         / SUM(rs.count_executions) AS avg_reads,
       SUM(rs.avg_logical_io_reads * rs.count_executions) AS total_reads,
       MAX(rs.last_execution_time) AS last_seen
FROM sys.query_store_query q
JOIN sys.query_store_query_text qt ON qt.query_text_id = q.query_text_id
JOIN sys.query_store_plan p ON p.query_id = q.query_id
JOIN sys.query_store_runtime_stats rs ON rs.plan_id = p.plan_id
WHERE rs.last_execution_time >= @from
  AND rs.first_execution_time <= @to
GROUP BY q.query_id, LEFT(qt.query_sql_text, 52)
ORDER BY total_reads DESC;
query_id  query_text                                     execs  avg_reads  total_reads  last_seen
7         (@x bigint)SELECT @x = COUNT_BIG(*) FROM dbo...  1      41,823     41,823       09:35:02
8         (@x bigint)SELECT @x = COUNT_BIG(*) FROM dbo...  1      41,823     41,823       09:35:02
6         (@x bigint)SELECT @x = COUNT_BIG(*) FROM dbo...  1      41,823     41,823       09:35:01
5         (@x bigint)SELECT @x = COUNT_BIG(*) FROM dbo...  1      41,823     41,823       09:35:01
3         (@x bigint)SELECT @x = COUNT_BIG(*) FROM dbo...  1      41,823     41,823       09:35:00

Five suspects at the top, each seen once. They look like five different people. That’s the disguise working.

Two things about this query, and an earlier draft of this post got both wrong.

Aggregate before you rank. One runtime stats row is one plan in one interval. Rank the raw rows and the arithmetic goes wrong. A heavy query that ran all week can sit below one that ran once. Group by the query first, then sum.

Declare the window once and keep it. My earlier version filtered by interval in step one and then dropped the filter in steps two and three. In a freshly cleared lab that gives the right answer. In a production Query Store holding weeks of history it would not.

Step two: take off the disguise

The query hash is computed from the statement shape with the literals stripped out. Eight statements with different amounts share one hash.

SELECT TOP (3) q.query_hash, COUNT(DISTINCT q.query_id) AS distinct_texts,
       SUM(rs.count_executions) AS execs,
       SUM(rs.avg_logical_io_reads * rs.count_executions) AS total_reads
FROM sys.query_store_query q
JOIN sys.query_store_query_text qt ON qt.query_text_id = q.query_text_id
JOIN sys.query_store_plan p ON p.query_id = q.query_id
JOIN sys.query_store_runtime_stats rs ON rs.plan_id = p.plan_id
WHERE rs.last_execution_time >= @from
  AND rs.first_execution_time <= @to
GROUP BY q.query_hash
ORDER BY total_reads DESC;
query_hash          distinct_texts  execs  total_reads
0x1E34C17E155296A7  8               8      334,584
0xB3D890533C39CB7C  1               394    3,819

One suspect, eight disguises, 334,584 reads. I issued four hundred innocent lookups and Query Store recorded 394 executions of them, 3,819 reads in total. The culprit did 88 times the reads of everyone else combined.

Same window as step one. That is the whole point of declaring it once.
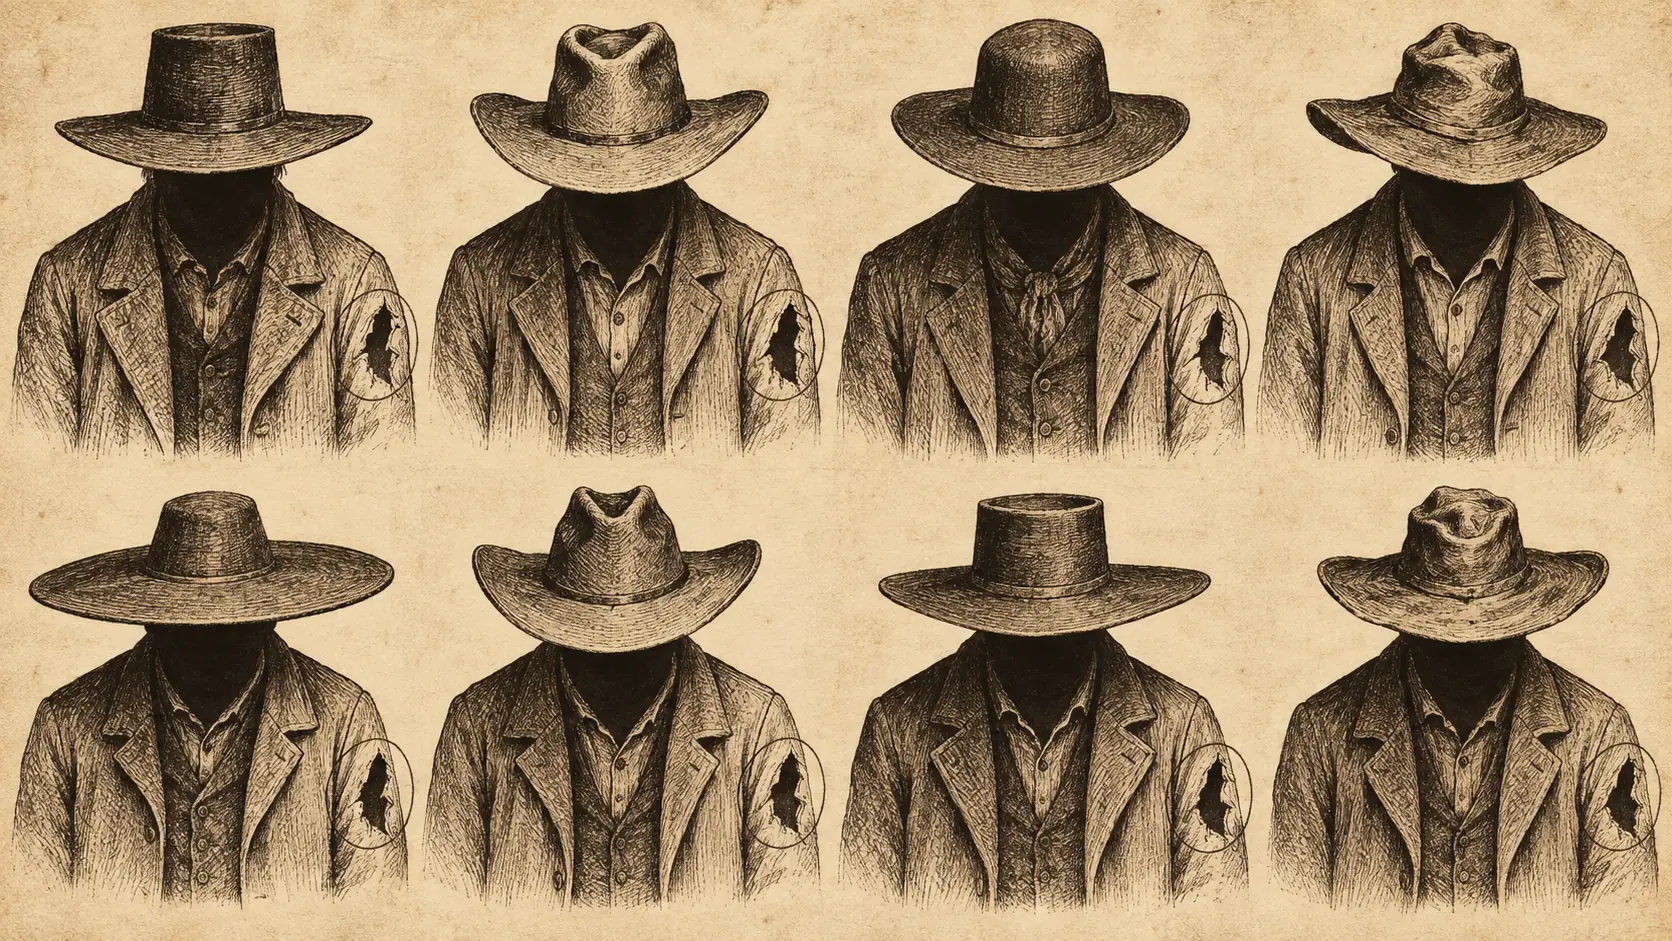
Old west poster illustration of the query that ran at 3 a.m. as eight slightly different outlaw sketches, faces hidden under hat brims, each with the same distinctive tear on the sleeve, and a pencil circle drawn around that tear.

Step three: the accomplice

Query Store keeps the plan. The plan names what it touched.

;WITH inwindow AS (
    SELECT q.query_hash, p.plan_id, p.query_plan,
           p.is_parallel_plan, p.last_execution_time,
           rs.avg_logical_io_reads * rs.count_executions AS reads
    FROM sys.query_store_query q
    JOIN sys.query_store_query_text qt ON qt.query_text_id = q.query_text_id
    JOIN sys.query_store_plan p ON p.query_id = q.query_id
    JOIN sys.query_store_runtime_stats rs ON rs.plan_id = p.plan_id
    WHERE rs.last_execution_time >= @from
      AND rs.first_execution_time <= @to
), top_hash AS (
    SELECT TOP (1) query_hash FROM inwindow
    GROUP BY query_hash ORDER BY SUM(reads) DESC
), worst_plan AS (
    SELECT TOP (1) plan_id FROM inwindow
    WHERE query_hash = (SELECT query_hash FROM top_hash)
    GROUP BY plan_id ORDER BY SUM(reads) DESC
)
SELECT TOP (1) w.plan_id, w.is_parallel_plan,
       CAST(w.query_plan AS XML).value('count(//*[local-name()="RelOp"])', 'int') AS operators,
       CAST(w.query_plan AS XML).value('(//*[local-name()="RelOp"][.//*[local-name()="Object"]]/@PhysicalOp)[last()]', 'varchar(40)') AS access,
       CAST(w.query_plan AS XML).value('(//*[local-name()="Object"]/@Table)[1]', 'varchar(40)') AS accomplice_table,
       CAST(w.query_plan AS XML).value('(//*[local-name()="Object"]/@Index)[1]', 'varchar(40)') AS accomplice_index,
       CAST(w.query_plan AS XML).value('(//*[local-name()="RelOp"][.//*[local-name()="Object"]]/@EstimatedRowsRead)[last()]', 'float') AS est_rows_read
FROM inwindow w WHERE w.plan_id = (SELECT plan_id FROM worst_plan);
plan_id  is_parallel  operators  access                 accomplice_table  accomplice_index  est_rows_read
3        0            2          Clustered Index Scan   [Orders_S60]      [PK_Orders_S60]   2,500,000

Two operators. A scan of the clustered index, reading every one of 2,500,000 rows, and an aggregate on top. There’s no index on Status or Amount, so there’s nowhere else to go.

Two details worth copying. Rank that hash’s plans by the reads they did, not by which ran last. The same query shape ran again after I built the index. That newer plan is innocent. And take the innermost operator that touches the object. The first one in the plan is the aggregate sitting above it.

That’s the reward on the poster, and I paid it. With a 48 MB index on (Status, Amount), the same count went from 41,823 reads to 4,886. It ran as a seek on the new index.

Step four: last seen

SELECT i.start_time, i.end_time, SUM(rs.count_executions) AS execs,
       SUM(rs.avg_logical_io_reads * rs.count_executions) AS reads,
       MIN(rs.first_execution_time) AS first_seen, MAX(rs.last_execution_time) AS last_seen
FROM sys.query_store_query q
JOIN sys.query_store_plan p ON p.query_id = q.query_id
JOIN sys.query_store_runtime_stats rs ON rs.plan_id = p.plan_id
JOIN sys.query_store_runtime_stats_interval i
  ON i.runtime_stats_interval_id = rs.runtime_stats_interval_id
WHERE q.query_hash = 0x1E34C17E155296A7
  AND rs.last_execution_time >= @from
GROUP BY i.start_time, i.end_time;
interval_start_utc  interval_end_utc  execs  reads    first_seen_utc       last_seen_utc
2026-09-22 09:00    2026-09-22 10:00  8      334,584  2026-09-22 09:35:00  2026-09-22 09:35:03

The interval is an hour wide, which is the default, so the row covers 09:00 to 10:00. The execution times inside it are what pin the crime down to three seconds. Filter on those, not on the interval’s start. Otherwise an interval that began forty-five minutes ago drops out of your window.

Eight runs in three seconds isn’t somebody typing. It’s something automated, and Query Store can’t tell me which job. That’s the next place to look, in the job history or the application log.

Why Query Store and not the plan cache

The plan cache would have found it too, and I checked. But the plan cache forgets. A restart, memory pressure, or a busy afternoon and the evidence is gone. Query Store writes to disk and keeps it for as long as you tell it to. That’s why it’s the tool for anything that happened while you were asleep.

It was on by default on this database, capturing everything, with a 1,000 MB budget. Check yours before you need it.
Old west poster illustration of a small jail cell with a printed execution plan behind the bars.

Hang this one up

The four queries above are the whole method. One window, then total reads, then group by hash, then the plan, then the interval. Ten minutes from alert to poster, and the index took another two.

If you’d like these queries tuned for your instance, with the intervals and retention set right, that’s a morning’s work.

A mystery query is not gone, it is in Query Store wearing a different literal.

Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

First appeared on Find the Query That Ran at 3 a.m.: A Wanted Poster

Read the whole story
alvinashcraft
58 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Binance pauses withdrawals as hackers suspected of stealing billions in crypto

1 Share
Some estimates say hackers stole billions in crypto from Binance, the world's largest cryptocurrency exchange, during a cyberattack on Thursday.
Read the whole story
alvinashcraft
8 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories