Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164307 stories
·
33 followers

How to Debug and Validate HTML: A Practical Workflow

1 Share

Here is how to debug and validate HTML: reproduce the fault, inspect the source, fix the first useful validation error and try the page again. Do not stop at a passing report. The markup may be valid while a link still takes someone to the wrong place. Debugging means finding why that happened.

Work through the broken example below with a copy of the file beside you. There is a repaired version to compare it with, followed by commands you can reuse in a project. Save the original before editing. Otherwise it is surprisingly easy to forget which of several changes fixed the fault.

Workflow from reproducing an HTML problem through source inspection, validation, repair and browser testing
Use validation to find markup problems, then repeat the task that originally failed.

How to debug and validate HTML without guessing

Identify what failed. Write this down as the very first part of your report.

If you went to “See Materials” and nothing happened then you have a specific thing to do again. A report saying only “the website was broken” will leave the person who is going to fix it trying to figure out if they need to check the HTML, CSS, JavaScript, or the server. Include the address so someone else may find the same location on your site. The local version of workshop.html (i.e., on your computer) could be different than the published version of the page.

Test the same action again after reloading. If it does not fail until you have clicked some other button, include those steps in your documentation too. Another person should be able to get back to where you were.

Before you start editing anything in the markup, make certain you are viewing your most current work. Save all changes and then reload. Locate a unique word in your previous edit. Does it exist? Check your filename and/or folder name. It is easy to waste a lot of time clearing cache issues because you forgot you put the updated file in the wrong place.

If you are still getting familiar with the document structure, our beginner’s guide to HTML provides a complete starting example. Understanding where head and body belong makes error messages much less mysterious.

Compare the source with the browser’s DOM

View Source shows the document source delivered for that page. The Elements or Inspector panel shows the current document tree, usually called the DOM. They answer different questions. Scripts can change the tree after loading, and the browser can repair some invalid nesting as it parses the source.

Take a section written inside a paragraph. That is not a permitted relationship. The browser can close the paragraph before starting the section, so the tree in the Inspector differs from the nesting you typed. The page may still look plausible. Resist the temptation to keep adding closing tags until its spacing changes.

Select the problem element in the Inspector and look around it: which element contains it, and what sits immediately before it? Compare that with the source. For a template-based site, you need the combined output. Two individually tidy components can still produce duplicate identifiers when they appear on the same page.

Delivered HTML source compared with the parsed browser tree and later script changes

The source and the current document tree can answer different debugging questions.

Debug and validate a small HTML example

Try finding the faults in this fragment before reading the explanation. Nothing in its visible wording announces a problem. That is why inspecting the rendered page alone is not enough. Run a markup check, but follow the link yourself as well. The two checks answer different questions.

<p id="materials"><h2>Materials</h2></p>
<section id="materials">Bring a notebook.</section>
<label for="email">Email</label>
<input id="address" type="email">
<a href="#supplies">See materials</a>

Start by fixing materials: it’s labeled as an “id” in two places, but IDs must be uniquely identifiable. Next check the label (email) versus the input (address). An h2 is nested inside a p, where it does not belong. Where is supplies? The link names supplies as its destination, but this fragment has no corresponding identifier. Make each fix for a good reason. Fix the materials id so that the id isn’t duplicated, fix the nesting since the source code is incorrect.

Finally, fix the link so that you’ve created the intended destination.

A corrected complete document

Save this version as workshop.html. Open it, follow the materials link, and select the email label. The link should move to the named section. The label should focus the corresponding field. This form demonstrates markup relationships; it does not send a message or save the address anywhere.

<!doctype html>
<html lang="en">
<head>
  <meta charset="utf-8">
  <meta name="viewport" content="width=device-width, initial-scale=1">
  <title>Workshop registration</title>
</head>
<body>
  <main>
    <h1>Workshop registration</h1>
    <p><a href="#materials">See materials</a></p>
    <section id="materials">
      <h2>Materials</h2>
      <p>Bring a notebook.</p>
    </section>
    <form>
      <label for="email">Email</label>
      <input id="email" name="email" type="email" autocomplete="email">
    </form>
  </main>
</body>
</html>

“Email” is the wording a reader sees. It does not, by itself, connect the label to the field. The matching for and id values do that. The jump link works through another matching pair: its fragment and the section identifier. These are useful relationships to check whenever a control looks right but behaves strangely.

Run a repeatable HTML validation check

For a local project, install a checker as a development dependency and keep its version in your project lockfile. This gives other contributors a repeatable starting point. The HTML-validate command-line documentation explains file targets, quoted glob patterns and rule options.

npm install --save-dev html-validate
npx html-validate workshop.html

First, add the dependency to your project. Then run the checker on workshop.html. Review the first message describing an actual error. Correct that error. Save your changes. Run it again. Several later errors may disappear after that repair. They can be symptoms of the same nesting mistake, rather than separate faults.

Who is responsible for interpreting a file pattern: Your shell or the checker? If you want the checker to interpret it, quote it. If you don’t use quotes, the shell may expand it before sending it to the checker. It’s also good to know about configuration files as well. Some of these messages represent team-wide conventions. The others will help you to recognize invalid markup. Understanding this distinction will enable you to correct your mistakes with confidence.

Another option is Markuplint. Its CLI guide documents file arguments and success or failure exit codes. Use one agreed configuration for the project. Running several tools without understanding their different rules can produce a long report with no clear repair order.

npm install --save-dev markuplint
npx markuplint workshop.html

Automatic fixes deserve review. Some messages require a decision about meaning, not a mechanical text replacement. Check the diff after any fixing command and rerun the browser task. Keep deliberate broken examples outside the normal passing-file pattern, or your teaching fixture will make every build fail.

Match the symptom to the right check

Where to investigate common page problems
Symptom First check What validation misses
Content appears in an unexpected place Nesting and the current DOM Your intended reading order
A jump link goes nowhere Fragment spelling and unique IDs Which section the reader needs
The page has no styling Stylesheet URL and network response Whether the CSS achieves your design
A custom button does nothing Console errors and event handling Whether application logic is correct
An image is missing Resource address and response Whether the chosen picture is appropriate

A valid stylesheet link can still point to a missing resource. Look at the browser’s Network panel for the actual request and response. For examples of where that link belongs, see our guide to linking CSS to HTML. Fixing the document and fixing a failed download are separate jobs.

The Console helps investigate script failures. A quiet one does not certify the HTML. Similarly, an HTML report may indicate there are no errors, but it will not verify the correctness of a script. Therefore, choose the appropriate tool for answering your current questions about the page and confirm its results by repeating the relevant visitor task.

Separate checks for markup rules, resource loading, keyboard operation and intended results

A passing markup report does not replace checking resources, controls and destinations.

Make validation part of a short testing routine

Return to the task you wrote down at the start. Does “See materials” now get to the section after a fresh load? Try both the keyboard and mouse. Then enlarge the text and narrow the window. Use a long heading or realistic name; short placeholders can hide layout problems.

The DWP accessibility testing guidance places HTML validation alongside automated, manual and assistive software testing. That is a useful distinction: fixing markup is one part of assessing a service, not a certificate that every person can use it.

Check representative documents after the build: one with a form, one with tables and one with shared navigation. A template problem can affect many URLs. Looking only at the original component means you never examine the complete output. Leave a brief note describing what has changed in the modified file.

Indicate what was failing; describe how to duplicate this failure; and indicate what is passing. Keep the note brief, but give the next developer enough detail to repeat the check.

Separate a page defect from a checking rule

The same care applies to generated attributes. A framework may accept a special attribute in its source template and replace it during compilation. Run the appropriate template-aware checks on the source, then validate the produced HTML. Do not delete required framework instructions merely to make a checker designed for plain HTML accept the uncompiled file.

Keep the reproduction small enough to share with a colleague. Include the opening elements that establish the context and the closing elements that finish it. A copied line by itself can hide the very nesting problem you are investigating. Remove private values from a shared example while preserving the structure that triggers the failure.

Check the repair after publishing

A successful “local pass” will give you a good idea that your changes are working, but they will not be the final word on deploying your work. Go back to the published URL; check that the new text appears, and then repeat what you originally intended to do. Confirm that this page makes the appropriate request for its stylesheets and images. Relative paths can behave differently when a document moves into a deeper directory.

When you report results, clearly indicate which tests you have performed. For example, “the duplicate ID is no longer there and the jump link goes to ‘Materials'” is a precise statement. The vague “everything is correct,” does way more than those two tests show. A specific result is easier for someone else to verify.

Questions and self-check

Does valid HTML guarantee a working website?

No. Validation checks a defined set of markup rules. It does not establish that every destination exists, that calculations are right or that the layout suits your readers. Combine it with task-based browser checks.

Should I fix every warning immediately?

Read what each message means. Fix actual errors, investigate warnings and document justified project-specific decisions. Do not suppress a message simply because the page appears to work in one browser.

Self-check: a link points to #supplies, but the section is materials. What should you inspect?

Inspect the intended destination, then make the fragment and the target identifier agree. Adding CSS cannot repair that relationship.

Self-check: the source and Inspector differ. Is that proof of a browser bug?

No. Parsing repairs or script changes may explain the difference. Compare the delivered source, the current tree and the steps that produced it before assigning a cause.

The post How to Debug and Validate HTML: A Practical Workflow appeared first on HTML5 Doctor.

Read the whole story
alvinashcraft
41 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Measuring AI’s Impact on Delivery Speed

1 Share

The following article was originally published on James Shore’s Successful Software blog and is being republished here with the author’s permission.

Is AI making software development faster? Most people I talk to say yes. But how much? What value are you getting for your money? Are there other ways of using AI that have a better ROI?

This is part 2 of my series on assessing AI’s impact on software development. In part 1, we looked at why assessing impact is important, and what not to do. In this part, we’re looking at how to measure AI’s impact on delivery speed. In part 3, we’ll look at how to measure the unintended consequences of AI, before wrapping up the series in part 4 with an examination of business outcomes. Finally, an epilogue puts it all together with notes you can share with your CFO.

What we’re measuring

Delivery speed isn’t productivity. I’ll say it again, loud, for the folks in the back: Delivery speed isn’t productivity!

It’s a component of productivity, sure. Given two equivalent teams creating the same piece of software, the team that delivers first is the one that’s more productive.

But it’s not just about output. To my mind, software development productivity is value produced divided by money spent. It’s a strict definition but a useful one, because it gets to the heart of why we build software: to achieve some valuable purpose. Going faster doesn’t mean you’re going in the right direction.

We’ll consider business outcomes in part 4. For now, though, we’ll tackle a simpler question: Are your teams finishing their assigned work faster, regardless of whether that work is actually useful or not?

The core approach

First, the bad news: There’s no objective measure of software development speed. I can’t look at two teams and say, “This one is fast, and that one is slow.” That’s because none of the outputs teams create are standardized. We already talked in part 1 about how lines of code and PRs are bad metrics. Well, nothing else is standardized, either.

Features? Some are big, some are small. Bugs? Some are easy, some are hard. Stories? Velocity? Story points? Completely arbitrary. They have way more to do with what’s being requested than the speed of the team.

Okay, if they’re all different sizes, couldn’t we just use estimates? Surely if a team is constantly missing its estimates, it’s because it’s slow, right?

Not so fast! Software estimates are famously inaccurate. A team that always misses its estimates isn’t slow. It’s just overly optimistic. Teams are nearly always overly optimistic.1

So we can’t count requests (features, bugs, stories, etc.) because they vary in size, and we can’t look at on-time delivery, because estimates are overly optimistic. Sounds like a whole lotta “can’t.” What can we do?

We can compare a team to itself. If a team’s estimates were perfectly consistent, and they went from taking 3x longer than estimated to 1.5x longer, then they’re twice as fast! Huzzah!

If only it were that simple. There are a few snags.2

Estimates aren’t consistent

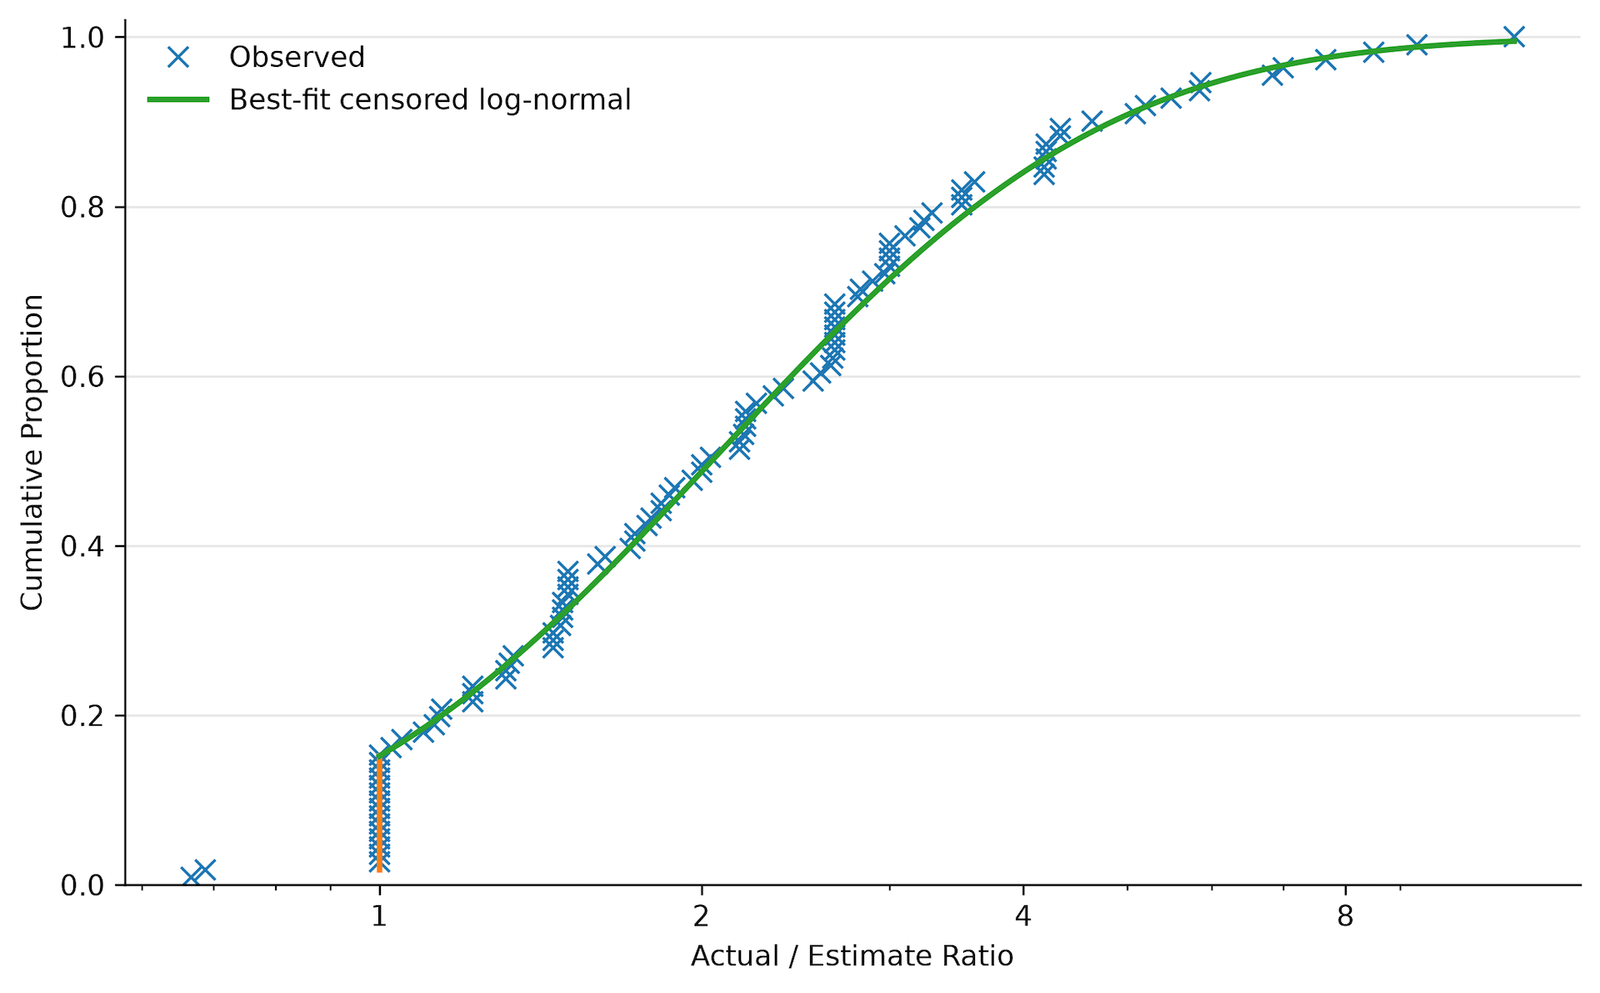
Snag the first: Teams’ actual estimate ratios aren’t actually consistent. Some are bigger, some are smaller. Plot them on a graph, and they form an “S” curve, as with this data from a real company.3

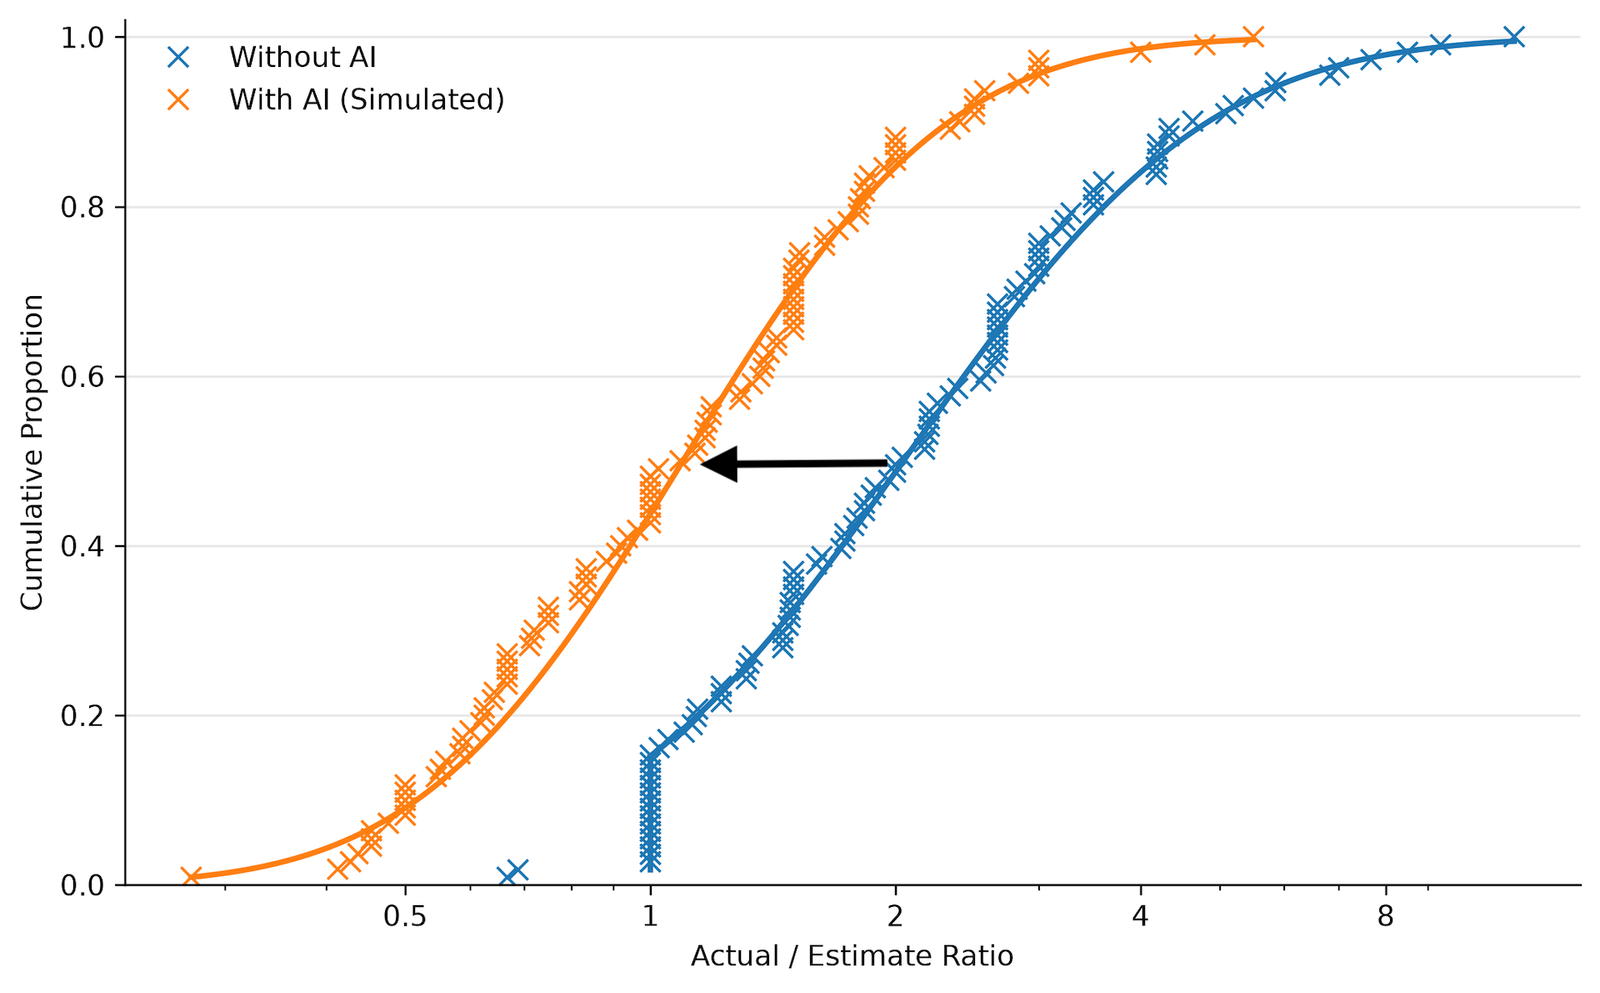
If delivery speed improves, the curve will shift. Individual data points may be better or worse than the original approach, but you can see the effect in aggregate.4

People work differently

Second snag: Some people are pessimistic and estimate high. Some estimate low. Some people spend a lot of time educating others. Others work heads down as fast as possible. Some clean up messes. Others create messes.

If you do a blanket comparison of everyone to each other, you introduce a lot of noise. Noise is bad because it increases the amount of data you have to collect. To keep things clean, compare people (or teams) to themselves.

Estimates change when people know they’re using AI

Third snag: People’s estimates will change according to the work they plan to do. So if they think they’re going to use AI, and they think AI makes them faster, their estimates will be smaller. Huh. Tricky.

This one’s actually pretty easy: Collect the estimate before people know whether they’re going to use AI or not. Then randomly assign the task to be done with or without AI.

Process improvements muddy the waters

Fourth and final snag: Are your speed increases due to introducing AI? Or the other changes you made at the same time?

AI forces you to rethink your software development processes. Leaders I talk to are streamlining request workflows and putting business experts in closer touch with developers as part of their efforts to introduce AI.

But these are the exact changes that make software development more effective in general! How much of the improvement you’re seeing is from spending thousands of dollars on tokens, and how much is the result of people talking to each other more?

Rather than comparing a chunk of pre-AI data to a chunk of post-AI data, interleave “without AI” tasks and “with AI” tasks. This reduces the influence of other changes. Update your without-AI approach to include the same streamlined workflows as your with-AI approach.

The complete measurement approach

In other words, if you want to be rigorous about this, you need to conduct a randomized controlled trial. Specifically, a “randomized within-subject repeated-measures” trial, which reduces the number of samples you need to collect.5

It’s not as bad as it sounds! People can still do their normal work.

Here’s what you do. First, establish a with-AI approach and a without-AI approach. (Or, more likely, “with a lot of expensive AI” and “with a sprinkling of cheap AI,” but I’ll say “with” and “without” for clarity.) Make sure they’re clearly defined and people have had a chance to practice both approaches.

The without-AI approach will probably be close to your current approach to software development, but if you’re streamlining your with-AI processes, be sure to incorporate those improvements into your without-AI approach too. Decide how you’re going to attribute rework, such as code review changes and bug fixes, back to the task that caused the rework.

Then give each person (or team) a virtual bag that’s half with-AI assignments and half without. For any given task, have people record their estimate first, then randomly pull an assignment from the bag.

The main data you’ll collect is estimated time spent, actual time spent, type of task, and spending. Decide in advance if you’re tracking calendar time (including interruptions) or effort (excluding interruptions) and how you’re going to handle parallel work. Think about what other useful information you might want, such as bug and incident counts, mental energy, excess lines of code, and so forth. We’ll talk about using that data to model unintended consequences in part 3.

You’ll need the help of a statistician to do the detailed experimental design and data analysis, but broadly speaking, each person’s with-AI data will be compared to their own without-AI data, then aggregated together to give you the final results.

Finally, remember that speed increases aren’t the same as productivity. Pay particular attention to how the tasks you’re measuring fit into the big picture. For example, if you see a 2x improvement in coding speed, but people spend 50% of their week on other work, their overall speed improvement is only 1.33x, not 2x.6

Is it worth it?

This is a lot more complicated than just counting PRs and calling it good. Is it worth it?

If this were just some run-of-the-mill process improvement exercise, no, it wouldn’t be worth it. It’s too much work, and the effect sizes have to be pretty large in order for the data collection to be practical.

But this isn’t some run-of-the-mill process improvement exercise. Productivity expectations are off the charts, and so are costs. As I talk to engineering leaders, I’m seeing order-of-magnitude differences in spending. Should you spend thousands per person per month on hands-off agentic coding? Or hundreds on analysis and fancy auto-complete?

It depends on the outcomes.

You can’t pick the right approach to AI without knowing what you’re getting for your money, and with so much money on the table, you can’t afford to half-ass this.

Remember, in a METR study, engineers overestimated AI’s speed benefits by nearly 50%. Without measurements, there’s no way to know what you’re actually getting.

Fortunately, it’s not as hard as it seems. With the level of impact you need to see, and enough participants, it doesn’t take many samples from each person.7 Your teams collect the data as they do their normal work. The hardest part is explicitly defining how you want people to use AI, and that’s worth doing anyway.

Of course, delivery speed is only part of the picture. There’s also the question of how sustainable speed improvements are. We’ll consider unintended consequences next, in part 3.

All my content is made with my 100% human meat brain, except where explicitly stated otherwise. If you liked this entry, check out my best writing and presentations, and consider subscribing to updates by email or RSS. To contact me about consulting, email me at jshore@jamesshore.com.


Footnotes

  1. When they’re not, it’s usually because they’re playing political games with estimate padding. That isn’t good either, because then the work tends to expand to meet the estimate. ↩︎
  2. This design was inspired by a METR study, with help from Brent Miller. AI Disclaimer: I used OpenAI’s GPT-5.6 Sol model operating in “High” thinking mode to critique my explanation, and I also used it to generate the Python programs that drew the graphs below. You can see my ChatGPT conversation here. ↩︎
  3. This data is from the Star Citizen alpha 3.0 release, which publicized its internal task estimates and actuals. Interestingly, the sharp cliff at the 1.0 mark is a classic sign of work growing to meet its estimate. ↩︎
  4. The Star Citizen data was split in half and artificially manipulated for the purpose of this example. It doesn’t represent real-world AI impact. ↩︎
  5. Many thanks to Brent Miller for introducing me to this technique. ↩︎
  6. Work that took 40 hours now takes 30. 40 ÷ 30 = 1.33. ↩︎
  7. The exact number will depend on the number of participants, the amount of variance in your results, and how conclusive you want the results to be. ↩︎


Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

JetBrains Foundation to discontinue new scholarships at Constructor University starting in 2027

1 Share

As JetBrains’ business direction evolves, we’re reviewing how our educational initiatives align with our priorities. As part of this shift, we’ve made the difficult decision to stop offering new scholarships at Constructor University.

We know this is disappointing news, especially if you were preparing to apply or have already submitted an application. We’re sorry for the uncertainty this brings to your plans.

Our commitments to current students remain unchanged. All existing Software, Data and Technology (SDT) and Advanced Software Technology (AST) scholarship recipients will retain the benefits covered by their scholarship agreements until graduation. JetBrains experts will also continue their teaching involvement in the SDT and AST programs for current scholarship students.

Our commitment to supporting talented young people through education continues. Our Math, AI, and Coding Clubs, Youth Coding and Math Challenges will continue as planned, along with the upcoming ACTS 2027.1 training camp.

We’ll also share an update on admissions and scholarship opportunities at Neapolis University Pafos on February 1, 2027.

We’re grateful to all the students, families, teachers, and coaches who have placed their trust in our programs. We understand how important clear and honest communication is, especially during times of change, and we’ll continue sharing updates as more information becomes available.

FAQ

1. Will there be any new JetBrains Foundation scholarships at Constructor University?

No. We will not offer new scholarships at Constructor University Bremen for the foreseeable future. Current scholarship students will continue receiving all the benefits in their scholarship agreements until graduation.

3. Why is JetBrains  Foundation ending these scholarships?

As JetBrains’ business direction evolves, we’re reviewing how our educational initiatives align with our priorities. As part of this shift, we’ve made the difficult decision to stop offering new scholarships at Constructor University. This decision follows a review of our educational initiatives and how they align with JetBrains’ evolving priorities.

We know this is disappointing for students who hoped to apply. Our commitments to current scholarship recipients remain unchanged, and we will continue supporting them through graduation.

Our commitment to supporting talented young people through education also continues. Our Math, AI, and Coding Clubs, Youth Coding and Math Challenges will continue as planned, along with the upcoming ACTS 2027.1 training camp.

3. I’ve already started preparing or applying. What does this mean for me?

Unfortunately, we won’t be awarding new JetBrains Foundation Scholarships at Constructor University for the 2027 intake.

We know you may have invested considerable time and effort in preparing your application, and we’re sorry if this decision affects your plans.

If you’ve already submitted an application or have questions about your individual situation, please contact Sofana Rojas Vargas from Constructor University recruiting directly: srojasvarg@constructor.university.  

4. Are there other scholarships or funding options I can apply for?

Constructor University offers various financial aid options, including scholarships for numerous degree programs. 

In the meantime, you can explore other degree programs and funding opportunities available at Constructor University here.

We’ll also share an update on scholarship opportunities at Neapolis University Pafos on February 1, 2027.

5. Can I still apply for a JetBrains Foundation scholarship at Neapolis University Pafos?

We will share an update on the next admissions round and scholarship opportunities at Neapolis University Pafos on February 1, 2027.

6. Can my application or selection results be transferred to the Pafos scholarship process?

No. Neapolis University Pafos has a separate admissions process and its requirements are different. You will need to apply separately and complete its selection process. Please reach out to us directly if you have any questions and need our support. 

7. Will current SDT students be able to finish their degrees?

Yes. Our agreement with Constructor University explicitly provides for current students to complete their studies.

All existing JetBrains Foundation scholarship recipients will also retain the full benefits covered by their scholarship agreements until graduation, including tuition, accommodation, and other covered expenses.

JetBrains will continue its academic involvement with current SDT and AST students.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Episode 535 - How an SRE Leader Built an AI Engine to Navigate His Job Search

1 Share

if you want to check out all the things ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠torc.dev⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠ has going on head to ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠linktr.ee/taylordesseyn⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠ for more information on how to get plugged in!


Download audio: https://episodes.captivate.fm/episode/1fe51881-d3aa-418e-8282-831c6ec93347.mp3
Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

1053: What’s in Our Home Lab

1 Share

Scott and CJ tour their homelabs, from a fully 3D printed server rack to a custom OPNsense firewall load balancing two ISPs. They dig into Proxmox, Tailscale, Caddy, Synology vs. DIY ZFS storage, Home Assistant, Jellyfin, Immich, Kiwix, and coding over the network with T3 Code and OpenCode.

Show Notes

Hit us up on Socials!

Syntax: X Instagram Tiktok LinkedIn Threads

Wes: X Instagram Tiktok LinkedIn Threads

Scott: X Instagram Tiktok LinkedIn Threads

Randy: X Instagram YouTube Threads


Download audio: https://traffic.megaphone.fm/FSI3828886334.mp3
Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Your voice shapes SPFx: take our developer survey

1 Share

spfx autumn survey 2 image

With Copilot UX components now generally available, SPFx is the pro-code way to extend Microsoft 365 and build experiences for Microsoft Copilot, SharePoint, Microsoft Teams, Viva Connections, and Outlook. Today we’re opening the SPFx developer survey, and we want to hear from everyone who builds with SPFx: how is it working for you, and what do you need next?

A year of SPFx updates 💡

Since September 2025, we’ve shared a monthly SPFx roadmap update on the Microsoft 365 Developer Blog. Here are the highlights from the past year:

  • Copilot UX components became generally available with SPFx 1.24 on October 28, 2026. Your agents can now bring interactive UX with dashboards, forms, and business actions directly into the Microsoft Copilot conversation, built with familiar web technologies and hosted automatically by Microsoft 365. Read the GA announcement.
  • SPFx 1.24 also moved React-based solutions to React 18.3.1 and added support for Node.js 24 and 26, alongside Node.js 22.
  • SPFx 1.23 in May 2026 brought list view command set improvements and a preview of the new open-source SPFx CLI.
  • Regular maintenance releases address reported npm dependency vulnerabilities, from SPFx 1.22.2 in January 2026 to SPFx 1.24.1 on November 2, 2026.

Share your feedback 📝

We use this survey to understand how satisfied SPFx developers are today and to decide where to invest next. Whether you build Copilot UX components, web parts, extensions, Teams apps, or Viva Connections cards, your answers go straight to the team planning the future of SPFx.

The survey is open until Wednesday, December 2, 2026.

Found a bug or have a specific feature request? Keep using the SPFx issue list in the sp-dev-docs repository on GitHub to report issues and share requirements.

Join the community 👋

The survey is one way to shape SPFx, and the community is another. The community calls run every week, with live demos, product updates, and time for questions with the presenters (Microsoft and community presenters). Join us, and bring your own demos too: we’d love to see what you’re building with SPFx and Copilot UX components. Build or created something you want to share? – sign up for a demo in the community calls.

There’s much more happening beyond the calls. Visit the Microsoft 365 & Power Platform Community to learn from others building for Microsoft Copilot, Microsoft 365, and Power Platform, share your samples, and find more ways to get involved.

What’s next 📅

The SPFx roadmap on Microsoft Learn is up to date with SPFx 1.24.1 and the plans for SPFx 1.25, currently targeted for December 2026 to January 2027. Planned investments include further development of Copilot UX components, general availability of the open-source SPFx CLI, and plenty of other plans for upcoming releases across Microsoft 365. Plans and dates can change, and your survey answers help us decide what comes after that.

Thank you 🙏

Thank you to everyone who has shared feedback with us over the past year, in GitHub issues, community calls, samples, at events, and in our spring survey. Your input shaped what we shipped this year, including Copilot UX components, and it will shape the SPFx roadmap ahead. We’ll share what we heard in an upcoming monthly update.

The post Your voice shapes SPFx: take our developer survey appeared first on Microsoft 365 Developer Blog.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories