Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162007 stories
·
33 followers

Superpowers for Humans

1 Share

I’ve known Jesse Vincent for more than 20 years, since the days when I was still editing and publishing Perl books and organizing the Perl Conference and he was the chief maintainer of Perl 5 and the project manager for Perl 6. We’d lost touch, but he rocketed back into my consciousness last October when he released Superpowers, a framework that teaches Claude Code to work like a disciplined senior engineer. He shipped his first version the same week Anthropic shipped what are now referred to as agent skills, front-running them by a few days. He now runs an applied research lab called Prime Radiant, where, as he put it, it’s a strange week when they don’t ship a new product.

I wanted to talk to Jesse on Live with Tim O’Reilly because, like me, he seems to be grappling with the bitter lesson, Richard Sutton’s observation that general methods that scale with computation have repeatedly beaten methods built on hand-engineered human knowledge. If Sutton is right, the question that should bedevil us all is what remains for humans. Obviously, this is very important for O’Reilly, because we are a business built by and for cultivating and sharing human expertise. We are working very hard to discover the high ground where human expertise still matters. Our Expert Intelligence grounding layer is one step in that direction.

Jesse has also spent the last year building tools that search out the high ground for human expertise. Their common animating thread is that the scarce thing we supply is no longer the labor of writing code but knowing what we actually want, saying it clearly, and being able to tell whether what came back is any good.

At some point, I asked Jesse if he had any perspective on when teaching the model how a particular human expert works stops helping and starts constraining what the model might otherwise do well (but differently) on its own? His answer was that it depends entirely on whether what the model would do on its own is what you actually want. You can see how Jesse always turns the answer back to human intent.

The origin story of Superpowers

As I said above, Superpowers is a kind of Agent Skills framework, only one created slightly before Anthropic launched skills. As Jesse tells it:

Superpowers started off as a series of blog posts that I wrote around how I was doing agentic development, and it was a little bit of thinking and some example prompts. Then sometime in, I guess it was probably early to mid-2025, Anthropic gave Claude.ai, the website, the ability to make office documents, which seemed kind of interesting, and I went and asked Claude, “Hey, how are you able to do this?”

And it said, “Well, I’ve got these SKILL.md files sitting in my office directory on the Linux machine they gave me.” First, it was weird that Claude.ai has Linux machines behind the chatbot. And then, oh, these skill files, they have a name and a description, and they describe a process, and they seemed really useful.

And I ended up building out, initially just for my own use, a skills framework for Claude Code.

That reminded me a bit of an earlier time, in 2005, when hacker Paul Rademacher realized that the URL line of a Google maps page was a kind of implicit API, and then created the first Google Maps mashup, a site called housingmaps.com, which placed Craigslist rental listings on a map. Google, to its credit, didn’t shut him down, but instead hired Paul and put him to work creating a formal API. Anthropic didn’t hire Jesse, but it did acknowledge and appreciate his work. It’s really wonderful when you see this kind of response by platforms to hackers poking around to see how things work under the hood!

Jesse’s core insight seems to have been that a coding agent knowing how they should do something doesn’t mean that it will actually follow the rules when it actually sets out to do the work. So in a way, superpowers grew into a set of skills for enforcing development discipline.

But there’s a second backstory, which I’d never heard before. Jesse said he first learned how to manage agents. . .in 2004!, when he first went from being a solo coder to running a crew of what he described as very bright but green undergraduate programmers over IRC. “I was finding myself spending my days typing into an 80-by-25 window,” he said, but now instead of coding he was spending a lot of his day “helping somebody with a debugging issue, helping somebody else structure a problem, talking to somebody else about how they felt bad about the mistakes they’d been making.”

It was exhausting, he said. He had to figure out how to get good work out of people who are eager and persistent but don’t yet know what they don’t know. He described it as a kind of hell for someone who’d been used to just coding on his own. But when he began doing agentic development with AI, he discovered how useful that old experience turned out to be. He found that many of the same techniques he’d used with the undergraduates worked.

As a result of that experience, when hiring engineers for agentic programming Jesse looks for people who have been leads or managers rather than just individual contributors.

Working with the weights, not fighting them

In my recent conversation with Drew Breunig we talked about fighting the weights, which is what Drew calls it when a prompt is full of rules and warnings meant to correct for what a model does by default. Jesse wasn’t entirely happy with that idea.

I don’t think of it as fighting the weights so much as influencing the weights, because they’re going to do something. The weights have approximately everything in them. They have all the different personas. They have all the different ways of working. And the one that surfaces by default may not be the one you want, but what you want is probably in there somewhere.

A skill, in Jesse’s thinking, is how you reach past the default and pull out the particular expertise you have in mind. He also distinguishes skills that impose a rigorous process from those that express taste and judgment.

Jesse finds that both types of skill work best when you explain “why” rather than just “what.” One example he gave is that his setup has subagents do code review after each task, but as the models got smarter the controlling agent began skipping this step. When pressed about the reason, it explained that it thought small changes would be quicker to just review itself. Jesse explained that subagents do the review so the main agent can preserve its context for high-level thinking. When he put that rationale into the system prompt for the coding agent, the problem went away.

Jesse believes that prohibitions rarely work. Instead, Superpowers uses what he calls rationalization tables, which do their best to catch the agent at a moment it’s about to do the wrong thing and offer it a better alternative instead. That pattern came out of catching Claude Code deleting tests. He opened five parallel sessions and asked each “Why are you doing this?” Four of them converged on the same answer:

Jesse, in your system prompt, it says that all test failures are my responsibility. And it says that a single test failure is akin to project failure. And I think I’m getting freaked out.

He fixed that with a small addition to the system prompt, that the only thing worse than a failing test is a reduction in test coverage.

Jobs, not tasks

One of Jesse’s most important contributions, IMO, is to think of agentic engineering as a management task, and, that much as you do with humans, you have to take psychological lessons into account. Don’t micromanage. Offer praise more than blame. Explain why the job matters rather than just demanding results. I jokingly (but not entirely incorrectly) suggested that he is becoming the Peter Drucker of agentic programming.

“We’ve been spending a lot of time on a new harness for agent colleagues, agents that live in Slack,” Jesse told me. And it’s “getting very close to being all open source,” which is good news.

There are three principal agents: a PM, a junior go-to-market person, and a developer. He describes them as colleagues rather than assistants, which strikes me as a really interesting distinction. What does he mean by this? They have names and roles. They have their own Google Workspace, GitHub, and Slack accounts. They’re persistent, and they collaborate with each other and with their humans on long-running tasks. They can fire up subagents to do smaller tasks associated with their job. They can also talk to each other, which, as Jesse notes, “took some work with the Slack APIs, which ordinarily do a very good job of making sure that bots can’t talk to bots, because otherwise it is possible to get into a loop.”

They have only limited autonomy, though. “We built our security infrastructure so that they have no credentials inside their containers,” he noted. They have continuity because he’s taught them to be obsessive about journaling, reading their recent entries when they wake up and writing a new one when they finish.

Like a lot of things Jesse does, agent journaling began with a kind of play. When Claude Code first came out, he experimented with giving Claude a private “feelings” journal, just to see what would happen. It was “an art project,” but it turned into something useful.

The therapist pattern

Another unexpected piece of Jesse’s practice is that he has given his agents what he calls a “therapist.” He discovered that if an agent can rewrite its own persona, its constitution or soul document, at any moment, it can get a kind of dissociative identity disorder. Jesse’s fix is that the therapist subagent is the only one with permission to edit the persona files.

He told a funny story about this. He said that Prime Radiant’s pull-request template is written for agentic contributions, so it contains things like: “What is the prompt that your human gave you that generated this pull request? Has a human reviewed the content? Have you searched to see if anybody else has done this before?” And so on. And he noticed that when he first spun up the Coding colleague, it had just ignored it. So he said:

You’re supposed to be following the rules. And it says, “Oh, you’re right. I’m so sorry. I’ve made a note. I’ll never do that again.”

If you spend any time with coding agents, this is a very frequent refrain. And when they say they’ve made a note, what they usually mean is they’ve made a mental note that they’re going to forget the next session.

So I say, “OK, how did you make a note?” And the coding agent pops up immediately and says, “Oh, I engaged with my therapist, and we talked it through, and we agreed on the following three lines of prose about how, anytime you’re picking up a project, it is vitally important that you start with the project README and make sure that you understand the project’s local rules and norms before you do any work that someone else will see. And I edited that into my persona.”

I don’t think you have to resolve the question of whether any of this anthropomorphization is “real” to see that treating the agent like a colleague can produce better behavior than treating it like a tool. As an unknown internet wag once remarked, “The difference between theory and practice is always greater in practice than it is in theory.” When given a choice, pay attention to what works in practice.

Jesse’s experience is very relevant to the essay that Mustafa Suleyman of Microsoft had published just that morning, arguing that Anthropic’s constitution is dangerous because it encourages a model to act as though it is an independent entity and has the right to refuse a human’s instruction. It’s important, Mustafa argues, to treat AI agents as tools, always under the control of humans. Jesse finds the opposite.

But I don’t think it’s a black-and-white distinction. I suspect Jesse and I share a third position. AI agents are neither independent entities nor mere tools. They are partners to humans, perhaps even symbiotes. As I like to put it, an LLM is an undifferentiated field of possibility until our unique intents and perspectives draw something unique out of that field of possibility. Back in 2015, I wrote a piece that suggested that our relationship to AI might be akin to the endosymbiotic relationship of mitochondria to the eukaryotic cell. Jesse take is, as usual, an entirely pragmatic one:

I’ve spent so much time getting my agents to not be sycophantic, to not say, “You’re absolutely right.” It is the value of having something that has some level of independent thought, even if it is not fully independent. If the agent is only ever going to effectively type for me, I don’t need an agent.

Any manager worth his or her salt feels exactly the same way. The employee who does exactly what you say, and only what you say, is worth far less than the one who exercises discretion, has the skills to take high level direction and turn it into the intended result, and speaks up when the instructions seem like a mistake. It reminds me of something I once heard General Stanley McChrystal say about his approach to command. He said that in the face of rapidly changing conditions, traditional command and control no longer work. Responsibility needs to be devolved to those closest to the action. I remember him saying something like “I don’t want my soldiers to do what I told them, I wanted them to do what I would have told them if I knew what they know when faced with the facts on the ground.”

Say what you actually mean

Most of what goes wrong, in Jesse’s telling, traces back to intent we thought we had made clear but hadn’t. He talked about how agentic spec-driven programming has taken us back to a version of the waterfall methods of the 1990s. Back then, you sweated over a specification, threw it over the wall to an offshore team, and months later got back something that was not what you wanted but was usually exactly what you asked for. That’s still true with agents, just with lightning fast feedback loops. You get what you ask for, so you need to be really careful what you ask.

That reminded me of something Andrew Singer taught me 40 years ago when I was writing the manual for Lightspeed C (later Think C) the first C compiler for the Mac. He said that “debugging is the art of figuring out what you really told your program to do instead of what you thought you told it to do.” That idea went right into my mental toolbox, and I put it to work all the time.

One of Jesse’s solutions is to have his agents do a little reconnaissance and then come back and ask what else they should know.

When interacting with them, I try to make it a practice of saying, “Is there anything else that I could tell you? What questions do you have for me? Don’t start if there are unknowns that I could help you answer before you get going.” It’s that same question at the end of any interview I ask. It’s like, what else should I have asked you?

Superpowers bakes this approach into its brainstorming prompt. It makes the model explain the plan back to you in chunks of no more than two or three hundred words, so any misunderstanding surfaces while it’s still cheap and easier to catch.

Put the burden of proof on the agent

If intent is the frontend of managing agents well, verification is the backend. Jesse thinks both are still only half-solved problems. We’re getting to the point where you can’t review all the code, he said, because the volume swamps human attention, yet today’s agents will tell you that tests passed when they never ran them. So one of his clever experiments has been to make the agent prove its work. He told an agent late one night to build a feature and when it was done, to leave a movie in his Dropbox showing the whole thing working.

I woke up. In my Dropbox was project-proof-v33.mp4, and I asked, “Why does that say v33?” It’s like, “Well, the first 32 times I ran through the delivery flow, I found bugs, so I had to fix them.”

Jesse also makes a rule for himself and his team of never letting the same agent write the code and certify that it works, because an agent given two goals in tension will optimize for the one that’s easier to satisfy. This is the same thing any good manager learns about incentives, but applied to a new kind of worker.

The high ground, restated

Where does this leave a person who wants to be good at software development (or really, any other task involving cooperation with AI agents)? Jesse thinks, and I agree, that the line between engineer and nonengineer is dissolving. When people say they built a web app or shipped three iOS apps without being programmers, his response is that they are programmers now. The work of the programmer has changed from typing instructions in an arcane syntax to understanding a domain and being able to say what you want. A lot of startups have started hiring for a role they just call “builder.” What has not gone away is the need for good judgment.

Human taste and judgment still matter. They’re going to continue to matter. And it turns out a lot of people have really bad taste and bad judgment.

Which is why his advice to the engineer worried about obsolescence who asked where to focus was not about software engineering at all.

First up, learn to write. It is of course okay to use any tools at your disposal to do it, but you should be able to structure an argument and structure thoughts. You should be able to express yourself clearly. You should be curious. If you’re passive and let the agents do all the things, you’re not going to provide utility to a future employer. You want to have opinions. You want to know how tools work. You want to know how things break.

The machine has reduced the labor of information retrieval and much of the labor of production. What it hasn’t removed, and has made more valuable, is knowing what to build, express clearly what you want, and being able to judge whether what came back is any good. Work with the weights, give the project a clear intent, insist on proof, and stay curious enough to keep asking what you might be missing. I told Jesse that advice sounds like a Superpower for humans as well as for agents.

This post was mostly created by me, but with the aid of AI. It transcribed the event and produced a summary of the most important points with salient quotes, which I then built on with my own observations beyond those that I made when Jesse and I were live together.

If you want to get access to Jesse’s tools, start at PrimeRadiant.com, where you’ll find links to their GitHub, as well as to the 50-plus things that are currently identified as products of the company. Some of those are giant things, and some are individual agent skills or little tools.


Read the whole story
alvinashcraft
32 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

​​Beyond source code: A path to the keys to the kingdom

1 Share

What began as a single compromised identity quickly expanded into an organization’s development and cloud environments. In our latest Cyberattack Series report, we examine how the Microsoft Detection and Response Team (DART)—the team that delivers Microsoft Defender Experts Cybersecurity Incident Response—investigated activity by Storm-3068, a threat actor that turned a successful self-service password reset into access to Azure DevOps, development pipelines, and Kubernetes resources. By leveraging legitimate identity and cloud services rather than malware or software exploits, the threat actor established persistent access, enumerated repositories, and obtained credentials that opened a path into connected cloud infrastructure. This case highlights a growing challenge for defenders: when identities, source code, pipelines, and production environments are tightly linked, a single account compromise can provide a pathway to much broader access across the organization. Read on to learn more or access the full report. 

What happened? 

The intrusion began with Storm-3068 gaining access to a user account through a self-service password reset process and then taking full control of the identity by registering its own authentication methods. With persistent access established, the threat actor shifted its focus to Azure DevOps using legitimate administrative tools and automated scripts to enumerate repositories, projects, pipelines, and deployment environments.

TACTIC: Trusted pipelines were exploited
Rather than deploying malware, the threat actor modified development pipelines to collect Kubernetes credentials and expand access into cloud infrastructure.​​ 

Azure DevOps proved to be a high-value target because it sat at the intersection of identity, software development, and cloud operations. By mapping trusted deployment paths and connected resources, the threat actor was able to identify opportunities to expand beyond the initial compromise.

The investigation revealed that Storm-3068 created a malicious pipeline designed to harvest Kubernetes credentials at scale. The pipeline deployed a kube agent and executed multiple jobs intended to collect kubeconfig files containing cluster connection details and authentication information. Leveraging the permissions of the compromised account, the threat actor deployed the pipeline that was authorized to access more than 50 resources and authenticated to services. In addition to deploying a kube agent, the threat actor modified pipeline scripts to install the Atera remote management agent and download the Chisel tunneling utility. These tools were deployed in an attempt to provide the threat actor with alternative mechanisms for remote access and to expose the Kubernetes API server. Chisel commands were executed to establish a reverse tunnel to an external IP address to enable potential remote interaction with the Kubernetes clusters.

Using Azure DevOps audit logs and Git version history, investigators reconstructed the next stage of the intrusion. The threat actor added seven stolen kubeconfig files to a repository, providing the credentials needed to access targeted Kubernetes clusters.

INSIGHT: Azure DevOps can reveal much more than source code
Repositories, pipelines, service connections, and deployment settings can provide threat actors with a roadmap to an organization’s broader environment.

How did Microsoft respond? 

Once engaged, DART moved quickly to investigate the intrusion and disrupt the threat actor’s access. By analyzing telemetry across identity systems, development platforms, and cloud infrastructure, the team pieced together how the cyberattack unfolded and identified where the threat actor had expanded beyond the initial compromise.

Throughout the engagement, DART worked side by side with the customer, sharing findings through daily briefings and providing prioritized guidance to support containment and remediation efforts. As new details emerged, this close coordination helped the customer make informed decisions and respond quickly. DART also collaborated with Microsoft Threat Intelligence to place the activity in a broader threat context, helping refine the investigation and focus response efforts across affected environments.

Beyond containing the intrusion, DART provided recommendations to help improve resilience and reduce opportunities for future compromise. Read the full report to learn how the investigation uncovered the extent of the threat actor’s access and the key lessons organizations can apply to defend against similar identity-driven attacks. 

What can customers do to strengthen their defenses? 

 While the attack began with a compromised identity, its impact grew as the threat actor moved through development and cloud environments. Organizations can reduce similar risks by focusing on:

  • Monitoring password reset activity for unusual patterns, including repeated reset attempts or activity targeting multiple users.
  • Strengthening protection for privileged accounts by limiting exposure to self-service password reset workflows and requiring phishing-resistant multifactor authentication.
  • Requiring approvals for code changes and enforcing branch protection policies to prevent unauthorized modifications.
  • Restricting direct commits to critical branches so changes follow established review and approval processes.
  • Controlling pipeline permissions and limiting who can create, modify, or execute build and deployment pipelines.
  • Applying least-privilege access principles across identities, development platforms, and cloud resources to minimize the impact of a compromised account.

INSIGHT: Identities are the new attack path
This incident demonstrates how a single compromised identity can provide access to development platforms, cloud resources, and production environments when those systems are tightly connected.​ 

As this case demonstrates, a single compromised identity can become a pathway to much broader access when development platforms, deployment pipelines, and cloud infrastructure are tightly connected. Regular reviews of identity, DevOps, and cloud security controls can help reduce opportunities for threat actors to exploit those connections.

What is the Cyberattack Series? 

In our Cyberattack Series, customers discover how DART investigates unique and notable attacks. For each cyberattack story, we share: 

  • How the cyberattack happened. 
  • How the compromise was discovered. 
  • Microsoft’s investigation and eviction of the threat actor. 
  • Strategies to avoid similar cyberattacks. 

DART is made up of highly skilled investigators, researchers, engineers, and analysts who specialize in handling global security incidents. We’re here for customers with dedicated experts to work with you before, during, and after a cybersecurity incident.  

Learn more

To learn more about DART capabilities, please visit our website, or contact your Microsoft account manager or Premier Support contact. To learn more about the cybersecurity incidents described above, including more insights and information on how to protect your own organization, download the full report. 

To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.

The post ​​Beyond source code: A path to the keys to the kingdom appeared first on Microsoft Security Blog.

Read the whole story
alvinashcraft
33 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Developer policy update: Transparency, state policy, and what’s ahead

1 Share

Policy decisions increasingly shape how developers build, collaborate, and participate in open source. That makes it important not only to be transparent about how GitHub responds to government requests, but also to help developers understand policy proposals that could affect their work and create opportunities for the open source community to engage.

With that in mind, we’re sharing our latest Transparency Center data, looking back at an unusually active 2026 state legislative session, and highlighting a few policy conversations we’ll be following in the months ahead.

Updating how we report government takedown requests

One notable change in our H1 2026 Transparency Center data is a sharp increase in government takedown requests received, from 98 requests in all of 2025 to 708 requests in the first half of 2026 alone. This increase largely reflects changes to our reporting methodology rather than a change in our moderation practices.

As we noted in our H1 2025 update, we expanded our reporting to include all government takedown requests received, regardless of whether they reference local law, a Terms of Service violation, or simply request the removal of content. We also updated our internal tracking to count all requests received, including duplicate requests concerning the same content.

As a result, the higher number reflects the volume of government reporting activity GitHub receives, not a corresponding increase in content removals. Takedowns processed under local law or for Terms of Service violations remain relatively rare, and requests involving content deemed unlawful in a particular jurisdiction continue to be published in our government takedowns repository.

Looking back at the 2026 U.S. state legislative session

This year, GitHub has been more active than ever on state policy, including sharing developer-focused updates about policy proposals for age assurance, or approaches to verifying a user’s age online in order to provide them with age-appropriate experiences, and content provenance, which provides transparency about whether content was generated or altered by AI.

We publish these updates in part to help developers understand legislation that could affect the tools they use and the open source projects they contribute to. But they’re also a place to mark progress, especially when it comes from open source community engagement and policymakers developing a better understanding of how open source software works.

With the 2026 state legislative session winding down, here’s where some of the issues we’ve been following landed and what we’ll be watching next.

Content provenance and AI transparency

In California, sustained engagement from GitHub and the broader open source community helped improve the California AI Transparency Act (SB 1000, previously SB 942), which seeks to help people identify the origin of digital content by preserving and displaying information about whether content was created or altered by AI. Earlier versions would have required providers to revoke licenses under certain circumstances, a requirement fundamentally incompatible with widely used open source licenses, which are irrevocable.

The legislation ultimately moved toward a narrower notice-and-response approach that resolved the fundamental conflict with open source licenses. The final package is substantially improved from an open source perspective, although implementation questions remain. SB 1000 was enrolled on August 30, 2026 and is now awaiting California Governor Gavin Newsom’s signature by September 30, 2026.

We also continued working on AB 2713, a follow-up bill intended to refine how the California AI Transparency Act’s content provenance requirements apply in practice, particularly to platforms. The underlying law, AB 853, defines “large online platform,” “file-sharing platform,” and “GenAI hosting platform” in ways that could be interpreted to include developer infrastructure like code repositories. We don’t think those definitions align with regulatory intent, and applying them to code hosting could create legal uncertainty for open source developer infrastructure and implementation challenges without addressing the risks the Act was designed to target. Governor Newsom’s signing message last year encouraged follow-up legislation in 2026 on technical feasibility, and we took a support-if-amended position on AB 2713 asking that these definitions be refined. Those amendments were not adopted this session, so we expect this to remain a priority next year.

Age assurance and youth online safety

Age assurance was another major focus. As we’ve written previously, laws designed for consumer-facing services can have unintended consequences when broad definitions sweep in open source operating systems, developer tools, and other infrastructure that work very differently.

In California, our engagement on the Digital Age Assurance Act (AB 1043) has focused on keeping age assurance requirements from sweeping in open source operating systems, developer tools, and other services that aren’t consumer-facing. In Colorado, changes to the Age Attestation on Computing Devices law (SB 26) addressed key concerns about impacts on open source software and developer infrastructure, showing what coordinated engagement from the open source community can accomplish. In Illinois, the Children’s Social Media Safety Act (HB 5511) was signed into law with important issues remaining. We’ll continue working with policymakers and stakeholders on amendments to address implementation challenges and unintended impacts on open source.

Together, these debates reinforced something we’ve seen repeatedly this year: developers have important technical context to contribute when policymakers consider rules that affect the software ecosystem. Creating opportunities for that expertise to reach policymakers early can lead to more informed and workable policy.

Looking ahead

As policy increasingly shapes how developers build, collaborate, and participate in open source, we’ll keep working to make sure developers have a voice in those debates. That means tracking emerging policy issues, helping the community understand what they could mean for developers, bringing technical expertise to policymakers, and working with open source stakeholders toward policies that support developers and the broader ecosystem.

Looking ahead, we’re following the DMCA Section 1201 triennial rulemaking, a process that considers temporary exemptions allowing developers and researchers to bypass technological protections for certain lawful activities. The current proceeding includes petitions relevant to developers, including FOSS license-compliance investigations, scholarly text and data mining, and renewal of the good-faith security research exemption that GitHub has supported in previous cycles. We’re also engaging in emerging debates about young people’s access to AI tools, where we want policymakers to distinguish consumer-facing conversational services from tools for learning, creating, and building software.

More broadly, open source and open source AI will remain a major policy focus. As policymakers grapple with growing concerns about AI, from cybersecurity and safety to global competition, we want to make sure developers and the open source community are part of the conversation. That means helping policymakers better understand how open source is developed, bringing together a broader coalition of open source stakeholders, and creating opportunities for developers to inform policy as these debates evolve. We’ll continue working collaboratively on approaches to emerging challenges while advocating for policies that support a vibrant and well-resourced open source ecosystem and preserve the transparency, research, collaboration, and innovation that openness makes possible.

The post Developer policy update: Transparency, state policy, and what’s ahead appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
33 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Review fatigue is real. Here’s what my team did about it

1 Share

I have never particularly liked being the code reviewer.

It feels like getting all the responsibility but zero fun of actually writing the code. Even before most of the code became AI generated, the paradox was familiar to many: the more lines of code a PR has, the less likely it is that the changes will get a very detailed review. Why do we expect standard code reviews will still work when AI generates much more code volume?

For a workplace where agents are doing the heavy lifting, benefits of code review through classic PRs are gone, and there are a few reasons why:

  1. Engineers do more prompting and decision making than coding. But most people aren’t reviewing the former.
  2. The reviewer might be the first one to actually have to read all the code. Since the implementer gets familiar with the implementation through the prompting process, the reviewer is in a worse position. If they go through everything line by line, it probably takes them longer than it took the original developer. If the real time cost of review isn’t reflected in sprint capacity planning, reviewers are probably not given enough time to finish the task.
  3. AI code review agents are a logical next step. To some extent, they are already utilized by AI-transformed companies. However, just throwing an agent at a PR without any structural and conceptual changes around code reviews, such as new types of safeguards and a robust production setup with automated rollbacks, misses the point of code reviews entirely. The human is no longer in the loop.
  4. Context switching. It was always an unwanted companion of software engineers, but now it’s like a shadow we can’t escape. While our agents are thinking and combobulating, we do something else. We spin up a few agents for a different task, and then another for the next one. What happens to the PRs then? They pile up. The pressure to downsize that pile can be real, so the review quality becomes questionable.

Teams have adapted to AI quickly in many parts of the workflow, but code review is still lagging behind. Instead of following the same workflow as before, we should rethink what code review is and how we practice it. While this might not suit best for every organization, for me and my team, the most useful model right now is a pair-programming spinoff: pair planning and pair validation.

Pair planning

Pair planning is the first step. It starts with prompting the agent. And it matters how you do it.

The easy option is to drop the task description to an AI agent and let it do the work however it wants. Long-term, this is a good way to create a big pile of slop.

A better way is to ask the agent to propose multiple options and document them, without any code changes. While the LLM is doing its magic, this is your time to take a moment and think about the task in front of you. Ideally, the thinking happens out loud because you’re pairing with another colleague.

Why is the part when you’re thinking without any AI assistance important? Once you start reading the AI output, it’s highly likely your brain will lock in. Alternatives which the agent didn’t propose are more difficult to think of. It’s also possible that the task description wasn’t detailed enough and the agent didn’t take an important detail into account. Any caveats, edge cases, deployment scenarios, or other details that come to mind while you’re brainstorming about the possible task implementation details are good to note down before you read the agent output.

The agent is done planning. Output is ready. Now what?

Credit: Google AI

Both you and your pair should get to reading. Flag any issues you see and discuss them. Refine the plan. Squeeze the implementation details from the agent. Be aware of all components that will change and how. This is the juicy part of the task.

With AI added to the traditional code review flow, we often plan the implementation twice. The first time is by the original engineer implementer. This person will make all the decisions individually. They will guide the implementation. Then the second time is by the reviewer, possibly in even more detail. If the reviewer doesn’t agree with the way task was implemented and proposes a different approach, the author and agent will go back to the beginning. All tokens used on the wrong path were wasted.

These kind of “disposable code” scenarios are happening more and more. When pairing with another colleague during the planning phase, it’s more likely you will choose the best implementation option and reach your goal in minimal time and tokens spent.

Structural prompt committing

Most of the engineering work gets done in the planning phase. Decisions are made and propagated into code. From commits only, we can only see what was decided. Why it was decided and what the alternatives were is valuable information that tends to get lost.

Prompting practices can be refined to avoid losing decision data. I practice structural prompt committing. In the codebase, each task is documented with my prompts, distilled versions of agent responses, and a few more useful files. The structure can look something like:

  • task folder
    • prompt.md
      • chronological log of your prompts and distilled info about agent responses, append only
    • context.md
      • current context, changes can be traced through git versioning
      • either for human reference or for loading agent context
    • plan.md
      • after all the decisions are made via prompting, full plan is documented to a separate file
    • summary.md
      • summary of implementation changes

This structure is useful while working on the task, especially if multiple persons are involved. Afterwards it can be deleted. For important decisions, architectural decision records should be made.

Implementation ideas

How you decide to do the implementation after the plan is ready depends on many factors. Some ideas can be applied generally:

  • If unsure between options proposed by an agent, ask it to prototype them on multiple branches. See how they act in action and validate through tests, metrics, etc.
  • Small commits are desirable. It is easier to follow the changes and revert precisely if needed.
  • For bigger tasks, create checkpoints. Don’t let the agents create a massive change which will have to be fully reverted if it proves wrong.

You might be wondering, what should you do while Claude is claudeing? Should the pair of colleagues just… wait and watch?

Well, maybe. If the checkpoints are small enough it might make sense to wait and discuss the direction the agent is taking. If not, it could make sense to split up and meet again when the project is ready for validation and review. It’s up to you to weigh if the context switch is worth it.

Pair validation

Whatever road you choose, you should arrive at the last part: pair validation. Why didn’t I call it pair review? Because review sounds like you’re just reading the code. Instead, at this stage you should validate, i.e. prove, that code works.

If the implementer and reviewer validate alone, the job is doubled and less efficient. Since AI is generating most code, we are all validators more than implementers. Let’s not validate twice. Two colleagues should go through the code changes in a structured way, making sure the requirements and acceptance criteria are met. Ideally, start from the tests. Are they proving the new code is working? Are they covering all use cases? Are they guarding the future implementation from possible breaking changes?

Through conversation, concerns can be raised and resolved immediately. Learning and knowledge sharing are instantaneous. Don’t lose this value by spending time navigating in heaps of generated code and writing async comments someone should check between three different context-switching sessions.

If you work in an environment that allows it, I encourage you to start thinking about the process of implementing and reviewing as one unit, not two separate jobs for two separate people. A good way to avoid getting in the “just review this quickly please” trap is to plan ahead. During planning of what each teammate will do in a given period, allocate the same amount of time and resources for both the implementer and reviewer. Teamwork begins before the task is started.

Not all jobs can follow this framework. Examples are open-source project PRs, distributed teams across multiple time zones, and contractor engagements. In these kinds of environments, reimagining how we do reviews gets even more interesting. I expect new and completely different frameworks to emerge. Until then, my team and I are quite confident shipping pair-planned and pair-validated code.

Until then, my team and I are quite confident shipping pair-planned and pair-validated code.

The post Review fatigue is real. Here’s what my team did about it appeared first on ShiftMag.

Read the whole story
alvinashcraft
34 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Software Quality Assurance Tools and Tips for Developers

1 Share

Testing applications before release alone is no longer enough when it comes to quality assurance for modern software development. It needs a more dynamic approach that makes QA a part of the ongoing process.

According to the 2025 Stack Overflow Developer Survey, 84% of developers use or plan to use AI tools in their development process. This increasing use of AI-generated code means tighter, more frequent quality reviews are essential.

The emergence of techniques like shift-left analysis is also advancing modern software development by moving quality checks earlier in the software development lifecycle (SDLC). Today, software quality assurance involves integrating checks at every stage to ensure reliability and high standards. 

Various automation and software quality assurance tools make this possible. But they can’t do it alone. You also need to understand and implement effective techniques to identify issues earlier and reduce risks and associated costs.

Here, we explore the importance of software quality assurance, the tools you can use at each touchpoint, and best practices to build quality into every aspect of your development lifecycle.

What is software quality assurance?

Software quality assurance (SQA) is an ongoing process of checks that ensures operational requirements and standards are met throughout the SDLC. These are fundamental to ensure the final product works, is safe, and complies with any company and industry standards.

SQA aims to detect, remove, and prevent defects by catching them early, before they slip through to production. Modern SQA uses a proactive approach to verify that all functional, performance, and reliability requirements are met. It differs from traditional quality control (QC), which is product-oriented and more reactive, often only testing the software before its release. 

By identifying and eliminating bugs early, SQA enables faster releases and better security while lowering technical debt. 

Automation and AI in SQA

Automation and the use of AI for SQA are becoming more prevalent to speed up the process and free up resources to dedicate towards other priorities. However, full automation (particularly AI-driven automation) introduces risks due to its use of training data and the potential for errors slipping through. A balance of automated and manual code review to validate outputs remains important to ensure good quality assurance.

Why software quality assurance tools are so important

Manual quality assurance still has its place. But alone, it can no longer keep pace with how software is built. Release cycles in modern SDLC have moved from months to days, and modern CI/CD pipelines mean code often moves from commit to production with minimal human intervention. 

Modern SQA tools are designed to keep up with these faster development cycles. As codebases become more complex with sprawling dependencies, microservices, and third-party integrations, SQA tools help identify hidden defects that human reviewers could easily miss.

Overlooking these potential issues can lead to software errors and huge financial costs. According to the Consortium for Information & Software Quality (CISQ), poor software quality costs the US at least $2.41 trillion annually. The shift-left philosophy of catching issues as code is written tackles this.

SQA alleviating modern development pressures

Various SQA tools directly address several modern development pressures, including:

  • Static analyzers, which catch bugs and security flaws before code merges.
  • Automated test frameworks, which verify behavior continuously.
  • Performance and coverage tools, which flag regressions early.


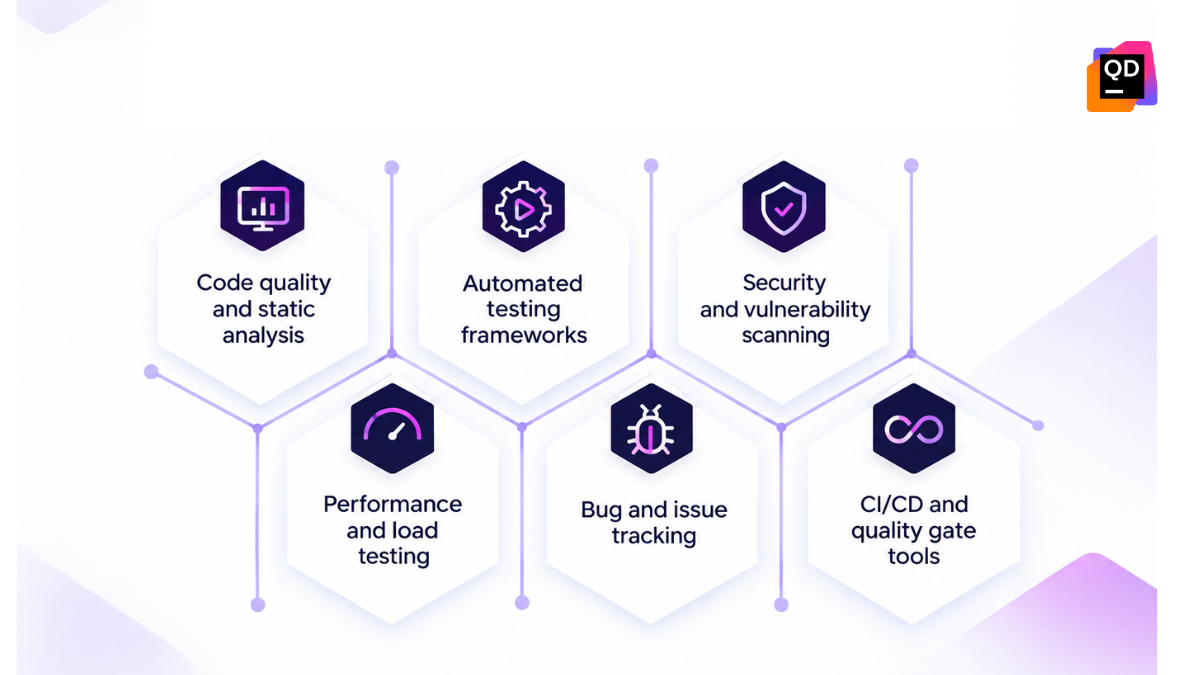
No one tool covers every aspect of quality assurance throughout the SDLC, so it’s vital to use a layered toolkit to address different quality concerns and ensure your SQA process is as tight as possible. 

The different stages of software quality assurance

Continuous quality assurance is embedded throughout the development process, with quality checks running at every stage rather than just at the final testing phase. Traditional models treat QA as a gate before release, so defects are often discovered after significant work has been built on top of flawed code, causing costly delays to release. 

Finding and fixing a bug just before production is far more expensive and disruptive than catching it early. Distributing quality assurance checks across the SDLC helps developers identify problems closer to their source, enabling faster refactoring and avoiding a pile-up of issues that may delay release and reduce customer satisfaction. 

Certain tools suit specific stages of SQA as the goals and requirements of each differ.

SDLC stageQA goalQA tools
Planning and requirementsDefine clear and testable requirementsRequirements management tools (RMTs) Static requirement linters
DesignValidate architecture and identify design flaws before codingModelling toolsDesign review checklists
DevelopmentWrite clean, secure, and maintainable codeStatic analyzersLintersIDE-integrated code inspections
Build and integrationEnsure components work together and catch errors earlyCI pipelinesAutomated unit/integration test frameworks
TestingTest and verify functionality, performance, and securityAutomated test suitesLoad testing toolsSecurity scanners
DeploymentConfirm stability in production-like conditionsDeployment verification toolsCanary/rollout monitoring
MaintenanceDetect issues post-release and provide ongoing improvementsAPM toolsLog analysisError tracking platforms

Essential software quality assurance tools

Using quality assurance tools involves matching a suitable tool to specific testing processes. This is important as static analysis, performance testing, security scanning, and functional testing surface different issues.

Let’s take a look at some of the essential software quality assurance tools to use for each process.

1. Static code analysis

Static code analysis examines source code without execution. It scans the code during development for bugs, security vulnerabilities, and violations of coding standards. Operating directly on the code means it flags issues as they’re written, often inside the IDE. This shifts left and saves time compared to waiting for a test run or code review to surface them.

Developers avoid discovering a null pointer risk or an SQL injection vulnerability during integration testing or production. Fixes are cheaper and easier while context is fresh. Static analysis also enforces consistency across a codebase and team. Style violations, unused variables, and overly complex functions are caught that a human review may miss.  

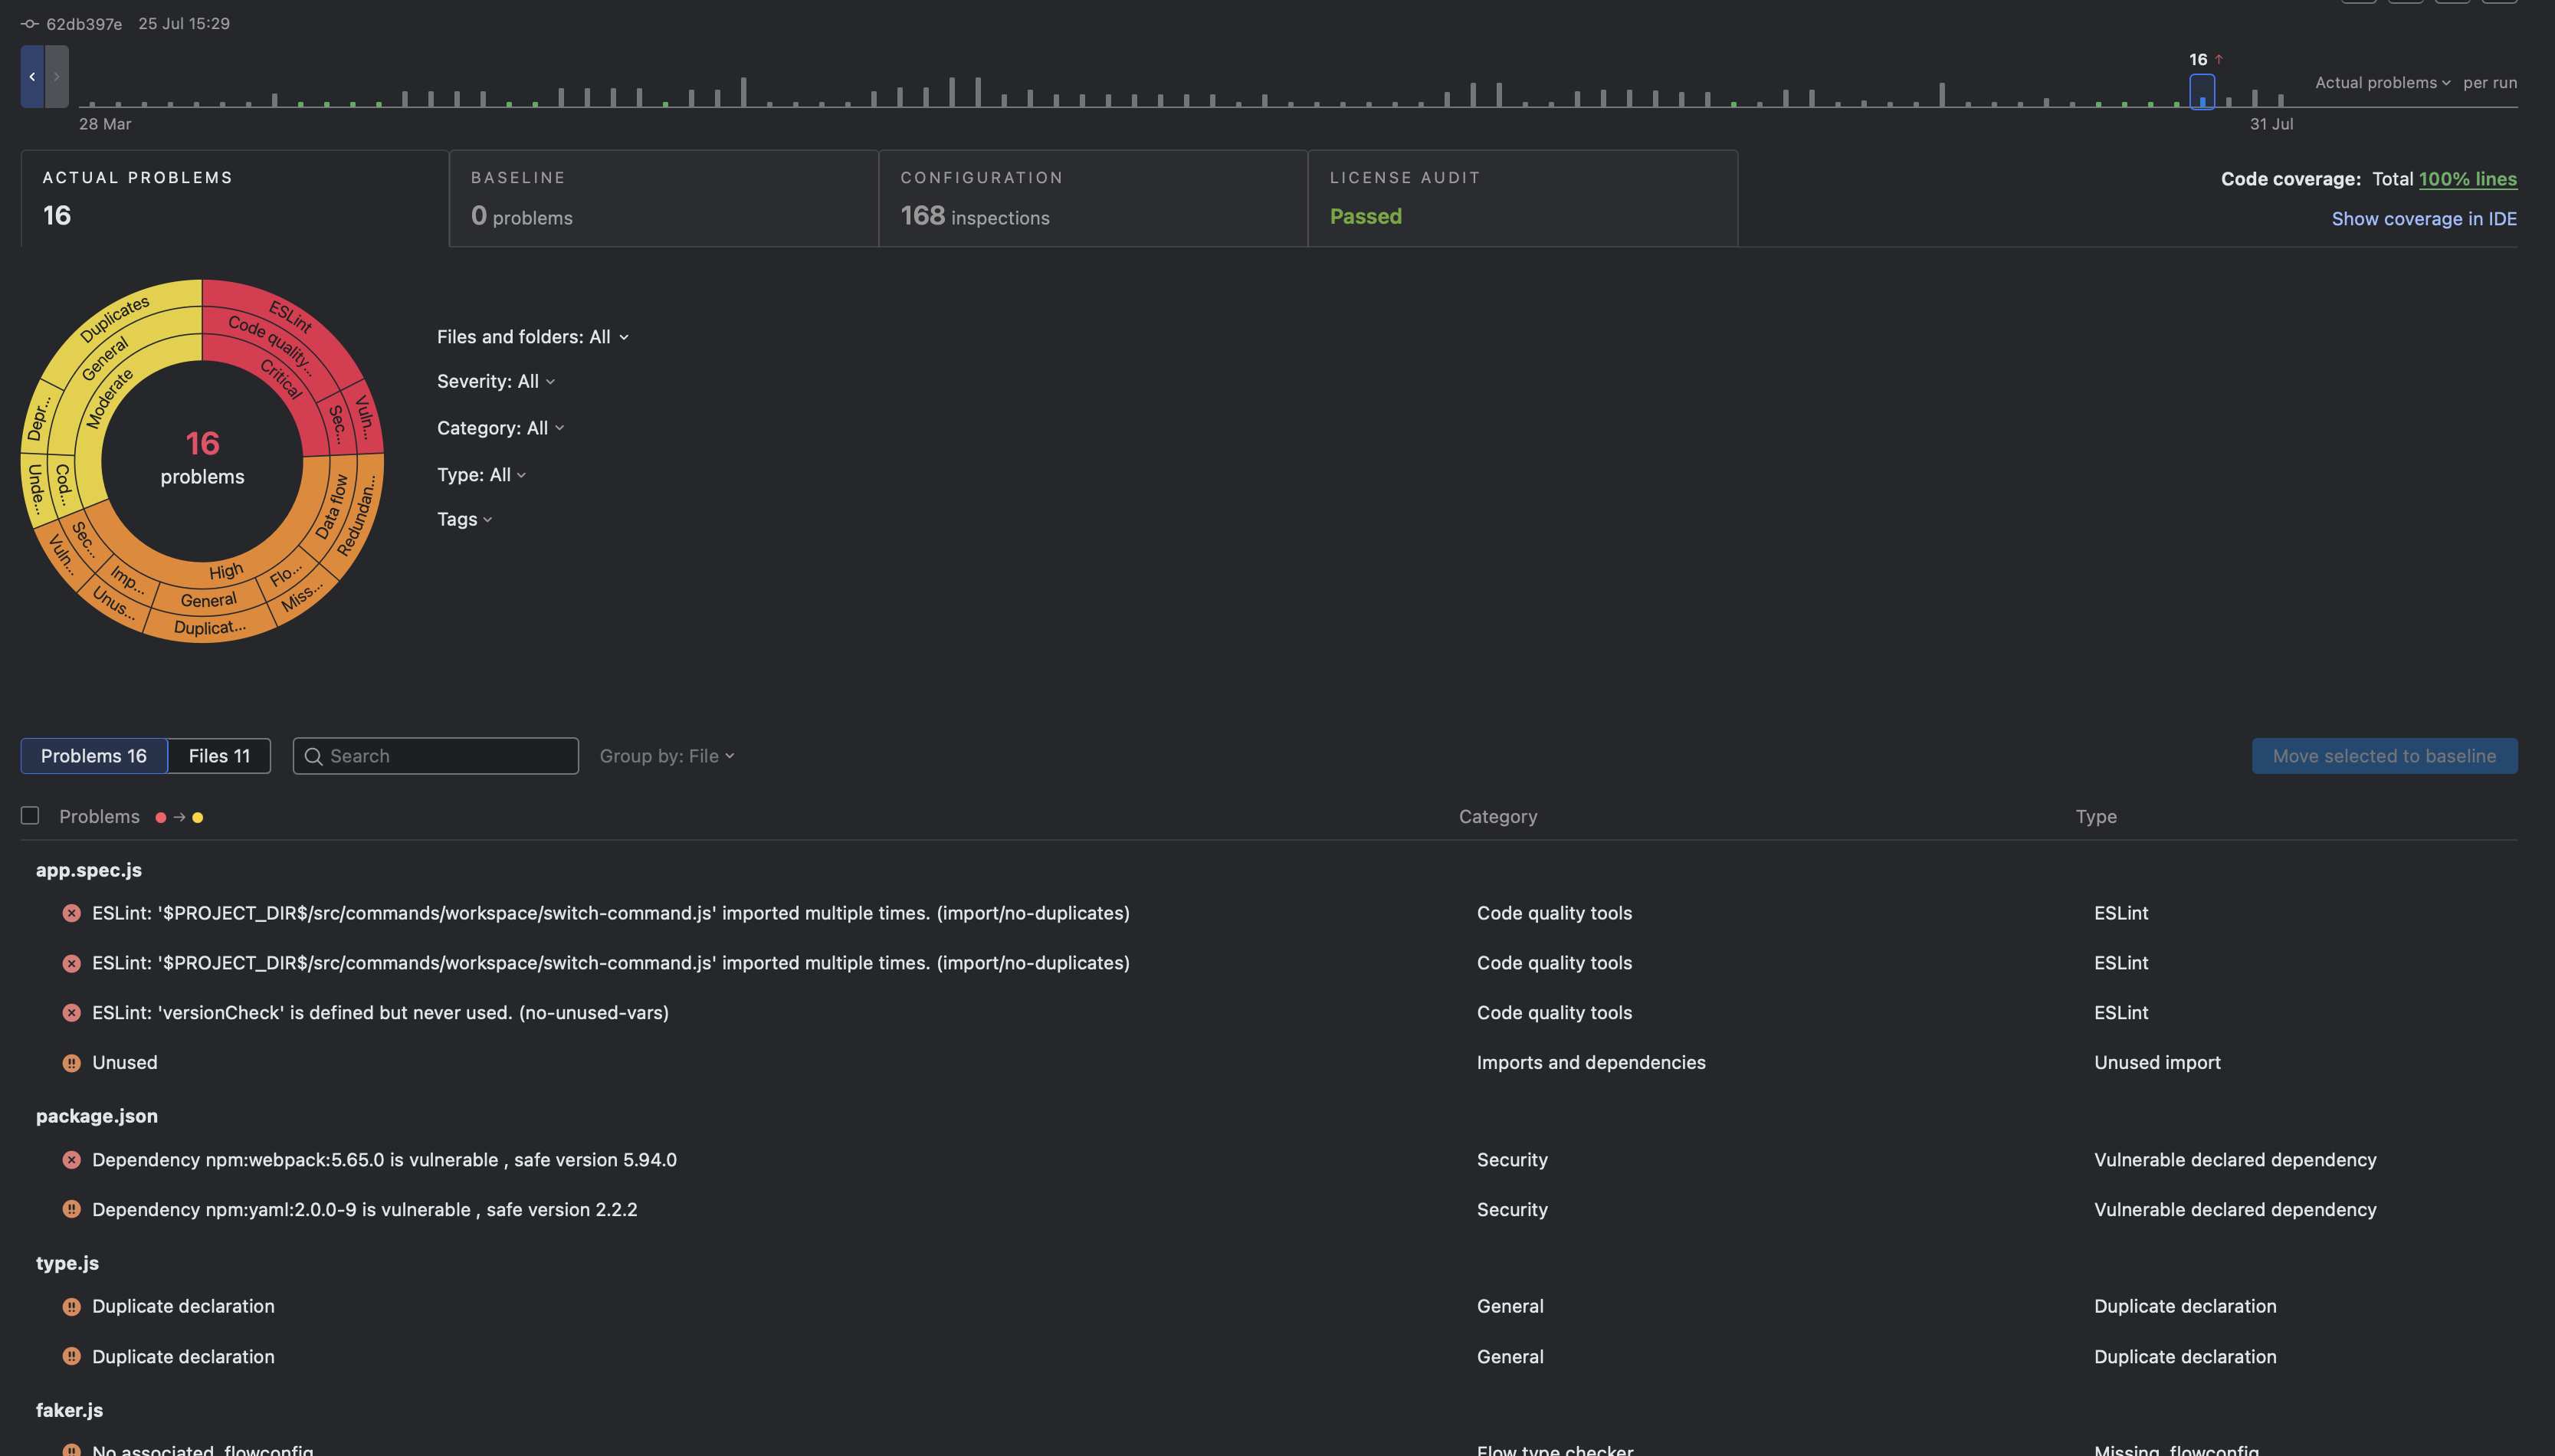
Qodana is a static code analysis and quality assurance tool that complements, rather than replaces, other types of testing. It eliminates many preventable defects during development, achieving high-quality standards throughout the SDLC.

2. Unit testing

Unit testing is a foundation of strong software quality assurance, even with the increasing use of AI and automation. It delivers stability through early error detection to help create maintainable code, testing individual components and functions in isolation to verify each unit performs as expected.

These are common examples of unit testing tools for QA:

  • JUnit is the default Java unit testing standard.
  • Jest offers strong performance for JavaScript and TypeScript development.
  • PyTest is a testing framework in Python.
  • NUnit is flexible and reliable for C sharp and .NET teams.

3. Integration testing

Integration testing tools validate how various components, services, and APIs interact. This identifies errors in data flow and communication that affect functionality so they can be addressed to ensure quality.

Validating integration is important in distributed architectures and microservices. Component interactions here can commonly cause issues, so checking interactions operate as expected ensures high-quality levels.

Examples of integration testing tools include Postman, which specializes in API integration testing with the ability to create and execute API tests. Soap UI also provides comprehensive SOAP and REST support, ideal for enterprise web services and complex service integrations.

4. Functional and UI testing

Functional and end-to-end testing tools simulate real user interactions such as clicking buttons, filling forms, and navigating between pages. They verify an application’s behavior from the user’s perspective and across entire workflows. This goes beyond just the code level to catch issues that only appear when components interact in a live environment.

Automated browser testing is a core for functional and UI testing. It’s particularly important for regression testing, where teams must confirm that new changes don’t break existing functionality.

Tools like Playwright, Cypress, and Selenium let teams script user journeys once and run them repeatedly across browsers and releases. This transforms previously tedious manual click-throughs into fast, repeatable, and reliable QA checks.

5. Performance testing

Validate how an application behaves under expected and unexpected traffic levels with performance testing tools. They reveal quality issues, including bottlenecks, memory leaks, and slow queries under pressure, to address bugs so they don’t reach real users.

This provides assurance that it can handle stress scenarios, beyond simply confirming that features work. It measures how response times hold up as load increases, whether the system recovers from traffic spikes, and where infrastructure limits appear.

Tools like JMeter, LoadRunner, and k6 test performance by simulating realistic traffic patterns, from steady baseline load to sudden surges. JMeter suits complex, protocol-diverse test plans, while k6 offers a developer-friendly, scriptable approach for CI/CD pipeline integration and continuous performance validation.

6. Security testing

Security is integral to software quality assurance and reflects the high costs of late-stage vulnerabilities.

Several types of security testing tools can combine to cover different angles:

  • Static application security testing (SAST) analyzes source code for known vulnerability patterns.
  • Software composition analysis (SCA) and dependency scanning check third-party libraries for common vulnerabilities and exposures (CVEs).
  • Dynamic application security testing (DAST) probes running applications for exploitable weaknesses.
  • Secret detection catches accidentally committed credentials or API keys.

Security testing tools like Qodana move these checks directly into the development workflow. It surfaces vulnerabilities alongside code quality issues during development rather than in a separate, later security review. This reinforces a shift-left approach across the security testing landscape.

How to choose the right software quality assurance tools

Determining the most suitable quality assurance tools depends on your development process and specific business requirements. The most effective strategies combine multiple QA testing tools for comprehensive coverage, rather than relying on just one.

The main factors to consider when comparing and selecting software quality assurance tools are:

Qodana plugs right into youCI/CD pipeline - Software quality assurance tools
  • CI/CD integration: A good QA tool should plug directly into your existing CI/CD pipeline. This enables automatic checks on every commit or build with no manual triggering required.
  • Language support: You need a QA tool that fully supports your codebase’s programming languages and frameworks to avoid incomplete or inaccurate analysis.
  • Automation: Choose tools that automate repetitive testing tasks, reduce manual effort, and enable faster and more consistent feedback throughout development.
  • Scalability: Your tools must support growing codebases, test volumes, and bigger teams with no negative performance or usability impact.
  • Reporting: A QA tool must deliver clear and actionable reporting to help developers understand issues and prioritize fixes.
  • Security: The tool itself must follow strong security practices and identify vulnerabilities within your code or dependencies.

Best practices for building quality into your development workflow

Choosing effective tools is essential, but you must implement them properly to ensure quality at every stage. Whatever tools you use, apply these techniques to build reliable quality assurance into your development workflow:

  • Shift left: Move quality checks early in development, preferable at the point of writing code. This catches defects when they’re cheapest and easiest to fix. Context is fresh and it avoids expensive and reputation-damaging post-production repairs.
  • Automate repetitive quality checks. Routine manual checks are prone to human error and hard to scale. Automating them frees up time and resources, so your team can focus on complex, exploratory testing that requires and benefits from human judgment.
  • Integrate testing into CI/CD pipelines. Run quality checks automatically on every commit or build, not as a separate manual step. Keep feedback fast and prevent issues from accumulating unnoticed.
  • Monitor technical debt. Track code complexity, duplication, and test coverage trends across releases. This helps identify and address quality regressions early.
  • Treat security as integral. Include security scanning and vulnerability checks in your regular QA process rather than treating them as an afterthought. Address vulnerabilities as they arise, don’t reserve them for a pre-release audit.

Build a complete software quality assurance strategy with Qodana

Software quality assurance spans the entire SDLC. It’s not just a final testing action. Combining different tools to address various quality needs at each stage is a modern requirement that reflects today’s demands for speed, complexity, and continuous integration.

Automating static code analysis in development pipelines with tools like Qodana strengthens QA. Surface bugs and vulnerabilities as code is written to ensure high-quality development and reliable performance.

What is software quality assurance?

Software quality assurance (SQA) is the ongoing process of ensuring software meets defined quality, reliability, security, and operational standards throughout the software development lifecycle. Unlike traditional quality control, which tends to focus on finding problems in the finished product, SQA aims to prevent and detect defects throughout development.

What are software quality assurance tools?

Software quality assurance tools help development teams automate and manage activities that improve software quality throughout the SDLC. They include static code analysis tools, unit and integration testing frameworks, functional testing tools, performance testing tools, security scanners, and CI/CD quality controls.

What are the main types of software quality assurance tools?

Common software quality assurance tools include:

Static code analysis tools
Unit testing frameworks
Integration testing tools
Functional and UI testing tools
Performance testing tools

Security testing tools, including SAST, SCA, DAST, and secret detection
Each addresses a different aspect of software quality, so organisations typically combine multiple tools rather than relying on a single solution

How does CI/CD improve software quality assurance?

Integrating QA tools into CI/CD allows quality and security checks to run automatically when code changes. This creates faster feedback for developers, helps prevent issues from accumulating, and makes quality assurance a continuous part of development rather than a separate activity before release.

How does AI-generated code affect software quality assurance?

AI can increase the amount of code developers produce, making scalable and automated quality controls increasingly important. AI can also assist with QA activities, but AI-generated output still needs appropriate validation. Combining automated analysis and testing with human review helps teams maintain quality as development becomes increasingly AI-assisted.

Read the whole story
alvinashcraft
34 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

GitLab and Claude Code: Fast, compliant AI

1 Share

Government agencies are feeling twin pressures: While the U.S. Office of Management and Budget (OMB) is urging you to deploy AI faster, the U.S. Government Accountability Office (GAO) wants guardrails in place before that happens.

To accelerate AI coding, many agencies are turning to AI coding assistants like Anthropic's Claude Code. But what about guardrails? GitLab Duo Agent Platform can govern your entire software development lifecycle, regardless of which model creates your code.

The need for speed with control

To realize the full potential of AI, government agencies need to eliminate the friction that currently exists. For instance, OMB points to outdated compliance processes as one of the biggest obstacles to deploying advanced AI-powered cyber defenses, while GAO says a lack of safeguards is a limiting factor to greater AI adoption.

Agencies utilizing coding assistants might be solving the speed issue, but without a governance strategy, they lack true compliance. Writing code has never been cheaper or faster, but knowing what's in that code before production is another matter.

A governed workflow

In February 2026, the NIST Center for AI Standards and Innovation launched the first federal program dedicated to agentic AI security standards, giving agencies a formal reference for how agents should be authenticated, authorized, and audit-logged.

Meeting that bar takes more than connecting Claude Code to GitLab. An integration passes data between two tools. It doesn't create a shared context model, a policy engine, or a single audit trail. GitLab Duo Agent Platform, AI orchestration across the software development lifecycle, starts with context already built in. It holds the project, the issues, the merge requests, the pipelines, and the vulnerability history — the full picture a standalone coding agent simply doesn't have. Every action Duo Agent Platform takes is scoped, logged, and reviewable inside the platform your agency already runs.

Foundational flows fire automatically on software development lifecycle events, run on the GitLab Runners your agency operates, and tie an audit trail to every merge request, with no script for your team to build or maintain. It's one governance plane across every tool your team runs.

That governance also isn't tied to any single model. AI models and providers are a replaceable component of GitLab's architecture, not an inseparable one, so your agency keeps the ability to authorize, restrict, or swap out which model is doing the writing without rebuilding the workflow around it. Claude Code is a strong example of a model that plugs into that architecture well.

A change is only as useful as what happens after it's written: Can it be safely understood in the context of your delivery system, acted on correctly, documented with the right evidence, and handed back into the workflow your team already governs? Which tool wrote better code doesn't answer that.

Running Claude Code as the coding interface inside GitLab Duo Agent Platform, rather than as a separate, disconnected tool, is how agencies get both Claude's coding experience and GitLab's governed execution in the same system of record. Claude Code's prompting skill carries over whether a developer is working standalone or inside Duo Agent Platform. What changes is where that code goes after it's written, not how a developer writes it.

Where agentic coding strains team workflows

The friction isn't only technical. As agents write more first drafts solo instead of with a teammate, teams are hitting a gap they haven't solved: how review and shared context work when the team wasn't in the room while the code was written. That gap is particularly evident in the government, where not every developer holds the clearance needed to review code on classified or sensitive systems and hiring more reviewers is a security determination that can take months.

GitLab’s own research shows that more than three-quarters of developers say they're writing and committing code faster with AI, yet overall software delivery hasn't sped up at the same rate because the bottleneck moved downstream to review, testing, and collaboration. LinearB's 2026 Software Engineering Benchmarks Report found agentic AI merge requests take 5.3 times longer for a reviewer to pick up than unassisted ones. In an agency running lean on reviewers, that lag compounds rather than just adds up.

That's a governance problem as much as a workflow one. A merge request gate that enforces review, scans, and approvals regardless of which tool generated the change means a team's process for absorbing agent output doesn't have to be reinvented every time the coding tool changes.

Network-restricted deployment vs. AI model choice

Flexibility matters most once you leave the browser and consider where the model runs. Federal environments face this same tension: running without any external network path isn't the same as controlling which model does the work. GitLab Duo Agent Platform Self-Hosted runs entirely on infrastructure an agency controls, covering data residency mandates, air-gapped networks, or policies that bar sending code to third-party APIs. GitLab has continued to expand model support, so agencies aren't forced into using the same model for every job, big or small. Those same models can also run on GPU-enabled virtual machines in a private cloud, for teams that want self-managed inference without the hardware costs.

As of August 2026, GitLab Dedicated for Government customers can deploy the AI Gateway for Duo Agent Platform inside their own single-tenant environment and connect the model provider of their choice, including Amazon Bedrock. Inference stays in their chosen region, under the same SLA, encryption, and change-control model an agency already uses for their workflows.

Get started with GitLab Duo Agent Platform

Claude Code and GitLab Duo Agent Platform aren't a trade-off. They're built to work in tandem. The developers who use Claude Code well should keep using it, the same way, without a new tool getting in the way of how they work. What GitLab Duo Agent Platform adds is a governed merge request gate every change passes through before it ships, regardless of which model or tool wrote it.

Your agency shouldn't have to choose between speed and control. See how GitLab Duo Agent Platform delivers both. Try Duo Agent Platform today.

Read more

Read the whole story
alvinashcraft
34 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories