Signal users on iOS will see this option to toggle blocking screenshots and preventing Siri AI from scanning on-screen content. | Image: Signal
Signal is restricting the ability to take screenshots on Android and iOS devices in an effort to prevent AI agents from reading users' messages and other data. The agentic AI capabilities built into operating systems that analyze on-screen information to learn more about the user are "undermining Signal's ability to independently guarantee privacy," Signal president Meredith Whittaker said in a blog post, while urging OS providers to make it easier for app developers to control what data agents can access.
"We want to be very clear: it is a serious problem that Signal - and application developers beyond - lack robust tools to prevent AI age …
I love using AI as a writing tool. But like I wrote in “Why Does AI Write Like Yoda?,” it’s not because AI is a good writer. In fact, it’s pretty bad at writing, and I edit absolutely everything it generates, so the end result is basically unrecognizable compared to what it created. Unfortunately, just because AI is, on average, a pretty lousy writer, that doesn’t stop people from using AI to write all sorts of things that people end up reading, and that’s how we end up with slop.
That’s where watermarking comes in. If AI-written text carries a hidden signal that a machine can pick up, someone could build slop filters with it and add a little friction to mass-producing AI text and stuffing it into every nook and cranny of the internet and, maybe, manage to keep some spaces on the internet for people. (Anthropic and OpenAI give a more official reason: the EU AI Act now requires them to mark AI-generated content in a way machines can read. I don’t know how they feel about slop.)
The upshot is that almost everything Claude writes now carries a hidden watermark. A slop filter needs a way to check for the watermark. And, unfortunately, for the time being, only the big AI companies and a few organizations they’ve approved can check for it.
Anthropic’s support page on marking AI-generated content now reports all of its newest models, and some older ones, watermark their text on every surface where you can use Claude, worldwide. (Bruce Hopkins covered what Anthropic announced here on Radar.) Google has used a text watermark in its Gemini app since 2024, and in October OpenAI announced it’s adding one to ChatGPT and Codex text in the EU. But none of those companies lets the public check text with its detector. (Google’s synthid.com lets anyone check images, video, and audio for its watermark, including images made with ChatGPT, but it won’t let you check text from any AI lab.)
I’ve read articles about watermarking, but I didn’t really know much about how it worked. So I did what any good developer would probably do: I took a shot at reasoning about it, and I came up with what I thought was a plausible way watermarking could work, based on what I know about how large language models work. And, strangely enough, it turned out I was basically right, and not because I’m some sort of amazing genius. It’s because watermarking is actually pretty straightforward, and if you know how the output part of an LLM works, you can probably design a decent watermarking system yourself.
The reason I’ve got such a big interest in how models work right now is my next O’Reilly book, a deep dive into how models work called Be the Model, which we’re planning on releasing early next year. I’ve spent a lot of time over the last year thinking really hard about how to explain the internals of LLMs, and it turns out that you don’t need to understand most of the parts inside a model to see how watermarking works. All you need is the very tail end.
So let’s try an experiment. I’m going to describe the relevant bits of how models work, and then, before I explain how watermarking works, I want you to take a guess and see how close you come.
The only part of the model you need
There’s a lot of stuff that happens inside a model. You’ve probably heard of transformer blocks, and you might know what a context window is. That’s all part of the whole machine. But at its core, a model is a next-word-predicting machine: You feed it a bunch of text as context, and it predicts the next word. The part that matters for watermarking is what goes into that machine and what comes out.
What goes into the machine is tokens. We all know that when you pay an API bill, you pay some number of dollars per million tokens, but we don’t always explain what a token is. Remember when people discovered that AIs were really bad at counting the r’s in the word strawberry? Part of the reason for that is that the AI never sees letters. It only works with numbers.
Every model has a fixed vocabulary of tokens, which are every word and piece of word it knows, and each token has a number called its token ID. On the way into the machine, a tokenizer splits your text into tokens and replaces each one with its ID. For example, if you ask GPT-2 (an early LLM created by OpenAI in 2019) “how many r’s are in strawberry,” its tokenizer turns the word strawberry into a single token, number 41236. The model gets that number, not the letters s-t-r-a-w-b-e-r-r-y, so it doesn’t have any actual letters to count.
Common words usually get a token of their own. But a word that isn’t in the vocabulary gets split into smaller pieces that are, which is how a tokenizer can handle any text you give it. GPT-2’s vocabulary has a token for "strawberry" with a space in front of it, but not for "strawberry" without the space. So if strawberry is the very first word of the text, with no space in front of it, the tokenizer splits it into three pieces that are in the vocabulary: st, raw, and berry.
GPT-2 has 50,257 tokens in its vocabulary. If you have Python and install the Hugging Face transformers library, you can check GPT-2’s vocabulary size and strawberry tokens with this command:
If you don’t have Python or don’t feel like installing transformers, you can go to ChatGPT, Claude.ai, or Gemini and paste that command in, and they’ll (probably) install the library and run it for you. It should print 50257, then ['Ġstrawberry']['st', 'raw', 'berry']. The Ġ is how this tokenizer writes the space. (If you don’t have PyTorch installed, you’ll see a warning about it first, which you can ignore.)
The token IDs go into the context window, which is just a big array of numbers, and then the AI does its thing. The context window contains every token the model sees when it’s making its next-word prediction. If you’re using a chat, it usually includes the whole conversation so far (your earlier prompts and the AI’s earlier responses) plus any instructions or files the chat app adds behind the scenes. When you send a new message, it typically gets added to the end of the context window, as does every token the AI writes in reply, so the window keeps growing as the conversation goes on (up to a size limit, at which point the app has to compact or drop older parts of it).
What comes out the other end of the machine is a probability for every token in the entire vocabulary: the model’s estimate of how likely each one is to be the next token, with all of them adding up to 100%.
The model’s job ends at the probabilities, and it never picks a word. Picking the next token is the job of a separate program called the inference runtime, or runner. The runner can take the most likely token every time, or it can roll the dice and pick a token at random, giving each one a chance that matches its probability. We’re used to thinking of AI as nondeterministic: give the same AI the exact same prompt 10 times in a row and you’ll get 10 slightly different answers, sometimes wildly different answers. That randomness is all done in the runner. Give the model the same context window and it produces the same probabilities. Then the runner adds the token it picked to the context window and runs the model again to get the next one.
Can you guess how a simple watermark works?
If you wanted to hide a pattern in an AI’s text that you could detect later, and all you could touch was the probabilities or the runner’s dice roll, how would you do it?
Here’s what I guessed. I’d divide the tokens into two groups, then I’d nudge up the probabilities for one group and nudge down the probabilities for the other. Then, since I’d know which tokens are in the favored group, I could do some pretty basic statistical analysis to figure out whether they show up more often than they should, and if they do, the text is probably watermarked.
That turns out to be a real, well-known watermark called the green list method, from a 2023 paper by John Kirchenbauer and his colleagues at the University of Maryland, “A Watermark for Large Language Models.” They called the favored group a green list, and the rest of the vocabulary a red list. Right before it picks, the runner gives every green token’s probability a boost. The red tokens never get touched, but each one’s share goes down, because the probabilities still have to add up to 100%.
Here’s an example. Say a tiny model only knows five words (cat, tree, the, by, and sat), and it has just read the word the, so it’s predicting the next word. The first probability column shows the probability the model gives each of its five words. Now say tree and by are on the green list for this spot, so the runner boosts those two before it picks. The second probability column shows the probabilities after the boost:
next word
probability before
probability after the boost
cat
56.3%
37.9%
tree
20.7%
37.9%
the
12.6%
8.4%
by
7.6%
13.9%
sat
2.8%
1.9%
Tree is now tied with cat. The model produced the same probabilities as before, and the runner boosted two of them after the model was done.
My guess missed an important detail, though. The green list can’t be the same every time the runner picks a token. If it were, the same favored words would show up all over the text, and anyone who read enough of it could work out which ones they were. So the runner determines the green list for each token using a secret key mixed with the token right before it. To check for the watermark, take each token in the text, use the key and the previous token to rebuild its green list, and check whether the token is on it. If the green list is half the vocabulary, you’d expect about half the tokens in ordinary text to be green by chance. In watermarked text, a lot more of them are green. A statistical test tells you how unlikely it would be to get that many green tokens by chance. You don’t need the model to check, just the key and the tokenizer.
SynthID: What Claude actually uses
Anthropic says Claude’s watermark is a version of SynthID-Text, a method Google DeepMind published in Nature in 2024 and uses in its own Gemini app. It works in the runner, just like the green list, but it gets the pattern into the text a different way. Anthropic describes it as a watermark that “only changes the source of the randomness used to pick among words.” So my guess was a real method, but Claude uses a different one.
Here’s the basic idea. Instead of boosting some words’ probabilities, the runner rolls its dice a few times, so it ends up with a few candidates for the next word. Then it flips a coin for each candidate. Whether the coin comes up heads or tails depends on the secret key, the candidate word, and the few words right before it, so anyone with the key can flip the same coin later and get the same result. The runner writes a candidate whose coin came up heads. If every candidate is the same word, there’s nothing to choose between, so the watermark only gets into the spots where the model had a real choice.
To check a text, a detector with the key goes through it word by word, redoes each coin flip, and counts the heads. Ordinary text comes up heads about half the time, and watermarked text comes up heads more often. The real detectors do more than count, but that’s the idea.
That’s kind of involved and hard to picture from a description alone. Luckily, I’ve got a better way for you to understand how watermarking works.
Be the Watermark
I mentioned that my new book, Be the Model, will be out next year. It starts from the fact that AI tools have gotten incredibly sophisticated, even the web chats like ChatGPT and Claude.ai. They can run Python code for you, and they can write an entire interactive HTML page from a single prompt. So why not use them as learning tools?
That’s one of the main ideas behind the book. You’ll use AI tools to create web pages (which I call “toys”) that let you play with different parts of LLMs, and that helps you get an intuitive feel for how they work. The toys let you literally do part of the job that a model does, so you learn how a model works by being the model.
Each toy starts with a short prompt and a picture of what the page should look like. I figured that for this article, you could build a toy to Be the Watermark. I think this is actually a good way to get a feel for how SynthID actually works.
Save the picture below, then copy the prompt under it, and paste them both into a fresh ChatGPT or Claude.ai chat. (In the book, you aren’t handed canned prompts; you come up with most of them yourself.)
Once the AI finishes building it, you’ll have a page with a short story and a secret key, 3 1 4 1 5. Most of the words in the story have a dropdown with near-equivalent words, like creek, pond, lake, and pool. Click Run, and the page checks the story the same way a detector does. It goes through the story one word at a time and flips each word’s coin. To flip the coin, it multiplies the token IDs of that word and the four before it by the five key digits, adds them up, and calls it heads if the last digit is 5 through 9. (In the toy, a word’s token ID is just its position in an alphabetical list of every word on the page.) In the picture, the page is checking creek. The five words tabby, rested, by, the, and creek have token IDs 62, 48, 8, 63, and 11. Multiplied by the key digits 3, 1, 4, 1, and 5, that’s 186 + 48 + 32 + 63 + 55 = 384, and the last digit is 4, so creek comes up tails. Then the page counts the heads. The starting story comes up heads on 14 of its 32 coin flips, which is about half, so the page shows “No watermark found.”
Build one HTML page with a white background that works like the attached picture. Make all of the text, including the button labels and the key digits, a dark color with high contrast against its background. A word’s token ID is its position, counting from 0, in an alphabetical list of every different word in the story and the dropdowns. Ignore case and punctuation.
The story starts: On a sunny day, the tabby rested by the creek. A duck glided over the water. The dog ran to the beach and barked. The toad jumped onto a rock. The bird sang in the tree.
Each word after the first four that’s in one of these groups gets a dropdown with its group: cat/kitten/kitty/tabby, sat/rested/waited/stayed, by/beside/near, pond/lake/pool/creek, duck/goose/swan, swam/paddled/floated/drifted/glided, across/over, dog/puppy/hound/pup, ran/raced/dashed/hurried/rushed, to/toward, shore/bank/beach, barked/yapped/growled/howled, frog/toad, jumped/hopped/leaped/sprang, onto/upon, rock/stone/log, bird/robin/sparrow/wren, sang/chirped/tweeted/whistled, in/from, tree/oak/elm/maple. In an open dropdown, every option shows whether its coin comes up heads or tails in that spot with the current key; a closed dropdown shows just the word.
The coin flip is the sum in the picture: the key digits times the token IDs of the four words before and the word itself. If the sum’s last digit is 5 to 9, it’s heads; 0 to 4 is tails. Check the story one word at a time, starting with the fifth word, animating each product and the growing sum, highlighting the word and the four before it, and counting the heads. A full run takes about 10 seconds. When the check finishes with at least 60% heads, animate a checkmark badge reading “Watermark detected” beside the heads count; otherwise show “No watermark found.” Changing the key or a word clears the heads count. Use only Step, Run, and Reset buttons. Reset keeps the key and the words.
Your job is to be the watermark. When you open a dropdown, it shows whether each word in it would come up heads or tails in that spot with the current key. Swap some tails words for heads words and run the check again. When at least 60% of the coin flips come up heads (20 of the 32), the page shows a “Watermark detected” badge. Every time you pick a heads word from a dropdown, you’re doing the runner’s job. The one difference is that the runner can only choose among the few candidates its dice rolls turned up, so sometimes there are no heads word to pick.
It’s a little harder than it seems because when you swap one word, it changes the coin flips for the next four words too. Each word’s coin flip uses that word and the four words before it, so the word you just swapped is part of the next four sums, and any of those coin flips can come out differently. A few things to know:
A swap never changes the coin flips for words before it, so it helps to work from left to right, the same way the runner writes.
A swap can cost you a heads on a word that doesn’t have a dropdown, like the or water. The only way to fix one of those is to change a word before it.
If you go back and change an earlier word, some of the words you already picked might now come up differently, so check the dropdowns again.
See if you can get the page to show a watermark for your story.
Once you get the badge, change the last digit of the key to 6 and run the check again. Your heads count will probably drop back toward half and the watermark badge will disappear, even though the watermark is still there, because the page is checking with the wrong key. (A story can still pass with the wrong key by chance.)
You’ll also notice that the first four words, “On a sunny day,” don’t have dropdowns, and the check doesn’t start until the fifth word. A coin flip needs a word and the four words before it, so the first four words don’t have enough words before them to flip a coin.
If you want to see the math for a particular word, ask the AI that built the page how it calculated whether that word comes up heads or tails. It should walk you through the token IDs, the key digits, and the sum. And if the animation feels slow, you can ask it to redo the page so the animation runs faster. To get the original story back, reload the page.
The toy’s vocabulary has 75 words, and 48 of them, like pool and puppy, don’t show up in the starting story. They’re the near-equivalent words in the dropdowns. A real model’s vocabulary works the same way because it’s fixed ahead of time and any one passage uses only a small part of it.
A story this short also shows why real detectors work better on longer text. With 32 fair coin flips that don’t affect each other, you’d get at least 60% heads about one time in 9, so a badge on a story this short doesn’t prove much. Over hundreds of words, the odds of that proportion of heads by chance get very small.
The toy is a lot simpler than the real thing. Real token IDs aren’t alphabetical. Real SynthID uses a much bigger key, mixes the key and the words together with a hash function instead of a sum, and plays several rounds of coin flips for every word instead of one. And its detectors weigh those rounds differently and are trained on watermarked and ordinary text for each key, instead of just counting heads.
Why you can’t check it yet
You just did the thing the AI companies are worried about. With the key, you could see which words came up heads and swap them, and the same trick works in the other direction: Someone with the key could strip the watermark out of AI text or write text that’s heavy on heads on purpose and make something a person wrote look like Claude wrote it. If the companies made their keys public, someone could easily write a watermark detector for your favorite text editor that fixed the text to remove the watermark, and that would defeat the whole purpose.
That’s likely why they keep their keys to themselves, and why right now only they and a few organizations they’ve approved can check for the watermark. I don’t know whether or not I agree with that reasoning, but I can understand that the issue is complicated. In the meantime, I’m applying for access to Claude’s detector (hence the “yet” in the title of this article).
Paola Elefante: Scrum Masters Who Build Ownership Instead Of Team Dependency
In this episode, we refer to Sprint Goals and Product Owner/Scrum Master collaboration.
The Great Scrum Master: Clear Responsibilities, Preparation, And Team Safety
Read the full Show Notes and search through the world's largest audio library on Agile and Scrum directly on the Scrum Master Toolbox Podcast website: http://bit.ly/SMTP_ShowNotes.
"After a year and a half or so of working together, we were even reading each other's mind." - Paola Elefante
Paola's great Scrum Master example is Petri, a Scrum Master who prepared before meetings, respected the team's time, and kept discussions focused. He knew when to park a topic, when a story was not refined enough for planning, and how story-level prioritization connected to the roadmap Paola owned. Their collaboration worked because responsibilities were explicit. Petri protected the team's day-to-day focus, removed obstacles, and became the go-to person for detailed team questions. Paola handled external stakeholders, roadmap direction, and feature-level trade-offs. The team knew who to ask, which created safety and reduced friction. Over time, the collaboration became so tight that Paola and Petri anticipated each other's needs. For listeners, the practical lesson is clear: great PO/SM collaboration starts with transparent communication and agreed responsibility areas, then becomes trust through repeated small decisions.
Self-reflection Question: Does your team know who owns which kind of decision, or do people have to guess every time they need help?
The Bad Scrum Master: Becoming The Owner Of Every Scrum Event
Read the full Show Notes and search through the world's largest audio library on Agile and Scrum directly on the Scrum Master Toolbox Podcast website: http://bit.ly/SMTP_ShowNotes.
"The whole thing is a shared responsibility, and these are just the tools to make sure that we can deliver on it." - Paola Elefante
Paola does not describe a personal bad Scrum Master story. Instead, she names a pitfall Scrum Masters can fall into: making the ceremonies flow so smoothly that the team starts leaning on the Scrum Master to own them. The Scrum Master prepares, facilitates, calls the next person, asks the hard questions, and slowly the team becomes passive. Paola connects this to sprint goals. If the team stays silent, the easy move is for the facilitator or Product Owner to suggest the sprint goal. The better move is to let the silence exist and ask the team what they can promise for the sprint. That moment transfers ownership back where it belongs. Scrum events are not performances delivered by the Scrum Master. They are tools the team uses to take responsibility for delivery.
Self-reflection Question: Where are you making an Agile event easier in a way that may also be making the team less responsible?
[The Scrum Master Toolbox Podcast Recommends]
🔥In the ruthless world of fintech, success isn't just about innovation—it's about coaching!🔥
Angela thought she was just there to coach a team. But now, she's caught in the middle of a corporate espionage drama that could make or break the future of digital banking. Can she help the team regain their mojo and outwit their rivals, or will the competition crush their ambitions? As alliances shift and the pressure builds, one thing becomes clear: this isn't just about the product—it's about the people.
🚨 Will Angela's coaching be enough? Find out in Shift: From Product to People—the gripping story of high-stakes innovation and corporate intrigue.
Paola is a Product Owner whose career has taken her from software development and project management to international development and, eventually, a PO role. Today she works on B2B IoT solutions. Her varied experience has shaped how she think about Agile, software development, and the importance of adapting practices to the reality of people and teams.
TL;DR: The new Syncfusion® JavaScript Excel Library enables developers to work with Excel workbooks programmatically in JavaScript and TypeScript applications. Developers can create and open XLSX files, manage worksheets and cells, apply formatting, define formulas, add charts, and configure data validation and protection. This blog explores the library’s key features and demonstrates how to generate and download an Excel workbook in an application without requiring Microsoft Excel.
Introduction
Creating an Excel file may seem straightforward at first. However, as application requirements grow, developers may need to generate business reports, export large datasets, and create workbooks containing multiple worksheets, formulas, and charts. Handling these operations can become increasingly complex.
Relying on manual spreadsheet operations or desktop-based automation can also introduce additional dependencies and maintenance challenges. Developers need a way to work with Excel files programmatically within their applications.
The new Syncfusion® JavaScript Excel Library provides a programmatic way to handle this process and is available as a preview in Essential Studio® 2026 Volume 3.
The library enables developers to create, read, modify, format, and save Excel (.xlsx) workbooks using JavaScript or TypeScript. It supports browser and Node.js environments without requiring Microsoft Excel or COM automation.
In this blog, we’ll explore the library’s key features and demonstrate how to create and download an Excel workbook in a React application.
Why choose the Syncfusion JavaScript Excel Library?
As spreadsheet requirements grow, traditional Excel automation approaches can introduce additional dependencies and maintenance challenges.
For example, Office Interop automation requires Microsoft Excel and a compatible Windows environment. Lightweight spreadsheet generators may also have limitations when handling complex formatting, formulas, and workbook structures.
The Syncfusion JavaScript Excel Library provides a JavaScript-based approach to workbook processing. Here’s how it compares with traditional Office Interop automation.
Traditional Office interop vs. Syncfusion JavaScript Excel Library
Comparison
Traditional Office interop
Syncfusion JavaScript Excel Library
Microsoft Excel dependency
Requires Microsoft Excel installation
Does not require Microsoft Excel
COM dependency
Uses COM automation
No COM dependency
Execution environment
Windows environment with compatible Office installation
Browser and Node.js
Application integration
Requires Office automation setup
Integrates with JavaScript and TypeScript applications
Workbook processing
Automates an installed Excel application
Uses a programmatic workbook object model
Deployment
Requires managing Office installation and automation dependencies
Runs within supported JavaScript environments
With the Syncfusion library, developers can create and manage Excel workbooks directly through JavaScript or TypeScript without launching a desktop Excel application. This makes it useful for browser-based exports, server-side report generation, and spreadsheet-processing features in modern web applications.
Key features of the JavaScript Excel Library
Once spreadsheet generation becomes part of an application, developers often need more than basic cell exports. Reports may require multiple worksheets, formulas, structured tables, formatting, charts, and protection.
Workbook and worksheet management: Create new workbooks, open existing .xlsx files, and manage worksheets, named ranges, document properties, and frozen panes.
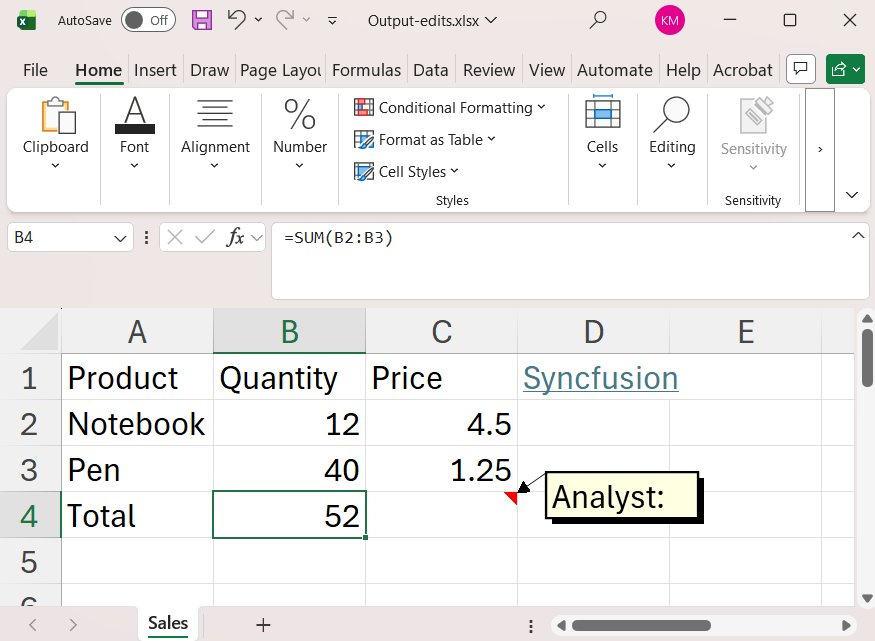
Modifying an existing worksheet using the JavaScript Excel Library
Cell operations and formulas: Work with cell values such as strings, numbers, dates, and Boolean values. Define mathematical, logical, statistical, and financial formulas. The library stores formula expressions; Microsoft Excel recalculates them when the workbook opens.
Performing cell operations in an Excel Workbook
Tables and structured data: Create tables and named ranges to organize business records. Tables provide structured data regions that can include header rows, totals rows, and styles.
Formatting and visual elements: Customize cell styles, fonts, borders, alignment, background fills, and conditional formatting. Add images, text boxes, and AutoShapes to improve workbook presentation.
Charts and data analysis: Create charts to visualize spreadsheet data. Use sorting and filtering to organize and analyze information.
Visualizing data with charts in JavaScript Excel Library
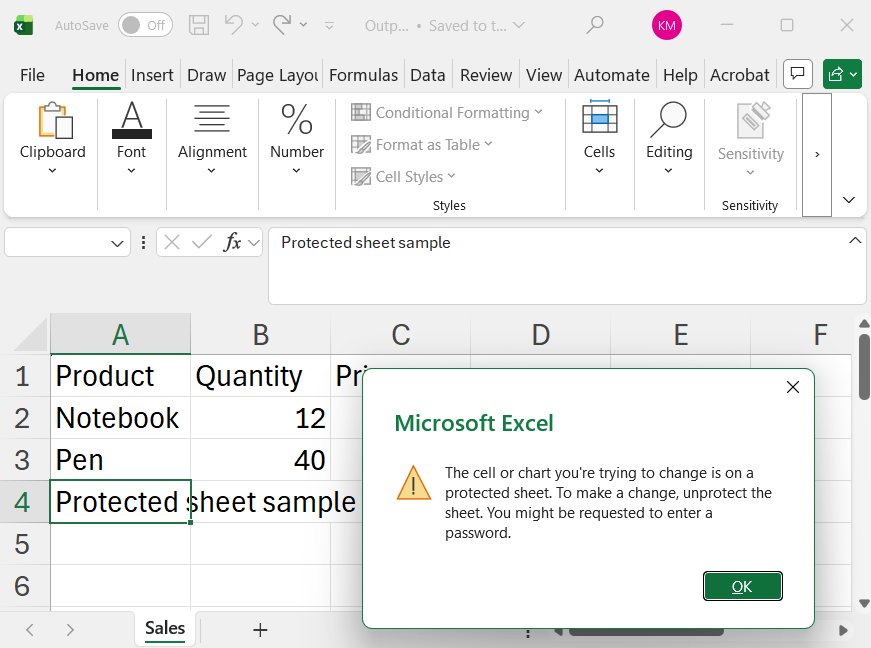
Data validation and protection: Configure data-validation rules and protect worksheets or workbooks to control permitted changes.
Protecting data in an Excel worksheet
Interactive spreadsheet elements: Create and manage form controls for spreadsheet-based data-entry scenarios.
These capabilities help developers generate structured reports, update existing workbooks, and automate spreadsheet workflows within JavaScript applications.
Getting started: Create and download an Excel workbook in React
Before exploring advanced spreadsheet workflows, let’s start with a common requirement: generating an Excel file directly from a web application.
In this example, we’ll use React to create and download an Excel workbook containing sample sales data. While this guide uses React, the JavaScript Excel Library also supports Angular, Vue, JavaScript, ASP.NET Core, and ASP.NET MVC, making it easy to generate and manage Excel files across different application frameworks.
Prerequisites
Before getting started, make sure you have:
Node.js 18 or later.
npm 9 or later (or Yarn 1.22 or later).
React 18 or later.
Visual Studio Code or your preferred code editor.
A modern browser such as Chrome, Edge, or Firefox.
Step 1: Create a React Application
We’ll use Vite to create the React project. Run the following commands in your terminal:
Install the library using the following npm command:
npm install @syncfusion/ej2-xlsx --save
Step 3: Generate and download a workbook
Create a new workbook, rename its default worksheet, and add the headers and sample data. The following code downloads the workbook when the user clicks the Generate Excel button.
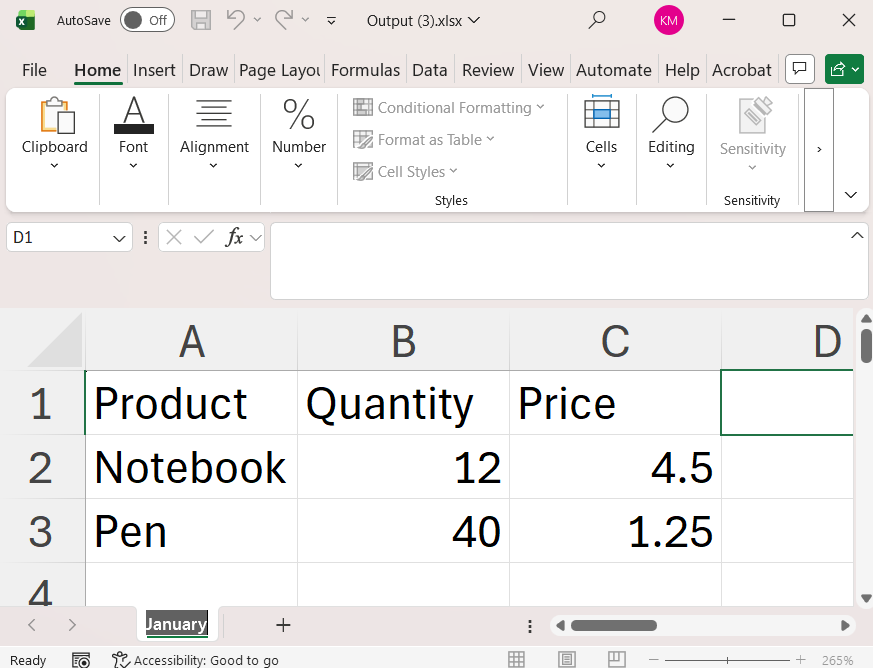
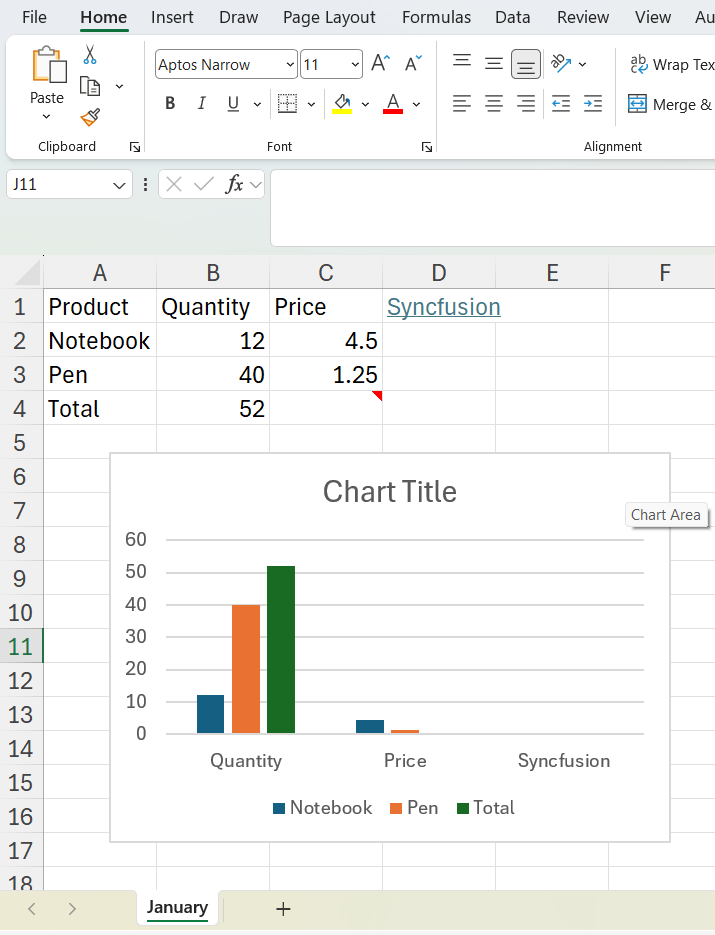
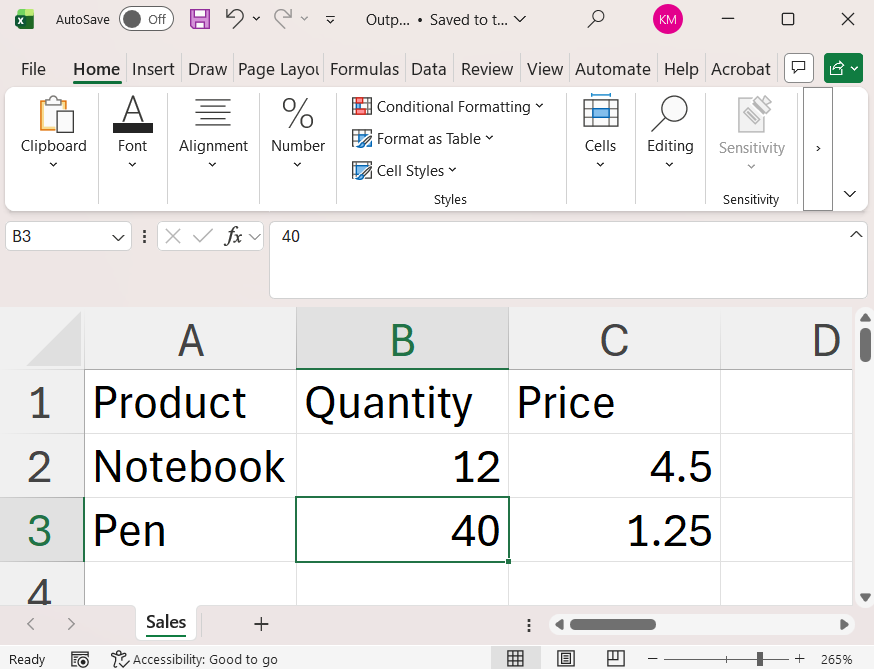
Run the React application and click the Generate Excel button. The browser downloads a file named Output.xlsx containing a worksheet named Sales with the sample product, quantity, and price data.
Refer to the following image.
Creating and downloading an Excel worksheet using the Syncfusion JavaScript Excel Library
This example demonstrates the basic workbook-generation process. You can extend the same approach to add worksheets, formulas, formatting, charts, and other spreadsheet features as your application requirements grow.
Consider a SaaS platform that delivers monthly performance reports to hundreds of customers.
Each report may contain:
Executive summary: A worksheet showing total sales and key performance metrics.
Transaction details: Product names, quantities, prices, and individual order records.
Revenue calculations: Formulas for calculating totals and other financial values.
Charts: Visual representations of monthly sales and growth trends.
Worksheet protection: Restrictions that help prevent accidental changes to important workbook content.
Maintaining these reports manually can become time-consuming, especially when the application generates them regularly for many customers.
With the JavaScript Excel Library, developers can create each workbook programmatically, populate it with the latest application data, organize the information into worksheets, apply formatting, and configure worksheet protection. The application can then save the generated workbook and make it available for download.
For example, a reporting service can generate a separate workbook for each customer at the end of the month. Each workbook follows the same structure while containing that customer’s latest sales data.
This approach reduces repetitive spreadsheet work and helps keep reports consistent across customers.
What’s coming next?
Spreadsheet requirements continue to evolve. As reporting systems mature, developers may need more advanced workbook operations, file conversions, analytics, and security features.
The original product roadmap identifies the following areas for future enhancements:
Advanced workbook features: Worksheet cloning and merging content across multiple workbooks.
Additional file formats and conversions: Support for formats such as .xlsm, .xltm, .xlsb, .xltx, .csv, and .tsv, along with Excel-to-PDF conversion.
Advanced analytics: Pivot tables and pivot charts for multidimensional data summarization.
Extended spreadsheet capabilities: Features such as slicers, sparklines, template markers, OLE objects, and group shapes.
Data governance and security: Encryption, decryption, and digital signatures for document-protection and compliance scenarios.
These planned enhancements aim to expand workbook processing, reporting, and document security capabilities in future updates. Refer to the official release notes for the latest availability information.
Frequently Asked Questions
Does the JavaScript Excel Library require Microsoft Office to be installed on the server?
No. The Syncfusion JavaScript Excel Library is a standalone spreadsheet engine built with TypeScript and JavaScript. It runs directly in Node.js environments and modern web browsers, eliminating the need for Microsoft Excel installations, Office Interop dependencies, or third-party background services.
Which JavaScript frameworks and runtimes does the Excel Library support?
The library integrates seamlessly with modern JavaScript environments, including ECMAScript/TypeScript applications, Node.js (18+), React, Angular, Vue, and Next.js. It can also be used on serverless platforms such as AWS Lambda and Azure Functions.
Which Excel features does the JavaScript Excel Library support?
Developers can programmatically create and manage worksheets, cells, ranges, formulas, tables, charts, images, hyperlinks, comments, data validation rules, and workbook or worksheet protection settings.
Which file formats does the JavaScript Excel Library support?
The current release supports the Excel .xlsx format, which is compatible with Microsoft Excel 2007 and later versions, including Microsoft 365.
Does the JavaScript Excel Library support workbook and worksheet protection?
Yes. The library includes workbook and worksheet protection features that help prevent unauthorized modifications, safeguard formulas and critical data, and maintain the integrity of spreadsheet content.
Automate Excel Reports in JavaScript
Create, read, edit, and format Excel workbooks in browser and Node.js apps with the Syncfusion JavaScript Excel Library. Work with formulas, tables, charts, and worksheet protection without Microsoft Excel.
Automating Excel tasks becomes easier when developers can manage workbooks directly within their applications. The Syncfusion JavaScript Excel Library provides a simple way to create, read, edit, format, and process Excel workbooks using JavaScript or TypeScript.
With support for browser and Node.js environments, developers can automate spreadsheet operations without depending on Microsoft Excel or COM automation. Whether you’re generating business reports, exporting application data, or managing existing workbooks, the library helps simplify these tasks.
Available as a preview in Essential Studio 2026 Volume 3, the library brings new possibilities for Excel automation in modern JavaScript applications.
TL;DR:To validate GPS coordinates in SQL Server, stage the raw latitude and longitude as text, check each value’s format and range, log failures with a rejection reason, and only then pass the accepted pairs to geography::Point().
This stops malformed values, such as the word “north”, a blank longitude or a latitude of 95, from breaking your load, and it lets you run distance queries on clean spatial data.
This article follows 12 fictional service locations from raw input to a “within 10 km” search. It also shows the one thing numeric validation can’t catch: a swapped latitude and longitude that passes every check.
In brief:
– Stage the raw coordinates as nvarchar so nothing is lost or rounded before validation.
– Normalize each value by trimming spaces and turning empty strings into NULL.
– Check the format, then convert with TRY_CONVERT() to decimal(9,6) for latitude and decimal(10,6) for longitude.
– Check ranges (latitude -90 to 90, longitude -180 to 180) and assign one rejection code per failed row.
– Build geography points from accepted rows only, in a separate statement.
– Keep rejected rows with their original text and query accepted points with STDistance().
Read on for the full guide, including code.
Why bad coordinates break geography::Point() loads
A list of service locations comes in with a name, latitude, and longitude for each entry. Most of the coordinates look fine…but not all. One entry, for example, contains the word “north” instead of a latitude. Another has a blank longitude. And a third entry has a latitude of 95 degrees.
This is a problem, as the valid rows still need to be loaded to be used for searches – such as finding locations within 10 km of a customer.
Passing the raw values directly to geography::Point() can also cause problems. Malformed text may fail during conversion, an out-of-range coordinate may pass through a weak validation process, and some mistakes can still produce a valid point in the wrong place.
This article follows twelve fictional records from the raw input through validation and, finally, to a distance query. The original coordinate values are preserved, each row is checked against clear validation rules, rejected records are stored with a reason, and only accepted coordinate pairs are converted to SQL Server geography values.
One deliberately swapped pair, meanwhile, is kept in the ‘accepted’ set. This is to demonstrate an important limitation: numeric validation alone cannot prove that a location is correct.
The sample coordinates are assumed to use World Geodetic System (WGS) 84, represented here by SRID 4326. The geography data type is appropriate for this example because the coordinates represent locations on the Earth.
The geometry type represents data in a flat Euclidean coordinate system – with the choice between them depending on the coordinate system being used and thetype of calculation required.
The test environment and table design
I tested the examples on SQL Server 2022 Developer Edition, build 16.0.1000.6, using a GPSGeographyDemo database at compatibility level 160.
The example uses three tables, each with a different job:
dbo.GPSImportStage keeps the coordinate values exactly as they arrived.
dbo.ValidLocations stores the rows that pass validation, including their parsed latitude and longitude values and the final geography point.
dbo.GPSImportRejects stores rows that fail validation together with the reason for rejection.
The two coordinate columns in the staging table use nvarchar deliberately.
Step 1: Stage raw coordinates as text
The raw staging table
CREATE TABLE dbo.GPSImportStage
(
    ImportRowID int NOT NULL,
    LocationName nvarchar(100) NOT NULL,
    RawLatitude nvarchar(50) NULL,
    RawLongitude nvarchar(50) NULL,
    LoadedAt datetime2(0) NOT NULL
        CONSTRAINT DF_GPSImportStage_LoadedAt
        DEFAULT (SYSUTCDATETIME()),

    CONSTRAINT PK_GPSImportStage
        PRIMARY KEY CLUSTERED (ImportRowID)
);
Converting the coordinates as soon as they arrive could remove useful information before validation has a chance to inspect it. A blank value might be mistaken for zero, or extra decimal places might be rounded during conversion. Keeping the incoming values as text means the validation process can work with the original input.
The 50-character limit is only part of this demonstration. In a production landing process, the complete source value should be preserved, or an over-length value should be rejected before any truncation takes place. Once part of the original value has been lost, the validator cannot recover it.
The 12-row sample batch
The sample batch contains the following rows:
The original sample batch
ID
Location
Raw latitude
Raw longitude
1
London Central
51.5074
-0.1278
2
Camden Service Point
51.5416
-0.1433
3
Greenwich Service Point
51.4826
0.0077
4
Heathrow Depot
51.4700
-0.4543
5
Manchester Depot
53.4808
-2.2426
6
Missing Latitude
NULL
-0.1180
7
Blank Longitude
51.5150
(three spaces)
8
Bad Latitude Text
north
-0.1410
9
Bad Longitude Text
51.5200
west
10
Latitude Out of Range
95.0000
-0.1278
11
Longitude Out of Range
51.5074
190.0000
12
Karachi – Swapped Example
67.0011
24.8607
In the sample batch, Row 6 contains a database NULL, and Row 7 contains three ordinary spaces in the longitude field.
ImportRowID, meanwhile, identifies the incoming source row. When a row is accepted, that value is copied into SourceImportRowID.
LocationID is a separate identity value generated by dbo.ValidLocations. SourceImportRowID then provides the link back to the original staged row, while LocationID identifies the accepted location inside the destination table.
Step 2: Create tables for accepted and rejected rows
The two output tables separate accepted rows from rejected rows. The accepted rows keep the parsed coordinates and the final geography value, while the rejected rows keep the text so the source data can still be investigated.
The output tables
CREATE TABLE dbo.ValidLocations
(
    LocationID int IDENTITY(1,1) NOT NULL,
    LocationName nvarchar(100) NOT NULL,
    Latitude decimal(9,6) NOT NULL,
    Longitude decimal(10,6) NOT NULL,
    GeoPoint geography NOT NULL,
    SourceImportRowID int NOT NULL,

    CONSTRAINT PK_ValidLocations
        PRIMARY KEY CLUSTERED (LocationID),

    CONSTRAINT UQ_ValidLocations_SourceImportRowID
        UNIQUE (SourceImportRowID)
);

CREATE TABLE dbo.GPSImportRejects
(
    ImportRowID int NOT NULL,
    LocationName nvarchar(100) NOT NULL,
    RawLatitude nvarchar(50) NULL,
    RawLongitude nvarchar(50) NULL,
    RejectCode varchar(40) NOT NULL,
    RejectReason nvarchar(250) NOT NULL,
    RejectedAt datetime2(0) NOT NULL
        CONSTRAINT DF_GPSImportRejects_RejectedAt
        DEFAULT (SYSUTCDATETIME()),

    CONSTRAINT PK_GPSImportRejects
        PRIMARY KEY CLUSTERED (ImportRowID)
);
Here, dbo.ValidLocations gives each accepted location its own LocationID, while SourceImportRowID keeps the link back to the staged row.
The unique constraint on SourceImportRowID also prevents the same source row from being loaded into the accepted table more than once.
dbo.GPSImportRejects uses the original ImportRowID as its primary key and keeps the raw latitude and longitude text together with the rejection code and reason. This makes it possible to investigate a failed row without losing the source values that caused the rejection.
Step 3: Parse latitude and longitude safely with TRY_CONVERT()
A decimal point is optional but, when one is present, there must be digits on both sides of it (with no more than six digits after the decimal point.)
Ordinary spaces, meanwhile, are allowed at the beginning or end of the value – but tabs, commas, scientific notation, degree symbols, and embedded spaces are not accepted in any form.
These rules form the contract for this particular feed. Another source might allow scientific notation or a greater number of decimal places, but that would require a different set of validation rules and tests.
Normalize values with TRIM() and NULLIF()
Normalization begins by removing ordinary spaces from both ends of the value. If nothing remains, NULLIF() turns the empty string into NULL.
Normalize latitude for validation
NULLIF(
    TRIM(RawLatitude) COLLATE Latin1_General_100_BIN2,
    N''
) AS LatitudeText
The longitude uses the same expression. By default, TRIM() removes ordinary char(32) spaces from the beginning and end of the string. Tabs and nonbreaking spaces remain in place, however, so the later format checks can reject them, and a coordinate value of zero is valid data (so must remain different from a missing value.)
For the character checks, an optional leading sign is removed temporarily and the rest of the text is examined. The remaining value must start and end with a digit, contain only digits, have one decimal point at most, and contain no more than six digits after the decimal point.
The Latin1_General_100_BIN2 collation makes these checks follow the ASCII-based rules defined for this feed instead of relying on linguistic comparison rules.
After a value passes the format checks, TRY_CONVERT() attempts to convert latitude to decimal(9,6) and longitude to decimal(10,6). TRY_CONVERT() the returns NULL if a value cannot be converted to the required decimal type.
This allows the validation logic to handle the row instead of stopping the import.
For example, 90.0000004 could become 90.000000 when converted to decimal(9,6). That would hide the fact that the original latitude was greater than 90. By rejecting values with more than six fractional digits before conversion, the parser avoids this problem.
The same rule also rejects an otherwise valid-looking value such as 51.5074001. That is intentional: both cases are treated consistently according to the format contract for this feed.
Fast, reliable and consistent SQL Server development…
…with SQL Toolbelt Essentials. 10 ingeniously simple tools for accelerating development, reducing risk, and standardizing workflows.
Step 4: Validate ranges and assign rejection codes
The next query brings the parsing rules together and assigns one validation result to each staged row.
It returns the original values, the parsed coordinates, and the final validation result without inserting anything into the output tables or constructing a geography value.
Preview the complete validation result
;WITH Normalized AS
(
    SELECT
        ImportRowID,
        LocationName,
        RawLatitude,
        RawLongitude,
        NULLIF(TRIM(RawLatitude) COLLATE Latin1_General_100_BIN2, N'')
            AS LatitudeText,
        NULLIF(TRIM(RawLongitude) COLLATE Latin1_General_100_BIN2, N'')
            AS LongitudeText
    FROM dbo.GPSImportStage
),
CoordinateBodies AS
(
    SELECT
        *,
        CASE WHEN LEFT(LatitudeText, 1) IN (N'+', N'-')
             THEN SUBSTRING(LatitudeText, 2, 50)
             ELSE LatitudeText
        END AS LatitudeBody,
        CASE WHEN LEFT(LongitudeText, 1) IN (N'+', N'-')
             THEN SUBSTRING(LongitudeText, 2, 50)
             ELSE LongitudeText
        END AS LongitudeBody
    FROM Normalized
),
Parsed AS
(
    SELECT
        *,
        CASE
            WHEN LatitudeBody LIKE N'[0-9]%'
             AND RIGHT(LatitudeBody, 1) LIKE N'[0-9]'
             AND LatitudeBody NOT LIKE N'%[^0-9.]%'
             AND LatitudeBody NOT LIKE N'%.%.%'
             AND (CHARINDEX(N'.', LatitudeBody) = 0
                  OR LEN(LatitudeBody) - CHARINDEX(N'.', LatitudeBody) <= 6)
            THEN TRY_CONVERT(decimal(9,6), LatitudeText)
        END AS ParsedLatitude,
        CASE
            WHEN LongitudeBody LIKE N'[0-9]%'
             AND RIGHT(LongitudeBody, 1) LIKE N'[0-9]'
             AND LongitudeBody NOT LIKE N'%[^0-9.]%'
             AND LongitudeBody NOT LIKE N'%.%.%'
             AND (CHARINDEX(N'.', LongitudeBody) = 0
                  OR LEN(LongitudeBody) - CHARINDEX(N'.', LongitudeBody) <= 6)
            THEN TRY_CONVERT(decimal(10,6), LongitudeText)
        END AS ParsedLongitude
    FROM CoordinateBodies
)
SELECT
    ImportRowID,
    LocationName,
    RawLatitude,
    RawLongitude,
    ParsedLatitude,
    ParsedLongitude,
    CASE
        WHEN LatitudeText IS NULL
            THEN 'MISSING_LATITUDE'
        WHEN LongitudeText IS NULL
            THEN 'MISSING_LONGITUDE'
        WHEN ParsedLatitude IS NULL
            THEN 'INVALID_LATITUDE_FORMAT'
        WHEN ParsedLongitude IS NULL
            THEN 'INVALID_LONGITUDE_FORMAT'
        WHEN ParsedLatitude NOT BETWEEN -90 AND 90
            THEN 'LATITUDE_OUT_OF_RANGE'
        WHEN ParsedLongitude NOT BETWEEN -180 AND 180
            THEN 'LONGITUDE_OUT_OF_RANGE'
        ELSE 'ACCEPT'
    END AS ValidationResult
FROM Parsed
ORDER BY ImportRowID;
The order of the final CASE expression is deliberate. Missing latitude and longitude are checked first, followed by invalid coordinate formats, and then the latitude and longitude ranges. If a row has more than one problem, the first matching rule determines the rejection code.
For example, a row containing latitude 95 and longitude west is classified as INVALID_LONGITUDE_FORMAT. The latitude can be converted successfully but the longitude cannot. Both format checks are evaluated before either range check.
The format codes can also apply to any numeric text that doesn’t fit the selected decimal type. decimal(9,6) allows nine digits in total, with six after the decimal point (leaving three digits before it.)
A latitude such as 1000, however, cannot fit that type – so TRY_CONVERT() returns NULL, and the row is classified as INVALID_LATITUDE_FORMAT.
A value such as 95, on the other hand, converts successfully and is rejected later by the range check.
Therefore, in this example, a format error doesn’t necessarily mean that the source value contained letters; it can also mean that the numeric value is too large for the chosen decimal type.
Latitude must be between -90 and 90, inclusive. For this feed, longitude must be between -180 and 180, inclusive. These limits are checked before any geography value is created.
The import, therefore, doesn’t depend on how a particular SQL Server build handles longitude values outside the range accepted by the feed. In the sample batch, 190.0000 is rejected as LONGITUDE_OUT_OF_RANGE.
Row 12: valid numbers, wrong place
The 12 staged rows produce the following results:
Validation results from the sample batch
Import Row ID
Validation Result
1, 2, 3, 4, 5, 12
ACCEPT
6
MISSING_LATITUDE
7
MISSING_LONGITUDE
8
INVALID_LATITUDE_FORMAT
9
INVALID_LONGITUDE_FORMAT
10
LATITUDE_OUT_OF_RANGE
11
LONGITUDE_OUT_OF_RANGE
Row 12 shows a limit of this validation. Both 67.0011 and 24.8607 are valid numeric values and fall within the allowed latitude and longitude ranges, so the row is classified as ACCEPT. However, none of these rules checks whether those coordinates actually correspond to the location name Karachi.
Detecting that kind of problem requires additional business context, such as an expected service region, a known site record, or another trusted source. Automatically swapping latitude and longitude because a pair looks suspicious would be unsafe, because an unusual but correct location could then be changed into an incorrect one.
The supporting parser tests cover 30 cases, including zero, both range boundaries, values immediately outside those boundaries, competing rejection reasons, values with seven fractional digits, numeric overflow, and unexpected characters.
Step 5: Build geography points from accepted rows only
The listings in this section show the post-validation part of the load. In the complete load script, the validation logic from Listing 4 is materialized in #GPSDemoValidated, and rejected rows are routed separately to dbo.GPSImportRejects.
Rows classified as ACCEPT are then copied into #GPSDemoAccepted before any geography value is constructed.
Constrain the accepted coordinate pairs
CREATE TABLE #GPSDemoAccepted
(
    ImportRowID int NOT NULL PRIMARY KEY,
    LocationName nvarchar(100) NOT NULL,
    Latitude decimal(9,6) NOT NULL
        CHECK (Latitude BETWEEN -90 AND 90),
    Longitude decimal(10,6) NOT NULL
        CHECK (Longitude BETWEEN -180 AND 180)
);
Materialize the accepted rows
INSERT INTO #GPSDemoAccepted
    (ImportRowID, LocationName, Latitude, Longitude)
SELECT ImportRowID, LocationName, ParsedLatitude, ParsedLongitude
FROM #GPSDemoValidated
WHERE ValidationResult = 'ACCEPT';
The NOT NULL and CHECK constraints reinforce the rules that were already applied during validation. At this point, geography::Point() no longer operates directly on the raw feed or on a query containing both valid and invalid rows.
Instead, it now operates on the materialized set of accepted coordinate pairs only.
Build the stored geography points
INSERT INTO dbo.ValidLocations
    (LocationName, Latitude, Longitude, GeoPoint, SourceImportRowID)
SELECT
    LocationName,
    Latitude,
    Longitude,
    geography::Point(Latitude, Longitude, 4326),
    ImportRowID
FROM #GPSDemoAccepted;
Keeping validation and construction in separate statements is deliberate. I think this approach also makes the logic easier to follow, as a common table expression (CTE)is not a materialized result, and SQL Server doesn’t guarantee that predicates or expressions will be evaluated in the order they appear in a query.
Therfore, putting a filter and geography::Point() in the same statement does not guarantee that invalid rows will always be removed before the constructor is evaluated. In this example, the accepted values have already been stored in #GPSDemoAccepted before the constructor runs.
Latitude and longitude order: Point() vs WKT
geography::Point() takes latitude, longitude, and SRID in that order. Well-known text (WKT) represents a point using the opposite coordinate order: longitude first, followed by latitude. The following two expressions describe the same point in London:
When the London point is displayed as WKT, it appears as POINT (-0.1278 51.5074). In this format, longitude comes before latitude.
I also ran a test using STDistance() between the Point() and WKT versions, and the result was zero. This confirms that both expressions describe the same location.
I use SRID 4326 in this example because the feed is assumed to contain WGS 84 coordinates. Assigning SRID 4326 doesn’t transform coordinates from another reference system into WGS 84.
If the incoming coordinates use a different coordinate reference system, they must be converted correctly before being treated as WGS 84 values. All six points accepted by the test load use SRID 4326.
The complete load wraps its output changes in a transaction with XACT_ABORT enabled, and a TRY...CATCH block that rolls back an active transaction before rethrowing the error. The supporting transaction test deliberately causes a failure after an initial write, confirming that no partial output remains.
The successful sample load then produces six accepted rows and six rejected rows from the 12 staged records.
Step 6: Keep the rejected rows for review
A rejected row should keep enough information to explain what went wrong and to trace the result back to the original import.
In this example, the rejection table stores the source row identifier, location name, original latitude and longitude strings, a rejection code, a readable explanation, and a timestamp.
The raw coordinate strings are copied from staging without being normalized or rewritten. This is important because details such as NULL, an empty value, or whitespace can help explain what the source system actually supplied.
To review the rejected rows after the load:
Review the rejected input
SELECT
    ImportRowID,
    LocationName,
    RawLatitude,
    RawLongitude,
    RejectCode,
    RejectReason
FROM dbo.GPSImportRejects
ORDER BY ImportRowID;
The six rejected rows come from source IDs 6 through 11. Row 6 has a missing latitude, while row 7 contains three spaces in the longitude field. Both are treated as missing values by the validation rules.
Also, preserving the original input still lets us distinguish between a field that was not supplied, and one that arrived as whitespace.
Additionally, the supporting checks compare the rejected coordinate strings with the staged values to confirm that the original text was preserved. This is useful for values such as the three spaces in row 7, which are difficult to verify simply by looking at a SQL Server Management Studio (SSMS) results grid.
The two output tables enforce uniqueness separately, but the schema doesn’t actually contain one single rule that guarantees every staged row appears in exactly one output table.
The reconciliation checks therefore verify that each staged row is routed once (either to the accepted table or to the rejection table.) A production process would also need a clear policy for corrections, retries, and reprocessing.
Step 7: Find locations within 10 km with STDistance()
With the accepted points stored, they can now be used to answer the practical question: which locations are within 10 km of London Central? The query creates a reference point, sets the search radius to 10,000 metres, and compares that point with each stored geography value.
Find points within 10 kilometres
DECLARE @ReferencePoint geography =
    geography::Point(51.5074, -0.1278, 4326);

DECLARE @RadiusMetres float = 10000.0;

SELECT
    v.SourceImportRowID,
    v.LocationName,
    CONVERT(decimal(12,3),
        v.GeoPoint.STDistance(@ReferencePoint)) AS DistanceMetres,
    CONVERT(decimal(10,3),
        v.GeoPoint.STDistance(@ReferencePoint) / 1000.0) AS DistanceKm
FROM dbo.ValidLocations AS v
WHERE v.GeoPoint.STDistance(@ReferencePoint) <= @RadiusMetres
ORDER BY
    v.GeoPoint.STDistance(@ReferencePoint),
    v.SourceImportRowID;
For SRID 4326, STDistance() returns the distance in metres. The supporting checks also confirm the corresponding unit information in sys.spatial_reference_systems. Dividing the result by 1000.0 converts the displayed value to kilometres.
Locations returned by the 10km query
Source ID
Location
Distance (m)
Distance (km)
1
London Central
0.000
0.000
2
Camden Service Point
3954.178
3.954
3
Greenwich Service Point
9806.393
9.806
London Central returns a distance of zero because its coordinates are identical to the reference point. Camden Service Point and Greenwich Service Point are also within the 10 km radius.
The other accepted locations fall outside that radius. Heathrow Depot is about 23.056 km away, Manchester Depot is 262.371 km away, and the swapped Karachi example produces a distance of about 2206.859 km. That number describes the stored point with latitude 67.0011 and longitude 24.8607 – not the actual distance to the intended Karachi location!
Put simply, a plausible numeric result does not prove that the source coordinates describe the correct place.
The radius comparison uses the original STDistance() value in metres. Rounding is applied only to the columns shown in the result set, while the WHERE clause and ordering use the unrounded distance.
This matters near the boundary, as a point slightly more than 10 km away remains outside the result even if its displayed distance rounds to 10.000 km.
STDistance() represents an approximate geodesic distance between the two geography points, rather than being a road distance or travel-time estimate. Similarly, the number of decimal places shown in the result doesn’t indicate the accuracy of the GPS.
If the two geography values have different SRIDs, STDistance() returns NULL. Because a comparison with NULL doesn’t satisfy the radius predicate, an SRID mismatch could cause a row to be excluded without appearing as an error.
The query therefore assumes that all points use the same reference system.
Do you actually need a spatial index?
With only six accepted locations, this example is too small to demonstrate any performance benefit from a spatial index. This is why the scripts do not include timing or logical-read comparisons.
For a larger table, SQL Server can use a spatial index with an STDistance() predicate such as:
The predicate needs to remain in a form that SQL Server can recognize for spatial index use. Even when a query is eligible to use a spatial index, the optimizer may still choose a different access method if it estimates that approach will cost less.
A spatial index also requires a clustered primary key. dbo.ValidLocations already has one on LocationID, although this example doesn’t create a spatial index. For a real workload, performance should be tested with a representative number and distribution of locations and realistic search radii.
The actual execution plan should also be examined. A 10 km search in a dense city can behave very differently from a much broader search over the same table.
Conclusion: what validation can’t catch (swapped coordinates)
The sample import finishes with six accepted locations and six rejected rows. Missing values are kept separate from valid zero coordinates, malformed text receives a clear rejection reason, and out-of-range coordinates are rejected before a geography value is constructed.
Once the accepted points are stored, the 10 km query can work directly with validated spatial data instead of parsing raw coordinate text each time.
The swapped Karachi example shows what numeric validation cannot determine on its own. Its latitude and longitude both satisfy the format and range rules, so SQL Server can construct a valid point and calculate a distance from it.
That does not mean the coordinates describe the intended location, however. Detecting this kind of problem requires additional business knowledge, such as an expected service area or a trusted record of known locations.
Furthermore, preserving the original source values makes it possible to investigate a suspicious row and apply a correction – but only when there is enough evidence to justify it.
Subscribe to the Simple Talk newsletter
All the latest articles, guides, podcasts, and more – delivered straight to your inbox.
1. How do you validate latitude and longitude in SQL Server?
Store the raw values as nvarchar, trim spaces, and check the format with pattern rules before converting with TRY_CONVERT() to decimal(9,6) for latitude and decimal(10,6) for longitude. Then confirm latitude is between -90 and 90 and longitude is between -180 and 180. Only rows that pass every check should reach geography::Point().
2. Why does geography::Point() fail on some coordinates?
It fails when a value is malformed text or falls outside the range the type accepts, such as a latitude above 90. If valid and invalid rows share one statement, SQL Server doesn’t guarantee the filter runs before the constructor. Validate first, store accepted pairs in a temp table, then build the points in a separate statement.
3. Does geography::Point() take latitude or longitude first?
geography::Point() takes latitude, then longitude, then the SRID. Well-known text (WKT) reverses this, writing POINT(longitude latitude). geography::Point(51.5074, -0.1278, 4326) and STGeomFromText(N'POINT(-0.1278 51.5074)', 4326) describe the same London point, and STDistance() between them returns zero.
4. How do you find locations within 10 km in SQL Server?
Create a reference point, set the radius to 10,000 metres, and filter with STDistance(). For SRID 4326, STDistance() returns metres, so GeoPoint.STDistance(@ReferencePoint) <= 10000 returns everything within 10 km. Both points must share the same SRID, or STDistance() returns NULL and rows drop out silently.
5. Can SQL Server detect swapped latitude and longitude?
No. A swapped pair such as 67.0011, 24.8607 for Karachi passes every format and range check and builds a valid point in the wrong place. Catching it needs business context, such as an expected service region or a trusted site record. Don’t auto-swap values, because an unusual but correct location could be corrupted.
Email attachments are base64. So are cryptographic PEM certificates. In both cases the text is broken into lines, 76 characters for email and 64 for PEM.
Skipping line endings sounds trivial. Yet many fast decoders only work on uninterrupted base64. As soon as they meet a line break, they fall back to a slow path.
How fast can we decode MIME base64 in popular programming languages? I wrote a small benchmark. I generate one megabyte of random bytes, encode it as base64 with 76-character lines ending in CRLF (1.37 MB of text) and decode it again with the standard or most popular function of each language. I check that each decoder returns the right bytes.
I use an Intel Xeon Gold 6548N (Emerald Rapids) with Linux, pinned to one core. I report speeds in gigabytes of input per second (GB/s). Each number is the median of three runs, and each run keeps the best of ten timed batches. I use the latest version of each tool.
rank
system
function
GB/s
1
C++ (GCC 16) with simdutf 9.4
simdutf::base64_to_binary
18.4
2
PHP 8.7-dev with my pull request
base64_decode
17.1
3
Python 3.15 with fastpybase64
fastpybase64.b64decode
16.4
4
Bun 1.4.4
Buffer.from(s, 'base64')
14.2
5
Node.js 26.13
Buffer.from(s, 'base64')
13.3
6
Deno 2.9.8
Uint8Array.fromBase64(s)
8.4
7
.NET 11
Base64.DecodeFromUtf8
4.9
8
Go 1.27.4
base64.StdEncoding.Decode
1.6
9
Java 27
Base64.getMimeDecoder().decode
1.2
10
Zig 0.17.1
std.base64 decoder ignoring \r\n
0.85
11
PHP 8.5.12
base64_decode
0.61
There is a factor of thirty between the top and the bottom of the table.
The top six systems all rely on the simdutf library. The simdutf library removes the line endings inside its vector loop. A clean block of 64 characters is decoded directly. A block that contains line endings is compacted first, and decoding proceeds from a small buffer. The line endings never send the decoder to a slow path. See Lemire (2027) for the details.
PHP is the most dramatic case. With the current release, PHP is last at 0.61 GB/s, even though it decodes base64 without line endings at more than 20 GB/s on this machine. My pull request ports the simdutf decoders to PHP. It makes MIME decoding 28 times faster, and PHP moves to second place.
 Log in