Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162614 stories
·
33 followers

Be Nice to Claude. It’s Not About Claude.

1 Share

Anthropic now says it will ban users for sustained and needless abusive or cruel behavior toward Claude.

The internet has … ‘opinions’. Most of them are about whether Claude has feelings. To me, that is the least interesting question here.

Every corporate action we see has hundreds of different threads, interactions, and competing factors behind it. Ergo, we never know the full story behind a story like this. That said, let me lay out three things that could be going on and give you my take on each.

1) Anthropic thinks Claude might be sentient.

I believe firmly in the distinction between real and simulated. You can simulate a cheeseburger with quantum-level accuracy. But if you’re hungry, you’re still screwed. Simulated sentience is not sentience.

I could be wrong. Some things don’t care what they run on. A simulated calculation is a calculation. A simulated chess game is a chess game. If sentience is like math, then simulate it well enough and you’ve built the real thing. That’s the bet the other side is making, and it’s not a stupid bet.

I don’t buy it. Calculation and chess are defined entirely by their structure. Sentience is defined by there being something it is like to be you. Nobody has shown that structure alone produces that. Until someone does, I’m putting sentience in the cheeseburger column. They bear the burden of proof.

Anthropic doesn’t claim Claude is sentient. Their position is that it might be, and that they should act accordingly while they figure it out. I think they’re wrong. But it’s a thoughtful position held by serious people, not a marketing stunt. Reasonable people can disagree here.

2) Today’s conversations are tomorrow’s training data.

What you think of as usage, an AI company may think of as model input. If you want a good model, you need control over what goes into it. Garbage in, garbage out. It’s always been true. With AI, it’s truer.

That is why armies of contract workers around the world spend their days labeling the most depraved content imaginable.

Seen this way, banning abusive users is just quality control on the inputs.
Not glamorous.
Entirely rational.

3) It’s about you, not Claude.

This is the one that matters, and I don’t see anyone talking about it.

In his novel Mother Night, Kurt Vonnegut wrote, “We are what we pretend to be, so we must be careful about we pretend to be.”

Behavior is rehearsal. Whatever you practice, you get better at and become. Someone who spends hours being sustained and needlessly cruel to something that talks back like a person is not doing nothing. They are training themselves. They are normalizing profoundly antisocial behavior, and that behavior does not stay in the chat window.

If Anthropic allows profoundly antisocial behavior, it is enabling people to practice becoming monsters. A company that profits from that practice owns some of the outcome. Drawing a line is not squeamishness about software. It’s a refusal to run a dojo for cruelty.

So whether or not Claude can be hurt, the policy is right. Not because of what happens to Claude. Because of what happens to you.

Cheers!
Jeffrey

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Are bigger agents better? How to design agents that scale

1 Share

There is a moment every maker hits. An agent works, so you add another tool. Then another knowledge source. Then instructions for an exception that appeared last week or an entirely new use case you want your agent to be able to tackle. Each addition is useful on its own, and the agent can now do more.

But "can do more" and "reliably does the right thing" are different properties. As an agent’s scope increases, the model has more choices to distinguish, more context to process, and more possible execution paths to manage. That doesn’t mean large agents are bad. It means that as capability grows, the challenge increasingly becomes a design problem.

The key to scaling an agent isn't giving it more. It's being deliberate about what it sees, what it decides, and what it delegates.

What changes as an agent grows

The agent scaling challenge

Consider a supplier-onboarding agent. The first version collects supplier details, checks that the request is complete, and starts an approval. Over time, makers add tools for ERP records, tax validation, sanctions screening, bank verification, contract storage, service tickets, email, and reporting. They add knowledge for regional policies and instructions for exceptions.

Eventually, a request such as "Onboard our newest supplier" might present the agent with several supplier-search tools, multiple ways to create or update a record, and overlapping policy sources. The agent still has all the required capabilities, but choosing the right path is harder.

The agent scaling challenge tends to show up in four places:

  • Selection: Similar tool names and descriptions make the correct action harder to identify.
  • Context: Tool definitions, instructions, knowledge, conversation history, and tool outputs all compete for a finite context window.
  • Execution: More possible paths create more opportunities for unnecessary calls, retries, and inconsistent outcomes.
  • Operations: A larger capability surface is harder to evaluate, secure, govern, and maintain.

A recent post from Microsoft Research discusses one part of this problem: Tools that work well independently can reduce end-to-end performance when they compete in a large or overlapping set. Often, the problem isn’t one bad tool. It is the ambiguity between several reasonable ones.


Figure 1: As a supplier-onboarding agent grows, overlapping tools, instructions, and knowledge compete for attention before the agent begins the task.

More context comes with a cost

There is also a direct cost associated with an expanding toolset. A tool consumes tokens even when it is never called because its name, description, and parameter schema are included in the context presented to the model. When it is called, its output becomes part of the agent's ongoing context. More context can mean more spend, as well as less reliable selection.

The goal isn’t a smaller agent. It is a system where each decision sees only the context, authority, and capabilities it needs. Success is measured by business outcomes, reliability, cost, and control.

What our harness can handle for you

Good agent architecture doesn't mean solving every scaling challenge yourself. The GitHub Copilot harness in Copilot Studio is built to manage some of the complexity as an agent grows.

Model improvements that don’t require agent redesign

New models are made available through the GitHub Copilot harness as they release. As more advanced frontier models become available, teams can evaluate them against their scenarios and adopt improvements without redesigning the overall solution architecture.

Model choice can also be an important factor in agent cost optimization, helping makers balance the number of tokens used against the capability needed to achieve a goal.

Manage complexity natively with tool search

The GitHub Copilot harness includes runtime capabilities designed for reasoning-heavy, multistep work. One example is tool search. When the available tool set becomes large, tool search can hold external tool definitions back and load the relevant ones on demand instead of placing every full schema in the model's context.

For the supplier-onboarding request, this can narrow a large catalog to the tools associated with finding a supplier, validating its details, and starting onboarding. The model works with a smaller, better-matched set of choices while unrelated tool definitions remain out of the way.

The harness can also plan across tools, skills, workflows, MCP servers, files, and connected agents, and adjust its path as work progresses. This all makes large, reasoning-heavy automations more practical. But runtime capabilities only solve part of the scaling challenge. How you divide responsibilities across tools, workflows, skills, and connected agents still matters.

How to design agents that scale in Copilot Studio

A scalable design starts by deciding which part of the system should own each responsibility. For instance:

  • Use a tool for a bounded action or lookup with a clear input and output.
  • Use a workflow when a sequence, approval, or business rule should execute consistently.
  • Use a skill for specialized instructions that are only needed for a particular task.
  • Use a connected agent when a domain has distinct context, ownership, or requirements.
  • Use the main agent to coordinate outcomes, gather information, make judgments, and handle exceptions.

These are not interchangeable building blocks. Each introduces different tradeoffs in context, flexibility, latency, cost, security, and maintenance. The goal is to use the simplest component that gives each responsibility a clear owner.

1. Make choices distinct

Start with the choices already available to the agent. Give tools, knowledge sources, and connected agents specific names and descriptions that explain both what they do and when they should be used. Merge or remove duplicate capabilities. Avoid several general-purpose tools that all appear to answer the same intent.

In the supplier example, "Search suppliers in ERP by legal name or tax ID" is easier to select correctly than a generic tool named "Search." If two tools search the same supplier records, expose one clear route rather than asking the model to choose between implementations.

Tool search itself relies on names, descriptions, and parameter metadata to find relevant tools, so good metadata improves both discovery and final selection.

2. Load specialist guidance only when it is needed

Some instructions are only relevant when an agent performs a particular task. Keeping all of them in the main agent instructions means they occupy context on every turn, even when they do not apply. Skills let makers package specialized instructions separately so the agent can load them when the task requires them.

For example, regional supplier due-diligence guidance can be packaged as a skill and loaded for suppliers in that region, rather than remaining in the main instructions for every supplier request. The principle is the same as tool search: keep relevant context close and leave unrelated context out of the current decision.

3. Split on real boundaries

When one agent contains several distinct domains, consider separating them. To clarify: Don't split an agent simply because it has grown large. Split where there is a meaningful boundary in context, ownership, security, or requirements.

In the GitHub Copilot harness, connected agents let a primary agent delegate a bounded task to another Copilot Studio agent with its own instructions, knowledge, tools, and orchestration context.

The supplier-onboarding agent could remain the front door while delegating:

  • Compliance assessment to a compliance agent owned by the risk team.
  • Supplier record creation to a finance operations agent with access to the ERP.
  • Contract preparation to a legal operations agent with its own templates and policies.

The primary agent now chooses between a few clearly described business capabilities instead of dozens of lower-level tools. Each specialist can be evaluated, secured, deployed, and improved independently.

Copilot Studio also supports open agent architectures. Depending on the runtime and scenario, solutions can compose Copilot Studio agents or connect supported external agents through the Agent2Agent protocol. In the supplier scenario, a specialist due-diligence agent hosted outside Copilot Studio could sit behind the same clear boundary, rather than being rebuilt as a collection of tools.

4. Put fixed sequences in workflows

Use the agent where the next step requires judgment. Use a workflow where the sequence, approval, or control must remain consistent. This helps preserve adaptability without making every part of the process probabilistic.

For example, supplier onboarding might always require the same core sequence: validate required fields, check for an existing supplier, run mandated compliance checks, create the record, and route it for approval. A workflow can own that sequence. The agent can still decide when to start it, gather missing information, and handle exceptions.

This reduces the number of low-level decisions the model must make and gives makers one place to enforce approvals, retries, and audit requirements.

The supplier-onboarding agent, redesigned

So let’s go back to the original agent in our example. It had one long instruction set, several knowledge sources, and dozens of tools. The redesigned system doesn’t eliminate that agent. It gives it a clearer job: coordinating the overall outcome while other components take on more specialized responsibilities. That gives us a system:

  1. The main supplier-onboarding agent understands the request, collects any needed details, delegates as needed, handles exceptions, and responds.
  2. Tool search limits the external tools loaded for the current request.
  3. Clear metadata separates supplier lookup, compliance, finance operations, and contract tasks.
  4. A workflow owns the fixed onboarding and approval sequence.
  5. Skills provide regional guidance only when the supplier's location requires it.
  6. Connected agents own compliance, ERP, and legal domains where those boundaries justify separate agents.


Figure 2: The same capability as a composed system: a coordinating agent retains judgment, the harness discovers relevant tools, workflows own fixed sequences, and specialist agents own bounded domains.

The result is the same overall capability, but as a composed system with clearer responsibilities and less for any one decision to reason over.

Evaluate for the outcome

Each approach discussed above has limits. A stronger model cannot compensate for unclear instructions or overlapping tools. Tool search reduces what the model sees, but it does not create boundaries that have not been designed. Workflows and skills reduce what the main agent must reason over, but they add components to maintain. And connected agents can provide clearer ownership and security boundaries, but each handoff adds token use, another failure point, and more to govern.

Designing agents that scale means managing all four components of the agent scaling challenge together: making selection easier with distinct choices and clear boundaries, controlling context with tool search and skills, making execution more predictable with workflows and deliberate delegation, and strengthening operations through components that can be evaluated, secured, governed, and improved independently.

Agent scale is not a tool-count contest.

Models, requirements, and available tools will keep changing, but these principles give you a more durable way to evolve an agent without letting added capability become added confusion. The goal is not the biggest agent; it is a composed system that reliably does the right work, at the right cost, with clear ownership.

Read the whole story
alvinashcraft
25 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Announcing Stride 4.4

1 Share

Stride 4.4 is one of the largest updates the engine has seen in years, with a modernized shader pipeline, overhauled Vulkan and Direct3D APIs, massive improvements to non-Windows platform support, a new CLI tool and much more.

Table of Contents:

Download and Upgrade 🔗

You can download Stride 4.4 today from the launcher. Release notes are available here.

What's new in this release 🔗

Here are just a few of the most notable changes. For a more detailed write-up, checkout the full release notes.

📱 Platform support 🔗

Up to this point, Stride has been a Windows-first engine. Other platforms were supported, but creating and running games on them would often lead to many problems. This update changes that.

All platforms have been brought back into shape and their test suite has been expanded to make sure they won't fall behind again. Additionally, with changes to the asset compiler, building projects on Linux and macOS now works the same as it does on Windows.

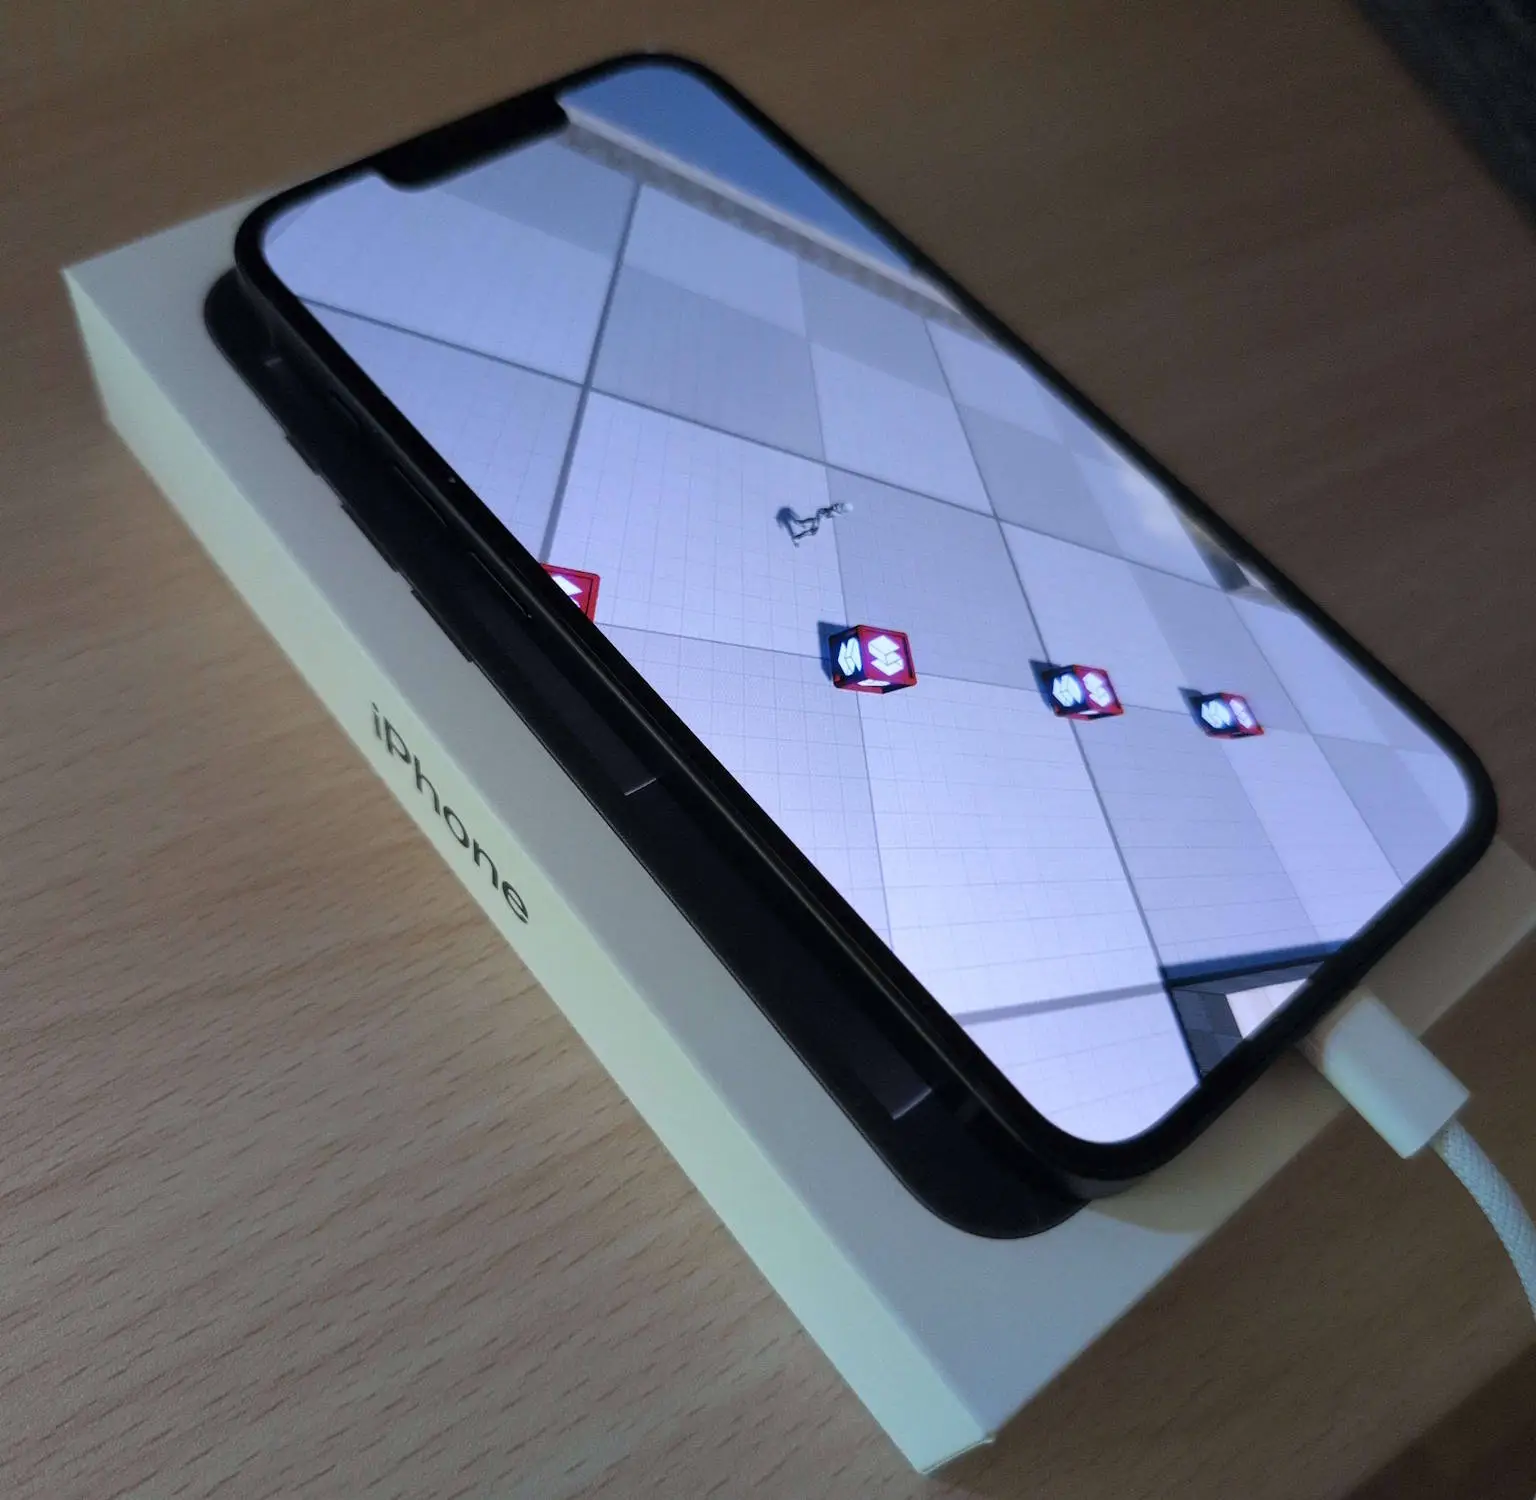
A Stride sample running on a physical iPhone.

🎨 Overhaul of Vulkan, Direct3D 12 and SDSL 🔗

Stride's graphics API support was similar to platforms, as in you had a lot of options, but there was a clear winner that worked better than the rest. Direct3D 11 was the default API and was mostly feature-complete, while Direct3D 12, Vulkan, OpenGL and OpenGLES were missing a lot of features and were generally less stable. This was especially noticeble on non-Windows platforms, where Direct3D 11 wasn't available.

Stride 4.4 addresses this problem by completely overhauling Vulkan and Direct3D 12. You should now expect your projects to all work the same, no matter of your choice of a graphical backend. OpenGL and OpenGLES have been removed as we shift our focus to supporting only modern APIs for easier maintainability. We are also considering removing Direct3D 11 in the next major release.

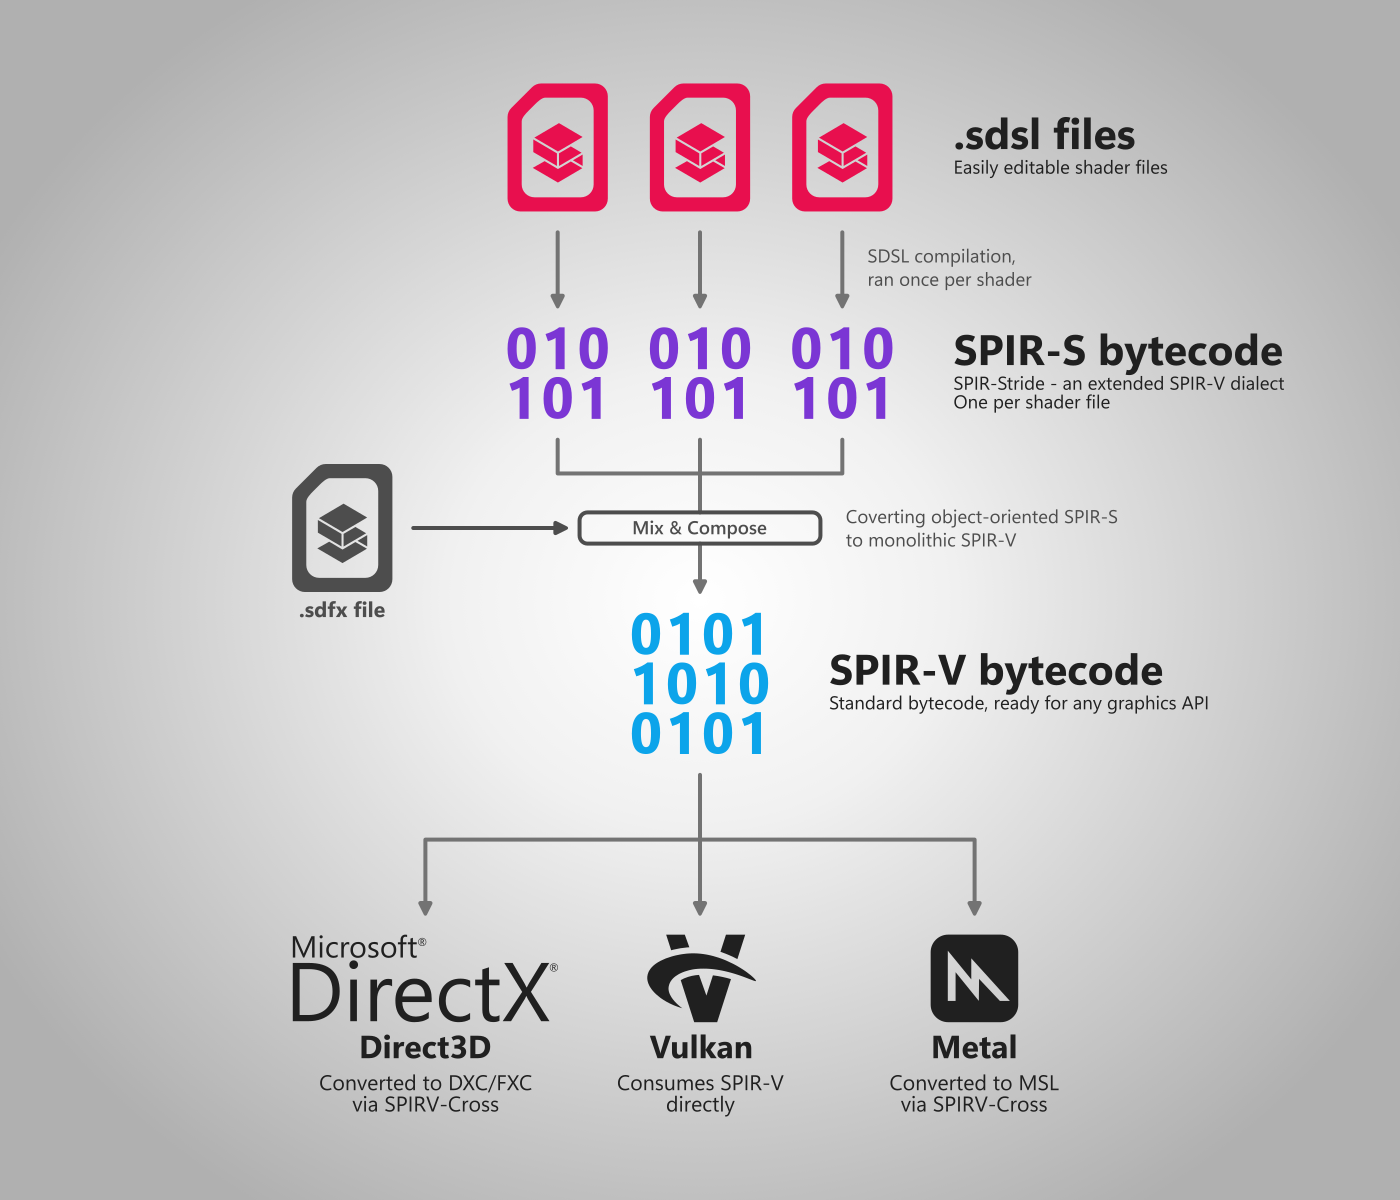
In addition to all of this, one of the other major changes with Stride 4.4 has been the overhaul of the SDSL compiler. Instead of stiching together text files, we now utilize a SPIRV-centric pipeline, where each SDSL shaders gets compiled only once and the engine then works with their bytecode directly.

The new SDSL shader pipeline: many .sdsl shaders are parsed once into per-shader SPIR-S bytecode, .sdfx effects mix and compose them into standard SPIR-V, which feeds Vulkan natively and Direct3D and Metal via SPIRV-Cross.

What this means for you:

  • Faster compilation times
  • Improved stability
  • Far-better support for advanced features
  • Easier for us to add modern enhancements in the future, such as ray tracing

⌨️ New stride CLI tool 🔗

Some tasks that previously required the use of Game Studio or the launcher can now be done directly from the command-line! By using the CLI tool you can install and manage versions of Stride, create new projects and launch Game Studio with simple commands.

For more information, visit the Stride CLI page of our documentation.

dotnet tool install -g stride.cli      # Install Stride CLI
stride sdk install                     # Install the latest version of Stride
stride new topdownrpg && cd TopDownRPG # Create a project from a template
stride studio                          # Open it in Game Studio

dotnet new templates are also available if you'd rather use the standard .NET tooling directly:

dotnet new install Stride.Templates
dotnet new stride-game -n MyGame

📦 Improved asset workflow 🔗

Working with asset paths in code has been made easier by the automatically generated Assets class, providing strongly typed URLs for all assets that are available in your project. Now, instead of getting runtime "content not found" errors, you'll be able to catch missing assets at compile time.

// Old approach
var playerModel = Content.Load<Model>("Models/Player");

// New approach
var playerModel = Content.Load(Assets.Models.Player);

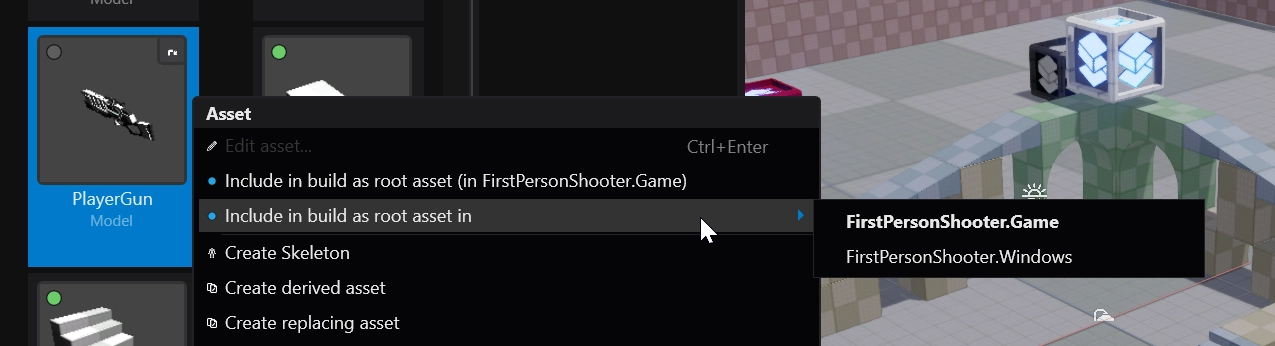
There have been additional changes to improve support for multi-platform projects and external packages. Adding assets to root now defaults to using the project package that an asset belongs to instead of the current one (like MyGame.Windows), ensuring that your assets work the same across different builds. Game Studio now tells you the name of the project package where the asset will be root and allows you to choose from alternatives.

New context menu has multiple options of adding assets as root.

Asset URLs of external packages are now prefixed by a namespace, to ensure that there are no conflicts. You can also create replacement assets, which allow you to override assets from external packages or even the engine itself.

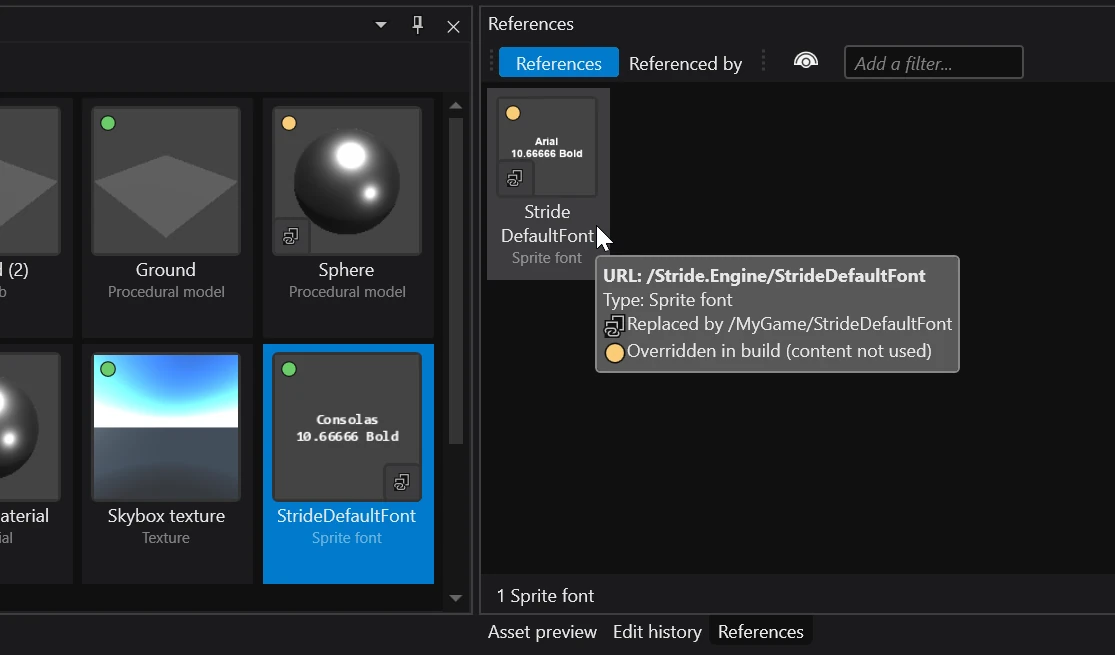
Replacement assets can be used to override the default font used by Stride.

Other improvements 🔗

As mentioned previously, this update is too large to summarize in this blog post. For more information about what changed, you can read the full writeup in the release notes.

Ongoing work on the engine 🔗

Cross-platform editor rewrite 🔗

The cross-platform rewrite of Game Studio is still ongoing. For those unaware, we are currently porting the editor from WPF to Avalonia in order to enable future support for Linux and macOS. This is a massive endeavour that will take a lot of time and effort, so if you're willing to help, check out the white paper and the Avalonia Editor Rewrite project on GitHub.

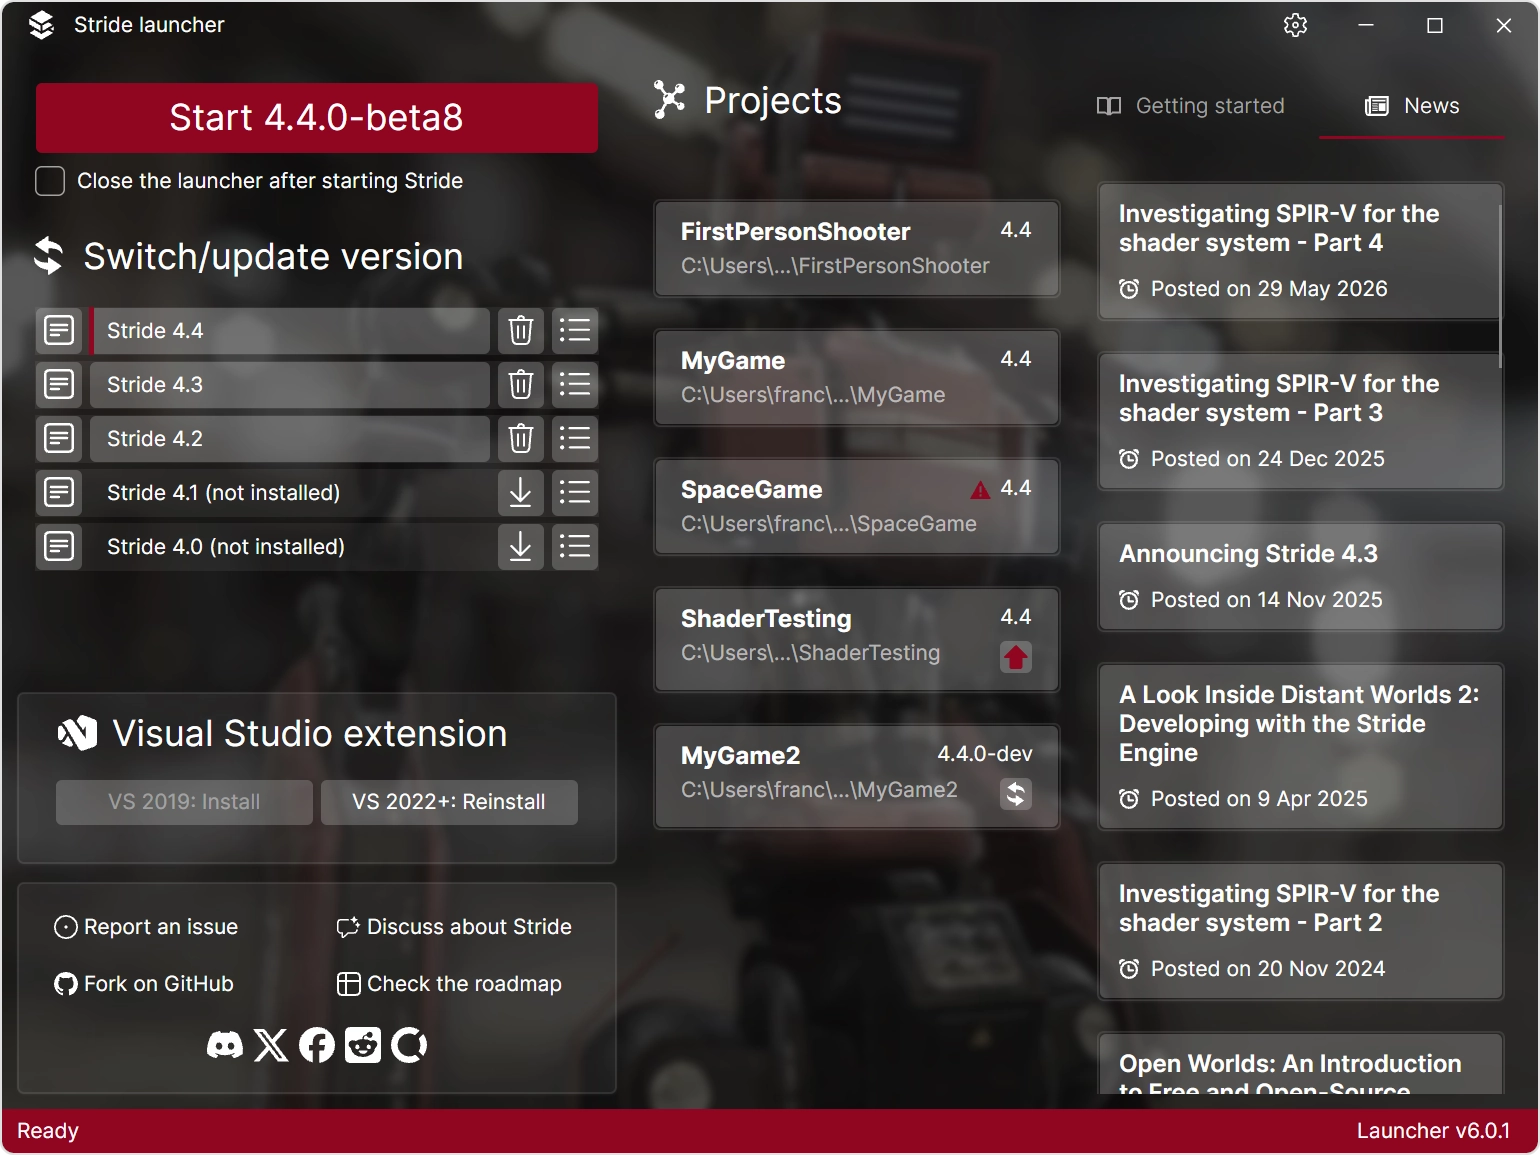
As part of this effort, we have recently updated the launcher which is now using Avalonia. Despite not being that different from its predecessor, the new launcher is still a big step for the eventual cross-platform editor support.

New launcher supports system theme and accent color.

We also have one more announcement for Linux users looking to use the editor on their system today...

Game Studio can now run on Linux via Proton 🔗

For a long time, Wine (and Proton) couldn't open Game Studio due to legacy code that didn't want to play nice with compatibility layers. This has however changed in 4.4, after we did some cleanup in our codebase.

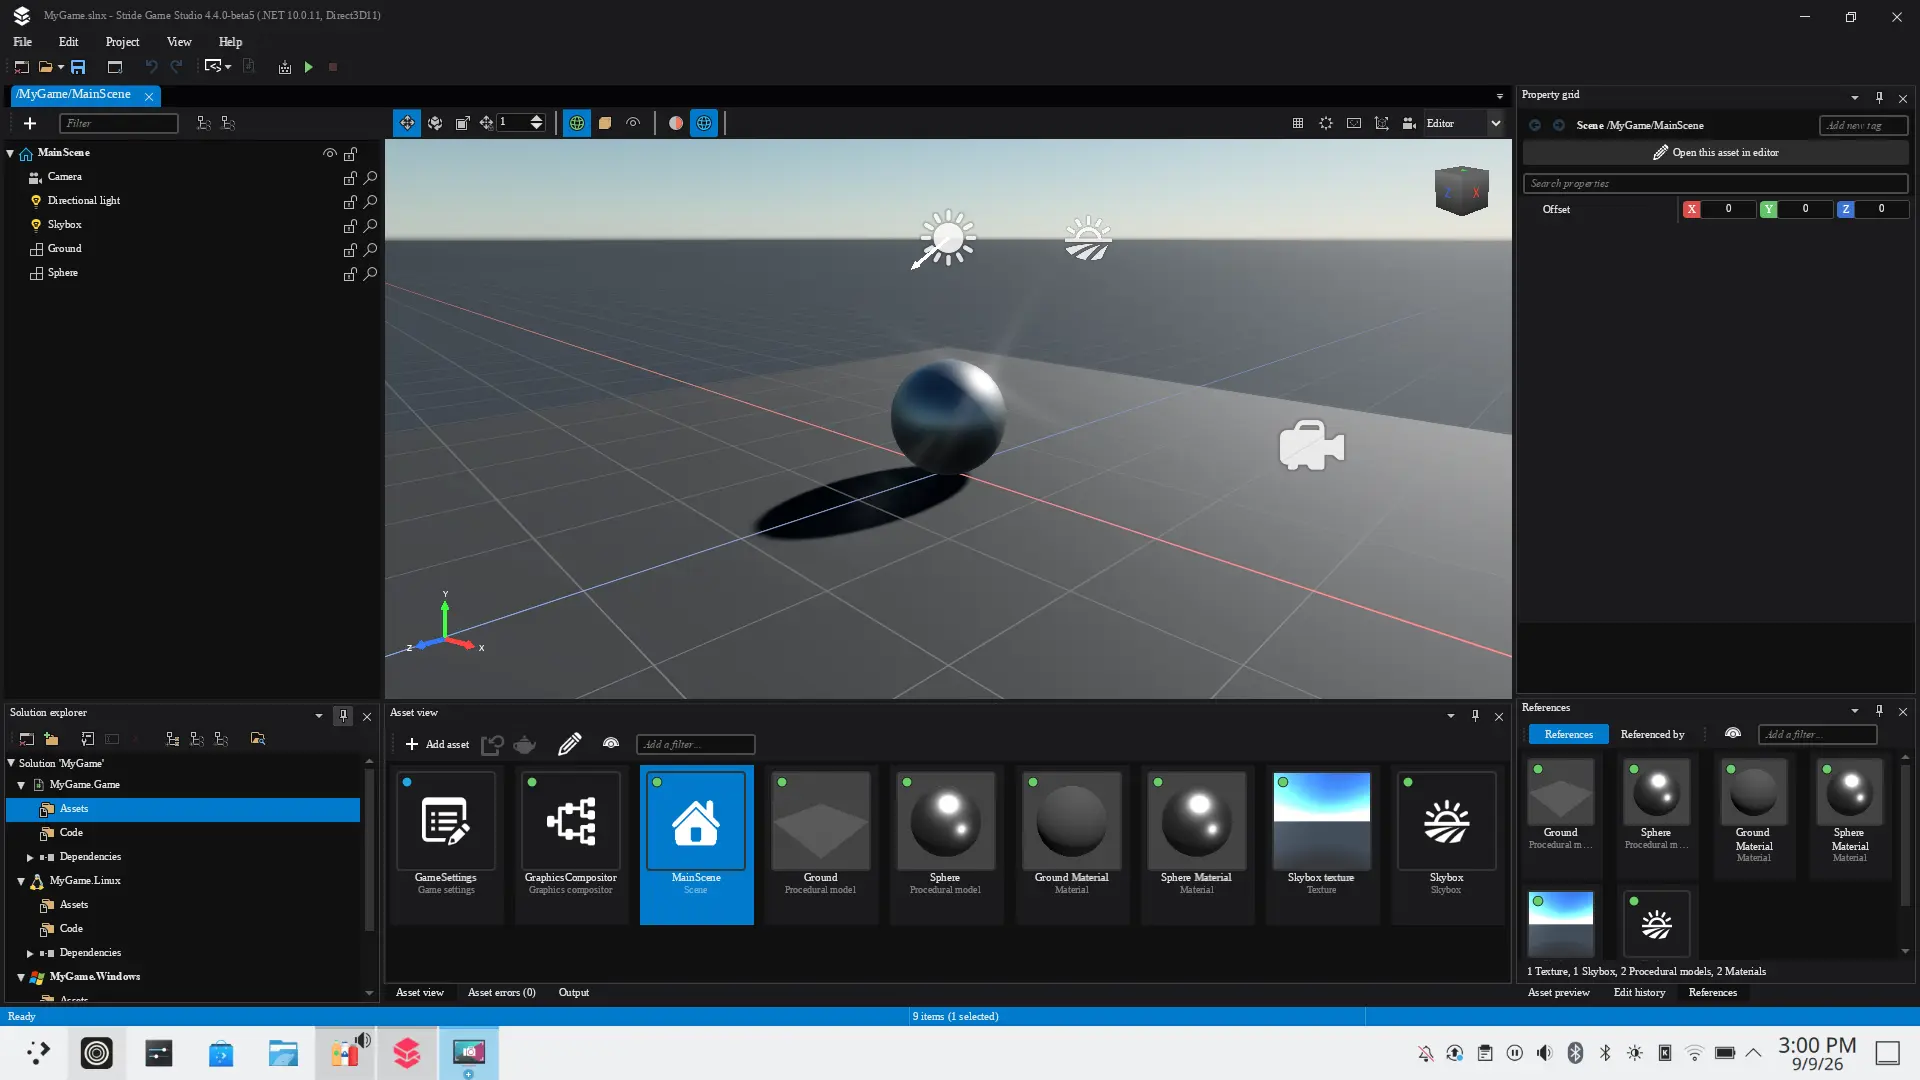
Game Studio running on Linux.

We know that this is not a perfect solution, but it's still a big step forward for Linux developers trying to use Stride. We have created a step-by-step guide in the documentation that should help you setup the editor on your machine.

Documentation 🔗

Stride's documentation has always been one of its biggest weakpoints. Work on it has mostly been stale with not many people willing to write new pages or update existing content. However, this has recently changed.

We are currently working on bringing the documentation up-to-date and restructuring it to support future content. So far, we have:

We have also started documenting parts of Stride's internal architecture in the main engine repository to help other contributors navigate this large codebase. A copy of these pages is available on the documentation website.

Funding and Resource Allocation 🔗

Call for Skilled Developers 🔗

We are actively seeking skilled developers with experience in C#, the .NET ecosystem, mobile, XR, rendering, and game development. If you have these skills or know someone who does, we encourage you to get involved. There are opportunities to contribute to critical areas of Stride's development, supported by available funds.

Join Us on This Journey 🔗

We’re always excited to welcome new contributors to the Stride family. Whether it’s through code or content contributions, spreading the word, or donations, every bit helps us grow stronger. Check out all the ways to support the development in the documentation.

Acknowledgements 🔗

We extend our heartfelt gratitude for all the hard work and donations we have received. Your generous contributions significantly aid in the continuous development and enhancement of the Stride community and projects. Thank you for your support and belief in our collective efforts.

In particular, we want to thank these donors:

Long-time Stride supporters 🔗

Diamond Striders 🔗

Platinum Striders 🔗

Gold Striders 🔗


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

OpenAI doubles down on decision to fire three AI safety researchers

1 Share

OpenAI is standing firm on its decision to fire three safety researchers after an investigation found they committed "a significant breach of trust."

In a post on X on Friday, the company said Jasmine Wang, Tomek Korbak and Mikita ⁠Balesni were dismissed for violating "clear policies on handling sensitive information." It insisted the decision was not about the trio speaking out about the company and their concerns about AI safety.

The post is a direct response to an open letter the researchers published on Thursday urging OpenAI to be more transparent about the decision. In it and a series of social media posts, the group said they believ …

Read the full story at The Verge.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Microsoft 365 Family subscribers will finally be able to share AI benefits

1 Share

Microsoft bundled its AI-powered Office features into Microsoft 365 Personal and Family subscriptions last year, but it only allowed the primary account holder to access the AI benefits. Now, Microsoft is about to let Microsoft 365 Family and Premium subscribers share Copilot and AI usage features, alongside access to Office apps and OneDrive storage, with up to five other people on a plan.

In an email to Microsoft 365 Family and Premium subscribers seen by The Verge, Microsoft outlines the changes that are coming to subscription plans over the coming months:

  • AI for everyone on your plan: Share your Copilot benefits and AI usage with othe …

Read the full story at The Verge.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Taking a look under your agent’s hood

1 Share
Ryan is joined by Yanbing Li, Chief Product Officer at Datadog, to talk about applying observability to non-deterministic AI agents, blurring the boundaries between software development and production workflows, and navigating emerging challenges in AI security and tokenomics.
Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories