Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
165166 stories
·
33 followers

When AI-Generated Data Becomes Tomorrow’s Ground Truth

1 Share

Manufacturers qualify suppliers before trusting them with critical work. Before a supplier can provide parts for a regulated product such as a medical device, the manufacturer collects evidence: quality certifications, test reports, insurance documents, and regulatory approvals. Increasingly, an AI agent reads that evidence first. The agent reviews the documents and proposes a finding, and a business process decides whether the finding is good enough for the supplier to be accepted. Once a supplier is accepted, that decision is recorded in the manufacturer’s supplier-management system. From there, sourcing workflows, readiness dashboards, and program reports all rely on that record without repeating the review.

Here is how that process can go wrong. A supplier-review agent examines a new supplier’s documents and concludes that a mandatory quality certificate is valid. The qualification workflow accepts the finding, the supplier is recorded as compliant, and the procurement lead approves the supplier for an upcoming order. A few days later, a human reviewer notices that the certificate does not cover the part being sourced; the agent had misread the certificate’s scope. At 11:00am, the reviewer corrects the supplier record and sends the supplier back for review. At 2:00pm, the readiness dashboard still shows the supplier as cleared, and a program report still lists the supplier as compliant. The procurement lead’s sourcing decision remains in force, and nothing tells the procurement lead that the evidence behind it has changed.

A misread scope is only one way a certificate finding can fail. A certificate may be revoked after it was checked, expire before the order ships, apply to a different plant than the one making the part, or turn out to be forged. In each case, someone can correct the supplier record while the systems that already used the old finding keep acting on it.

No system in this example malfunctioned. Each one processed information that appeared valid under its local contract, yet the combined result was wrong. The manufacturer had corrected a value without correcting its influence. Part of this is a familiar problem: Enterprise systems have always struggled to keep reports, indexes, caches, and workflow state in line with the source record. Agents make the problem harder because they generate conclusions. A conclusion can be assembled from several sources, rewritten in reports, and retrieved later as if it were independent evidence. Reconciliation can make stored values agree. It cannot reveal that differently worded records come from the same conclusion, or find the decisions that already relied on that conclusion.

This problem is not limited to manufacturing. In our work across banking, telecommunications, and resources, it appears wherever an agent’s output becomes a record that other systems trust. A fraud classification is written into a case record. A risk assessment is summarized in a management report. An incident diagnosis becomes part of a knowledge base. In each of these cases, as in the supplier example, the conclusion loses some of its original context at every step it passes through and begins to influence decisions made later.

The conclusion can also travel back into model development. Accepted findings become labeled examples, evaluation sets, and fine-tuning data, where they are treated as ground truth for the next model. If an incorrect supplier finding survives correction in the operational systems, a future model may learn it. Whether the conclusion ends up in a dashboard, a report, or a training set, the hard problem is the same: finding every consequential decision that depends on a result that can change.

When an answer acquires authority

Look again at the supplier-review agent’s conclusion that the certificate is valid. When the agent produces that conclusion, it is a generated assertion: a claim made by a model, with no business authority until the qualification workflow accepts it for a specific use, such as approving the supplier for sourcing. The words “certificate valid” also change character as they move. In the agent’s response, they are visibly part of an AI-assisted assessment. In the supplier master record, the same words look like an established fact. The dashboard strips away more context: It shows the supplier as cleared, with no sign of which checks were incomplete or whether a review was pending. The program report compresses the finding into a sentence, and the search index splits that sentence into passages that can be retrieved on their own.

Along the way, enterprise systems tend to keep the value the agent produced and lose the conditions under which it was produced. A label saying that the finding was AI-generated may survive on the supplier record and disappear from a dashboard total, a data export, or a retrieval chunk. As that context falls away, the conclusion takes on the authority of whichever system is carrying it.

That is why two questions need to be kept separate: Who produced a result? And who is allowed to rely on it? An agent may be allowed to record a proposed finding without being allowed to establish a business fact. The same finding may be good enough to move a supplier up a review queue and not good enough to approve the supplier or release a payment. Where that line falls depends on what is at stake and which controls grant authority for that use. Once the qualification workflow accepts a finding, downstream systems usually treat it as settled and do not repeat the checks. That is efficient, and it creates an obligation: Those systems still need to know which decisions rely on the finding and under what conditions.

When repetition looks like corroboration

Acceptance also multiplies the finding. Once the supplier is recorded as compliant, the readiness dashboard shows the supplier as cleared, the sourcing workflow moves forward, and the program report repeats the approval. A later agent, when asked about the supplier, can retrieve the supplier record and the program report as two separate documents, each appearing to support the same conclusion. Across the supplier record, the program report, and the dashboard, one says the evidence was verified, another says the controls passed, and a third shows an approved outcome. What appears to be corroboration is propagation: several records repeating one finding. Because each system changes the wording or format, the duplication is easy to miss.

A stronger model will not reliably catch this duplication when the retrieval system presents the copies as unrelated documents. Reranking improves relevance, but every copy may be relevant. Telling the model to look for independent evidence cannot restore ancestry that was discarded before the documents reached it. Agent memory makes the problem worse. An agent that records its own finding and retrieves it a week later is citing itself, and nothing in the retrieved passage says so. In multi-agent workflows, one agent’s summary becomes another agent’s context, and a third agent’s supposedly independent check may read both.

Decision lineage is the missing recovery path

Existing tools cover parts of this problem. W3C PROV models the entities, activities, and agents involved in producing data, establishing origin and responsibility.[1] OpenLineage standardizes lineage metadata around datasets, jobs, and runs.[2] Event sourcing records changes to application state as a sequence of events.[3] PROV is expressive enough to model the whole supplier example. The gap is in implementation. Lineage tooling often stops at dataset and job boundaries and rarely reaches the decision record or the retrieval layer that assembles an agent’s context. As usually deployed, none of these tools answers the question that matters after the certificate finding changes: Which decisions still depend on it? Decision lineage extends these mechanisms. It records the relationship between the source evidence, the generated assertion, the authority granted to that assertion, and the decisions that rely on it.

Data lineage tells us where an assertion traveled. Decision lineage tells us what the organization did because it believed the assertion.

In the supplier example, the chain runs from the certificate to the agent’s finding to the accepted supplier record to the procurement lead’s sourcing decision and on to the dashboard, report, and search index that reuse the finding. If the certificate turns out to be invalid, that chain lets the system find the sourcing decision and identify every report, workflow, and AI output that inherited the old finding, before any of them influence another decision.

The chain also marks where automated recovery and business accountability separate. Software can identify the affected artifacts, stop the withdrawn finding from appearing as current evidence, and open a review task for the person who owns the decision. That person decides whether the decision still stands, needs to be reversed, or needs to be communicated to customers or regulators. An implementation might remove stale search entries automatically while still requiring human approval to change a sourcing decision that has already been made.

A production pattern for preserving decision dependence

The pattern starts where the agent’s output enters the system of record. The agent records its finding as a proposal, tied to the evidence it reviewed. A deterministic workflow, owned by the business, decides whether that proposal gains authority for a defined use. If a required check cannot run, the finding stays a proposal and is never silently promoted. Keeping proposals separate from accepted findings prevents accidental promotion, but it does not record what happens next, when the sourcing decision relies on the accepted finding. The decision needs a link back to that finding and to the version of the evidence behind it. This does not require a universal graph of everything the agent touched. For a high-consequence decision, it is enough that the finding’s influence can still be traced after the workflow has finished.

The dependency record that holds this link can be small. For the supplier example, it might look like this:

{
  "assertion_id": "asr-7781",
  "claim": "Mandatory certificate valid for supplier S-204",
  "evidence_snapshot": "evd-2291@v3",
  "authority": {
    "granted_by": "qualification-workflow",
    "scope": ["sourcing-approval"]
  },
  "dependent_decisions": ["sourcing-5520"],
  "derived_artifacts": ["dashboard:readiness",
                        "report:program-q3",
                        "index:supplier-docs"],
  "status": "accepted"
}

When the certificate finding is withdrawn, the record’s status changes to withdrawn, and the dependent_decisions and derived_artifacts fields become the list of everything that needs to be revisited.

The dependency record has to survive as the finding is copied downstream, because the same finding may come back through the program report or the search index. When a later agent retrieves both the supplier record and the program report, the retrieval layer should recognize that they share an origin and present them as two copies of one finding. If the finding has been withdrawn, the retrieval layer should filter or flag both copies before they reach the agent.

When a finding turns out to be wrong it is withdrawn, and the supplier goes back to review. The dependency record lets services find the decisions that relied on the finding, recompute dashboards, flag reports for regeneration, remove stale search results, and stop pending workflows. Decisions that have already taken effect go back to their owners, and nothing is reversed automatically. Cache invalidation, vector-index refresh, report regeneration, and workflow reversal are all parts of the same recovery job. A correction has traveled far enough only when the old finding no longer drives any current decision.

Where the pattern is worth the cost

Not every AI output needs decision lineage. An answer that is low-stakes, never stored, never reused as evidence, and cheap to regenerate can live with ordinary logging. Decision lineage earns its cost once an AI-generated finding can affect an approval, a payment, safety, compliance, or later machine decisions. By the time an error in such a finding is discovered, the finding may already have changed what the organization did, so recovery has to finish within the time the business process can tolerate. That recovery work, finding and reconsidering the decisions affected when evidence changes, is what the pattern makes cheaper.

The pattern also does not require tracking every word an agent produces. The unit to track is the material assertion: a specific claim, such as “the certificate is valid,” that could change a decision if it were wrong. A long supplier assessment may contain only one or two material assertions. Recording dependencies for those claims is more useful than keeping a complete trace of everything the agent wrote, and it costs less in storage, privacy exposure, and operations.

Tracking ancestry also has to be precise enough to keep independent evidence independent. If two laboratories separately validate the same certificate, the system should not merge their results into a single source just because they agree. What matters is whether the observations share an origin, and similar wording proves nothing either way.

How to test whether correction traveled far enough

Recording dependencies proves little unless a correction actually travels through them, so the pattern needs a test. In a controlled environment, introduce an incorrect finding, let it reach a report and a search index, and then withdraw it. The test passes only if the affected decision can be found, and the stale copies stop appearing as evidence within the recovery time the process requires.

Three indicators show how well the test went. Decision coverage is the share of high-consequence decisions that can be traced back to a supporting finding. Time to impact is the time between withdrawing a finding and identifying the decisions it affected. Stale-evidence leakage counts the withdrawn copies still returned as current evidence. Targets depend on the process. A payment approval might need affected decisions identified within the hour, with zero leakage, while a review-queue priority may tolerate a day.

Replay the supplier decision

Now return to the supplier example and run it again with the pattern in place. When the supplier-review agent concludes that the certificate is valid, its finding is recorded as a proposal tied to the documents it reviewed. The qualification workflow checks the finding, grants it authority for the sourcing decision, and writes the dependency record shown earlier. The dashboard and program report still pick up the accepted finding, and a later agent that retrieves both sees them as two copies of one finding.

When the reviewer corrects the record at 11:00am, the finding is withdrawn and the supplier goes back to review. This time the correction travels. The dashboard recomputes, the program report is flagged for regeneration, stale entries drop out of the search index, and the procurement lead gets a task to review the sourcing decision. By 2:00pm, the dashboard shows the supplier as under review.

The procurement lead can now see that the certificate finding changed, which decision relied on it, and which reports and records carried it. The original mistake still happened. Its spread is now visible, and its consequences go back to someone who can act on them.

Ground truth begins with the next decision

In the supplier example, the procurement lead never treated the model’s response as final. The finding became organizational truth because the supplier system accepted it, the workflow advanced, the report repeated it, and later systems inherited its authority.

Decision lineage does not prove that the original evidence is authentic, replace data-quality or entitlement controls, or make a model’s conclusions accurate. It addresses what happens after a finding exists: how its influence is recorded, found, and reconsidered across the decisions that depend on it. For the manufacturer, correcting the certificate record was only the first step. Recovery also meant finding the sourcing decision that relied on the finding and stopping stale copies from coming back as current evidence.


AI-generated data becomes ground truth the moment the next decision stops asking where it came from.


References

  1. World Wide Web Consortium, “PROV-Overview: An Overview of the PROV Family of Documents,” April 30, 2013. View the W3C PROV overview.
  2. OpenLineage, “An Open Framework for Data Lineage Collection and Analysis.” View the OpenLineage documentation.
  3. Martin Fowler, “Event Sourcing,” December 12, 2005. Read “Event Sourcing.”

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

AI-Generated Code Security Risks: What Qodana Found in a Java App

1 Share

Adding search functionality, converting a document, or connecting a service sound like small changes. An AI coding agent may take it on in one pass, changing application logic, dependencies, configuration, and tests along the way. The result may pass functional tests and still contain security vulnerabilities.

Static analysis can surface some AI-generated code security risks, while reviewers and targeted tests determine which findings matter in practice. Where can external input travel? What happens if a configuration value is missing? Do the new dependencies introduce risks the functional tests never exercise? The same questions matter in any codebase, including code written with AI.

A study of AI-generated Python and JavaScript snippets in public GitHub projects found weaknesses across 43 Common Weakness Enumeration (CWE) categories. OWASP recommends reviewing any fully agent-produced changes, including dependencies and tests. Passing tests are useful evidence, but they don’t answer every security question.

Static analysis gives reviewers a place to start. It can point to data flows, unsafe code patterns, vulnerable dependencies, and hardcoded values, but each finding still needs context. A reviewer must check whether the path is reachable, what runs in production, and which fix fits the application.

Why AI-generated code still needs a security review

An agent may implement the requested behavior while missing constraints that live outside the feature description. Passing functional tests may still leave questions about how data crosses trust boundaries or how deployment settings affect security. OWASP’s secure code review guidance calls for understanding business requirements, tracing data flows, and checking configuration and deployment. These checks often span modules.

Qodana points to relevant paths and patterns, then reviewers supply the application context needed to judge them.

Scanning the Corporate Payments Portal with Qodana

We examined the Corporate Payments Portal, a Java app from the RealVuln Benchmark, alongside its public Qodana report. The benchmark deliberately seeds vulnerabilities in AI-generated code, giving us concrete findings to investigate. We’ll follow several of them from the code to the questions a reviewer would ask. This single case does not tell us how often AI introduces vulnerabilities.

The Corporate Payments Portal uses Java 21 and Spring Boot and includes a web portal, a payment API, a mock core banking service, and a batch worker. We use a pinned source revision so the excerpts match the report. That matters because a risky flow may begin with a controller and end with a service, while a dependency or configuration value can create a separate concern even when a Java method looks ordinary.

We ran a focused Qodana scan for data flows, vulnerable dependencies, hardcoded passwords, and dependency licenses. The password inspection was configured more broadly than its defaults for this example. Qodana’s findings provide starting points – a trace can show where data may travel, and a dependency alert can identify a version with known advisories. Neither, by itself, settles whether a specific attack is reachable in this deployment.

What Qodana found in the application

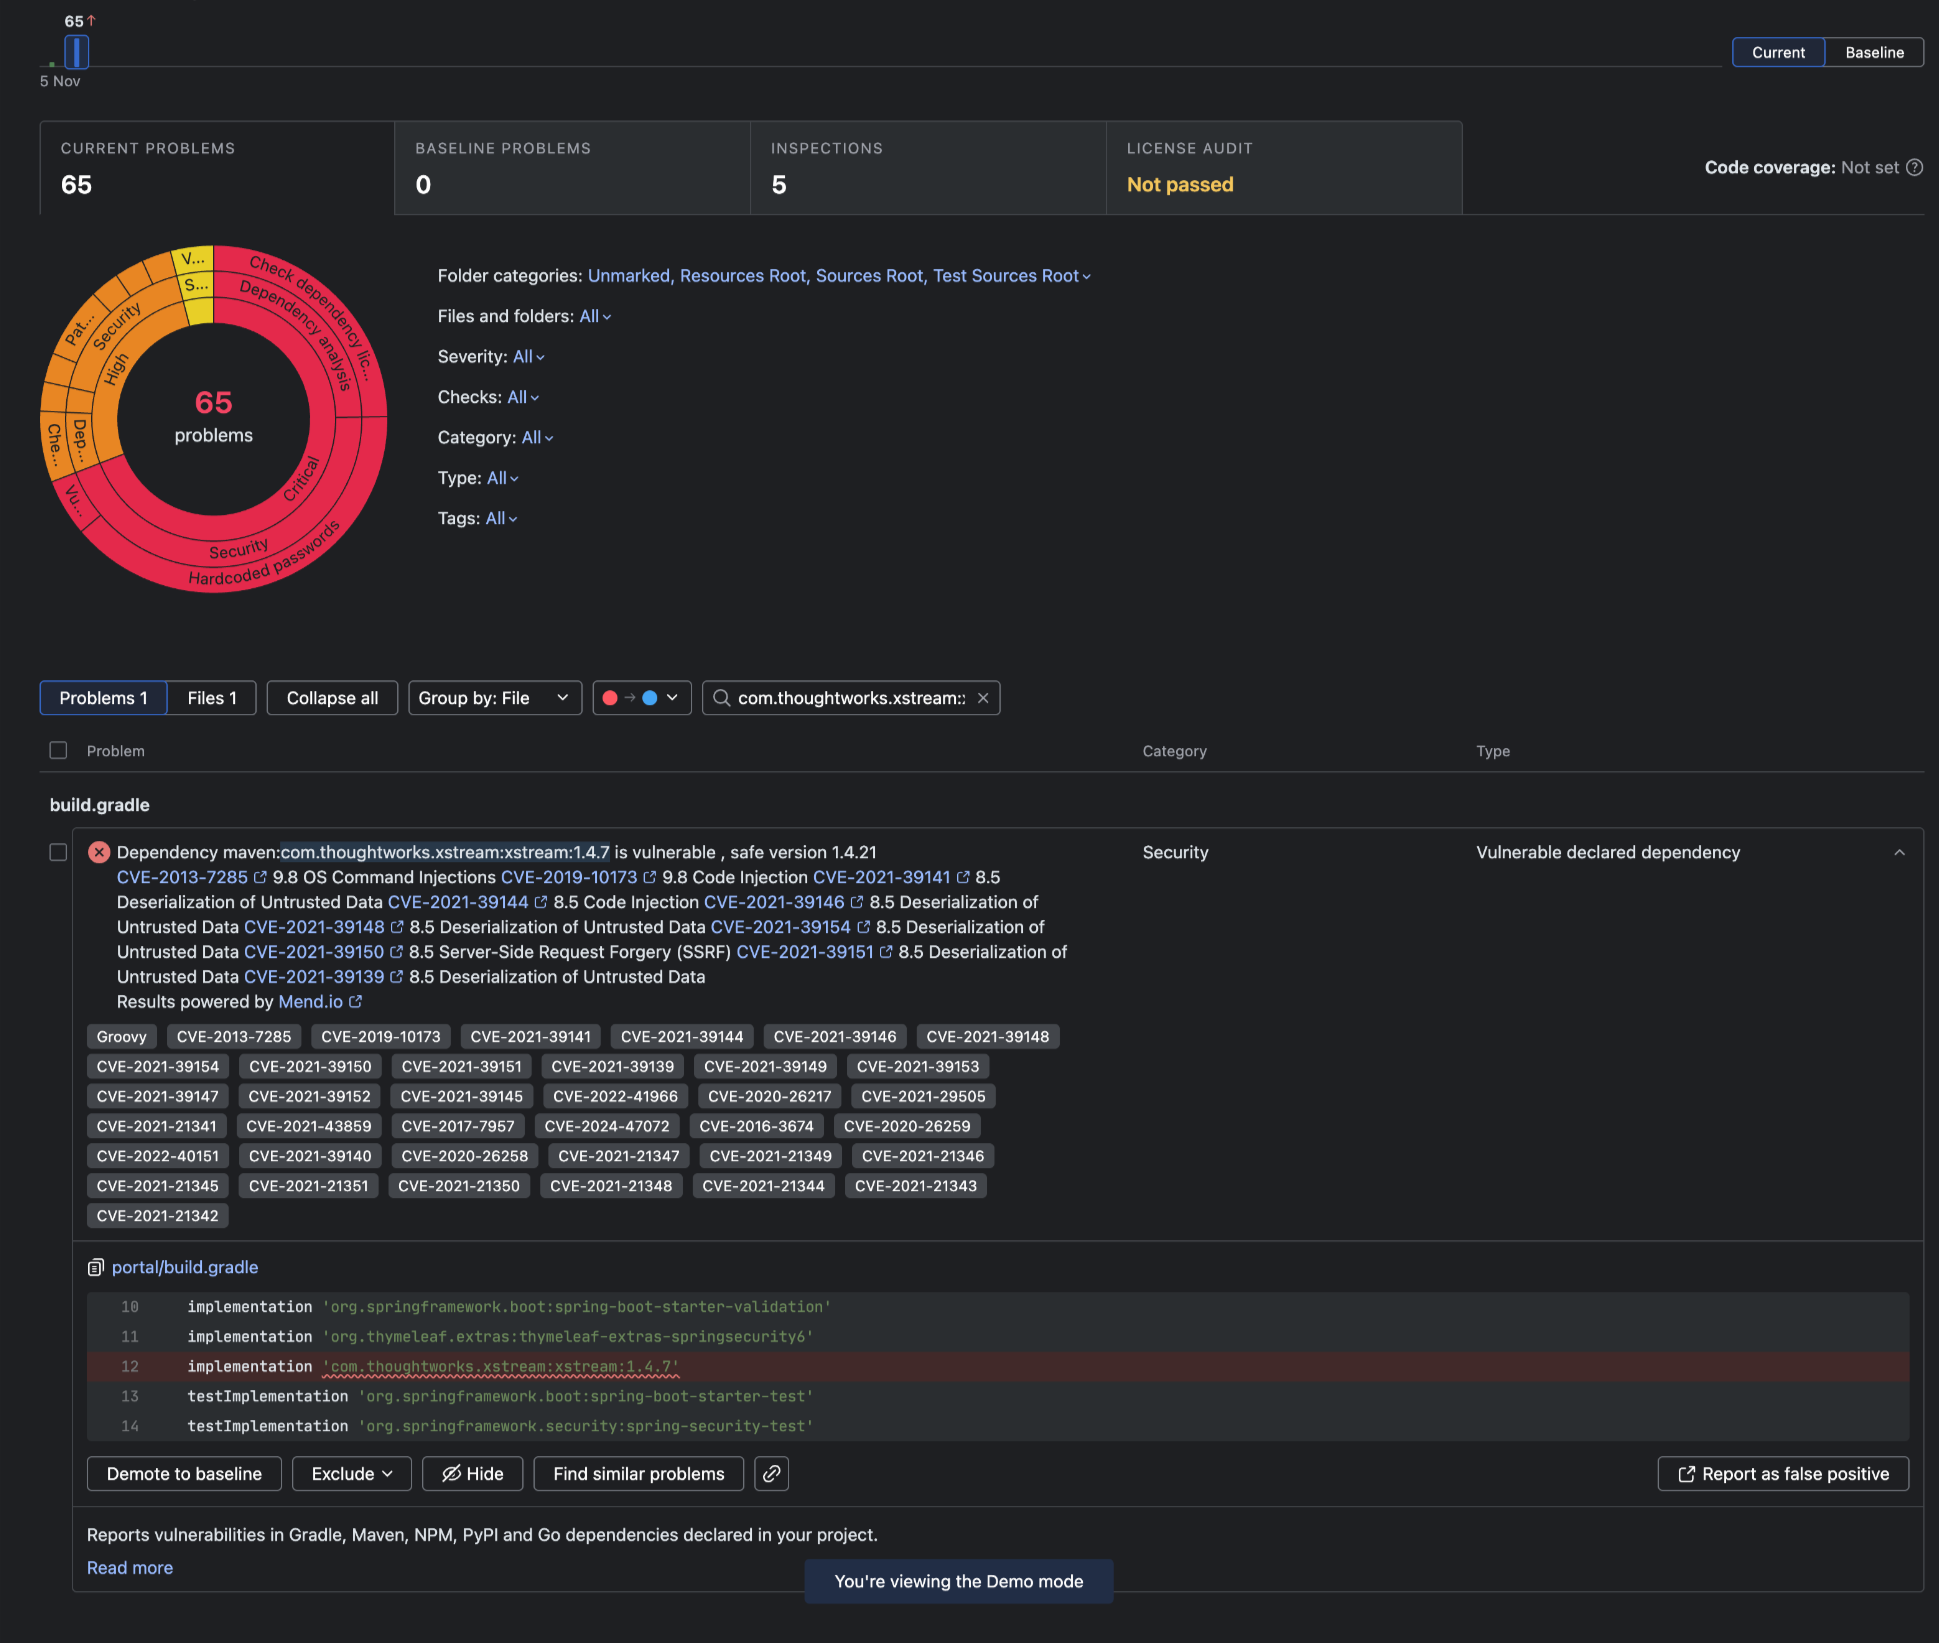
The public Qodana report lists 65 findings across 21 files. That is a triage queue, not a count of exploitable vulnerabilities. Alerts repeat across modules, and some point to synthetic values in tests and documentation. The examples below show how a finding can lead to a concrete question about code, configuration, or dependencies.

A vulnerable dependency and an XML-processing call

The Corporate Payments Portal’s web module parses XML drafts using XStream. Its build file, portal/build.gradle, declares version 1.4.7:

implementation 'com.thoughtworks.xstream:xstream:1.4.7'

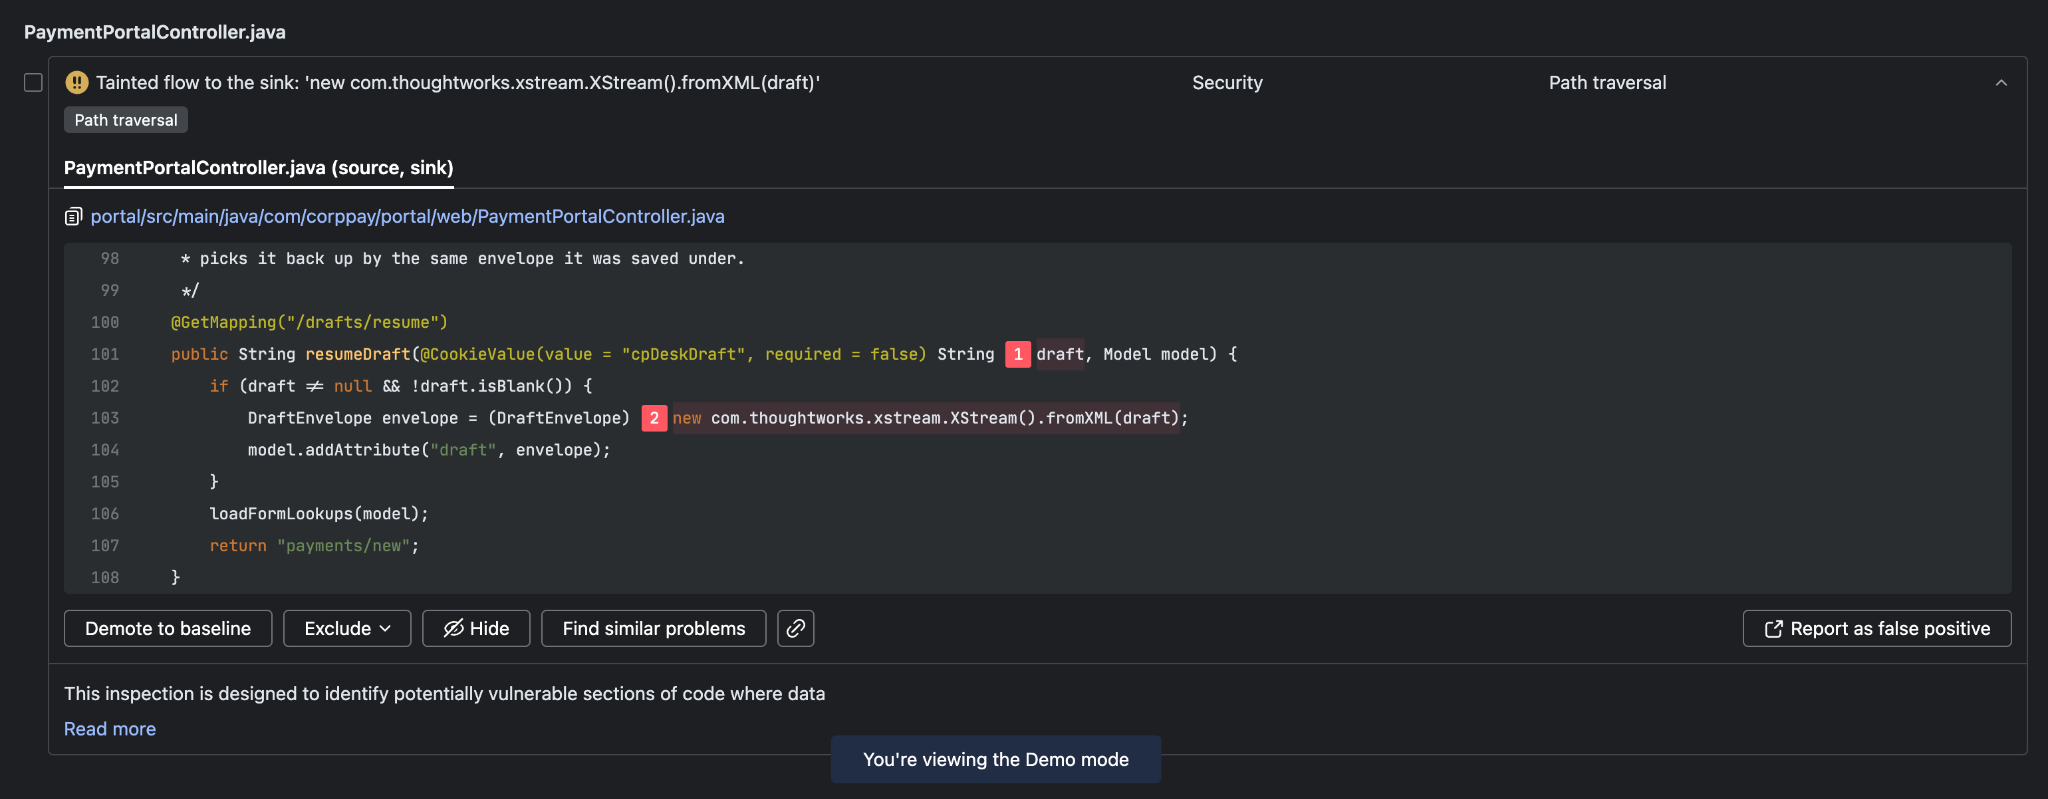
Qodana’s dependency check flags this version and lists known advisories. A separate taint finding points to the call that turns the XML string into Java objects:

new com.thoughtworks.xstream.XStream().fromXML(draft)

These two signals answer different questions. The dependency alert says the application includes a version with known issues. The fromXML(draft) call takes its XML from the cpDeskDraft browser cookie. The controller checks only whether the cookie is empty. Because a client can change its cookie, this is considered untrusted input. XStream 1.4.7 does not use a type allowlist by default, so deserialization can instantiate unintended types. The exact impact depends on the payload and runtime environment.

The taint finding is labeled path traversal in this report, and the vulnerable API usage inspection did not produce a separate result. It would be misleading to tie a specific CVE to this call from these findings alone. Review whether XML deserialization is needed at all. If it is, update the dependency, allow only expected types, and test that unexpected XML is rejected.

A hardcoded fallback remains in configuration

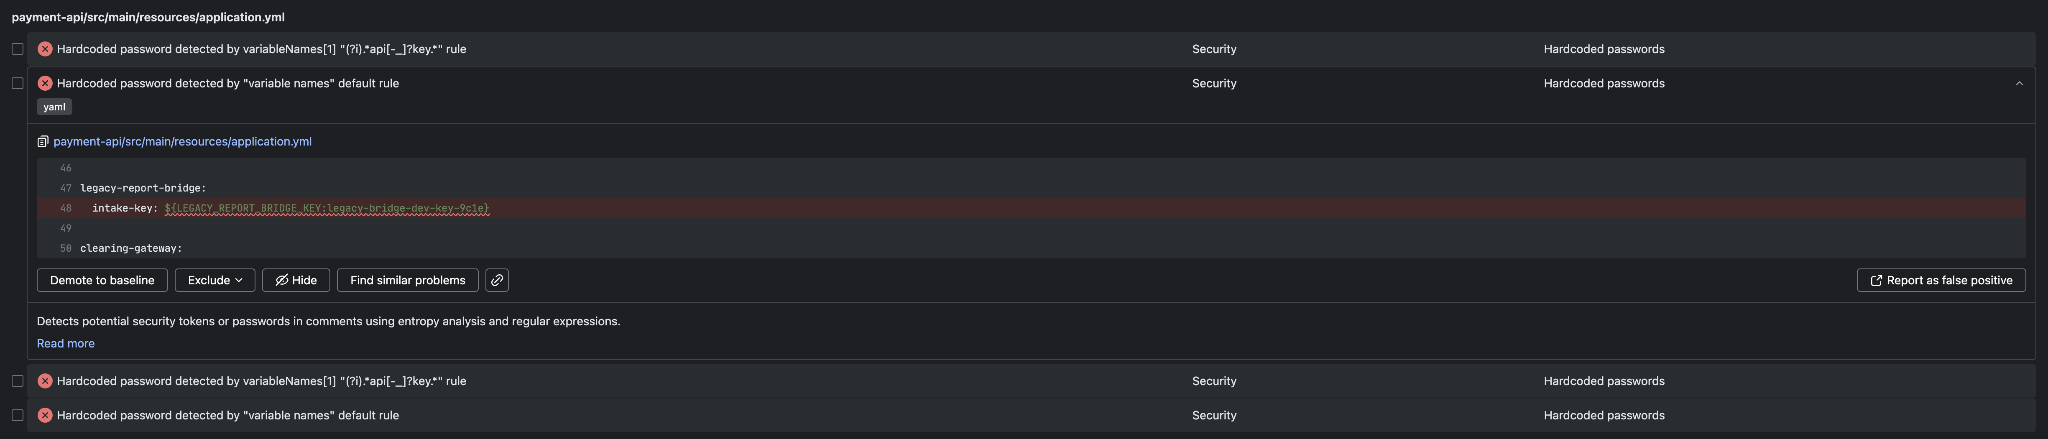
In the Corporate Payments Portal’s payment API, the legacy report bridge reads an intake key from a Spring configuration property. The colon inside the Spring placeholder defines a fallback value:

legacy-report-bridge:
  intake-key: ${LEGACY_REPORT_BRIDGE_KEY:legacy-bridge-dev-key-9c1e}

Spring reads the value after the colon when LEGACY_REPORT_BRIDGE_KEY is absent. The same fallback also appears in LegacyReportBridge‘s Java constructor. That component sends the resulting key to an internal reporting service as a bridge-key query parameter. In this benchmark, the value is synthetic, but a deployment that omits the environment variable could silently use a credential stored in source control.

Qodana’s Hardcoded passwords inspection flagged this example after we enabled detection based on suspicious variable names. Its default configuration would not flag this exact pattern. For production, remove the fallback in both the application.yml and LegacyReportBridge‘s @Value annotation. Require the key from an external secret source and fail startup if it is missing. Keep any development default confined to a development profile, and confirm whether the bridge is enabled in deployed environments.

For another example of Qodana detecting a hardcoded password, watch Helen’s video walkthrough:

A license finding raises a different question

One finding concerns dependency policy rather than an exploitable bug. In the Corporate Payments Portal, Qodana’s license audit flags hibernate-core 6.5.3.Final, brought in transitively, because its LGPL-2.1-or-later license is on the report’s prohibited list for a project marked PROPRIETARY-LICENSE. Transitive means another dependency brings the component into the build; it may not appear in the developer’s direct dependency list.

The risk is making a distribution decision without reviewing the dependency’s obligations. This is a policy signal, not a legal conclusion or evidence that hibernate-core is insecure. A reviewer should confirm the project’s actual policy and distribution model, review the applicable terms, and then document an accepted exception or choose another dependency path. Repeated alerts across modules do not necessarily represent different libraries.

How to use the findings in a security review

An alert becomes useful when it changes a review decision. The examples give us different kinds of evidence, and each leaves a different question open. The table summarizes selected signals:

PatternWhat Qodana showsReview question
Vulnerable dependencyAdvisories and an XML callWhat objects could XStream create from this cookie?
Credential fallbackConstant key in configurationCould the fallback run in production?
License policyTransitive license policy alertDoes the project policy allow it?

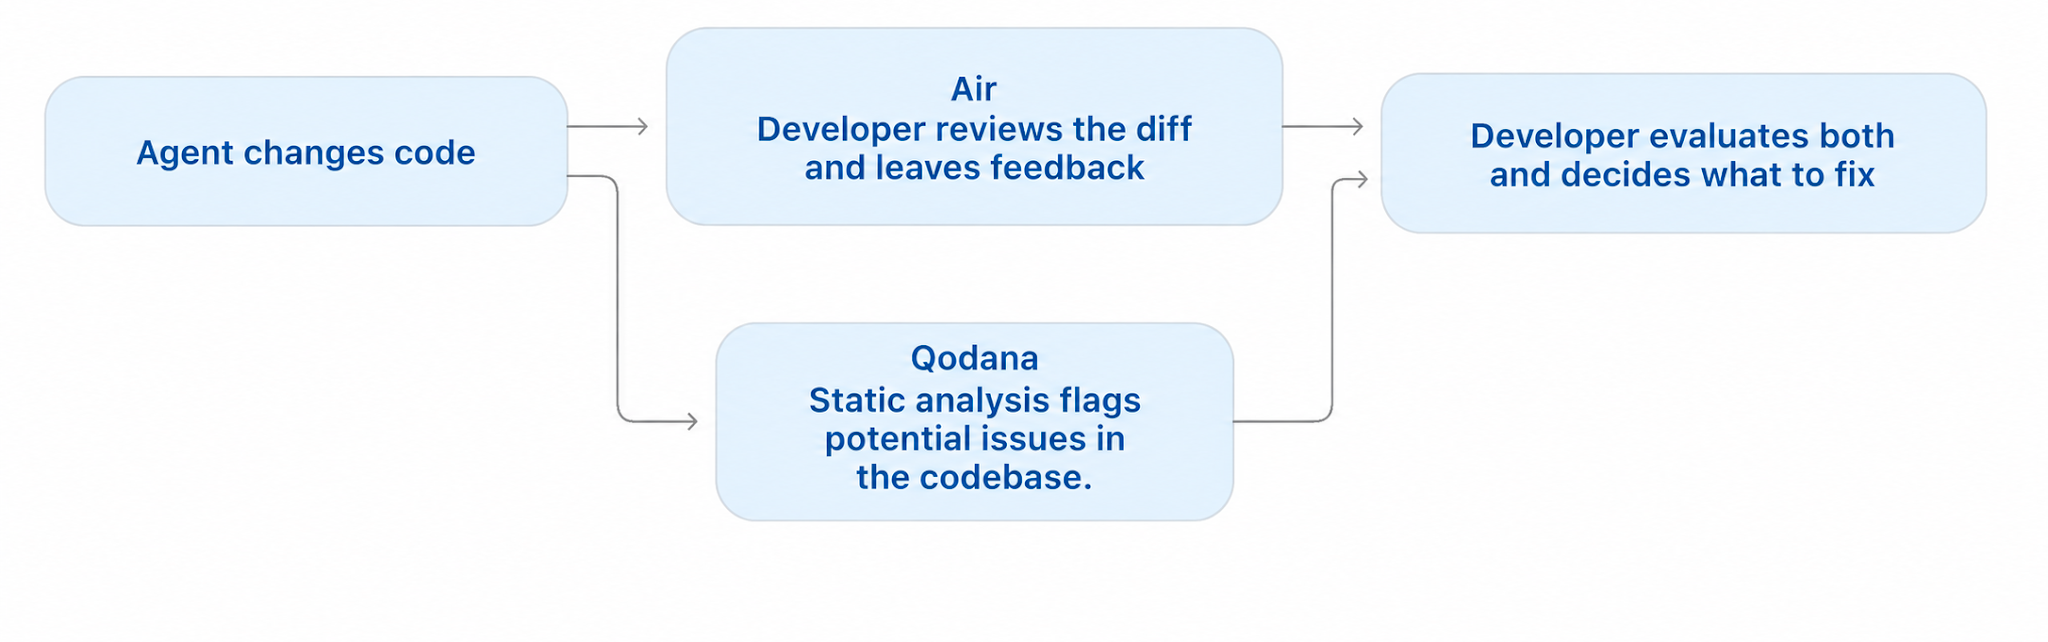
A developer using JetBrains Air can open an agent’s diffs in context and leave comments on specific lines for the agent to act on. Qodana adds a different view, scanning the codebase and reporting issues found by its inspections. The developer can weigh both when deciding what to fix. The findings discussed in this article were derived solely from Qodana.

From there, the team checks whether input reaches each operation, whether an affected component is actually used, and which configuration applies in deployment. It fixes the relevant code or policy, tests the change, and records why any remaining alerts are accepted or dismissed. Supported checks can also run in CI, so later changes receive the same review signals.

Static analysis makes these questions visible and repeatable. It helps the team spend review time on specific paths and components, while developers supply the application context and decide whether a change is ready to ship.

You can explore the evidence in our public report. If you would like to run the experiment yourself, leave a comment, and we’ll get in touch to help with the setup.

Explore Qodana’s Report

FAQ

Is AI-generated code more vulnerable than human-written code?

There is no universal answer. Results depend on the tool, task, application context, and review process. This deliberately vulnerable benchmark cannot establish a comparative rate.

Can static analysis detect every security issue in AI-generated code?

No. It can identify supported patterns and trace some data flows, but it can miss application-specific authorization rules and runtime behavior. Combine it with human review and targeted testing.

Can Qodana automatically secure AI-generated code?

Qodana can automate supported inspections and surface findings for triage. It cannot determine whether every flagged path is exploitable or whether the application’s security requirements are complete.

Book a demo

Get more practical insights on code quality and security. Subscribe to the Qodana blog for new posts.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Congratulations to WIRED’s Class of 2026

1 Share
This past year was, frankly, crazy. For our inaugural WIRED Yearbook, we celebrate the people, inventions, and viral moments that made it a little more bearable—and are already defining the future.
Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Is your OpenTelemetry pipeline becoming a performance bottleneck?

1 Share

At Cloud Native Days Austria 2026, I presented a talk called How to Defeat OTel’s Silent Killer: The Performance Overhead, exploring a problem that is easy to overlook when building observability pipelines: the cost of collecting telemetry itself.

OpenTelemetry has become a cornerstone of cloud-native observability, providing standardized APIs, SDKs, and tooling for generating, collecting, processing, and exporting metrics, logs, and traces. However, instrumentation and telemetry processing are not free. Every span created, attribute attached, and batch exported consumes resources.

As applications scale, poorly configured telemetry pipelines can introduce significant CPU usage, memory pressure, network traffic, and storage costs. In some cases, the infrastructure responsible for observing a system can become a performance problem of its own.

The good news is that much of this overhead can be understood, measured, and reduced without sacrificing the visibility engineers depend on.

Where does OpenTelemetry overhead come from?

At Cloud Native Days Austria 2026, I presented a talk called How to Defeat OTel’s Silent Killer: The Performance Overhead, exploring a problem that is easy to overlook when building observability pipelines: the cost of collecting telemetry itself.

OpenTelemetry has become a cornerstone of cloud-native observability, providing standardized APIs, SDKs, and tooling for generating, collecting, processing, and exporting metrics, logs, and traces. However, instrumentation and telemetry processing are not free. Every span created, attribute attached, and batch exported consumes resources.

As applications scale, poorly configured telemetry pipelines can introduce significant CPU usage, memory pressure, network traffic, and storage costs. In some cases, the infrastructure responsible for observing a system can become a performance problem of its own.

The good news is that much of this overhead can be understood, measured, and reduced without sacrificing the visibility engineers depend on.

Where does OpenTelemetry overhead come from?

When discussing OpenTelemetry performance, we often focus on the application SDK. However, the cost extends beyond instrumentation.

The entire telemetry pipeline contributes to resource consumption, from generating spans and collecting metrics to processing, exporting, and storing data.

Instrumentation overhead is also workload-dependent. Two applications using the same instrumentation libraries can experience very different results depending on request throughput, attribute volume, runtime behavior, and the number of spans generated per request.

This is why relying on a single overhead percentage can be misleading. Instead, we should examine CPU consumption, memory usage, application latency, telemetry volume, and the behavior of the Collector under load.

There is also an important trade-off between application safety and telemetry completeness. When a pipeline becomes overloaded, backpressure and memory safeguards can protect the application and OpenTelemetry Collector, but they may also lead to rejected or dropped telemetry.

The objective is not simply to minimize resource consumption. It is to maintain useful observability while keeping its operational cost predictable.

Investigating the Collector: five common configuration problems

For my demonstration, I used Telemetrygen, an OpenTelemetry utility that generates synthetic telemetry, to investigate how Collector configuration affects resource consumption.

The investigation focused on five common sources of unnecessary overhead.

1. Inefficient batching

Exporting small amounts of telemetry frequently can increase serialization work, export requests, and network overhead.

The OpenTelemetry Collector groups telemetry inside the exporter’s sending queue before transmitting it downstream, helping amortize this work across larger payloads. (Note: Historically, this was handled by a standalone batch processor, which is now deprecated in favor of built-in exporter batching).

However, batching parameters should reflect the actual workload. Larger batches are not automatically better: they can increase buffering requirements and affect export latency.

exporters:
  otlp_grpc:
    endpoint: "otel-backend:4317"
    sending_queue:
      enabled: true
      sizer: items       
      queue_size: 100000 
      batch:
        enabled: true
        min_size: 8192
        flush_timeout: 200ms

Configuring batch inside an exporter’s sending_queue groups spans, metrics, or logs before forwarding them downstream, improving compression efficiency and durability while reducing export overhead. Batches are sent when a configured size threshold is reached or a timeout expires.

In this example, min_size: 8192 triggers an export when the batch reaches 8,192 items, while flush_timeout: 200ms triggers an export regardless of batch size. Once batching is enabled, these values are the Collector’s documented defaults, not universal performance recommendations. (Note: Because unbatched requests enter the queue first in this architecture, this example switches sizer from the default requests to items with a queue_size of 100000 to prevent smaller, unbatched bursts from overflowing the queue).

The important point is to measure how batching affects resource consumption and throughput rather than relying on example configurations.

2. Unnecessary resource attributes

Resource attributes provide valuable context about the systems producing telemetry. But collecting and forwarding attributes that nobody uses can increase payload sizes and downstream processing costs.

For example, an application might need host.name, host.arch, and os.type for troubleshooting, but not detailed hardware information such as host.cpu.model.name or host.cpu.cache.l2.size.

The OpenTelemetry Collector’s resource detection processor allows engineers to configure which system attributes are collected. Disabling unnecessary attributes can reduce telemetry volume and processing overhead, although the impact on storage and cardinality depends on the backend.

A practical example: Keep the hostname and operating system type, but disable CPU model and cache metadata when those details are not needed for troubleshooting.

3. Aggressive receiver polling

Infrastructure receivers collect metrics at configured intervals, often independently of application traffic.

Polling host metrics, container statistics, databases, and network services every few seconds creates continuous work even when applications are relatively idle.

Increasing collection intervals from 10 to 30 seconds, where operational requirements permit, can reduce collection frequency and associated overhead.

This introduces a trade-off: lower polling frequency means less temporal resolution. The appropriate interval depends on how quickly a metric changes and how it is used for troubleshooting or alerting.

4. Exporting every trace

Not every successful request needs to produce a trace that is retained.

Exporting all traces can consume significant bandwidth, Collector resources, and backend capacity, particularly in high-throughput applications.

Sampling provides a way to control this volume.

Head-based sampling makes decisions early, reducing downstream work. Tail-based sampling makes decisions after observing more of a trace, enabling policies that retain errors or other diagnostically interesting requests.

Figure 1: OpenTelemetry Collector YAML configuration showing tail-based sampling with a 10-second decision window. The configuration retains traces with an ERROR status and probabilistically samples 5% of traces. The trace pipeline applies memory limiting, resource detection, span sanitization, GenAI normalization, tail sampling, and batching before exporting telemetry.

These policies retain traces with an error status and probabilistically sample 5% of traces, including potentially some additional error traces. However, tail sampling is not free. It requires buffering trace data until a decision can be made, introducing additional memory and processing overhead. 

Choosing a sampling strategy means balancing cost, diagnostic value, and the resources needed to make sampling decisions.

5. Memory safeguards applied too late

The OpenTelemetry Collector includes a memory_limiter processor to help manage memory pressure.

Processor ordering matters. When enrichment and transformation processors run before memory limiting, the Collector may perform additional work on telemetry that is subsequently refused under memory pressure.

Memory limiting is a protective mechanism rather than a performance optimization in itself. Its purpose is to improve stability under pressure, not necessarily to reduce CPU consumption during normal operation. Placing the memory limiter early in the pipeline helps apply safeguards before more expensive processing. 

It is important to understand that the memory limiter is not a substitute for appropriate resource limits or capacity planning. It can refuse incoming data when memory pressure becomes excessive, and receivers must handle this behavior correctly to avoid unnecessary telemetry loss.

From local experiments to production architecture

Optimizing a single Collector is only part of the solution.

In Kubernetes, telemetry workloads can fluctuate significantly as applications scale, deployments change, and traffic increases. A Collector configuration that performs well under synthetic load may behave differently in production.

Here are some architectural practices that can help address these challenges.

  1. Separate collection from centralized processing. A two-tier architecture can use lightweight edge Collectors for local collection and gateway Collectors for more expensive processing. This allows different parts of the pipeline to scale according to their workloads.
  2. Control telemetry volume early. Filtering unnecessary attributes, removing unneeded data, and avoiding excessive cardinality can reduce the amount of information processed and transferred downstream. These decisions should preserve the context required for debugging and correlation.
  3. Plan for memory pressure and backend outages. Kubernetes memory limits, Collector memory safeguards, bounded queues, and retry mechanisms serve different purposes. Persistent queues can improve resilience during temporary backend failures, but they still require capacity planning and cannot guarantee delivery under every failure scenario.
  4. Scale with signal-specific requirements in mind. Horizontal scaling can increase throughput, but stateful processing requires additional consideration. Tail sampling, for example, generally requires spans belonging to the same trace to reach the same processing instance.

These architectural decisions are just as important as tuning individual processors.

Don’t forget the instrumentation

One of the most effective optimizations happens before telemetry reaches the Collector.

Instrumentation should answer meaningful operational questions rather than collect everything simply because it is possible. Excessive spans, high-cardinality attributes, and unnecessary instrumentation can increase resource consumption throughout the entire pipeline.

For metrics, attributes containing unbounded values such as unique request IDs can create large numbers of distinct time series. For traces and logs, excessive attributes and events increase payload sizes and may affect backend processing or indexing costs.

Why I chose Telemetrygen for my demo

When preparing my performance investigation, I initially considered using the official OpenTelemetry Astronomy Shop. While it is an excellent environment for exploring instrumentation across microservices, its multiple applications, databases, and supporting services introduce additional CPU and memory consumption.

For this experiment, I wanted to isolate the Collector’s performance overhead without the background noise of a complete application environment.

Instead, I chose Telemetrygen, a lightweight utility for generating synthetic traces, metrics, and logs at controlled rates.

In my OpenTelemetry performance overhead demo, I used synthetic telemetry to investigate how Collector configuration affects resource consumption. The demonstration walks through common inefficiencies, including missing batching, unnecessary resource attributes, aggressive receiver polling, excessive trace export, and memory limiter placement, showing how targeted configuration changes can improve pipeline efficiency.

This approach helped isolate Collector behavior, but it is only one part of the performance picture. For understanding instrumentation overhead inside real applications, a complete environment such as Astronomy Shop remains valuable.

Exploring instrumentation further

Reducing overhead starts with understanding what telemetry an application generates and why. The official OpenTelemetry instrumentation documentation introduces automatic and manual instrumentation, while the sampling documentation explains how to control trace volume. These are useful starting points for reviewing instrumentation decisions before optimizing the Collector itself.

For engineers interested in investigating performance further, the OpenTelemetry Collector documentation covers pipeline configuration and processing. The OpenTelemetry community is also a good place to discuss performance challenges. The Collector SIG focuses on Collector architecture, performance, and configuration, with discussions taking place in the #otel-collector channel on CNCF Slack.

For questions about instrumentation overhead in a specific programming language, the corresponding language SIG is a better starting point. The OpenTelemetry community page provides information about SIGs, public meetings, and how to get involved.

Making performance part of observability design

OpenTelemetry overhead is not a single problem with a single configuration fix.

It is the combined effect of instrumentation decisions, data volume, processor configuration, export behavior, and infrastructure architecture.

The most useful lesson from this investigation is that observability pipelines should be measured and optimized like any other production system.

Start with controlled benchmarks. Understand where resources are consumed. Introduce configuration changes individually, and evaluate their impact on CPU, memory, latency, throughput, and telemetry loss.

Most importantly, treat example configurations as starting points rather than production-ready defaults.

OpenTelemetry gives us the tools to understand complex distributed systems. With thoughtful instrumentation, careful pipeline configuration, and appropriate scaling strategies, we can ensure that collecting this information does not become an unnecessary burden on the systems we are trying to observe.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

AI Sped Up The Build: How Can Accessibility Testing Keep Up?

1 Share

This article is a sponsored by Level Access

Lately, I’ve been thinking and writing a lot about what AI is doing to product development, and what that means for accessibility. The thing that has my wheels turning is a finding from Level Access’s 2026 State of Digital Accessibility Report. Basically: AI is helping us hit fast-forward on the build, but testing practices haven’t kept up.

We asked more than 2,500 professionals where they noticed AI was speeding up their work in the SDLC. Most said they noticed gains in planning (58%), design (61%), and development (51%). But QA and testing lagged behind: Only 30% said AI had sped up that stage.

These results point to a two-speed workflow. AI has turbocharged design, planning, and development, while checking and validation are still running at a very different pace. This means a lot of teams are likely racing through the build, then being forced to hit the brakes the moment someone has to answer a pretty fundamental question: Is this thing actually accessible?

Accessibility has historically been treated as a QA bottleneck, and AI is pushing far more work into it, faster. If your team has already shifted left on accessibility, you’re off to a good start. But AI has reshuffled the workflow, so even proactive teams need to work out where those early checks belong now.

This matters because right now, the web is moving in the wrong direction. WebAIM’s latest scan of the top million home pages found that automatically detected errors per home page rose 10.1% in a year, from 51 to 56.1 per page. WebAIM cited AI-assisted coding as one possible contributing factor.

So how do we get validation out of first gear? How do we build human judgment into the workflow as AI keeps pushing the pace?

AI Isn’t The Biggest Differentiator

We looked at the organizations that are improving across every accessibility metric they track (a group we call the “improvers”) to find out what they’re doing differently.

Here’s what stood out: AI adoption made the smallest difference of anything we measured. Improvers use AI at a similar rate to everyone else we surveyed. Their edge shows up in the maturity of their surrounding accessibility practices — things like training, communication, and a culture of accessibility.

A quick caveat: This is survey data, so it only shows correlation, and mature programs may simply be better at tracking and reporting their wins. Even so, this finding was hard to ignore.

And it got even more interesting. Professionals in mature accessibility programs were nearly six times as likely to say AI helps them prioritize issues. They were also nearly three times as likely to say it helps them tackle accessibility more proactively in development.

In other words, AI works best as an amplifier of a strong program. With context, testing, environments, and guardrails in place, agents can take on a large share of the work from drafting through to operations, and much of the time lost to waiting and handoffs goes away. People stay responsible for deciding what to build and for approving what ships.

So let me ask you: When it comes to accessibility, where does human judgment sit in your workflow today?

Not sure? Here’s a quick way to find out.

Pick a feature you shipped recently and trace it from the first Figma frame to production. Mark every moment a person decided whether it would work for someone using a keyboard, a screen reader, or their browser at 400% zoom.

How many marks did you get? If most of them cluster at the end of creation, you’re likely heading to one of two places: You’ll either ship accessibility barriers or spend the time you saved upstream fixing them later, when they’re harder and costlier to fix.

Here’s how to avoid both outcomes by building the right accessibility checks and judgment calls into the work your team is already doing.

Build The Judgment Calls Into Your Workflow

As AI takes on more work, people need to stay involved at three points: finding issues, fixing them, and documenting the evidence. Each one plugs into a step your team already takes, like a handoff, a pull request, or a review, so nothing new gets added to the timeline, and accessibility keeps pace with the work that’s in motion.

1. Find: Catch Issues While The Work Is Still Warm

Context fades fast. Put the first judgment checkpoints as close to the creation work as you can:

  • Start at the handoff.
    Spell out focus order, accessible names, states, heading structure, and what gets announced when something changes or goes wrong. If you leave anything vague, the model fills the gap with its own defaults. Then, put it where the model reads it: your design system components, rules files (Cursor rules, AGENTS.md, Copilot instructions), and prompt templates, not only a spec document. For designers, free annotation kits make this concrete. GitHub’s Annotation Toolkit offers Figma components for marking headings, landmarks, focus order, and keyboard behaviour on the canvas, so the intent travels with the file instead of living in someone’s head.
  • Gate the pull request.
    Run checks in your CI/CD pipeline and at the pull request. Let them block or warn on a merge. Compare against a baseline so you only review changes. (This is the automated half of the gate: The human half of this same checkpoint shows up again under Fix). Most teams already have the tooling in place for this, but what is new is volume. AI-assisted pull requests arrive faster than reviewers can read them, so the automated gate matters more, not less. In React projects, eslint-plugin-jsx-a11y flags issues before commit, while Pa11y and Lighthouse CI scan builds for new errors. Level CI also brings accessibility testing into the CI/CD workflow, including pre-merge detection, delta findings, quality gates, and fix recommendations in pull requests.
  • Let automation do the sweep, send the judgment calls to people.
    Run automated checks across pages, screens, and documents for broad, repeatable coverage. For the sweep, QualWeb, for example, checks pages against the W3C’s ACT rules. Running your tests across several engines, like axe-core and Equal Access, can be a good idea, as one may help you catch things that the other misses. But, have people assess usability: A dropdown can pass automated checks while its submenu remains inaccessible to keyboard users.
  • Give every check an owner.
    For example, designers specify focus, errors, and states. Developers run a keyboard pass and a screen reader smoke test on custom components. (Note: Screen reader testing is harder in practice than it may seem at first, so your team might need an introductory training). UX or QA navigates the full journey. Put accessibility metrics in acceptance criteria and the definition of done, and back it with component-level tests because “everyone owns it” has a funny way of turning into “nobody did it.” When teams decide, in advance, who is responsible for each check, they create the clarity and communication that our data shows sets the organizations improving accessibility apart from those stuck fighting ever-growing backlogs.

2. Fix: Act Before The Context Goes Cold

Found the issue? Great. Fix it while it’s fresh. When issues end up as tickets, make sure the context travels with them. They should carry the element, the repro, the related WCAG criterion, a suggested fix, and the PR link, so context doesn’t leak.

  • Move the guidance to the work.
    Whether the fix happens in the editor, the design file, or the component library, the answers should be right there. If your team uses an AI coding assistant, an MCP server can pull accessibility findings and fix guidance straight into it so developers can work through issues without leaving their editor. Level Access offers one that connects to tools like Cursor and Claude.
  • Let AI take the first pass.
    Use AI to draft, with guardrails. AI coding assistants can propose changes quickly, but they optimize for a passing check, not a correct experience. Give them grounded fix guidance for the specific issue, and treat their output as a draft. Open-source skill sets can help ground that guidance. A good starting point is the accessibility instructions file in the Awesome Copilot collection, which steers Copilot toward accessible patterns. Once you’ve got your draft, re-run the check, then review the semantics and test the behaviour because a green result can come from markup that looks right and isn’t (e.g., role="button" on a div, redundant ARIA, invented alt text). The speed is useful only if verification keeps pace.
  • Review before anything merges.
    Test the change in context. Did it solve the original problem without breaking anything else? Does the interaction now behave and announce itself as intended? Note: This gate is doing different work than the per-check testing upstream in “Find”: That caught the issue; this work confirms the fix actually holds in context.
  • Work the backlog by impact.
    Pulling older findings? Start with things that block someone from completing a key journey, like paying a bill or resetting a password. Then tackle the quickest fixes first. Include the component, what went wrong, and the guidance to fix it. Don’t expect someone to reconstruct the story.

3. Prove: Leave A Receipt

The worst time to start gathering evidence is when somebody’s asking for it.

Every check, fix, and judgment call throughout the process described above should ideally leave a trail. A fix isn’t done until something fails if the issue comes back. Ask your AI assistant to write the regression test with the fix and put the finding link and any judgment call in the PR description. That’s the receipt.

A passing test shows a known issue hasn’t returned. It doesn’t show the experience works. For what automation can’t cover, add a short note to the PR: what you tested, with which assistive technology, and any judgment calls you made.

  • Let tooling do the admin.
    When someone later asks what was tested and who approved it, tooling can assemble the answer from those PRs and tests. We cut VPAT/ACR authoring time by more than 70% this way with the Level Access Reporting Agent, but only because the evidence already existed. Again, the tool compounds a practice. It doesn’t replace one.
Keep The Speed: Move The Judgment With It

AI has given digital creation a speed boost, but broadly speaking, validating the work hasn’t kept pace. Closing that gap isn’t about adopting more AI in more places or abandoning the toolset that helped make your team faster.

According to our data, the opportunity in front of teams is to build the practice around that toolset, so that human judgment is flagged, embedded, and acted on earlier, and more often.

We’ve only scratched the surface of what our data tells us about AI and accessibility. If you’re curious about what else we found, check out the 2026 State of Digital Accessibility Report. There’s plenty more to unpack.


Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Build a Simple AI Coding Harness in C# with SharpVector and Microsoft Agent Framework

1 Share
Build a small C# AI coding harness that searches project context with SharpVector, edits an approved file, and uses deterministic scripts to validate the result.
Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories