Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162809 stories
·
33 followers

Coding, Math, and AI: What’s Ahead for School Students in 2026–2027

1 Share

Looking for new ways to challenge your programming skills, explore AI, or get better at solving math problems?

This school year, JetBrains is bringing even more opportunities to young people interested in technology. From free online clubs and coding competitions across Europe to intensive programming camps, there’s plenty to get involved in.

Whether you want to prepare for competitions, learn something new, or meet other students who share your interests, here’s what’s coming up in 2026–2027.
Join one of our free Youth Clubs

Our Youth Clubs bring together school students who want to go further in mathematics, programming, and AI. Through practical assignments and challenging problems, participants can develop their skills and learn alongside like-minded peers.

Youth Math Club

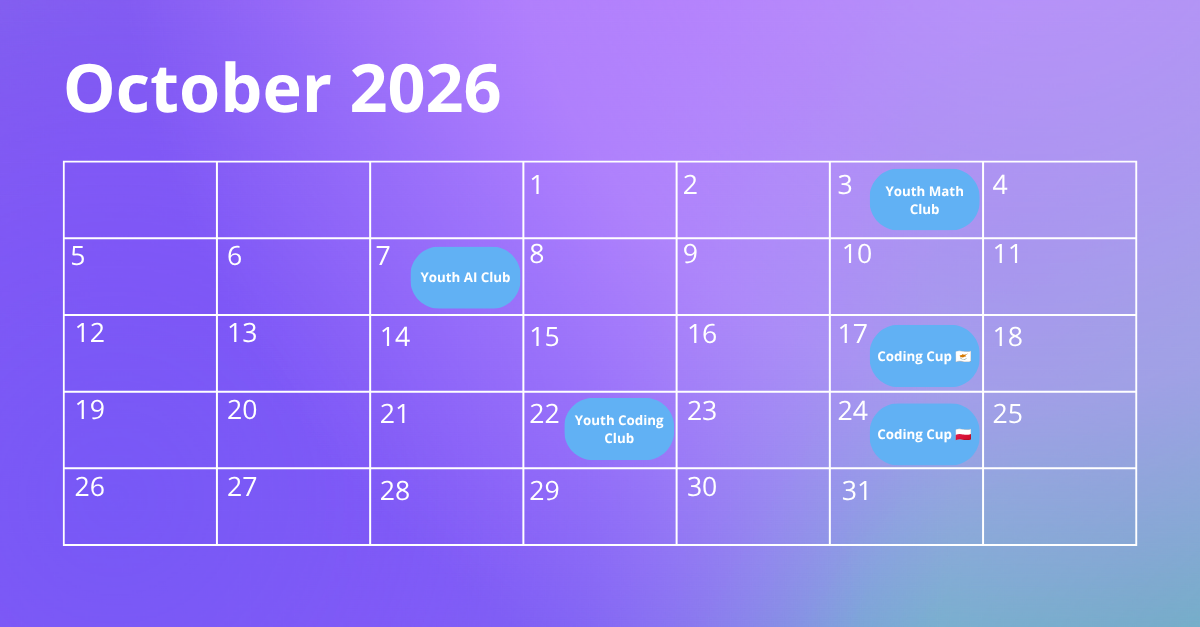
Registration open until October 31

Mathematical thinking is at the heart of good programming. At the Youth Math Club, students practise solving unfamiliar problems, identifying patterns, and developing logical reasoning skills.

It’s an opportunity to strengthen mathematical foundations and learn to approach complex problems with confidence.

Youth AI Club

Registration open until October 31

What does it take to build and train a machine learning model?

At the Youth AI Club, students explore the mathematics and programming behind artificial intelligence. Through practical assignments, they work with machine learning problems, train models, and experiment with neural networks.

Youth Coding Club

Starts October 22

For students who enjoy solving programming problems and finding efficient solutions, the Youth Coding Club offers opportunities to put their skills into practice.

Participants tackle coding challenges, strengthen their problem-solving abilities, and develop their programming skills step by step.

JetBrains Coding Cups: Cyprus, Poland, and Serbia

This autumn, we’re bringing our in-person JetBrains Coding Cups to new locations: Cyprus, Poland, and Serbia.

Open to school students aged 13–19, these competitions offer a chance to test programming skills, tackle interesting problems, and meet fellow young coders.

DateCountry
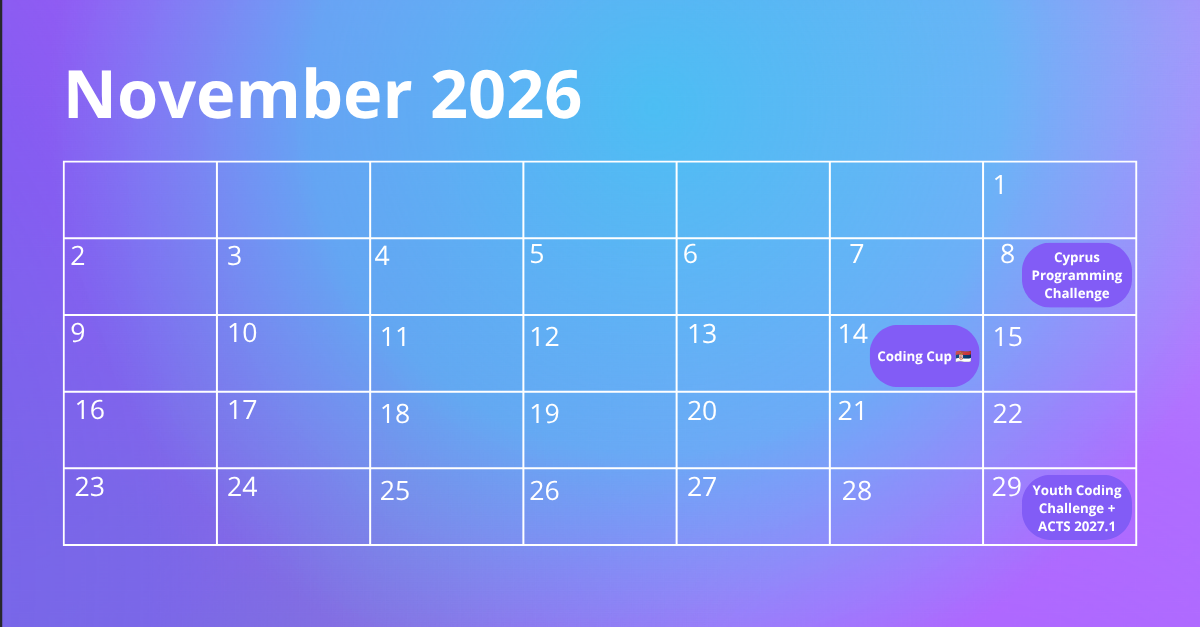
October 17, 2026🇨🇾 Cyprus
October 24, 2026🇵🇱 Poland
November 14, 2026🇷🇸 Serbia

The Cyprus Programming Challenge returns for its fourth edition

November 8, 2026 | Cyprus

The Cyprus Programming Challenge is back for the fourth time!

This competition brings together young programmers from across Cyprus to solve problems, demonstrate their skills, and gain competition experience.

It’s open to both middle and high school students, with participants of all skill levels welcome.

Registration opens soon. Follow us on Instagram and LinkedIn for announcements.

Youth Coding Challenge: Put your skills to the test and unlock new opportunities

November 29, 2026

The Youth Coding Challenge is more than a programming competition. It’s also an opportunity for students to take the next step in their learning journey.

This year’s challenge features two leagues, each offering different opportunities.

Junior League (ages 13–15)

Winners may receive an invitation to join the second level of the Youth Coding Club in the spring semester, with opportunities for in-person learning alongside teaching assistants and teachers.

Senior League (ages 16–19)

Competition results can count towards selection for ACTS 2027.1, our intensive programming camp in Cyprus, planned for March 15–26, 2027.

ACTS stands for Algorithm and Code Training Schools. These camps bring motivated students together to learn from experienced teachers, take part in programming contests, and exchange ideas with other young programmers.

Registration opens soon. Follow us on Instagram and LinkedIn for announcements.

ACTS 2027.1: Eleven days of programming, AI, and learning together

March 15–25, 2027 | Cyprus

One of the highlights of the academic year will be the next edition of ACTS.

For eleven days, school students will come together in Cyprus for intensive learning, practical challenges, and discussions with teachers and peers who share their passion for technology.

ACTS 2027.1 will feature three tracks:

  • Competitive Programming: For students who want to deepen their algorithmic knowledge and sharpen their contest skills.
  • Software Engineering: For students interested in developing their software development and practical programming skills.
  • Artificial Intelligence: For students looking to explore advanced AI topics alongside other talented young learners.

Results from the Youth Coding Challenge on November 29 will be considered during selection for the Competitive Programming and Software Engineering tracks.

The AI track will follow a different format. Participation will be by invitation only, bringing together national teams from five countries and 20 students living in Cyprus who are taking part in the selection process for the country’s International Olympiad in Artificial Intelligence (IOAI) national team.

Beyond the lectures and coding challenges, ACTS is also about meeting people who share your interests, exchanging ideas, and finding new motivation to keep learning.

Registration is expected to open in mid-October. If you’re interested, follow our Instagram and LinkedIn channels for updates.

Read the whole story
alvinashcraft
41 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Keep calm and call clone with Rust

1 Share
Ryan sits down with Josh Triplett, member of the Rust Leadership Team at the Rust Project, to chat about how the borrow checker delivers compile-time memory safety without garbage collection overhead, why Rust consistently ranks as developers' most loved language by providing psychological safety for complex systems, and how strict compiler constraints make Rust an ideal target for AI coding agents.
Read the whole story
alvinashcraft
41 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Out Now: Building Serverless Applications with WebAssembly & Spin

1 Share

Hey friends 👋🏼,

The wait is finally over! After countless early mornings, extensive refactorings, and hours spent obsessing over every code sample and diagram, the first version of Building Serverless Applications with WebAssembly & Spin is officially live.

You can grab your copy right now on Leanpub:

👉 https://leanpub.com/building-serverless-apps-with-wasm-and-spin

Building Serverless Applications with WebAssembly & Spin

What the Book Is About

Server-side WebAssembly represents the next major evolution in cloud architecture. By combining sub-millisecond cold starts, near-native performance, and robust sandboxed isolation, Wasm components eliminate the overhead of traditional containers and function-as-a-service platforms.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Deep dive into Azure Maia 300 architecture

1 Share

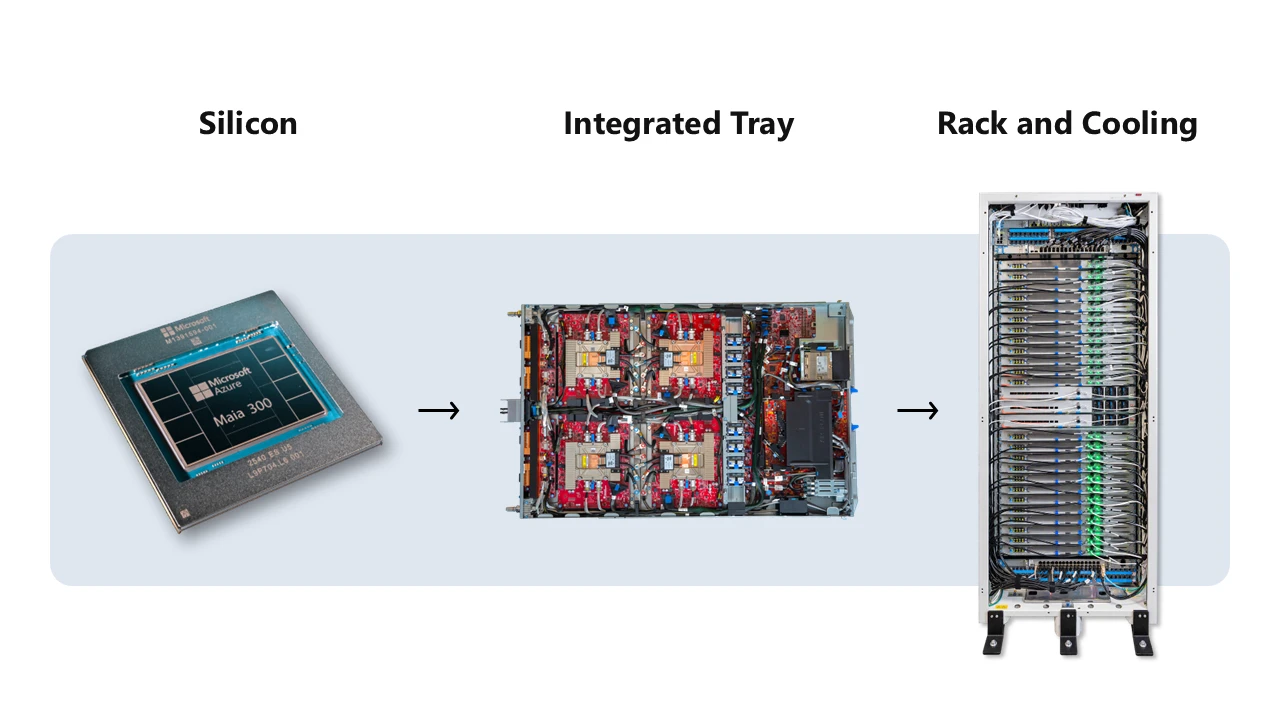
From its inception, Azure Maia has been built around a single architectural philosophy: optimize the entire system for LLM inference so that every watt and every dollar delivers more intelligence. Now in its third generation, Maia 300 is the fullest expression of that philosophy. Maia 300 is built as a complete system, with software, silicon, physical rack infrastructure, networking, and datacenters co-designed to operate as a single platform to meet the demands of cloud-scale agentic inference.

That system-level approach is increasingly necessary as agentic workloads, including multi-step execution, long-context decoding, and tool use, change the computational profile and arithmetic intensity of inference. Meeting these demands requires sustaining locality, supplying compute with enough memory capacity and bandwidth, minimizing data movement, scaling communication efficiently, and fitting the most capability within a datacenter’s fixed power and cooling envelope.

At Microsoft, we see this transformation firsthand through the products and platforms our customers use every day, from Microsoft Copilot and GitHub Copilot to Microsoft Foundry. Operating these workloads at scale gives us a unique view into how AI is being adopted across industries and the infrastructure needed to support the next generation of AI applications and agents. Maia 300 is designed to maximize useful tokens per watt and useful tokens per dollar, bringing more capacity, capability, and performance to these products and Microsoft’s broader AI portfolio for our customers.

Energy-efficient inference through software-defined dataflow

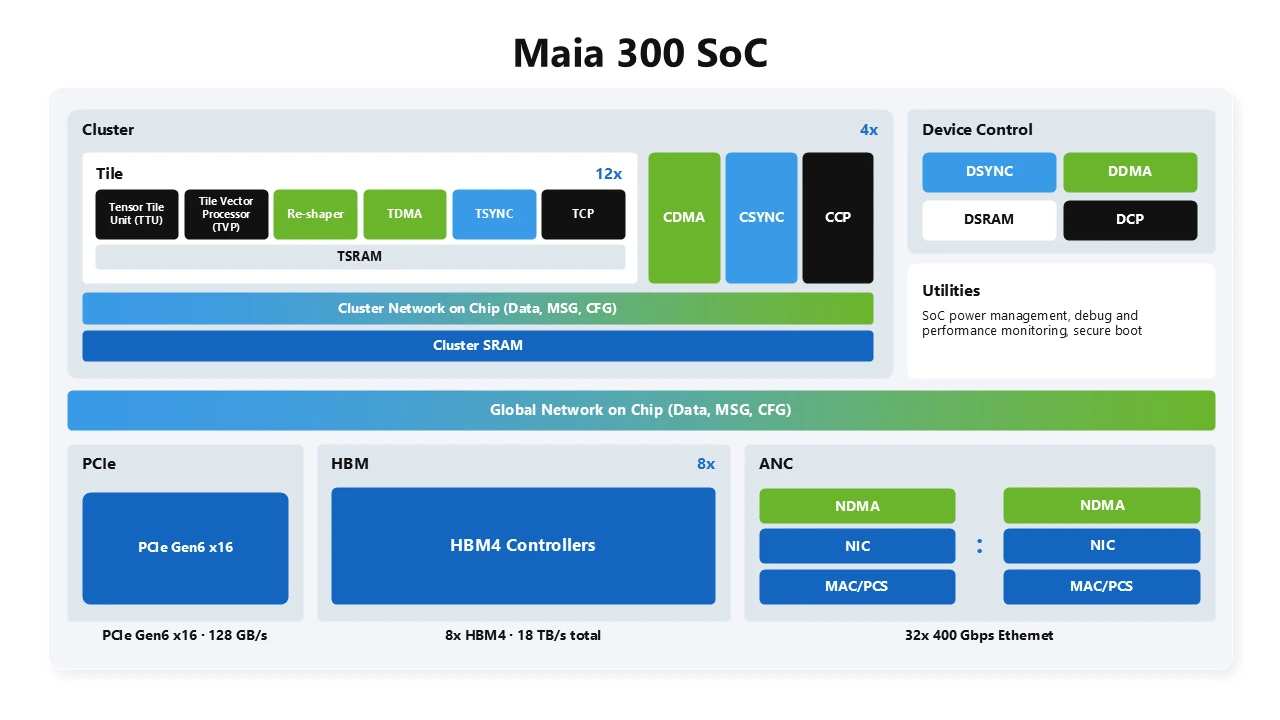
Maia 200 introduced a new class of accelerator architecture called Software Defined Locally Accessed Dataflow Architecture, or SDLA. It begins with the observation that efficient data management, including storing, moving and converting data, is one of the central challenges in modern AI systems. The Maia programmable dataflow architecture separates control path programming from data path execution and allows software to explicitly coordinate data placement, movement, conversion and synchronization across specialized local memories, DMA engines, compute engines, and the network.

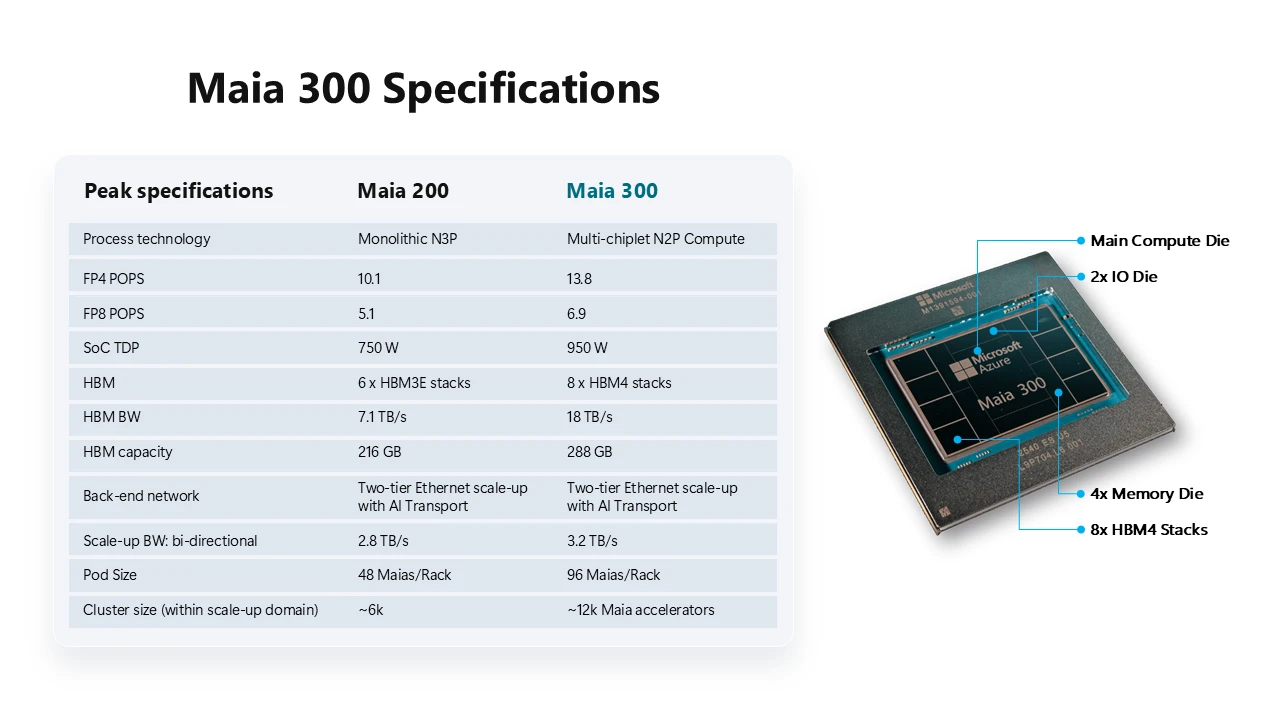
Maia 300 evolves this architecture for long-context, reasoning-intensive, and decode-heavy inference. First, memory moves from the uniform memory access (UMA) organization of the SoC to a locality-aware non-uniform (NUMA) organization across chiplets, so software can place data near the compute that uses it. Second, new narrow-precision formats with hardware-accelerated data type conversion reduce the bytes moved for each token. Third, the rack doubles to 96 accelerators and the scale-up domain grows to a superpod of 12,288 accelerators, enabling more accelerators to work effectively as a single system.

Rather than scaling performance through increased power and silicon area alone, Maia 300 improves performance per watt through a set of architectural innovations that optimize data movement, locality, precision, and memory efficiency across the system:

  • Multi-chiplet architecture boosts performance by placing compute on TSMC N2P, where the advanced process delivers the greatest performance-per-watt benefit, while separating memory-controller and I/O functions onto dies optimized for bandwidth, connectivity, and cost. This increases the silicon area dedicated to compute performance and allows each function to use the technology best suited to its role, while SDLA manages locality and data movement across the package. This strategy increases the system’s compute FLOPs by 36%, adds 2.5 times HBM bandwidth, and provides 14% more scale-up bandwidth.
  • Optimized low precision inference, introducing enhanced MXFP4 and sub-3-bit storage formats. Narrower representations reduce memory footprint and data movement, allowing the system to support larger models, longer contexts, and more concurrent sessions within the same power envelope.
  • Optimized inference kernel through ISA enhancement: The vector engine adds optimizations for key inference kernels, including softmax, low precision data casting, and other operations.
  • Efficient on-die data movement, Maia 300 changes memory from a uniform organization to a non-uniform (NUMA) one across chiplets. Each compute region has nearby memory, and SDLA’s explicit control over DMA engines, local SRAM, HBM and the network-on-chip places data next to the compute that uses it. Data travels shorter distances, which reduces the energy spent moving it.
  • Memory hierarchy optimized for bandwidth per watt, combining software-managed on-die SRAM with eight HBM4 stacks providing 288 GB of capacity and 18 TB/s of bandwidth per accelerator. Compared with Maia 200, this delivers 2.5 times the memory bandwidth, 33% more capacity, and approximately 2 times the HBM bandwidth per watt, keeping more model and KV state close to compute.

One scale-up fabric: From pod to superpod

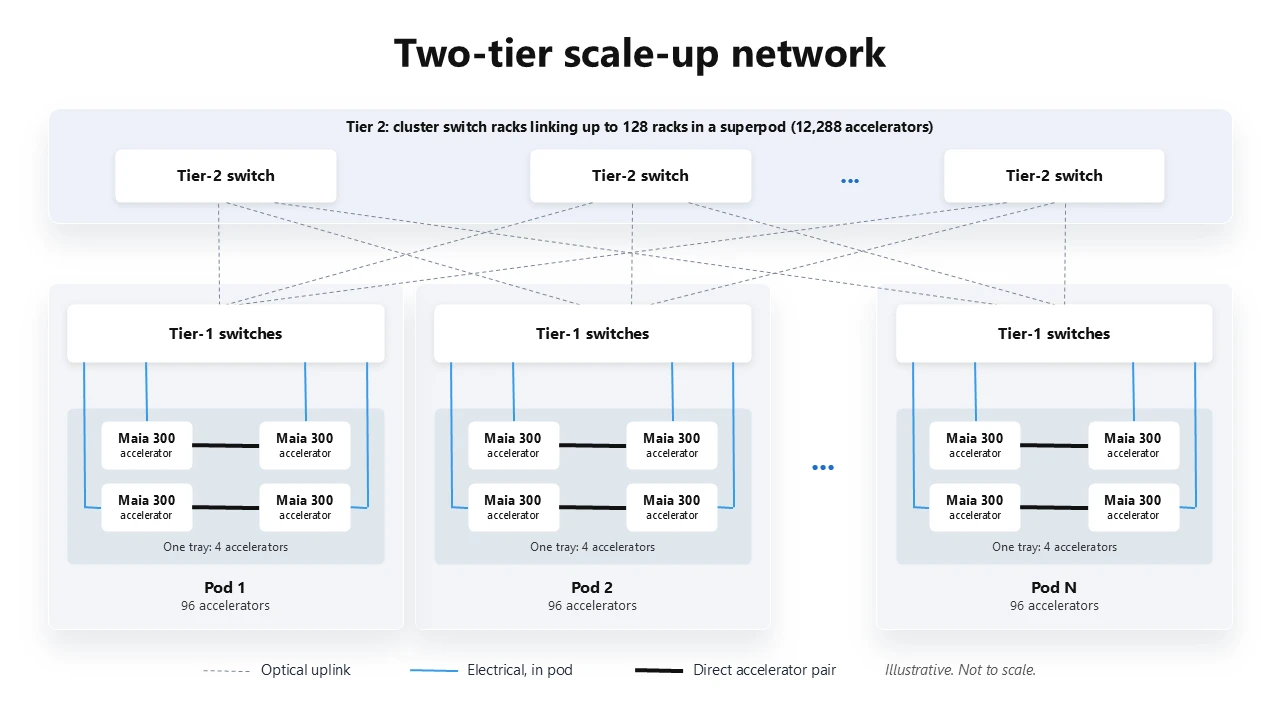
Maia 300 makes the network a native extension of its software-defined dataflow architecture. Maia’s AI network controller implements custom AI transport based on Ethernet. A two-tier network builds a high-performance superpod with up to 12,288 accelerators. Maia presents one communication model to software—the same semantics to move data directly to any accelerator within a superpod.

  • Half-switched in-rack topology
    Each accelerator divides its scale-up connectivity between direct links and switched paths. Direct links connect two accelerators in a tray, while the switched fabric connects all 96 accelerators in the rack to form a pod. All in-rack connectivity uses electrical links to reduce power and cost.
  • Optical second tier across racks
    Second-tier switches connect up to 128 racks together to form a superpod. Optics provide the reach required to extend scale-up network across the pods.
  • One fabric rather than separate scale-up and scale-out domains
    Integrated network controllers and specialized AI transport use the same communication semantics inside the pod and across the superpod. Maia accelerators can directly initiate communication to any accelerator in the superpod, without involving the host or a discrete scale-out NIC.
  • Low-hop communication paths
    There are three latency domains: A direct connected accelerator pair is the lowest latency domain, then accelerators within a pod are one switch hop away, and any accelerator across pods is three switch hops away. Software can keep latency-sensitive tensor-parallel traffic local within the lowest latency domains.
  • Bandwidth allocated to the workload
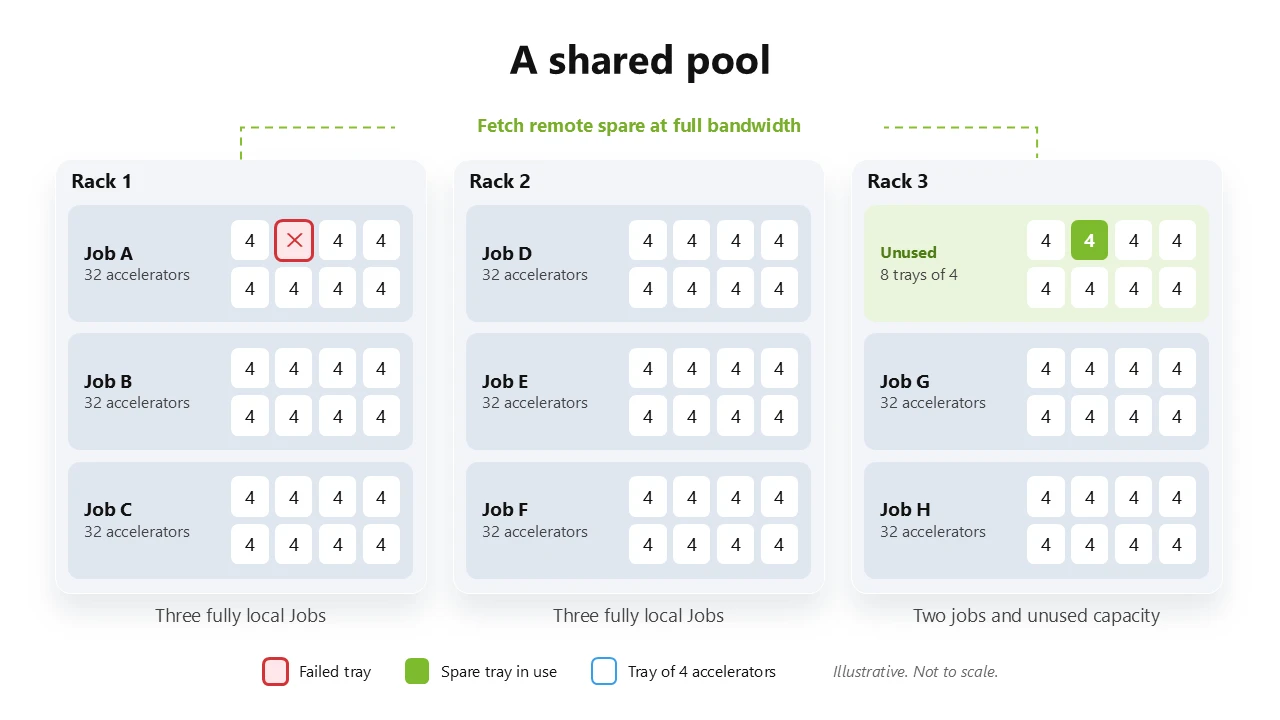
    The bandwidth split between in-rack and cross-rack bandwidth per accelerator is not fixed at the system design time. It becomes a parameter that is set based on job packing. An accelerator can drive up to 750 GB/s to any peer within the superpod, when only a subset of accelerators are going cross-rack. Refer to the spare tray example below.
  • Flexible job placement
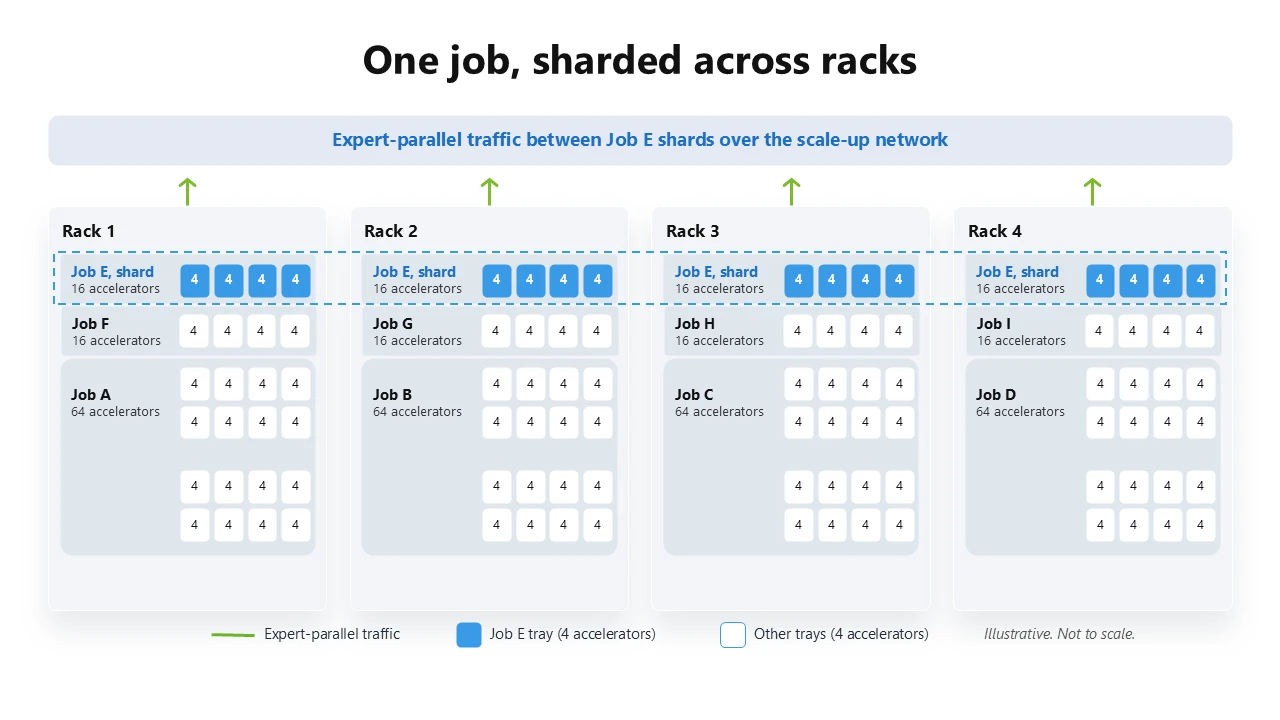
    Tensor parallelism can remain within the 96-accelerator rack, while wider expert and pipeline parallelism span racks. Jobs can use capacity across rack boundaries, reducing stranded accelerators when workload sizes do not align with the physical rack configuration.
  • Disaggregated inference within the scale-up domain
    Prefill and decode workers can be sized and placed independently. After prefill computation completes, KV state moves directly to the selected decode workers over the same scale-up fabric rather than leaving the domain through a separate host-mediated scale-out path.
  • Resilience across racks
    When accelerators become unavailable, schedulers can use hot-spare capacity in another rack within the superpod transparently to software kernels. The workload remains on the scale-up fabric, trading additional path latency for improved availability and resource utilization.

Rack-scale architecture for deployment efficiency

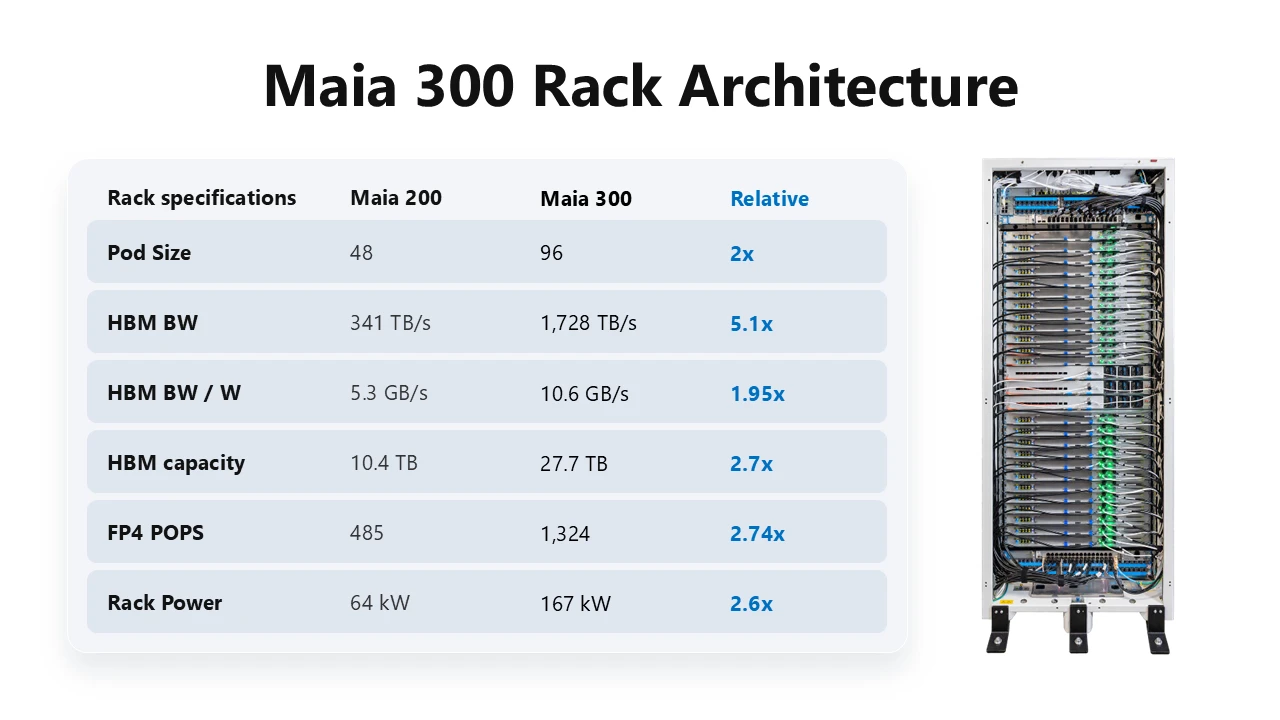
At datacenter scale, efficiency is determined by how much useful infrastructure can be deployed and operated within a fixed power and cooling envelope. Building on the foundational energy efficiency of the Maia SoC architecture, the Maia 300 rack co-designs server layout and density, network topology and switching, power and cooling design, and advanced telemetry to deliver up to 2.5x more performance per watt compared to Maia 200.

  • 96 accelerators within 167 kW
    Maia 300 integrates 96 accelerators across 24 four-accelerator trays within a 167-kW rack, doubling the accelerator density of Maia 200. Each tray incorporates four accelerators with its host processor, memory, storage, and cooling. Eliminating separate host trays frees rack space and allows power and thermal resources to be managed as one system, increasing the inference capacity deployed within each rack.
  • Consolidated switch architecture
    Six high-radix switch ASICs are integrated into three liquid-cooled switch trays, providing the rack-local connectivity required by all 96 accelerators while minimizing the space and power consumed by switching.
  • Rack-level power delivery
    Dual power feeds, high-capacity power shelves, and a 50 V busbar architecture distribute power efficiently across accelerator and switch trays while providing operational redundancy. The integrated rack automatic transfer switch maintains high availability even when a single power feed is offline for servicing.
  • Flexible cooling architecture
    Liquid cooling removes more than 80% of the rack’s thermal load from accelerators, voltage regulators, and switch ASICs, while air cooling supports memory, storage, and other ancillary components. Maia 300 can connect directly to facility water where it is available or use a heat-exchanger unit to reject heat in air-cooled datacenter environments. This provides greater flexibility in where and how the system can be deployed at scale.
  • Datacenter-integrated telemetry
    We have incorporated deployment learnings to strengthen reliability, availability, and serviceability (RAS), observability, debuggability, fault handling, and redundancy, improving robustness as we deploy additional volume. Rack and row level power telemetry connect with datacenter operations, enabling operating points to be managed against available power and cooling capacity. This data informs algorithms that dynamically allocate power and optimize workload placement and deployment density, improving utilization and tokens delivered per watt.

What Maia 300 delivers

Maia 300 is the next step in a multigenerational program to deploy efficient AI systems at scale. The design is optimized end to end across software, silicon, physical rack infrastructure, networking, and datacenters to deliver a leap in performance and efficiency for cloud-scale agentic inference.

Relative to Maia 200, Maia 300 delivers up to 7 times greater rack-scale token throughput in its full 96-accelerator configuration and more than 2.5 times the performance per watt. It brings more memory bandwidth per watt and twice the accelerators per rack, while building on SDLA, our software-defined dataflow architecture and a two-tier scale-up network to support a single programming model spanning kernel to data center scale. Together, these advances enable us to deliver more useful intelligence, more efficiently, to more people and organizations.

The opportunity ahead is not simply to build more compute. It is to make advanced AI capabilities more accessible, affordable, and useful. Maia 300 is an important step toward that goal.

Next month at Microsoft Ignite 2026 in San Francisco and online, we’re looking forward to sharing more information on our AI strategy, technology adoption trends, and success in Frontier Transformation.


Read about the latest Azure Maia 300’s news here.

Learn more about Azure Maia 300 here.

Learn more about Azure’s silicon to systems approach here.

The post Deep dive into Azure Maia 300 architecture appeared first on Microsoft Azure Blog.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Why does 'Here comes he' sound so wrong?

1 Share

1228. This week, we look at why "Here comes the bride" sounds right but "Here comes he" sounds wrong. Then we have an update on Zipf's law: after whales and dolphins, researchers may have found it in birdsong too.


The "here comes he" segment was written by Ray Belli, a longtime podcaster, musician, and language writer. You can find him at WordsforGranted.libsyn.com


A hearty thank-you to our Keepers of the Commas on Patreon. We appreciate your support!

  • Larry Rosenblum
  • Mahala Russell
  • George Wilson
  • Laurel Paul
  • Linda Cox
  • Birna Anna Björnsdóttir
  • Kate Wade


🔗 Share your familect recording in Speakpipe or by leaving a voicemail at 833-214-GIRL (833-214-4475)

🔗 Watch my LinkedIn Learning writing courses.

🔗 Subscribe to the newsletter.

🔗 Find an edited transcript.

🔗 Get Grammar Girl books.

| HOST: Mignon Fogarty

| Grammar Girl is part of the Quick and Dirty Tips podcast network.

  • Audio Engineer: Castria Communications
  • Director of Podcast: Holly Hutchings
  • Advertising Operations Specialist: Morgan Christianson
  • Marketing and Video: Nat Hoopes, Rebekah Sebastian
  • Podcast Associate: Maram Elnagheeb

| Theme music by Catherine Rannus.

| Grammar Girl Social Media: YouTube. TikTok. Facebook. Threads. Instagram. LinkedIn. Mastodon. Bluesky.


Hosted on Acast. See acast.com/privacy for more information.


Download audio: https://sphinx.acast.com/p/open/s/69c1476c007cdcf83fc0964b/e/6ac5a5c48f340788893b86e6/media.mp3
Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Bot Traffic as a Capacity and Cost Problem with Netacea CTO Andy Still

1 Share

Andy Still has spent nearly 30 years keeping high-traffic websites standing, starting in rock and pop ticketing before there was a cloud to scale into. Today he is CTO and Co-Founder of Netacea, a bot and agent trust platform. In this episode of the Smooth Scaling Podcast, Andy walks host Jose Quaresma through what automated traffic actually costs, from autoscaling bills and stolen loyalty points to skewed analytics that steer a business toward the wrong decisions. His starting point: bots are still a performance and availability problem as much as a security one. He gets into how cheap it has become to launch a bot attack (commercial tools with support agreements, up and running in about an hour) and why detection is now an AI-on-AI arms race, before the harder question of telling a real fan's AI agent from a scalper bot when the requests look alike. Then the data from one early-access event, where the share of visitors flagged as malicious rose from 17% entering Queue-it's waiting room to 59% leaving it, and what that says about time as a detection signal. A practical, technical look at what bot traffic costs and how you actually tell it apart.

Episode page

---

  • (00:00) - Intro
  • (00:50) - From rock and pop ticketing to fighting bots
  • (04:50) - Where bots show up on the bill
  • (07:59) - Capacity planning becomes a cost conversation
  • (09:41) - Bots in the analytics, and the KPI that was never real
  • (12:10) - A bot attack, up and running in an hour
  • (15:40) - An AI-on-AI arms race
  • (18:48) - Telling a fan's AI agent from a scalper bot
  • (22:14) - Why Netacea chose server-side detection
  • (27:00) - Agent identity protocols: helpful, but voluntary
  • (30:07) - Where to draw the line on false positives
  • (33:50) - The longer they wait, the more you see
  • (37:54) - Blocking isn't always the right move
  • (40:41) - Time as a signal, and a holding pen for suspects
  • (44:15) - Rapid fire: the agentic web, and "scalability is..."

Andy Still is CTO and Co-Founder of Netacea, a leading bot and agent trust platform giving enterprises complete control over their web traffic. Andy has nearly 30 years of experience working with the world's largest retailers and ticketing providers to operate the most demanding events online. Beyond his focus on how automated traffic, including AI agents, interacts with digital services, he's also the author of Web Performance Warrior (O'Reilly) and previously ran the Web Performance Group North UK.

Andy Still: https://www.linkedin.com/in/andystillintechnica/
Host José Quaresma: https://www.linkedin.com/in/jose-quaresma/

This podcast is produced and researched by Perseu Mandillo, and brought to you by Queue-it, your virtual waiting room partner.

© Queue-it, 2026


Download audio: https://media.transistor.fm/73ad06a9/3792b484.mp3
Read the whole story
alvinashcraft
43 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories