Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
163847 stories
·
33 followers

Couchbase Server 8.5 Private Preview: Easier to Run, Smarter to Query

1 Share

Easier to run means you recover from mistakes to the second, scale without waiting for a maintenance window, encrypt everything without bolting on extra tools, and replicate across clouds without a firewall ticket per node. Smarter to query means AI apps get better answers from the data you already have, your data lake joins the conversation without an ETL pipeline, and developers can ask follow-up questions in plain English.

Couchbase Server 8.5 makes two promises: It’s easier to run at enterprise scale, and it’s smarter to query. The release is in private preview now (register here) for teams running Couchbase Server Enterprise Edition, and general availability (GA) is expected in January 2027.

Here’s what that looks like in practice, and what problem each piece solves.

How does Couchbase Server 8.5 make enterprise operations easier?

You picked Couchbase Server because your apps need to stay fast at peak traffic and stay up when a node fails. That part isn’t changing. What has changed is everything around it. AI agents write to your database now. Datasets keep growing. Your security team wants every byte encrypted, and your network team wants fewer open ports, not more.

Server 8.5 handles four jobs that keep your ops team in cleanup mode, so they can get back to the work they planned.

Recover to the second before a mistake

Picture a normal Tuesday. Your last full backup ran at midnight. At 2:03 p.m., someone runs a delete with a missing filter. Maybe it’s a tired engineer. Maybe it’s an AI agent, which is fast, tireless and occasionally very confident about the wrong WHERE clause.

Today, your best option is last night’s backup. That means losing 14 hours of orders, bookings or claims, rebuilding them by hand and then having a long talk with your auditors. Nobody enjoys that talk.

8.5 helps on two fronts:

  • Point-in-time recovery (PITR) restores data to a specific second. Continuous backup ships every change to backup storage as often as every two minutes. When something goes wrong, you pick the second before the mistake and restore. You can scope the restore to a single collection, so one bad delete doesn’t roll back the whole bucket.
  • Immutable backups go to object storage that’s locked for a retention period, on AWS, Azure or Google Cloud. Nobody can change or delete them until that period ends, including an attacker with stolen admin credentials. This builds on features like Amazon S3 Object Lock, often called WORM (write once, read many) storage. PITR runs on buckets that use the Magma storage engine.

The result: you lose seconds of data, not hours, and ransomware can’t quietly edit your safety net. With less to lose and less to rebuild, your next incident review gets a lot shorter.

Add capacity without a maintenance window

Couchbase Server already lets you add nodes while your app stays online. The data still has to move to the new nodes, though. That process is called a rebalance, and until now it moved data one document at a time. On a big cluster, that’s slow enough that many teams schedule it for nights and weekends. Or they add capacity weeks before a peak and pay for it the whole time.

That’s real money spent on idle hardware. It also turns a simple scaling job into a project with a change ticket and, in many shops, a pizza order for the late night ahead.

8.5 helps on three fronts:

  • File-based rebalance copies whole data files between nodes instead of single documents. In our testing, it ran 4x faster on average. Your results will depend on your data and hardware.
  • 30 TB per node triples the previous limit, so very large datasets fit on fewer servers.
  • Powered by 8.5, Capella Express Scaling goes further for Capella on AWS. New nodes load their data in parallel from cloud object storage instead of copying it from busy nodes. In internal testing, it scaled 10 TB per node in under 30 minutes. It’s in its own private preview, so ask your account team.

The result: you add capacity the day you need it, fit more workloads on each cluster and stop buying hardware for traffic that hasn’t shown up yet.
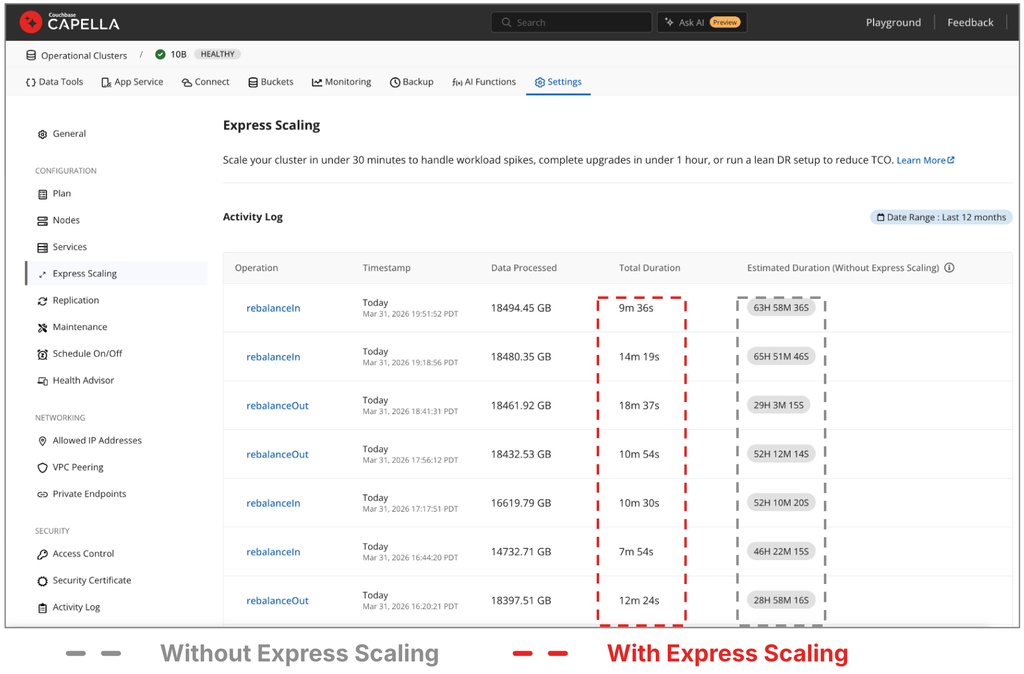
Scale in minutes, not days. Capella Express Scaling adds capacity in under 30 minutes, so you can size for today’s traffic and grow fast when a spike hits. Now in private preview for Capella on AWS.

Close security gaps without bolting on more tools

Encryption at rest usually means another layer to buy and manage, like a disk tool or a third-party product. Those layers leave gaps. Logs and config files are exactly where auditors find unencrypted data. And auditors love a good gap.

8.5 closes those gaps inside the database:

  • Native encryption at rest now covers everything Couchbase writes to disk: data, indexes, search, logs, audit files and config. Keys stay in the key management system you already use and rotate on schedule with no downtime. In our testing, the throughput cost averaged in the single digits.
  • JWT and single sign-on replace stored passwords for users and services.
  • A built-in credential store holds the keys for cloud storage and AI model providers, so secrets don’t end up in config files.

The result: fewer audit findings, fewer tools to manage and one less conversation about “we thought that was covered.”

Replicate with fewer firewall rules and a smaller transfer bill

Cross data center replication (XDCR) keeps clusters in sync across regions and clouds, in both directions. It works well. Traditionally, though, the source cluster needs to reach every node on the target cluster directly. On Kubernetes, behind a cloud provider private link, or at an edge site, that means a pile of per-node ports that network teams don’t love.

There’s a cost side too. In a full global mesh, where every cluster replicates to every other cluster, the same change can travel more than once. Every extra trip shows up on the cloud bill as data transfer.

8.5 makes replication friendlier to your network and your budget:

  • XDCR over Cloud Native Gateway. Replication can now run through Cloud Native Gateway over HTTPS ports using gRPC. The target cluster exposes one endpoint instead of every node, so your network team approves one door, once.
  • Send local changes only. In a full mesh, each cluster forwards only the changes that started there, one time. Less duplicate traffic means a smaller data transfer bill.
  • Staged credentials. Add a second set of credentials to an XDCR connection ahead of time. When the old ones stop working, XDCR switches over on its own, so credential rotation doesn’t break replication.

With these updates, replication fits standard cloud networking, costs less to run, and survives your next password rotation.

On Kubernetes or behind a cloud provider private link, opening a firewall port for XDCR between every pair of database nodes is tricky. In 8.5, the Couchbase Cloud Native Gateway replaces that with one endpoint, which makes compliance reviews and change management easier.

How does Couchbase Server 8.5 make querying smarter?

The second theme is about getting better answers with less plumbing. Most teams already have the data they need. It’s just spread across a database, a vector store and a data lake, with sync jobs holding it all together. Server 8.5 brings more of that work into one SQL query, with new ways to use Couchbase’s SQL++. SQL++ is SQL for JSON. Anyone who writes SQL can use it.

Find the exact match and the right meaning in one query

Most AI projects start by adding a standalone vector database next to the operational one. Then come the sync jobs. Then come the support tickets when the AI answers from yesterday’s data.

There’s a second problem too: Vector search knows what you mean, but it doesn’t always know what you typed. It can miss exact matches like a SKU, an error code or part number 4471B. Keyword search has the opposite problem. Your users will notice both.

Server 8.5 helps address both problems:

  • Hybrid search in SQL++ combines keyword and vector results in one query. It can also mix sparse vectors (keyword-style) and dense vectors (meaning-style). Then it fuses the scores into one ranked list using methods like reciprocal rank fusion (RRF), which merges the rankings from different searches.
  • Binary quantization stores vectors in a compact form. In Hyperscale and Composite vector indexes, it cut index memory by about 75% compared with 8-bit quantization in our testing. Memory is usually the priciest line on a database bill, so this is where AI pilots stop being too expensive to scale.

The result: AI answers that hold up, one less database to secure and patch, and a smaller memory bill.

You can check whether you have this problem today, no preview needed. Search your current system for an exact part number or error code. If the top result only sounds similar, you’ve found the gap hybrid search closes.

Query your data lake without copying it

Here’s a common setup: Your live app data sits in Couchbase, but its aggregated history sits in a data lake. Somebody built an ETL pipeline to copy one into the other, so an app can show a customer’s lifetime value next to today’s order. ETL pipelines are the most expensive way ever invented to make data stale. Every pipeline is code to maintain, a second copy to pay for, and data that’s already out of date when it lands.

Server 8.5 lets the lake stay in the lake:

  • External collections for Apache Iceberg. Point Couchbase Server at Apache Iceberg tables in Amazon S3, Google Cloud Storage or Azure, and query them like any other collection.
  • One SQL++ query across both. Join live operational data with historical data in the same query. Nothing moves, and nothing gets copied.

This is built for joining live data with history inside an app or an AI workflow. It isn’t meant for heavy analytics, which is what Couchbase Operational Insights is for.

It all means fewer pipelines to babysit, no duplicate copies to pay for and answers that combine “right now” with your data’s recorded history.

Ask follow-up questions in plain English

Since Couchbase Server 8.0, USING AI has turned plain-English questions into SQL++ queries. It works from the SDKs, the REST API and the command line. In 8.0, though, every question stood alone, like talking to someone with no short-term memory.

Server 8.5 makes it a conversation. Ask how many hotels are in Half Moon Bay, then say “show me its details,” and it knows which hotel you mean. Pause the chat, go to lunch, update some data with regular SQL++, and resume later with the context intact. You can also teach it your business terms, like what “net revenue” means at your company.

One important detail: USING AI only runs SELECT queries on its own. If a question turns into an insert, update or delete, it hands the query back as text and doesn’t run it.

The goal of conversational support is for developers to spend less time writing throwaway queries, and for the people waiting on answers to get them sooner.

What’s next for Couchbase Server 8.5?

Running a database at enterprise scale shouldn’t mean losing a day of data to one bad delete, waiting for a weekend to add capacity, or opening a firewall port for every node. Getting good answers shouldn’t take a second database and three pipelines. Couchbase Server 8.5 is our answer to both. It’s easier to run and smarter to query, on the same engine you already trust.

If you attended our Catalyst user conference, then you got an early look at 8.5 in person, including demos of point-in-time recovery and the Cloud Native Gateway. (Videos from the event will be coming soon to our YouTube channel!) GA is expected in January 2027. If you’d like to try it sooner on your own workload, request a spot in the private preview.

The post Couchbase Server 8.5 Private Preview: Easier to Run, Smarter to Query appeared first on The Couchbase Blog.

Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

MongoDB BSON Mapping in C#: Typed Models and Immutable Records

1 Share

Understand MongoDB BSON mapping in C# with explicit field names, immutable record creation, ID representations, and compatibility checks for stored documents.


Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

[PREVIEW] Raytracing: Clustered Geometry, Partitioned TLAS, Indirect Acceleration Structure Builds

1 Share

Today we’re introducing a preview of DirectX Raytracing (DXR) Clustered Geometry and Partitioned Top-Level Acceleration Structures (PTLAS), with a unified GPU-driven API for building and updating them.

This is part of a larger AgilitySDK release described in the parent post: https://devblogs.microsoft.com/directx/agilitysdk-1-620-retail-and-1-722-preview/

For DXR this is the most significant update since its debut in 2018.

Mar 2018 DXR debut
Nov 2019 Tier 1.1: inline raytracing and GPU-driven ray dispatch
Apr 2021 Shader Model 6.6: payload access qualifiers
Feb 2026 SM 6.9 / Tier 1.2: Shader Execution Reordering (SER) and Opacity Micromaps
Oct 2026

this preview

Clustered Geometry and Partitioned TLAS: GPU-driven efficient scene updates

Here’s the motivation for Clustered Geometry and Partitioned TLAS:

At object level scope within a scene, animation, streaming, and generated geometry can repeatedly incur the cost of building large bottom-level acceleration structures (BLAS). Clustered Geometry breaks the unit of building down into small reusable clusters of triangles. One benefit of more efficient builds is it can become practical to raytrace the same full-detail geometry used for rasterization, rather than simplified proxies, so ray-traced shadows and reflections match the visible scene.

At scene wide scope, updating a top-level acceleration structure (TLAS) can be costly for large worlds even if only a few instances changed. Partitioned TLAS focuses update costs on changed scene regions while retaining acceleration-structure data elsewhere.

Applications can use Clustered Geometry and PTLAS separately or together.

These features don’t require new hardware capabilities beyond existing raytracing support. Even in normal times this would be a wonderful thing.

The breadth of support will depend on hardware vendors implementing and validating drivers for each of their hardware generations. Support for some older raytracing GPUs is to be determined: implementation work may uncover performance issues, so exposing the features may be impractical for that or other reasons. For now, see Availability and prerequisites for currently supported hardware and drivers from AMD, Intel and NVIDIA (Qualcomm in 2027).

Gears of War: E-Day is an early example of a title adopting clustered geometry through NVIDIA’s vendor-specific API, RTX Mega Geometry. Standardizing these capabilities in DirectX provides a common integration path across supporting hardware, making them accessible to a broader range of future titles.

Since this is a preview, your feedback (Discord) can help refine the design before final release, or give us confidence to go to retail as soon as possible. There are various samples as well as PIX support to go with these features, detailed later in this blog.

NVIDIA has a great post with additional samples and resources here: https://github.com/NVIDIA-RTX/Whitepapers/blob/main/dx_clusters_and_ptlas/README.md

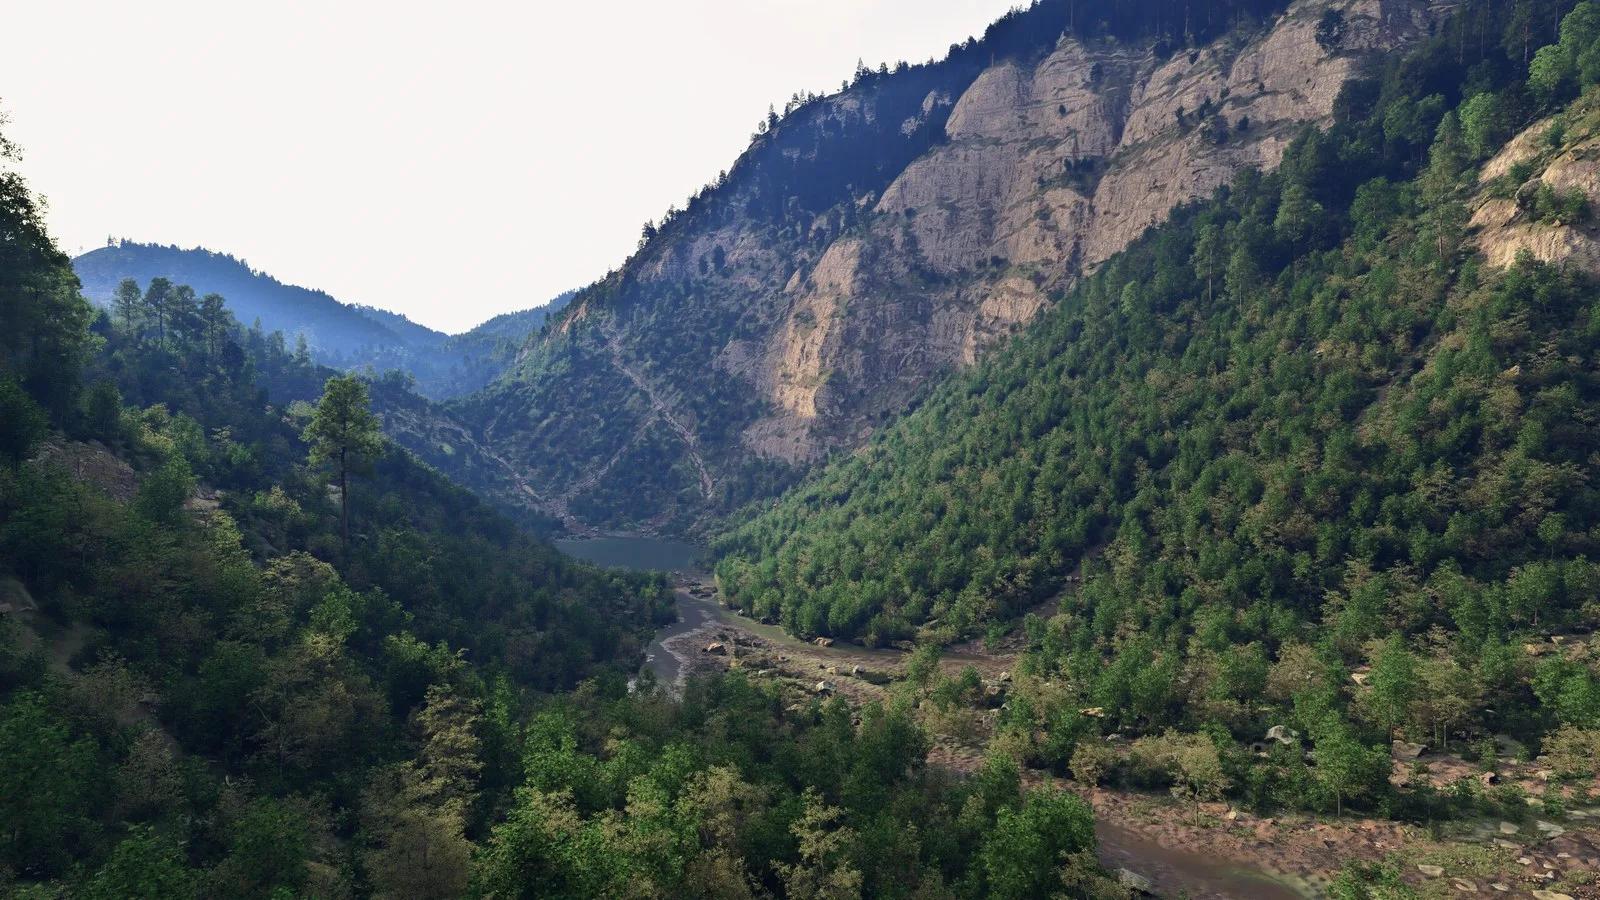
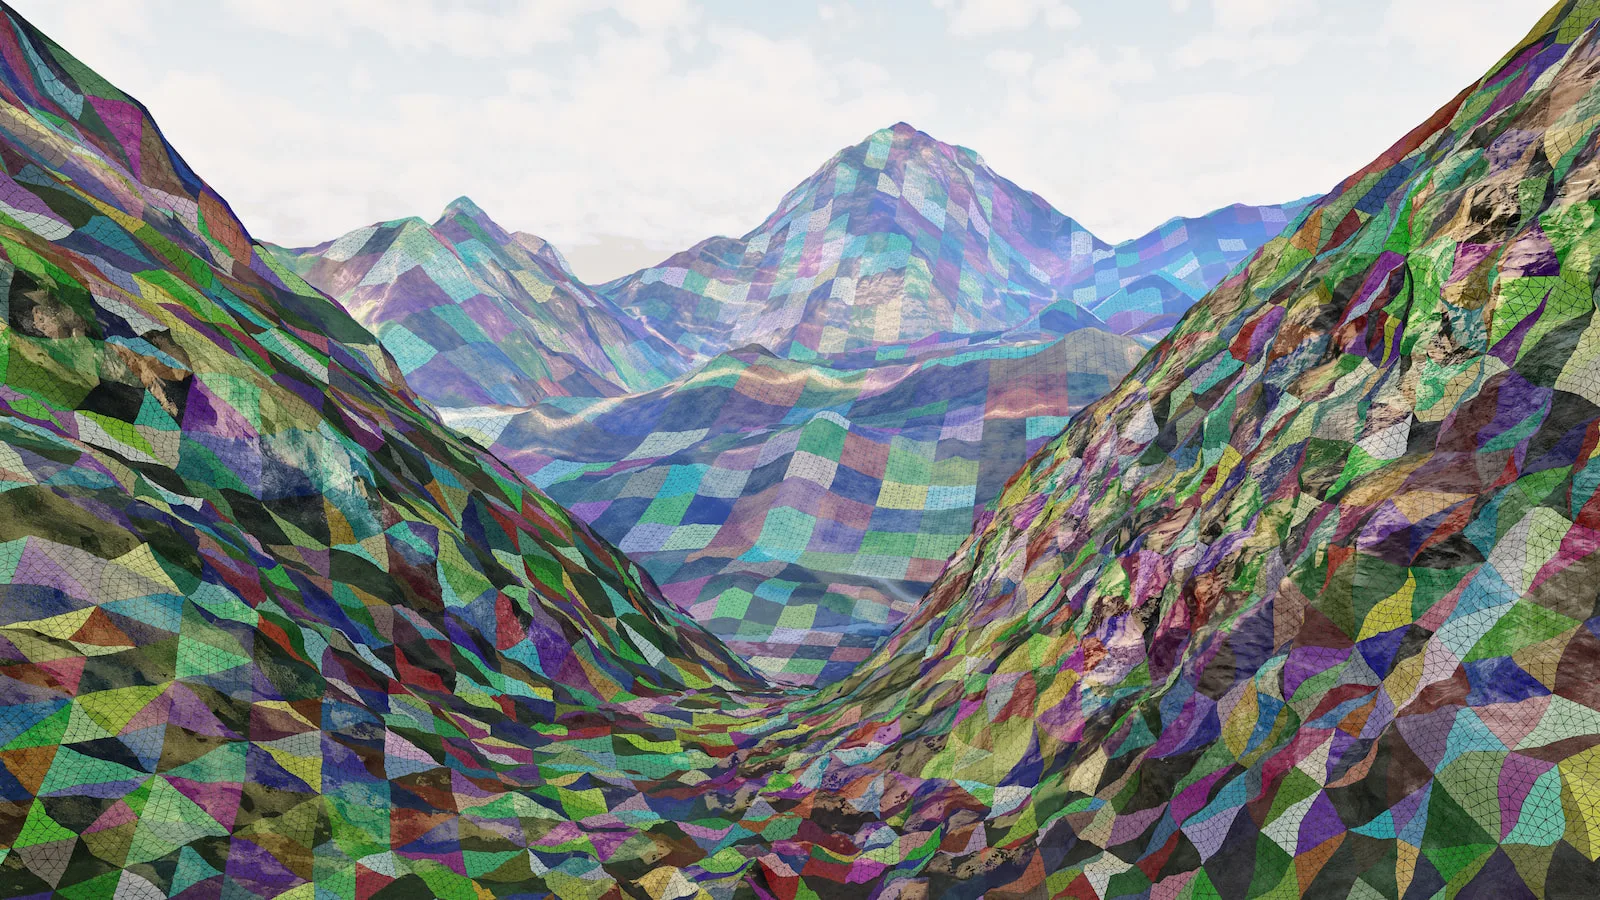
The scenes below are from that post, describing their dx12_forest_ray_tracing demo which uses all of the new features to impressive effect.  This new D3D12 version is a work in progress, available soon. The sample uses cluster templates to optimize builds of its dynamic terrain. In the background, cluster templates form square patches, which are then doubled in resolution towards the midground and then recursively subdivided into triangular patches in the foreground. This achieves a nearly uniform screen-space triangle density.

An aerial shot of a beautiful forest. This is a fully path traced scene from the dx12_forest_ray_tracing sample, featuring over 60 million plants over 25 square kilometers, rendered in real time using D3D12 Clusters and Partitioned TLAS.

In the middle of a valley in the dx12_forest_ray_tracing sample, we view a far-away mountain range. A debug visualization shows the terrain’s clusters in different colors, and individual triangles are outlined using a wireframe display.


Spec and API Overview

The following is a brief walkthrough of how code drives the new features.

See the spec for full detail: Clustered Geometry and Partitioned TLAS specification.


GPU-driven Acceleration Structure Builds

The raytracing acceleration-structure (RTAS) operation API has two entry points. GetRTASOperationPrebuildInfo() queries conservative result and scratch requirements. ExecuteIndirectRTASOperations() executes batches whose argument arrays, and where supported their counts, reside in GPU memory.

The CPU describes each operation and its workload bounds; compute shaders can generate the arguments. Cluster operations also support size-only queries and copy/move operations.

Operations submitted in one ExecuteIndirectRTASOperations() call may execute in any order and must not depend on each other. Dependent stages need separate calls with barriers between them — for example, cluster builds → Cluster BLAS builds → PTLAS builds when an application combines Clustered Geometry and PTLAS.


Clustered Geometry

Clusters as raytracing building blocks

A Cluster Level Acceleration Structure (CLAS) contains an indexed mesh of up to 256 triangles and 256 vertices. An application builds a Cluster BLAS from a list of CLAS references, then creates instances of that BLAS in a non-partitioned TLAS or a Partitioned TLAS.

The point is to reduce aggregate acceleration structure build costs across smaller chunks.

Multiple Cluster BLAS can share a CLAS; TLAS instances reference BLAS, not individual CLAS.

The vertex positions in all CLAS used by a Cluster BLAS are expressed in that Cluster BLAS’s object space. There is no per-CLAS transform during assembly.

For streaming and level of detail (LOD), applications can assemble different sets of existing CLAS rather than rebuild from triangles. Meshlet-based geometry pipelines may already provide suitable triangle groupings.

The application assigns each CLAS a 32-bit ClusterID, retrieved in hit shaders with ClusterID(). PrimitiveIndex() is local to the hit CLAS; use the pair to look up that triangle’s normals, materials, or other application data.

Shader Model 6.10 also requires support for TriangleObjectPositions() and its RayQuery counterparts, CandidateTriangleObjectPositions() and CommittedTriangleObjectPositions(). When data access is enabled at build time, these intrinsics retrieve a triangle’s object-space vertex positions from the acceleration structure. This is useful with clustered geometry, for example to compute geometric normals without fetching positions from a separate vertex buffer.

Changing a referenced CLAS’s contents or address invalidates the Cluster BLAS, so it would need a rebuild along with dependent top-level structures.

Vertex position formats

Cluster builds support a range of vertex formats, including floating-point and normalized integer positions. For these formats, applications can also request truncation of low mantissa bits after conversion to float32, providing another way to quantize positions.

COMPRESSED1 is a fixed-point position encoding that uses a shared anchor and power-of-two scale for each cluster. Vertices store packed integer offsets from that anchor instead of three full floating-point values, with precision and range chosen for the content.

Position encodings and precision controls in the specification

Building CLAS from triangles

The BUILD_CLAS_FROM_TRIANGLES operation builds one CLAS for each argument in a GPU array. Each argument references a cluster’s vertices and triangle indices.

This example lets the implementation place the CLAS within a single application-allocated result buffer. This is implicit-destination mode: the build writes an array of GPU addresses identifying where each CLAS was placed. In explicit-destination mode, the application supplies the individual result addresses instead.

With formats and workload limits already filled in clusterInputs, select implicit destinations and query the batch’s result and scratch requirements:

clusterInputs.Mode = D3D12_RTAS_OPERATION_MODE_IMPLICIT_DESTINATIONS;

D3D12_RTAS_OPERATION_INPUTS inputs = {};
inputs.Type = D3D12_RTAS_OPERATION_TYPE_BUILD_CLAS_FROM_TRIANGLES;
inputs.pClusterTrianglesDesc = &clusterInputs;

D3D12_RTAS_OPERATION_PREBUILD_INFO sizes = {};
rtasDevice->GetRTASOperationPrebuildInfo(&inputs, &sizes);

Allocate clasResults and clasScratch using the returned sizes, plus an output address array with one entry per cluster:

D3D12_RTAS_BATCHED_OPERATION_DATA batch = {};
batch.BatchResultData = clasResults->GetGPUVirtualAddress();
batch.BatchScratchData = clasScratch->GetGPUVirtualAddress();
batch.ResultAddressArray = {
    clasAddresses->GetGPUVirtualAddress(),
    sizeof(D3D12_GPU_VIRTUAL_ADDRESS)
};
batch.IndirectArgumentArray = { argsGpuAddress, argsStride };

D3D12_RTAS_OPERATION_DESC build = {};
build.Inputs = inputs;
build.pBatchedOperationData = &batch;

rtasCommandList->ExecuteIndirectRTASOperations(
    1, &build, D3D12_EXECUTE_INDIRECT_RTAS_OPERATIONS_FLAG_NONE);

After the build and a barrier, the address array can feed a BUILD_BLAS_FROM_CLAS operation to assemble the Cluster BLAS.

The sizing query must cover the entire implicit-destination batch; adding separate query results does not guarantee sufficient space.

Cluster templates for animation and generated geometry

Clustered geometry does not support refits, intentionally. For deforming meshes, cluster templates fill that role by precomputing position-independent build work. A template stores topology and other non-positional properties, but not final vertex positions. Instantiating it with positions produces a CLAS; the template itself cannot be traced.

For an animated mesh, a typical sequence is:

  1. Build templates for the mesh’s clusters, optionally supplying example vertex positions as build hints.
  2. Generate the current vertex positions with a compute shader.
  3. Instantiate templates into CLAS using those positions.
  4. Build a Cluster BLAS from the CLAS and update its top-level instances.

The template’s VertexInstantiationFormat specifies the precision and range contract adhered to by stored positions, without dictating their physical storage layout. Positions supplied at instantiation use a separately selected VertexSourceFormat. When the formats differ, instantiation converts the input to the template’s format contract.

Templates also suit recurring topology in generated surfaces. Selecting different templates or CLAS permits topology and LOD changes without fixing the update topology of the entire object.


Partitioned TLAS

Partitioned TLAS is a functional superset of non-partitioned TLAS. It adds partitioned-based management and sparse updates, supporting existing BLAS types and Cluster BLAS.

The point is to allow the cost of TLAS build to be proportional to the amount that changed in a scene as opposed to the entire scene.

Applications assign persistent instance records to partitions. Grouping spatially coherent instances lets PTLAS build a structure for each group and combine those structures at the top level. A group that receives no changes can retain its built structure across frames.

Frequently moving instances can instead use a special global partition, separate from those spatial groups. For building and tracing, each instance in the global partition behaves as if it were in its own partition, avoiding repeated work in larger spatial groups. Once an instance stops changing frequently, the application can move it back to a spatially appropriate partition.

Overlapping partition bounds can hurt traversal. Global-partition membership trades partition rebuild work against the cost of handling instances individually; the best choice depends on layout and activity.

PTLAS operation types

  • WRITE_INSTANCE writes complete instance records, including transforms and partition assignments. Use it to populate a PTLAS, move instances, or reassign them to partitions. Affected partitions are rebuilt.
  • UPDATE_INSTANCE changes only the referenced BLAS address and hit-group-table contribution, for example when swapping LODs. It does not change the instance transform. If the instance has explicit bounds, the replacement must fit within them. Without explicit bounds, updates may expand the instance bounds and trigger a partition refit.
  • TRANSLATE_PARTITION sets a partition’s translation without rewriting each instance’s transform, supporting origin-relative large-world coordinates. Partition translation must be enabled; each value replaces the previous translation rather than accumulating.

Operation argument layouts and validity rules

Updating a Partitioned TLAS

Sparse transform changes require WRITE_INSTANCE, not UPDATE_INSTANCE. After populating the PTLAS, a compute pass generates writes for just the changed instances. Each write’s stable InstanceIndex identifies the persistent record, not its position in that frame’s write array. Unwritten records remain unchanged.

A WRITE_INSTANCE operation in the GPU operation buffer references that write array:

D3D12_RTAS_PARTITIONED_TLAS_OPERATION_DATA data = {};
data.SourceAccelerationStructureData = ptlas->GetGPUVirtualAddress();
data.DestAccelerationStructureData = ptlas->GetGPUVirtualAddress();
data.ScratchAccelerationStructureData = scratch->GetGPUVirtualAddress();
data.IndirectPartitionedTlasOpCount = operationCount->GetGPUVirtualAddress();
data.IndirectPartitionedTlasOps = operations->GetGPUVirtualAddress();

D3D12_RTAS_OPERATION_DESC update = {};
update.Inputs.Type = D3D12_RTAS_OPERATION_TYPE_PARTITIONED_TLAS;
update.Inputs.pPartitionedTLASInputsDesc = &ptlasInputs;
update.pPartitionedTlasOperationData = &data;

rtasCommandList->ExecuteIndirectRTASOperations(
    1, &update, D3D12_EXECUTE_INDIRECT_RTAS_OPERATIONS_FLAG_NONE);

Source and destination match for an in-place update; the initial build has no source. Allocation must cover declared instance and partition capacities, not just the current write count.

IndirectPartitionedTlasOpCount points to the operation count, whereas each WRITE_INSTANCE operation’s ArgCount counts instance writes. Here the operation count is one; compute varies ArgCount as instances change.


Availability and prerequisites

Use matching Agility SDK preview headers and runtime, a supporting driver, and Windows Developer Mode for experimental feature enablement.

Agility SDK:

DirectX Shader Compiler:

Drivers and hardware:

NVIDIA NVIDIA and Microsoft have been collaborating closely to bring Clusters and Partitioned Top Level Acceleration Structures to DirectX Raytracing. These features enable unprecedented levels of animated geometric detail and unlock new algorithms including path tracing of hierarchical LOD streaming solutions found in modern game engines. We are excited to fully support this update to DXR on all RTX GPUs.

– Martin Stich, Senior Director of Engineering

Drivers: Download the official NVIDIA drivers or use the NVIDIA App for automatic driver updates.

Supported hardware: All RTX GPUs

AMD Clustered Geometry and Partitioned TLAS are important advancements for the DirectX Raytracing ecosystem. The ability to reuse geometry work through clusters and update only the portions of a scene that have changed can significantly improve scalability for streaming content, level-of-detail transitions, animation, and large open-world experiences.

– Rodney Andre, Corp. VP Software Development, AMD

Drivers: https://www.amd.com/en/resources/support-articles/release-notes/RN-RAD-MS-AGILITY-SDK-26-20-12-01.html.

Supported hardware: AMD Radeon™ RX 9000 series GPUs

Intel The latest agility SDK brings a major improvement in raytracing in the form of PTLAS/cluster APIs. They set the foundation for efficient updates and management of very large and complex scenes, while keeping the memory footprint low, allow developers to represent their scenes with high fidelity without excessive memory usage. We’re very happy to support this API early on to enable smooth developer adoption over the coming months!

– Matthäus Chajdas, Senior Principal Engineer, Intel

Drivers: https://www.intel.com/content/www/us/en/download/931698

Supported hardware:

  • Intel® Arc™ B-Series Graphics
  • Intel® Core™ Ultra processor family (200V series, Series 3)
Qualcomm DirectX Clustered Geometry and Partitioned TLAS represent important advancements for next-generation gaming experiences on Snapdragon® compute platforms. Qualcomm is working closely with Microsoft to enable these features on Snapdragon X2 platforms, with driver support targeted for availability in Q1/Q2 2027.
WARP Software Renderer https://www.nuget.org/packages/Microsoft.Direct3D.WARP/1.65535.22-preview

Before device creation, enable the preview:

UUID features[] = {
    D3D12ExperimentalShaderModels,
    D3D12RaytracingPreview
};
ThrowIfFailed(D3D12EnableExperimentalFeatures(
    _countof(features), features, nullptr, nullptr));

Query support through ID3D12Device16:

D3D12_FEATURE_DATA_D3D12_OPTIONS_RAYTRACING2 options = {};
ThrowIfFailed(device16->CheckFeatureSupport1(
    D3D12_FEATURE_D3D12_OPTIONS_RAYTRACING2,
    &options, sizeof(options), D3D12_PREVIEW_SDK_VERSION));

if (!options.ClustersAndPTLASSupported)
{
    // Fall back to traditional BLAS/TLAS path or report unsupported hardware.
}

Clustered Geometry’s shader intrinsics use Shader Model 6.10. Raytracing pipelines that traverse Cluster BLAS opt in with D3D12_RAYTRACING_PIPELINE_FLAG_ALLOW_CLUSTERED_GEOMETRY. Inline raytracing uses the corresponding clustered-geometry RayQuery flag.


Samples


D3D12 Clustered Geometry sample

D3D12RaytracingClusteredGeometry is a cluster sandbox for experimenting with build modes, allocation strategies, vertex formats and precision, workload size, and primary rays per pixel. Procedural objects exercise CLAS builds, while an animated sphere demonstrates template instantiation.

The scene is programmer art, with the goal to help you build intuition for how clusters behave as you change the settings.

You can switch between building BLAS from triangles and assembling Cluster BLAS for the same scene, with allocation sizes and GPU build timings shown in the overlay.

In the pair of images below running on an AMD RX 9070, the first shows traditional BLAS mode, and the second Clustered Geometry mode.  Since the stats are hard to read with jpg compression, the table below highlights the differences.  This is just one configuration, so keep in mind conclusions might vary depending on settings / load / GPU.

ClusteredGeometry BLAS image ClusteredGeometry CLAS image

Metric Traditional BLAS rebuild Clustered geometry Cluster vs Traditional
Frame rate 1.8 FPS 84 FPS ~47x higher
Per-frame GPU AS preparation/build 482 ms 3.06 ms 157x less time
Per-frame GPU raytracing 73.8 ms 8.47 ms 8.7x less time
Static AS memory 1,368 MiB 527 MiB 61.5% less
Animated AS memory 11,359 MiB 245 MiB 97.8% less
Total AS memory, including TLAS 12,728 MiB 774 MiB 93.9% less
Static build scratch 1.78 MiB 526 MiB Higher scratch requirement
Animated build scratch 8 MiB 179 MiB Higher scratch requirement
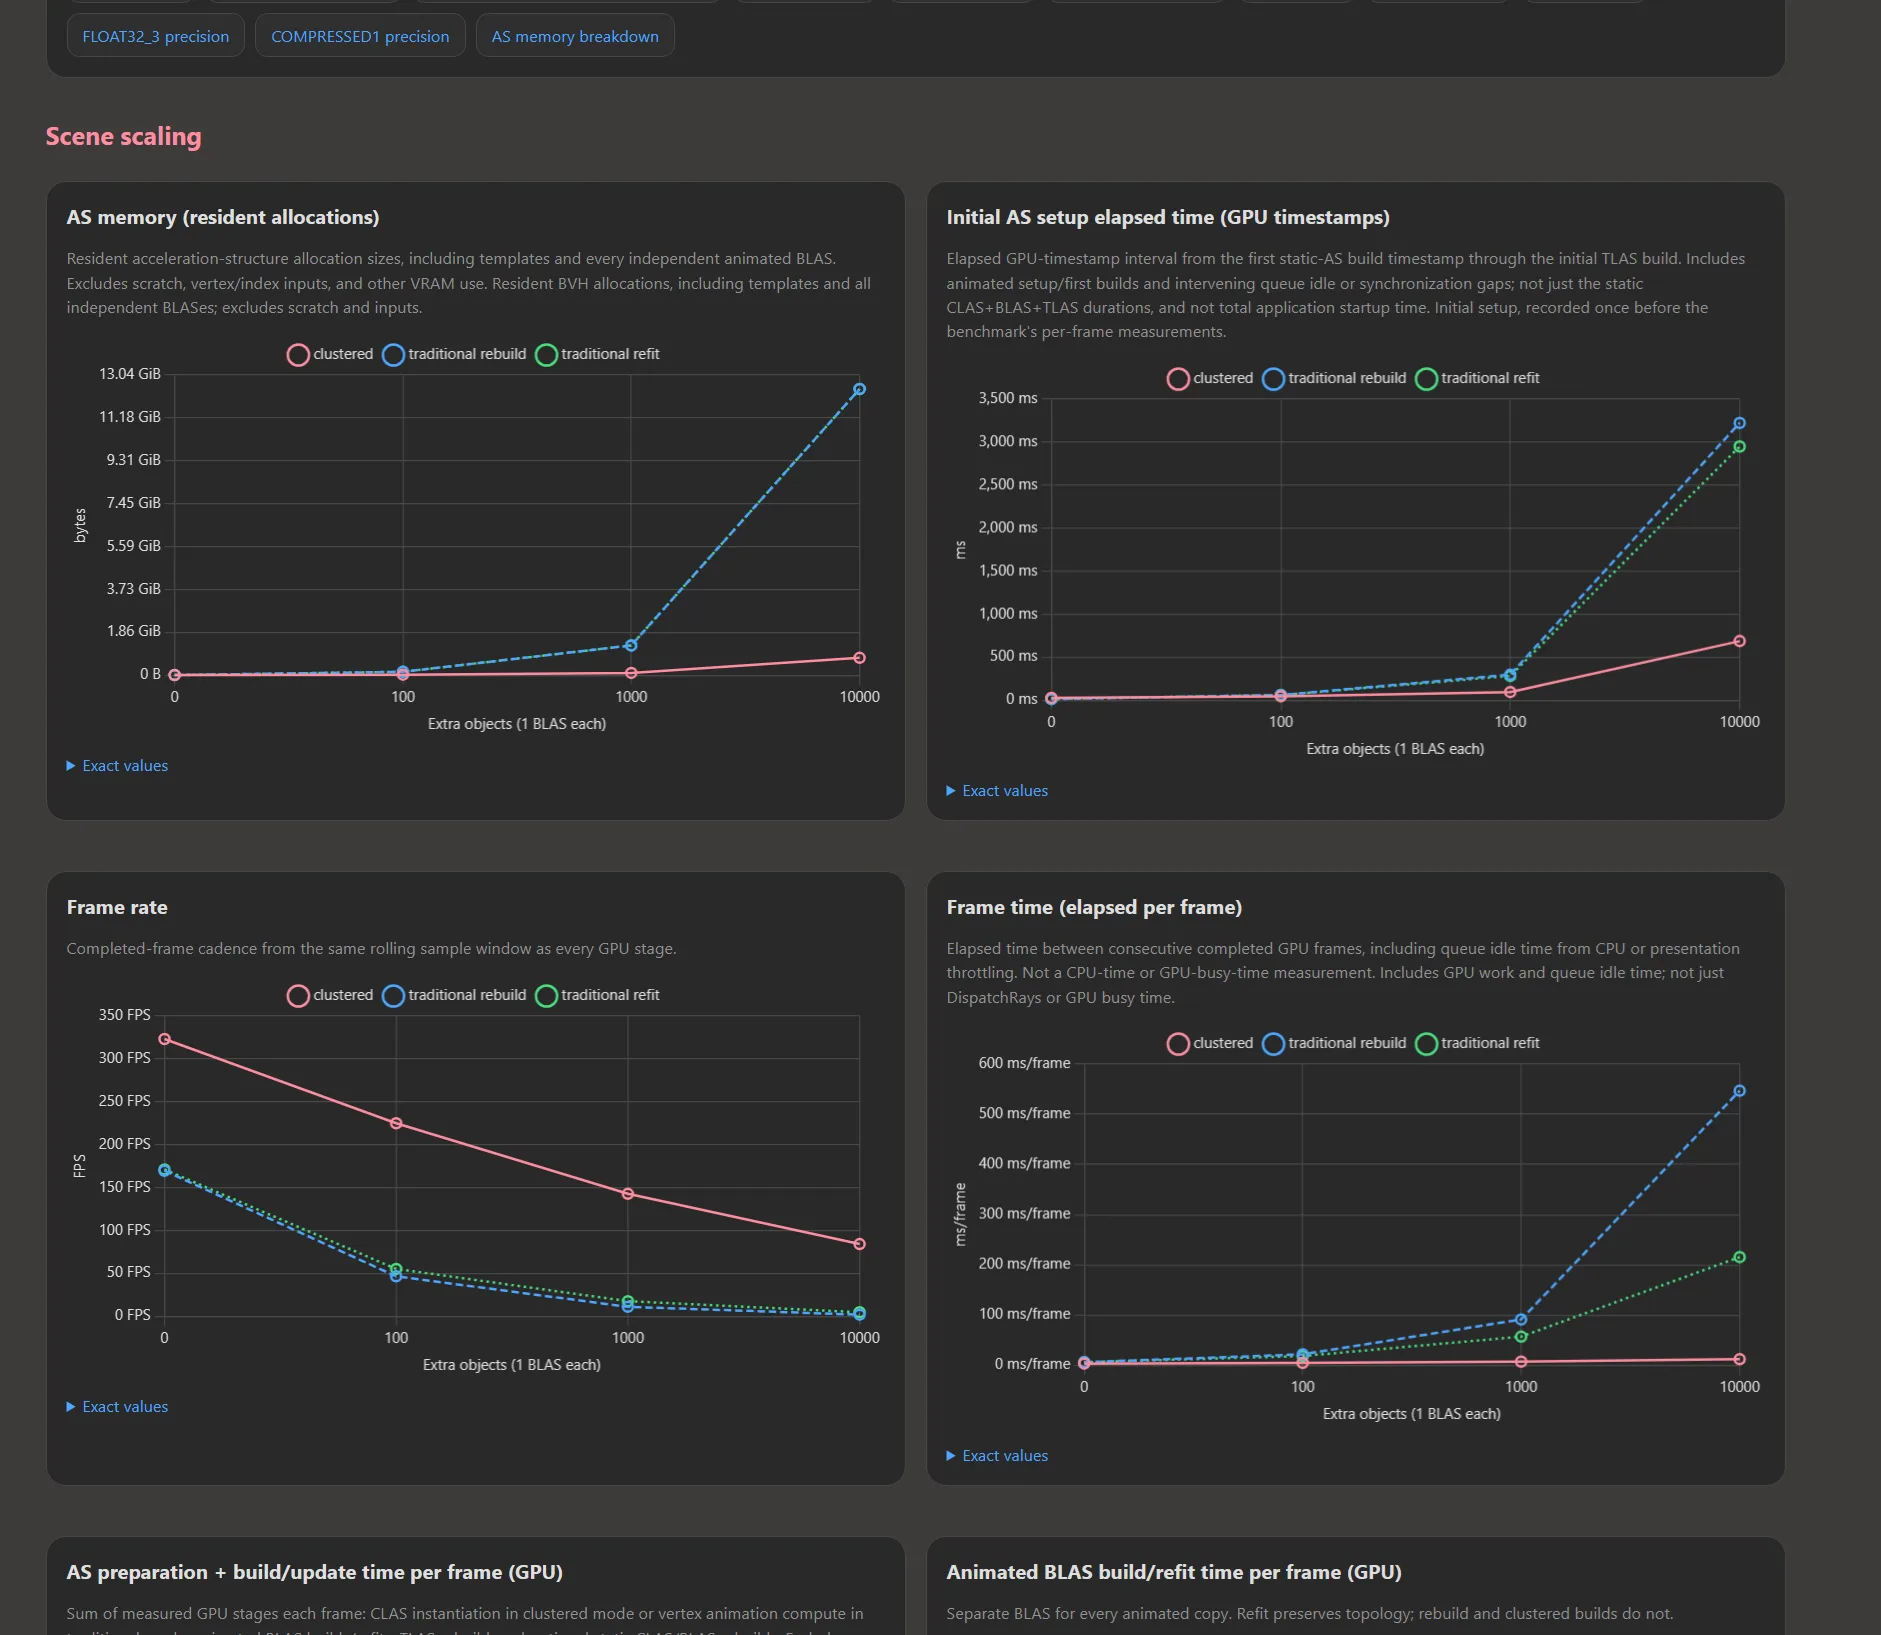
The sample offers automated benchmarking from the command-line that compares clustered geometry with traditional BLAS rebuild and refit across scene sizes, build settings, allocation modes, and vertex formats and precision. It tracks stats like GPU build/update and rendering times, and memory usage, enabling offline reports for matched-workload comparisons across GPUs.

Here’s a short snippet of the report the benchmark generated for the AMD RX 9070 in this example.

ClusterBenchmarkReportExamples image

Instructions for generating reports can be found in the sample’s readme here.

The sample is available in the DirectX-Graphics-Samples repository here: https://github.com/microsoft/DirectX-Graphics-Samples/tree/master/Samples/Desktop/D3D12Raytracing/src/D3D12RaytracingClusteredGeometry

If you want to browse the sourcecode, for the shortest CLAS example, start with BuildClasImplicitand BuildBlasFromClasIndirect. For animation, followBuildAnimatedObjectSetup and UpdateAnimatedObjectPerFrame, together with the GPU argument writers in the Fill*Args.hlsl files.


NVIDIA D3D12 Clustered Geometry sample

NVIDIA’s RTX Mega Geometry sample demonstrates Clustered Geometry with animated content, path-traced rendering, and visualization modes for inspecting the generated geometry.  A good selection of assets / scenes is available to load into the app.

NVIDIA-RTX/RTXMG: NVIDIA RTX Mega Geometry SDK

Github release tag: https://github.com/NVIDIA-RTX/RTXMG/releases/tag/v2.2.0

Below: NVIDIA Zorah scene running on D3D12.  The second image shows clusters and the third triangles.  This hasn’t been tested on other vendors’ GPUs yet.

rtxmg screenshot 0000 image rtxmg screenshot 0001 image rtxmg screenshot 0002 image

As mentioned in the intro, NVIDIA has a post with additional samples here: https://github.com/NVIDIA-RTX/Whitepapers/blob/main/dx_clusters_and_ptlas/README.md


D3D12 Partitioned TLAS domino sample

D3D12RaytracingPartitionedTLAS is a D3D12 sample contributed by NVIDIA to DirectX-Graphics-Samples. It demonstrates sparse instance updates using the D3D12 PTLAS API in a world of dominoes and static scenery, with BLAS built from triangles. You can compare Partitioned TLAS with non-partitioned TLAS refit or rebuild using the same scene and animation.

The sample’s partitioning modes keep moving dominoes in their spatial partitions, move active instances to the global partition, or combine the approaches according to camera distance. Colors show real partition membership and simulation activity.

The sample focuses on sparse writes and fixed-capacity partitions. The Partitioned TLAS specification covers additional features such as partition translations, explicit instance bounds, and resizing.

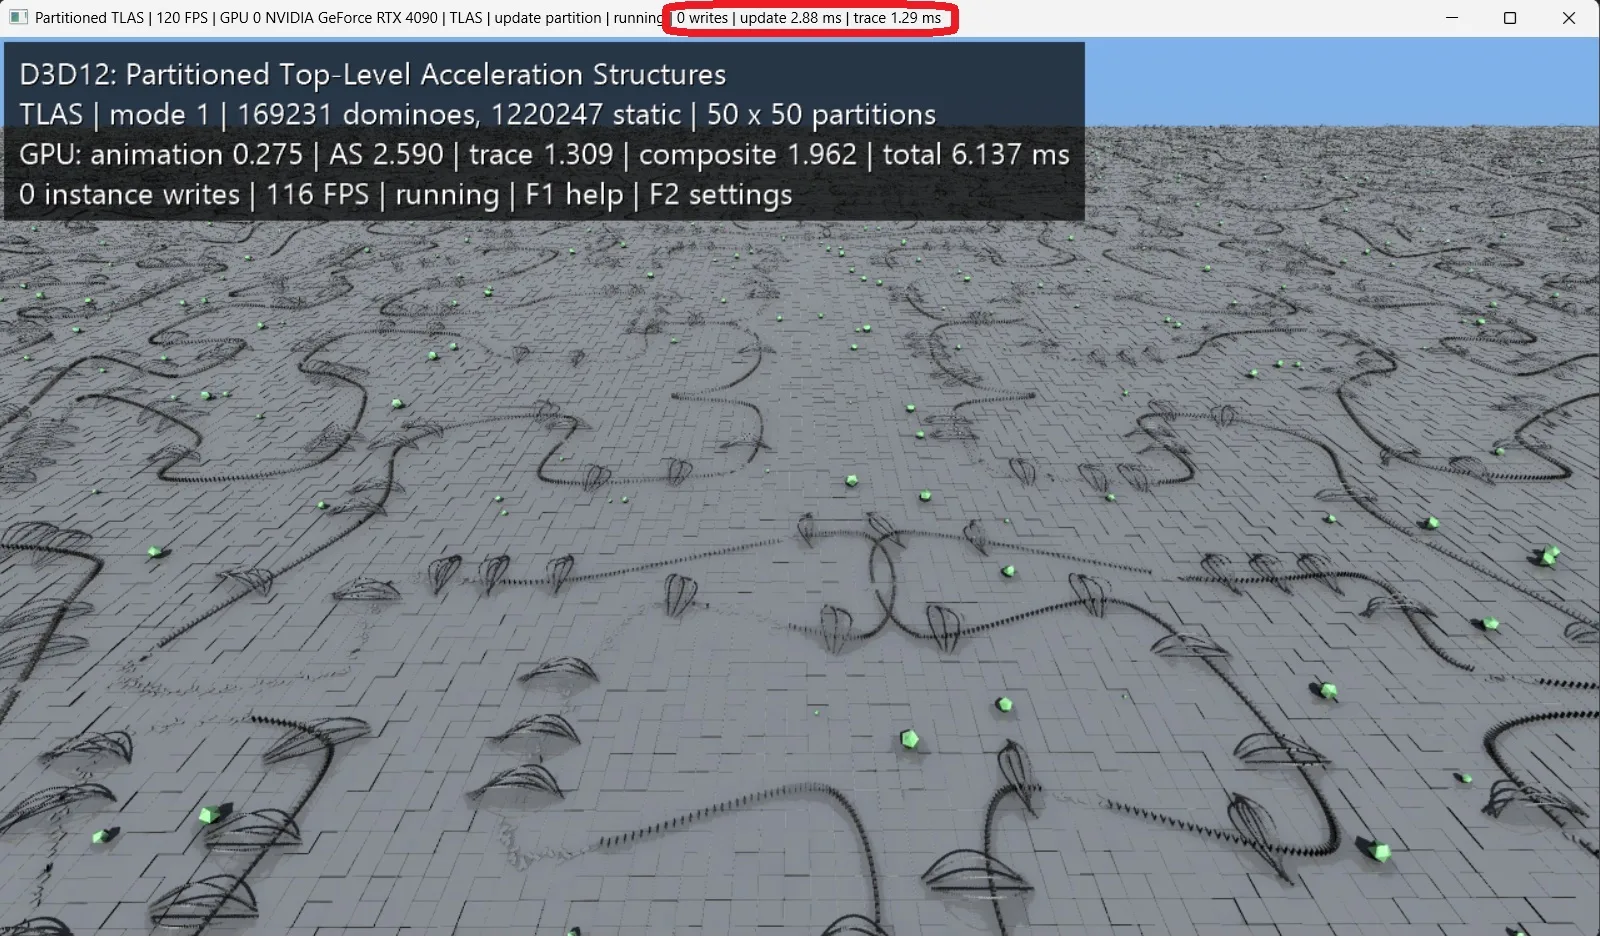
The first screenshot shows a TLAS compared to PTLAS in the second shot.  Note the huge difference in scene update time as many dominos are falling.  TLAS needs a full rebuild each frame and takes 2.88ms, while PTLAS with localized writes (4702 in this case) only takes 0.79ms.  PTLAS trace time is a bit slower here, but here the tradeoff is worth it.

DominosTLAS image

DominosPTLAS image

The sample is available in the DirectX-Graphics-Samples repository here: https://github.com/microsoft/DirectX-Graphics-Samples/tree/master/Samples/Desktop/D3D12Raytracing/src/D3D12RaytracingPartitionedTLAS

NVIDIA ported the sample from its original Vulkan implementation by Pascal Gautron and the nvpro-samples contributors.


PIX

Last but not least, PIX with preview support for Clusters and PTLAS can be found here:

https://devblogs.microsoft.com/pix/?p=7181&preview=true

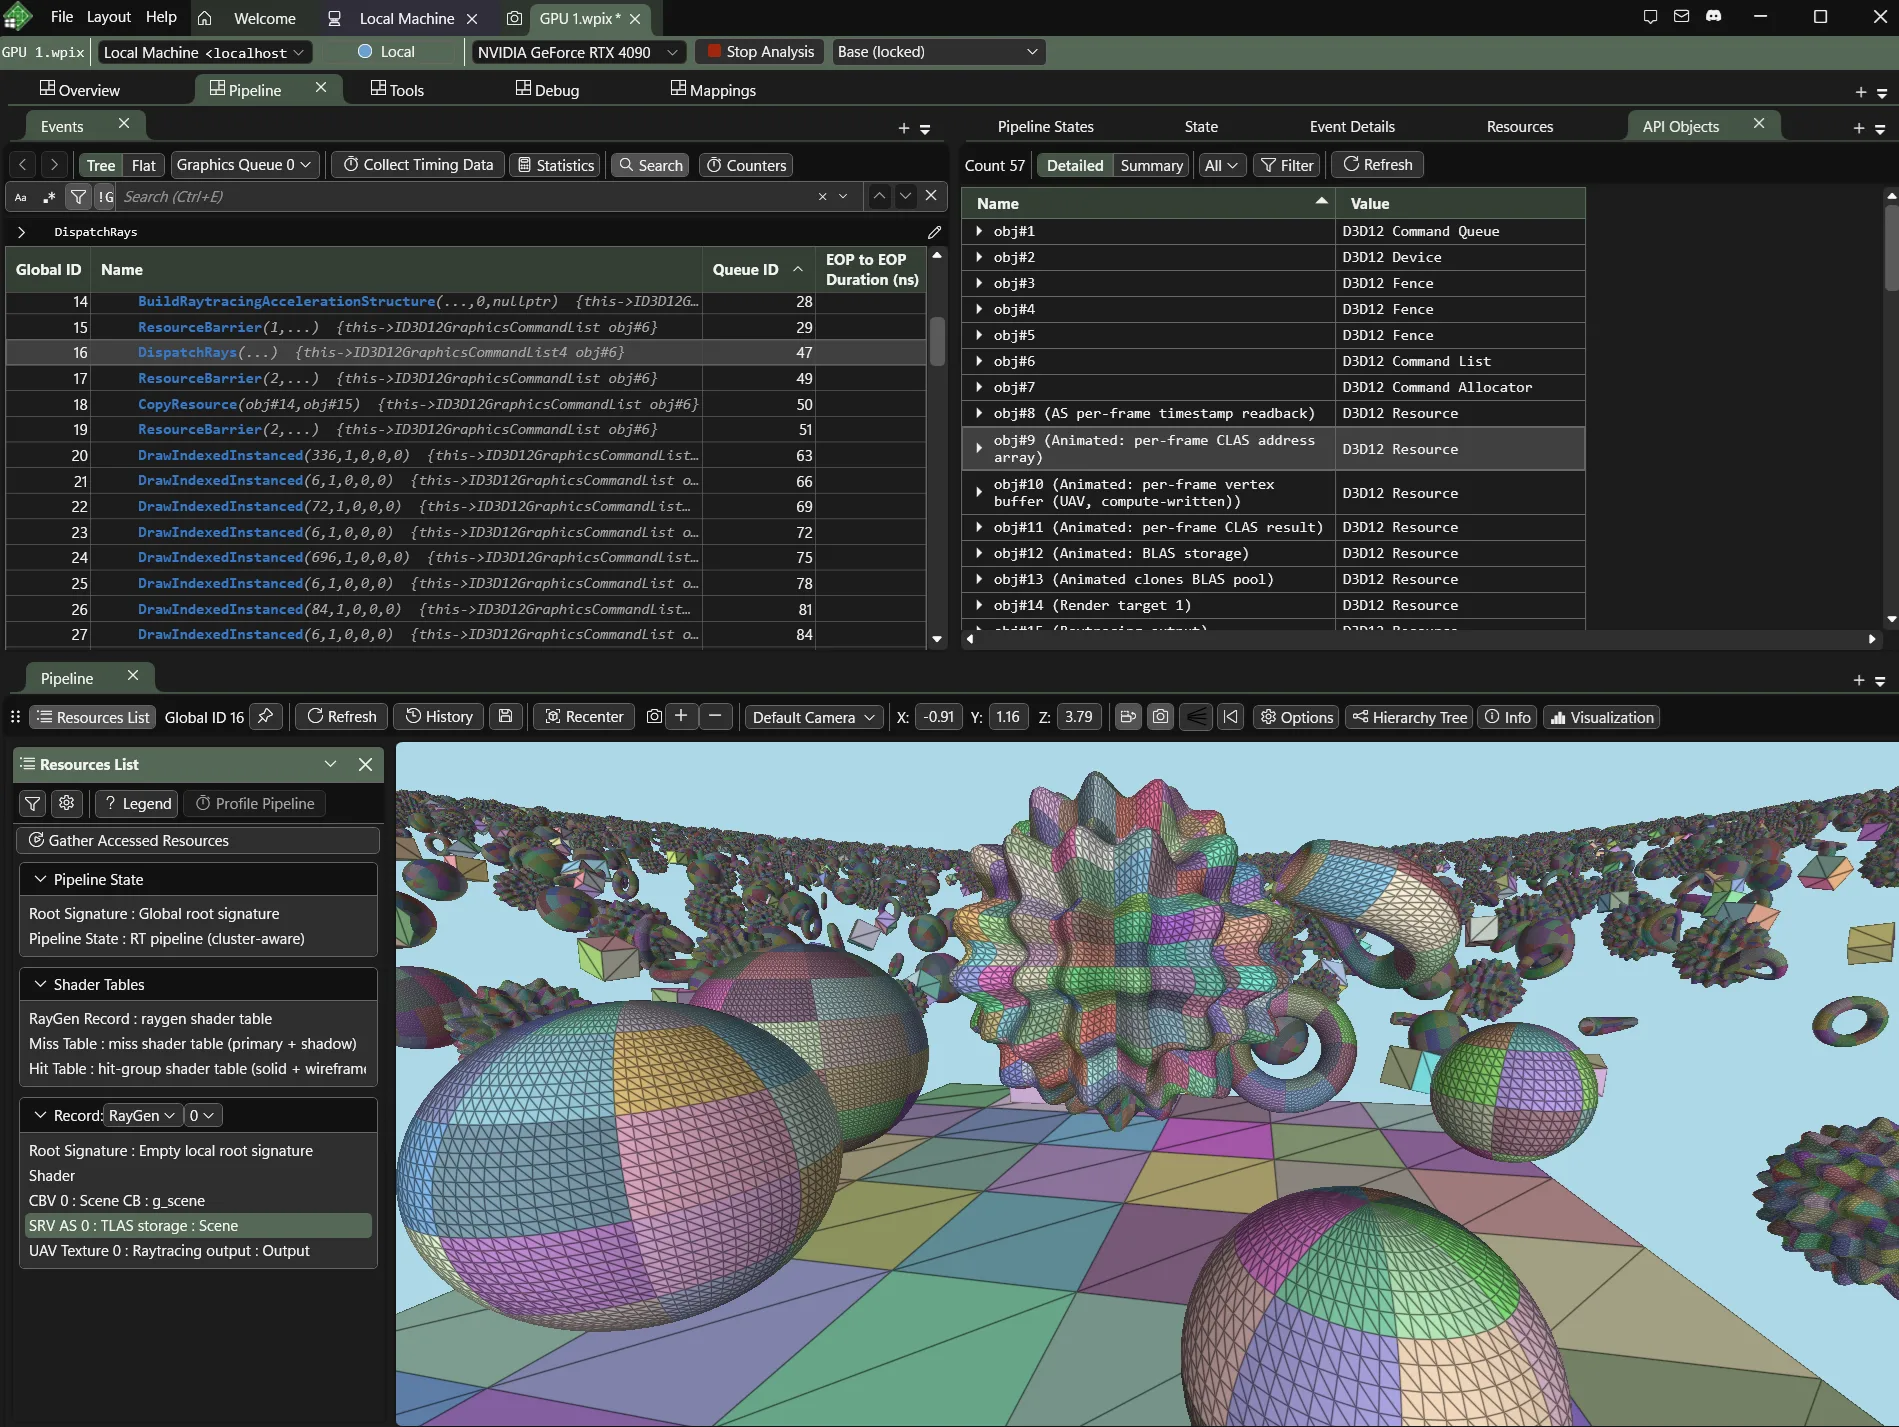
Here is PIX analyzing the Clustered Geometry sample:

PIXClusterSample image

The post [PREVIEW] Raytracing: Clustered Geometry, Partitioned TLAS, Indirect Acceleration Structure Builds appeared first on DirectX Developer Blog.

Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

CPython Dropping Experimental JIT

1 Share
Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Publish Visual Studio Marketplace extensions securely with Trusted Publishing

1 Share

We are excited to announce Trusted Publishing for Visual Studio Marketplace —a simpler and safer way to publish Visual Studio Code and Visual Studio extensions from GitHub Actions or Azure Pipelines without storing a long-lived Azure DevOps personal access token (PAT).

Trusted Publishing uses federated identity to verify your release workflow and grant access for the publish—no publishing secret to store or rotate.

Why Trusted Publishing?

Automated Marketplace publishing has traditionally required storing a PAT as a CI/CD secret. Trusted Publishing offers a safer alternative:

  • No long-lived secrets—there is no publishing credential to store or rotate in your CI/CD system.
  • Short-lived access—for GitHub Actions, Marketplace issues a temporary credential that expires after 15 minutes.
  • Federated identity—Marketplace trusts a configured GitHub workflow or Azure Pipelines workload identity.

Existing PAT-based publishing continues to work, so you can adopt Trusted Publishing when you are ready.

How it works

  1. The CI/CD system presents its federated identity to Visual Studio Marketplace.
  2. Marketplace verifies the GitHub Trusted Publishing policy or the Azure Pipelines workload identity.
  3. The publishing tool uses the verified identity to publish the extension without a PAT.

The process is automatic when you publish with OIDC—there is no PAT to retrieve or manage.

Supported CI/CD providers

Provider Status Authentication and setup
GitHub Actions Supported Create a policy on the publisher’s Trusted Publishing page and publish with GitHub OIDC.
Azure Pipelines Supported Configure a Microsoft Entra-backed WIF service connection and add its identity as a publisher contributor. No Marketplace policy is required.

For Azure Pipelines, see configure a Microsoft Entra-backed WIF service connection and add its identity as a publisher contributor.

Get started with GitHub Actions

Create a Marketplace policy that identifies the GitHub repository and workflow allowed to publish.

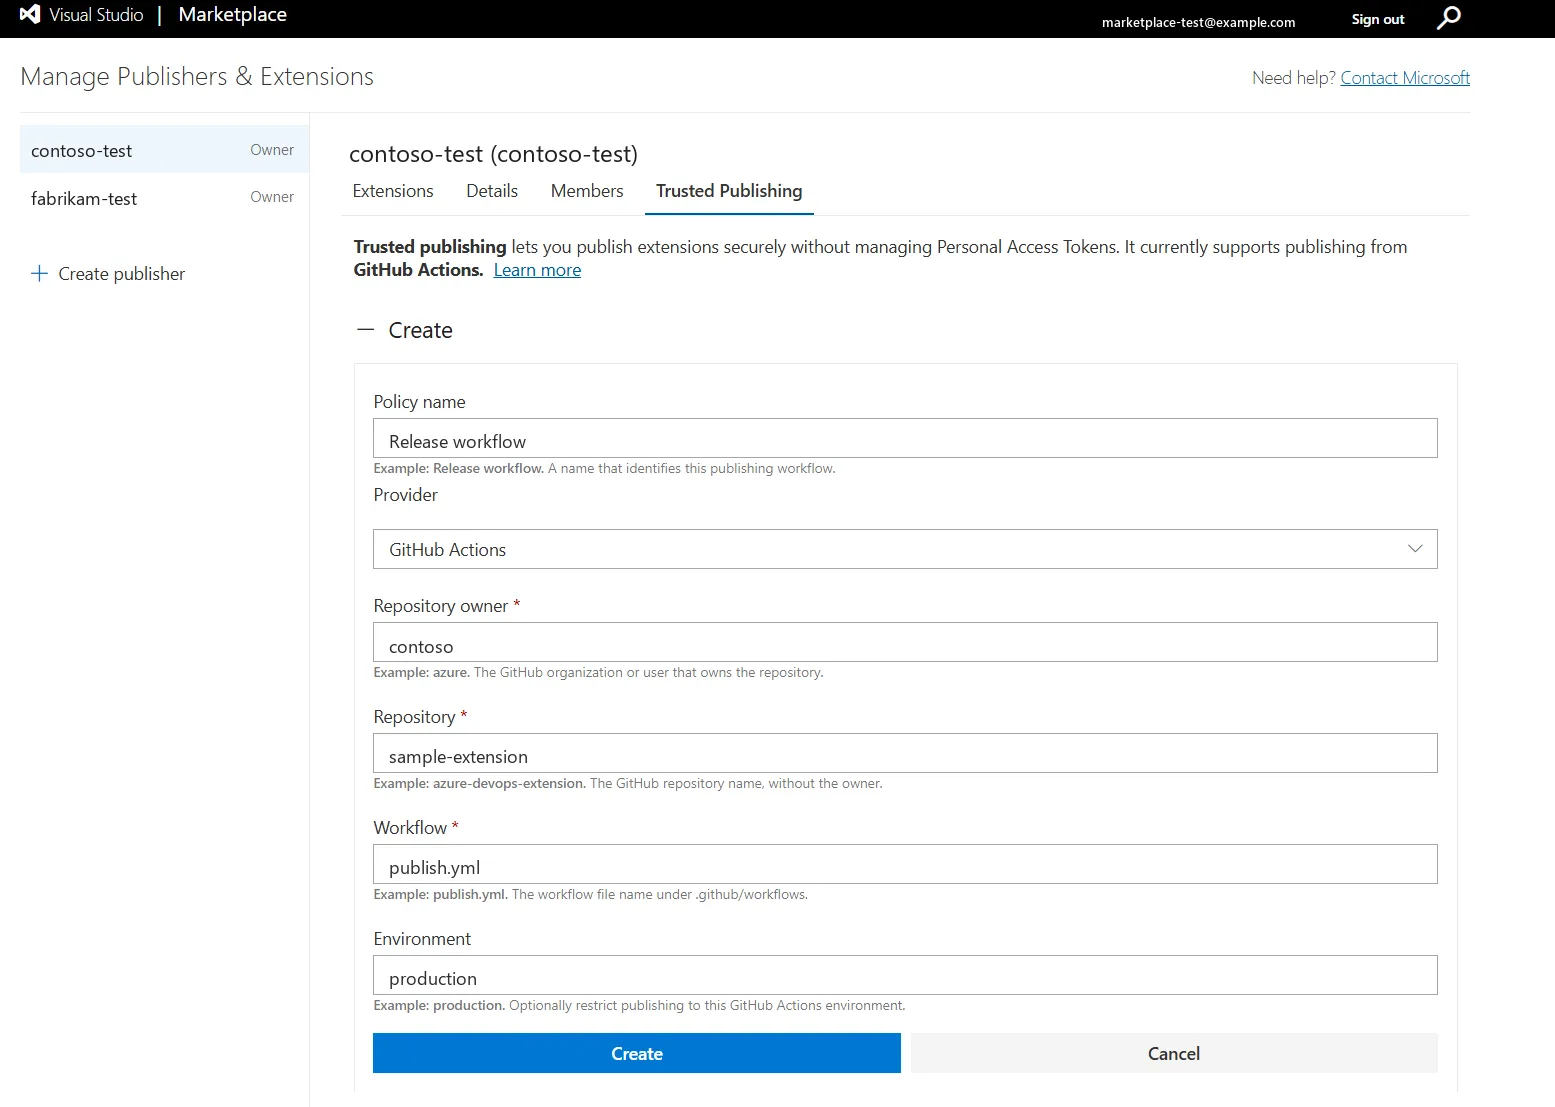
The Trusted Publishing tab for configuring GitHub Actions policies in Visual Studio Marketplace

1. Create a Trusted Publishing policy

  1. Sign in to Visual Studio Marketplace.
  2. Open the publisher that owns your extension.
  3. Select Trusted Publishing.
  4. Expand Create, then fill in the fields described below.
    Field Value
    Policy name A descriptive name such as Release workflow.
    Repository owner The exact GitHub organization or user login that owns the repository, such as contoso.
    Repository The repository name without the owner, such as sample-extension.
    Workflow The workflow filename under .github/workflows, such as publish.yml.
    Environment (optional) If the workflow uses a GitHub environment, enter its exact name, such as production.
  5. Select Create.Creating a Trusted Publishing policy with fictional test account data

For a private repository, run the configured workflow within 48 hours of creating the policy. The first successful token exchange permanently activates the policy.

2. Publish a Visual Studio Code extension

To configure your GitHub Actions workflow and publish without a PAT, follow the Secure automated publishing to Visual Studio Marketplace guide in the Visual Studio Code documentation.

3. Publish a Visual Studio extension

To publish your Visual Studio extension from the command line, follow the Publish a Visual Studio extension via command line guide in the Visual Studio documentation.

Publishing from Azure Pipelines

Azure Pipelines uses an Azure DevOps service connection with Workload Identity Federation (WIF) instead of a GitHub Trusted Publishing policy.

Do not create a policy on the Marketplace Trusted Publishing page for Azure Pipelines.

Before publishing:

  1. Configure an Azure Pipelines service connection that uses Workload Identity Federation. Back the connection with either a Microsoft Entra app registration and service principal or a managed identity.
  2. Add that identity to your Visual Studio Marketplace publisher and grant it the Contributor role.
  3. Configure the publishing step to use the WIF service connection.

The pipeline can then publish Visual Studio Code or Visual Studio extensions without storing a Marketplace PAT.

GitHub policy lifecycle

GitHub policy activation differs based on repository visibility. For a private repository, a new policy is temporarily active for 48 hours. The first successful token exchange makes the policy permanently active. If the policy is not used during that period, it expires and can be reopened for another 48 hours.

You can view the status and last use of each policy from the Trusted Publishing page.

Migrating from a PAT

If your GitHub Actions workflow already publishes with vsce, migration is straightforward:

  1. Create a Trusted Publishing policy for the repository and workflow.
  2. Add id-token: write to the publishing job.
  3. Update the publishing command to use OIDC.
  4. Run the workflow and verify that the OIDC publish succeeds.
  5. After the OIDC publish succeeds, remove the Marketplace PAT from the workflow and repository secrets.

We recommend keeping the PAT until you have verified the first Trusted Publishing run. After the migration succeeds, remove the unused secret so it cannot be used accidentally by another workflow step.

For Azure Pipelines, configure the WIF service connection and publisher identity first, update the publishing step to use that connection, and remove the PAT only after the federated publish succeeds. No Marketplace Trusted Publishing policy is needed.

Try Trusted Publishing Today

Trusted Publishing makes automated extension releases easier to maintain and safer by default—without requiring a long-lived publishing secret.

To get started:

  1. Open your publisher in Visual Studio Marketplace publisher management.
  2. Create a policy under Trusted Publishing.
  3. Update your GitHub Actions workflow to use OIDC.
  4. Publish your extension without a PAT.

Using Azure Pipelines instead? Follow the Azure Pipelines setup guide to publish with Workload Identity Federation (WIF), without a PAT.

For complete setup instructions and troubleshooting guidance, visit the Trusted Publishing documentation.

Thank you

Thank you to our extension publishers for investing in more secure releases. As you adopt Trusted Publishing, we would love to hear what works well and where we can improve—from configuring your first policy to publishing without a PAT.

Share your feedback in the Visual Studio Marketplace GitHub discussions.

The post Publish Visual Studio Marketplace extensions securely with Trusted Publishing appeared first on Microsoft for Developers.

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Announcing Agility SDK 1.620 Retail and 1.722 Preview: DirectX Dump Files, Partial Graphics Programs, and So Much More!

1 Share

Today, we are pleased to announce the release of Agility SDK 1.620 retail and Agility SDK 1.722-preview!

Agility SDK 1.620 brings DirectX Dump Files to retail, along with Fence Barriers Tier 1, the Batched Asynchronous Command List APIs, and Partial Graphics Programs.

Meanwhile, Agility SDK 1.722-preview introduces major updates to DirectX Raytracing capabilities for highly detailed, dynamic scenes.

Here’s the list of everything in Agility SDK 1.620:

  • GPU diagnostics: DirectX Dump Files; D3D12 Driver Reported Messages; Extended PIX Markers
  • Advanced Shader Delivery: Partial Graphics Programs; Explicitly Specified PSDBs; SODB Enumeration and Transaction API; serialized root-signature support
  • Command submission: Fence Barriers Tier 1; Batched Asynchronous Command List APIs
  • Feature queries: CheckFeatureSupport1; Castable Format Query
  • Resource management: GUID Texture Layout – basic and VPBLT support
  • ML: DirectX Compute Graph Compiler runtime interfaces for MLIR programs
  • Video: VPblit 3DLUT; Video Encode CPU Metadata Resolution

And here’s what’s new in Agility SDK 1.722-preview:

  • Raytracing: Clustered geometry; partitioned top-level acceleration structures; indirect acceleration-structure builds
  • Descriptor heaps: GPU Timeline CopyDescriptors

Quick note: Shader Model 6.10 remains in preview for this release, but it won’t stay there for long! Keep an eye out for it in the Agility SDK 1.621 retail release, coming in early December.

For more detail, including drivers, download links, and feature support, read on down below.

Downloads

These releases are available on Agility SDK Downloads today! As usual, the features in this release come with day one PIX support. Be sure to check out the PIX release blog post for more information.

Drivers

IHV Driver link
AMD AMD Software: Agility SDK Retail Edition 26.20.12.02 (1.620 retail)

AMD Software: Agility SDK Developer Preview Edition 26.20.12.01 (1.722 preview)

AMD Software: DirectX Compute Graph Compiler (DxCGC) Developer Preview Edition 26.10.07.11

Intel Intel Graphics Beta Preview Feature Driver
NVIDIA Download the official NVIDIA drivers or use the NVIDIA App for automatic driver updates.
Qualcomm Qualcomm® Adreno™ Windows Graphics Drivers

See the Feature Support table at the end of this post for more detail on hardware support by feature.

Agility SDK 1.620 retail features

D3D12 features

Advanced Shader Delivery updates

Advanced Shader Delivery (ASD) delivers precompiled shaders so games can avoid doing that compilation on the player’s PC. Agility SDK 1.620 expands how developers prepare and use that shader data.

Partial Graphics Programs allow reuse of compiled program parts across pipeline variants, which can decrease download size and compile time. See the blog post about this topic for more details.

Explicitly Specified PSDBs enables a game to use more than one PSDB, chunking up downloads based on DLC or other criteria. Note that support for multiple SODBs/PSDBs per title from Xbox is not available at this time.

The SODB Enumeration and Transaction API lets developers inspect and update the state-object databases used for ASD. The D3D12StateObjectCompiler.exe tool has been rewritten to sit on top of this API, proving that it’s sufficient for any use case we’ve seen for this database.

Serialized root-signature support lets ASD’s offline compilation tools and the D3D12 runtime work from the same root-signature descriptions. After PSO/SO creation succeeds, you can retrieve the root signature object for use on the command list.

CheckFeatureSupport1

An application programmed to check for specific capability tiers may not recognize capability tiers introduced by a newer runtime. We’ve added an additional way to perform capability checks with CheckFeatureSupport1. This lets the application specify an SDK version and clamps reported tier values to those defined at or before that version, avoiding unexpectedly newer values.

Spec: CheckFeatureSupport1

Resource Management

Batched Asynchronous Command List APIs

Older copy and clear commands impose ordering even when operations touch independent memory. That can serialize work the GPU could otherwise overlap.

The batched APIs let an application express independent work while using Enhanced Barriers for dependencies. For example, CopyBufferRegions can batch independent copies so they may execute concurrently; the application inserts an Enhanced Barrier before a subsequent operation that depends on their results.

ClearTextureSubresources also clears by resource and format rather than requiring view descriptors, while FillBuffers provides batched buffer fills. ClearBoundRenderTargetViews and ClearBoundDepthStencilView allow you to do clears even within render passes.

We’re also providing the option of enabling a fallback layer to bring emulated support for the new commands to older hardware, check out more detail in our in-depth blog.

Spec: Batched Asynchronous Commands

Castable Format Query

Middleware that receives a resource does not necessarily have the format-cast list supplied when the resource was created. Without a query, it is nigh impossible for the middleware to track this information.

ID3D12Resource3::GetCastableFormatsCount and GetCastableFormats expose the recorded list. A component can retrieve the declared view formats from the resource itself. This retrieves the explicit creation-time cast list; it does not grant new casting permissions.

Spec: Castable Format Query

GUID Texture Layout

GUID Texture Layout lets the application specify D3D-defined texture layouts or query driver-managed layouts. One supported scenario is CPU-accessible NV12 resources.

Spec: GUID Texture Layout

Synchronization and Submission

Fence Barriers Tier 1

In February, we released a preview of Fence Barriers, a new D3D12 capability that lets you wait for and/or signal D3D12 fences within a command list. This Agility SDK moves Tier 1 support to the retail release, letting you use it in retail games.

Tier 2 support, which adds support for cross-queue waits, is still restricted to preview Agility SDKs for now, but it will be available in a future retail Agility SDK.

Spec: Enhanced Barriers

ML/AI

DirectX Compute Graph Compiler runtime interfaces

Compiling each operation of an ML model as an independent shader can hide the graph structure needed to optimize across operations. MLIR programs preserve that higher-level information, including opportunities to fuse work and avoid intermediate memory traffic.

The runtime interfaces support compiling MLIR programs into executable programs within D3D12 state objects. DXCGC produces optimized graph representations, and the driver performs final hardware code generation. Engines can integrate that compiled graph work with D3D12 execution.

Spec: MLIR Programs and DXCGC

Video

D3D12 VPblit 3DLUT

Tone mapping and color transformations do not always need to occupy the 3D engine. VPblit 3DLUT exposes color-space conversion, one-dimensional lookup tables, and a three-dimensional lookup table through dedicated video-processing hardware.

Where supported, applications can perform those transformations as part of their video-processing pipeline instead of implementing the same work in shaders.

Spec: Video Processing 1D/3D LUT

Video Encode CPU Metadata Resolution

For certain codecs, the application needs completed-frame resolved metadata to finish the bitstream headers. A separate GPU resolve can delay that step even after encoding has finished, particularly when a virtual GPU’s compute work must wait for another scheduling slice.

ID3D12VideoEncoder1::ResolveEncoderOutputMetadataCPU performs the resolve synchronously on the CPU using the encoder instance that produced the metadata. The application waits for encode completion, supplies CPU-readable input metadata, and receives results in application-owned memory.

Query D3D12_FEATURE_VIDEO_ENCODER_CPU_RESOLVE for the codec and configuration. This path is not available with protected resource sessions.

Spec: Video Encode CPU Resolve

PIX and GPU diagnostics

Agility SDK 1.620-retail also brings support for DirectX Dump Files, Driver Reported Messages, and Extended PIX Markers in retail. Check out the latest PIX release blog for more details!

Driver Reported Messages

Driver Reported Messages gives drivers a standard channel to send diagnostic messages to applications through ID3D12InfoQueue. Drivers can use this channel to report issues found by their own validation checks, such as shader binding table errors or acceleration structure problems. When available, messages include context that helps developers trace an issue back to the associated draw or dispatch.

Enable the debug layer and call ID3D12Debug7::SetEnableDriverReportedMessages(TRUE) before creating the device. Driver support determines whether messages are available.


Agility SDK 1.722 preview features

GPU Timeline CopyDescriptors

GPU Timeline CopyDescriptors adds a command-list operation for ranged copies between shader-visible descriptor heaps.

Descriptor heap barriers order updates against shader reads or further copies. This feature requires Resource Binding Tier 4.

DXR Updates

Dynamic geometry and changing scene instances can make acceleration-structure maintenance cost prohibitive for highly detailed scenes. Agility SDK 1.722 preview adds Clustered Geometry, Partitioned Top-Level Acceleration Structures, and Indirect Acceleration-Structure builds. These capabilities let engines reuse geometry clusters, retain unchanged scene partitions, and supply build inputs from GPU memory rather than rebuilding CPU-side descriptions.

Our dedicated Raytracing Updates blog has more details.

Spec: DirectX Raytracing


Appendix

Feature Support

Release Feature AMD Intel NVIDIA Qualcomm
1.620 retail Partial Graphics Programs AMD Radeon™ RX 7000 and 9000 series Planned in a future driver Planned in a future driver Planned in a future driver
1.620 retail Batched Asynchronous Command List APIs AMD Radeon™ RX 7000 and 9000 series Intel® Arc™ B-Series Graphics Intel® Core™ Ultra processor family (200V series, Series 3) Intel® Core™ processor family All RTX GPUs Planned in a future driver
1.620 retail GUID Texture Layout AMD Radeon™ RX 7000 and 9000 series Intel® Arc™ B-Series Graphics Intel® Core™ Ultra processor family (200V series, Series 3) Intel® Core™ processors (Series 3) All RTX GPUs —
1.620 retail Fence Barriers Tier 1 AMD Radeon™ RX 7000 and 9000 series Intel® Arc™ B-Series Graphics Intel® Core™ Ultra processor family (200V series, Series 3) Intel® Core™ processor family GeForce RTX™ 30 series (Ampere) and newer GPUs —
1.620 retail DXCGC runtime interfaces for MLIR programs AMD Radeon™ RX 9000 series — Turing and newer GPUs Planned in a future driver
1.620 retail VPblit 3DLUT AMD Radeon™ RX 9000 series Intel® Core™ Ultra processor family (200V series, Series 3) — —
1.620 retail Video Encode CPU Metadata Resolution AMD Radeon™ RX 7000 and 9000 series Intel® Arc™ B-Series Graphics Intel® Core™ Ultra processor family (Series 1, 200V series, 200S and 200H series, Series 3) Intel® Core™ processor family Turing and newer GPUs with NVENC —
1.620 retail DirectX Dump Files AMD Radeon™ RX 7000 and 9000 series Planned in a future driver All RTX GPUs Planned in a future driver
1.620 retail Extended PIX Markers AMD Radeon™ RX 7000 and 9000 series Planned in a future driver All RTX GPUs Planned in a future driver
1.620 retail Driver Reported Messages Planned in a future driver Planned in a future driver Planned in a future driver Planned in a future driver
1.722 preview GPU Timeline CopyDescriptors AMD Radeon™ RX 7000 and 9000 series Planned in a future driver Planned in a future driver Planned in a future driver
1.722 preview Clustered Geometry, Partitioned Top-Level Acceleration Structures, and indirect acceleration-structure builds AMD Radeon™ RX 9000 series Intel® Arc™ B-Series Graphics Intel® Core™ Ultra processor family (200V series, Series 3) All RTX GPUs Planned in a future driver

— indicates no announced support at this time.

The post Announcing Agility SDK 1.620 Retail and 1.722 Preview: DirectX Dump Files, Partial Graphics Programs, and So Much More! appeared first on DirectX Developer Blog.

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories