Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164513 stories
·
33 followers

OpenAI valued at $1.25 trillion, as rival Anthropic nears its IPO

1 Share

OpenAI is now valued at $1.25 trillion in a new round of funding that has raised another $11 billion, according to Bloomberg. That would make it one of the world's most valuable companies, not long after raising $122 billion from investors in March at a valuation of $852 billion.

Echoing FT and Wall Street Journal reports from last week, Bloomberg says OpenAI is still pursuing additional investments that could increase the amount to $20 billion, and that it had initially hoped to raise as much as $30 billion at a higher valuation of $1.4 trillion. That was before tech stocks dropped, and the results of the midterms showed how much public o …

Read the full story at The Verge.

Read the whole story
alvinashcraft
23 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Beyond code generation: A developer’s guide to agentic engineering

1 Share

This October, GitHub saw more than 1.2 billion commits in one week—over 400% more than a year earlier. This is more commits than GitHub received in all of 2025. Chances are, you’re generating more code than you were a year ago. But ask yourself: do you feel 400% more productive than you were last year?

Building software takes more than a good prompt. As AI speeds up implementation, software developers are feeling more pressure in other places: a Faros AI study found that pull requests spent 441% longer in review when teams went from low to high AI adoption.

As a software developer, you gather requirements and steer implementation, review changes and evaluate test results, then investigate what happens in production. Agents can help you work more efficiently across all of these stages: Plan, Build, Verify, and Observe. We’ll walk through what an effective agentic engineering workflow looks like on GitHub.

Plan: Get everyone and every agent on the same page

See if this sounds familiar. You’re planning an API change. The design is in one tool, a compatibility requirement is buried in Slack, and an old pull request explains why the current implementation works this way. Before you can write a useful plan, you need to connect those details, compare approaches, and agree on how existing clients will keep working. What looked like a straightforward planning task has become hours of searching, cross-checking, and chasing answers. You’re exhausted before implementation even begins.

You can use Copilot to pull that scattered context into one place, work through the tradeoffs, and turn the decisions into an implementation plan.

  • Plan together where your team already works. Use Copilot in Slack or Teams to collaborate with everyone involved—from product managers and designers to analysts and business stakeholders. Bring in context from connected tools so your team can check assumptions, contribute ideas, and refine requirements together.
  • Turn agreed-upon requirements into actionable work. Ask Copilot to create GitHub Issues with the context and acceptance criteria needed for implementation, breaking out tasks that can be handled separately.
  • Keep routine triage from consuming planning time. Use GitHub Agentic Workflows to label your issues and estimate task complexity. Assign low-complexity tasks directly to Copilot, then spend your time focusing on harder decisions.
  • Give complex work the planning it needs. Use Plan Mode in your preferred Copilot surface to compare approaches and refine an implementation plan. Review and approve the plan before handing it off to Copilot to begin implementation.

What took days of searching and context gathering now produces a reviewable plan, explicit acceptance criteria, and scoped issues, with your time spent on the decisions instead of the retrieval. Then, once you settle on an approach, you’ve already set yourself and your agents up to implement your plan.

Build: Move more than one task forward at a time

You’re ready to turn that plan into code. But life has other ideas. Your agent is halfway through a task, your next meeting starts in five minutes, and your dog has been staring at the door for twenty. Then someone in the meeting points out an edge case the implementation needs to handle. Everyone needs something from you at once. You’d like to keep making progress, but you can’t be in three places at the same time.

You can keep your work moving without being tied to the computer where you started it.

  • Continue your conversation from another device. Session continuity lets you pick up the same Copilot session across clients, so you can work wherever it’s most convenient for you.
  • Let work continue after you close your laptop. Copilot runs tasks in cloud sandboxes, keeping execution off your machine and allowing you to leave and return to a session later.
  • Work on separate tasks without mixing their edits. The Copilot app gives sessions isolated copies of the repository, so an implementation task and a documentation update don’t share an unfinished working tree.
  • Carry project knowledge into each task. Repository instructions capture conventions and validation commands, while shared memory stores useful facts Copilot can reuse across a repository. Copilot Dreaming reviews eligible sessions and pull request feedback to keep memories current and propose instruction or skill updates. That means less time re-explaining how your team works and more consistent help from Copilot across tasks.
  • Match the models to the work. Select Copilot Fusion to choose models and reasoning depth for the task, bringing in additional models to review a solution when needed. You set the effort level to balance quality, cost, and response time.
  • Follow company rules wherever you work. Enterprise managed settings carry your company’s policies and configured tools across Copilot surfaces, reducing setup differences as you move between clients.

Writing code is more than shooting off a single prompt to your LLM and seeing what you get back. And with more work on your plate than ever, it can be difficult to maintain your coding standards and deliver your projects on time. Copilot helps tasks progress independently with shared project knowledge, while letting you pick up a session where you left off across devices. That gives you more room to work through implementation decisions and handle changes as they come up. And as your work finishes, you have focused changes ready to review.

Verify: Spend your attention where it counts

After spending an hour wrangling your agents to get them moving in the right direction, you think you’ve all landed in a good spot. So you open a pull request labeled “small refactor.” It changes 47 files. You wanted feedback on shared validation logic, but it’s buried among updates to every endpoint that calls it, formatting changes, and several hundred lines of generated tests. You wonder how long it will take to get an approval on this, given the endless list of pull requests on your team’s review board.

That review queue is the 441% in practice. You can shorten the wait from both ends: make your changes easier for a person to review, and let Copilot clear the routine checks and fixes before anyone opens the diff.

  • Stack up smaller, more focused pull requests instead of creating a single, massive change. You and your agents can use stacked pull requests to separate dependent work into smaller pieces. This lets each PR be reviewed on its own, keeps dependencies visible, and unblocks teams by letting them build on top of your work before it merges.
  • Catch routine quality issues before they consume review time. GitHub Code Quality checks changes against coding practices and your organization’s standards, catching issues before they reach a human reviewer and saving time for both authors and reviewers.
  • Get review help matched to the change. Copilot code review gives automated feedback, with lighter analysis for simple changes and deeper analysis for complex ones. You can set that depth yourself or let Copilot select it for each pull request.
  • Check security across more of your codebase. AI Scan finds vulnerabilities in languages and files beyond CodeQL’s coverage. AI secret detection helps identify unstructured secrets, such as passwords, that pattern matching can miss.
  • Keep new dependencies within policy. License compliance checks dependency licenses against your company’s rules before merging. GitHub package firewall, currently in public preview for npm, can block downloads that violate configured security policies.
  • Resolve findings and follow-up work without babysitting every pull request. Agentic Autofix proposes repairs for security issues, while Agent Merge automatically addresses failing checks, review comments, and merge conflicts—helping you keep your pull requests moving and preparing them for merge. And, if you configure it, Copilot will even merge your pull requests once your verification steps are passing.

Smaller changes with the routine work already handled means fewer rounds of back-and-forth. Your reviewers get to spend their attention on whether the code does what you intended, and what could go wrong.

Observe: Learn from what happens after you ship

Your change gets approved, the deployment checks pass, and you finally get to cross it off your list. The next morning, your on-call dashboard shows intermittent timeouts, and support reports that a few large customers are affected. Now you’re comparing logs, release history, and customer reports while someone asks whether you should roll back. “All checks passed” feels less reassuring than it did yesterday.

Bring operational evidence and engineering context together so you can decide what to do.

  • Check assumptions against real behavior. With access to your observability tools and business data through connectors such as Fabric, Copilot can help investigate which requests or customer groups are affected.
  • Capture the finding where someone can act on it. Ask Copilot to draft an issue with supporting evidence and acceptance criteria, including a regression test for the failure you uncovered.
  • Carry useful lessons into future work. Review suggested improvements from Dreaming, which uses sessions and repository activity to help refine memories, skills, and code review guidance.

Figuring out what happened after a release can leave you bouncing between dashboards, conversations, and commit history. With Copilot helping connect that information, you can document what you found, create follow-up issues, and improve the guidance available for future tasks. You spend more time deciding what needs to change and less time retracing the investigation. And your next plan starts with what you learned from the software people are actually using.

Where to start

Take one piece of work already on your plate and look beyond the coding task. What context does it need? How will you review and test it? How will you know it worked after it ships?

You don’t have to change your whole process at once. Start with something that frustrates you most this week and put an agent on it. Then expand to other parts of your process over time. Once agents are helping across your whole workflow, you might finally feel as productive as your commit count says you are.

We covered this topic live at GitHub Universe 2026 in “Agentic Engineering: Past the Pilot.”

Get started with Copilot >

The post Beyond code generation: A developer’s guide to agentic engineering appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

AI Stockpocalypse, Anthropic Nears RSI?, Prediction Markets vs. Pollsters

1 Share

Ranjan Roy from Margins is back for our weekly discussion of the latest tech news. We cover: 1) The midterms impact on AI 2) Why the market struggles to trade AI in a normal way 3) Will the AI vision ever be realized as planned after this week? 4) A simple theory of the case on the AI trade 5) If datacenters are banned, do AI labs make tradeoffs in training, inference, or safety? 6) Will Anthropic's IPO still go on as planned? 7) Can the AI labs help turn around datacenter unpopularity 8) Is Anthropic getting close to RSI? 9) Who did better: The polls or prediction markets 10) An homage to Alex's special, temporary red chair

---

Enjoying Big Technology Podcast? Please rate us five stars ⭐⭐⭐⭐⭐ in your podcast app of choice.

Want a discount for Big Technology on Substack + Discord? Here’s 25% off for the first year: https://www.bigtechnology.com/subscribe?coupon=0843016b

Learn more about your ad choices. Visit megaphone.fm/adchoices


Download audio: https://pdst.fm/e/tracking.swap.fm/track/t7yC0rGPUqahTF4et8YD/pscrb.fm/rss/p/traffic.megaphone.fm/AMPP6817214496.mp3
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Outbox Pattern in Postgres: Concurrent Workers vs Reading the WAL

1 Share

The outbox pattern saves a message in the same database transaction as the data change it describes, then uses a background worker to send it. Concurrent workers can drain the outbox table with FOR UPDATE SKIP LOCKED, but new messages wait for the next poll. Reading the Postgres write-ahead log with logical replication delivers them in about a millisecond at low load, at the cost of a replication slot and a cleanup job.

If you build distributed systems, you probably heard about the Outbox pattern.

Your API saves an order, then crashes before it can send the message announcing that order.

The order is in the database, but other services waiting for that message never hear about it. The outbox pattern handles this by saving the message in a separate table, in the same database transaction as the order.

Either both are saved or neither is. This is the A in ACID. Atomicity.

A background worker reads the saved messages and publishes them to a message broker for other services to receive. If the API crashes after saving the order, the message is still there for the worker to send. Querying the table repeatedly for pending messages is called polling.

Polling is a good starting point for an outbox processor. It's decently fast and easy to implement. But the delay between checks is a tradeoff. Checking more often means more database queries, while waiting longer delays new messages.

I want to reduce that wait by having Postgres tell me when there's something to process, and see how that compares with the polling workers.

Concurrent Workers Draining the Table

For this walkthrough, we'll use an order API on Postgres that saves each OrderCreated message in an outbox_messages table, with RabbitMQ as the broker.

I want to run several workers at once, and Postgres row locks stop two of them from grabbing the same message.

Each worker starts a transaction and claims a batch with this query, using Dapper:

SELECT id, type, content
FROM outbox_messages
WHERE processed_on_utc IS NULL
ORDER BY occurred_on_utc
LIMIT 1000
FOR UPDATE SKIP LOCKED

FOR UPDATE locks the rows this worker picked until its transaction ends. SKIP LOCKED makes the next worker take other rows instead of waiting. The locks live in Postgres, so these workers can run in one process or in several.

The worker keeps that transaction open while it publishes with RabbitMQ.Client, then sets processed_on_utc and commits once RabbitMQ confirms.

When a worker runs out of rows, it sleeps for one second with Task.Delay and tries again.
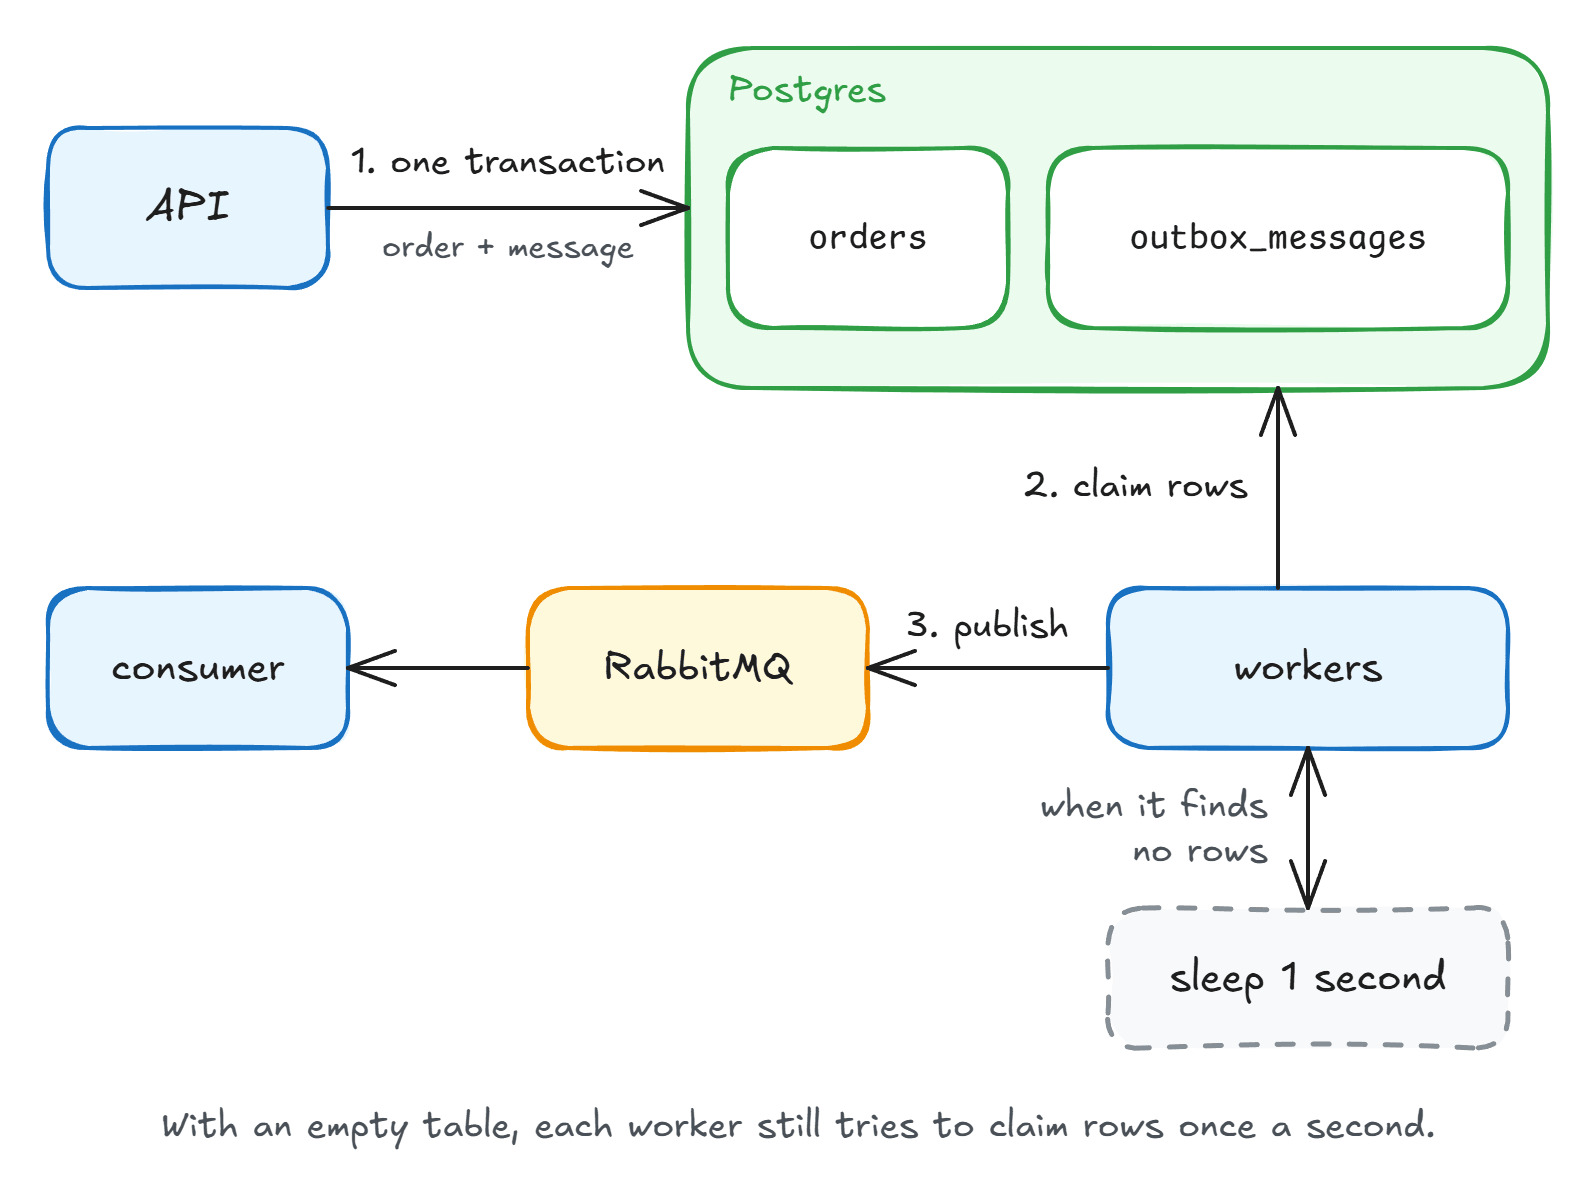
The API writes an order and its message in one transaction. Workers poll and publish to RabbitMQ.

If a worker crashes before it commits, those rows are still unprocessed, and a worker picks them up again. Some of those messages may have already reached RabbitMQ, so the same message can arrive twice.

That makes this at-least-once delivery, so your consumers must be idempotent.

Why Not Just LISTEN/NOTIFY?

Postgres has a built-in way to wake those workers. With LISTEN/NOTIFY, one connection runs LISTEN outbox_new, and Postgres tells it when another connection runs NOTIFY outbox_new and commits.

My first implementation sent NOTIFY from a database trigger on the outbox table. It needs no API changes and worked well at 100 orders per second. But with 100 concurrent users, throughput fell from 8,070 orders per second with polling to 256.

The trigger runs inside the order transaction. Before that transaction commits, Postgres takes a lock and holds it until after the commit. Every transaction that sends a notification takes the same lock.

A commit normally waits for a disk flush, and concurrent transactions can share one, which is called group commit. With the lock, each order waits for the one in front of it to finish its own flush.
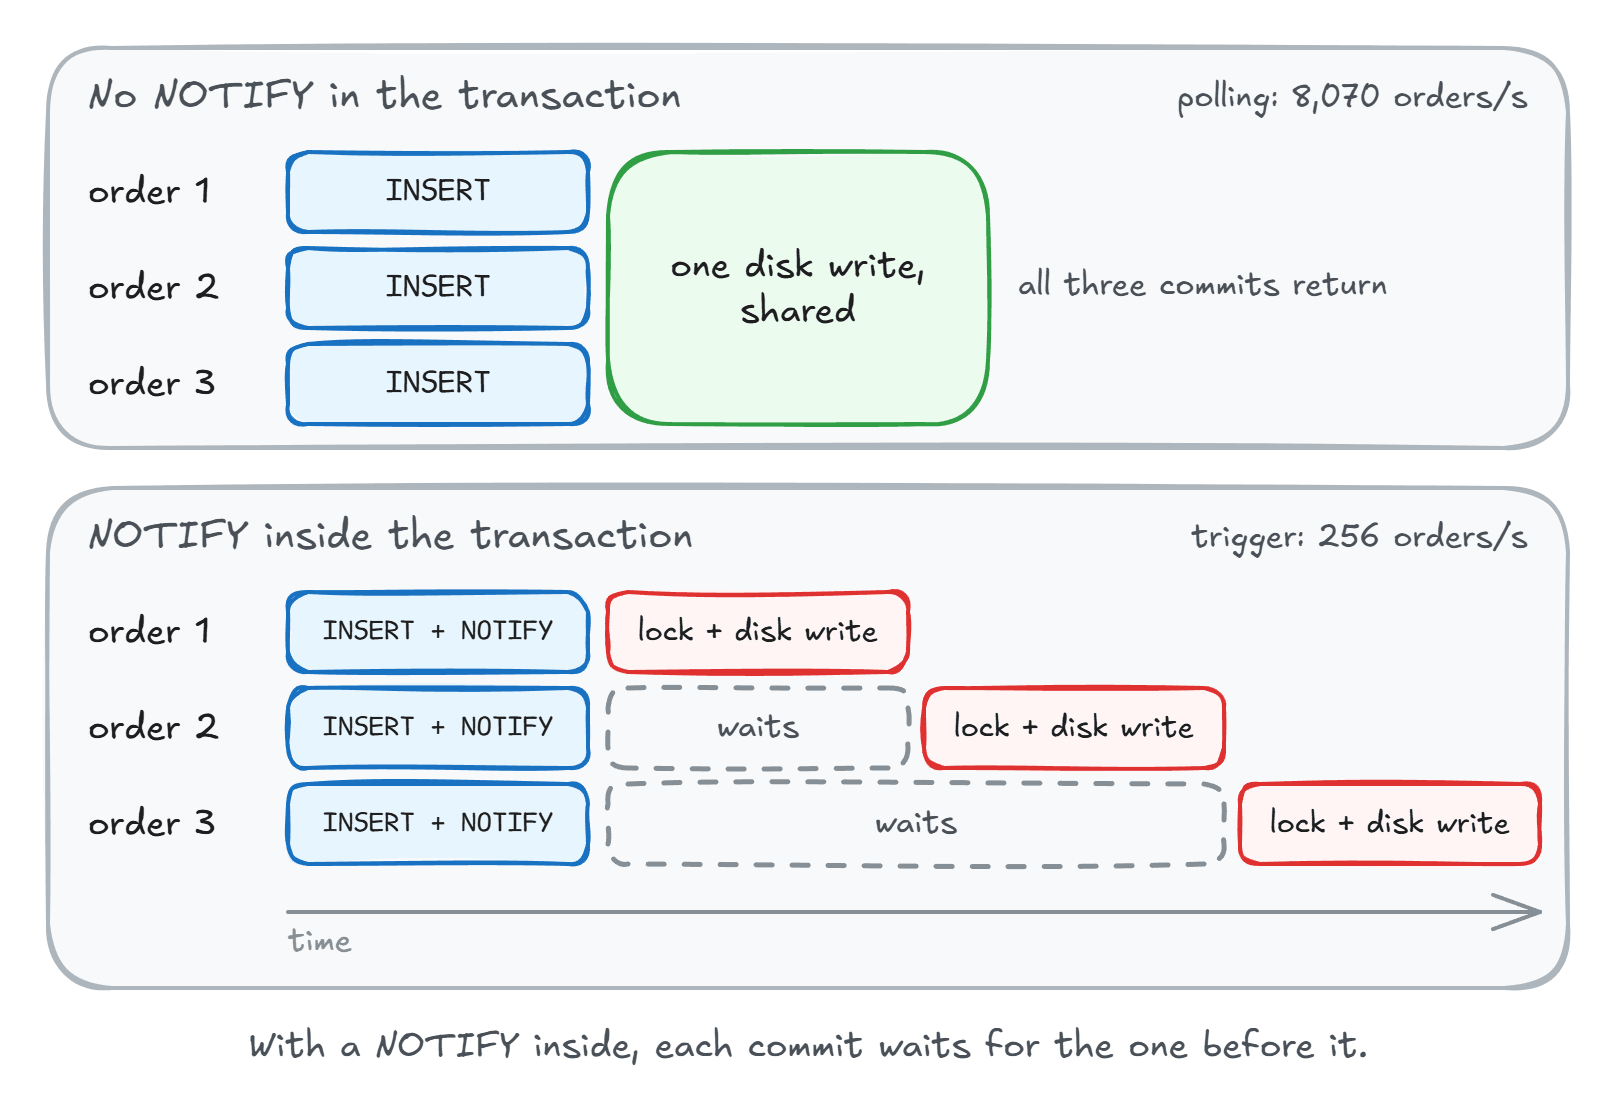
Without NOTIFY, commits share one disk write. With it, each waits for the lock.

Sending NOTIFY after the commit, from a separate connection, avoids that lock. At 100 users the API handled 7,674 orders per second, about 5% below polling, and at 100 orders per second a message took 1.91 ms from commit to consumer.

But now I'm running a notifier, a listener, and a fallback poll for notifications sent while the listener is disconnected, all to wake the same workers. Postgres already has a record of every new row, so let's read that instead.

Read the Outbox From the WAL

Postgres writes every change to the write-ahead log (WAL). Logical replication streams committed changes to my app, so there's no polling and no wake-up to miss.
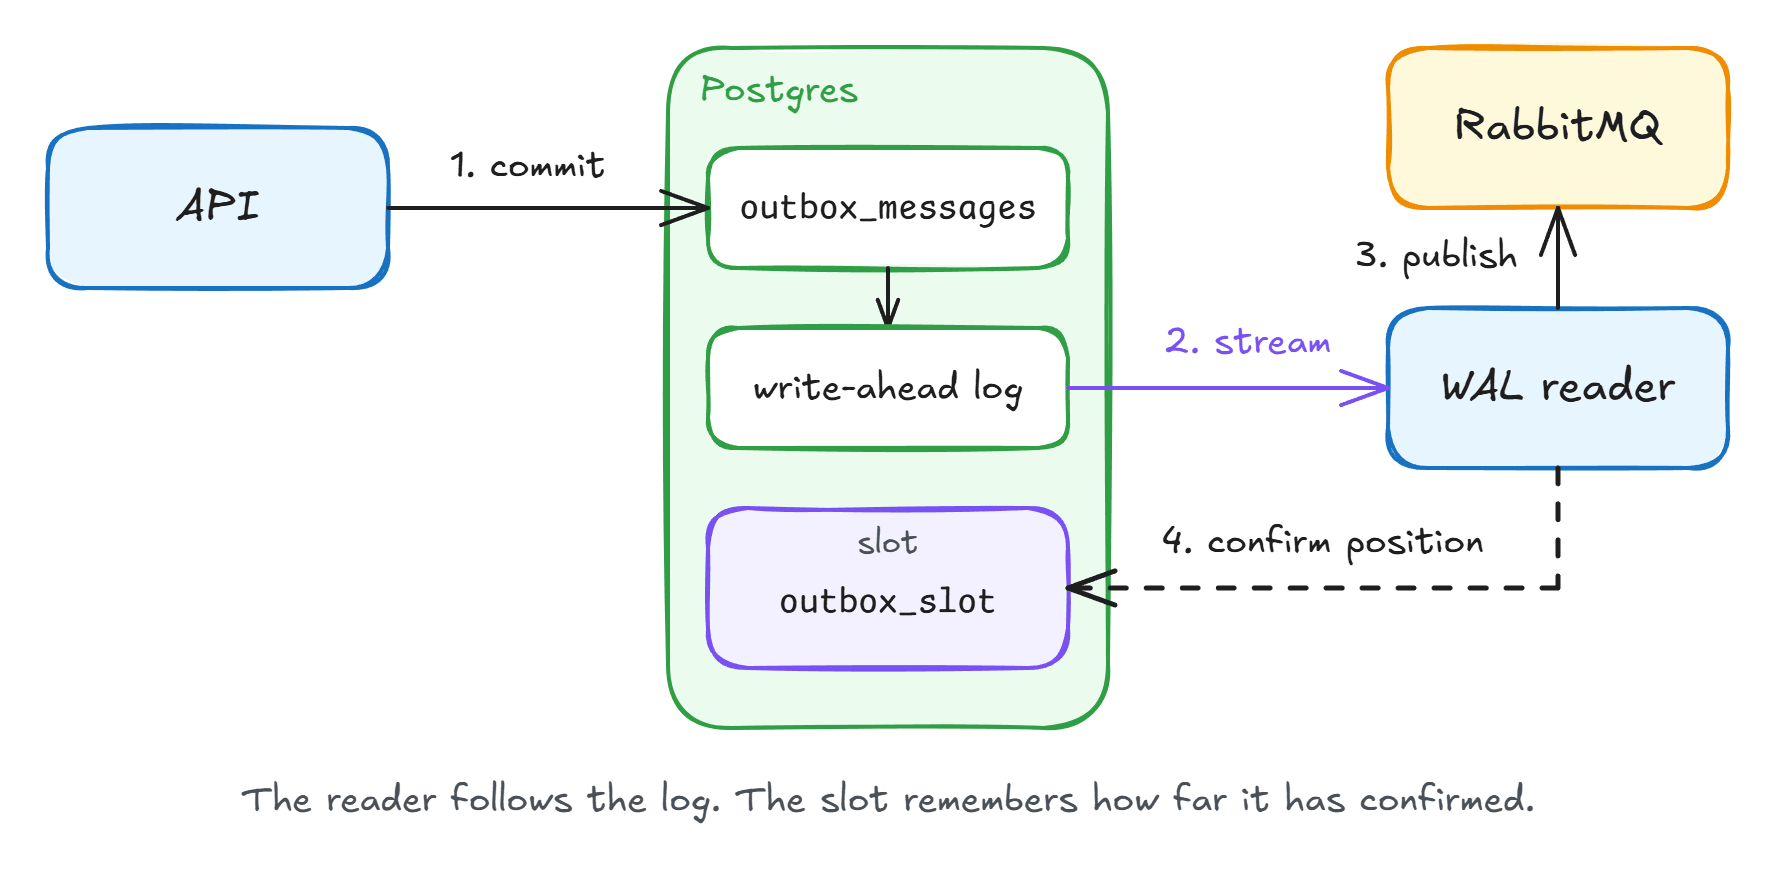
The WAL reader follows the log, publishes to RabbitMQ, and confirms its position.

You need wal_level=logical, which takes a restart on Postgres 18. Then create a publication and a replication slot:

CREATE PUBLICATION outbox_pub FOR TABLE outbox_messages WITH (publish = 'insert');
SELECT pg_create_logical_replication_slot('outbox_slot', 'pgoutput');

The slot remembers how far my reader has confirmed, so it can resume after a restart.

Let's read the stream with an Npgsql replication connection:

await using var connection = new LogicalReplicationConnection(connectionString);
await connection.Open(cancellationToken);

var slot = new PgOutputReplicationSlot("outbox_slot");
var options = new PgOutputReplicationOptions("outbox_pub", PgOutputProtocolVersion.V1);

await foreach (var message in connection.StartReplication(slot, options, cancellationToken))
{
    if (message is InsertMessage insert)
    {
        await PublishAsync(insert, cancellationToken);
    }
    else if (message is CommitMessage commit)
    {
        connection.SetReplicationStatus(commit.TransactionEndLsn);
    }
}

PublishAsync publishes to RabbitMQ and waits for the confirm. I only confirm a position after that, when the CommitMessage arrives, so a crash replays messages instead of losing them.

This loop only suits low rates, because waiting on every message drained about 1,600 per second. So the reader I measured publishes first and waits for confirms, in order, in a separate task.

While the reader is down, the slot keeps all the server's WAL on disk, so a long outage can fill it. You can cap that with max_slot_wal_keep_size, but Postgres invalidates a slot past the cap.

This reader is a prototype, and I haven't tested it through a failover or on managed Postgres.

Workers vs the WAL Reader

The main benchmark comes from my scaling article: I seeded a backlog, started the processor, and counted what RabbitMQ had after one minute, in messages per second (MPS). To keep it fair, the WAL reader also marks rows as processed in batches, so it does the same UPDATE as the workers. This ran on one machine, with Postgres 18 and RabbitMQ 4 in Docker:

SetupMPS after 1 minuteAverage commit to consumer, 100 orders/sAverage commit to consumer, 100 users
1 worker14,516 to 15,050500 ms8.5 s
5 workers22,216 to 24,133419 ms54 to 85 ms
WAL reader27,962 to 34,9300.83 ms8.6 ms

One worker already moves about 15,000 messages per second, and five get to about 23,000. The WAL reader leads at about 31,000, and it reached about 57,600 without the UPDATE. Both move thousands of messages per second, so throughput alone isn't a reason to switch.

Latency is the real difference. New messages wait for a worker's one-second sleep, so five workers average 419 ms at 100 orders per second, while the reader stays under a millisecond. At 100 users, one worker fell 8.5 seconds behind, five workers averaged 54 to 85 ms, and the reader held 8.6 ms.

A crash goes the other way. A hard kill partway through 200,000 rows lost nothing, but the workers sent 4,536 duplicates and the WAL reader 31,095, because it replays from its last confirmed position.

Workers also scale out, because you can add more in any process. A slot has one reader, which keeps commit order, but I can't scale it out.

Summary

Keep polling if the delay is acceptable for your application. Add workers when you need more throughput, because the row locks already handle the concurrency.

Read the WAL if you need new messages right away and can run a replication slot and a cleanup job. If you use NOTIFY instead, send it after the commit and keep a fallback poll.

A worker can still crash after publishing but before committing its processed markers, causing a message to be sent again. Consumers must be idempotent: processing the same message twice must not repeat its effects.

Thanks for reading.

And stay awesome!


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Catch the import. Name the culprit. Keep threads free: Introducing gilguard

1 Share

Catch the import. Name the culprit. Keep threads free: gilguard

TL;DR: gilguard is a tiny, zero-dependency package for free-threaded Python (3.13t, 3.14t, 3.15t). Import it first. If any later import quietly turns the GIL back on, you get an error naming the extension module, the package that shipped it, and the line of your code that pulled it in. python -m gilguard audits an entire environment in one go. It’s on PyPI now, and it’s the second piece of a larger free-threaded Python effort I’ve been working on.

The quiet failure mode of free-threaded Python

Free-threaded Python is officially supported as of 3.14, and I’m all in. Threads that actually run Python code in parallel? Yes please. But the migration has a failure mode that I think is going to bite a lot of teams, and there isn’t much written about it.

Here’s the scenario. You move a service to 3.14t. You give the hot path a thread pool. You deploy, pull up the dashboard, and the throughput graph does… nothing. It’s the exact same shape as last week, as if the whole migration had been a dream.

An hour later you find the reason, one line in a startup log that scrolled past in half a second:

RuntimeWarning: The global interpreter lock (GIL) has 
been enabled to load module 'somepackage._speedups', 
which has not declared that it can run safely without the GIL.

That line is CPython being careful. Every C extension has to declare that it’s safe to run without the GIL (via the Py_mod_gil slot). When the interpreter loads one that hasn’t, it turns the GIL back on for the rest of the process and carries on. Your threads still run, they just take turns again. And here’s the kicker: once the GIL is on, nothing can turn it back off for the life of that process.

The warning names a private module you’ve never heard of. It doesn’t tell you which package you installed shipped it, or which of your imports dragged it in. So now you’re bisecting imports.

What is gilguard?

gilguard turns that one line into an exception, raised at the import statement that caused it. Make it the first import in your program and you’re done. You don’t call anything or configure anything:

import gilguard  # must be first

import fastapi
import pandas  # <- raises here if anything in pandas' import tree needs the GIL

When something in that tree forces the GIL back on, this is what you see instead of a warning you’d miss:

gilguard.GILEnabledError: Importing 'gilneeder._speedups' re-enabled the GIL.

  Module:       gilneeder._speedups
  File:         .../site-packages/gilneeder/_speedups.cpython-314t-x86_64-linux-gnu.so
  Distribution: gilneeder 1.2.0
  Import chain: gilneeder -> gilneeder._speedups
  Your code:    /home/me/app.py:5
  Imported by:  .../site-packages/gilneeder/__init__.py:1

This extension module does not declare free-threading 
support (Py_mod_gil), so CPython turned the GIL back 
on for the rest of the process. It cannot be turned off again.

Options:
  - Upgrade gilneeder to a release that ships free-threaded (cp314t) wheels.
  - Drop or replace gilneeder.
  - If you have verified it is thread-safe, run with PYTHON_GIL=0 to keep the GIL off (at your own risk).
  - Run `python -m gilguard` to list every installed package that does this.

(gilneeder is one of gilguard’s test fixtures, a tiny C extension built to misbehave so the real ones don’t have to.)

Everything you’d otherwise be asking a debugger for is right there: which module flipped it, what file it lives in, and which distribution and version shipped it (so you know what to upgrade or report). You also get the import chain from your code down to the culprit, which matters when the offender is a dependency of a dependency of something you installed for one function, and the line in your code where it all started.

You might notice that GILEnabledError derives from BaseException rather than Exception, putting it alongside KeyboardInterrupt. Here’s why. Lots of packages have an optional speedup import like try: import fastthing / except ImportError: import slowthing. If gilguard raised a normal exception, that except would eat it, the package would quietly fall back to its pure-Python path, and your app would carry on with the GIL already back on. The report would end up inside someone else’s except block, where nobody would ever see it. With BaseException, it sails right past those handlers. To catch it, you have to ask for GILEnabledError by name (or use a bare except:, and you know better).

Not ready to fail hard? Set GILGUARD_ACTION=warn and you get the same report as a warning while the program keeps running. Set it to off and the same code runs on a standard build.

How do I find every offender in an environment?

A single process can only tell you about the first module that flips the GIL. After that it’s already on, and the rest have nothing left to flip. So gilguard also ships a scanner:

python -m gilguard
GIL    gilneeder                via gilneeder._speedups  [gilneeder 1.2.0]

8 checked: 7 ok, 1 re-enable the GIL, 0 failed to import.

It gives every installed package its own fresh interpreter (in parallel, across your CPUs), so none of them can hide behind the one that went first. It exits 1 when it finds anything, so it drops into CI as a single step without any extra scripting. There’s --json for tooling and --strict if a package that fails to import should fail the build too. Pass package names to check just those, which is how you re-check one after an upgrade to see if the fix took.

The scan has one blind spot: extensions a package loads lazily, on first use of a feature, don’t show up at import time. For those, run your test suite with gilguard loaded as a plugin:

pytest -p gilguard

pytest loads -p plugins before it touches conftest.py or any test module, so the guard is watching before your code imports anything. The two checks cover different gaps. The scanner sees every installed package but only at import time, and the test suite sees lazy loads but only on the code paths your tests run. Use both. Tests and CI has a GitHub Actions job that does exactly that.

What does a clean run actually mean?

“The GIL stayed off” is easy to over-read. Here are the limits. A clean run means none of the imports that actually ran turned the GIL back on. It does not mean your code or your dependencies are thread-safe, and it does not mean your program gets faster with more threads. Those are separate problems with their own tests. gilguard catches one specific failure, and that’s all it tries to do.

Once you have a name, the docs have a whole page on what to do with it: upgrade, report upstream (with exactly which lines to paste into the issue), replace, or, if the extension is yours, the one slot that declares support, with the one-line equivalents for Cython, pybind11, and PyO3.

Why I built this

When I announced chameleon-rs ten days ago, I said free-threaded Python means we need to start expecting more from our web apps. What I didn’t say is that chameleon-rs was the first piece of a larger free-threaded effort, and just the first one I am able to talk about publicly. gilguard is the second.

It’s a much smaller piece, a few hundred lines of plain Python with no dependencies. But it’s the kind of building block everything else depends on. There’s no point making a template engine or a web framework thread-safe and fast if one dependency turned the lock back on at startup and nobody noticed for a month. Before you can make free-threaded Python fast, you have to be able to trust that you’re actually running free-threaded.

My goal with all of this work is simple to state: free-threaded Python faster, safer, better, and adopted sooner. gilguard is my contribution to the “safer” and “sooner” parts. I’ll write about the rest as soon as I’m able to.

Try it

uv pip install gilguard

Then import gilguard at the top of your entry point, or run python -m gilguard against your current environment and see what’s lurking. I’d love to hear what it finds. The docs are short and the code is on GitHub. If you use an AI coding agent, the docs also ship an agent skill that teaches it the rules (first import, don’t catch the error, what a pass means), so it can wire gilguard into your project and CI without you explaining any of this.

Read the whole story
alvinashcraft
2 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Working with designers

1 Share

I love working with designers, in part because (unlike managers and product managers) they’re culturally different from engineers. However, having more than one designer on a team is asking for trouble, and I have complicated negative thoughts about design systems.

Design is a strange role

Designers demonstrate their value immediately. While working on some feature, I’ll typically put together some placeholder UI that I’m reasonably happy with. I then show it to a designer, who strokes their chin and says “hmm, I have some ideas here”. They then go away and produce a mockup UI that is not just clearly better, but better in ways I could not have imagined. There aren’t any other roles at a tech company where you can see the value at a glance.

Designers are an unusual role in other ways, too. Engineering managers, product managers, and engineers all come from broadly the same stock: technical, detail-oriented planners. We are people of the spreadsheet. In fact, many managers and product managers were once engineers: it’s a natural transition. Not so for designers. I’m sure they exist, but I’ve never met any designers who started out as engineers.

Because of this, designers are culturally distant from engineers. In my experience, this is a big positive. I’ve complained before that product managers who were once engineers tend to be worse, not better. Once you start trying to make your own secret technical assessments instead of finding a way to trust your engineering team, you’re doomed: you won’t be able to do it well enough, and the fact that you’re trying will make it impossible to build the trust you need. Designers don’t have this problem at all1.

One designer at a time

So far I have made designers sound like the elves of Middle-earth: mysterious creatures who glide around tech companies dispensing magic. In fact, they are more like the Slavic household spirits, or Domovoy. If you have one Domovoy in a household, it will protect your home against misfortune. If you ever have more than one, they will fight bitterly: “making all sorts of noises, injuring the cattle, turning the master out of his bed, choking people while asleep, etc”. Likewise, a designer can turn your scrappy product into something really beautiful — but you had better have only one designer, otherwise you’re asking for trouble.

The worst experience I have ever had working with designers was on a product where we had three of them: initially just one, who then rotated off the project and was replaced by two very senior designers. As far as I could tell, the first design was pretty good. Unfortunately, the new designers didn’t feel the same way. The very first thing they did was completely redesign the product, which meant I had to rewrite most of the frontend styles. Then they began disagreeing with each other. I think we went back on each page of the product three or four times: one designer would tell me to change X, then the other would change it back, and so on. In the meantime, I was desperately trying to get the product to work.

I knew what I was supposed to do in theory: get everyone in a room talking to each other and hash out a decision. Maybe this would have worked on a different product where the requirements were more stable, but it didn’t work here. The differences in taste, while imperceptible to me, were just too deep. It seemed like everything Designer A produced was slightly wrong in Designer B’s eyes, and vice versa. In the end we just powered through by implementing2 each new iteration until about a week before the deadline, at which point I called in two layers of management as air cover3 to freeze the design in its current state.

These were really good designers! They were far, far better than me at design, and were very nice people who I’d happily work with again. I just think it’s inherently bad to work with more than one designer at a time. I’ve had this experience over and over on different teams and companies. I can only guess4 as to why, but here are two theories:

  • Engineering disagreements can pivot on concrete measures of quality like latency, bugs, lines of code, and so on, while designers must rely only on taste
  • Design changes anywhere affect the whole product, because users experience the product as a single design, while many engineering choices are invisible to the user (and so can be safely inconsistent)

Flexibility and design systems

One way companies try to scale design work is to produce a “design system”: a library of frontend components that are all design-compliant, that can in theory be assembled like Legos into a page that looks consistent with the rest of the company. I hate design systems. However, like democracy, they’re better than any other way I’ve seen to enforce a consistent design.

The first problem with design systems is one of incentives. The engineering team that owns the design system5 is incentivized to produce elegant components that will look beautiful all the time. The engineering teams that use the design system are incentivized to produce systems that meet inelegant or ugly customer requirements. So you have this permanent battle where a product team demands something — say, the ability to embed arbitrary images into the dropdown component — and the design team pushes back because they’re worried it will look bad.

The dynamic I described above (where designers tend to disagree with each other) makes this much worse. Often an embedded designer on the engineering team will push for some design that is slightly different from the design system, which (a) makes the design system owners very unhappy, and (b) makes the engineers unhappy, because the component must be tortured into a very slightly different appearance.

The result of this problem is that engineering teams are perpetually hacking their way around the design system: reimplementing their own versions of components, reaching in with CSS to tweak the styles of existing components (which then get broken in each component update), and so on.

This leads into the second problem: compatibility. Design systems are typically written in the latest and greatest frontend framework, but the actual frontend code at a company is always a hodge-podge of various technologies and versions that are too expensive and risky to update. For instance, you often have a design system in React that is being used to plan changes to a frontend in pure HTML and CSS6. I have spent years of my life wrestling with this exact problem: either you spend ages trying to reimplement some percentage of the React component, or you try and use the outdated pure-CSS design system (if one exists), or you give up and just embed a React component directly into the HTML. All of these are very unpleasant for different reasons.

One common situation is that the version of the design system available to you (i.e. the pure-CSS version, or the React 16 version) looks subtly different from the design system available to your designer, and so when you plug your Legos together you don’t quite get what they were visualizing. This leads to a very tedious conversation where you have to explain that no, it’s not actually trivial to bump the entire app to the latest React version7. When you’re actually implementing the app, you have to constantly run a kind of translation in your head: “okay, the designer wants dropdown feature A, but the dropdowns in my version of the design system only offer features B and C, so I guess C is close enough…”

I still think design systems are better than the alternatives. When you’re up-to-date and don’t have a designer who wants anything weird, they work great. Ensuring that a thousand engineers across a giant application all produce consistent UI is a very hard problem and I don’t know any other way to solve it. I just wish that the designers I worked with were more considerate of the fact that design systems often make the immediate work of engineering more difficult.

Do you actually need designers?

The classic three-legged stool of product development is made up of engineering, product management, and design. Design is definitely the shorter leg. Almost every team I’ve worked on has had some kind of embedded product management, but only about half the teams I’ve worked on8 have had some access to design (and even fewer have had an embedded designer on the team). Why is that?

Partly it’s because there are products that don’t require design, or at least not in the visual sense that designers provide. Some of the teams I’ve worked on have owned systems with no real visual component: APIs, billing and reconciliation, markdown or pdf rendering9. I have seen companies put designers on these teams anyway, out of some sense that “design thinking” can improve the structure of an API. This is nonsense. Good API design is very important, but it’s a technical job, not an aesthetic one. Designers on these teams typically just sit around or tunnel-vision on some unimportant piece of UI that the team does own (e.g. some internal admin component that no customer will ever see).

It’s also because badly designed products still work. I don’t think Netlify Analytics is well-designed: it’s awkward to use and does not show me information it definitely has. But I still pay for it, because I want server-side analytics for my blog. I don’t think many people have complimented the aesthetics of the Microsoft Azure admin portal, but Azure broke $100B of revenue this year. There are very few software products where design is truly business-critical.

As an engineer, I selfishly wish I could work with a designer all the time. I want to work on beautiful products, and I can’t make them beautiful myself.


  1. This is partly structural. Because they’re not responsible for delivery, they just aren’t under the same pressure as product managers and managers.

    ↩
  2. In fairness, it helped that both designers were technical enough to write their own frontend PRs, though these usually needed some polishing and deploying.

    ↩
  3. This didn’t really work. While there were no major redesigns after that point, we were shipping design changes until the day before launch.

    ↩
  4. Incidentally, if you’re a designer reading this, please email me! I’d love to know if this sounds right to you, and if so whether you have theories as to why.

    ↩
  5. The culture on these teams tends to be a bit unusual as well: you get the subset of frontend engineers who are obsessed with general frontend software design instead of specific products. It’s like a whole group made up of the one guy in your team who is really into Haskell.

    ↩
  6. Or in Angular, or in a different version of React.

    ↩
  7. Sometimes because it’d break all the little hacks to the design system that your designer has strong-armed you into doing in the past.

    ↩
  8. I did some very loose vibe research which estimated that Microsoft/Google/Amazon has 3/10/7 designers per 100 engineers, compared to 7/7/9 product managers.

    ↩
  9. This sounds like it’d have a visual component but it’s not the kind that requires design: sandboxing a pdf or turning markdown into HTML is a technical operation that happens pre-design. The team that owns the page where that pdf or HTML is rendered is the team that makes design decisions about how it should look.

    ↩
Read the whole story
alvinashcraft
2 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories
