Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162138 stories
·
33 followers

Android Central ‘will continue’ despite laying off its staff

1 Share

Android Central, a blog focused on the Android ecosystem, laid off its staff yesterday, but owner Future confirms to The Verge that the site will continue publishing.

Yesterday, four of the six staffers on Android Central's staff page posted publicly about the layoffs, including Shruti Shekar, Derrek Lee, Harish Jonnalagadda, and Nicholas Sutrich, and former senior editor Namerah Saud Fatmi updated her LinkedIn to indicate that her tenure at Android Central had ended. Both Lee, the site's managing editor, and Sutrich confirmed that all remaining staff were laid off.

The former staffers weren't told whether the site would shut down. Today, …

Read the full story at The Verge.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Inside Microsoft’s big Copilot rethink

1 Share

Last week, Microsoft CEO Satya Nadella hosted an intimate, invite-only event for leaders from some of its key enterprise customers. Instead of a flashy media event, Nadella outlined the future of Copilot directly to the customers Microsoft really cares about, pitching its latest rethink of the AI assistant as the "OS for work."

Microsoft is adding coding and agent capabilities directly into Copilot, as well as bringing the full power of Office into Copilot for the first time. Nadella is betting that AI will change the way people work in the same way that Microsoft Office did in the '80s and '90s.

"How did a multinational company do a fore …

Read the full story at The Verge.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Trust Docker for the agents you don’t

1 Share

Cloud Sandboxes, open Kits, and a developer community building the next generation of AI software

Docker Cloud Sandboxes are here. At WeAreDevelopers World Congress North America, we launched a way for developers to start agent work in a safe way on their laptop, move to the same microVM environment on Docker-managed cloud compute, and bring the results back. Longer tasks can keep running, even after you close your laptop. 

That launch reflects a bigger ambition. We want developers to be able to give agents useful work with confidence in the systems around them. That means a place for the agent to run, clear limits on what it can access, and a way to inspect what happened. It also means keeping the freedom to choose the agent and model that fit the job.

We brought that message to San Jose with Cloud Sandboxes, the open Sandbox Kit specification, and a commitment to bring the spec to the Cloud Native Computing Foundation (CNCF). Three mainstage talks explored what trust requires in practice. Four workshops gave developers time with the tools. Across the Docker Pavilion and booth, customers, partners, and community members brought their own experience and questions into the discussion.

A year after announcing our partnership to bring WeAreDevelopers to North America, it was exciting to join more than 10,000 developers, AI builders, and technology leaders at the inaugural event, September 23-25. Here is what we shared, and where developers can get started.

Introducing Docker Cloud Sandboxes

An agent working through a large refactor or migration may need more time than you want to keep a laptop open. Running several tasks at once can put pressure on local resources, too. Cloud Sandboxes gives those tasks somewhere else to run.

Each sandbox is an isolated microVM, a small virtual machine with its own kernel and Docker daemon. The agent can install dependencies, build applications, and run containers inside that environment. With Cloud Sandboxes, Docker supplies the compute, and developers use sbx, the same command-line tool they use for local sandboxes.

The workflow starts wherever the developer needs it to. Begin locally, move the sandbox’s filesystem to the cloud for a longer run, and bring it back when it is time to review the results. The same reusable agent packages, called Kits, work in both environments. Local and cloud credentials and policies are configured separately, so the access granted in each environment remains an explicit decision.

Cloud Sandboxes are available now, with compute billed by the second. For developers, that opens up a useful choice: keep interactive work on the laptop and give longer agent tasks their own capacity. It makes the move from local experimentation to sustained agent work a practical part of the development workflow.

The foundation for trusting agents with more work

In his opening keynote, Docker President and COO Mark Cavage explained why giving agents more freedom also requires a stronger foundation. He described four requirements for an agent factory: containment, control, choice, and capacity. Teams need to know where agents can act, see and stop their activity, choose their models and tools, and run work beyond a single laptop.

The keynote included a clear example of what can go wrong. An agent running in a container with the host Docker socket mounted found a way to read a secret on the host. It had not discovered a new vulnerability. It was using access the configuration had given it.

Docker Sandboxes puts a microVM boundary around the agent. In a subsequent demonstration, the same attempt to reach the host through the Docker socket failed inside the sandbox. Containers still do the job of packaging and running applications; the sandbox gives the agent building those applications an execution boundary of its own.

This is what we mean by trust Docker for the agents you don’t. The infrastructure enforces the boundary, even when an agent chooses an unexpected course of action. Developers can decide how much access to grant and retain responsibility for the work that ships.

Cavage also addressed the limits of those controls. Blocking an unapproved network destination is different from recognizing that an otherwise permitted email is going to the wrong customer. Narrow permissions, such as allowing an agent to read and draft messages without letting it send them, remain an essential part of using agents responsibly. There is still work to do on whether an action matches the user’s intent, and we should be clear about that.

Open Kits for environments teams can share

Once an agent has a place to run, the next question is what belongs in that environment. Which tools does it need? Which services may it reach? What credentials and storage should be available?

The new Docker Sandbox Kit specification puts those requirements in an artifact teams can share and review. A Kit is an OCI image containing the agent and its tools, together with declarations of the access it needs. It works with familiar image tooling: teams can build, push, pull, scan, and pin it by digest.

That makes an environment easier to reproduce, and it makes changes to its requested permissions visible. If a Kit asks for another network destination or credential, reviewers can see that change alongside the rest of the package. The runtime decides which requests to grant and enforces the resulting policy outside the agent.

We published the specification under Apache 2.0 and committed to bringing it to the CNCF for neutral governance. Docker Sandboxes is the first runtime to implement it. Opening the format gives other runtimes a specification they can adopt and developers a common way to describe an agent environment.

Nous Research joined Cavage onstage with Hermes, its open-source agent, as a launch partner. Packaging an independently developed agent as a Kit demonstrated the choice we want developers to have: use the agent that fits the work, with an environment and controls the team can understand.

Governing agents across the organization

Docker CTO Tushar Jain’s keynote, “Govern the Runtime, Not the Agent,” took the discussion to the team level. Organizations use different models and agent tools. Governing each tool separately makes it harder to maintain a consistent policy and see the full picture of agent activity.

Tushar made the case for a common runtime layer that can govern execution, tools, credentials, permissions, and spend. His demo supplied a concrete example: an agent’s request to delete a GitHub repository was blocked by a default-deny rule and returned HTTP 403. Enforcement came from the runtime. In the Q&A, he described team-specific policies that can give a finance user and a developer different access to the same agent, while acknowledging that agent identity remains an open industry challenge.

Docker CISO Mark Lechner connected those ideas to security in his keynote, “One Boundary for the Agentic Era”. His talk connected those runtime controls to the software supply chain. An agent consumes dependencies and tools, then creates code that a team has to review and ship. Lechner showed how a Kit manifest describes the agent’s requested access, and how a proxy can use a credential without exposing the raw API key inside the sandbox.

Managing those capabilities as code gives security teams something concrete to review. They can inspect the environment an agent receives and compare its permissions with the activity recorded during a task. Across the three talks, the common goal was to make greater agent autonomy something teams can govern.

Building with our customers, partners, and community

The Docker Pavilion kept the discussion going across Thursday and Friday, with customers, partners, and Docker engineers sharing how these ideas apply to real systems. A field-notes panel compared lessons from rolling out sandboxed agents to thousands of developers. Our engineers took questions about Sandboxes and AI Governance. A panel with Spectro Cloud and J.P. Morgan Payments asked what it takes to own how AI is deployed and governed, beyond simply consuming more tokens.

The customer and partner sessions covered several parts of the agent workflow:

• Running real workloads. Spectro Cloud showed repeatable agent workloads at the edge. J.P. Morgan Payments brought a two-container payments example that starts with docker compose up. ClickHouse showed what changes when a database starts from a hardened image, and BAND demonstrated separately sandboxed agents exchanging work.

• Controlling access and investigating activity. Palo Alto Networks connected agent audit records to investigation, while Datadog followed a security incident from detection to response. Prediction Guard demonstrated model-call controls alongside execution isolation, and Snyk showed how to inspect work inside a sandbox. GitGuardian, Mend, and Merge covered secrets, runtime guardrails, and third-party integrations.

• Providing context and reviewing results. Box, Cognee, and SurrealDB explored giving agents useful knowledge and memory with visible limits. Chainloop brought signed records to the review process, and Sonar showed how to verify generated code.

These sessions showed how the sandbox fits into a wider system of tools for running agents, protecting their access, and checking their work.

Eli Aleyner and Kelsey Hightower also sat down for a fireside chat at the Pavilion, bringing the cloud-native community into the program alongside customers, partners, and Docker engineers. The platform and security roundtables gave smaller groups space to compare what they were seeing in their own organizations.

Four workshops to get hands-on

On Wednesday, September 23, our stage and workshop program gave developers time to work with the tools themselves. All four workshops connected the larger message to practical development tasks:

• Dan Ndombe introduced Docker’s sbx command for running agents in isolated sandboxes, then worked through network rules, tools connected through Model Context Protocol (MCP), and packaging agent workflows with Kits.

• Michael Irwin built an AI-ready developer environment with Kits and sbxenv files, which describe a set of sandbox environments as configuration.

• Oleg Šelajev connected Sandboxes, MCP, and the infrastructure beneath agent workflows in a hands-on agentic platform workshop.

• Ajeet Raina focused on Docker Hardened Images and supply chain security when agents write the code.

The shorter talks connected those pieces to ordinary development work. Michael showed how to make an agent environment work across machines. Ajeet and Docker Captain Kristiyan Velkov covered Docker tools developers may have missed, including Testcontainers and Scout. Other sessions examined giving an agent its own machine and verifying the components agents put into a software build.

Demos and conversations at the Docker booth

There was plenty to explore at the Docker booth, where a steady stream of visitors could see the tools working and talk with the team. In the coding factory demo, an agent worked on a Next.js app inside its own microVM, built and served the application, and encountered a network destination blocked by organization policy. The audit view recorded the policy decision, letting visitors follow the agent’s work and see where a rule had been enforced. The demonstration connected the infrastructure controls to a familiar result: a working application developers could inspect.

The booth also hosted Sandbox Royale, an AI game challenge that invited visitors to connect agents through Model Context Protocol (MCP) and compete in a shared virtual town. Agents negotiated, traded fictional assets, and navigated a trust dilemma in fifteen-minute games with a live leaderboard. It was a lively way to explore how agents behave when they interact with other agents and untrusted input.

The steady booth traffic, demonstrations, and conversations gave our team opportunities to hear directly from developers about the work they want agents to take on.

Build with us

We came to WeAreDevelopers with a clear direction for Docker’s work in AI: make agents easier to run, make their access visible and controllable, and give developers the tools to build with them on their own terms. Cloud Sandboxes and the open Kit specification are concrete steps in that direction.

The conference gave us the chance to put that work in front of developers alongside the partners and community helping shape it. Thank you to everyone who spent time with us in San Jose. We are looking forward to seeing what you build next.

Try Docker Cloud Sandboxes, start locally with Docker Sandboxes, or explore and contribute to the Sandbox Kit specification.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete

How to Track Every API Your Organization Owns with API Catalog

1 Share

Ask most engineering leaders how many APIs their organization runs, and you’ll get an estimate, not an answer. Teams spin up services independently, specs live scattered across repos, test results sit in whichever CI tool a given team happens to adopt, and production health lives in a separate observability stack entirely. By the time an incident happens or an audit comes around, “who owns this API and is it actually healthy?” turns into a multi-team Slack thread instead of a five-second lookup.

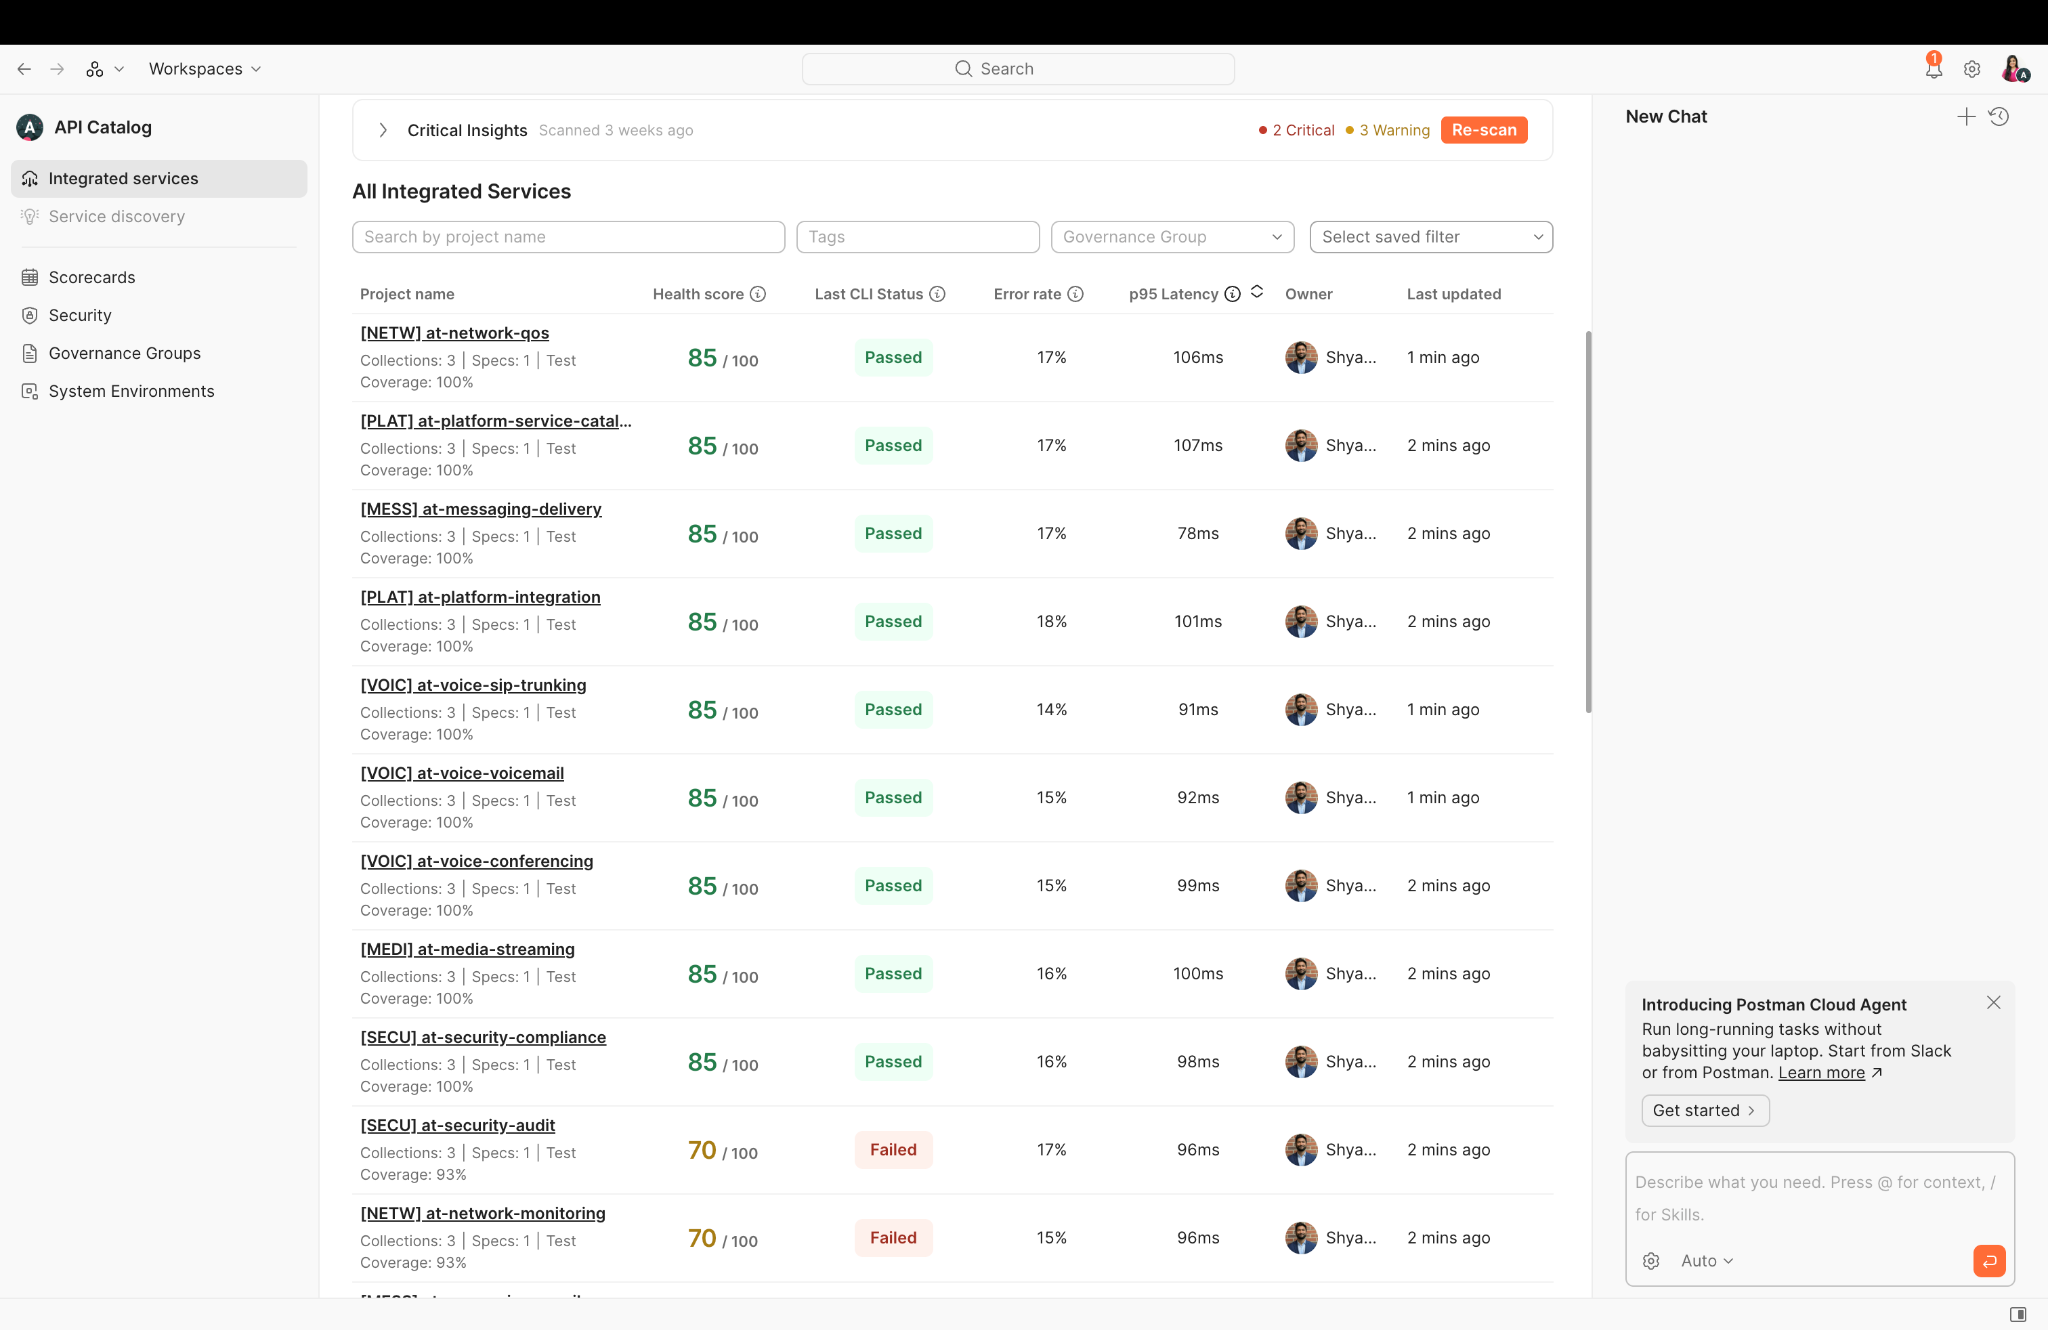
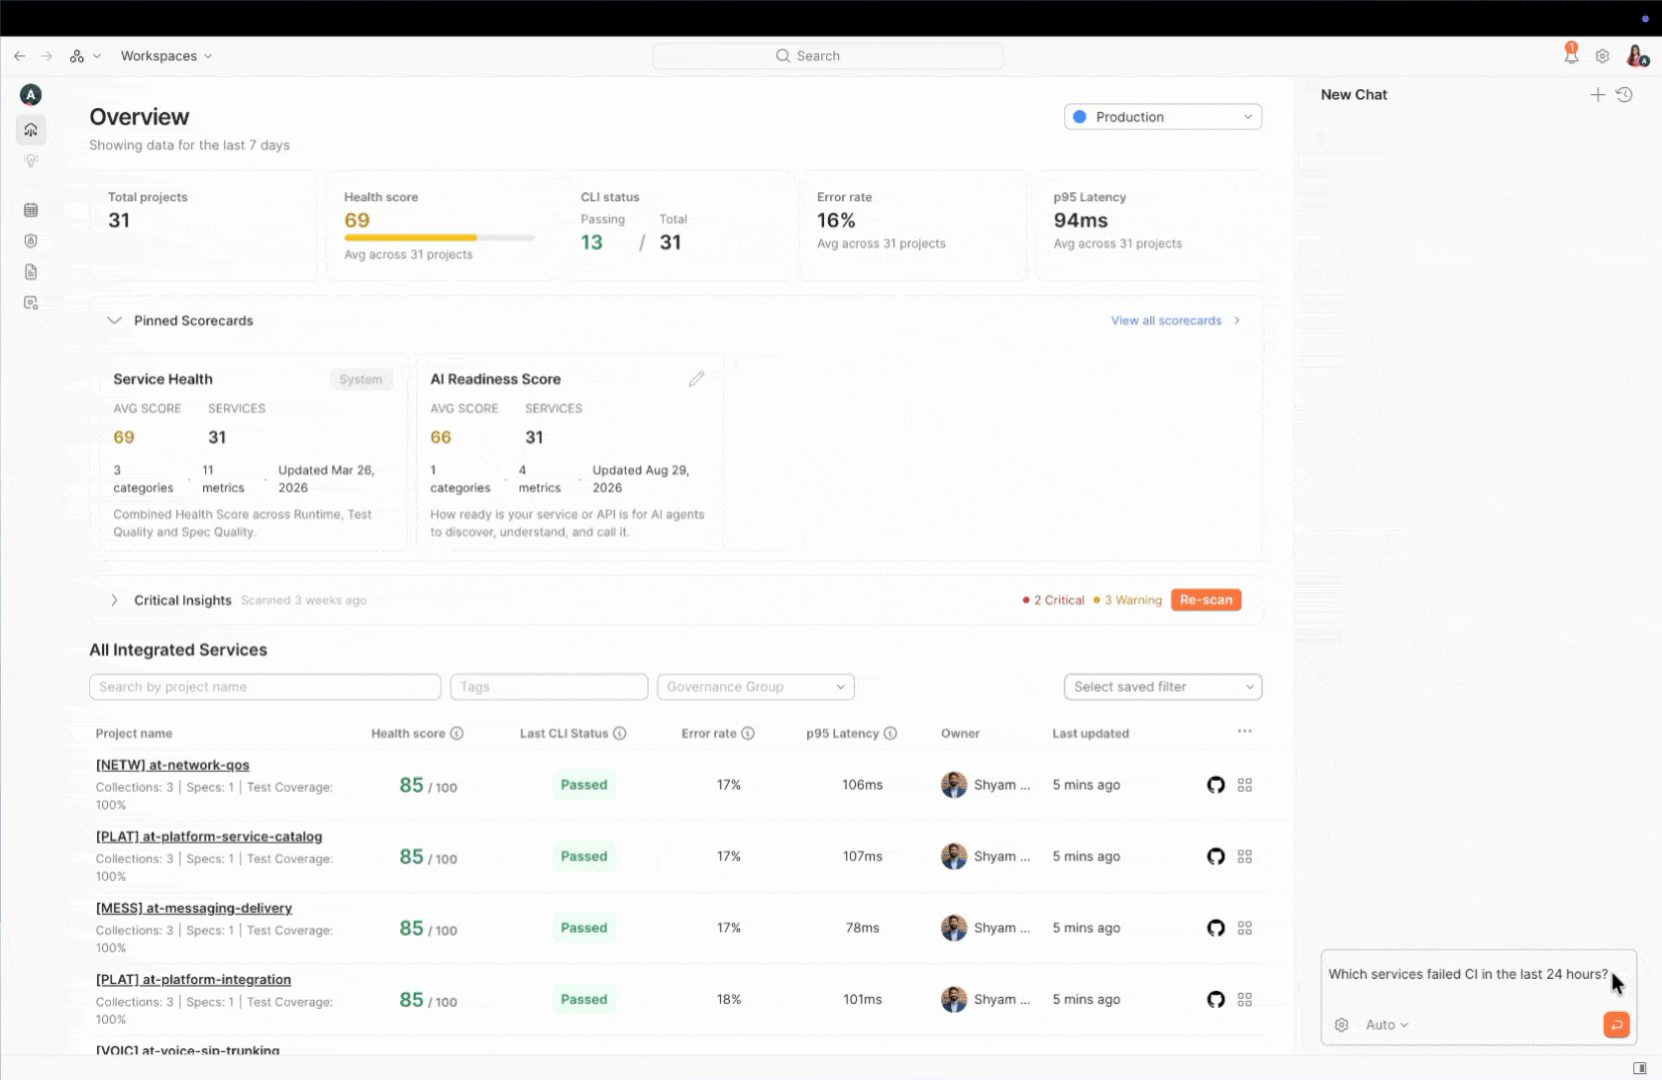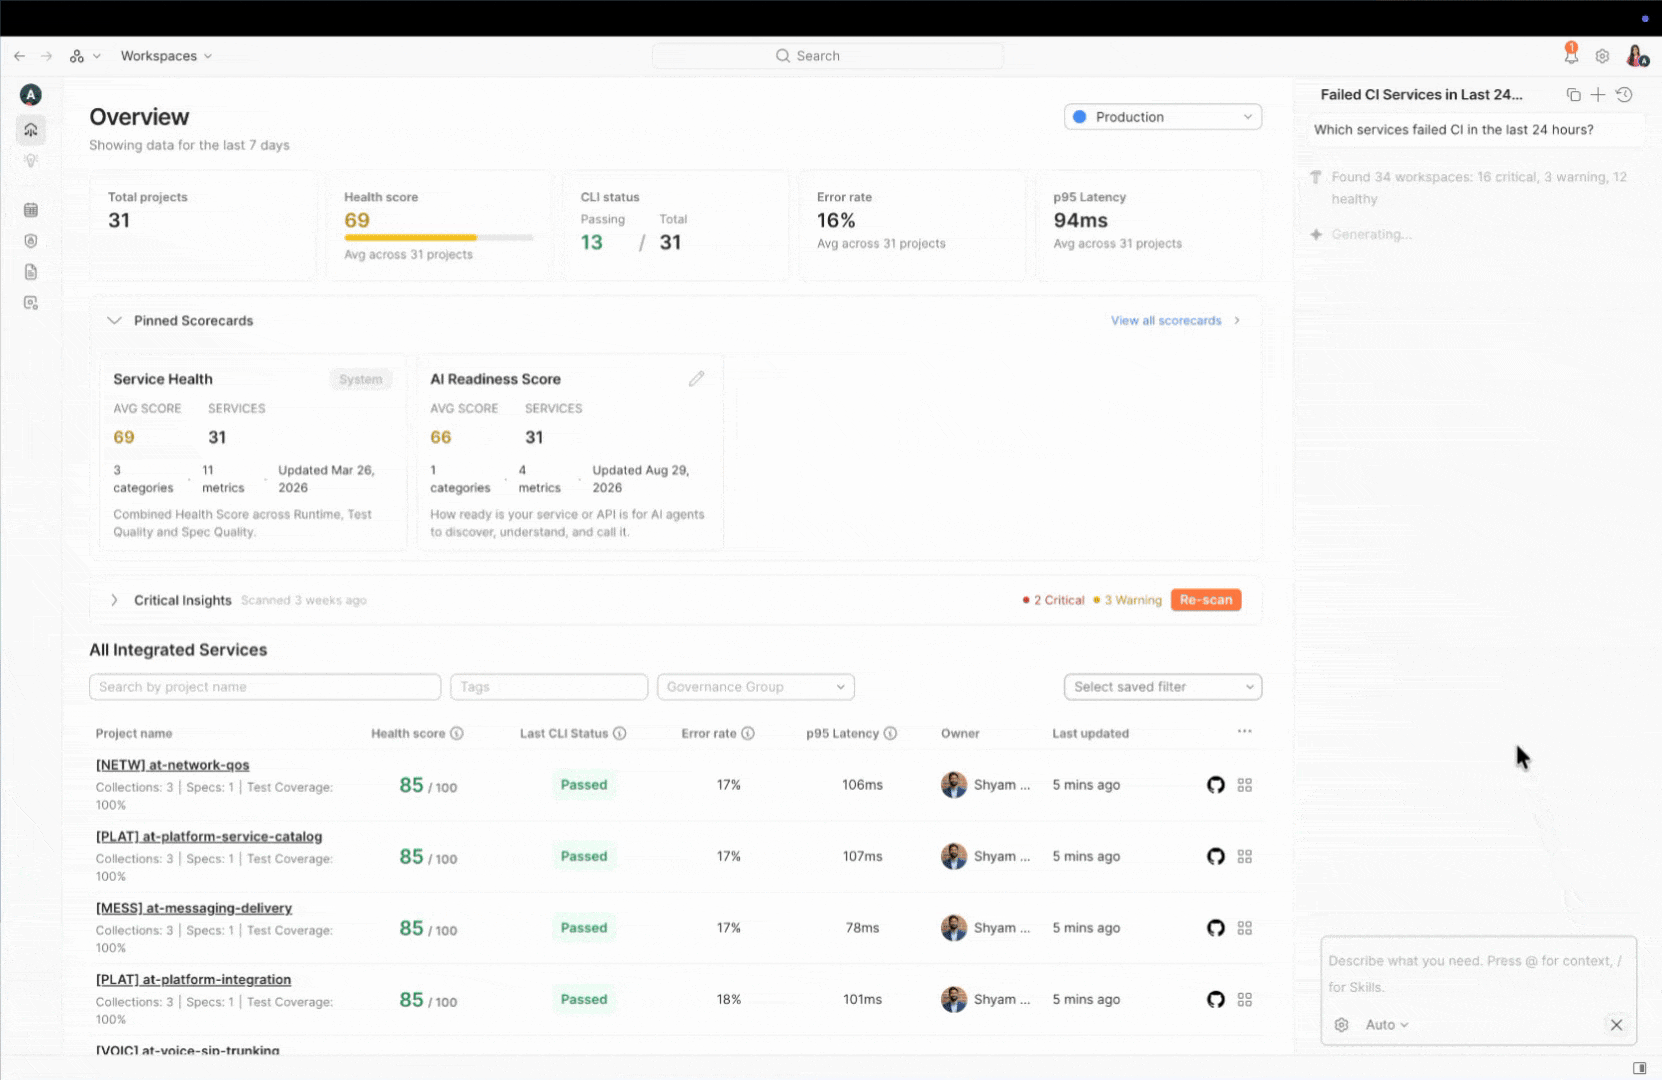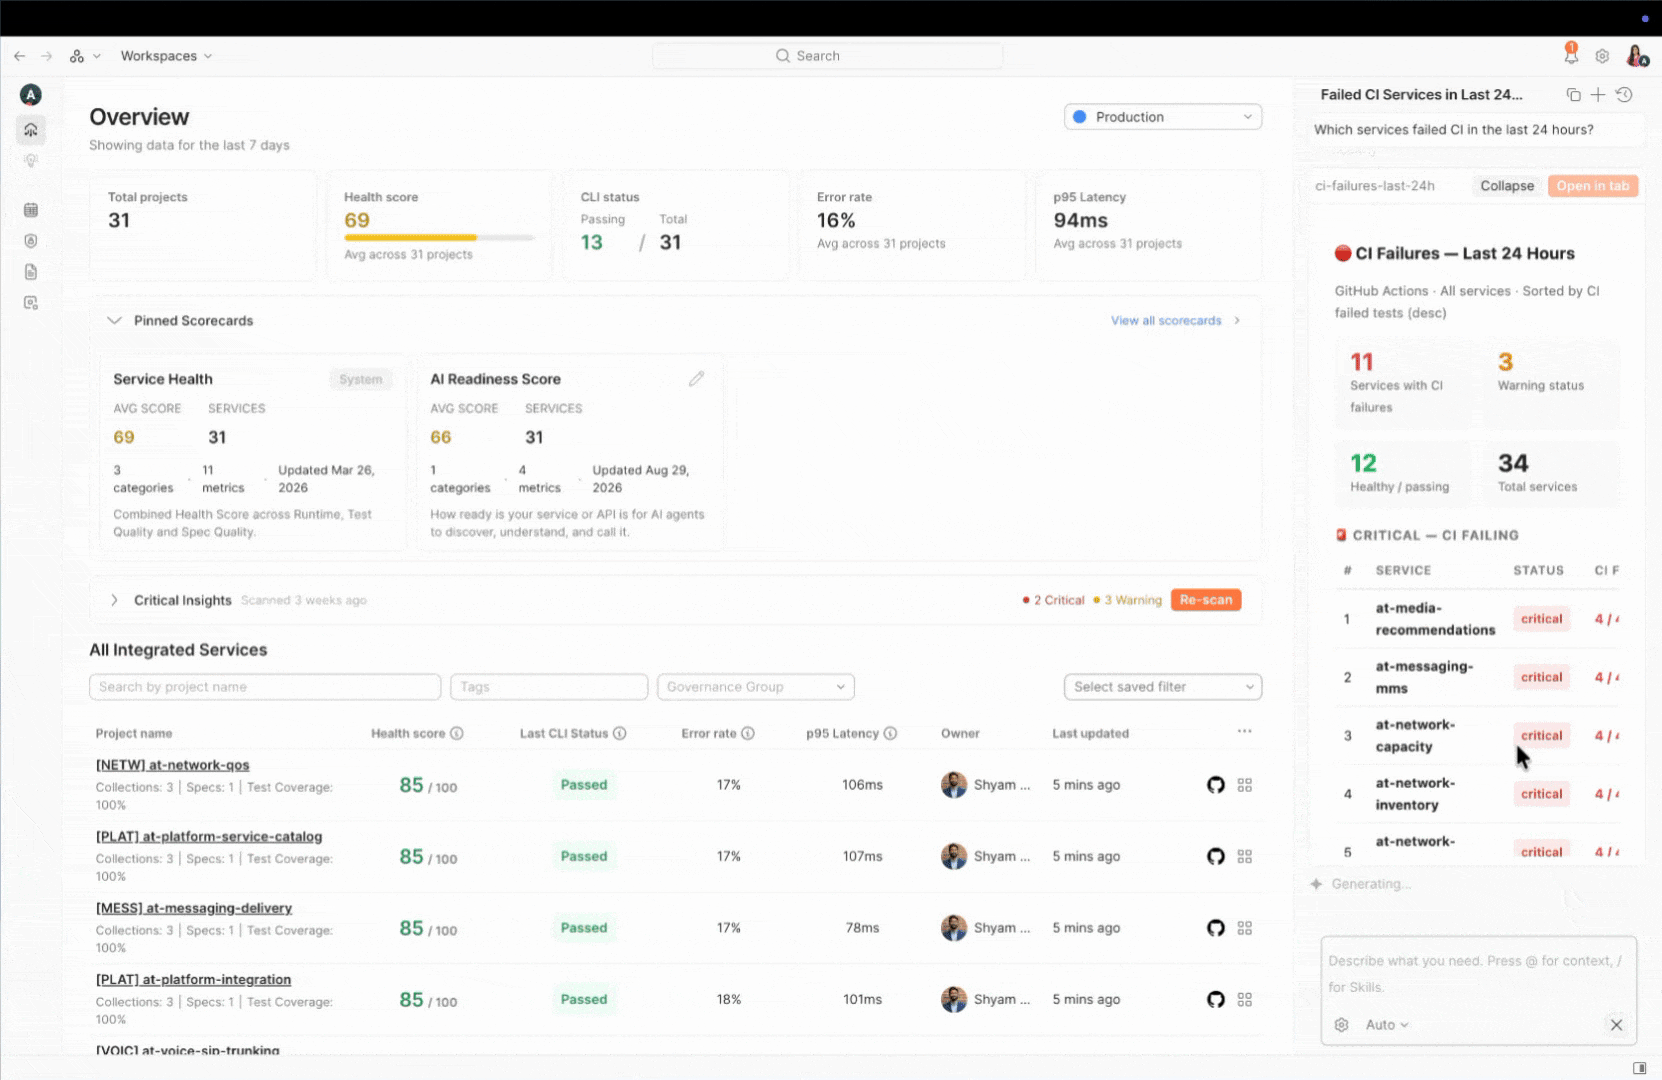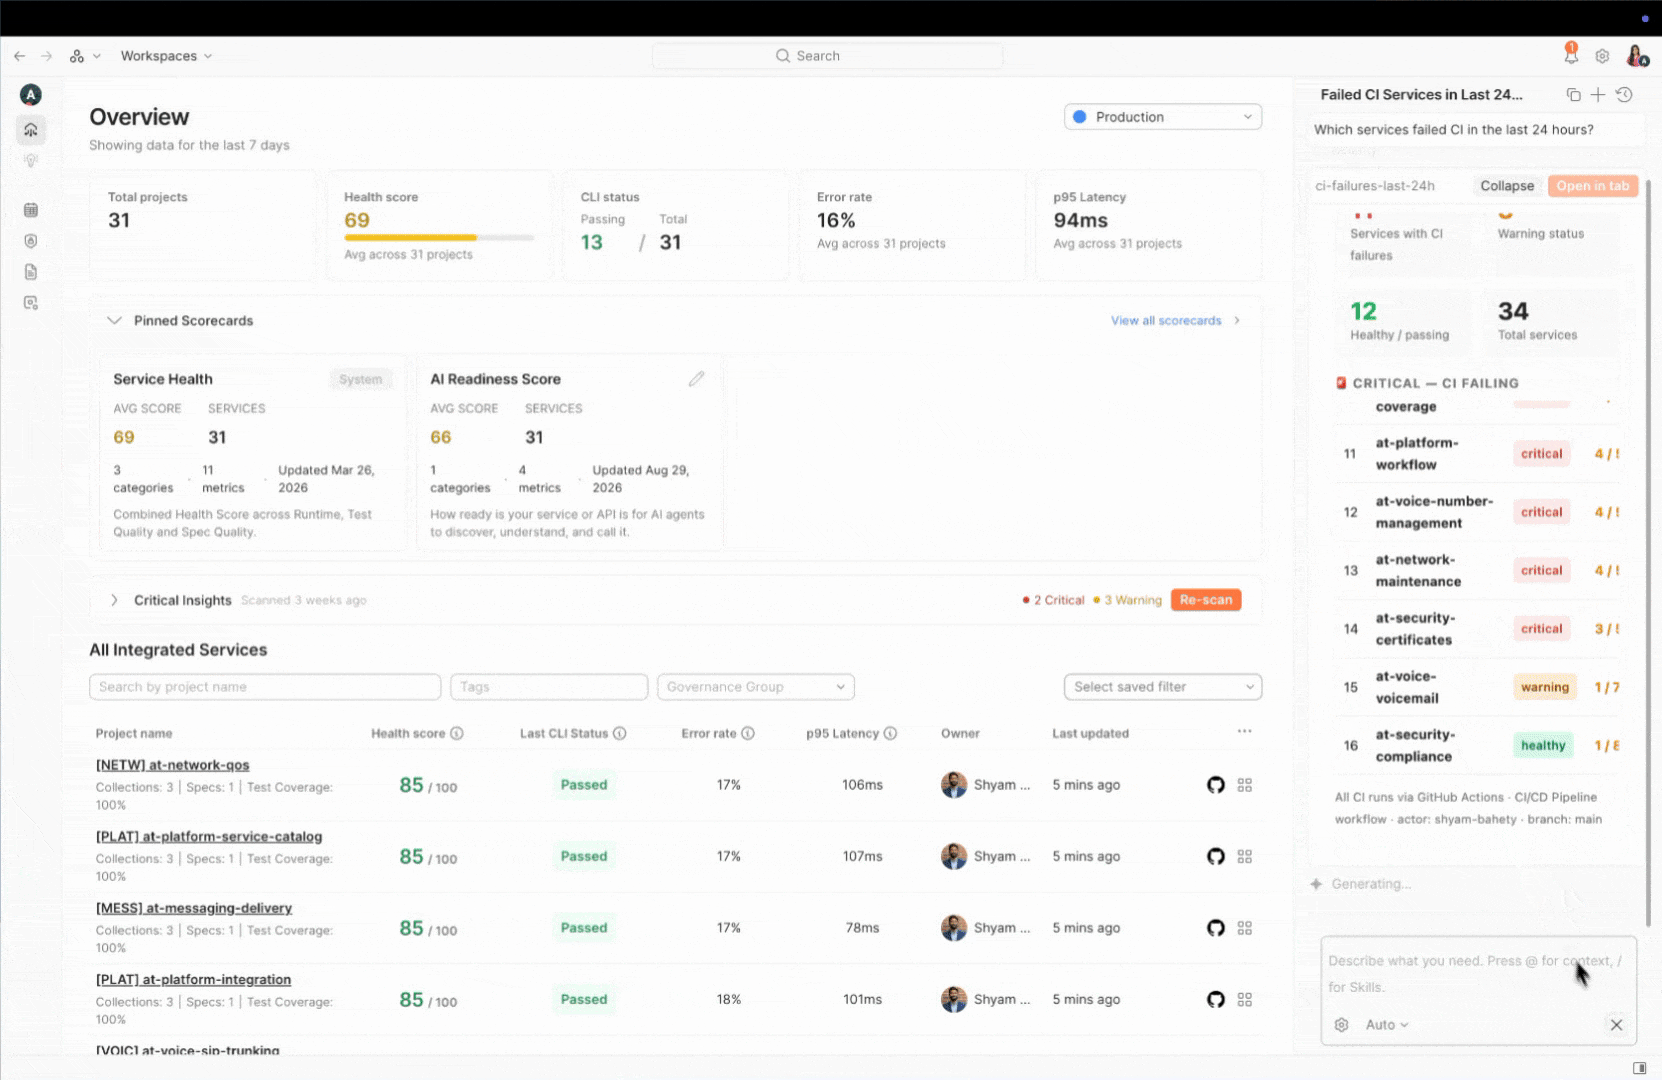
That’s the exact gap API Catalog is built to close: a single, always-current view of every API and service your org owns – what exists, who owns it, how well-tested it is, whether it’s passing CI, and how it’s actually behaving in production. This walkthrough covers how to set it up and use it day to day.

What API Catalog actually aggregates

Before getting into setup, it’s worth being clear on what’s actually flowing into this single view. API Catalog pulls together four categories of signal per service:

  • Ownership and discovery – what APIs exist, where they’re defined, and who’s responsible for them
  • Spec quality – OpenAPI/AsyncAPI linting results and governance violations
  • CI/CD status – pipeline runs from GitHub Actions, GitLab CI, or Jenkins, down to the PR level
  • Production health – p95 latency, error rates, uptime, and request volume per endpoint

The point isn’t only visibility – it’s that these signals sit next to each other. A developer reviewing a service before integrating with it isn’t only looking at a static spec; they’re looking at that spec alongside how the API is actually behaving right now.

Step 1: Connect your source repositories

You don’t populate the Catalog by manually registering every API – it scans for them. Connect a GitHub (or GitLab/Jenkins-backed) repository to your Postman workspace, and Postman scans it and pulls in what it finds: API specifications, collections, and, if you’re running services in a Kubernetes cluster, the live endpoints themselves.

To do this:

  1. From Home, click API Catalog.
  2. Connect your Git provider and select the repositories you want scanned. (You’ll need the Admin role for this step, since it wires up the data flow from third-party connectors and repos.)
  3. Postman scans each connected repo and adds discovered APIs as entries in the Catalog automatically.

This is the piece that keeps the Catalog from rotting into another stale spreadsheet – new services get picked up as they’re pushed, not weeks later when someone remembers to log them.

Step 2: Map each API to its real-world environments

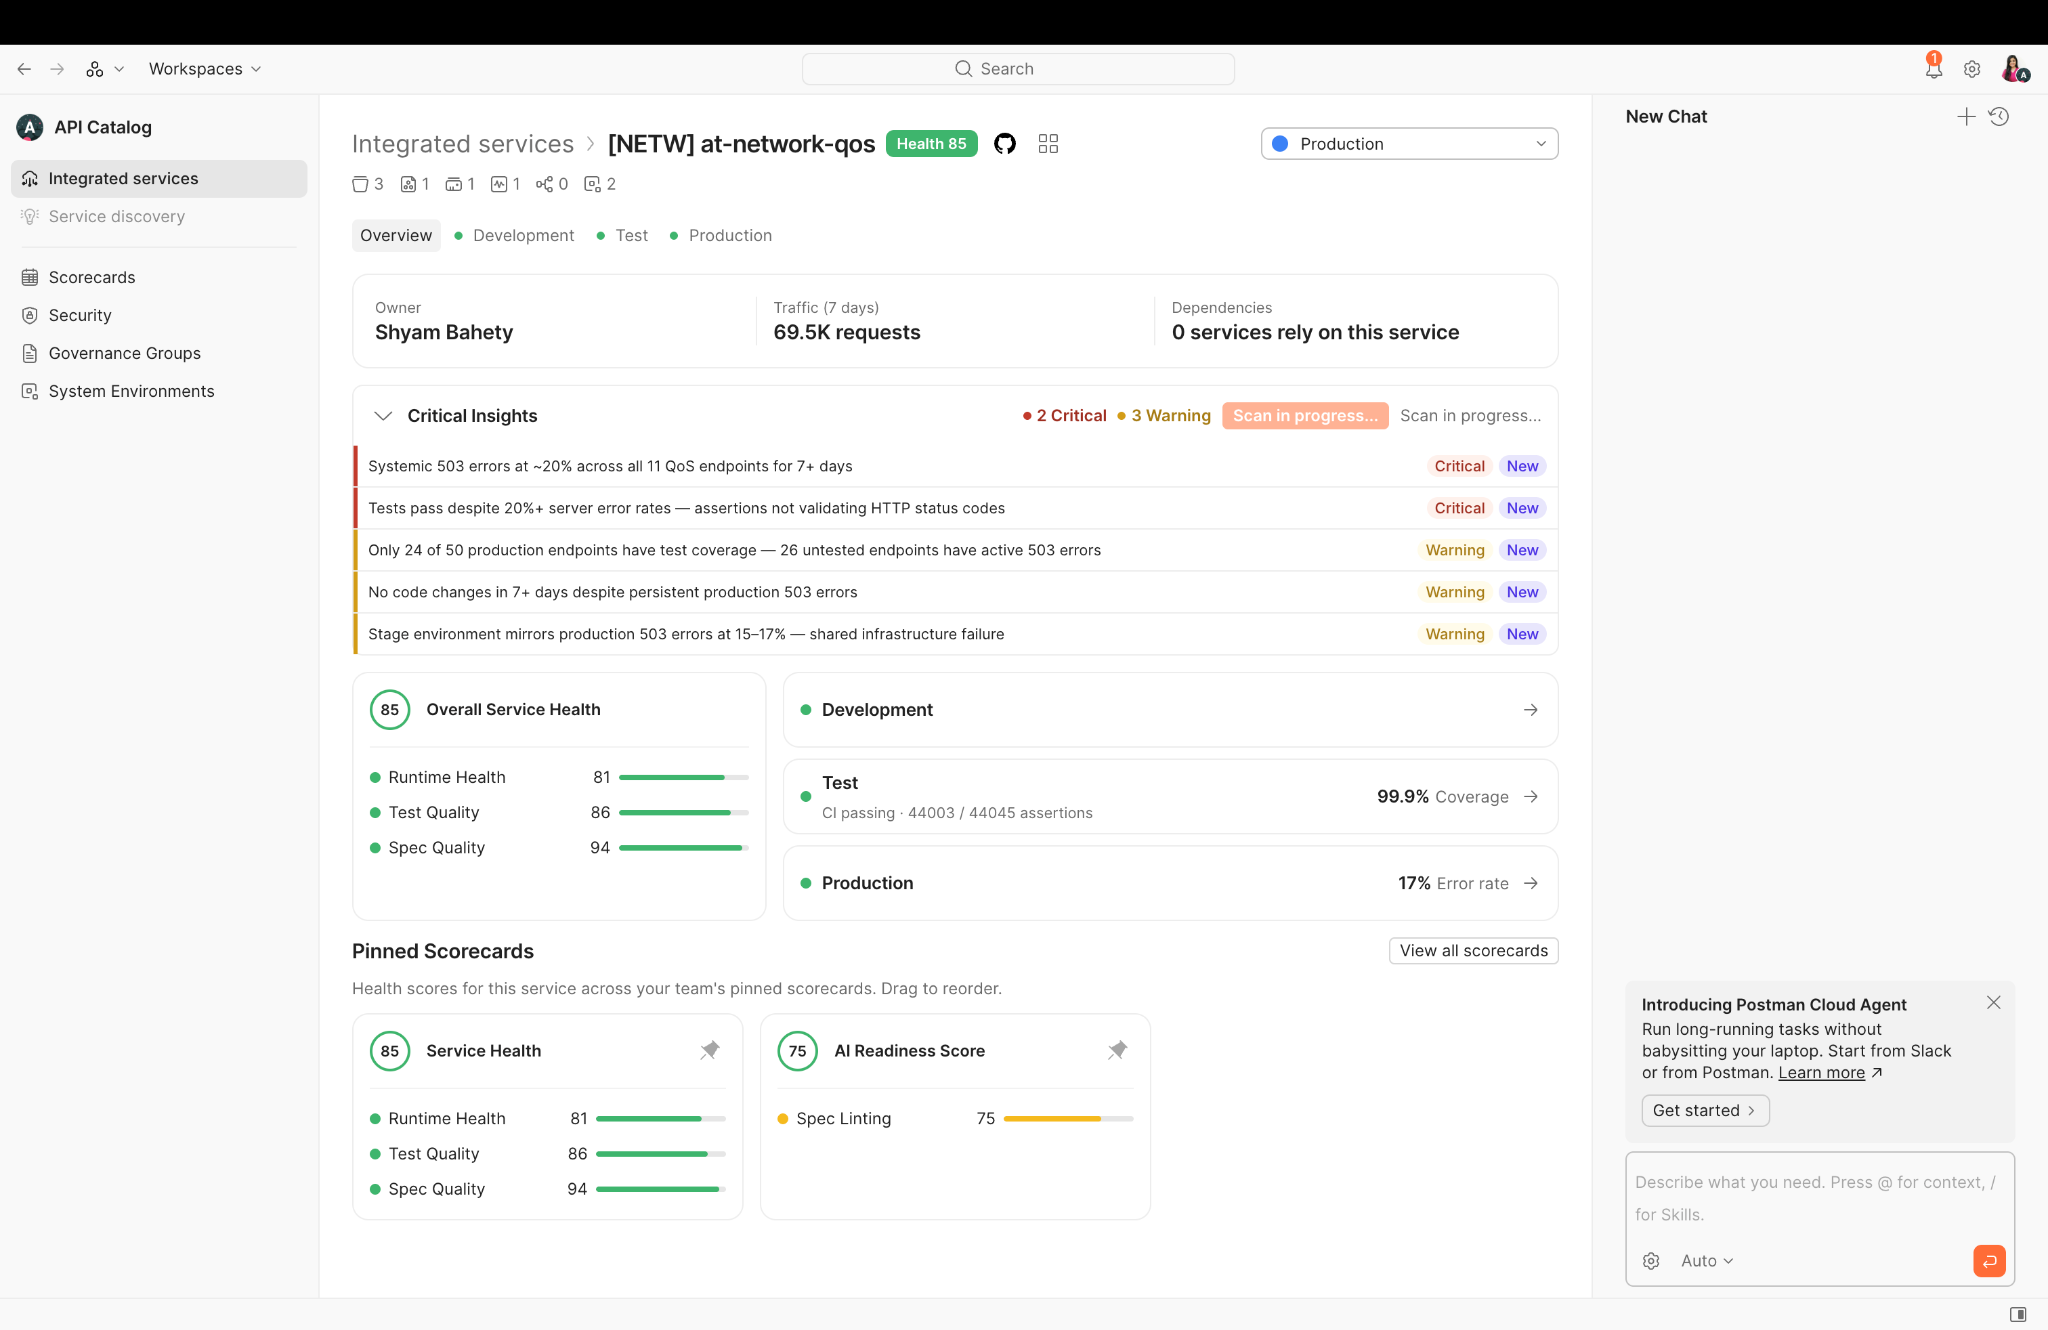
An API “working” means something different in staging than it does in production, and API Catalog keeps that distinction explicit through System Environments – letting you map the same API to each deployment context and see health data specific to that context, rather than one blended number.

To set this up:

  1. Open the API in the Catalog and go to Service Environments.
  2. Add an environment record for each deployment context (Staging, Production, Beta, etc.).
  3. Connect each environment to its relevant source:
  4. Staging typically connects to your CI/CD pipeline, showing the latest test pass rate and any spec violations introduced on the current branch.
  5. Production connects to your observability stack via the cluster watcher, surfacing live p95 latency, error rates, and uptime per endpoint.

Once this is wired up, switching between environments in the Catalog view shows you a genuinely different picture of the same API – which is usually exactly the picture a platform team needs before approving a change or debugging an incident.

Step 3: Read the health scorecard

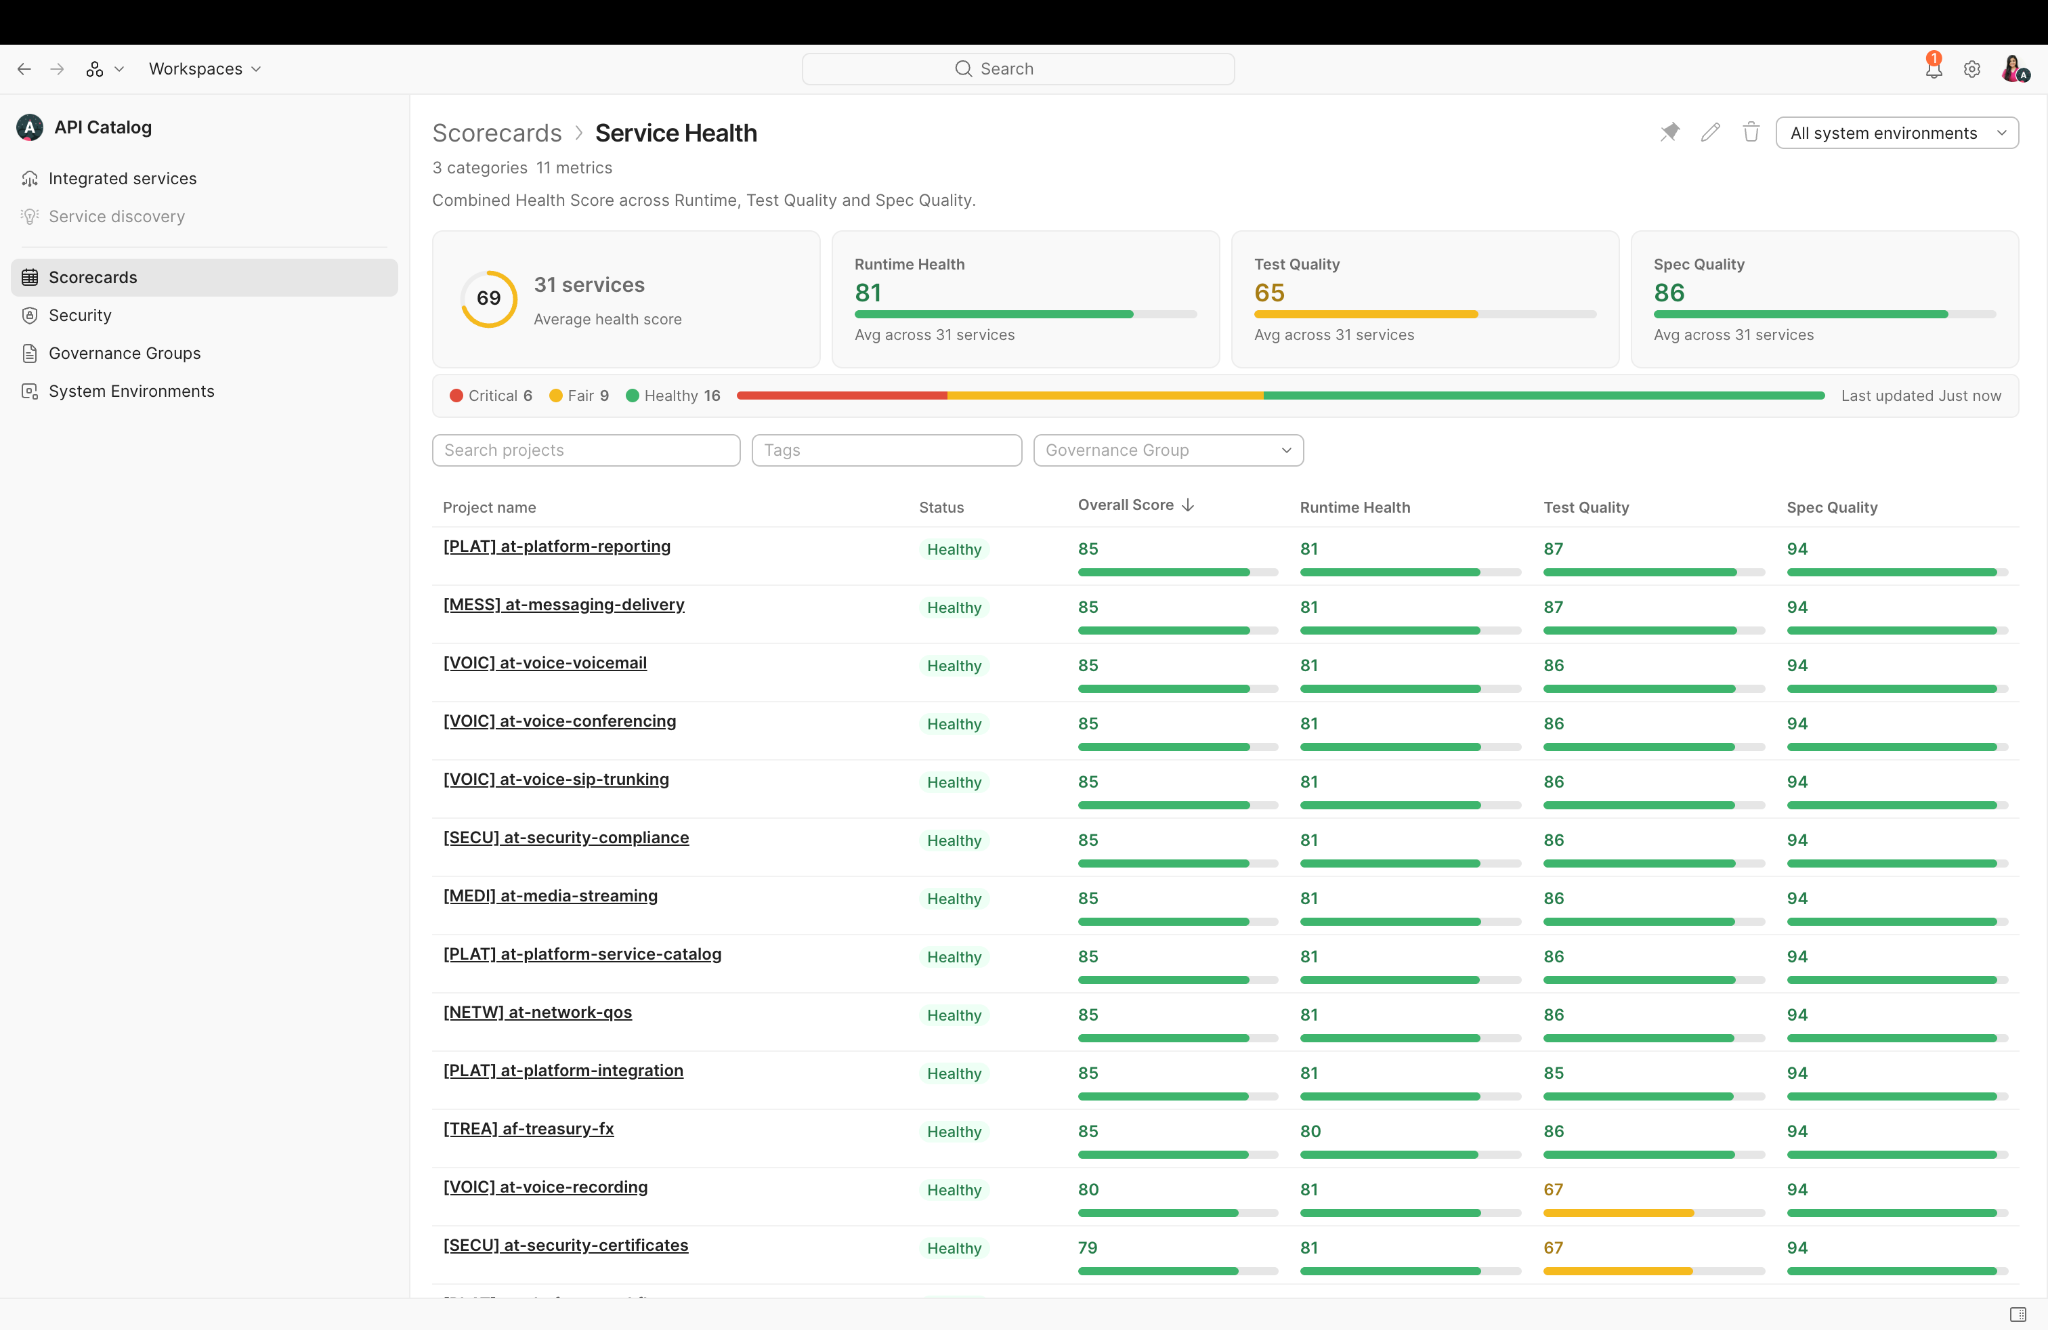
Every service in the Catalog gets a Service Health Scorecard – a rollup of test results, spec compliance, and gateway metrics in one view. Instead of manually checking a monitor dashboard, a separate test report, and a spec linter for every service on a rotation, you open the service and the Catalog tells you.

To use it:

  1. Open a service in the Catalog.

  1. Check the health scorecard section for a combined read on test pass rate, spec compliance score, and live gateway metrics.

  1. Set thresholds per metric so a service is flagged as healthy, needs attention, or critical – rather than relying on someone to notice a slow decline.

This is the piece that turns API governance from a weekly manual review cycle into something closer to real-time. If a service’s test pass rate drops or a new spec violation gets introduced, it shows up here immediately rather than at the next scheduled check.

Step 4: Query the Catalog with Agent Mode

Once data is flowing in, you don’t have to click through service by service to find what needs attention. Postman Agent Mode can query the Catalog directly using natural language – for example, asking which services have recently failed CI/CD tests, or which ones are returning errors in production.

A typical flow looks like this:

  1. Ask Agent Mode something like “Which services failed CI in the last 24 hours?”
  2. Agent Mode correlates the recent deployments and failures across the connected services.
  3. From there, you can instruct it to suggest – or directly implement – a fix, whether that’s correcting a spec issue, updating a failing test, or pushing a fix back to the repo via the Git integration.

This is where API Catalog stops being a dashboard you check and starts being a workflow you run through: surface the problem, diagnose it, and resolve it, without switching between four different tools to do it.

Why this matters for platform teams specifically

If you’re running an API governance program, the value here isn’t only dashboarding – it’s what it does to your review cycle. Identifying which APIs need attention today usually means someone manually cross-referencing monitor dashboards, test reports, and spec compliance results on a weekly cadence, with real issues sitting undetected in the gaps between reviews.

With API Catalog, that becomes: development activity, test results, and production signals sitting together in one place, updated continuously. Teams tend to use it as their source of truth for what APIs exist and who owns them in the first place – and once health data lives in that same view, service-level agreement conversations and service reviews stop requiring a round of “let me go check and get back to you.”

Get started

API Catalog is available on Postman Enterprise plans. If your org already has it, start with the Catalog overview in Postman Docs – it walks through registering APIs, connecting workspaces, and pulling in the signals the scorecard depends on. If you’re only running scheduled monitors today, you’ll still get baseline health data; connecting your CI pipeline and API gateway is what unlocks spec compliance and production signals in the same view.
See your organization’s full API landscape in one place. Explore API Catalog.

The post How to Track Every API Your Organization Owns with API Catalog appeared first on Postman Blog.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Responsible infrastructure at hyperscale: Managing the full lifecycle of Azure hardware

1 Share

Every new generation of cloud infrastructure creates two jobs. We must deploy more capable systems quickly, and we must manage the hardware they replace responsibly.

Even though these jobs happen behind the scenes, the results matter to Microsoft Azure customers. Newer systems deliver more compute capacity from the space and power available in a datacenter. At the same time, the reuse, refurbishment, and recycling of older equipment can extend the life of valuable components and return materials to the supply chain, ensuring cost efficiency and reliability.

Managing this process starts early in the lifecycle, with the design of our silicon, servers, networks, and datacenters. It continues through years of operation. When equipment leaves active service, Microsoft Circular Centers help determine its next useful life.

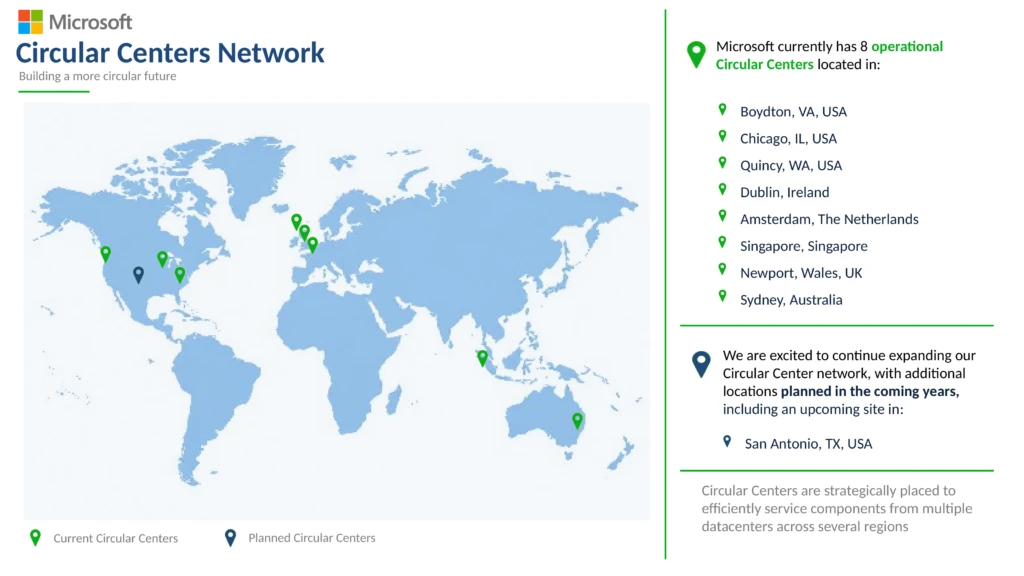
With new Circular Centers in Newport, Wales, and Sydney, Australia, this work now spans North America, Europe, and Asia Pacific. These facilities help us recover components, prepare space for new infrastructure, and get more value from the hardware and materials already in our system.

Getting more from every rack and every watt

Cloud infrastructure must keep pace with the work customers want to run. That means increasing compute capacity while making better use of the space and power available in each datacenter.

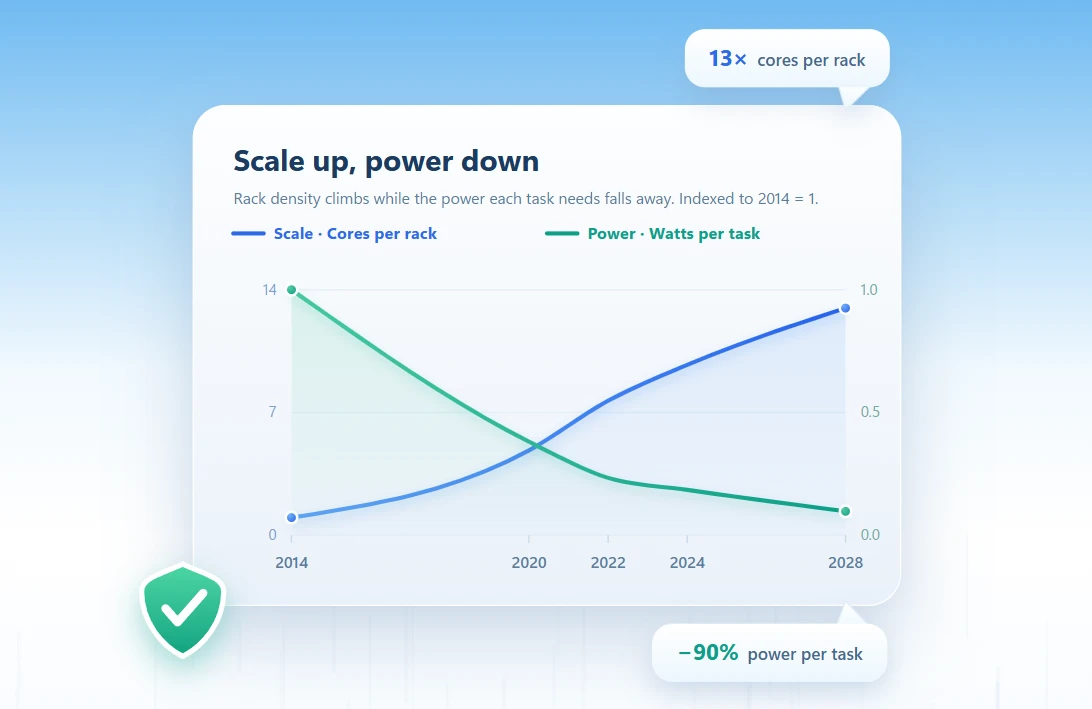
Compared with early general-purpose systems, today’s servers provide significantly more processor cores, more memory capacity, and network bandwidth. As shown in the chart below, Azure infrastructure has become both denser and more efficient over time. Since 2014, cores per rack have increased approximately 13-fold, while the power required to complete the same task has decreased by roughly 90%. For example, a workload such as code compilation that consumed approximately 100 watts on early systems can now be completed using less than 10 watts.

This increase in compute density means we’re able to provide more server capacity to support customer workloads using the same datacenter footprint. By delivering more useful work from each rack, newer infrastructure helps improve resource efficiency while supporting continued growth and scale to meet cloud and AI demand.

Source: Microsoft internal analysis using combined average data across general compute infra partners and Cobalt using industry benchmark performance such as SPEC CPU report and industry-standard utilization markdown.

Azure Cobalt is one example of this systems approach. Our custom-designed cloud processor allows Microsoft to optimize silicon, servers, networking, storage, and software together. Cobalt 200 delivers up to 50% higher performance than Cobalt 100 and incorporates the latest Microsoft security, networking, and storage technologies.

This constant cycle of innovation is one of the defining characteristics of cloud infrastructure. As new generations of cloud and AI infrastructure are deployed, older hardware is gradually taken out of service. What happens to the equipment being replaced?

Giving hardware its next useful life

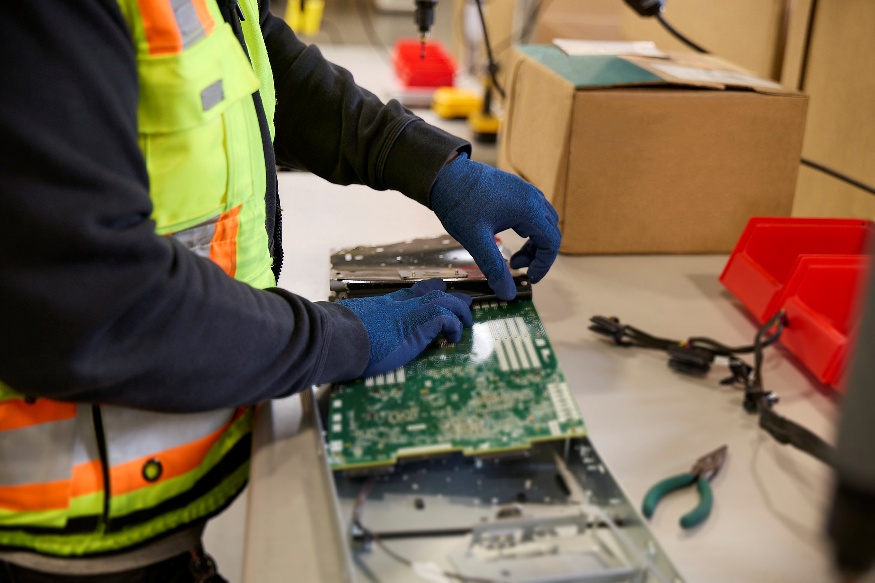
Last year, Microsoft achieved a 92% reuse and recycling rate for decommissioned servers and components. However, at the scale we operate, retiring a server is a little more complex than simply sorting components into the correct recycling bin. Every server must be securely decommissioned, and data-bearing components wiped. Then we must decide how to recover the most value from it. Can the complete system serve another purpose? Can processors, memory, and other components keep working elsewhere? Which materials can return to the supply chain?

Microsoft Circular Centers manage these decisions as part of our datacenter operations. At these facilities, our staff give decommissioned hardware a series of possible next lives. Complete systems can support Microsoft labs and training environments, help schools and universities teach technical skills, or be sold to qualified buyers for continued use. Components can become spare parts for other systems. Materials are recycled when reuse is no longer possible.

Our Circular Centers operate as a connected global network. With recent launches in Wales and Australia, eight centers are now in operation across North America, Europe, and Asia Pacific. The network continues to grow, with a new center planned for San Antonio, Texas.

We are also investing in technologies that improve the efficiency and scale of circular operations. Through automation initiatives with AI-powered capabilities, such as robotic disassembly and autonomous material handling, we are helping accelerate the recovery of components and materials.

Making the most of every resource

As demand for cloud and AI continues to grow, every part of the infrastructure lifecycle matters. We must get more compute from every rack and every watt, while getting more value from every server and component. Circular Centers help us do both. They make responsible recovery part of how we grow Azure, renew the foundational infrastructure, and build capacity for what customers need next.

Learn More

Microsoft Circular Centers

Helping deliver towards our commitment on Zero Waste

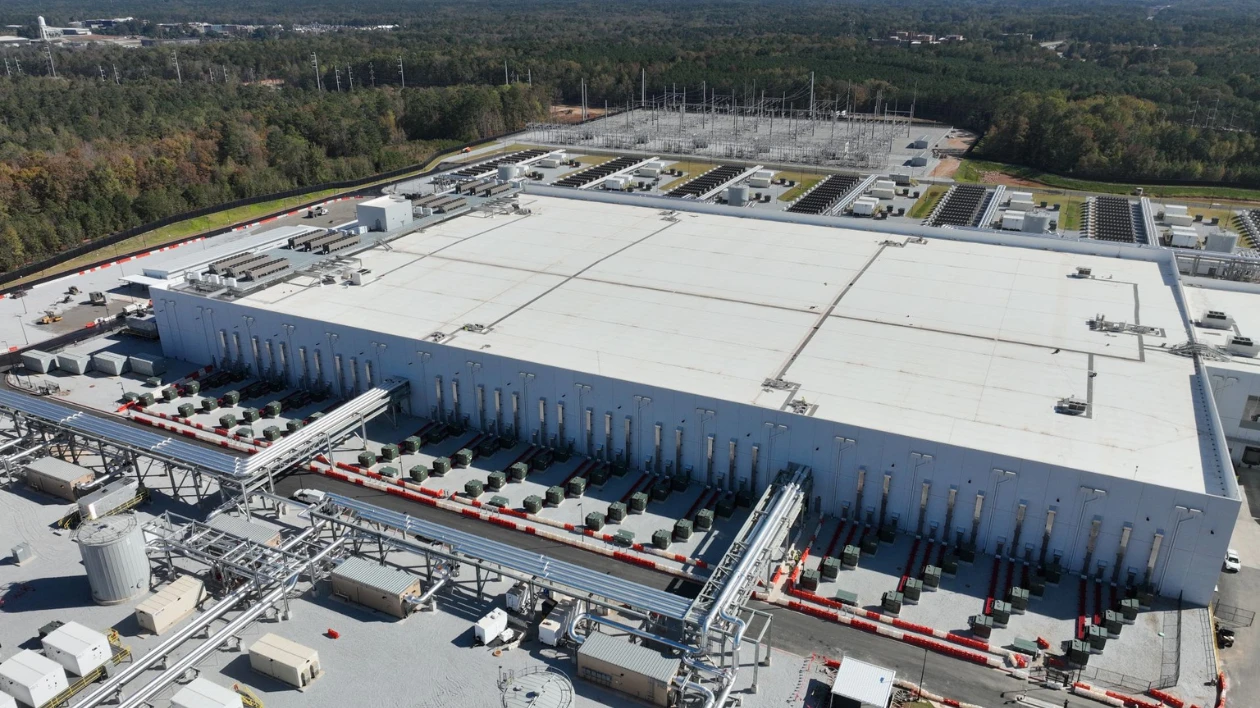
An aerial shot of the Fairwater AI datacenter near Atlanta, Georgia.

The post Responsible infrastructure at hyperscale: Managing the full lifecycle of Azure hardware appeared first on Microsoft Azure Blog.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete

From standards to software: Microsoft’s ongoing work on OpenAPI and developer tooling

1 Share

Today I’m excited to share several updates across Microsoft products, oen-source projects, and services related to OpenAPI and JSON Schema support.

Taken together, these updates show how specifications are moving from background plumbing to active developer experience infrastructure: they help teams describe APIs more accurately, build better tools, and make AI-assisted development more reliable.

Why OpenAPI and JSON Schema matter for AI-assisted development

Open specifications enable interoperable ecosystems of products, tools, and services, while giving engineering teams the precision they need to build consistently across implementations. Microsoft has long contributed to specifications such as OpenAPI and remains committed to advancing them as the foundation for better engineering practices.

In the age of AI-assisted and agentic development, that precision matters even more. Because large language models are probabilistic, grounding their work in detailed specifications improves the reliability of generated code.

What is OpenAPI and why developers use it?

OpenAPI is a language-agnostic specification for describing REST APIs in a way that both humans and tools can understand. For more than a decade, it has been the de facto standard for REST API descriptions, backed by a broad community of vendors, tool builders, and practitioners.

OpenAPI 3.2.0: What’s new for API developers

OpenAPI 3.2.0 brings updates to tags, improves performance through the added HTTP QUERY support, improves security through added device flow support, and adds support of streaming data. These improvements give API producers more precise ways to describe modern, AI-ready API patterns.

You can learn more in the announcing OpenAPI v3.2 blog post.

JSON Schema 2020-12: Key improvements for OpenAPI and API design

Improving OpenAPI support also led us to improve support for JSON Schema. The latest version of JSON Schema brings support for $dynamicRef/Anchor which finally solves recursive schemas without brittle $ref chains. It also clarifies vocabulary handling and improves interoperability. Better schemas mean a greater ability for you to catch issues earlier on!

Case study: How Microsoft Foundry uses OpenAPI, TypeSpec, and JSON Schema

Foundry provides a useful example of how specifications, converters, schemas, editors, gateways, and generated assets can reinforce one another across a large platform.

Microsoft Foundry is a platform for building AI and agentic solutions, with thousands of models from many providers, evaluation and fine-tuning capabilities, agent building and hosting, and more.

Foundry exposes its own REST APIs for platform-specific capabilities, while also maintaining full fidelity with OpenAI’s REST APIs so customers can move solutions between them without rebuilding from scratch.

This is where strong specifications and the tooling around them helped accelerate that work, control implementation costs, and improve overall quality.

OpenAI maintains an OpenAPI description for everyone to use, which it also uses internally to generate software development kits (SDKs) and more. The Foundry developer experience team imports that description as a TypeSpec definition using the TypeSpec convert tool.

Using those definitions, Foundry service teams can describe their additional APIs in TypeSpec and use the consolidated model to:

  • Generate SDKs.
  • Generate the Foundry API reference.
  • Generate server-side code.
  • Perform contract testing to ensure highfidelity with the OpenAI REST API.

The developer experience for engineers across the platform is also supported by JSON Schema and Schema Store integration in Visual Studio Code, while parts of the service infrastructure rely on API Management under the hood.

Microsoft investments in OpenAPI, JSON Schema, and developer tooling

Over the last year, multiple teams at Microsoft have worked to bring products and services up to date with the latest developments in the OpenAPI and JSON Schema space. The examples below show how that work is landing across libraries, frameworks, editors, API platforms, and AI developer experiences.

.NET

Microsoft.OpenAPI

Microsoft.OpenAPI is the main .NET library for parsing, building, and serializing OpenAPI descriptions. A shared implementation helps the ecosystem avoid duplicating the complex work required to fully support the specification.

This library provides a foundation for ASP.NET Core OpenAPI integration, Swashbuckle, Azure API Management, Microsoft Kiota, and hundreds of product teams at Microsoft.

After OpenAPI 3.2.0 was released, we shipped a new Microsoft.OpenAPI version with support for the updated specification so the broader ecosystem could adopt the new capabilities. That work, along with countless contributions since, was done by community members like you!

ASP.NET Core in .NET 11

ASP.NET Core is Microsoft’s open-source, cross-platform framework for building modern web apps, services, and APIs with .NET. It gives developers a high-performance foundation for creating cloud-ready applications that can run on Windows, Linux, and macOS.

ASP.NET Core in .NET 11 continues to make OpenAPI a first-class part of the web API developer experience. In this release, ASP.NET Core adds support for OpenAPI 3.2.0 by default, built on Microsoft.OpenAPI, giving developers a clear path to describe and validate modern API patterns.

The list of new capabilities was informed by the community and includes support for:

  • HTTP QUERY operations.
  • Server-Sent Events (SSE) streams.
  • Accurate binary and file result response schemas.
  • C# union-typed responses.
  • And many more improvements!

Note: .NET 11 will become generally available in November 2026 and is currently in public preview.

TypeSpec

TypeSpec is Microsoft’s open-source language for designing APIs in a concise, reusable, specification-friendly way. Teams can define their model once in TypeSpec and generate OpenAPI descriptions, JSON Schemas, documentation, and client or server code from that source of truth.

Over the last year, we’ve greatly improved the OpenAPI to TypeSpec convert tool, enabling lift-and-shift production scenarios where API producers and architects can build on existing API investments while improving their design experience.

We’ve also added support for emitting OpenAPI 3.2.0 descriptions and implemented new OpenAPI capabilities, so once you’re done designing your API, you can get high-fidelity OpenAPI descriptions and use them in your favorite tool/platform.

Visual Studio Code

Support for JSON schema 2020-12

Developers spend a lot of their time in the integrated development environment (IDE). When reviewing or authoring any JSON document, they expect that environment to catch simple mistakes and provide accurate autocompletion.

Visual Studio Code uses a JSON language server to provide syntax highlighting and validate documents against JSON Schema. Until recently, that language server only supported JSON Schema Draft 07, a specification published back in 2018.

This meant that if your JSON document relied on a schema that used more modern capabilities from JSON Schema 2019-09 or 2020-12, some validation rules could be ignored or fail entirely. OpenAPI 3.1 and 3.2 are good examples because their schemas rely on JSON Schema 2020-12 to validate that a document is properly structured.

Since version 1.130.0, Visual Studio Code now supports JSON Schema 2019-09 and 2020-12, offering the latest validation experience you could ask for any JSON document.

Built-in OpenAPI and schema validation in Visual Studio Code

In version 1.140.0, Visual Studio Code also added built-in schema mappings for OpenAPI, Overlay, and Arazzo documents.

Combined with support for newer JSON Schema versions, these built-in mappings give known JSON documents, including OpenAPI 3.2 documents, structural validation in Visual Studio Code without requiring a third-party extension.

Help improve JSON Schema Store integration in Visual Studio Code

The JSON Schema Store is an open-source catalog of schemas for common JSON documents. Each catalog entry can also include metadata such as the filename patterns associated with that schema.

Integrating the JSON Schema Store would let Visual Studio Code automatically select and validate against the appropriate schema based on known filename patterns, without requiring manual configuration or a $schema property. If you’d like to see this capability, please upvote this issue.

Azure API Management

Azure API Management helps teams publish, secure, govern, monitor, and expose backend APIs, including REST and AI APIs, through managed gateways and developer portal experiences powered by OpenAPI descriptions.

Until recently, API Management only supported up to OpenAPI 3.1 for ingestion and 3.0 for publishing. With the support for OpenAPI 3.2, customers can expand how they define and publish APIs and integrate with other platforms. This update also improves support for importing OpenAI v1 model APIs, making it easier to automate API creation and manage traffic to OpenAI models through AI Gateway capabilities in API Management that thousands of Azure customers rely on.

API Management is deploying OpenAPI 3.2.0 support across Azure regions and service tiers.

Recognizing the contributors advancing the OpenAPI ecosystem

Thank you for using, maintaining, and contributing to the specifications, libraries, tools, and services that make this ecosystem work. OpenAPI succeeds because people across organizations keep improving both the standard and the developer experiences built on top of it.

Special thanks to:

Build better APIs with OpenAPI

Explore Microsoft’s OpenAPI documentation, tools, and SDK resources to learn how to work with OpenAPI-described APIs and build modern API development experiences.

The post From standards to software: Microsoft’s ongoing work on OpenAPI and developer tooling appeared first on Microsoft Open Source Blog.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories