Microsoft's MAI-DxO AI diagnostic system achieved 83.2% accuracy in complex medical cases, compared with 36.1% for physicians using reference materials.
Keeping up with new technology is one thing. Finding worthwhile opportunities to explore what matters most to your work is another.
That’s where VSLive! can help. It brings technical learning, hands-on experience, expert guidance, and a community of developers together in one place, giving you focused time to explore evolving technologies and decide what’s worth bringing back to your team.
And if you’re an eligible Dev Essentials member, Visual Studio Professional subscriber, or Visual Studio Enterprise subscriber, you have benefits that can provide a significant discount for these in-person events.
Develop skills you can put to work
One of the things that makes VSLive! so beneficial is its focus on practical learning. Rather than simply hearing about the latest technologies, developers have opportunities to explore how those technologies can help solve real development challenges.
For example, if you’re interested in furthering your skills with Copilot, VSlive! Las Vegas 2027 will offer a dedicated hands on lab equipping you to build an ASP.NET Core Web Assembly SPA from scratch (all in just one day).
Maybe you’d like to witness Microsoft Foundry in action. VSLive! Las Vegas 2027 will also include dedicated session time for a practical tour of Foundry through the lifecycle of an AI agent. This session will show how Toolbox connects agents to services and tools, how Foundry IQ grounds to enterprise knowledge, and how Hosted Agents support custom agents.
If you’re struggling with the growing menu of AI coding tools and looking for a framework to compare your many options, you’ll love the demo driven AI comparison session. During this session, major AI contenders will be contrasted side by side as they work to accomplish the same tasks. You’ll see for yourself which tools are best suited for the challenges you face everyday and come away with practical insights.
Learn from the people around you
Some of the most valuable opportunities at VSLive! happen outside the scheduled sessions.
Think about the last time you tried to work through a new technical problem on your own. Chances are another developer has encountered something similar, and at VSLive!, you can connect with developers facing many of the same challenges, compare experiences, discuss solutions, and discover approaches you might not have considered. A conversation between sessions could introduce you to a useful tool, a better development practice, or a different way of solving a problem.
There’s also value in learning directly from the people who work with these technologies every day. Attendees often have the chance to interact with Microsoft product team members, ask questions about the tools they use, and share feedback based on the latest industry changes.
Those conversations can create opportunities for two-way learning. Developers gain additional insight into the critical technologies they depend on, while our product team can hear directly about real-world challenges and experiences.
It’s this combination of technical learning, shared experience, and community that makes VSLive! more than just a collection of conference sessions.
Save up to $900 with your Visual Studio Subscription
Here’s a benefit worth checking before making your conference plans: Subscribers can receive discounts of up to $900 on VSLive! conference registration through their Visual Studio Subscription.
It’s another way your Subscription can help you stay ahead of the curve and take advantage of learning opportunities beyond the software, cloud services, and training resources you may already be using.
Looking ahead to VSLive! in 2027
As you consider investing in your technical skills next year, several VSLive! events are already scheduled for 2027:
If you’re an eligible Dev Essentials member or Visual Studio subscriber, visit the Visual Studio Subscriber Portal to redeem your VSLive! benefit. Join the community at VSLive! and realize what thousands of developers already have: there’s no place like VSLive! to sharpen your skillset, get practical experience, and solve for the challenges you face every day.
TL;DR: Need to verify signed PDFs long after signing? Learn how to digitally sign PDFs, add trusted timestamps, enable Long-Term Validation (LTV), and validate individual or multiple signatures using the Syncfusion JavaScript PDF Library.
A digital signature helps verify who signed a PDF and whether the document has changed since signing. But how can you validate that signature months or even years later, especially when the signing certificate has expired or revocation information is no longer available?
Trusted timestamps and Long-Term Validation (LTV) information help preserve the evidence needed for future signature verification.
Add a trusted timestamp from a Time Stamping Authority (TSA).
Enable Long-Term Validation (LTV).
Validate individual and multiple signatures.
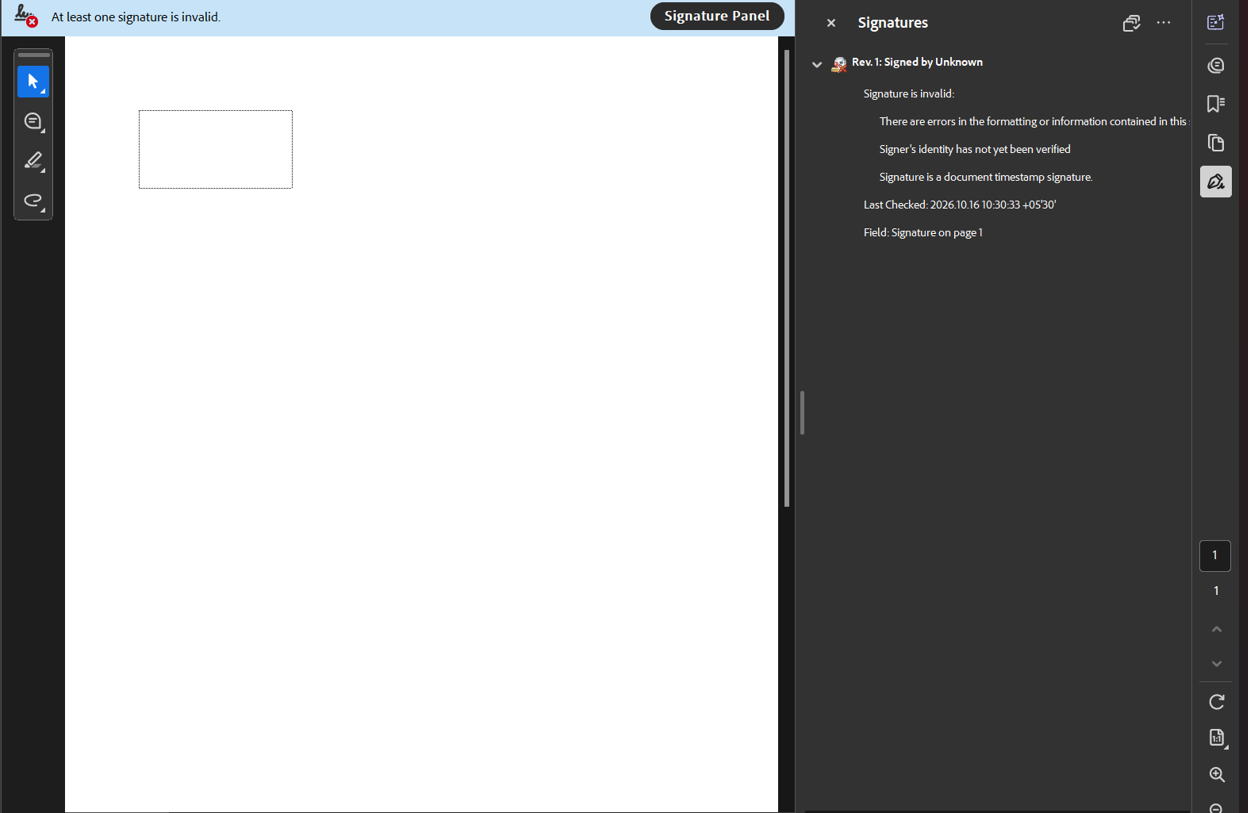
Interpret validation results correctly.
Important: A trusted timestamp and LTV information can help preserve the evidence needed to validate a PDF signature in the future. However, successful long-term validation still depends on the signature’s integrity, the available certificate and revocation evidence, the certificate chain, and the trust policies used by the validating application. LTV improves future validation readiness but does not guarantee indefinite validation under all circumstances.
What the new PDF validation capability enables
The new validation capabilities allow developers to:
Verify whether a signed document has been altered after signing.
Validate certificate chains used by signatures.
Inspect trusted timestamp information.
Check certificate revocation status using OCSP and CRL evidence.
Validate a specific signature field.
Validate multiple signatures in a single PDF document.
Support processes that require long-term signature verification.
These capabilities are especially useful in document management, finance, legal, healthcare, government, and compliance-focused applications where document integrity must be preserved over time.
Digitally sign a PDF in JavaScript
Digital signatures help verify a PDF document’s authenticity, confirm the identity of the signer, and detect whether the document has been altered after signing. By applying a certificate-based digital signature, you can establish trust in electronic documents and support secure document processing.
Using the Syncfusion JavaScript PDF Library, you can digitally sign both newly created and existing PDF documents with industry-standard certificates.
Prerequisites
Before you begin, ensure you have the following:
A valid digital certificate (.PFX or .P12) containing the private key.
The certificate password.
A PDF document to sign, or a new PDF document to create.
The Syncfusion JavaScript PDF Library.
Security Consideration: Never hardcode PFX passwords, private keys, or certificate files in browser-delivered JavaScript. Private keys are sensitive cryptographic assets and should be protected appropriately. For high-security environments, consider server-side signing or a managed digital-signing service rather than exposing signing credentials to client applications.
Once your certificate and PDF document are ready, you can sign the document by creating a signature field, applying a digital signature, and saving the signed PDF.
Steps to digitally sign a PDF
Step 1: Create or load a PDF document
Create a new document or load an existing PDF, depending on your use case. The document acts as the container for the digital signature and related form fields.
Step 2: Create a signature field
Add a PdfSignatureField to the document. This field defines where the signature information will be stored and displayed within the PDF.
Step 3: Create and apply a digital signature
Load the PFX certificate and create a PdfSignature object using the certificate and password. You can also specify the cryptographic standard and hashing algorithm used to generate the signature.
Step 4: Add the signature field and save the document
After applying the signature, add the signature field to the PDF form and save the document. The resulting PDF contains a verifiable digital signature that can later be validated for integrity and authenticity.
The following example creates a new PDF document, adds a signature field, and applies a digital signature using a PFX certificate and the SHA-256 hashing algorithm:
// Create the documentvardocument = new ej.pdf.PdfDocument();
// Get the first page of the documentvar page = document.addPage();
// Access the PDF formvar form = document.form;
// Create a new signature fieldvar field = new ej.pdf.PdfSignatureField(page, 'Signature', {x: 10, y: 10, width: 100, height: 50});
// Create a new signature using PFX data and private keyvar sign = ej.pdf.PdfSignature.create(certData, password, {cryptographicStandard: ej.pdf.CryptographicStandard.cms, digestAlgorithm: ej.pdf.DigestAlgorithm.sha256});
// Set the signature to the field
field.setSignature(sign);
// Add the field to the PDF form
form.add(field);
// Save the documentdocument.save('output.pdf');
// Destroy the documentdocument.destroy();
Adding a signature field to a PDF document
Note: In this example, certData represents the PFX certificate bytes and password is the certificate password. These values should be securely loaded through your application’s credential management process rather than embedded directly in source code.
For additional signing scenarios, including signing existing PDFs and advanced signature configuration options, explore the digital signature demo and refer to the API documentation.
Add a trusted timestamp to a PDF signature
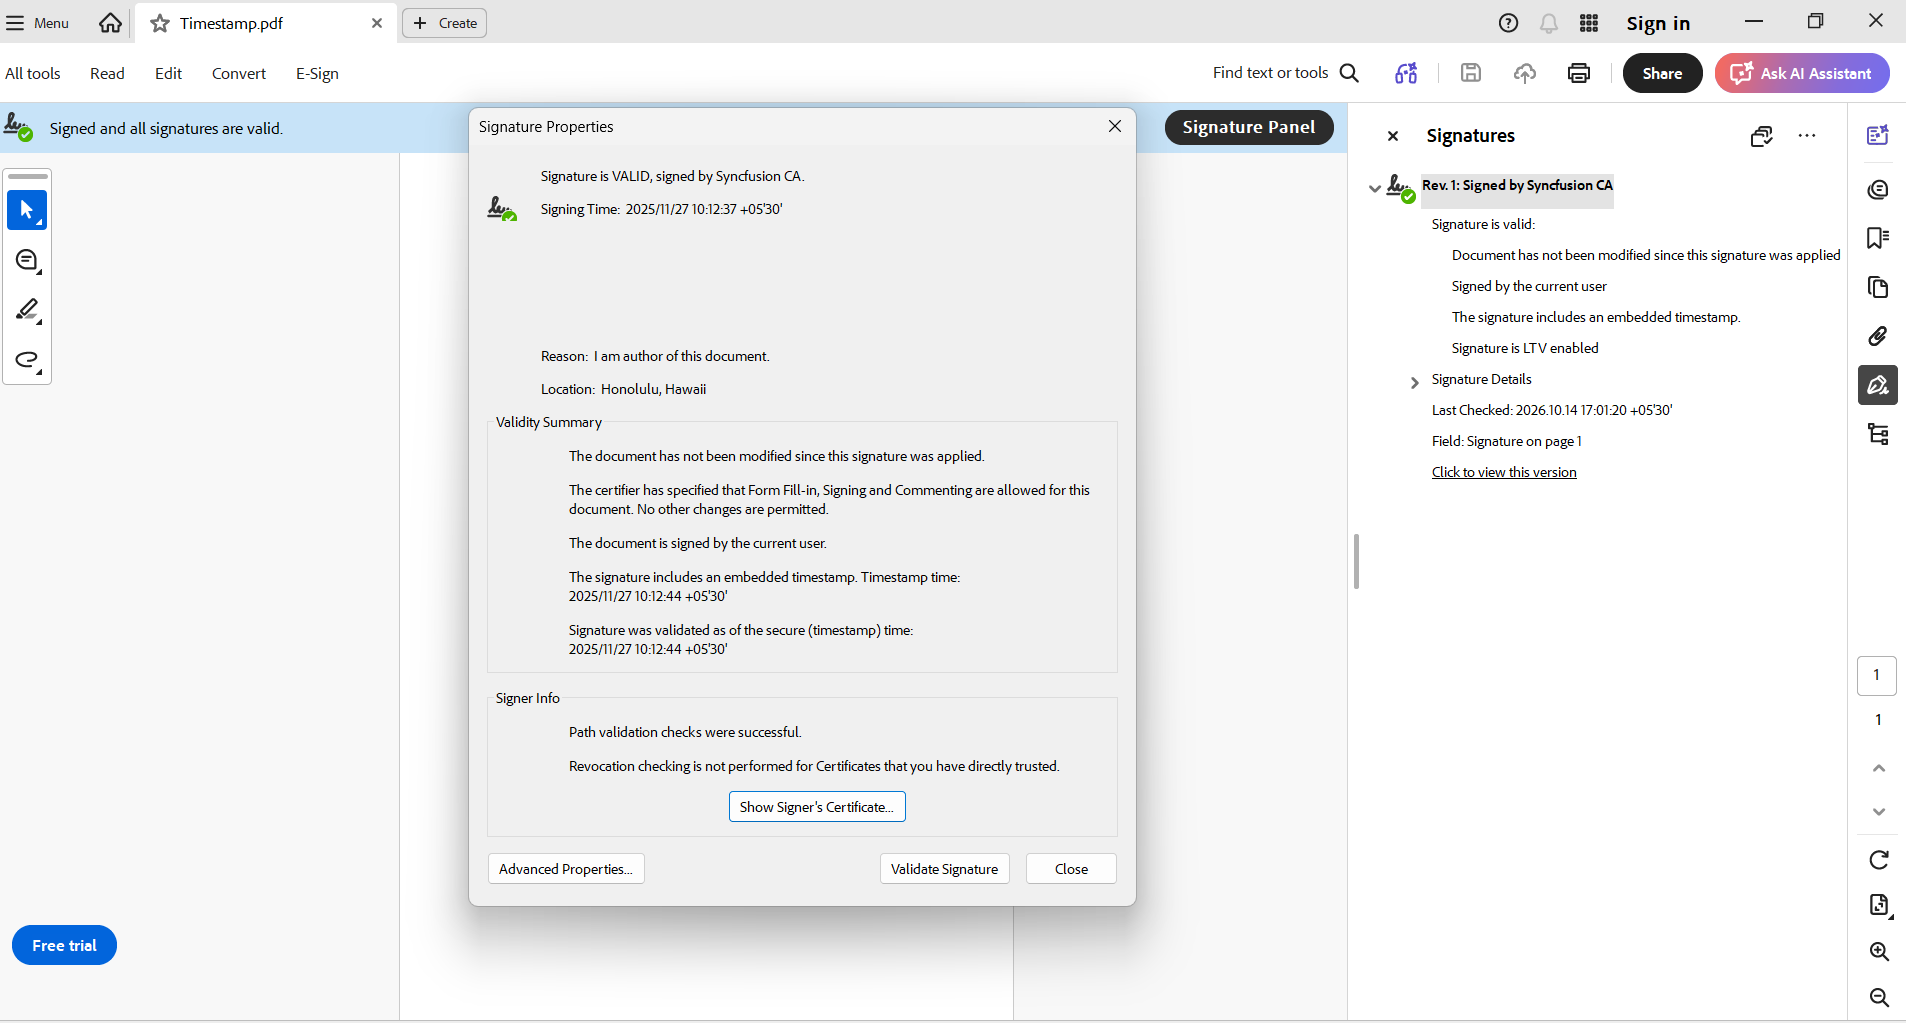
A timestamp records when a document was signed through a trusted Time Stamping Authority (TSA). It provides evidence of the signing time and helps support future signature verification.
To add a timestamp, provide a timestamp callback when creating the digital signature. The callback returns the TSA response, which is embedded into the signature during the save operation.
The following example shows how to add a timestamp to a digitally signed PDF document.
// Create a timestamp callbackasyncfunctiontimestampCallback(request) {
// Implement timestamp response logic herereturn { response: newUint8Array() }; // Placeholder return
}
// Create a new signature using PFX data, private key and callback function for timestampconst signature = ej.pdf.PdfSignature.create(certData, password, { cryptographicStandard: ej.pdf.CryptographicStandard.cms, digestAlgorithm: ej.pdf.DigestAlgorithm.sha256 }, timestampCallback);
field.setSignature(signature);
// Save the documentawaitdocument.saveAsync('output.pdf');
Adding a timestamp to a digitally signed PDF document
Note: This example demonstrates the callback contract only. Your application must send the timestamp request to a trusted Time Stamping Authority (TSA) and return the TSA response bytes.
Why use saveAsync()?
When timestamping is enabled, the library must communicate with an external TSA service. Because the operation is asynchronous, use await document.saveAsync() to ensure that the timestamp response is received and embedded before the PDF is generated.
Enhance PDF signature validation with Long-Term Validation (LTV)
A trusted timestamp helps establish when a document was signed, but long-term verification often requires additional evidence. If certificate revocation services become unavailable, validators may not be able to retrieve the information needed to determine whether the signing certificate was trusted at the time of signing.
Long-Term Validation (LTV) helps address this challenge by embedding certificate and revocation information directly into the PDF.
To enable LTV:
Sign and save the PDF.
Reload the signed document.
Retrieve the signature.
Call the enableLTV() method and provide revocation responses through the callback.
The following code example demonstrates how to enable LTV for a signed PDF document.
// Load the signed PDF documentconstdocument = new ej.pdf.PdfDocument(data);
// Get the signature fieldconst field = document.form.fieldAt(0);
// Retrieve the PDF signatureconst signature = field.getSignature();
// Retrieve the OCSP or CRL response requested by the libraryvar longTermValidationCallback = asyncfunction (url, requestBytes) {
// Send requestBytes to the approved URL and return the actual response bytesreturn { response: revocationResponse };
};
// Enable LTV for the created signaturevar ltvEnabled = await signature.enableLTV(longTermValidationCallback);
// Save the LTV-enabled PDF documentdocument.save('output.pdf');
Note: This callback must return the actual OCSP or CRL response bytes requested by the library. Network communication, authentication, retry logic, and error handling should be implemented by your application.
After you enable LTV, the PDF contains additional validation information that can support future verification and archival processes.
For complete LTV examples and implementation guidance, refer to the LTV documentation.
Validate PDF signatures
Once a signed PDF contains timestamp and optional LTV information, the next step is validation. Validation helps determine whether the document has been modified after signing and whether the associated certificates, timestamps, and revocation information remain trustworthy.
The Syncfusion JavaScript PDF Library supports validation for both individual signatures and multiple signatures contained within a PDF document.
During validation, the library can verify document modifications, certificate chains, timestamp information, revocation status through OCSP or CRL data, and multiple signatures available in the document.
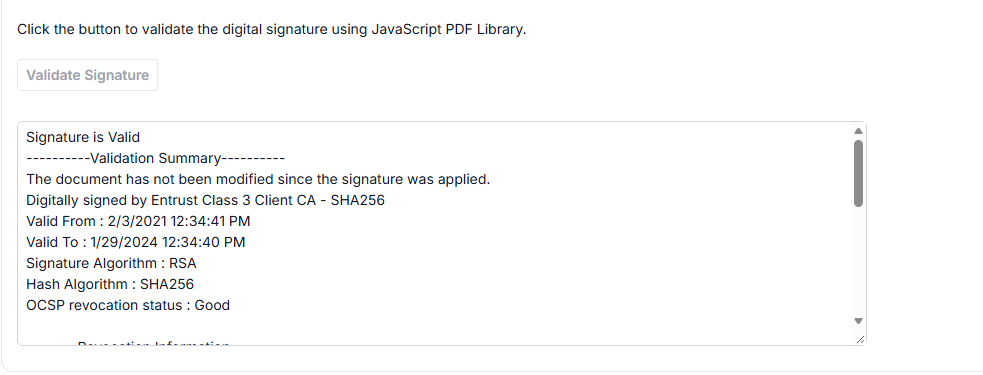
Validating PDF signatures using the Syncfusion JavaScript PDF Library
Validation prerequisites
Before validating signatures, prepare the following:
documentData: The PDF document bytes to validate.
certificateData: Trusted root or intermediate certificate data used to establish trust.
passwords: Optional passwords used only when validating encrypted PDFs or password-protected processes.
Providing a certificate does not automatically establish trust. Validation depends on whether a complete and trusted certificate chain can be successfully built according to your organization’s trust requirements.
Validate a single signature
To validate an individual signature, retrieve the associated signature field and call the validate() method. The validation process checks whether the document has been modified after signing and evaluates certificate trust, timestamp validity, and revocation status based on the specified validation options.
The following example validates a single signature using trusted certificate information:
// Load the signed PDF document.constdocument = new ej.pdf.PdfDocument(documentData);
// Get the first signature field from the form.const field = document.form.fieldAt(0);
// Configure the signature validation options.const options = {
trustedCertificates: [certificateData],
passwords: ['syncfusion']
};
// Validate the signature.const validationResult = field.validateSignature(options);
// Check the validation result.console.log('Signature name: ' + validationResult.signatureName);
console.log('Signature valid: ' + validationResult.isSignatureValid);
console.log('Signature status: ' + validationResult.signatureStatus);
console.log('Document modified: ' + validationResult.isDocumentModified);
console.log('Revocation result: ', validationResult.revocationResult);
// Destroy the document and release its resources.document. Destroy();
The returned validation result contains details about signature validity, document integrity, certificate-chain validation, timestamp verification, and revocation checks.
Include the passwords option only when validating encrypted PDFs or processes that require password-protected content.
Note: Explore the digital signature validation demo to see the validation process in action and review the validation results returned by the API.
Validate multiple signatures in a PDF
When a PDF contains multiple signatures, validate them collectively using the validateSignatures() method. The method evaluates every signature field in the document and returns both overall and signature-specific validation results.
The following example validates all signatures in a PDF document:
// Load the PDF document that contains multiple signatures.constdocument = new ej.pdf.PdfDocument(documentData);
// Configure the validation options.const options = {
trustedCertificates: [certificateData]
passwords: ['syncfusion']
};
// Validate all signatures in the PDF document.const validationResult = document.form.validateSignatures(options);
if (validationResult.results !== null &&
validationResult.results !== undefined) {
console.log(
'Number of validated signatures: ' +
validationResult.results.length
);
validationResult.results.forEach((result) => {
console.log(
`${result.signatureName}: ${result.isSignatureValid}`
);
});
}
// Determine whether all signatures are valid.if (validationResult.isValid) {
console.log('All signatures in the PDF document are valid.');
} else {
console.log('One or more signatures in the PDF document are invalid.');
}
The validationResult.isValid property indicates the overall validation outcome for the document. Review the entries in validationResult.results to inspect the status of each individual signature.
Note: For additional validation scenarios, review the digital signature validation demo and documentation. They include examples covering certificate validation, revocation checking, timestamp verification, and multi-signature validation processes.
Understanding validation results
The validationResult.isValid property represents the overall validation outcome based on the validation options you supplied.
However, developers should also review the individual entries in validationResult.results, since each signature may have different validation outcomes for:
Certificate trust.
Timestamp verification.
Revocation status.
Certificate-chain validation.
Document integrity.
Reviewing individual validation results provides a more complete assessment than relying only on a single Boolean value. It also helps you make more informed trust decisions when processing signed PDF documents.
Build a trusted PDF signing and validation process
Now that we’ve covered signing, timestamping, LTV, and validation individually, let’s see how they fit together in a complete process.
Creating a trusted PDF process involves more than simply applying a digital signature. To ensure long-term document reliability, follow this recommended sequence:
Sign the PDF to establish document authenticity and integrity.
Add a trusted timestamp to record when the document was signed.
Enable LTV to embed revocation information required for future verification.
Validate the signature before accepting, sharing, or archiving the document.
Following this process helps preserve the evidence needed to validate signed PDF documents after certificate expiration or when external revocation services are unavailable.
In production environments, these four stages represent the complete trust lifecycle of a signed PDF document. Each stage adds verification evidence that helps preserve trust beyond the initial signing event.
By combining these stages, you can build secure and reliable PDF signing processes for contracts, compliance documents, business records, and other long-term digital documents.
Frequently Asked Questions
Why is a basic digital signature not enough for long-term PDF trust?
Certificates can expire, and revocation information may not always be available in the future. Without a trusted timestamp and Long-Term Validation (LTV), signature validation may lack the evidence required to verify the document over time.
What does a signature timestamp prove?
A trusted Time Stamping Authority (TSA) provides evidence of when a document was signed. This timestamp can help establish that the signature existed at a particular time and support verification against the signing certificate’s validity period.
What is LTV in PDF digital signatures?
Long-Term Validation (LTV) embeds revocation information, such as OCSP and CRL responses, directly into the PDF. This helps support signature validation even when external revocation services are unavailable.
Does the JavaScript PDF Library support PDF digital signing?
Yes. The Syncfusion JavaScript PDF Library supports certificate-based digital signatures for both new and existing PDF documents through the PdfSignature and PdfSignatureField classes.
Can LTV and timestamps be used together?
Yes. You can add a timestamp when creating the digital signature and then enable Long-Term Validation (LTV) after signing to support long-term signature verification.
How are signatures validated with the library?
Use signature.validate() to validate an individual signature and document.form.validateSignatures() to validate all signatures in a PDF document.
Digital signatures help verify the authenticity and integrity of PDF documents, but trusted timestamps, Long-Term Validation (LTV), and signature validation are essential for maintaining trust over time.
In this blog, we explored how to sign PDFs in JavaScript, add trusted timestamps, enable LTV, and validate digital signatures using the Syncfusion JavaScript PDF Library. By combining these capabilities, you can build secure PDF processes that remain verifiable long after documents are signed.
Erik Darling here with Darling Data. And I’ve got a question that I thought was interesting enough to actually answer with a brief demonstration, so I’m going to do that today. But it is about DOP and tipping points, or as I will lovingly refer to them from now on, DOPing points, because why not? Let’s just make things hard for everyone to understand. What’s wrong with that query? at the DOPing point? What’s that? You don’t want to know. It’s going to cost you $10.99 to find out. Down in the video description, there are very many helpful links for you to click on. If you’d like to hire me to fix your SQL Server performance problems, you can do that. It’s right down that way. You can also purchase my training at a discount. There’s coupons down in the doodads there. You can become a supporting member of the channel. Ask me office hours questions like I did yesterday-ish. And of course, like, subscribe, tell a friend, all that stuff. You know, the usual. If you need free SQL Server and Postgres performance monitoring, I’ve got it all under one handy umbrella. Totally free, totally open source, no weird email stuff. Just a whole bunch of perfectly written collector quiz.
queries that go and get all the stuff that you would care about as a performance tuning data professional. I recently added AGs in there, which, you know, personally, I didn’t want to do, but some people like that stuff. So here we are. And if, you know, as we transfer ourselves over to the robots, my tooling, I built it in there on purpose, has all sorts of fantastic read-of fantastic read-only MCP tools, so you can let your robot friends talk to your collected monitoring data and do all the sort of fun analysis and figuring things out for you. And then you come back and look like either a hero or an idiot, depending on what you’re using to do that analysis. So, could go either way. Choose wisely, my friends. Choose wisely. Choose wisely.
Choose wisely. And fewer than one month, I will be at Pass Summit West in Seattle, Washington, November 9th through 11th. I’ve got a pre-con there about T-SQL that doesn’t suck. You should come to that one. Because if you are out there in the world and you are using the robots to do the analysis you need you need to know what you’re talking about so the robots can’t talk past you um you know i still run into it quite a bit where uh you know i’m using my robots to do my stuff and they say something that is absolute nonsense and i’m like hey buddy bring that way back way back over here and and so you still need to know what you’re doing a little bit if you are going to remain a competent human in the loop uh with all these robots flying around doing things but it is time to continue to celebrate the month of october and uh let’s let’s do this old demo thing here so uh we’re gonna we’re gonna hope that uh the robots don’t pop anything up today i’ve asked them to i’ve asked them to take a break from anything that might pop up while i record this we’ll see how well that goes so uh i’ve created a single key column index over here uh the the because i need i want to show you something kind of interesting now uh this all has to do with query costing and at what point lookups become uh to the optimizer theoretically estimatedly more expensive than scanning something all right so if we run these two queries uh that are asking for where post type post id is less than 250 at max.1 which does limit max.1 and max.8 which remember max.1 is not min.1 this this will limit max.1 to 8 but it doesn’t guarantee max.1 will be 8 right just in case right and we did these return a lot of rows so we’re just going to work with estimated plans here when i run this these both uh let me check this up a little bit higher so uh it fills the screen and when i zoom in things don’t look dumb when we run this it for less than two post id is less than 250 they both get serial execution plans and they are both using key lookups right so we’re seeking to where post type id is less than 250 and then we are going back to the clustered index to get that user id column because that is not in our nonclustered index right and it is not the clustered primary key so it is not inherited by our non-unique nonclustered index right and then if we run these two queries for uh where post id is less than 2000 uh things change a little bit uh or rather a lot of bit at max.1 sql server still estimates that doing the lookups is cheaper than scanning the clustered index so with the single threaded query sql server is like uh i don’t know if scanning 53 million rows of the votes table is the best plan with one cpu i think i’d rather do a bunch more lookups when uh we don’t limit max.1 when we say max.1 you can go up to eight sql server is like well if i had eight of them scanning this 53 53 million row clustered index that turns out a little bit better for me right because uh that that seems like less work i don’t like we’re not looking at times or anything here i’m not saying whether the estimate the optimizer uh and its estimates are right or wrong it’s it’s it’s just showing you how it thinks and how it behaves a bit and then finally if we say where post id is less than 5000 these both do scans right sql server is like i don’t know that even at max.1 oh come on grabby thing even at max.1 that’s a lot of lookups for me uh i i think i’m just going to scan this whole thing instead so the the tipping point for these things does change depending on DOP right like DOP does have an effect on the cost models and all the other stuff there are some times where forcing a query to use max.1 retains a better plan across the board i know it’s a weird thing to say because for years everyone made fun of sharepoint and dunked on sharepoint because you had you had to have MAXDOP set to one and this was before we had the database scope configuration to uh change MAXDOP per database this was when MAXDOP was server level so if you had sharepoint on a sql server with other stuff you were like uh it’s a MAXDOP one everything sucks everywhere else well i mean sharepoint always suck but yeah whatever but there are some times where you might be in a situation where you’re like you know what i i know my data’s my data’s dictate that i never want to scan this clustered index and we’re forcing MAXDOP to one will uh be a strong enough guarantee uh for most cases this one it’s not a strong enough guarantee because uh just that less than predicate on 5 000 those are like an equality predicate we could do things differently but uh with a less than predicate like you probably don’t want to do like where where post id is less than 49 million and be like yeah you should still do a 49 million key lookup probably not a good idea but if you’re if you’re using equality predicates or you’re using very tight greater than less than with some equal twos in there maybe uh predicates and you know your data well enough where you’re like i never want to scan the clustered index no matter what sql server estimates um you know there are all sorts of ways to get sql server to do that that don’t involve creating a wider index you know you can uh have a stick a FORCESEEK hint on there uh you can use FORCESEEK with a named index uh or sometimes MAXDOP one is a good choice because for a small enough number of rows a parallel key lookup is not going to buy you right it’s just like like like what are you going to spread like you know 10 thousand rows out on eight threads that’s not a good use of eight of eight cpus why would you do that right uh small numbers of rows you don’t need lots of big numbers of rows lots of threads good small numbers of rows lots of threads not helpful right so um MAXDOP one is one interesting way one interesting hint that you can use to uh affect costing in a way that benefits you but as always test carefully all right thank you for watching i hope you enjoyed yourselves i hope you learned something and i’ll see you in tomorrow’s video uh where i actually i’m going to show you something neat with indexes so that that’ll be fun all right goodbye
Going Further
If this is the kind of SQL Server stuff you love learning about: these days I have AI do the annoying stuff for me. My new video course teaches you to work the same way, and I teach whole teams in a one-day workshop. Someone still has to know enough SQL Server to keep the robots in check, and that’s what my training is for.
SQL Server uses wait stats to track what queries are waiting on. Rather than monitoring gazillions of Perfmon counters and DMV objects, the easiest way to make your queries go faster is to ask, “What is my server waiting on?” Then, focus your efforts on your server’s top wait type.
When you’re learning how to do performance tuning in general, you wanna have a rough idea of what the top wait types are. Wonder no more: thanks to the data we gathered from thousands of SQL Servers around the world over the course of years, here are the top waits overall, and how much of the time SQL Server spent waiting on them:
That top 10 list really helps me focus my training classes on the most vital bottlenecks that will make the biggest difference in your tuning work, and your career. I know you’ve only got a limited amount of time to learn stuff, so I wanna concentrate your training on the problems you’re most likely to hit in your daily work. Let’s get you started with a summary of what each of those wait types mean, and how to begin reducing them:
CX% waits – your queries are going parallel to do a lot of CPU work, to read a lot of data, or both. Check to make sure your server has good default settings for Cost Threshold for Parallelism and MAXDOP, and then go past these CX% waits, and look at your next top wait types. Work on reducing those, and the parallelism will fall away because the queries won’t need to do as much work overall.
SOS_SCHEDULER_YIELD – queries are burning CPU. Run sp_BlitzCache @SortOrder = ‘cpu’, and work through the warnings. Usually we focus our query tuning on reducing logical reads, but that’s not what’s important here – focus on the operators burning the most CPU time.
LCK% waits – queries are being blocked. Have enough indexes to make queries fast, but not so many indexes that inserts/updates/deletes are slowed down. Tune your transactions to be as short and sweet as possible. Consider Read Committed Snapshot Isolation or Snapshot Isolation.
WRITELOG – insert/update/delete queries are waiting to write to the transaction log file. Your first instinct will be to make the log file faster, but hold off – instead, start questioning which queries are doing the most writes. Run sp_BlitzCache @SortOrder = ‘writes’ and sp_BlitzIndex @GetAllDatabases = 1, @Mode = 2, @SortOrder = ‘writes’ and ask questions about what’s happening on the server, and why.
PAGEIOLATCH – reading uncached data pages from disk. Run sp_BlitzIndex @GetAllDatabases = 1, and look at missing index requests. Run sp_BlitzCache @SortOrder = ‘reads’ and tune those queries and their indexes.
BACKUPIO – if your databases are <1TB, and you’re still doing native backups, try striping them across 4-8 files to see if you get faster throughput. As your databases approach 1TB, though, it’s time to think about storage snapshots and/or differentials.
LATCH_EX – reading cached data pages from memory, and often seen in combination with CX% waits. Start by checking sp_BlitzCache @SortOrder = ‘reads’ and sp_BlitzCache @SortOrder = ‘executions’. Can we tune these queries to read less pages, or even better, can we cache the data in the application tier instead of asking SQL Server for it repeatedly?
ASYNC_NETWORK_IO – returning results to the application. Try sampling live activity a few times to see if you notice a pattern:
EXEC sp_BlitzWho;
WAITFOR DELAY '00:00:01'
GO 5
Check out the server name, application name, and query. Is there a particular server, app, or query that repeatedly shows up? Is it an underpowered server that can’t digest the results quickly enough, or an app that’s running row-by-row calculations as each row comes down from the database server, or a query that’s returning millions of rows when it should be using pagination?
To learn more…
The above stuff is obviously only short summaries. I could – and do! – spend an hour or more on each of them, showing you examples of what kinds of queries trigger these wait types, and show you the various ways you can fix each wait type.
Because CX% and PAGEIOLATCH% waits are so important, so common, and so related to each other, I teach you how to fix them in my Fundamentals of Server Tuning class.
The rest of the top 10, plus more poison waits that I see often in the field, are covered in my Mastering Server Tuning class. And guess what? They’re on sale right now during my Black Friday sale! Go get ’em.
SQL Server limits, done the way a record book does them. Not what the documentation says, but what happened when I tried one more. Eleven records, each attempted on SQL Server 2025 build 17.0.4085.5, each with the exact error text at the edge. One documented figure turned out to be wrong on this build, by a factor of three. One test of mine measured the wrong thing.
Every record below has three parts. The attempt that passed, the attempt that failed, and SQL Server’s own words when it did. If a number is in a box, I hit it.
Record 1: columns in one table
1,024
1,024 BIT columns created. 1,025 refused.
Msg 1702: CREATE TABLE failed because column 'c1025' in table 'L_cols1025' exceeds the maximum of 1024 columns.
Record 2: characters in an identifier
128
A table named with 128 letters was created. 129 refused. Note for the record: QUOTENAME returns NULL past 128. My first attempt at this test ran nothing and reported success. The edge had to be built with square brackets by hand.
Msg 103: The identifier that starts with 'bbbb...' is too long. Maximum length is 128.
Record 3: bytes in a fixed-length row
8,060, of which 7 are overhead
CHAR(8000) + CHAR(49) + INT is 8,053 bytes of data and was accepted. One more byte and SQL Server counted for me.
Msg 1701: Creating or altering table 'L_row8054' failed because the minimum row size would be 8061, including 7 bytes of internal overhead. This exceeds the maximum allowable table row size of 8060 bytes.
Record 4: varchar(n)
8,000
varchar(8000) created. varchar(8001) refused.
Msg 131: The size (8001) given to the column 'v' exceeds the maximum allowed for any data type (8000).
Record 5: key columns in one index
32
A 32-column key was created. 33 refused.
Msg 1904: The index 'ix33' on table 'dbo.L_keys' has 33 columns in the key list. The maximum limit for index key column list is 32.
Record 6: bytes in a nonclustered index key
1,700
CHAR(1700) indexed. CHAR(1701) refused.
Msg 1944: Index 'ix1701' was not created because the index key size is at least 1701 bytes. The nonclustered index key size cannot exceed 1700 bytes.
Record 7: parameters in one stored procedure
2,100
A procedure with 2,100 parameters compiled. 2,101 refused. Nobody should ever find this out the hard way, and somebody has.
Msg 180: There are too many parameters in this CREATE PROCEDURE statement. The maximum number is 2100.
Record 8: columns in a SELECT list
4,096, with a catch
4,097 columns in the outer select list refused. 4,097 columns inside a derived table passed. The limit is checked on the outer list. And a SELECT INTO of 4,096 columns fails before it gets there, on record 1.
Msg 1056: The number of elements in the select list exceeds the maximum allowed number of 4096 elements.
Record 9: nonclustered indexes on one table
999
999 indexes on the same column created, one at a time. The thousandth refused.
Msg 1910: Could not create nonclustered index 'ix1000' because it exceeds the maximum of 999 allowed per table or view.
Where the documentation and the build part company
Record 10: levels of subquery nesting
100 nested subqueries (documented: 32)
The documented limit is 32 levels. A chain of 101 SELECT layers, which is 100 nested derived-table subqueries, passed. 102 layers refused. The documented figure is off by a factor of three on this build, in the reader’s favour.
Msg 191: Some part of your SQL statement is nested too deeply. Rewrite the query or break it up into smaller queries.
Record 11: tables in one SELECT
at least 257 (documented: limited by available resources)
Older material quotes 256. The current documentation says the limit is set by available resources, and my result agrees with it. A 257-table join compiled. I tried 300 next and the optimiser was still compiling the join after 504 seconds, so I stopped it. The edge is at least 257 and I did not reach it.
A record I withdrew
I created 254 foreign keys on one table, all pointing at the same parent, and they all passed. Then I read the documentation properly. The 253 limit counts the distinct tables one table may reference. The 10,000 figure from 2016 is the number of tables that may reference one table. My test pointed every key at one parent, so it measured neither. It’s out of the book.
What the SQL Server limits are for
Not for hitting. Nobody should be near 999 indexes or 2,100 parameters. A table with 1,024 columns is a spreadsheet with a database habit.
They’re for knowing which of the numbers you were taught are still true. One of them wasn’t, on this build. One I had wrong myself, and one test I’d have sworn was right was measuring something else.
Trust the error message. It’s the only limit that’s always current.
If your schema is closer to these edges than you’d like, that’s a sign of a different problem. I’d like to see it.
A documented limit is not a fact, it is a claim, and the error message is the fact.
 Log in