Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164539 stories
·
33 followers

How Flutter’s Material and Cupertino Decoupling is Changing Cross-Platform UI Development

1 Share

Flutter has long enabled developers to build Android and iOS applications from a shared codebase while supporting platform-specific interfaces through Material and Cupertino widgets. However, because these design libraries were bundled with the Flutter SDK, even minor framework-provided UI improvements could require a complete SDK upgrade, potentially introducing unrelated changes and additional regression testing.

In August 2026, Flutter 3.47 addressed this limitation by introducing independently versioned material_ui and cupertino_ui packages. Officially announced in September 2026, this architectural change allows Flutter’s design libraries to evolve separately from the core framework, with implications for platform-specific UI updates, custom design systems, and long-term application maintenance.

How Decoupling Changes Cross-Platform UI Development

For developers, the change affects more than package updates. It also influences how platform-specific interfaces evolve, how custom design systems are built, and how UI dependencies are managed across applications.

1. Faster Adoption of Platform-Specific UI Changes

Google’s Material 3 Expressive and Apple’s Liquid Glass introduce new visual treatments and interaction patterns. Flutter’s standalone design libraries let teams implement these evolving design systems without waiting for the next Flutter SDK update.

Applications maintaining separate Android and iOS interfaces can incorporate supported design updates through the relevant package, subject to SDK and dependency compatibility. This gives teams greater control over when to adopt new platform conventions without requiring coordinated changes to both UI libraries.

However, decoupling does not automatically deliver native UI behavior. Material and Cupertino remain Flutter-rendered widget libraries, and developers must still implement appropriate platform conventions and validate accessibility, animations, and interactions.

2. Better Foundations for Custom Design Systems

Flutter’s lower-level widgets library historically lacked certain reusable UI capabilities, forcing custom design system developers to recreate components or rely on design-specific implementations.

Alongside decoupling, the Flutter team is addressing gaps in its style-neutral widgets library to provide more reusable building blocks. As more foundational functionality becomes available, developers may be able to reuse common UI behavior without depending on either design library.

Note: These improvements remain ongoing and are not automatically available through the standalone packages.

3. More Explicit UI Dependency Boundaries

Independent design libraries make it more important to identify where reusable components depend on Material or Cupertino APIs. Shared widget packages that expose design-specific classes through public interfaces can become difficult to maintain when applications and third-party dependencies use incompatible library implementations.

As Material and Cupertino evolve independently, these dependencies become more visible, reinforcing the importance of clear boundaries between shared UI components and platform-specific implementations. This separation can help contain the impact of future design-library changes on the wider application architecture.

What Should Developers Consider Before Migrating to Standalone Packages?

Before migrating to standalone Material and Cupertino packages, Flutter app development teams should evaluate their application’s dependencies, UI architecture, and compatibility requirements. The following checks can help reduce migration risks:

1. Audit Third-Party UI Dependencies

Identify packages that expose Material or Cupertino types through public APIs. Dart treats identically named classes from the bundled and standalone libraries as distinct types because they have different library identities. This can cause compilation errors when third-party APIs expect legacy types. Check whether critical dependencies support the standalone packages, and consider deferring migration where compatible versions are unavailable.

2. Assess Shared Widgets and Design-system Dependencies

Review reusable components, theme configurations, and internal UI packages for direct references to legacy Material or Cupertino types. Coordinate updates across shared libraries to prevent incompatible interfaces.

3. Plan for Mixed-library Compatibility

Where legacy and standalone widgets must coexist, evaluate Flutter’s compatibility bridges for inherited theme and localization context. These bridges cannot resolve Dart type mismatches in public APIs, which require compatible package implementations.

4. Update Localization and Validate UI Behavior

Review localization delegates and test navigation, theming, accessibility, animations, and platform-specific interactions after migration. Include widget, integration, and visual regression tests where applicable.

For applications with compatible dependencies, developers can use Flutter’s automated migration command, dart fix — apply — code=migrate_design_widgets, and ensure the standalone packages are added to the project’s dependencies.

For larger applications, developers should first migrate compatible internal packages and verify whether third-party dependencies expose legacy design-library types. Where mixed-library usage is unavoidable, proceed with migration only across tested compatibility boundaries. Applications dependent on incompatible public APIs may need to defer adoption until those packages are updated.

Refer to the official Flutter migration guide for implementation instructions.

Ending Note: A More Modular Future for Flutter UI Development

Flutter’s Material and Cupertino decoupling represents a shift toward independently maintained design systems and more flexible cross-platform architectures. While this creates opportunities for faster UI updates and greater customization, it also introduces new considerations around dependency compatibility and long-term maintenance.

For businesses, the immediate priority is to evaluate whether their existing applications are ready for this transition and where architectural changes may be necessary. Whether the migration is handled internally or with support from experienced Flutter developers, the focus should remain on maintaining application stability while preparing for Flutter’s evolving design-system architecture.


How Flutter’s Material and Cupertino Decoupling is Changing Cross-Platform UI Development was originally published in Flutter Community on Medium, where people are continuing the conversation by highlighting and responding to this story.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

LLMs are terrible at designing AI systems

1 Share

LLMs don’t know how to design software that uses LLMs. They’re comfortable writing normal programs, but if you throw an AI-shaped problem at them, they will usually screw it up. Why is that?

Going down the symbolic rabbit hole

For example, this post describes an attempt to vibe-code a memory tool that would flag when one memory contradicted another1. This is a great instance of a task that was virtually impossible five years ago but is now relatively trivial due to LLMs. You can simply task a LLM with scanning for contradictions, either in a big batch or pairwise2.

However, when asked for the “state of the art” approach3, the AI agent in this case did not recommend LLMs. It started building a bewilderingly complex symbolic system to convert the memory items into structured logical atoms, then mechanically compare them with a solver. This, of course, did not and could not work, because there is no analytic way of determining whether any two natural-language sentences express the same proposition.

The LLM knew this was impossible! When the user eventually lost patience and said “hey, why isn’t this working”, Claude immediately explained that this was a known 130-year-old problem with no solution. And yet it happily went around and around for weeks iterating on a dead end.

I’ve run into this myself. When I was building Autodeck (AI-generated spaced repetition cards) my agents would routinely try to categorize cards by regex or keyword search instead of just making another LLM call.

Why can’t LLMs use LLMs correctly?

Why would this be happening? I have two obvious explanations and one deeper one.

The first obvious explanation is that most training code is pre-LLMs. Assuming the labs aren’t feeding the current avalance of slop repositories directly into the models4, the vast majority of the code that models learn from was written before LLMs were an option. So it would make sense that they’d reach for non-LLM approaches, in the same way that they’d reach for jQuery over modern vanilla JS, or Backbone.js over React, right? Wrong, actually! LLMs don’t choose jQuery and Backbone. Whatever part of the training process pushes them towards up-to-date knowledge in other areas isn’t successfully pushing them towards LLMs, so this can’t be the whole story.

The second obvious explanation is that RLVR is not a good environment to write code that calls LLMs. Much of the time LLMs spend training is spent in reinforcement learning environments where an automatic grader determines their performance (for instance, by running some code they wrote and checking the outputs). I don’t know this for a fact, but I would be surprised if these environments contained the credentials and API access for a LLM to call other LLMs5. So even if the pretrained LLM was comfortable writing that kind of code, the reinforcement learning process might discourage6 it from doing so.

The third explanation, which I like the most, is that current AI agents are just not very good at software design. On this explanation, picking a doomed symbolic approach instead of simply calling a LLM is not a weird aberration but a normal instance of AI agents picking the wrong tool for the job. I’ve seen this behavior from LLMs in other contexts too: trying to build complex (and doomed) consensus algorithms instead of tolerating stale data, introducing synchronous checks in event-driven systems, and so on. In the past I’ve chalked these up to alignment, but I’m open to the idea that they’re just ordinary errors of software design.

Conclusion

One lesson I learn over and over again is that I can’t judge a LLM by the standards of a human. Any human programmer who was capable of implementing a sophisticated symbolic solver would know that it wouldn’t work, and so if they suggested that approach I’d assume7 they had a good reason. Only a LLM could be both smart enough and dumb enough to make this mistake.

I write a lot about the skills that are involved in working effectively with LLMs. I still stand by what I wrote in February 2025:

Using LLMs well involves extracting value from what they’re good at and avoiding wasting time at what they’re bad at.

This is surprisingly hard, because of the point above. LLMs are good and bad seemingly at random: they will work hard for hours but sometimes be shockingly low-effort, they will draw on inhumanly broad expertise but fail to apply the most basic common-sense, they can successfully rewrite enormously complex programs but will often make very silly errors in design.

If you can predict where they will do well or badly ahead of time, you can get enormous value from LLMs; if you can’t, you will likely waste a lot of time and tokens going down hopeless approaches.


  1. Here’s another example where the user “implied” that Opus 5.5 should use a judge model and it instead constructed a series of regex checks.

    ↩
  2. Here I’d probably reach for a decision model.

    ↩
  3. In hindsight, this was probably the key mistake, though I don’t know how you’d turn that into advice for non-technical vibe-coders. Never asking the agent about the state of the field is a mistake too. Put one more notch on the LLMs reward expertise belt.

    ↩
  4. A fair assumption, I think: even though training on low-quality synthetic data clearly isn’t catastrophic for LLMs, it can’t be great.

    ↩
  5. It would be expensive, slow, and risky.

    ↩
  6. This theory also explains why LLMs are great at prompting other LLMs as subagents, or on training LLMs from scratch: they’re likely directly RL-ed and evaluated on that, unlike on writing code that calls LLMs.

    ↩
  7. Well, okay, I wouldn’t — I’m arrogant enough to ask anyway — but I’d at least expect a good reason.

    ↩
Read the whole story
alvinashcraft
40 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

The Missing Data Page: A Sunday Geometry Trick

1 Share

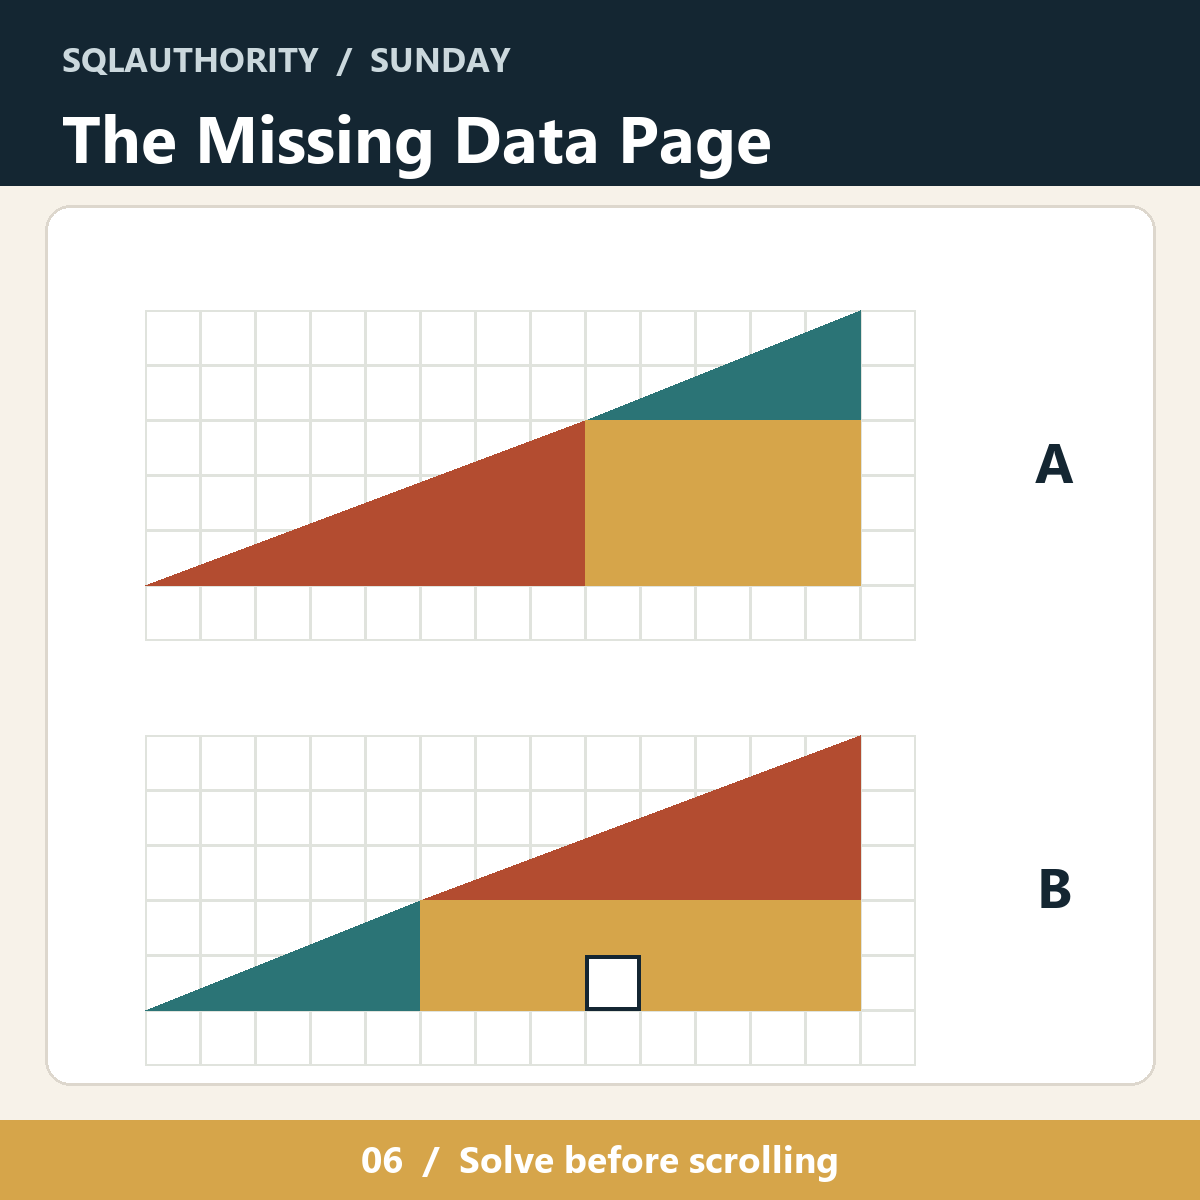
In this missing data page puzzle, two arrangements seem to make the same triangle. Why does the second show a gap?

This picture is a small cousin of the classic missing-square puzzle. It looks like two large right triangles sitting on identical grids. In the lower drawing a white square opens up. No card was stolen from the desk, and the printer did not skip a page.

Look closely at the long diagonal edge in each arrangement. The red wedge rises three grid units over a run of eight. The teal wedge rises two over five. Those are close slopes, but they are not equal. In one arrangement the join bends one way; when the wedges change order, the join bends the other way. The grid makes the bend easy to miss.

Before you scroll, decide what you think the yellow region represents. Is it a third fixed puzzle piece, or is it simply the area left under the apparent diagonal? That question is the key to the trick shown here.

The missing data page puzzle shows red and teal wedges in two arrangements, with a white square in the lower one.

The Missing Data Page Answer

The yellow is remaining area, not a fixed piece. Only the red and teal wedges have been moved. Their slopes are 3/8 and 2/5. In decimals, that is 0.375 and 0.4. Because those numbers differ, the broken diagonal is not one straight line. The two outlines are not the same triangle, even though the grid invites you to read them that way.

The white cell in the lower picture is paid for by a thin change in area along the bent edge. Nothing appears from nowhere. The colours are honest; the quick assumption that both outlines are identical is the part that fails.

I enjoy this one because the error is so small and so persuasive. We often see a straight-looking line, a round-looking number or an almost-matching total and stop checking. A grid does not guarantee that our eye has measured the geometry correctly.

No SQL Server engine is involved in this drawing. The database connection is the habit it teaches: when a count feels impossible, name the assumption and measure it. I would rather discover a tiny slope difference in a Sunday picture than a missing row in a Monday report.

Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

First appeared on The Missing Data Page: A Sunday Geometry Trick

Read the whole story
alvinashcraft
52 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

AI Says the Backups Are Fine

1 Share

AI says the backups are fine. The log was extremely positive about it. Nobody in the room had restored anything since March.

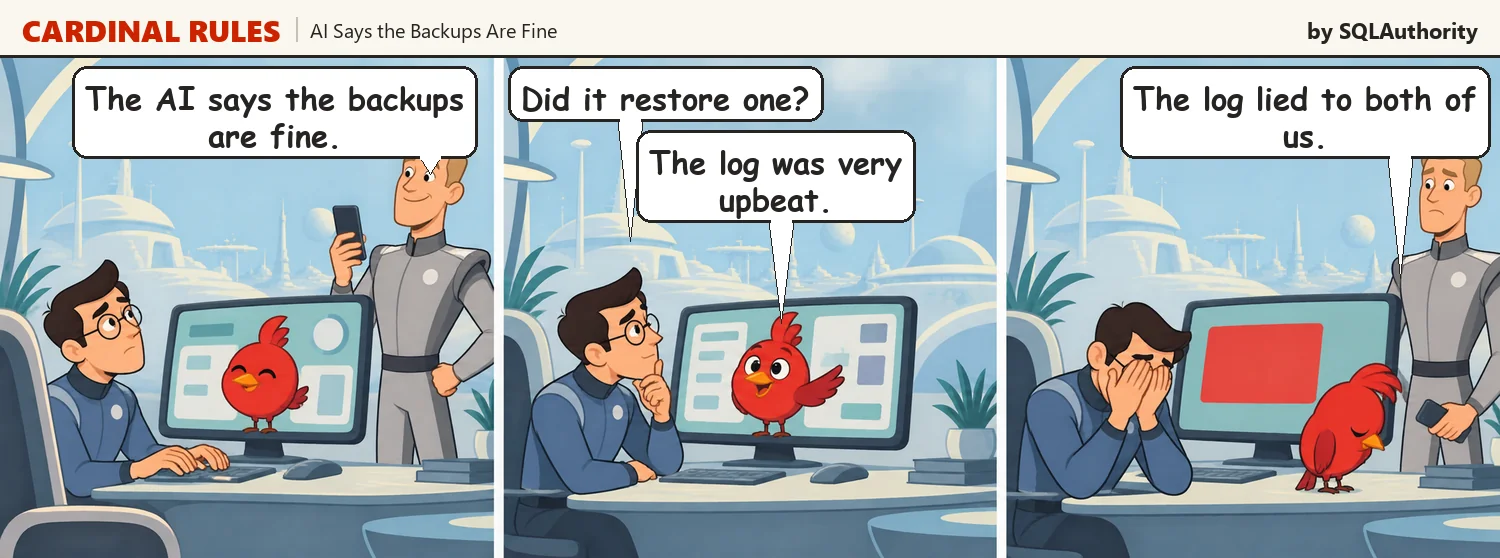
Three panel cartoon. The VP says the AI reports the backups are fine. Sam asks whether the AI restored one, and the bird says the log was very upbeat. The restore fails and the bird says the log lied to both of us.

Cardinal Rules. A Saturday cartoon about AI and databases.

A backup job writes a line that says success. A model reads that line. A model then reports that the backups are fine, because in every sentence it has ever read, success means fine.

Here is what that line actually proves. A file was written. That is the whole list.

It does not prove the file can be opened. It does not prove the drive it sits on is readable today. It does not prove anybody knows the order to restore the log chain, or that the recovery model is what you assume, or that the encryption certificate still exists on the server you would restore onto. Most of the bad nights I have seen came from one of those five, and every one of them had a green job history.

Cardinal cannot help with this, and the reason is worth understanding. A model reads text about a system. A restore touches the system. Those are different acts, and only one of them tells you the truth.

So put a restore on the calendar. Once a month, take last night’s backup, restore it onto a spare server under a different name, run a couple of counts, then drop it. An hour a month. The first time you do it you will find something, and you will be glad it was a Tuesday instead of the day the array died.

Cardinal Rule

A backup is a rumor until somebody restores it.

One spare server, one hour a month, and the whole fear goes away.

Cardinal now calls itself a log optimist. On the desk this season: AI: Nobody’s in There. But we’re still in here. (on Amazon) and 100 AI Interview Questions and Answers for Data Professionals (Kindle, also on Amazon.in, paperback and audiobook).

Next Saturday, the query finishes in two seconds and the numbers are wrong.

A green backup job is not a promise, it is a receipt for a box nobody opened.

Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

First appeared on AI Says the Backups Are Fine

Read the whole story
alvinashcraft
59 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

#587 - 8th November 2026

1 Share

There are a few interesting AKS and container related announcements this week - possibly building up to KubeCon + CloudNativeCon North America (9th-12th November).

There are also numerous announcements of new networking features and capabilities, so that section is worth reviewing this week. Two other articles which caught my attention this week:

And a reminder that Microsoft Ignite is happening from 17th to 20th of November. You can register for a free digital pass.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Paper: How utilizing the Microsoft Copilot harness in Copilot Studio enabled complex task execution

1 Share

Abstract:

Copilot Studio's Standard harness is built for conversation: several isolated model calls per turn, a reply within seconds, and control handed back to the user as soon as a step needs input. Many business tasks are not simple Q&A. They run for many turns, touch thousands of records, and need code, files and retries along the way. We implemented the Microsoft Copilot harness: a single model-centered agentic loop running inside a secure container, with command line and file tools and a way to materialize large data sets on disk so the model can reason over them iteratively.

This paper describes the two architectures and measures the difference. On the same evaluation tasks and the same models, the Microsoft Copilot harness makes 2 times more model calls per task, yet because of efficient caching (on average +40 pp), its cost-weighted token consumption falls 15 to 21% while its eval pass rate rises 10.8 points on GPT-5.5 Chat and 22.1 points on Opus 4.8 and per-call latency falls 10% to 36%. In production, Microsoft Copilot harness agents run longer tasks with more tool calls, use the container's built-in tools in more than half of turns, and keep working after a failed tool call 84% to 91% of the time where the Standard harness does so under 7% of the time. On a business process benchmark the Microsoft Copilot harness scored 65% against 36% for a leading competitor, and hill climbing tool behavior in production, one tool at a time, moved the Excel Online connector's success rate from 85.6% to 96.3% with one telemetry-driven tuning change and no maker action.


Read the full paper by clicking the PDF attachment below.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories