 Log in

I’m excited to announce the release of Entity Framework Core 11 provider for Firebird.

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


Today we are releasing Metalama MCP, a new, free and open-source MCP server that lets your AI coding agent explore C# projects and solutions, whether or not they use Metalama Framework. The agent loads your solution once, then answers questions about types, members, inheritance and references by querying the compiler’s semantic model, instead of grepping through dozens of files. When you want to see the results yourself, Metalama MCP opens them in an interactive HTML view, LINQPad style, where you can sort, filter and expand any declaration to browse the result set.
Any .NET Project, With or Without Metalama
Every exchange below is a real session against MediatR, a project that has never referenced Metalama. The first prompt loads it:
Load src/MediatR/MediatR.csproj.
load_workspace
MediatR is loaded: one project, built for net6.0 and netstandard2.0, with no load errors.
The server loads .csproj, .sln, .slnx and .slnf files with MSBuild and Roslyn, and exposes them through the same code model that Metalama aspects and fabrics use. Your projects do not need to reference Metalama. Multi-targeted projects load once per target framework, so the agent can tell you what differs between them. When your projects do use Metalama, the agent sees more: the aspect instances, the advice, and the transformed code that the aspects produce.
Asking Questions About the Code
The server exposes five tools: load_workspace, reload_workspace, unload_workspace, query and open. A query is a C# expression, or a block of statements ending with return, written against the same API as our LINQPad driver. You do not write the queries yourself: you ask in plain English, and the agent writes them.
Which classes implement an interface?
Which types in MediatR implement IPipelineBehavior?
query
workspace.GetProject( "MediatR", "net6.0" ).SourceCode.Types
    .Where( t => t.AllImplementedInterfaces.Any( i => i.Name == "IPipelineBehavior" ) )

Four types implement IPipelineBehavior<TRequest, TResponse>, all in MediatR.Pipeline: the pre-processor, post-processor, exception-processor and exception-action-processor behaviors.
AllImplementedInterfaces includes the interfaces inherited from base types, which no text search can give you. Behind the widget, the agent receives each declaration with a link it can pass back to the open tool to drill down, and a file:line location it can read with its own file tools.
Who uses this type?
Where is IMediator used, and how?
query
D<INamedType>( "T:MediatR.IMediator", project: "MediatR", tfm: "net6.0" )
    .GetInboundReferences()
    .Select( r => new { r.OriginDeclaration, r.Kinds } )

IMediator is used in two places, in both target frameworks: Mediator implements it, and ServiceRegistrar.AddRequiredServices registers it in the service collection, with typeof(IMediator) and as the type argument of GetRequiredService<IMediator>().
The references come with their kind, so the agent tells an implementation from a registration without opening the files. GetOutboundReferences() answers the reverse question, and GetDerivedTypes() walks the inheritance tree.
Where is the complexity?
Which five types have the most methods? Give me their method and property counts.
query
workspace.GetProject( "MediatR", "net6.0" ).SourceCode.Types
    .OrderByDescending( t => t.Methods.Count )
    .Select( t => new { Type = t, Methods = t.Methods.Count, Properties = t.Properties.Count } )
    .Take( 5 )

MediatRServiceConfiguration leads with 26 methods and 17 properties, ahead of ServiceRegistrar with 19 methods. No other type has more than 9 methods.
The workspace was loaded once, so follow-up queries take milliseconds. Projections to anonymous types render as tables, and declarations keep their links.
The Interactive HTML View
Text output is for the agent. For you, there is a browser view:
Show me this list in my browser.
query with format: html
Here it is: https://localhost:53271/…/r/HuYiYdCC7GdXNPhW. The link works as long as the MCP server is running.
The page works much like LINQPad:

- Sort and filter. Click a column header to sort; the Filter box keeps the rows that contain a text.
- Expand on demand. Click a declaration to expand its properties in place. Values are loaded from the server as you click, so you can walk from a type to its methods, to their parameters, to their references.
- Jump to the source. One icon opens the declaration on its own page, the other opens the source file at the right line in your editor.
- Hand back to the agent. The link button copies the link the agent accepts, and the C# button copies a C# expression that resolves the declaration in a query.

The query at the top of the page is editable. It has completion, tooltips, parameter hints and error underlines, and Ctrl+Enter runs it again. The agent writes the first draft of the query; you refine it yourself.

A download button saves a snapshot of the page that works without the server.
Agents that support MCP Apps, such as Claude, show results inline in the conversation, as in the replies above. Once a result has been shown in the browser, the widget gets an Open in browser button that takes you to the full page.
Inspecting the Aspects of a Metalama Project
When a project uses Metalama Framework, the agent also sees its aspects: which ones are applied, where, and what they changed. Our own example is the web application behind our store and customer portal. Its nine projects use Metalama Patterns for caching and contracts, plus three aspects of our own.
Which aspects are used?
Load our web application and tell me which aspects it uses, and how often.
load_workspace
query
workspace.AspectClasses
    .Where( c => c.Instances.Any() && !c.FullName.StartsWith( "Metalama.Framework" ) )
    .OrderByDescending( c => c.Instances.Count() )
    .Select( c => new { Aspect = c, Instances = c.Instances.Count() } )

Six aspects, applied 86 times. Three are your own: [AppSettingsProperty] (35), [KeyVaultProperty] (7) and [ExpandEmailProperty] (4) bind properties to application settings, Key Vault secrets and e-mail placeholders. The other three come from Metalama Patterns: [Cache] (20), and the [Required] (16) and [NotNull] (4) contracts.
The filter on Metalama.Framework leaves out the aspects that Metalama creates for its own needs.
Where is this aspect used?
Where is [Cache] used?
query
workspace.AspectInstances
    .Where( a => a.AspectClass.ShortName == "Cache" )
    .Select( a => a.TargetDeclaration )

On 20 methods. 12 are in CrmFacade, which caches the CRM lookups: products, prices, discounts, countries and users. The other 8 are in the web application itself: the product and account services, the GeoIP and VAT lookups, the country list, and the Metalama unit prices.
Each aspect instance also knows what created it, the advice it added, and the code it produced: the agent can follow it into TransformedCode to show you a method as it compiles, with the caching in place.
What the Agent Can Query
The workspace object exposes:
- Source code:
SourceCode.Types,Methods,Fields,Properties,Constructors,Events, across all projects and target frameworks. - References:
GetInboundReferences(),GetOutboundReferences()andGetDerivedTypes(). - Diagnostics: the compiler warnings and errors, and the load issues of the workspace.
- Metrics: from
Metalama.Extensions.Metrics, such as the number of syntax nodes of a method. - For Metalama projects:
TransformedCode,AspectClasses,AspectInstances,AdviceandTransformations.
The agent finds its way through this object model on its own, but you can read it too: see the Introspection API reference.
Getting Started
The server is the metalama-mcp .NET tool. It requires the .NET 10 SDK or later.
dotnet tool install -g Metalama.Mcp
With Claude Code:
claude mcp add metalama -- metalama-mcp
Other agents, such as GitHub Copilot and Cursor, take the same command in their MCP configuration. Start the agent from your repository directory, because the server resolves relative paths against its working directory. For the browser view, trust the .NET development certificate once:
dotnet dev-certs https --trust
The MCP server is part of Metalama 2027.0, currently in preview. See Using the MCP server for the details.
This article was first published on a https://postsharp.net/blog under the title Query Any .NET Codebase from Your AI Agent with the Metalama MCP Server.
Pennsylvania, USA
Powerplant, our tool for improving AI dev workflows using coding agents’ session traces, is now open without an invite:
Today we’re excited to announce that Powerplant is now available to all, and is free for teams under 25 seats.
Modern dev teams need to be able to leverage their coding agent sessions. These traces help make PRs more reviewable, improve in-repo skills and instructions, and can even explain why you’re spending a face-melting amount of money on Claude Enterprise. But developers shouldn’t need to push every agent session irrevocably to git to get this benefit.
If that sounds appealing to you, try Powerplant. Let me know how it could be better for your team, and we’ll donate $50 to Rewiring America or Let’s Encrypt. ⚡️
Pennsylvania, USA
Learn the benefits of using generic type arguments using the @typeparam directive to implement reusable and type-safe Razor components.
Generic type support brings generic types to Razor components, letting us build scalable Blazor web applications.
In this article, we will learn how to use generic types in our Razor components and when we might want to consider using them.
Hint: If you are new to generics in C#, please familiarize yourself first with generic types and methods in C# to be able to follow along.
You can access the code on GitHub.
Implementing a Simple Generic Razor Component
The @typeparam attribute allows us to define a generic parameter for a Razor component.
Consider the following simple generic NamedObjectRenderer component:
@typeparam TType where TType : INamedObject

<div>@Object.GetName()</div>

@code {
    [Parameter]
    public required TType Object { get; set; }
}
This component defines a generic type using the @typeparam directive.
We can then use TType as the type for the parameter property called Object.
Since we use a type constraint, we can use the GetName method defined in the INamedObject interface:
public interface INamedObject
{
    string GetName();
}
Now, let’s use the component.
@code {
    private Person person = new Person { Name = "Peter Parker", Age = 22 };

    public class Person : INamedObject
    {
        public required string Name { get; set; }
        public required int Age { get; set; }

        public string GetName()
        {
            return Name;
        }
    }
}
First, we create a Person class that implements the INamedObject interface. We add two properties Name and Age, and provide the value of the Name property in the GetName method from the INamedObject interface.
The usage of the NamedObjectRenderer component is straightforward:
<NamedObjectRenderer Object="person" />
We provide an object of the Person class as the argument for the Object parameter of the NamedObjectRenderer component.
Hint: Notice that we do not specifically provide the Person type as an argument for the TType parameter. That’s possible because Blazor is able to infer the type of the provided object.
It’s also possible to explicitly provide the type for the generic type argument. However, in most cases, type inference is good enough and makes using generic Razor components straightforward.
<NamedObjectRenderer Object="person" TType="Person" />
Implementing a Higher-Level Generic Razor Component
The previous example demonstrated the foundation of how to implement generic Razor components.
I agree that the example doesn’t feel revolutionary. There might be use cases here and there for it, but it does not change the general approach to how you will implement your Blazor web applications.
However, we can build on that foundation and implement a more advanced generic Razor component that has the potential to change how you structure and architect your Blazor web applications.
Consider the following scenario: We want to render two columns on the screen. A name and a value column. We want to implement a single component to encapsulate the behavior and the look and feel of the component.
But there is a twist! We want to be able to use that component with completely different data objects.
The following generic DataTable component is a great example:
@typeparam TItem

<table style="margin-top: 20px">
    <thead>
        <tr>
            <th style="width: 120px">Name</th>
            <th>Value</th>
        </tr>
    </thead>
    <tbody>
        @foreach (var item in Items)
        {
            <tr>
                <td>@GetName(item)</td>
                <td>@GetValue(item)</td>
            </tr>
        }
    </tbody>
</table>

@code {
    [Parameter]
    public IEnumerable<TItem> Items { get; set; } = [];

    [Parameter]
    public required Func<TItem, string> GetName { get; set; }

    [Parameter]
    public required Func<TItem, string> GetValue { get; set; }
}
Again, we define a generic type argument using the @typeparam directive at the top of the component.
In the code section, we use that type to implement three parameter properties. The Items property of type IEnumerable<TItem> contains a list of the provided items.
This list is looped through in the template section of the code, and for each item, the GetName and GetValue functions provided in the second and third component parameter are called.
Now, let’s see how we can use that component in our applications and why this implementation is as powerful as I advertised it.
@page "/"

<DataTable Items="persons"
           GetName="p => p.GetName()"
           GetValue="p => p.Age.ToString()" />

@code {
    private Person[] persons = [
        new Person { Name = "Peter Parker", Age = 22 },
        new Person { Name = "Mary Jane", Age = 20 }
    ];

    public class Person : INamedObject
    {
        public required string Name { get; set; }
        public required int Age { get; set; }

        public string GetName()
        {
            return Name;
        }
    }
}
Here, we have the same Person class we already used in the first chapter of this article. We create a list of Person objects and provide that list to the Items parameter of the DataTable component.
The magic happens in the definition of the GetName and GetValue parameter functions.
We use a lambda expression to define the behavior of the GetName and GetValue parameters.
For the Person class, we use its GetName method to render the person’s name, and for the value column, we use the Age property and call its ToString method.
By using a generic type argument, we can implement the behavior of the DataTable component outside the component definition.
Let’s look at a second example using a completely unrelated object:
@page "/"

<DataTable Items="animals"
           GetName="p => p.Name"
           GetValue="p => p.Type" />

@code {
    private Animal[] animals = [
        new Animal { Name = "Tom", Type = "Cat" },
        new Animal { Name = "Cherry", Type = "Mouse" }
    ];

    public class Animal
    {
        public required string Name { get; set; }
        public required string Type { get; set; }
    }
}
Here, we implement an Animal class with two properties Name and Type.
We want the animal’s name (what the owner calls the pet) and its type (kind of animal).
We can reuse the same DataTable component and provide a list of animals to the Items property. Again, type inference works perfectly; we do not need to explicitly provide the Animal type.
And again, we implement the behavior from outside the DataTable component when we use it, rather than when we define it. We use the Name property for the name column value and the Type property for the value column.
This example shows how to implement flexible, generic Razor components that let you share code across multiple uses of the same component and let each instance provide the behavior.
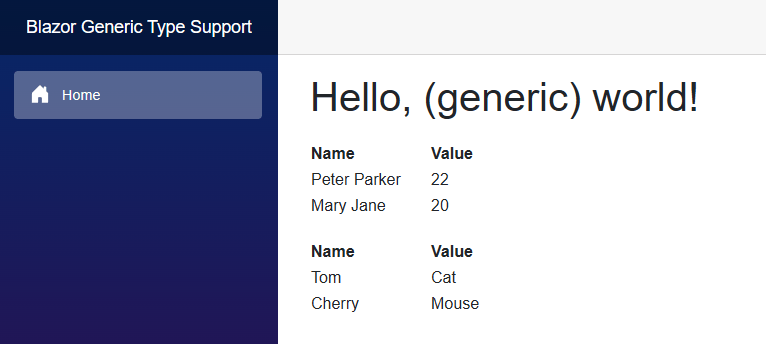
We can see that the look and feel of the first and the second list are exactly the same while we know that we provided two completely unrelated data types.
The Advantages of Generic Razor Components
We learned how to use the @typeparam directive to implement a generic type argument for Razor components.
We also implemented two examples that show how to build generic Razor components for your Blazor web applications.
Now, let’s look at the advantages of using generic type arguments in Razor components more broadly:
- Generic type arguments make components more reusable and keep them type-safe. Instead of using object as the base type of a parameter or using
System.Reflection, the compiler provides a type-safe environment. - Using the
Func<TItem, ...>construct, we can inject/provide behavior from outside the component. It is possible to use different behavior in each component instance depending on the data provided.
The component in our second example does not need to know whether it renders a list of animals, persons, or buildings. But it is responsible for providing a consistent and user-friendly experience. - Thanks to type inference, we do not need to explicitly provide the generic type when using the component. Blazor can infer the type for us. This helps us keep the code concise and expressive.
In short: Generic type support lets us implement generic type arguments in Razor components, allowing us to reuse a type-safe component that provides a consistent look and feel and provides the behavior for each instance.
Conclusion
Generic Razor components are a powerful tool for building reusable and type-safe Blazor applications. By using the @typeparam directive, we can create components that work with different data types.
Generic components can separate a component’s presentation (rendering) from its data and behavior.
In the DataTable example component, we demonstrated how to use the same Razor component with two completely unrelated data classes.
Compared to implementing a Razor component for each data type and somehow finding a solution to share the template code, generic type arguments provide an elegant and concise solution.
If you want to learn more about Blazor development, watch my free Blazor Crash Course on YouTube. And stay tuned to the Telerik blog for more Blazor Basics.
Pennsylvania, USA
Build an image for a NestJS project and deploy it on Google Cloud Platform and learn common tweaks and tips for updating and improving deployed services.
Containers allow us to package software and all its dependencies into a lightweight, portable unit that we can run and scale either locally or in the cloud. Google Cloud Run is a service provided on Google Cloud Platform that allows developers to deploy and scale containers for virtually any kind of application with minimal effort.
Before running containers, we have to build images. Google Cloud Run allows us to build them in the cloud using buildpacks, or build them locally on our PC with container runtimes like Docker or Podman. This article will focus on the latter. We’ll build an image for a NestJS project and deploy it on Google Cloud Platform. We’ll also cover common tips for updating and improving deployed services.
Prerequisites
This guide assumes that you’re familiar with server-side programming in TypeScript and have some familiarity with a container runtime like Docker or Podman.
Project Setup
Let’s start by setting up the NestJS project we’ll be deploying. Open your terminal and run the following command:
ng new my-nest-backend
The command above uses the Nest CLI to create a project in a folder called my-nest-backend. Follow the prompts and accept all the defaults.
Next, let’s install the dependencies we’ll be needing. Run this command in your terminal:
pnpm i -save @nestjs/config
We installed the config module to use environment variables. Later on, we’ll show how to add and use environment variables in our deployment. For now, run this command in your terminal to create a file that will hold environment variables locally.
touch .env
Next, update the .env file to look like this:
MESSAGE=dev-message
Now let’s update the contents of our app.module.ts file.
import { Module } from '@nestjs/common';
import { AppController } from './app.controller';
import { AppService } from './app.service';
import { ConfigModule } from '@nestjs/config';
import { CoreModule } from './dummy/core.module';

@Module({
imports: [
ConfigModule.forRoot({
    isGlobal: true,
    ignoreEnvFile: process.env.NODE_ENV === 'production',
    envFilePath: [process.env.NODE_ENV !== 'production' ? '.env' : ''],
}),
CoreModule,
],
controllers: [AppController],
providers: [AppService],
})
export class AppModule {}
We updated our app.module.ts to use the config module. There are two things to notice here: when not in production, we read environment variables from the .env file. In production, notice that the ignoreEnv option will be true. This allows our app to read any environment variables we inject into the container when we run our application in the cloud.
We’ll also need one endpoint. Let’s now update the app.controller.ts file with the following:
import { Controller, Get, Post } from '@nestjs/common';
import { AppService } from './app.service';

@Controller()
export class AppController {
constructor(private readonly appService: AppService) {}

@Get('/')
getHello(): string {
return this.appService.getHello();
}
}
Also update your app.service.ts file with the following:
import { Injectable } from '@nestjs/common';
import { ConfigService } from '@nestjs/config';

@Injectable()
export class AppService {
    constructor(private readonly configService: ConfigService) {}
    getHello(): string {
    return this.configService.getOrThrow<string>('MESSAGE');
    }
}
Our demo app has one route, /, which, when triggered, calls the getHello method. This method returns the value of the MESSAGE environment variable.
To see our running application, open your terminal and run the following command:
pnpm run start:dev
Our app currently listens on port 3000, as shown in the main.ts file below:
import { NestFactory } from '@nestjs/core';
import { AppModule } from './app.module';

async function bootstrap() {
    const app = await NestFactory.create(AppModule);
    await app.listen(process.env.PORT ?? 3000);
}
bootstrap();
Notice that our app listens on the special process.env.PORT value when provided. This will be important in production, since this value will be dynamically injected when the application is running within the container. For now, since we don’t have it set locally, it defaults to port 3000.
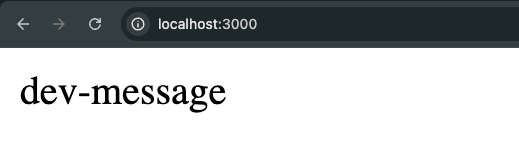
Now visit http://localhost:3000 to see the running application, as shown below:
Building the Image
We need to build the application’s image before running it as a container. We already mentioned in the introductory section that the image can be built either locally or remotely.
When building locally, we can either use local buildpacks or, as in our case, leverage container runtimes like Docker or Podman.
Now, within the my-nest-backend folder, create a file called Dockerfile and update its contents as follows:
FROM node:22-alpine AS builder
WORKDIR /app
RUN npm i -g pnpm@9
COPY package.json pnpm-lock.yaml ./
RUN pnpm install
COPY . .
RUN pnpm run build

FROM node:22-alpine AS runner
WORKDIR /app
COPY --from=builder /app/node_modules ./node_modules
COPY --from=builder /app/dist ./dist
USER test
EXPOSE 3000
CMD ["node", "dist/main.js"]
Our Dockerfile is straightforward: it has two main stages. In the first stage, we install the pnpm package manager, use it to install all dependencies listed in package.json, and then build the app.
The second stage simply copies over the contents from the build step: the node_modules folder and the generated dist folder, from the first (builder) stage.
For security reasons, we also set the USER to test so that commands don’t run as root. The EXPOSE instruction just documents in the image metadata that the app may listen on port 3000. Finally, the CMD instruction holds the command used to start the container from the image.
To build the image, open your terminal within the project directory and run the following command:
docker build . -f Dockerfile --platform linux/amd64 -t chrisnw/dummy-app:0002
The command above builds the image. The period (.) defines the build context, which in our case is the my-nest-backend folder. The -f flag specifies the file where the build script is located. This is optional if the file is named Dockerfile; we only added here for clarity.
Also notice that we specified the --platform flag and set it to linux/amd64. This is important to allow the generated image to run correctly, particularly when the image is built on an Apple Silicon machine.
We tag the image chrisnw/dummy-app:0002. This follows the standard format of <DOCKER_HUB_USERNAME>/IMAGE_NAME:TAG. If you don’t have a Docker Hub username, feel free to create one.
To push the image to Docker Hub, run the following command:
docker push chrisnw/dummy-app:0002
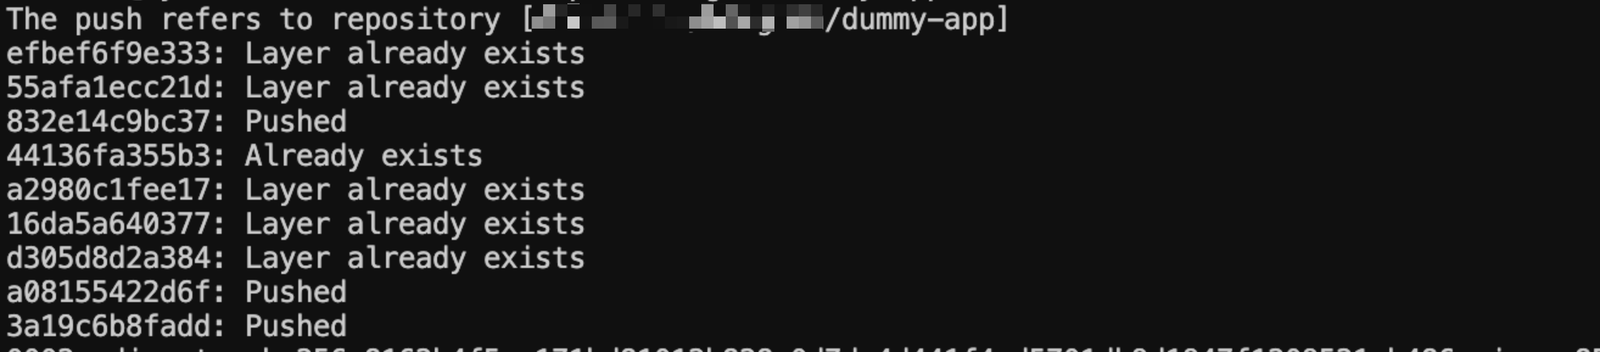
As seen above, the command executes successfully. The Docker image is pushed to the personal Docker Hub registry associated with the specified username.
Deploying the Container on Google Cloud Run
Internally, Google Cloud Run is based on Kubernetes, but with a simplified interface. Users are able to run any kind of workload, provided it’s housed in a container. You can either provide a built image, like we did, or have Cloud Run build it for you, either by pointing it to your source code or by using their provided buildpacks to have the build done in the cloud.
To start, visit Google Cloud Platform and create a project. Note that we can use the gcloud CLI to execute all these steps in the terminal, but for simplicity, we’ll be doing everything through the UI.
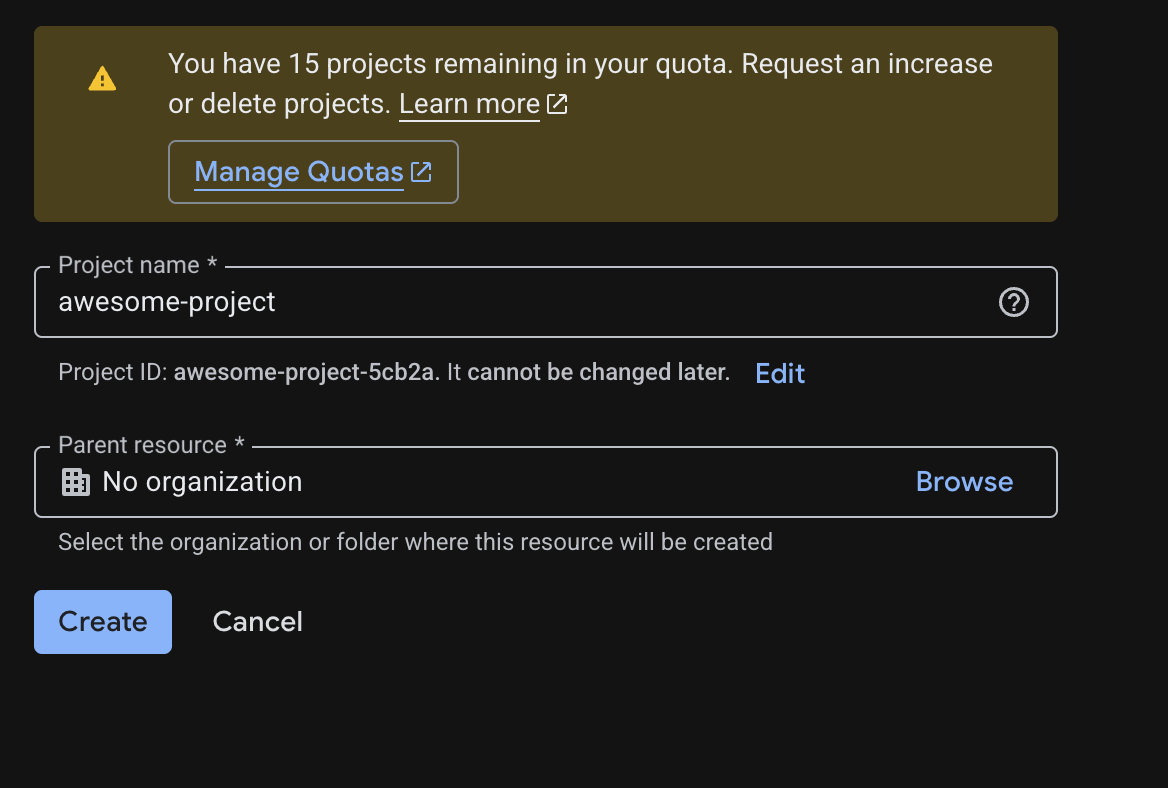
Select the project as the default project, as shown below.
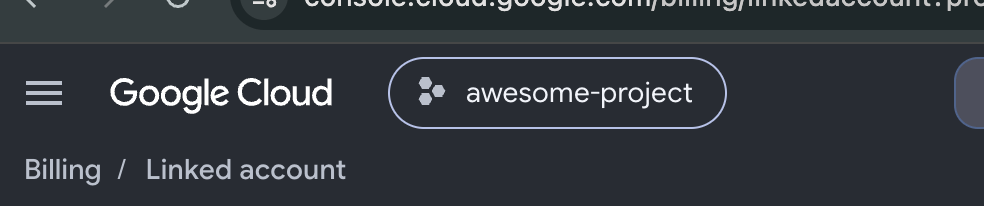
Next, we need to enable billing on our project to be able to use Cloud Run. Select Billing from the sidebar.
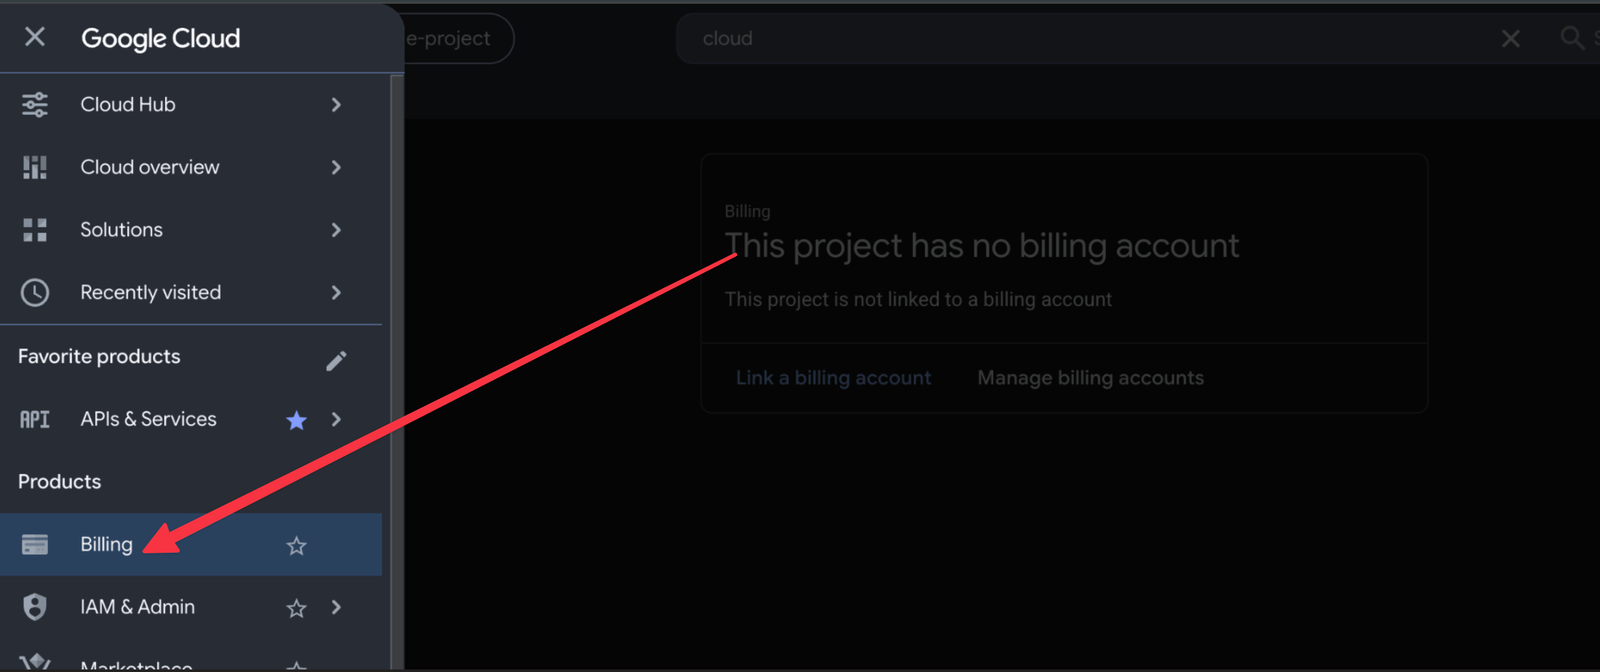
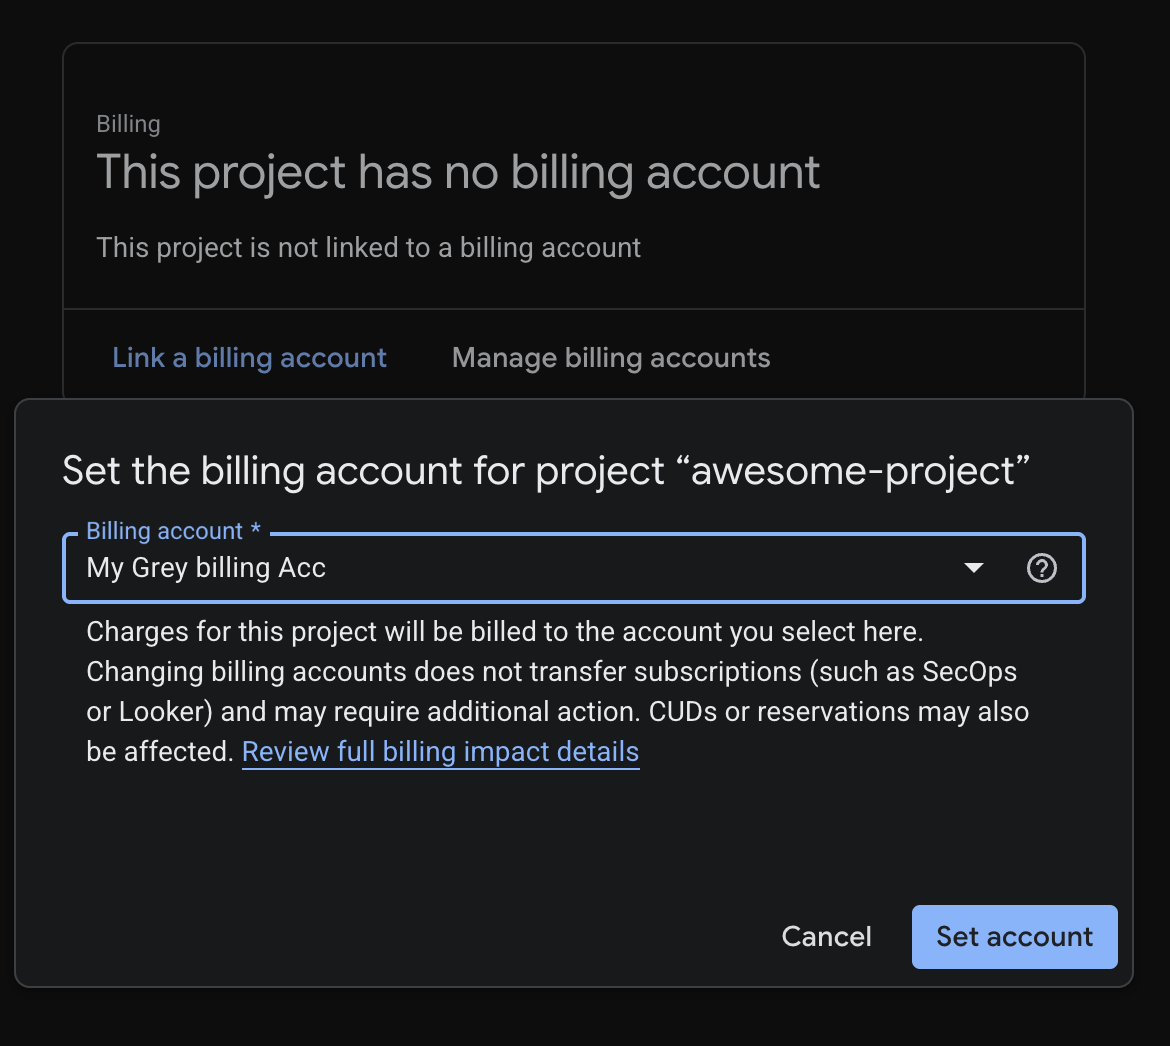
Next, click on “Link a billing account” and select an account to link.
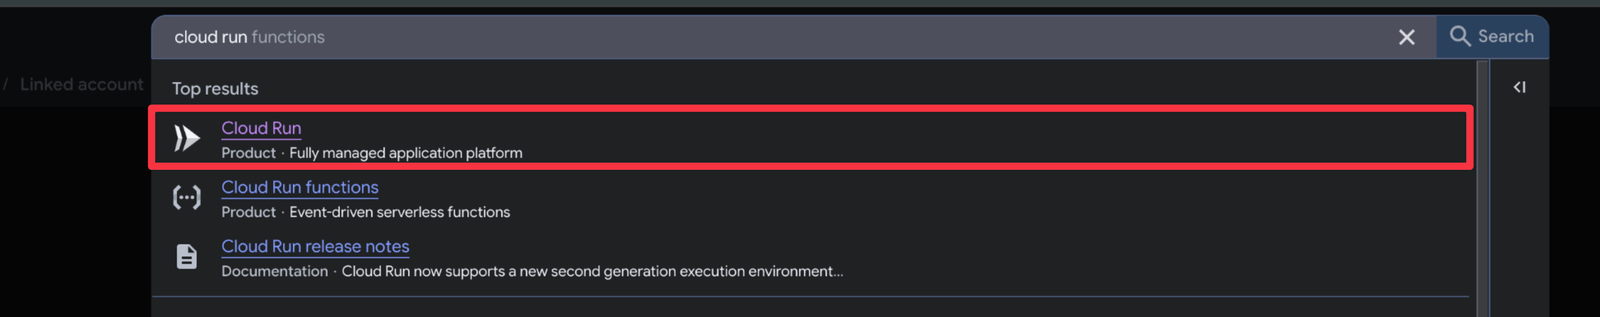
Now that billing is set up, we can go to the Cloud Run console. The quickest way to access it is by using the search bar.
Creating a Service
Now click on Cloud Run. Next, on the sidebar, select Services and click on Deploy container.
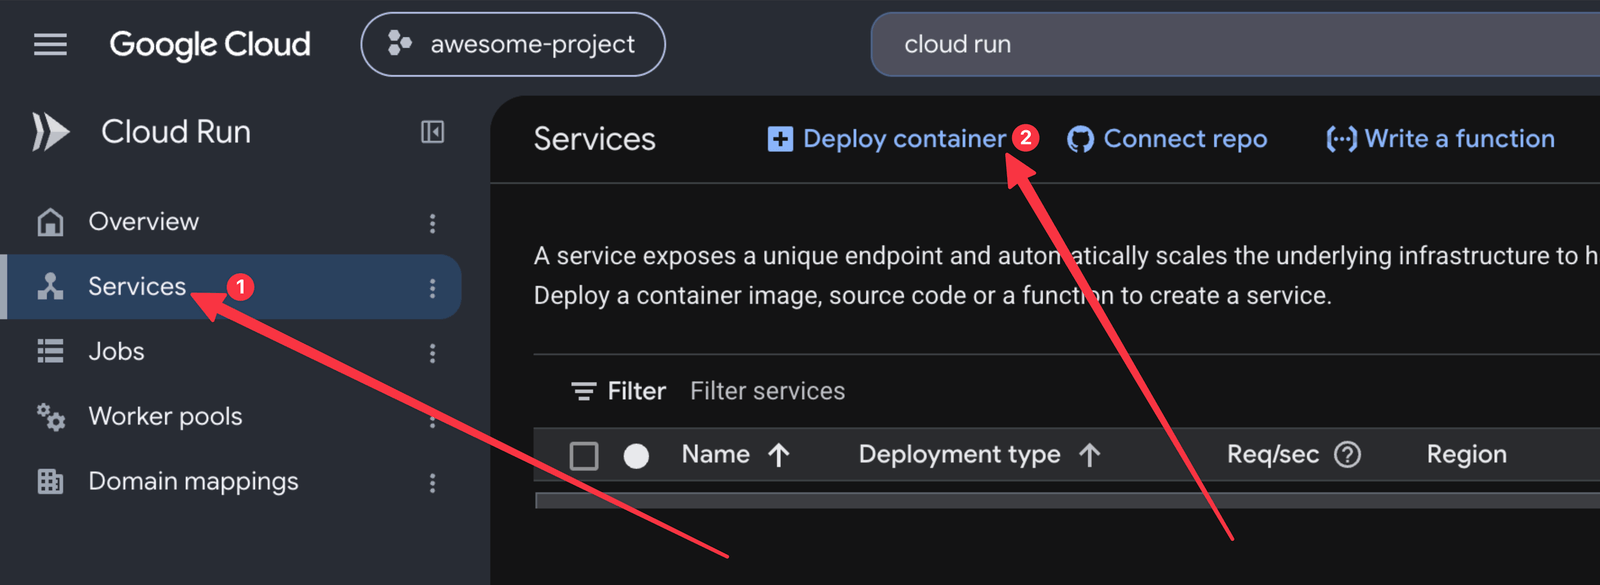
We chose the Service option because this is used for any HTTP-triggerable workload, like a web server in our case. Note that a service can be used to run one or more containers.
After clicking on Deploy container we’re presented with a form to configure the service before deploying.
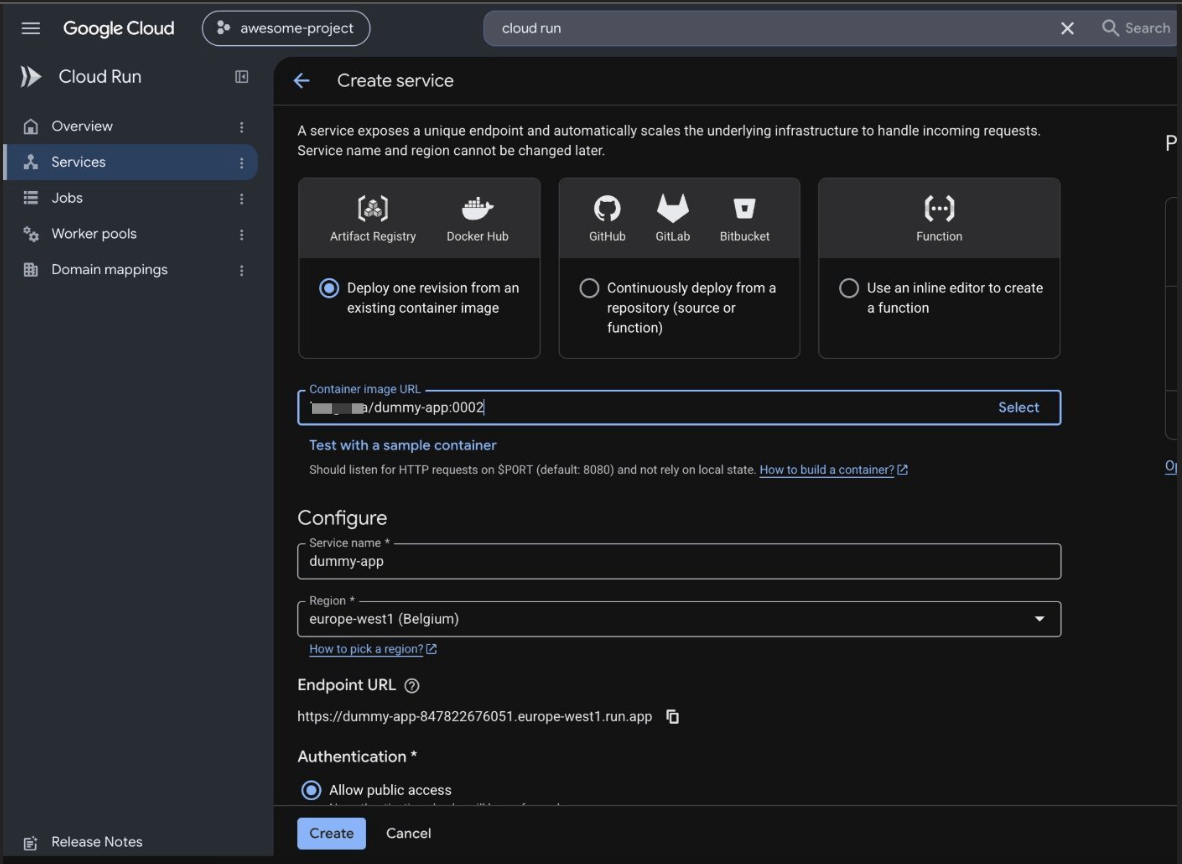
We choose “Deploy from a container image”, then provide the URL to the image we just pushed to Docker Hub. We name our service dummy-app. Notice that we also get an automatically generated URL to visit our application. In our case, it’s https://dummy-app-847822676051.europe-west1.run.app/.
Configuring Instances and Billing
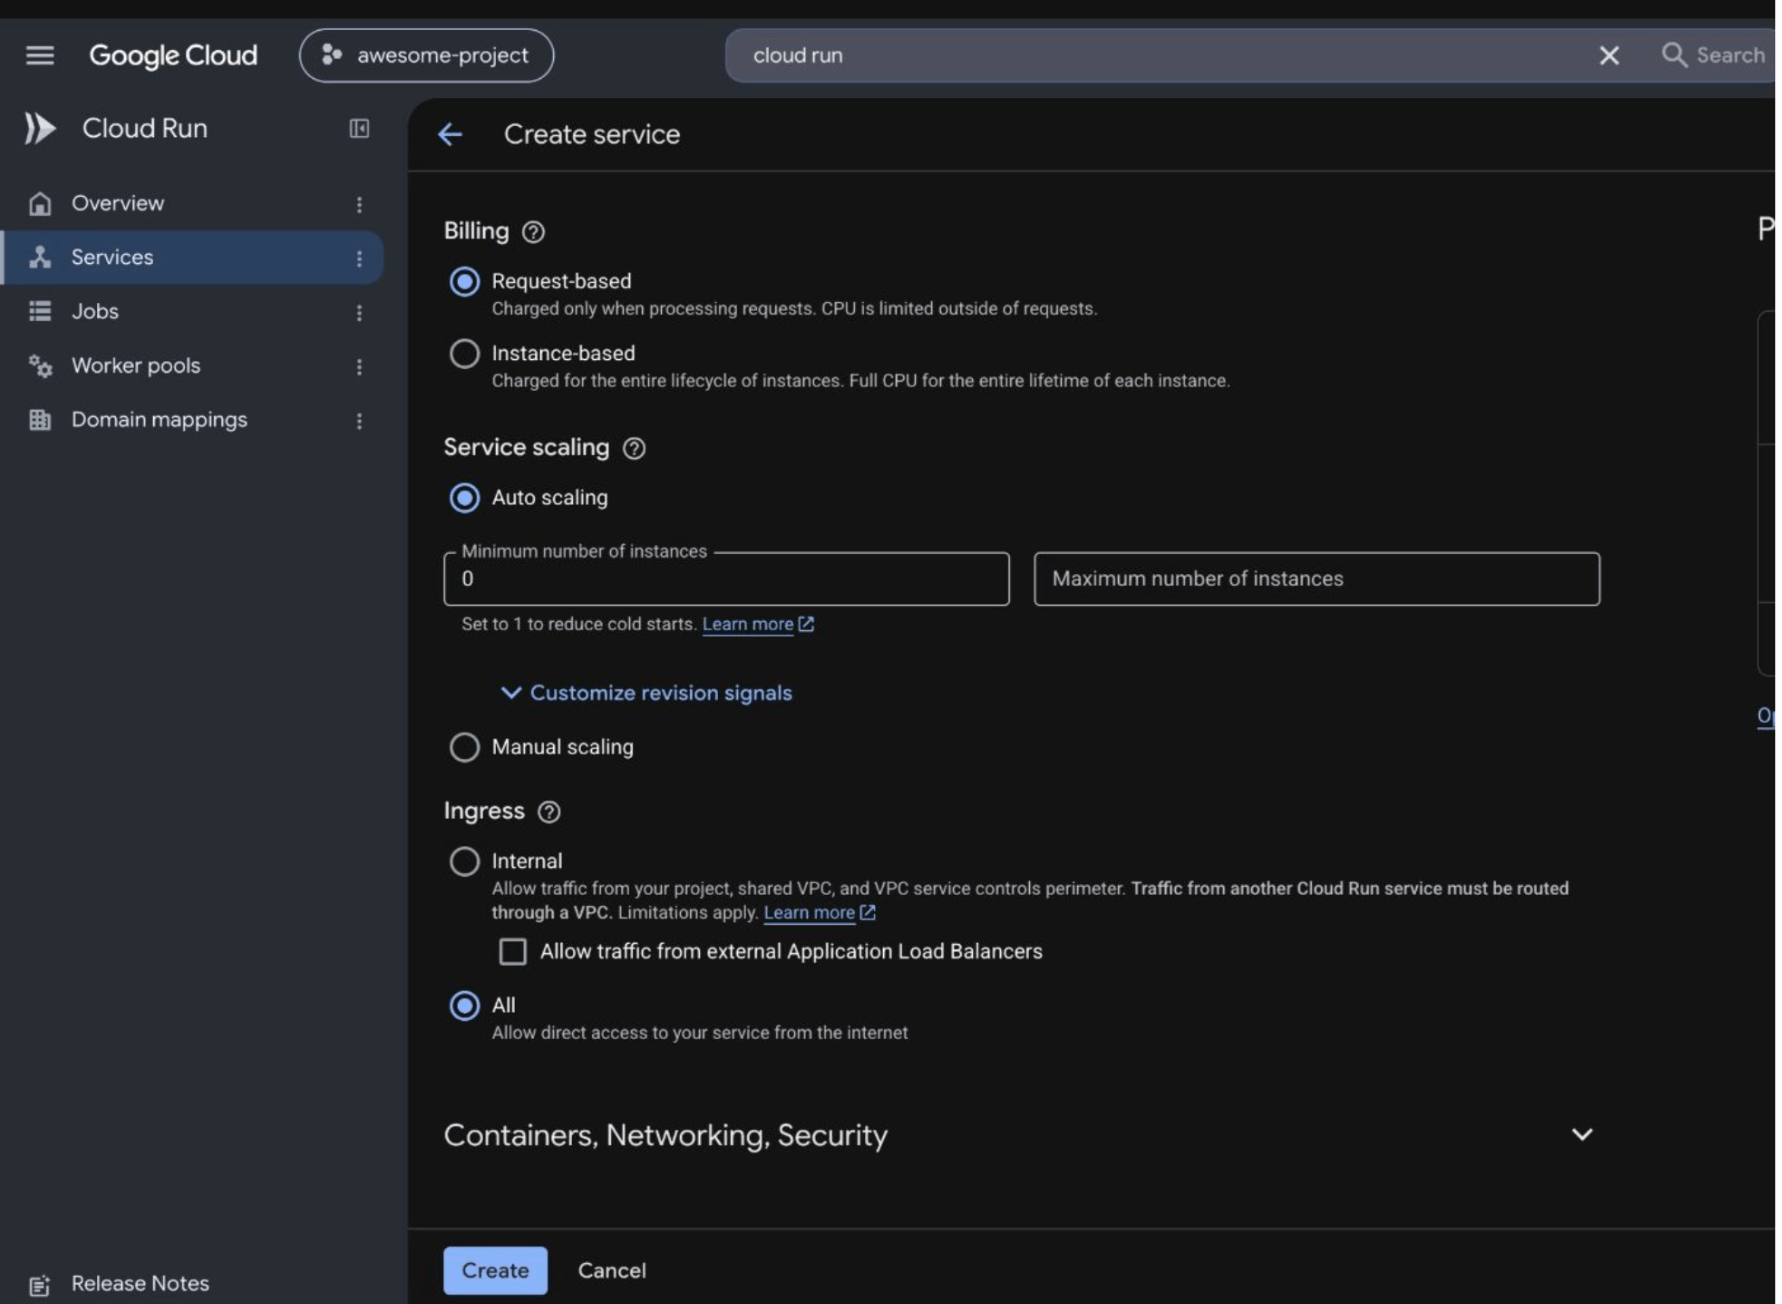
Services can be billed per request or per instance. Request-based billing, as the name implies, means you’re charged per request to your server. This way, lower traffic means lower charges, and vice versa.
However, your server won’t be able to run background tasks like CRON jobs or spawn workers to process tasks in a queue, since instances sleep when there’s no traffic.
If your web server needs to do this, it’s preferable to opt for instance-based billing and specify a minimum number of instances to run, so the server is reachable and running without any cold starts. For our small server, we’re fine with the request-based setup.
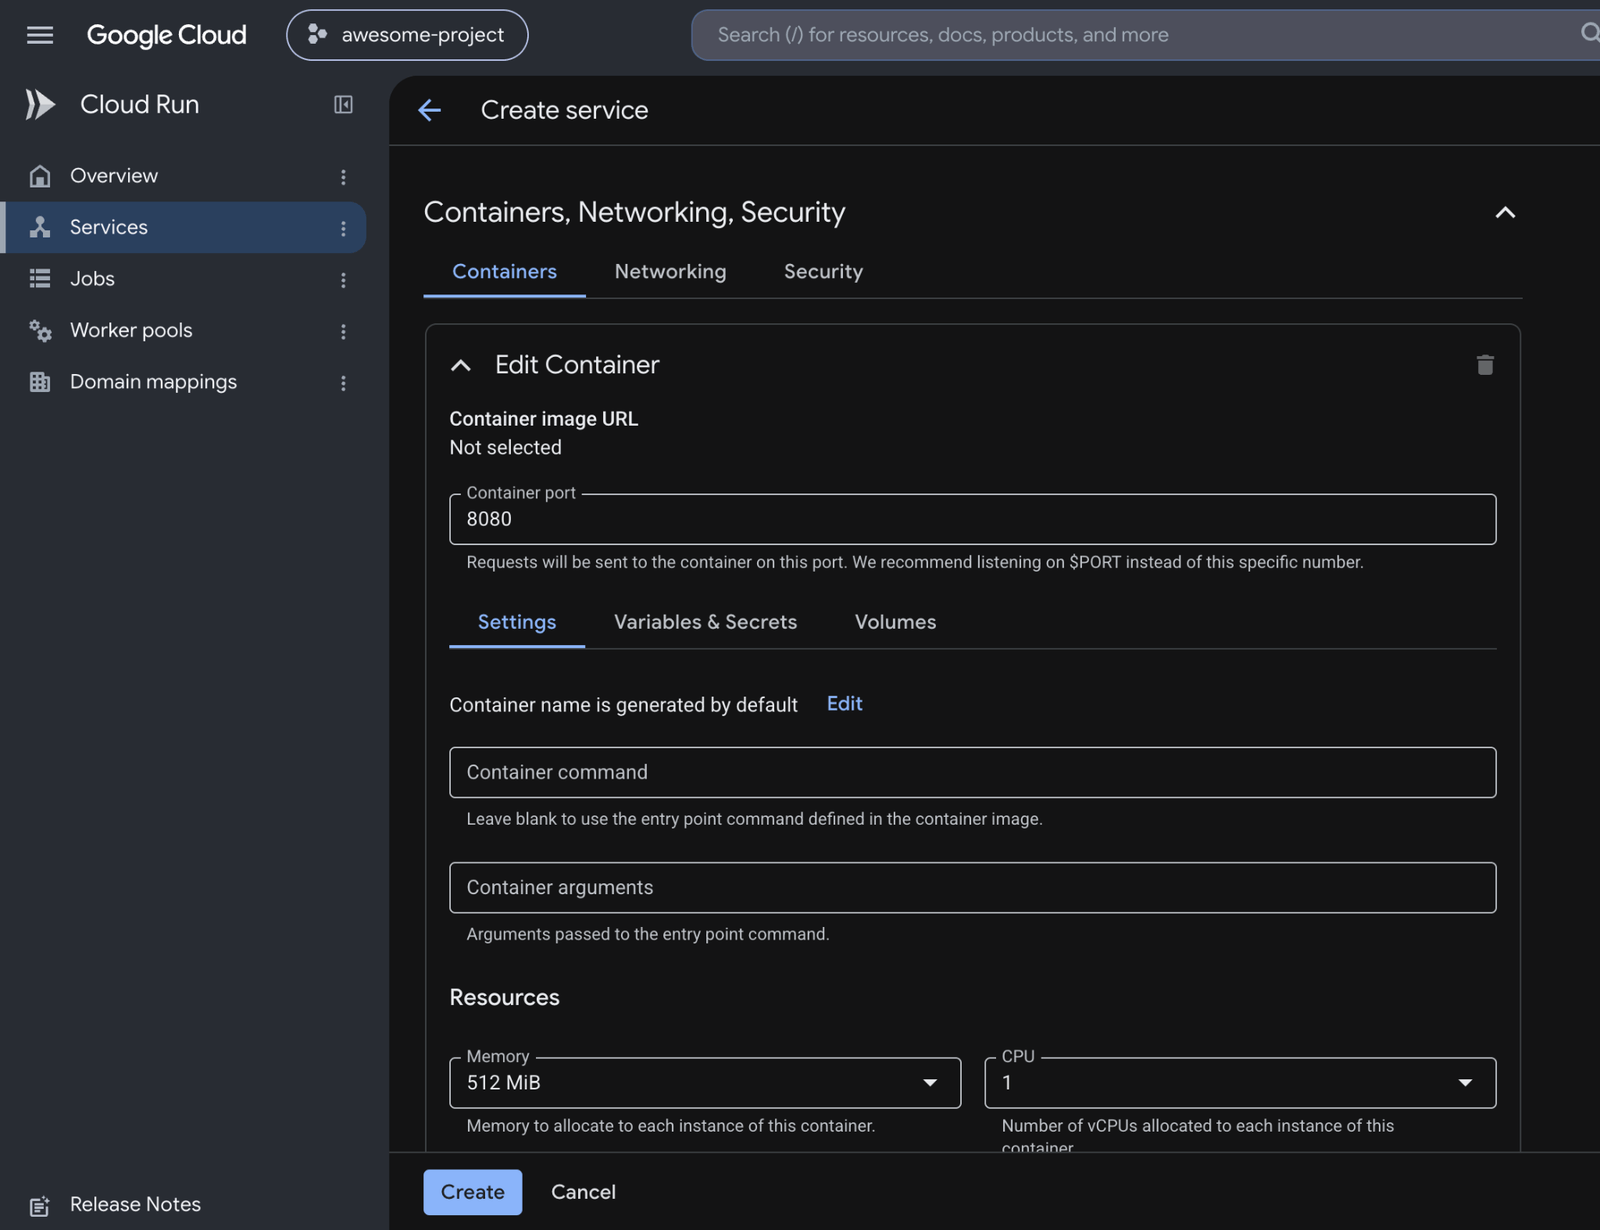
Next, we need to configure the container settings. For memory and compute, we leave the defaults. We didn’t set the container command field, since we already set it when we built the image—i.e., the CMD ["node", "dist/main.js"] we set earlier in our Dockerfile.
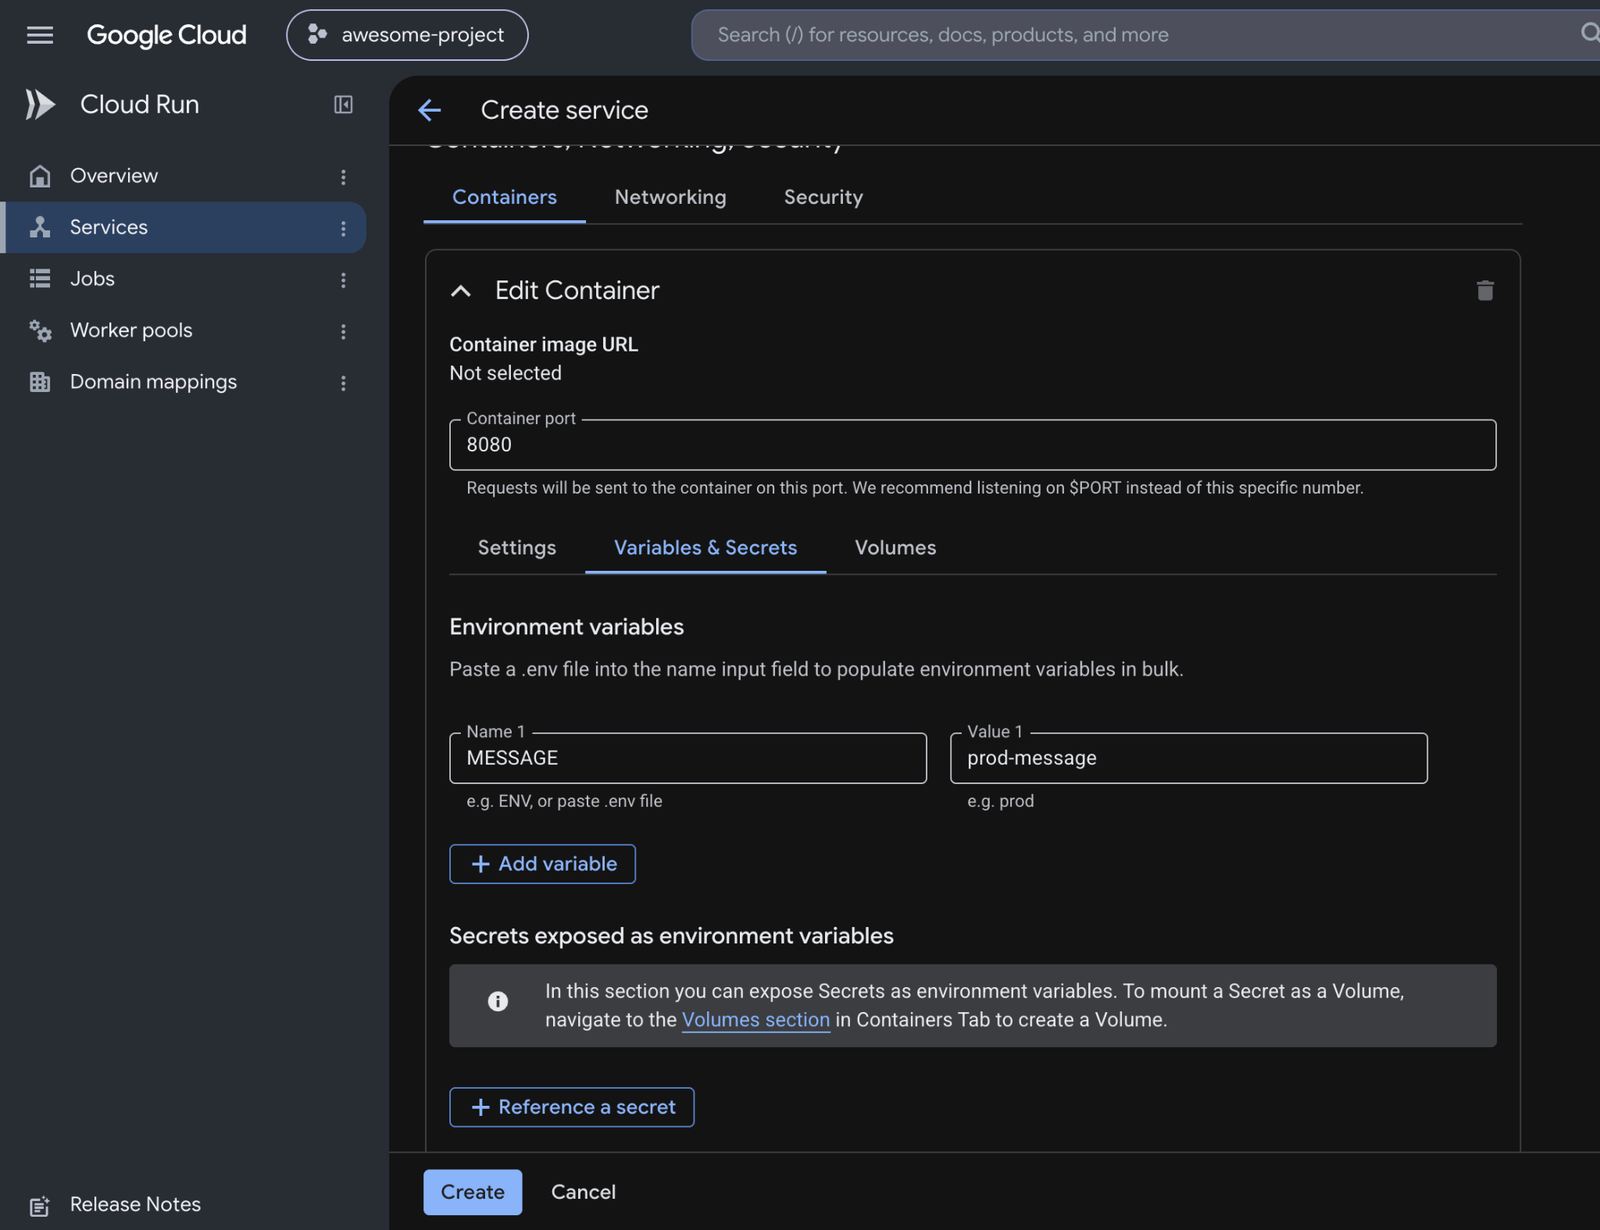
Next, we switch to the Variables and Secrets tab. We added one environment variable called MESSAGE and set its value to a dummy value we called prod-message. You can add multiple variables by clicking the Add variable button.
However, for sensitive credentials, like API keys or database connection strings, which shouldn’t be exposed as plain text, you can click on “Reference a secret” to enable the Secret Manager API and add one or more secrets to reference here.
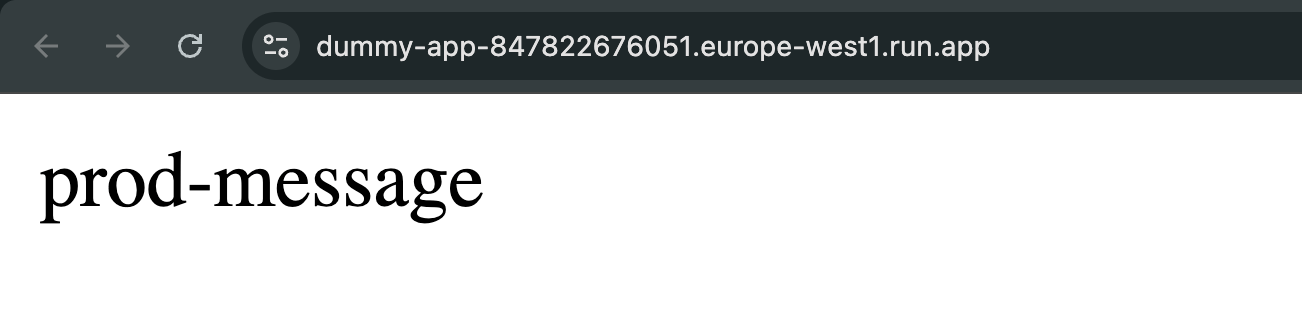
Finally, click on the Create button to deploy the service. If everything works fine, visit the URL now, and you should see the running application, as shown below:
Making Changes and Redeploying the Application
To redeploy our application, let’s make a change to the code. Update your app.service.ts file.
import { Injectable } from '@nestjs/common';
import { ConfigService } from '@nestjs/config';

@Injectable()
export class AppService {
 constructor(private readonly configService: ConfigService) {}
 getHello(): string {
   return this.configService.getOrThrow<string>('MESSAGE') + '';
 }
}
We simply added an emoji to the returned string from our getHello method. Now we can proceed to build the image by running:
docker build . --platform linux/amd64 -t chrisnw/dummy-app:0003
And push the image by running:
docker push benguma/dummy-app:0003
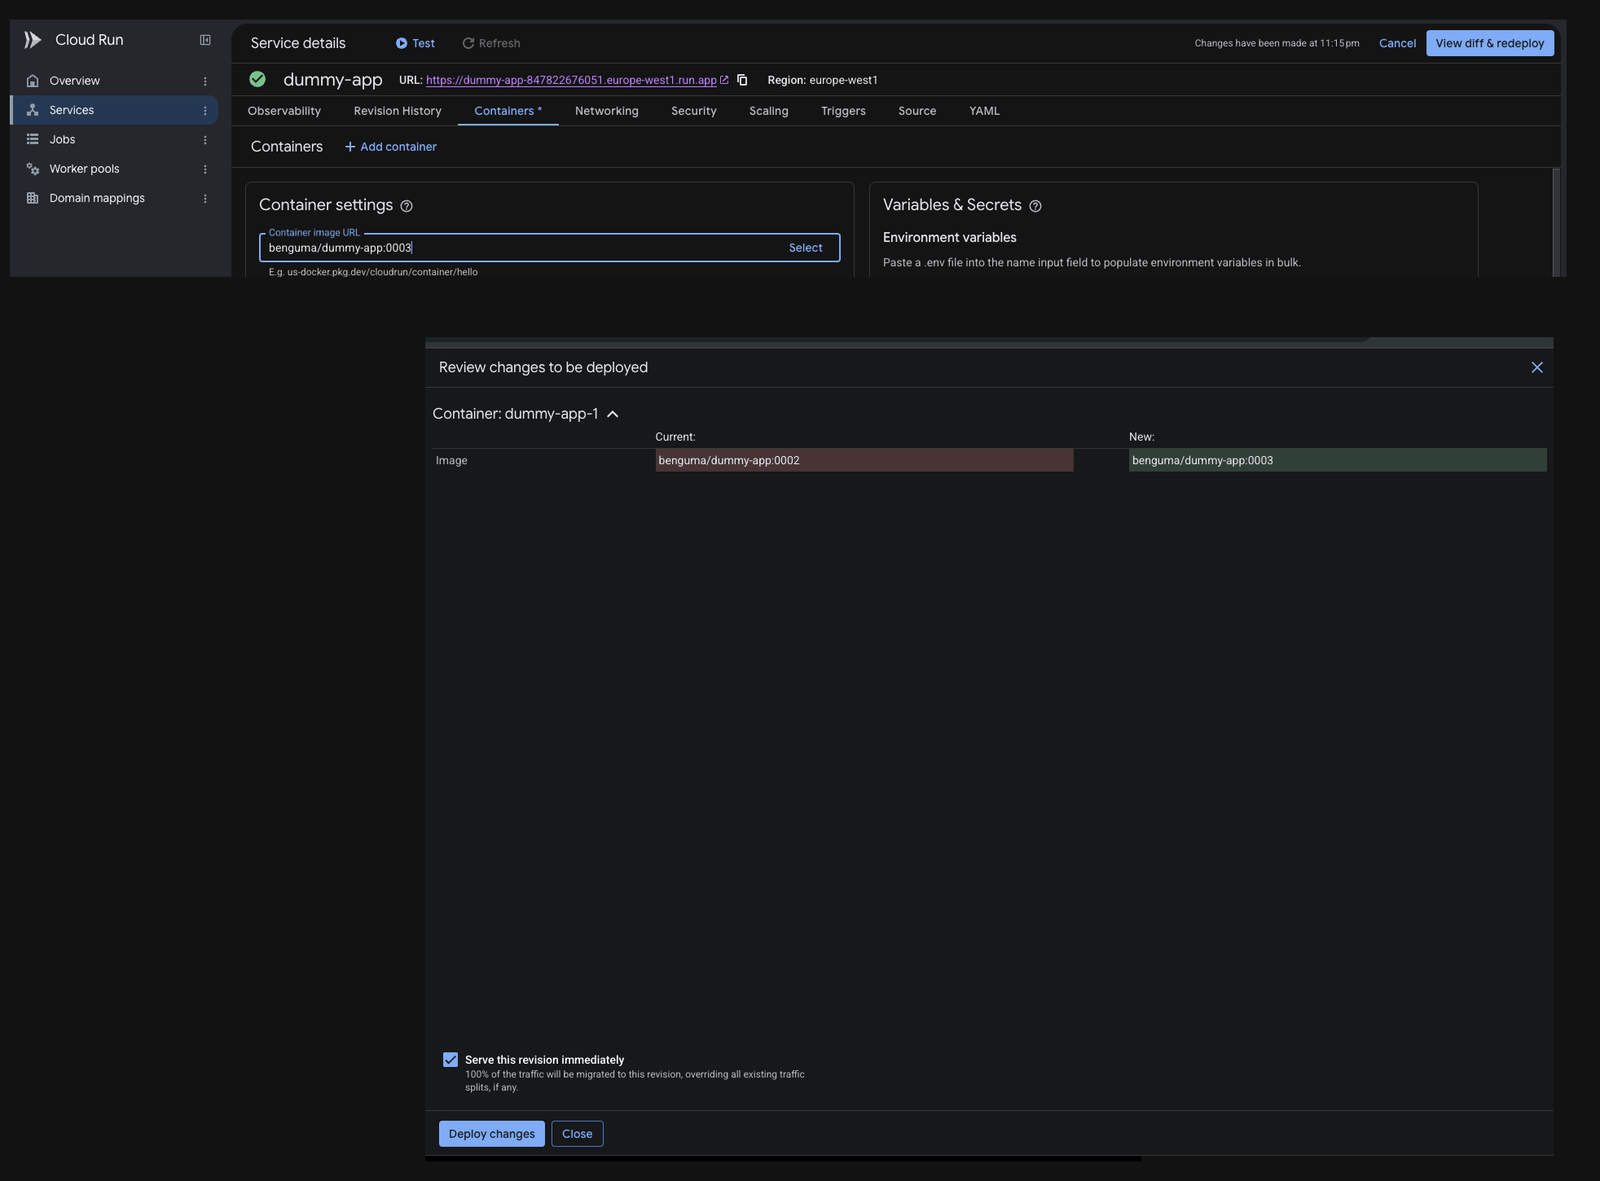
Now, on the Container tab, we update the field pointing to the new image. Click “View diff and deploy”, then click “Deploy changes”.
Automating for CI/CD
Instead of manually building and publishing the image, we can make the build step part of our CI/CD pipeline using common options like GitHub Actions. Google Cloud Run also provides the necessary automation scripts we can plug in to speed up image building, pushing and deployment.
Conclusion
Google Cloud Run makes it easy for developers to leverage the powerful features of Kubernetes, including its rich ecosystem of middleware and plugins, without dealing with the usual complexity. Hopefully, this demo can serve as a starting point for deploying similar workloads on Google Cloud Platform in your future projects.
Pennsylvania, USA

Get started with SQL Server Reporting Services Report Builder. Discover how to download, install, and create reports effortlessly.
The post Getting Started with SQL Server Reporting Services Report Builder appeared first on MSSQLTips.com.
Pennsylvania, USA
Next Page of Stories