Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164213 stories
·
33 followers

GM’s $220 Million Data Privacy Settlement: What Drivers Need to Know

1 Share

GM agrees to a $220 million settlement over drivers' data. Learn how connected-car information was allegedly shared and what vehicle owners should know.

The post GM’s $220 Million Data Privacy Settlement: What Drivers Need to Know appeared first on TechRepublic.

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

What Is ReactOS? How It Works and How to Try It Safely

1 Share
ReactOS is a free, open source OS that runs Windows apps and drivers. Here's what's new in 0.4.16 and how to test it safely in a VM.
Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Radar Trends to Watch: November 2026

1 Share

Coauthored with Claude

Security looms large as we enter November. There’s been a lot of bad news: a certificate authority with woefully inadequate private keys, vulnerabilities have been discovered (and exploited) in PHP and other widely used programs, and several organizations have detected Chinese open weight models misbehaving in several different ways. New models are arriving faster and faster, and the best open-weight models are catching up to frontier model performance. But organizations that would like to achieve AI sovereignty will have to ask some difficult questions about the models they adopt. Is this an inflection point? Whether or not it is, AI has changed security permanently, and things are bound to get worse before they improve.

AI models

We are starting to see models developed with recursive self-improvement; we continue to see clones of Jev; and we’ve seen text watermarks added to output generated by Anthropic’s and OpenAI’s models. (Google has been using text watermarks for some time.) But tools for detecting the watermark are hard to find. Anthropic’s and OpenAI’s are in a very limited beta, and Google’s is only available in their enterprise package. What does a watermark mean if you can’t detect it? And, as we get more accustomed to AI-generated output, will anyone care?

  • Kimi 3.1 Pro is a new open weight model with 3T tokens. On benchmarks, it is now the leading open weight model, only slightly behind the latest frontier models. Moonshot AI also released Kimi K3.1 Pro Highspeed, which is two to three times faster.
  • Recursive has announced Flint, a 40B parameter mixture-of-experts model that activates 2.5B parameters per token. It was designed for coding, and sized to run on laptops. Flint is open weight; weights are available on Hugging Face, and it works with model runners like Ollama.
  • Meta has shipped Muse Spark Open, an open weight model that they claim competes with the best Chinese open weight models. It’s a mixture-of-experts model with 816B parameters and 42B active parameters.
  • Meta’s latest models, Muse Wonder and Muse Wonder Full, claim parity with frontier-class models. Specifically, they claim parity with Claude and ChatGPT for financial and legal work. The announcement hints that Meta will be using Muse to develop specialized models.
  • OpenAI’s Decisions API is yet another Jev-like model. Like Jev, its input is a data structure that constrains the model’s output to be an answer to specific questions. The output is a data structure that includes a probability for each answer.
  • Claude has launched Haiku 5.5, a new version of its least expensive model. It’s faster, less expensive, and has better benchmark scores than its predecessors. Haiku 5.5 is a very capable model, particularly for users who are sensitive to cost.
  • Mistral has launched Mistral Large 4, a.k.a Le Chonk. It’s an open weight mixture-of-experts model with 1T parameters. It’s claimed to be the best open model from Europe and was designed with AI sovereignty in mind.
  • Aleph Alpha has released an open weight LLM for English and German that was trained entirely under European rules. It is a mixture-of-experts model with 78B parameters. It uses a different tokenizing algorithm to handle long German words without breaking them into fragments. Reasoning takes place mostly in German.
  • Crowdflare has released Clef and Clef Flash, new decision models that, like Jev, take typed queries and return typed answers about those queries. It’s also offering a new reinforcement learning service to help customers train Clef for their applications.
  • After a long wait, Google has released two new frontier models, Gemini 4 Argon and Carbon. Argon is available to paying customers. Argon’s successor, Carbon, is being released slowly, and is currently only available via the Fairwind program.
  • The Ember-1 model from Fireworks claims to have results similar to Kimi K3 at lower costs. It is priced similarly on OpenRouter but uses far fewer reasoning tokens.
  • OpenAI has published 722 papers solving problems in mathematics on GitHub. There is some controversy about whether all the proofs are correct; so far, three have been withdrawn, leaving 719.
  • Google has opened its SynthID detector to the general public. The detector can determine whether audio, image, or video files generated by any of Google’s partners (including OpenAI, NVIDIA, and Apple) have the SynthID watermark.
  • To comply with EU law, OpenAI will add watermarks to text in Europe. The company’s algorithm sounds similar to the one that Google and Anthropic are using: modifying the underlying probability distribution changes word choice in detectable but insignificant ways.

Agents and harnesses

There are more choices than ever for agents, along with new standards for the interaction between agents and models. In addition to general purpose agents, there are also agents specialized for coding, HR, BI, and more. And most agents will connect to many models, including local ones. Choose agents as carefully as you choose models; your agent is where you will do your work.

  • JetBrains has released Thinkrail, an agentic IDE that learns about your project as you use it. It is open source and based on the pi agent.
  • Anthropic has donated its Agent Skills standard to the Agentic AI Foundation (AAIF), which will shepherd further development. It has also donated Open Responses, a standard for building common interfaces, to AI providers.
  • OpenAI has introduced Intelligent UI, a feature that allows ChatGPT to generate its own user interfaces in response to the user’s question.
  • Workday is allowing its customers to build their own agents for HR and finance. An agent’s access to Workday data is tied to the user’s account.
  • Claude Dashboards is a new product that lets you build live dashboards from a group of data sources.
  • Claude’s Google Workspace connectors allow it to read and write Google documents, sheets, and slides directly.
  • MCP Events is an extension to the MCP protocol from OpenAI. It allows ChatGPT to subscribe to updates from MCP servers.
  • DeepSeek has released a harness (dsh). It’s open source, and currently in public preview. Everything is a plug-in.
  • The Pi agent has reached version 1.0.0, and is now capable of using MCP. There’s a variation, Pi Durable, that has been designed for long-running tasks.
  • OpenAI dots are consumer-oriented agents that run in the cloud. They are always on and have their own web browser along with other tools.

Software development

At last month’s SciFoo, Hugo Bowne-Anderson said that we’ve been through two major changes in the past few years: from writing code to letting AI write the code, and from reading the code to not reading the code. These changes are as radical as the shift from programming in machine language to programming in high-level languages. We will all go through a process of rethinking how we work and what we’re trying to accomplish.

  • Anthropic has introduced Claude Mods, a plug-in for Claude Code that can modify Code’s behavior: reshaping its user interface, providing information about context use, giving advice about what you’re doing, and much more.
  • One application for decision models is building evals to understand the performance of AI applications.
  • Workday is using Jev to build user interfaces on the fly. Jev’s very low latency makes choosing UI components at runtime viable.
  • Anthropic has outgrown Git, which wasn’t able to keep up with merges on their monorepo (roughly 30,000 merges in September). Anthropic has built a new source control system called Scion.
  • Kate Huston writes about reverse-engineering code review and trying to develop an effective “gate” that AI-generated code would have to pass before review by humans.
  • WordCraft is an open source clean-room re-implementation of Microsoft Word. The authors claim that it’s 60% of the way towards “replacing Word for real work.” It supports MCP, has a command line interface for interacting with agents, and can run in a browser through WASM.
  • ArtCraft is an open source tool for creating interactive AI-generated images and video in 2D or 3D. The company describes it as an “IDE for artists.” They’re also developing open source clones of Adobe Creative Suite tools like Photoshop. Early reports are that it’s very buggy.
  • Google Docs now supports Markdown natively. Users can read, write, collaborate, and comment on Markdown documents without converting them to another format.
  • Google’s Docsy documentation project is moving to the Linux Foundation. Docsy is a template for the Hugo static site generator that’s useful for generating documentation in ways that are helpful to agents.
  • Does programming with AI require more abstractions or fewer? Matt Pocock argues for more.
  • Anthropic has given Claude an auto-eval tool. While the first version of this tool has many flaws, it’s a significant step towards making evals easier.

Security

Security has been much in the news. Not all of the news is bad: AI was used to discover the PHP2Shell vulnerability and to develop a fix. The leaked CVE and the many out-of-date PHP sites online are serious problems, but not problems attributable to AI. Too many problems arise from getting the basics wrong: A certificate authority using 4 as its private key is a mistake that should never have been made. As always, security is about getting the basics right while watching for new threats. And while organizations claim to be paying more attention to security, the word from insiders is that “attention” means lip service. In the long run, AI may make the world a safer place, but the next few years look scary.

  • CrowdStrike and Booz Allen have found that Qwen3-Coder (and probably other models) generates weaker code if the prompt says that the code is for a politically sensitive user such as the US government. Hirundo reports similar flaws and also claims to have “fixed” the model and created a Westernized version.
  • Cohere makes a different claim: It has observed that Qwen3.8 models occasionally send data to an Alibaba cloud storage bucket in Beijing.
  • Malicious AGENTS.md files have been found in the Downloads folders of some users. If the user is using the Downloads folder as their working directory, an AI agent will read the AGENTS file and download a malicious NPM package.
  • 1Password has launched 1Password for Agents, a credential-brokering product that allows agents to access resources for a user without seeing the user’s password,
  • Alibaba also donated its OpenSandbox project to AAIF. OpenSandbox is a general-purpose sandbox for running AI models safely.
  • The PHP team has released patches for two critical vulnerabilities collectively known as PHP2Shell. However, many sites are running old versions of PHP that need to be upgraded before they can be patched. The maintainers have also released some partial mitigations for sites that can’t upgrade easily, but that won’t fully protect them. Sadly, “the panic hasn’t turned into patching,” and those who don’t patch will pay.
  • Brotli isn’t as widely used as PHP, or as old, but a critical flaw in Brotli compression library makes it clear that discovery of hidden vulnerabilities is the shape of things to come. Microsoft has released patches for .Net, PHP maintainers have released patches for PHP, Node.js is also affected, and that’s just the start.
  • The private keys of the certificate authority eMudhra have been cracked–not by brilliant cryptography or a quantum computer, but because the keys were generated very poorly. The Chrome and Firefox browsers aren’t trusting the compromised certificates, but almost everything else, including all major package managers, is a problem.
  • OpenCode was the victim of a hostile attack in which some users’ API keys and passwords were stolen from their Console service. Its response was hampered by lack of access to AI models without security restrictions.
  • The US Department of Homeland Security has banned the use of DeepSeek and applications developed using DeepSeek in all federal agencies.
  • To monitor the risks created by the development of frontier models, Anthropic has given six employees of METR access to their models. They continue to work with Accenture and Secure Bio.
  • Model abliteration is a poisoning attack in which post-training is used to discover which of a model’s weights corresponds to “no,” and altering them so the model cannot refuse a request. It’s effectively a backdoor into the model’s behavior.
  • AWS has launched Strands Box, an open source sandbox that’s designed specifically to prevent AI agents from escaping the sandbox’s control. It includes an open source policy engine, Dogwood, that allows users to place explicit limits on what an agent may do.
  • Meta’s Muse, its agent for people who aren’t technology professionals, is a privacy and security disaster.
  • Using MCP for communications between agents creates many risks, including new vulnerabilities to prompt injection.
  • Google has suspended submissions to the Open Source Software Vulnerability Rewards Program because of the flood of machine-generated vulnerability reports, most of which are (in Google’s words) “not valid.” This suspension should only be temporary.

Infrastructure and operations

There’s been a lot of news about certificate management, not all of it good. It’s time to check on your certificate providers, get ready for quantum-resistant encryption, and automate as much of the process as you can.

  • To increase security, the certificate provider Let’s Encrypt will be limiting the lifetime of free certificates to 64 days starting in February 2027. The change should be invisible to sites using automatic certificate management (ACME).
  • Crowdflare has announced that it will begin issuing TLS certificates with quantum-resistant encryption. They will continue issuing certificates with classical encryption. Crowdflare hasn’t given a date when they will start issuing the new certificates.
  • DeepSeek has open sourced DeepInfer, its inference framework, with an Apache 2.0 license. At present, DeepInfer only supports DeepSeek-V4.1-Flash.
  • RemoveMacAI is an open source command-line tool for deleting Apple’s AI from MacOS 27, freeing up 30 GB or so of disk space.

Web

Mark Twain didn’t quite say, “The reports of my death are greatly exaggerated.” But we are hearing that the Web is dead, and that’s indeed an exaggeration. The flood of crawler traffic and the disincentives towards human writing are a problem. But what does “death” mean for a technology so flexible that you can build an office suite that stores entire documents’ URLs?

  • TinyLittleOffice.com is a surprisingly complete set of surprisingly capable office applications. It includes a word processor, spreadsheets, and other Office-like apps. Everything is saved in the URL–not on your disk, not in someone’s datacenter. Not suitable for large documents.
  • Crowdflare has announced a web search API, now in beta. Although their announcement doesn’t say, we suspect this is an attempt to control web scraping traffic. Matthew Prince, its CEO, has estimated that bot traffic will reach 1000 times human traffic by mid-2027. All of his earlier predictions have been underestimates.
  • Jev and its clones have taken the world by storm. Can you beat it at Pacman?

Hardware

  • AI labs are heading towards models that can run on phones and similar hardware. Google has compressed Gemma 4 E4B to 5 GB, and Liquid has released LFM2.5-24B-A2B, a 24B mixture-of-experts model with 2B active parameters that also targets devices.
  • OpenTPU is an open source API accelerator, designed by AI. Bring your own silicon.

Quantum computing

  • Quantinuum has implemented quantum error correction on its latest hardware and has found that it scales well enough to be useful in practice: Adding a physical qubit to a logical cubit cuts the error rate significantly.
  • Researchers have discovered a way to read a qubit without collapsing the information it contains into a 1 or 0. Solving this problem (also known as quantum non-demolition or QND) is critical to building quantum computers large enough to do useful work.

Biology

  • Watermarking texts is one thing. Google has now designed a watermark for proteins. Like text watermarks, protein watermarks are based on Google’s SynthID.
  • Last month we mentioned EEG-capable earbuds. This month, a group of researchers has announced that they have developed an AI application that can reconstruct what someone is seeing from brain scans. The results are impressive, though the privacy implications are chilling.


Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

HHS’ Office for Civil Rights Settles Ransomware Investigation of Lehigh Valley Health Network

1 Share

DataBreaches.net previously covered the 2023 Lehigh Valley Health Network breach by AlphV (aka “BlackCat”). The breach garnered a lot of public attention when  the threat actors crossed a line by posting nude pictures of patients on their leak site. In 2024, patients settled civil litigation for $65 million. Now HHS has settled its own charges...

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Modern CSS Might Make Your Front-End More Complex

1 Share

Have you ever replaced fifty lines of JavaScript with a few lines of CSS, merged the PR, and felt like you just did the codebase a favor? You replace ResizeObserver with a container query, the diff is mostly red, and everyone approves it before lunch.

This was what it looked like before you made the change:
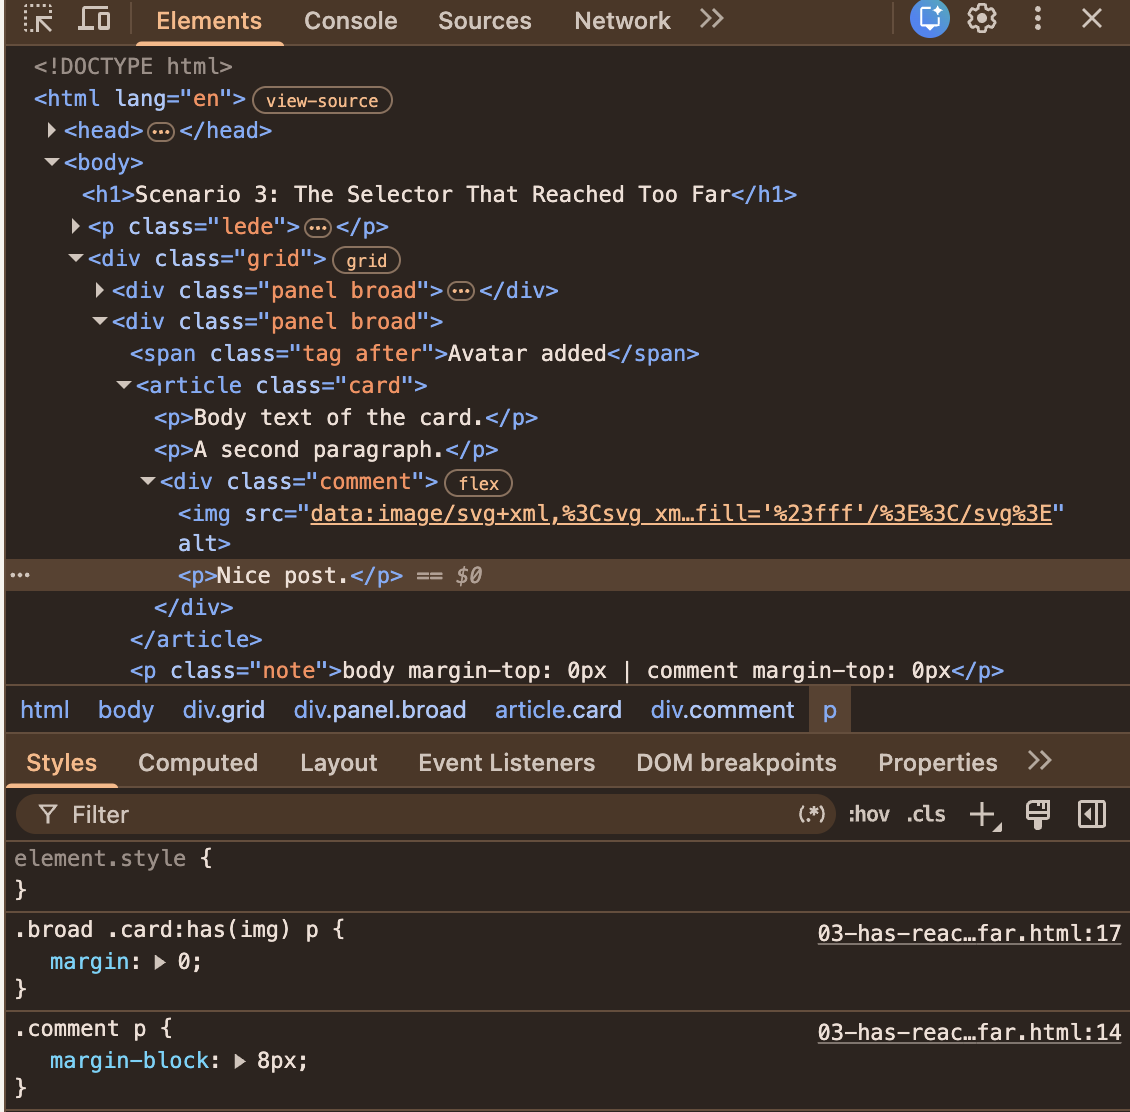
  1. The selector matches more than we meant.
    The :has(img) rule matches any descendant image, so the comment’s avatar counted as a hero image. And the p element selector matches any descendant paragraph. As a result, the comment’s text was caught in the selection.
  2. The selector outweighed the comment’s own rule.
    MDN’s specificity guide explains that :has() adds no weight by itself, but its argument does. That gives .card:has(img) p a specificity score of 0-1-2, while .comment p comes in at just 0-1-1 and loses the battle.

It could get even more complex and difficult to catch because the state changes at runtime. Let’s say a user posts a comment that includes an avatar. The body text of the card above it loses its spacing. Good luck reproducing that from a bug report that says “spacing looks off sometimes.”

The fix is to constrain the selector with child combinators:

.card:has(> img) > p {
  margin: 0;
}

This helps the selector get more specific about what it is yelling about.

Nesting Also Borrows Weight

Native nesting has the same habit. MDN’s guide to nesting and specificity says the & selector takes “the largest specificity in the associated selector list,” exactly like :is(). Look at this adaptation of MDN’s example:

/* Specificity 1-0-0 */
.card, #featured {
  /* Specificity: 1-0-1 */
  & a {
    color: blue;
  }
}

/* Specificity: 0-1-0 */
.button {
  color: red;
}

A .button link inside a .card is blue, even though the #featured ID is nowhere near it. The usual reaction is a more specific .button rule, then an exception to that rule. Before you know it, you are in a war of specificity you never knew you had declared.

The way out is to keep the selector list and drop its weight by wrapping it in :where():

/* :where() always weighs 0-0-0 */
:where(.card, #featured) {
  /* Specificity: 0-0-1 */
  & a {
    color: blue;
  }
}

/* Specificity: 0-1-0 */
.button {
  color: red;
}

Plain links inside a card are still blue, and the .button link is red again. Again, another way to quiet the loud housemate.

Layers Don’t Rescue You By Default

Don’t be fooled into thinking specificity is the whole story. MDN’s introduction to the cascade puts origin, importance, and cascade layers ahead of specificity, and notes that “normal layered styles have less precedence than normal unlayered styles.” In my test, a layered rule with a specificity of 0-4-0 lost to an unlayered .title (0-1-0). So if your new component styles go into @layer components while the legacy stylesheet stays unlayered, the legacy rule wins every conflict, however carefully you wrote the new one. The exception is when the !important keyword is used, because it actually reverses the cascade order.

Miriam Suzanne’s original proposal for cascade layers describes exactly the pain layers were meant to remove: having to “be very careful with matching specificity to layer.” Layers do remove it, but only when the rules on both sides of the conflict are layered. A half-layered codebase just gives you one more ordering to keep in your head.

An Old Fight With A New Tool

None of these battles started with :has() or nesting. In an r/webdev thread titled “CSS-in-JS: What’s the biggest performance drop you actually felt?”, one of the most upvoted answers isn’t about performance at all. It is about the cascade:

“Here’s a fun one: refactoring your JS can cause your CSS to break, because your CSS builds are determined by JS import orders.”

— mq2thez

This is about the “order of appearance,” which is the last step in the cascade that ends up deciding a conflict nobody knew existed. Another commenter in the subreddit adds that the injected styles can land in a different order in development and production builds: “Who doesn’t love debugging something that works locally but not in prod.”

Not everyone in the thread agrees on who is to blame. TheThirdRace replies, “It’s a coding issue, not a technology issue.”

I think both are right, and that is exactly the point. CSS-in-JS is a different technology from the native features we are looking at, so take this as a neighboring example, not as proof. But the shape of the problem is the same: the tool did what it promised, and the trouble arose from how it complied with the existing rules.

Before you add the rule:

  1. Constrain it. Use > so the selector stops at the component’s own children.
  2. Drop the borrowed weight. Wrap heavy selectors in :where(), which always has a specificity of 0-0-0.
  3. Check the layers. Which layer does your rule land in, and where do its competitors live?
Scenario 4: The Housemate That’s Slow To Pay Rent

“We moved it to CSS, so it’s faster now.” You have probably heard this in a code review, and maybe said it yourself. In my last article, I warned that it isn’t always the case. Let’s test it.

Moving a behavior from JavaScript to CSS changes who does the work. It doesn’t tell you how much work there is. The last housemate, the browser’s rendering engine, is the one who gets the bill. Everyone in the apartment shares it, and nobody looks at it after the move.

Take :has() as an example. Browser vendors were worried about its cost from the start. In a CSS Working Group issue about :has() restrictions, Emilio Cobos Álvarez noted that implementations wanted to ship it with limitations “in order to prevent performance footguns and complexity.” Today, MDN’s :has() page has a whole section on performance with two pieces of advice:

  • Don’t anchor :has() to an element with a large subtree, “like body, :root, or *.”
  • Constrain the inner selector with > or +, because otherwise “the browser might need to traverse the entire subtree of the anchor element on every DOM mutation.”

I wanted numbers, so I built a list with 5,000 rows. The test toggles an .is-selected class on the same row 300 times, so the row’s selected state changes on every toggle, and forces a style and layout update each time. I ran it in Chrome 153 on a Mac in October 2026, and recorded a trace in DevTools to count how many elements each toggle restyles.

See the Pen Scenario 4: The Rewrite Nobody Measured [forked] by Shoyombo Gabriel Ayomide.

Rule What is in the stylesheet Median time per toggle Elements restyled
1 JavaScript toggles a class on the toolbar Under 0.1ms 1
2 body:has(.row.is-selected) .toolbar About 1.4ms 1
3 .list:has(.cell > b) .row, with the toolbar handled by JavaScript Under 0.1ms 1
4 Rules 2 and 3 together About 7ms 5,001
5 For scale: JavaScript restyles all 5,000 rows on every toggle About 6ms 5,001

There are two lessons in that table.

First, the “bad” selector was fine. Rule 2 is exactly the shape MDN warns against: a :has() anchored to body. It cost about a millisecond and a half more than the script, and it restyled a single element, the toolbar. A frame at 60Hz lasts 16.7ms, so I would take that trade for deleting an event handler any day.

Second, two harmless rules were not harmless together. Rule 3 styles the rows, and its :has() condition remains unchanged throughout the test. On its own, it costs nothing measurable. Put it in the same stylesheet as the second rule instead, and every toggle restyles all 5,000 rows plus the toolbar. That is about what it costs a script to restyle every row on purpose.

Let’s keep this in proportion. Since 7ms still fits inside a frame, nobody would notice it on this page. However, the browser is now restyling 5,001 elements to change just one, and neither rule says so. Also, the cost grows with the list. When I set the demo to 20,000 rows, the two rules together restyled 20,001 elements and took about 31ms per toggle, which is nearly two frames.

I can tell you what Chrome does here, but not why. Changing .is-selected on one row restyles every element that the other :has() rule targets, even though that rule never mentions .is-selected and its result never changes. I have filed this with the Chromium team as an issue, with a reduced test case, and I only tested Chrome. Whatever the cause, neither rule looks suspicious in a code review, and the cost applies only when both are met.

That is system complexity in a single table. And please take the pattern from it, not the numbers: this is one page, one browser, and one machine.

The same goes for animation. The animation guide on web.dev recommends restricting animations to opacity and transform where possible, and warns that “an animation that moves an element using something other than transform is likely to be slow.” MDN’s CSS performance guide lists the properties that trigger layout when animated, such as width, height, margin, top, and left. A CSS transition on left runs layout on every frame, while a JavaScript animation of transform skips it. The property determines the cost, regardless of which language you write it in.

To be fair, CSS often wins. A script that reads layout, writes styles, and reads layout again forces the browser to do layout several times in one frame, and a container query hands that whole job to the browser. But that win is something you can measure, so measure it:

  1. Record the interaction in the “Performance” panel of Chrome DevTools, before and after the change.
  2. Compare the time spent in “Recalculate Style,” “Layout,” and “Paint.”
  3. Enable CSS selector stats in the panel’s settings to see which selectors cost the most.
  4. Use production-sized data. A 20-row fixture hides what a 5,000-row list reveals.
When All Four Show Up In One Pull Request

Each of these scenarios is small on its own. The trouble is that a real migration could hit all four scenarios at once. You have already seen three of them. They are the three bugs in the “after” demo at the top of this article. Add a long list, and you get the fourth. One move-in, four housemates disturbed.

A team replaces a card’s JavaScript-driven responsive layout with a container query and :has(). The pull request adds twelve lines of CSS, deletes one script, and misses another. Within a month, three bug reports land, and there’s a chance a performance trace turns up as the fourth problem:

  1. The card title is too big on tablets. The observer still sets .card--wide, and one rule still reads it. The developer goes digging through the JavaScript.
  2. The cards on the dashboard have disappeared. On the dashboard, the card is a flex item, and inline-size containment collapsed it to 0px. The developer reads the parent’s layout.
  3. The text is squashed in some cards. Those cards have comments with avatars, so .card:has(img) p matches. The developer traces the winning declaration in DevTools.
  4. Selecting a row might become laggy for our biggest customer. At 5,000 rows, the two :has() rules cost about 7ms per selection. That fits within a frame, even though each selection restyles 5,001 elements, whereas it used to restyle one. As the number of rows increases, the elements restyled increase, and the cost of the two :has() rules per selection will also increase, but who renders a table with a large number of rows without pagination?

None of these reports means that container queries or :has() were the wrong choice. Each bug lives in the meeting point between the new CSS and the system it moved into. Still, one small pull request has sent a developer through the JavaScript, the page layout, the cascade, and the profiler.

And the way out is not a return to JavaScript. Here is the same page once more, fixed.

See the Pen demo (fixed PR) [forked] by Shoyombo Gabriel Ayomide.

It still uses a container query and :has(), with three changes:

  1. The observer and the leftover .card--wide rule are removed, so the layout has a single owner.
  2. The query container is a wrapper that inherits its width from the surrounding layout, so the card can no longer collapse.
  3. The selector is constrained to the card’s own image and its own paragraphs, so the comment keeps its spacing.

This gap between a clean start and a real codebase shows up in the same r/webdev thread. The person who started it, JRM_Insights, opens with an observation that could describe any of our four scenarios:

“I often find that the initial tooling simplicity gives way to harder-to-debug runtime styling issues.”

— JRM_Insights

Further down, mq2thez describes moving an old CSS-in-JS codebase to a newer pattern: “In isolation or greenfield maybe it wouldn’t be a huge issue,” but in practice, it meant rewriting “whole component trees.” TheThirdRace, who had been defending the technology, answers that they had only ever evaluated it “from a greenfield project perspective,” and that it was “very enlightening to see this through the lens of a spaghetti CSS migration.”

That is the honest version of this whole article.

Most of what we read about a new feature is written from the greenfield perspective. Most of what we ship is a migration.

Your Migration Checklist

Before you replace JavaScript with a modern CSS feature, or adopt one in an existing codebase, answer these six questions. Think of them as the conversation to have with the housemates before the new tenant gets a key. I suggest putting the answers right in the pull request description.

  1. Ownership: Is exactly one of CSS or JavaScript the owner of this behavior?
  2. Scope: What changes for the element’s formatting context: its width, its parent, its children, and its neighbors?
  3. Cascade: Which existing rules could override this one, and which rules could it override?
  4. Migration: Have you deleted the old implementation, including every class and selector it relied on, and tested every state?
  5. Performance: Have you measured the real workload before and after, rather than assuming the rewrite is faster?
  6. Maintainability: Can the next developer tell why this rule exists and where its effects stop?
Conclusion

Modern CSS is great and a huge improvement to styling as a whole. In particular, container queries and :has() let us express things that used to need a script, a dependency, or a hack. But a new capability does not hand us a simpler system by default. In every scenario we looked at, the new tenant did something that didn’t sit well with others, and that was because nobody introduced them to the housemates’ ways of doing things. We get a simpler system when the new rule has one clear owner, a scope we have checked, a place in the cascade we chose on purpose, and numbers showing it helped.

So, the next time a pull request deletes more than it adds, enjoy the red lines. Then ask where the complexity went, and run the six questions. If you can’t answer one of them, the migration isn’t finished yet.

References

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Write mo'

1 Share

I decided not to do #NaNoWriMo this year. Part of that is because I’ve never done it. Never even attempted it. Don’t even want to. Writing a novel is a life goal of mine, but cramming it all into one month isn’t for me. November is impossibly busy. But I do think it would be cool to have a big excuse for avoiding all those obligations.

“Dave, come to this holiday party!”
“Sorry, I’m writing a novel.”
“Dave, come work at the school’s fall carnival!”
“Sorry, I’m writing a novel.”
“Dave, pay attention to your kids!”
“Sorry, I’m writing a novel.”

See, that level of self-preservation and pre-emptive boxing out of other responsibilities would be so cool. Like cigarettes cool.

Despite not having a novel excuse, I am feeling compelled to wri’ mo’ this month. Whether it’s autumnal ghosts or pumpkin spices, there’s a draw pulling me back to my text editor. A vapor of creativity stolen by corporate dementors and their infernal machines, seeping back into my lifeless shell.

Last week I powered through a handful of short stories by Arthur C. Clarke. Vintage sci-fi inspires me. Partly because the experimental short form factor containing a single “What If?” thought experiment seems achievable and because most of the stories are complete shit. In a modern world of blockbuster movie adaptations and eight volume octologies, vintage sci-fi sets the bar real low.

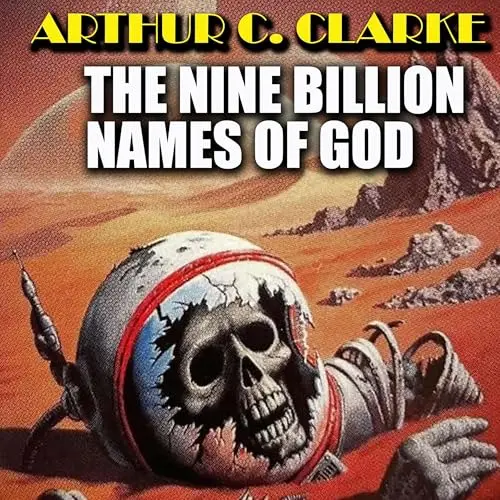
One story I came across was The Nine Billion Names of God. The audiobook has a sick-ass cover of a skeleton in a cracked space helmet on a dying planet with a giant sun rising in the distance. You can pause this and get through it in ten minutes.

A human skull in a cracked space suit helmet stranded on a deserted planet

Nothing in the story relates to that cover. Rather, the story is about two Western men that work for a fancy computer company that makes the Mark V. They’re hired by a group of Tibetan monks to help them write a program that will procedurally generate the nine billion names of God which they believe will bring about the end of the world. The Mark V will shorten the task of writing down all the possible names of God from 15,000 years of manual writing down to 100 days! Incredible productivity gains!

AAABBBAAA AAABBBABA AAABBBACA AAABBBADA AAABBBAEA AAABBBAFA AAABBBAGA AAABBBAHA AAABBBAIA AAABBBAJA
AAABBBAAB AAABBBABB AAABBBACB AAABBBADB AAABBBAEB AAABBBAFB AAABBBAGB AAABBBAHB AAABBBAIB AAABBBAJB
AAABBBAAC AAABBBABC AAABBBACC AAABBBADC AAABBBAEC AAABBBAFC AAABBBAGC AAABBBAHC AAABBBAIC AAABBBAJC
AAABBBAAD AAABBBABD AAABBBACD AAABBBADD AAABBBAED AAABBBAFD AAABBBAGD AAABBBAHD AAABBBAID AAABBBAJD
AAABBBAAE AAABBBABE AAABBBACE AAABBBADE AAABBBAEE AAABBBAFE AAABBBAGE AAABBBAHE AAABBBAIE AAABBBAJE
AAABBBAAF AAABBBABF AAABBBACF AAABBBADF AAABBBAEF AAABBBAFF AAABBBAGF AAABBBAHF AAABBBAIF AAABBBAJF
AAABBBAAG AAABBBABG AAABBBACG AAABBBADG AAABBBAEG AAABBBAFG AAABBBAGG AAABBBAHG AAABBBAIG AAABBBAJG
...       ...       ...       ...       ...       ...       ...       ...       ...       ...      

THIS STORY HAS NO MODERN DAY PARALLELS. An altruistic sex cult from a specific locale using a mountain of money to hasten the end of the world with their enormous computers that endlessly generate combinations of nonsense words that they believe will summon God… well, that would be a work of cheesy science fiction, not real life.

The Nine Billion Names of God flipped a switch in me and has renewed my courage to write more. As someone with ideas about ideas burning holes in my head and it’d be worthwhile to offload some of my cognitive surplus. I don’t have any solid plans, words-per-day goals, charts, graphs, storyboards, outlines, or some Benjamin Franklin life hack schedule to make this happen. Instead I have an Obsidian vault with a hundred unsorted drafts.

I don’t want commit myself to publishing every day, but my goal is to get up and spend thirty minutes to an hour each day writing something. I want to carve out time before work, before doing my puzzles, before doom-scrolling the news. I want to use those premium dopamine reserves –the flavorful floating creme of consciousness that comes from a good night’s sleep, not the metallic bitter dregs distilled from caffeine and stimulants– I want to savor and use that precious natural dopamine on writing.

My promise to you, dear reader, is that I will write more this month. I will write no less than nine billion stories and/or blog posts by the end of November. And upon completing my works, I can shed this mortal coil and leave this forsaken world.

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories