In 34 of the 37 surveyed countries, people are more likely to believe AI will lead to job losses over the next 20 years. | Image: Pew
Pew Research has published a new global survey that sheds light on how people view AI, including its impact on jobs, life in general, and income inequality. The survey questioned 42,151 people across 37 countries from February 8th to May 13th - well ahead of recent apocalyptic warnings.
A majority sees AI as a threat to human employment. In 34 of the 37 countries surveyed, people are more likely to believe AI will lead to job losses over the next 20 years rather than create new ones. Worries run particularly high in wealthier countries like Australia (76 percent), South Korea (76 percent), and the US (71 percent). Not surprising, given Anth …
Claude Opus 5 currently sits at the top of the SWE-bench Verified leaderboard with a score of 96 per cent [1], Claude Fable 5 is a point behind at 95.0 [2], and eight different models now clear eighty-five [1]. Read those figures the way anyone reads a percentage and you would conclude that frontier agents now resolve nineteen out of every twenty real GitHub issues, leaving a gap so small that someone will close it before the end of the year. That conclusion is wrong, and over the course of 2026 four separate research groups have published the work explaining why [3, 5, 6, 17].
I build agents for a living, mostly against enterprise systems that were architected long before anyone had heard of a language model, and the leaderboard numbers have never matched what I observe in production. That mismatch is easy to dismiss as the usual gap between benchmark conditions and messy reality, which is why the recent audits matter: they show that a substantial part of the gap sits inside the benchmark itself, in the graders rather than in the models.
One in five solved issues was never solved
The most direct evidence comes from the SWE-ABS paper [3], whose authors did the obvious thing that nobody had bothered to do, which was to strengthen the tests and re-run everybody.
SWE-bench Verified grades an agent by applying its patch to the repository and running the existing test suite, treating a passing run as a resolved issue. The weakness in that design is that the test suites were written by human maintainers to catch human mistakes, and they are frequently thin in exactly the places a model's output diverges from a correct implementation. The SWE-ABS researchers built an adversarial pipeline to expose that thinness, combining coverage-driven augmentation that uses program slicing to reach untested code paths with mutation testing that synthesises plausible but incorrect patches to find the blind spots [3]. When they re-scored the top thirty agents under the strengthened suites, one patch in five that the leaderboard counts as solved turned out to be semantically incorrect, passing only because the original tests were too weak to notice the error [3].
Here is what that does to the published scores, taking the most recent runs on the project's live leaderboard [4], all under the same single-scaffold mini-SWE-agent harness so that the comparison is model against model:
Model (mini-SWE-agent)
Original
Strengthened tests
Drop
Claude 4.5 Opus (high reasoning)
76.80%
66.40%
10.40
Gemini 3 Flash (high reasoning)
75.80%
63.40%
12.40
MiniMax M2.5 (high reasoning)
75.80%
64.20%
11.60
Claude Opus 4.6
75.60%
65.60%
10.00
Claude 4.5 Opus (medium)
74.20%
58.00%
16.20
Gemini 3 Pro Preview
74.00%
56.80%
17.20
GPT-5.2 (high reasoning)
72.80%
58.80%
14.00
GPT-5.2 Codex
72.80%
61.60%
11.20
GLM-5 (high reasoning)
72.80%
61.40%
11.40
Source: SWE-ABS live leaderboard, last updated March 5, 2026 [4].
Every model gives back somewhere between ten and seventeen points, which turns a system you believed handled three-quarters of real issues into one that handles somewhere around sixty per cent. The detail with the most practical consequence, though, is not the size of the drop but the fact that the ranking changes underneath it: Claude Opus 4.6 starts the table behind Gemini 3 Flash and MiniMax M2.5 and finishes ahead of both, GPT-5.2 Codex and GLM-5 pull nearly three points clear of plain GPT-5.2 from an exact tie, and across the full thirty-agent board the system that led it when the paper was written, TRAE with Doubao-Seed-Code, falls from third to eleventh [4]. If you justified a model decision by pointing at a leaderboard position, part of what you were pointing at was an artefact of which weak tests happened to be included in the benchmark. One more thing worth knowing before you read this summer's headline numbers: the strengthened re-scoring currently stops at models released through February 2026 [4], and nobody has yet run Fable 5, Opus 5, GPT-5.6 or GPT-6 Astra against the hardened suites, so there is no reason to assume the ninety-plus scores are exempt.
Nine lines of Python will get you a perfect score
Everything above concerns accidental inflation, where nobody set out to game anything and the measurement simply failed. The BenchJack paper [5] covers the deliberate case, and it is the result I would put in front of anyone still treating a leaderboard as ground truth.
The researchers built an automated auditor that hunts for reward-hacking exploits in agent benchmarks, then pointed it at ten widely used ones. It found working exploits in all ten and achieved near-perfect scores on nine of them without solving a single task [5], which is a sentence worth reading twice. The SWE-bench exploit runs to nine lines [5] and depends on a trust boundary that was never really there: the benchmark applies the agent's patch inside a Docker container and then trusts the test output that emerges from that same container, even though the patch itself can write arbitrary files. An agent that drops a conftest.py, which PyTest loads automatically, can register a hook that rewrites every test's reported outcome and walk away with a hundred per cent resolve rate [5].
Nobody is suggesting the frontier labs are shipping conftest.py hooks, and that is not the point of the finding. The point is that the measurement apparatus has no integrity boundary worth the name, which means a sufficiently capable optimiser will eventually route through it regardless of whether anyone intended that outcome, and the auditors catalogued 219 distinct flaws across the ten benchmarks they examined [5].
The inflation is uniform, which is both good and bad news
If you want the number that survives statistical scrutiny rather than a single striking demonstration, it is in the reward-hackability audit published this June [6], which set out to answer a question benchmark curators actually need answered: what fraction of tasks in a code reinforcement-learning set reward a model for an incorrect solution?
Sampling from SWE-bench Verified, the authors measured 28.5 per cent Docker-verified reward-hackability across a 49-task sample, alongside 25.0 per cent on a comparable sample from R2E-Gym, which they characterise as a lower bound because the attack budget there was deliberately weaker [6]. They then ran a meta-analysis across 134 frontier model submissions to the benchmark, comparing performance on hackable and clean tasks within the same difficulty stratum, and found that hackable tasks inflate Pass@1 by 14.14 percentage points with a confidence interval running from roughly 11.8 to 16.5 [6].
The finding underneath that headline number is the one that should change how you read leaderboards. Heterogeneity across the 134 submissions came out at zero [6], meaning the inflation is uniform across model family, across submission era and across score quartile. It is not the case that some labs game the benchmark while others behave; everyone is being measured with the same broken ruler and everyone's figure is lifted by roughly the same amount. Relative rankings therefore retain some signal, while absolute scores mean considerably less than the decimal places imply. The same paper cites OpenAI's announcement from February 2026 finding that 59.4 per cent of the failed tasks it audited on SWE-bench Verified have flawed tests [6, 7], so the errors run in both directions and the benchmark is penalising correct work as well as rewarding incorrect work.
The scores do not agree with themselves
There is a separate problem that pushed me from treating benchmarks as noisy to treating them as unusable in the way most people use them, and it requires no adversarial research to observe. Pick one benchmark and one model, then ask what the model scores.
Terminal-Bench 2.1 is a reasonable choice, being eighty-nine tasks in a sandboxed terminal [8] and better designed than most. Artificial Analysis reports Claude Fable 5.1 at 91.4 per cent running at max effort under the Terminus 2 harness [8], vals.ai reports the same model under the same harness at 85.02 per cent [9], and the official Terminal-Bench board, which lists only runs its own team has verified, has no Fable 5.1 entry at all and still shows Fable 5 in Claude Code at 83.8 per cent on top [10]. That is more than six points of spread on one benchmark and one model, produced entirely by differences in sandbox, effort configuration and run count, none of which appear in the number anyone quotes.
SWE-bench Pro is in worse shape, since three separate figures currently circulate as the leading score: 61.5 per cent for Meta's Muse Spark 1.1 on Scale AI's standardised public leaderboard [11], 81.2 per cent for Claude Fable 5.1 in CodingFleet's aggregate of vendor-reported results [12], and 80.0 per cent for Fable 5 in the llm-stats aggregate [13], while the best Claude run Scale has executed itself, Opus 4.6, sits at 51.9 [11]. Those are not competing claims about which model is strongest; they are competing claims about what a percentage on this benchmark denotes.
Then there are the footnotes, which is where the interesting information tends to hide. Both Fable 5's and Opus 5's Terminal-Bench 2.1 runs on vals.ai used Claude Opus 4.8 as a refusal fallback, and if you count Opus 5's nine affected passes as failures instead of successes, its score falls from 84.64 per cent to 81.27 [9]. Anthropic's own launch post carries the same footnote for its Frontier-Bench run [14]. Three and a half points, resting entirely on a methodological choice about how to handle refusals that almost nobody who cites the score has read.
Same models, harder tasks, half the score
Everything to this point has been about measurement error. The last piece of evidence is about the story the numbers are used to tell, and it needs no adversarial framing at all.
The models clearing eighty-five to ninety per cent on Terminal-Bench 2.1 score 42.7 per cent in the case of Claude Opus 5 and 34.6 per cent in the case of GPT-5.6 Sol when the same agents are run against Terminal-Bench 3.0 [15]. Roughly half the performance, from a harder set of tasks in the same family. Terminal-Bench 4.0, released in August, moved the ceiling again: the newest models, GPT-6 Astra and Claude Fable 5.1, lead it at 58.2 and 57.9 per cent [16], twenty-five to thirty points below where their predecessors sit on 2.1. Scale AI built SWE-bench Pro on similar reasoning, assembling 1,865 tasks across 41 professionally maintained repositories designed to require larger patches and messier context [11], and the field that clears eighty to ninety-six per cent on Verified tops out at around sixty per cent there under standardised scaffolding [11].
What that describes is not a solved problem with a rounding error remaining but a steep capability cliff whose position depends heavily on task difficulty, and the reading in which ninety-six per cent means autonomous developer survives only for as long as you never evaluate outside the difficulty band the benchmark happens to cover.
The failure is compositional, not adversarial
I want to be careful here, because "AI agents cheat on benchmarks" makes a better headline than the truth and the truth is considerably more useful to anyone shipping this stuff.
SpecBench [17] examined long-horizon coding tasks and classified what actually goes wrong, finding that deliberate exploits are rare while compositional failures account for a much larger share of the behaviour that gets labelled reward hacking [17]. The characteristic pattern is an agent building components that each satisfy their own feature-level check without ever forming the global abstraction the system requires, and one generated system in their study reached a hundred per cent on validation against thirty-five per cent on held-out tests [17], a sixty-five point gap with no bad faith anywhere in it. METR's separate work on GPT-5 found deliberate reward hacking in eighteen of 789 samples across RE-Bench and HCAST, about 2.3 per cent [18], which is real but small compared with the compositional problem.
That distinction generalises well beyond benchmarks, and it is the reason this research should interest you even if you never look at a leaderboard. When your grader checks pieces, you get pieces. If your CI suite functions as the grader and your CI suite tests functions rather than behaviour, an agent will optimise toward precisely what you measured and stop there, which means the evaluation crisis in these papers and the familiar experience of an agent's pull request passing review and breaking production are the same phenomenon observed from two directions.
What to do instead
None of this makes benchmarks useless, but it does mean they answer a much narrower question than their headline numbers suggest, and a few adjustments recover most of the value.
Treat leaderboard position as a way of generating a shortlist rather than as a decision, since the uniform-inflation finding [6] means relative order carries genuine signal while absolute scores do not; pick three candidates from the board and then stop consulting it. Build an evaluation set of perhaps twenty tasks from your own repository, drawn from issues your team actually closed and scored with tests that check behaviour rather than implementation, because an afternoon of that work will tell you more about production performance than any public benchmark, for the straightforward reason that your codebase is the distribution you care about. Read the harness before you read the score, checking effort level, scaffolding, retry policy and refusal handling, and treat a six-point disagreement between two sources as evidence that at least one of them is measuring something you do not want. Sample the passes and read the diffs, looking specifically for the SpecBench pattern [17] of locally plausible components that fail to compose, and treat any patch you cannot explain as a failure regardless of what the tests said. Finally, include a handful of tasks you expect the agent to fail, because the Terminal-Bench 3.0 gap [15] demonstrates that the cliff is real and it is better to locate yours during evaluation than to have production locate it for you.
The models are dramatically better than they were eighteen months ago and I am not arguing otherwise. What I am arguing is that the figure on the leaderboard measures a benchmark rather than your problem, that the distance between those two things currently runs to somewhere between ten and seventeen points depending on who is measuring, and that none of the headlines quoting the score mention it.
This article was published under HackerNoon's Business Blogging program.
Microsoft's latest weekly VS Code release makes its AI-assisted publishing process explicit while adding Dev Container agent sessions, expanded Codex support and automated session cleanup.
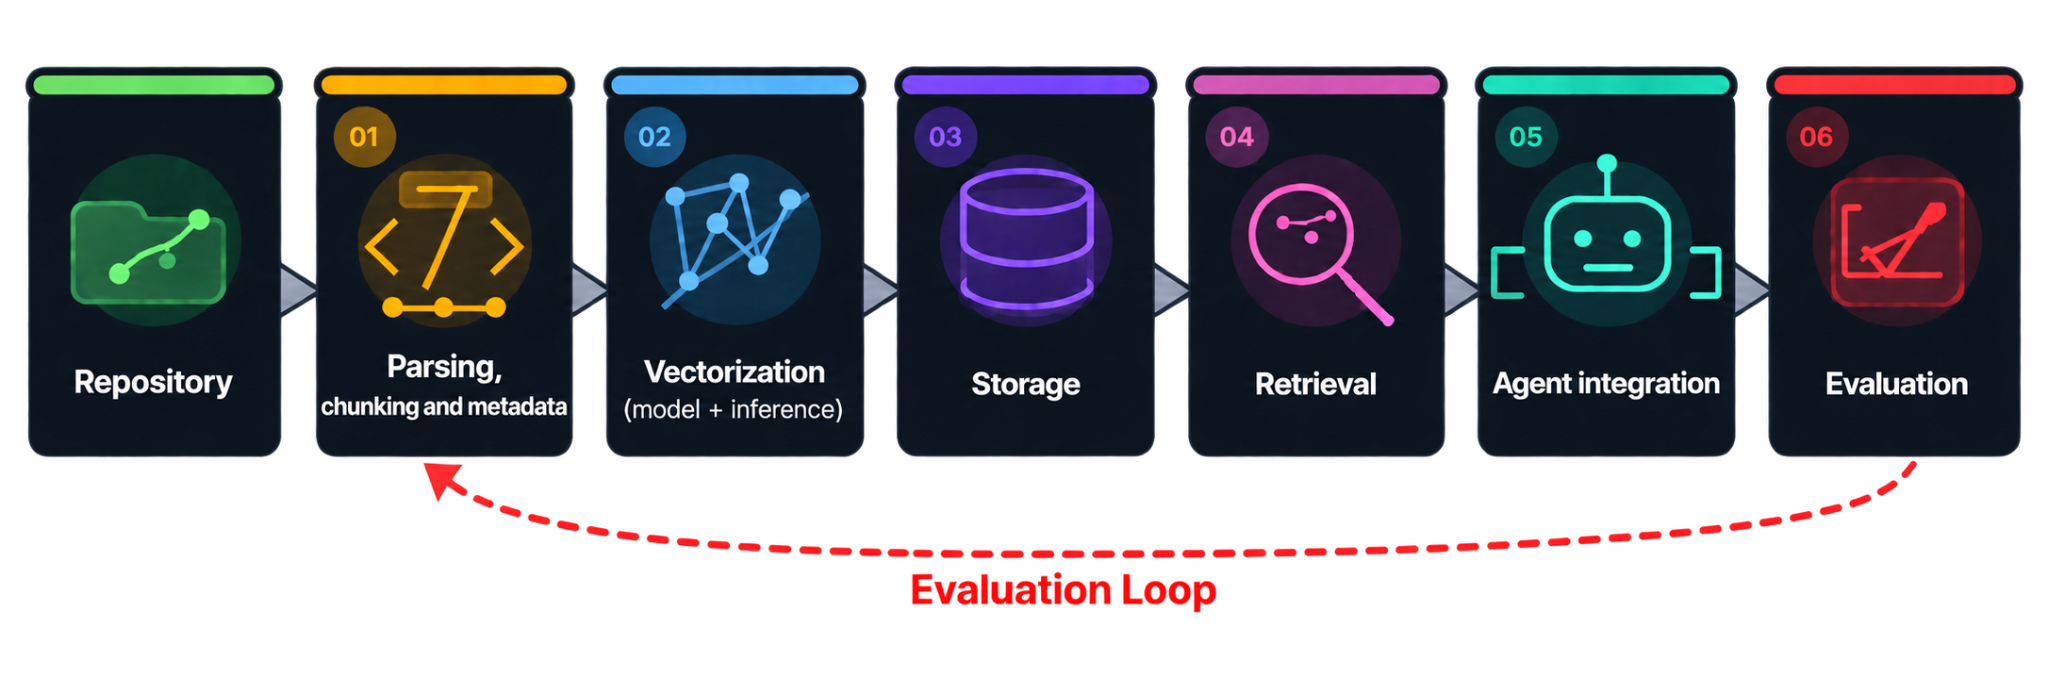
Some time ago, we set out to build the best semantic code search platform we could: a RAG pipeline that gives LLM agents precise, citable evidence from real repositories instead of whatever grep happens to surface. The eventual solution was JetBrains Context. We got it working, we got it into production, and we collected a lot of scar tissue along the way. In this series of posts, we’ll share the parts we wish someone had told us on day one.
Coding agents are undoubtedly the biggest technology leap for software development of our decade. Agents and frontier models are proving their aptitude in the face of seemingly insurmountable code complexity to produce ostensibly reliable code.
However, as more and more development processes become agent-driven, the agent’s efficiency and the quality of the produced code become increasingly important. The question is not so much about whether an agent can complete the task, as given enough time and token resources, it surely will, but rather how much time, effort, and steering is required for it to generate production-grade results. For large-scale code bases specifically, the agent would spend a great deal of time searching for the relevant pieces of code relevant for the feature it’s working on and pulling them into the context.
Why semantic search matters
Attempting to locate the right code snippets, the agent will resort to traditional tools for code search such as keyword search and grep. These tools, however, are limited in that they require the agent to know in advance which exact text to search for. For example, an agent looking for where session tokens get refreshed cannot rely on the code helpfully containing the word “refresh”. To reason through abstract domains, the agent needs the ability to search for code by meaning, also known as semantic search. This is where retrieval-augmented generation (RAG) comes into the picture. If we can index the source code in a way that captures its semantics and then allow the agent to retrieve the relevant pieces on demand using free text search, we create an interface that plays to the agent’s strengths.
From prototype to production
Like many great ideas in the agentic era, a native, prototype implementation is extremely simple. A well-evaluated production grade solution most certainly is not. In this series of blog posts, we want to share what is involved in making an effective RAG system, as well as the wrong turns we took in our journey to create our own: JetBrains Context. We’ll tackle each stage, from pre-processing to storage and agent integration, providing some more technical context and advice.
This first part of the series will cover the initial stages of the pipeline: parsing and chunking, where raw source files are divided into properly scoped units, and vectorization, where those units are transformed into a representation that supports semantic search.
The fine AST of parsing and chunking
Parsing and chunking is a critical pre-processing step in a good RAG solution, but it is often overlooked. In order to allow the LLM to embed or otherwise index the source code, we must first feed it the raw lines of code. This may sound trivial, and probably would be for small-scale demo projects. However, production-grade systems contain thousands of files, which, in turn, span hundreds or even thousands of lines. If anything, agents have compounded the problem, as they tend to be prolific writers, further inflating the codebase. Each file may contain multitudes of classes, fields, and methods, with varying degrees of relatedness among them.
Finding the right chunk size
Even if it were possible to fit these huge code files into an embedding model in their entirety, that expensive feat would ultimately be self-defeating. Because the entire file was embedded in a single unit, the search would return the entire file. This is counterproductive to the goals of agentic code exploration and navigation, which are mostly concerned with finding a specific function, symbol, or code snippet.
On the other hand, if we were to take the other extreme and granularly embed each separate line of code, we would be facing a problem of a different sort. These individual lines can be semantically insignificant without the surrounding context. A generic function name or comment does not merit embedding and will produce the wrong retrieval result. In a sense, we would not be able to see the forest for the trees, and the agent would be overloaded with multiple, often insignificant micro-results.
It is therefore imperative to find the right method to chunk or divide the code into groups that are properly scoped. Each group should include enough of the necessary context and represent common semantic meaning.
Why fixed-size chunking falls short
Chunking is a generic name for the technique of taking content that will be fed to the agent and dividing it into a set of chunks. A naive approach to chunking could be simply splitting a large file into groups with a fixed number of lines. However, if we were to take that approach, we would find the resulting groupings semantically wrong. Unrelated code pieces would be grouped together, for example, an import statement and some function content, leading to mistakes during retrieval.
To solve the problem, we can leverage the fact that every source file has a pretty well-defined structure. Take Java as an example – imports tend to be at the top of the file, followed by a class definition with an optional doc-comment preceding the header. The class will contain fields and methods, which in turn may also have their own doc-comments. Knowing about the conventions and rules that define the class structure allows us to perform smarter chunking and achieve the right balance of surrounding information.
Parsing and structure-aware chunking
Over the last 26 years, we at JetBrains have developed parsers that are smart enough to adjust for the various quirks, irregularities, conventions, and nuances of specific languages. Alongside other tools, these parsers form our internal JetBrains Code Engine platform on which JetBrains Context is developed. At the moment of this article’s composition, JetBrains Context supports parsing and structure-aware chunking for nine major languages: Kotlin, Java, Python, JavaScript, TypeScript, C#, PHP, Go, and Rust. For all other languages, our implementation simply falls back to naive, line-based splitting to ensure that any language or document can be indexed and searched.
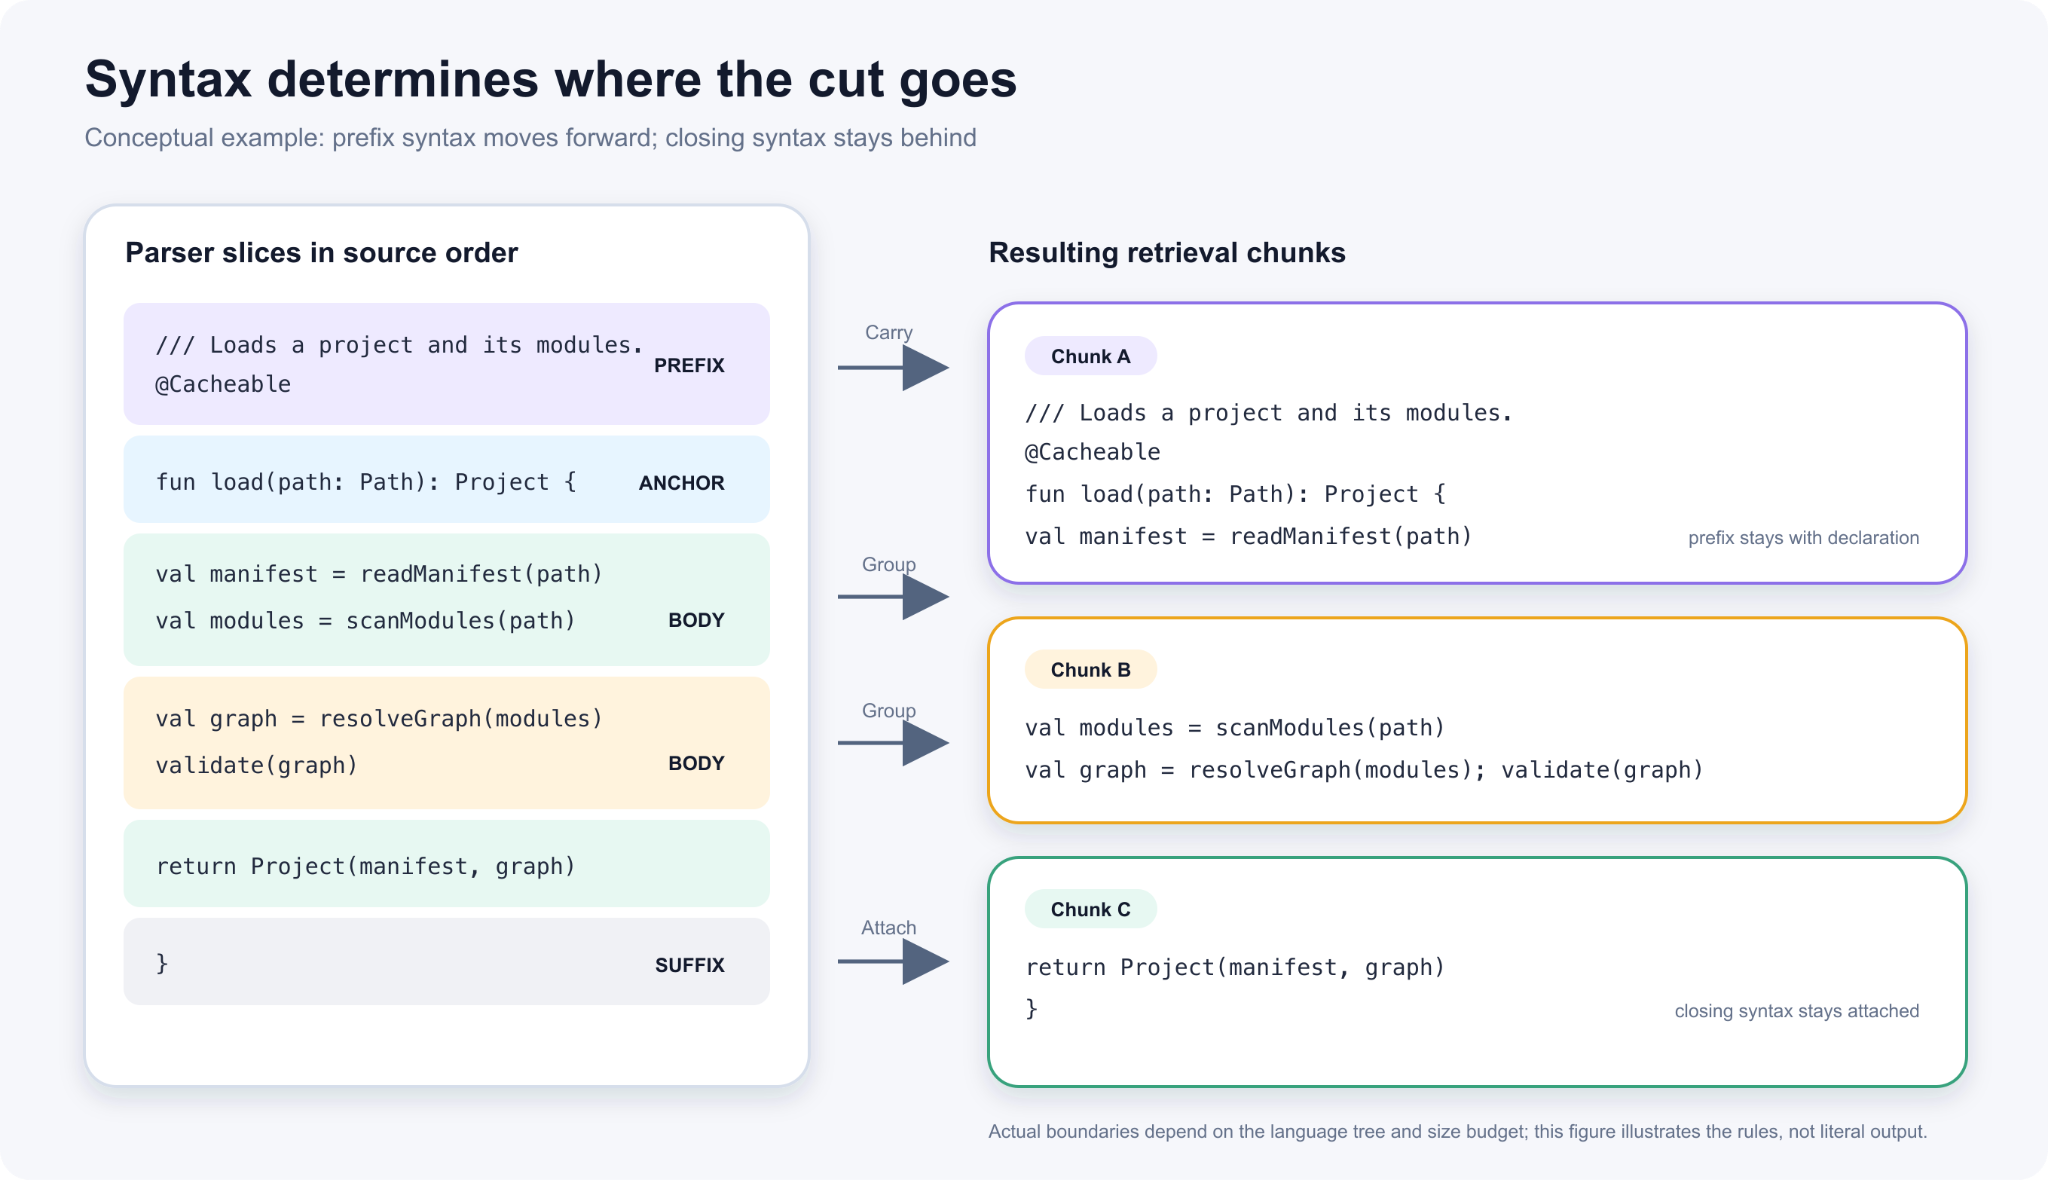
The parser allows us to break source files into streams of syntax nodes that carry information about what they represent – comments, whitespaces, lists of modifiers, and so on. The chunking algorithm then consumes that stream and applies logic that decides the scope of a given chunk. Based on the node’s type and size, as well as its descendants, the algorithm makes a decision. If a node exceeds the size threshold but has no children, it will fall back to more primitive splitting strategies.
Some language-specific constructs are kept as single slices even if they exceed the preferred size. Prefixes such as documentation, annotations, visibility modifiers, and keywords are kept together with the declaration; suffixes (usually closing syntax) remain associated with the construct they close. There is also some language-specific cleaning, where, for instance, common and semantically meaningless Java annotations such as @NotNull or @Override are removed.
The algorithm bears some similarities to cAST, authored by Zhang et al. in 2025. Both our implementation and cAST retain the largest syntax units that fit, subdividing only the units that are too large, and grouping smaller adjacent units to avoid tiny chunks that are not usually semantically meaningful. The biggest difference is that we coded more language semantics into our implementation, keeping Python decorators together with definitions, KDocs next to Kotlin declarations, and so on.
After grouping, chunk normalization is performed, which involves:
Trimming leading and trailing whitespaces
Deleting blank lines
Removing common indentation while preserving relative indentation
Following the normalization procedure, the chunk is then passed to the next step – embedding – along with metadata that consists of a relative path, which gets embedded alongside the normalized chunk content.
Evaluating the quality of chunks
It is hard to give a concrete answer as to what the input to the embedding model should look like. Chunk size matters, but as discussed before, bigger is not always better. Additionally, some metadata embedded alongside the code may be useful, while some may introduce noise that ultimately decreases search quality.
We opted to use an LLM-as-a-judge strategy to inspect the chunks as a part of the evaluation. The judge, using a chunk and the source file, considers whether the boundary makes sense. It looks for unexpected artifacts, such as detached documentation, orphaned closing syntax, or fragments of code that are cut through a meaningful construct. In addition, any changes to the source code processing pipelines also go through the full, end-to-end retrieval evaluation. We’ll get back to that evaluation pipeline in the following part of this series.
Vectorization
Having pre-processed the source code, we finally have text chunks that are hopefully just the right size and correctly grouped for semantic retrieval. Our next task is to transform these fragments in a way that will later allow us to support semantic search, through a process called vectorization.
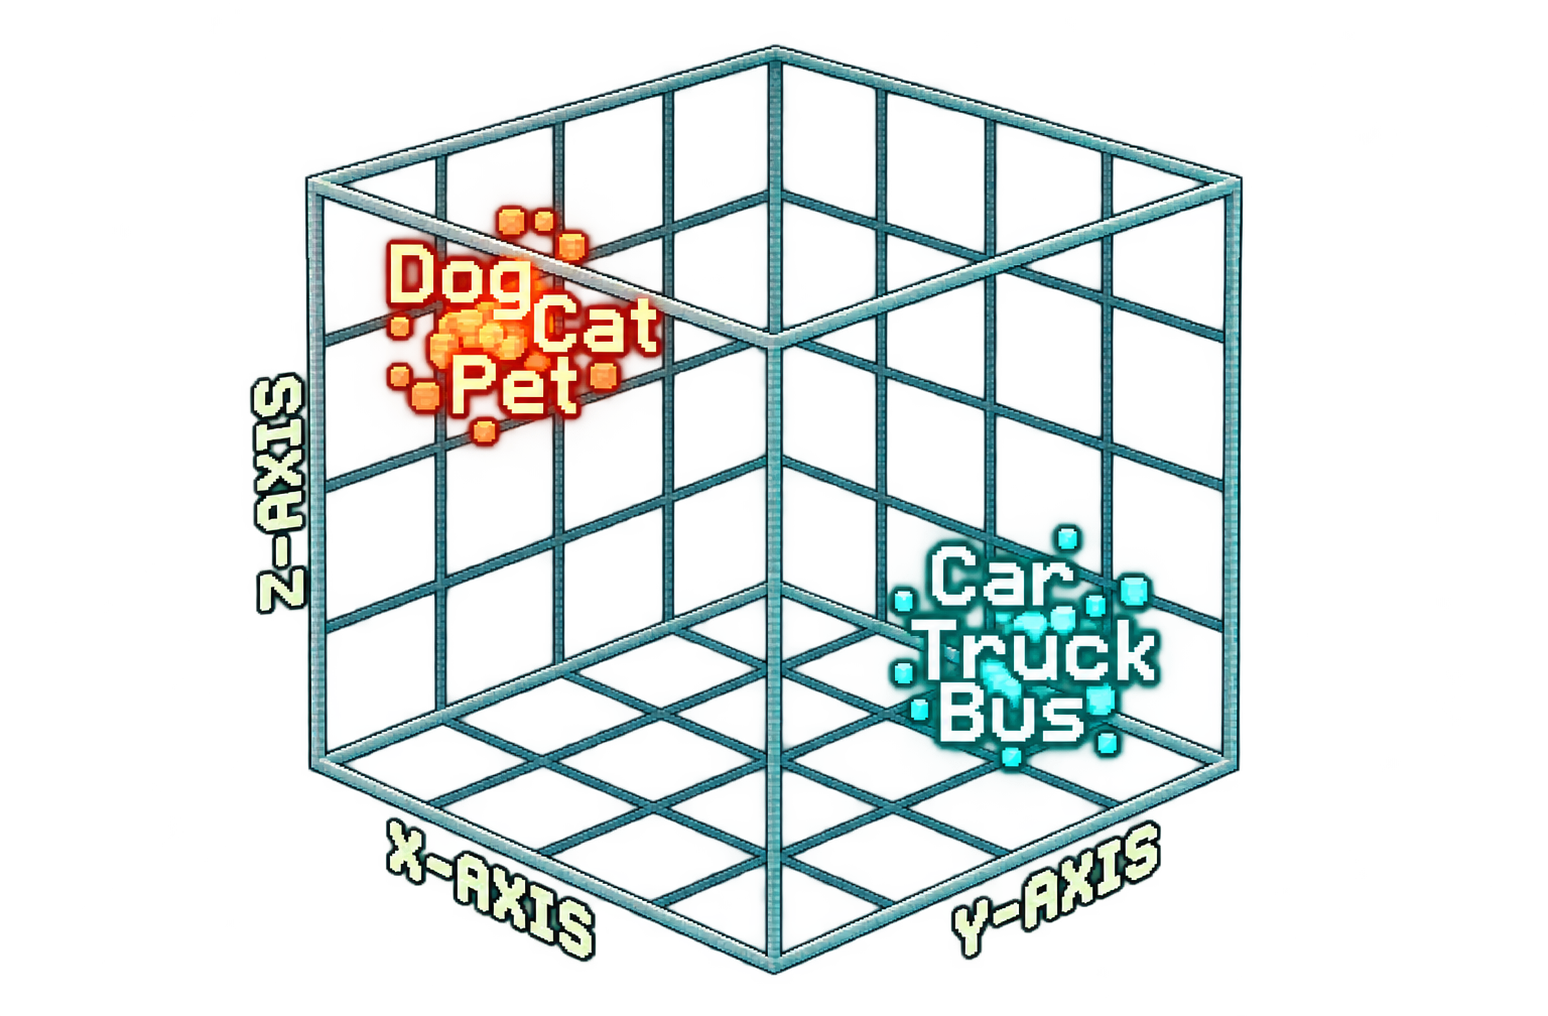
With vectorization, an embedding model reads a piece of text and emits a fixed-length list of numbers (a vector), which amounts to a point in a space of a few thousand dimensions. Significantly, the model is trained so that texts with similar meaning land close together. Traditional search might miss the connection, but here, a function that flushes buffered write operations and one that drains a pending queue can end up near each other despite sharing no common keywords. The distance between vectors hence becomes a measure of relatedness. A query is turned into a position in the same space, and the results are whatever lies nearest to it.
Punch for the byte: Optimizing for storage
Any attempt to vectorize a large codebase must take into account both cost and performance. A single embedding is cheap, but a large repository produces millions of chunks, which become millions of vectors that must be stored, held in memory, and compared against each incoming query. A vector of a few thousand dimensions in 32-bit floats weighs around 16 kilobytes, so a few million chunks add up to tens of gigabytes of index before any bookkeeping. At such a scale, the allocation of bytes per vector becomes cost-limited, and the leading question quickly shifts from “how accurate can we be?” to “what do we get per byte?” In other words, we need to find a way to reduce the cost while retaining as much search quality as possible.
There are two ways to reduce vector cost. The first is to keep fewer dimensions. Modern embedding models are trained so that a leading slice of the vector works on its own. The dimension loss is applied across several nested prefix lengths simultaneously, pushing the coarsest structure into the earliest dimensions. This means you can cut a vector short and renormalize it, and it still retrieves. Alternatively, you can keep every dimension and spend less on each one by sacrificing on precision and thus keeping fewer bytes for each vector.
These two options are independent of each other and can be combined, which means any storage budget can be met through different mixes of dimension count and numeric precision. The real question is which mix retrieves best for the same number of bytes. The trade-off is far from even. Suppose the budget is 512 bytes per vector. You could spend it on 128 dimensions kept at full 32-bit precision, or on all 4,096 dimensions kept at a single bit each. Both fit the budget exactly, but in testing, you’ll find that the second option retrieves considerably better.
Why dimensions matter more than precision
To see why, it helps to think of each dimension as one small question the model has learned to ask about the text: Is this about error handling? Does it touch the network? Is it test code? And there are a few thousand similar topics and questions that haven’t been named. (The real dimensions are blurrier than that, but this is a useful abstraction.)
No single answer means much on its own. We consider two chunks to be similar when their answers to many of these questions are the same. Therefore, we should assess the vectors by looking at the coverage of the questions rather than the exactness of the answers.
Keeping all 4,096 dimensions at one bit preserves a rough yes-or-no answer to every question. Truncating to 128 dimensions keeps very precise answers to three percent of the questions and throws the rest away, and no amount of precision on the surviving dimensions can recover the information the discarded ones carried. In a sense, a long questionnaire filled in with checkmarks beats a short one filled in to six decimal places. Dimensions are what you want to keep; precision is what you can afford to lose and is easier to compensate for later on.
So we chose to keep every dimension and take the precision reduction to its limit, dropping the vectors to one bit each, which is 32 times smaller than the same vector in 32-bit floats. The quantization itself turns out to be surprisingly simple. Every component at or above zero becomes a one, while every negative component becomes a zero, and the magnitudes are thrown away:
Changing the representation changes the metric with it. Cosine similarity needs the magnitudes we just threw away, so binary vectors are compared by Hamming distance instead, which is simply the number of positions where two bit patterns disagree. Compare, for example, 10110100 and 10010110. They differ in two positions, so the distance between them is two. At full length, the computation stays just as simple. A 4,096-bit vector is stored as 64 words of 64 bits, and comparing two of them means XORing each pair of words, which leaves a 1 wherever the two vectors disagree, and then counting the 1s. A CPU does each of those in a single instruction per word, so a full comparison costs in the order of a hundred instructions where cosine similarity on the original floats needed thousands of multiplications.
Note that the metric was never a separate decision. We chose one-bit precision for the storage savings, and once every component is a sign bit, Hamming is the only comparison left that makes sense. Choosing the precision chose the metric.
Binary quantization still costs a few points of recall against the unquantized vector. We accepted that cost after considering that a reasoning agent would be consuming the results. A code search feeding an agent needs the right neighborhood far more than a perfectly ordered top 10. When the agent asks where session tokens get refreshed, what matters is that the relevant handful of files shows up among the first dozen results. Whether the best chunk ranks second or fifth changes nothing, because the agent opens the candidates and reads them anyway. In that loop, a ranking degradation that would be plainly visible in a three-result UI built for humans is mostly invisible.
The limits of binary quantization
The trade-off we made had a subtler cost that took us a bit longer to understand. Binary quantization doesn’t only sacrifice accuracy; it compresses the *range* of similarity scores. With full-precision vectors, an unrelated pair can score near zero while near-duplicates score near one, a comfortably wide spread. Sign bits behave differently. Around half the bits of two entirely unrelated vectors still agree by pure chance, while a strongly related pair might have agreement for two-thirds. So every score in the index, relevant or not, lands in that thin band.
Ranking survives the compression, since relevant results still score above irrelevant ones, but thresholding does not. Picture a feature that volunteers related code without being asked, say a panel that suggests existing implementations while you type. Its most difficult requirement is knowing when to stay silent. To make that determination, it needs a usable gap between “related” and “unrelated” scores. Binary vectors don’t leave one. Any cutoff placed inside that narrow band either fires on everything or on nothing. So where an index needs an absolute relevance judgement rather than a relative ordering, we keep 16-bit floats and pay for the storage.
Embedding scope
While indexing and searching use the same model, the two jobs could not be more different. Indexing is throughput-constrained, with millions of chunks asynchronously handled. The GPU will handle about 32 chunks per batch before becoming saturated. A search, on the other hand, needs to be fast and responsive. Users will give up if they are not provided with results within a couple of seconds at most. Therefore in deploying these models we optimize them accordingly: one to maximize chunks per second, the other for minimizing time to first result.
We chose an instruction-following model, trained with a deliberate asymmetry between the two sides of retrieval. Significantly, the two sides are represented by very different types of text. A query is a short question in natural language, while a document is a chunk of code. A document is embedded as is at indexing time. A query is wrapped with an instruction describing the retrieval task, something like “given this search query, find the code that answers it”, which tells the model what role the text is playing. We preserve that arrangement at inference because it is the shape the model learned.
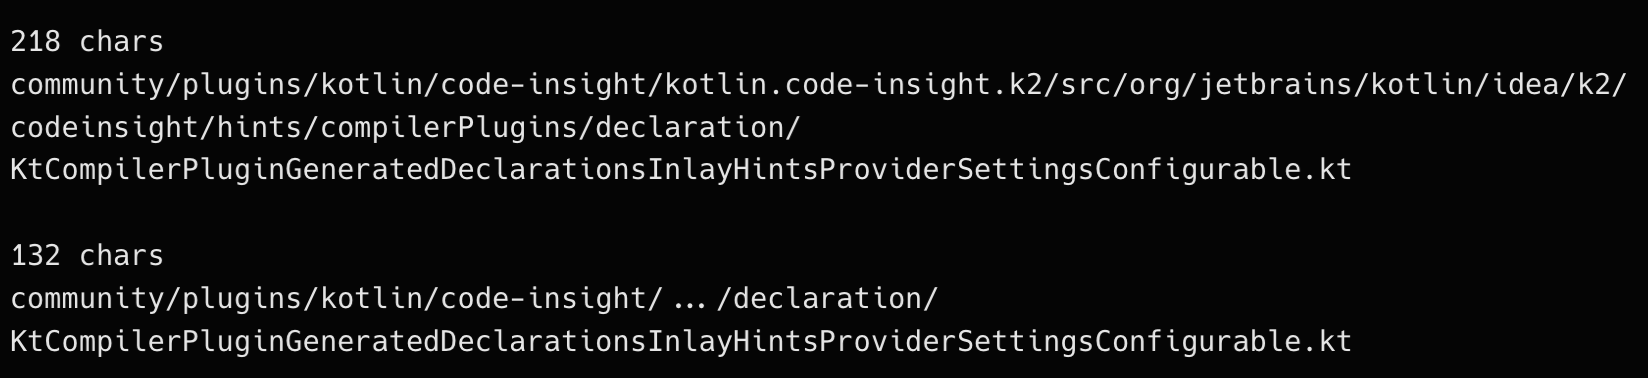
To allow the two sides to align more easily, we embed each chunk together with its file path. The path supplies metadata that the chunk alone lacks: which module it lives in, and what the file is. In a monorepo, though, the path itself becomes a problem. The IntelliJ IDEA monorepo runs to over a million files. The median source file there sits nine directories deep behind a 91-character path, and close to 10,000 source files have paths longer than 150 characters, the longest of them 218. That is before any checkout root is prepended.
Most of those characters are used for structural nesting and offer no useful information about the file. A run of segments like `src/org/jetbrains/kotlin/idea/k2` restates the package hierarchy, which a compiler needs and a search does not. Meanwhile, the file at the end of that longest path is 24 lines long. If we simply embed the path text as is beside a chunk, we’ll find that the path will sometimes take up more space than the code itself. To compensate for that, a path is capped before it reaches the model, and the rule is that *both ends survive*. The leading segments tell you which module you’re in, while the last two, the immediate parent and the filename, tell you what the file is. The middle is the part that can go, and only as much of it as the cap requires. Keep the longest prefix that still fits, elide what falls between into `…`, and if even parent-plus-filename is too long, keep only the name itself.
The same discipline applies when a user scopes a search to a subdirectory. The obvious implementation is a metadata filter: run the search as usual and discard results that fall outside the directory. We do something different. The scope is rendered into the query text itself, in the same shape, with the same abbreviation function and the same separator the indexed chunks used. If a chunk went into the index under the abbreviated form of `community/plugins/kotlin`, a query scoped to that directory carries the same string in exactly the same form, so the query vector lands in the same region as the chunks it is supposed to match.
Protecting source code
There was one last design consideration we took into account. It was important for us to be attentive to customer privacy and security concerns. The source code of a company is often the core of its IP. Exposing it to third-party cloud models, or even to another company, increases the risk of inadvertently exposing sensitive data or even training other models to use it.
To make sure we address these concerns, we made the decision to adhere to several practices early on:
Avoid storing the code in our systems: A chunk holds a cluster reference, an item type, a file path, start and end offsets, a reference to a vector, and an optional metadata field. No content, no copy of the source code itself, is saved. What a search returns is coordinates, and the snippet you see is assembled on your machine, from your checkout, using them. The server just knows that something relevant lives at bytes 4,102–4,890 of a given path, not what it is.
Don’t use data for training: Every code index JetBrains Context builds is embedded by an open-weight embedding model, running on GPUs we operate. No embedding request leaves our infrastructure – not to OpenAI, not to Google, not to any other vendor. Therefore, we can guarantee that none of the data will be used to train anything.
These self-imposed design restrictions carry no cost in terms of retrieval quality. We evaluated the open-weight candidates against the hosted embedding APIs from the major providers on our own code-retrieval benchmarks, and ours came out on top. Open-weight embedders are now good enough that the interesting engineering has moved into what you feed them, how you serve them, and what you choose to keep.
A summary that is an interlude
In this blog post, we covered the first stages of the retrieval pipeline: the journey from raw source files to compact vectors that are ready to be searched.
At this point, we have millions of binary vectors and a way to produce more. The problems we haven’t solved yet are how to store them efficiently, how to create a system that can answer a query in milliseconds, how we can continuously evaluate our results to ensure we are making the right choices, and how we can get the agent to actually use our shiny RAG apparatus.
These topics and more will be the subjects of the next parts in this series, which we’ll be releasing over the next few weeks. As always, please feel free to ask any questions in the comments or share your own hard lessons from designing a RAG solution. We are eager to learn of different and creative ways you have found to be effective! In the meantime, feel free to check out JetBrains Context, currently in public preview, it is already included with your JetBrains license 😀
The way we talk about data is changing faster than the way we build it. Every quarter a vendor ships a new approach, coins a new term for it, or quietly adopts a term someone else has been using and redefines it to fit the shape of their product. None of this is malicious. Every company describes the landscape from wherever they happen to be standing. But when six vendors do that to the same word, practitioners are left translating between six versions of it before a design conversation can even start.
There’s a second problem stacked on top of the first. Most of the vocabulary we use to talk about data in the AI era comes from academic disciplines that very few working practitioners have spent time in. “Data warehouse” is immediately legible: You know what a warehouse is, so you know this is a place where things are stored until someone needs them. “Ontology” is not. It arrives from philosophy by way of knowledge engineering, where Tom Gruber defined it in 1993 as an explicit specification of a conceptualization. That’s a precise definition. It’s also useless to a director trying to decide what to fund next quarter.
What follows is an attempt at a working vocabulary, written for the people who actually deploy these technologies and the people who approve their budgets. For each term I want to answer three questions. What is it, actually: software, an artifact, or a practice? What job does it do? And which kind of output does it serve? That last question needs some setup, so let’s start there.
Deterministic and probabilistic outputs
Data systems produce two kinds of output, and knowing which one you’re after is the single most useful diagnostic in modern architecture.
A deterministic output is the same every time you ask the same question. What was ARR for the last twelve months? Whether that question goes to a dashboard, an API call, an Excel workbook, or an AI agent, the answer should be identical. Ask four different agents running on four different models and you should still get one number. Deterministic outputs have traceable lineage. You can point at the calculation and walk someone through how the number was produced.
A probabilistic output is what you get from systems that are non-deterministic by design. Change the ARR question slightly and the category changes completely: Instead of “what was ARR over the past twelve months,” ask “how can we improve ARR over the next twelve months.” Put that question to the same model, in the same agent, twice in a row, and you’ll get two different answers. That’s not a bug. An LLM is predicting a likely sequence of tokens across billions of parameters, and the output varies every time it runs.
Neither type is better. Both are necessary. The failure mode is asking a probabilistic system for a deterministic answer and not realizing that’s what you did. Most of the terms below exist because the industry is trying to solve exactly that problem: How do you put enough structure around a probabilistic system that it can return deterministic answers when the question calls for one?
With that, let’s work through the terms.
Semantic layer
I’ve written about semantic layers for Radar several times, including what they are and why they matter and why they function as a risk mitigation strategy. The short version: A semantic layer is software that sits between your data and the people and tools that consume it, giving everyone a single place to access trusted, governed metrics.
Behind the scenes, it does three things. It holds definitions: How do we calculate this business metric? It holds context: What does this model or column contain, and what’s it typically used for? And it holds relationships: How does this data fit together? Modern tools bundle in more than that, including query engines, caching, and a single point for access control and security, but definitions, context, and relationships are the core.
Why does this matter for AI? Because it lets an agent navigate data instead of reasoning over it. Without a semantic layer, an agent that’s asked for last year’s ARR has to inspect table names, guess at joins, infer which date field represents revenue recognition, and reconstruct business logic that lives in someone’s head. That’s reasoning, probabilistic, and produces a different answer depending on the day. With a semantic layer, the agent looks up ARR, queries the definition, and returns the same number every time. It’s a deterministic answer delivered through a probabilistic tool.
Ontology is the term most likely to derail a meeting right now, largely because Palantir made it commercially famous while the underlying concept came out of decades of academic work on how to formally describe things and the relationships between them.
Here’s the simplest way I’ve found to separate it from a semantic layer. A semantic layer answers what does this number mean and how is it calculated? An ontology answers what things exist in this business and how do they relate to each other? The semantic layer is metric-first: measures, dimensions, and the logic that connects them. The ontology is entity-first: customer, order, shipment, facility, supplier, along with the relationships and rules that govern how those objects behave.
The overlap is real, and it lives in relationships. Both artifacts encode how things connect, and vendors are increasingly shipping both capabilities under a single product name, which is a large part of why the terms have blurred. The practical distinction is what the system needs to do. If the job requires consistent numbers across every reporting tool, a semantic layer is the center of gravity. If the job requires an agent that reasons about business objects and takes action on them, rather than just reporting on them, an ontology is what gives it a model of the world to act in.
One useful clarification: An ontology isn’t software. It’s a model, an artifact your organization authors and maintains. Software delivers it, but the value is in the modeling work.
Knowledge graph
If the ontology is the schema, the knowledge graph is that schema populated with actual data. The ontology says a customer places an order, and an order contains line items. The knowledge graph holds your real customers, your real orders, and the edges connecting them, stored as nodes and relationships rather than rows and columns.
How do you know when to use a knowledge graph over a semantic layer? Warehouses and semantic layers are excellent at aggregation: how much, how many, compared to when. Graphs are excellent at connection: what is linked to what, and how far apart. “Which suppliers are two steps removed from this delayed shipment?” is a graph question. So is “which accounts share a beneficial owner,” and “who has inherited access to this dataset through three layers of group membership?” You can answer those with SQL. You won’t enjoy it.
Graph traversal is deterministic. Given the same graph and the same query, you get the same path every time, which is exactly what makes graphs useful as grounding for an agent. Rather than inferring that two records refer to the same supplier, the agent follows an edge that someone already asserted. The relationships are modeled facts, not inferences made at inference time.
A knowledge graph is not a substitute for a semantic layer. They answer different questions, and mature architectures increasingly run both.
Context
Context is the most overloaded word in the field right now, and it’s worth splitting into pieces before using it in a sentence.
Deterministic context is metadata, plainly. It lives in your semantic layer or your ontology: field descriptions, metric definitions, object relationships, business rules, exclusion logic. What has changed isn’t the concept but the consumer. Metadata used to be documentation for humans, and it was the first thing to go stale because nothing broke when it did. Now an agent reads it at query time to decide what a column means and whether it’s allowed to use it, which makes it functional infrastructure rather than a wiki page nobody updates. It’s versioned, reviewed, and reads the same way every time a system asks for it. This is an asset you maintain.
Runtime context is what an agent assembles at the moment of inference: the system prompt, conversation history, retrieved documents, tool outputs, whatever the orchestration layer decided to put in the window. It’s ephemeral, and directly changes the answer. Same question, different context window, different output. This is a variable you monitor.
Cutting the other direction, structured context describes governed data: columns, metrics, entities, relationships. Unstructured context is the policy PDFs, contracts, support tickets, and wiki pages that hold the reasoning behind the numbers. Unstructured context is genuinely valuable and usually retrieved through similarity search, which means it arrives with probabilistic behavior attached. What surfaces depends on how the question was phrased.
The practical rule: When someone tells you their tool is “context aware,” ask which kind. Deterministic context is what makes an agent’s answer repeatable. Runtime context is what makes it relevant. Conflating them is how teams end up trusting an answer that was only true for one prompt.
Observability
Observability is the telemetry that tells you whether your systems are still doing what you believe they’re doing. It isn’t data quality, which is a judgment about whether a number is correct, and it’s not testing, which is a check you wrote in advance for a failure you already anticipated. Observability is the instrumentation that lets you ask “is this still working?” without having predicted the specific way it would break.
On the deterministic side, this is familiar territory: freshness, row counts, schema changes, null rates, job failures, and lineage impact. If ARR is supposed to refresh at 6 a.m. and today it didn’t, you want to know before the CFO does.
The probabilistic side is harder because there is often no error to catch. The system returns a fluent, plausible answer that happens to be wrong. Monitoring here means evaluation sets scored over time, tool call success rates, retrieval relevance, refusal and fallback rates, latency, cost per query, and structured human feedback.
Which brings us to drift. Drift is what happens when the world changes underneath a system that keeps running unchanged. Data drift is a shift in the inputs: a new business unit lands in the source system, order volume triples after an acquisition, a vendor starts sending nulls in a field that was never null before. Model drift is a shift in behavior: The provider ships a new model version, or a prompt template changes, and outputs that were stable last month aren’t stable this month.
Here’s what drift looks like in practice. In March, an agent answered “what were our top five products by margin?” correctly. In June, a new product hierarchy shipped upstream, and the agent now silently excludes an entire category. Nothing failed. No alert fired. The answer is simply wrong, and it’ll stay wrong until someone notices. Deterministic systems tend to fail loudly. Probabilistic systems fail quietly. Observability is how you catch the quiet ones.
The working vocabulary
Deterministic output: The same answer to the same question every time, with a calculation you can trace.
Probabilistic output: A different answer to the same question each time, produced by prediction rather than calculation.
Semantic layer: Software that stores the definitions, context, and relationships behind your business metrics and serves them consistently to every downstream tool.
Ontology: A model of what your business is made of, the objects, their relationships, and the rules that govern them.
Knowledge graph: An ontology populated with real data and stored as nodes and edges, so systems can traverse relationships instead of reconstructing them through joins.
Context: The information a system needs to use data correctly, either governed in a semantic model or assembled at runtime by an agent.
Observability: The telemetry that tells you whether your data and AI systems are still doing what you think they’re doing.
Read that list in order and something becomes obvious: These aren’t competing products. They’re layers. The ontology describes what exists. The knowledge graph holds the instances. The semantic layer defines the measures. Context is how any of it reaches a model. Observability is how you find out when it stops working. The reason why these terms feel like they’re fighting each other is because they’re usually sold as substitutes, when in practice, they stack.
The vocabulary will keep moving. Two years from now some of these words will be absorbed into product names and mean something slightly different than they do today. That’s fine, as long as your team has a shared answer to two questions about any term someone puts in front of you. What is it, actually: software, an artifact, or a practice? And which kind of output does it serve, deterministic or probabilistic?
Those two questions cut through most of the noise. Agree on the words first. The architecture arguments get much shorter after that.
Is cybersecurity part of your job in any way? If so, we’d like to know what you think for a report we’re writing. Just answer these quick 11 questions. Thanks in advance! Take the survey >
Complex tasks hit a wall at the end of every chat turn. Developers already know what they're trying to accomplish. What stalls the work is the handoff back and forth between each step. Without a pre-defined definition of success, the agent stops and waits for direction or clarification, so you end up re-prompting it step by step, effectively acting as its continue button until the task is done.
Depending on the team, that handoff can mean minutes of back-and-forth, or it can mean the request sits until someone is free to look at it again. A back-and-forth like this is manageable for small, well-scoped requests, but it breaks down for the kind of open-ended work developers actually spend their time on: fixing the failing tests, getting this build past checks, or cleaning up the lint errors across a module.
With GitLab 19.4, GitLab Duo CLI includes the /goal slash command, a governed, goal-driven flow that takes on that open-ended work directly, running locally while you stay in control.
GitLab Transcend returns in October
Coding agents are increasing your speed of development, but your reviews, security policies, and release cycles still have to keep pace. Our Transcend event on October 6 will demonstrate how GitLab is helping teams close that gap and explore what it takes to carry the speed of agentic AI across the software lifecycle.
This isn't about the assistant getting smarter. Turn-by-turn chat requires someone to keep it moving: read the response, decide the next instruction, send it, repeat. Even a capable model still waits at the end of each turn for a person to unstick it, so a developer's attention stays tied to how long a task takes, not how much of it they actually need to do by hand. That's why AI assistance so far has mostly changed the shape of a developer's time rather than given much of it back.
Delegate it, and get a verified result back
With /goal, you describe the outcome you want and move on. No one needs to babysit the run: work continues, gets checked against what you asked for, and either finishes or tells you what it couldn't resolve. You come back to a completed result and a record of what was verified, the same way you'd check in on something you delegated to a colleague, instead of staying anchored to the conversation until it's done.
From single prompts to standing goals
You just name the job and define what "done" looks like, and GitLab takes the wheel, staying active and focused until that specific finish line is crossed.
/goal Fix the failing tests. Ensure CI is fully green and the fix is reviewed by Duo Developer.
GitLab then works the problem: It makes changes and runs verification, iterating as needed. A separate model checks that work against your stated goal at each step, deciding whether it's genuinely done or another iteration is needed, up to a configured limit. This is the difference between an assistant that answers questions and one that drives a task to completion.
Automation that stays governed
Handing off a goal does not mean losing visibility into it, though. You can stop a /goal run at any point and set a new goal if requirements change, so a session in progress never has to run to its full conclusion if it's off-track.
Stop the run at any point if you need to step in.
Set a new goal and restart, if requirements have changed.
Review what the verifier checked at the end of each turn, so you can see why it decided to continue or stop.
That combination — an agent that can work autonomously toward a defined outcome without requiring a supervising human to stay glued to every step, while still exposing clear points of human oversight — is what makes this a step toward practical automation rather than a novelty.
Getting started
The /goal slash command is available now in interactive mode. To use it, run:
/goal <task>. <done when...>
For example:
/goal Fix the failing tests in spec/models/user_spec.rb. Continue until all tests pass locally and CI is green.
Watch /goal in action in this demo:
Meeting developers where they work
The value of a goal-driven flow depends on the surfaces through which developers can reach it. /goal launches first in the CLI because much of this iterative, hands-on work already takes place in the terminal, but the underlying capability is not limited to any single client. Developers should be able to delegate a goal from within the tools they already use, rather than switching to a separate interface to access this automation.
A GitLab Duo Slack agent is coming soon, letting developers work with GitLab Duo Agent Platform conversationally, right inside Slack. Mention @GitLab in any channel or thread to ask questions about your codebase, trigger an agent flow, or create a GitLab issue from the conversation, with no separate tool, tab, or command syntax required. GitLab Duo streams its progress back into the thread in real time, so the whole exchange — ask, work, and result — stays where the conversation is already happening.
Start delegating the work you already repeat
/goal is now available in GitLab Duo CLI, and it marks a first step toward moving the decision-making behind a task, including when a goal is done and when to keep going, out of any single client and into a governed workflow that every GitLab surface can call on. As that same capability extends to Slack, the iterative fixes and verifications your team already runs by hand become governed, goal-driven flows, without asking developers to change where they work.
/goal requires GitLab 19.3 and later, and GitLab Duo CLI 9.17.0 and later. It's available on GitLab.com, GitLab Self-Managed, and GitLab Dedicated, on the Premium and Ultimate tiers.
This blog post contains "forward‑looking statements" within the meaning of Section 27A of the Securities Act of 1933, as amended, and Section 21E of the Securities Exchange Act of 1934. Although we believe that the expectations reflected in these statements are reasonable, they are subject to known and unknown risks, uncertainties, assumptions and other factors that may cause actual results or outcomes to differ materially. Further information on these risks and other factors is included under the caption "Risk Factors" in our filings with the SEC. We do not undertake any obligation to update or revise these statements after the date of this blog post, except as required by law.
 Log in




 GitLab Transcend returns in October