Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162602 stories
·
33 followers

What’s new in the W3C Website Design System

1 Share

The W3C Team published a significant update to the W3C Website Design System at the end of September 2026. The update was built by my team, as part of our involvement since the launch of the W3C website redesign in 2023, in response to feedback on the site. Our focus was on making the design system more flexible and easier to use. This post is about why the W3C website looks a bit different. It dives (sometimes deep) into the technical details of the update.

The design system itself was created in 2021 as part of the W3C website redesign project by Studio 24. A design system helps document and standardize the look and feel of a website, which then makes it easier to apply a consistent design across the different areas of a website.

Changes include replacing an old CSS reset, rebuilding typography around a new type scale, reviewing how space is managed, and removing several wrapper elements to simplify page markup. Here’s what changed, why, and what it means if you browse pages that use the design system.

collage of two side-by-side screenshots showing before on the left and after on the right

Before / after the design system changes on the W3C homepage and the page about web standards

Less empty space and text that adapts to the screen

Following the launch of the W3C design system, a lot of feedback was received about text sizes:

This update introduces a new 1.125 type scale. The steps between text sizes are more subtle, and headings are now smaller overall, so pages feel tighter while retaining a hierarchy that reads clearly, and a comparable elegant and airy use of space. We have also introduced fluid typography, so text sizes adjust smoothly with the viewport instead of jumping at fixed breakpoints.

Nine font sizes are now defined as CSS custom properties. These replace the Sass mixins that previously set combinations of font size and line height.

People familiar with the design system will remember that those mixins were tied to classes named after objects in our Solar System. The new text size classes are named for what they are. For backwards compatibility, the old classes still work and now map to the new ones.

Simpler page structure

We have removed the sticky footer pattern. Dropping it simplifies the overall page markup, in keeping with other changes made as part of this update.

The pre-footer component has also been refactored to make room for more content. The switcher layout which holds links such as an RSS feed, a contact email or event archives, is now a child of <div class="pre-footer">. Extra content can be added to the pre-footer, as long as it sits outside the switcher layout.

Small additions for lists and tables

Two new list modifier classes provide more control over list styles, with an option to hide bullets or numbers and another to remove the default indentation.

A new table modifier class adds vertical borders between columns, which helps with dense data tables.

Changes to listing templates

Listing templates used to require a wrapping container around their items or filtered results, with a class for each type of content.

That container and its classes are now gone entirely. The cards themselves handle most of the styling, including the space between them, through a class for each type of card.

Because cards no longer depend on a parent list, nesting one type inside another is much easier. For example, you can now place <div class="card card--user"> inside <div class="card card--member">. We have added styles for exactly that case: a nested user card has no content width restriction, and its avatar is 30% smaller.

Dense option for cards

There is a new modifier class for cards, to make them visually more dense. When added to a card that uses the sidebar layout, <div class="l-sidebar card">, two things happen: the width restriction on the wider content panel is removed, and all headings shrink to body copy size. This condenses each card, which makes long pages easier to scan.

A lighter, more modern baseline

Previously, the design system used Normalize.css, a widely used stylesheet that smooths out differences in how browsers display HTML elements by default. Because Normalize hasn't been updated since 2018, it has been replaced with a smaller, more modern set of baseline styles that serve the same purpose. We've also switched to CSS logical properties where practical, which adjust automatically for different text directions and reduce the need for language-specific rules.

A bigger change is how margin and padding are handled in the design system, in response to feedback from the community. Previously, a wildcard selector reset the initial margin and padding of all HTML elements and pseudo elements to zero, evening out any differences between browsers and allowing a fine degree of control by CSS authors. Spacing was then added on a granular basis, often targeting the sibling elements of a specifically named parent container.

This worked well for pages derived from the content management system, which offers a tightly defined set of content “components” and page templates. However, a number of GitHub issues were raised, which highlighted a lack of flexibility when working with the design system decoupled from the CMS environment:

That ruleset has been removed in the September 2026 update, which should make using the design system significantly easier.

For example, prose content previously had to sit within a dedicated text component, <div class="component component--text">, which managed the space and capped line length. With this update, that wrapper is gone. Line length is now limited directly on headings, paragraphs, list items and description lists. The result is a cleaner and more semantic markup that behaves the way you would expect HTML to behave.

Tell us what you think

The full list of changes is in the design system changelog. If you spot a problem, please open a GitHub issue.

Read the whole story
alvinashcraft
11 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Faster Python startup with lazy imports

1 Share

When a Python program starts, it needs to load all its dependencies (import). With the upcoming version of Python, it is possible to use lazy imports instead.

lazy import json
lazy from decimal import Decimal

In this instance, the name json is no longer the module, but a mere placeholder object. The actual import only happens when you use json. If you never use json, the module is never loaded.

How much does it help? Let us measure.

I wrote a toy command-line tool. It imports sixteen modules: json, csv, decimal, sqlite3, asyncio, email.parser, http.client, urllib.request, xml.etree.ElementTree, zipfile, tarfile, statistics and some popular third-party packages (numpy, pandas, requests, rich). The tool has three paths:

  • --version prints a string and needs nothing;
  • mean reads a small CSV file with the csv module and calls statistics.fmean;
  • stats loads the same file with pandas and prints a summary.

The lazy version of the tool is identical, except that I prefix the imports with lazy. It is a one-word change per line.

I use Python 3.15 (3.15.0b4) on an Intel Xeon Gold 6548N (Emerald Rapids), with numpy 2.5, pandas 3.0 and requests 2.34.

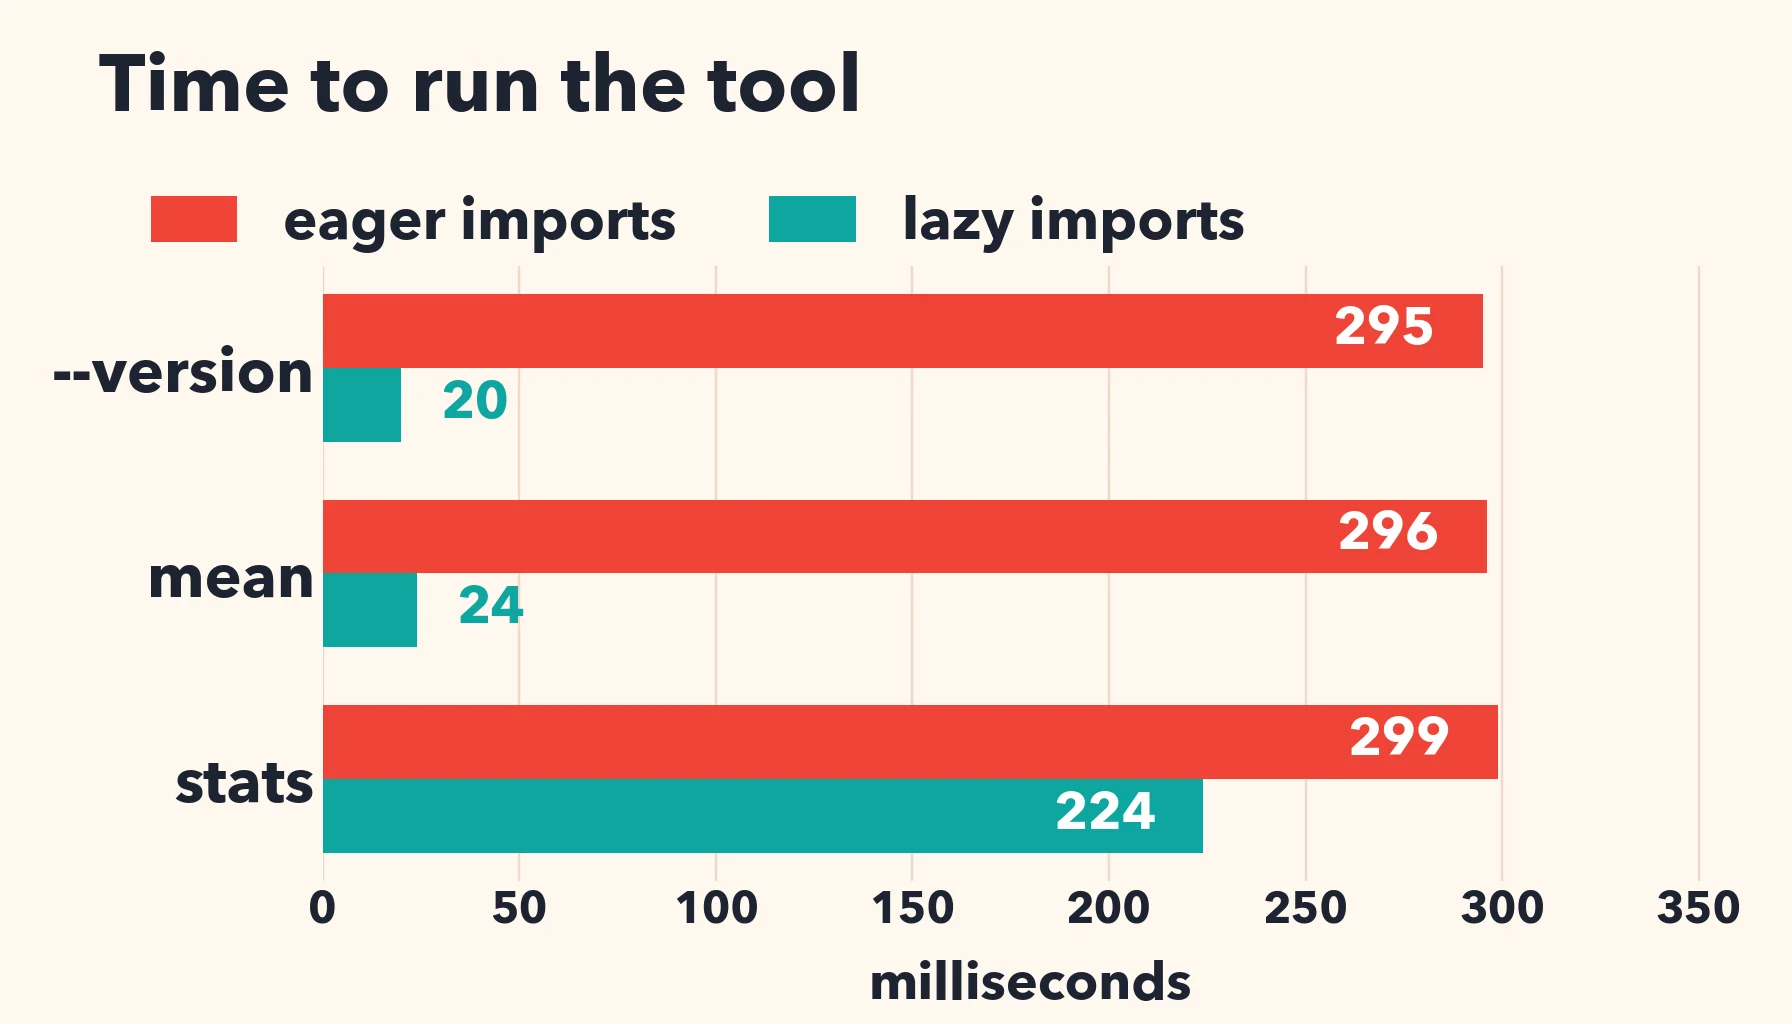
command eager imports lazy imports speedup
--version 295 ms 20 ms 15×
mean 296 ms 24 ms 12×
stats 299 ms 224 ms 1.3×

Eager imports take about 300 ms. Lazy imports take 20 ms for --version, 24 ms for mean, and 224 ms for stats.

Printing the version number goes from 295 ms to 20 ms. If you subtract the interpreter startup (11.7 ms), the cost of the imports goes from 283 ms to about 8 ms: a 35-fold reduction. The mean command, which needs a few standard modules, is twelve times faster.

There is a downside: errors move. With an eager import, a missing module fails at startup. With a lazy import, it fails at the first use, perhaps deep inside a function, perhaps hours later in a long-running server.

My source code is available.

Read the whole story
alvinashcraft
40 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Podcast: The Minimum Viable Manager: Building Trust, Feedback, and Alignment

1 Share

In this podcast, Shane Hastie, Lead Editor for Culture & Methods, spoke to Matt Gjertsen, founder of Built and author of Minimum Viable Manager, about the three foundational skills every first-time manager needs, how to build trust and give effective feedback, and why human leadership skills matter even more in the age of AI.

By Matt Gjertsen
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Model Selection Criteria

1 Share

How do you decide what model to use? Let’s look at workload, deployment, regulated environments and other criteria for selecting the right AI model.

In an AI application, a model is the trained component that receives an input and produces generated output such as text or structured data. The models we’re considering are large language models (LLMs), which can interpret language and return text or structured data (e.g., GPT, Claude, Llama, Mistral).

A model can perform well in a prototype and still be the wrong choice for production because the surrounding requirements change what counts as a good fit.

For example, a security review may show that requests cannot cross a regional boundary, while load testing may reveal that the model misses the feature’s response-time budget. Cost at projected traffic and the team’s ability to operate the deployment can also remove models from consideration.

In this article, we’ll look at the practical criteria that shape model selection. We’ll focus on workload fit and deployment requirements, including the constraints that come with regulated environments.

What the Model Needs to Do

Before we compare models, we need a clear description of the job. A strong score on a broad reasoning test won’t tell us whether a model can handle our document formats or return tool arguments that our backend accepts.

An evaluation set built from real inputs gives us a consistent way to compare candidates. Each test needs an expected result or a scoring rule so we can judge every model against the same requirements.

For each model, we can ask four questions:

  • Does it produce useful and accurate output?
  • Can it handle the required context length and languages?
  • Do its structured responses match the schemas our application expects?
  • Do its tool calls select the right operation and provide valid arguments?

A smaller model may be enough for document classification, while an agent choosing tools may need stronger reasoning. Public benchmarks and model cards can help us find candidates before we run these tests. A model card describes intended uses and limitations along with licensing and published evaluations. Those results give us a starting point while our own inputs show whether the model fits the feature we intend to ship.

Where the Model Runs

Once we know a model can do the job, the next question is where it will run. Running a model to produce an output is called inference, and the infrastructure that handles this work becomes part of the selection decision.

With a hosted model API, the provider operates the serving stack. A self-hosted model makes our team responsible for that stack in a cloud account or local environment.

A self-hosted model can run in our cloud account or our own data center. When it runs in our data center, the deployment is on-premises.

There are four common arrangements, each giving us a different level of control and operational responsibility:

DeploymentWhere Inference RunsWho Operates ItStrong FitMain Constraint
Hosted APIProvider infrastructureModel providerFast integration or traffic that changes quicklyRequests follow the provider’s data boundary and service terms
Managed private deploymentAn isolated managed environmentProvider or cloud platformTighter networking or reserved capacityAvailability and model choice vary by provider
Self-hosted cloudOur cloud accountOur teamControl over model versions and serving configurationWe own accelerator capacity and scaling
On-premisesOur data centerOur teamPolicies that require locally operated infrastructureWe own the hardware and its full lifecycle

If we choose to self-host, we need access to the model’s weights (the numerical values learned during training that help determine its output) under a license that allows our intended use. We also need to confirm that the model works with serving software our team can maintain and fits within the GPU capacity available at normal and peak traffic.

Because deployment affects performance and cost, we should compare candidates in the setup we intend to use. A hosted endpoint and a self-hosted deployment of the same model can differ in response time and total cost at production traffic.

Model Selection in Regulated Environments

The deployment choices become more specific when the feature handles regulated data. The applicable rules and our organization’s risk assessment give us concrete requirements for where inference can run and how its data must be handled.

In healthcare, HHS guidance on HIPAA and cloud computing says a covered entity may use a cloud service to process electronic protected health information when the required business associate agreement and HIPAA safeguards are in place. The organization still needs to understand the cloud environment and complete its own risk analysis.

For broker-dealers, FINRA’s cloud guidance says moving infrastructure to the cloud does not remove the firm’s regulatory responsibilities. The deployment still has to support vendor oversight and recordkeeping.

That means we need more than a model that performs well. Before using one with regulated data, we should be able to answer some additional practical questions:

  • Where are prompts and outputs processed, and can the provider use them for training?
  • How is the data retained and deleted, and which access and audit records can we export?
  • Which contracts govern the provider and any subprocessors it uses?
  • How are model changes approved, and can we restore an earlier version?

Making the Final Choice

Once we have a shortlist that fits the workload and deployment requirements, we can make the final choice by answering four questions:

  1. Does the model meet the workload? The model needs to clear the quality threshold on representative inputs and support the capabilities the feature uses.
  2. Can we deploy it within the required boundary? Its license and contracts must permit our intended use, and its data handling has to satisfy the relevant policies.
  3. Can it meet the runtime budget? Response time and total cost need to remain within budget at normal traffic and peak demand.
  4. Can we support the deployment? The responsibilities should be clear, including who manages capacity and model changes.

Together, these questions keep us from choosing a model based on quality alone. Recording the answers also shows why it was selected and gives us a useful starting point when the workload or deployment environment changes.

Wrap-up

Choosing a model begins with the work it must perform and where inference can run. From there, we can compare the remaining candidates against the response-time budget and the cost of the intended deployment.

A hosted model can still be a good fit for a regulated workload when its contracts and controls satisfy the requirements. When inference needs to stay within infrastructure we operate, self-hosting can provide the necessary control. The right model is the one that fits both the feature and the environment in which we need to run it.

For more on building AI-powered applications and agents with Progress, check out the following resources:

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Getting started with DSC 3.0 – Part 6: Using the DSC MCP server with your AI coding tools

1 Share

Throughout this series I ran into the same kind of problem again and again. Which resource type do I need? What is the exact name and casing of a property? Which adapter runs it? Names also change between versions. The Windows PowerShell adapter got a new name in 3.2, and the dsc mcp command became dsc server in 3.3.

An AI assistant that writes DSC YAML for you can easily get this wrong. It guesses, based on what it saw during training. DSC 3.0 has a built-in answer for that: an MCP server that lets the assistant ask DSC itself.

Note: this post is part of a bigger series on Microsoft Desired State Configuration.

DSC has an MCP server built in

You start it with:

dsc server

On DSC 3.2 the command was dsc mcp. From 3.3 on, mcp still works as an alias.

It talks over standard input and output. The AI tool starts the process and communicates with it, so you rarely run it by hand.

Remark: The Model Context Protocol is an open standard that connects AI agents to external tools and data. A server offers tools, and the AI tool, the client, calls them. Your AI coding tool is the client, and DSC is the server.

What tools does the DSC MCP server has to offer?

The tools fall into four groups:

  • Discover: list_dsc_resources lists the resources on the machine, show_dsc_resource shows one resource with its properties, and list_dsc_functions lists the configuration functions
  • Understand: show_dsc_schema (new in 3.3) returns the JSON schema for a configuration document, a resource or an output type
  • Evaluate: invoke_dsc_function and invoke_dsc_expression (both new in 3.3) let the assistant check a function or expression instead of guessing the result
  • Act: invoke_dsc_resource and invoke_dsc_config can run operations on your system. More about those below
Here is the list of tools as seen through the ModelContextInspector:


Why do we need this?

Take Part 4 of this series. We had to get the adapter name right, put requireAdapter on every instance, and use the exact property names of resources like WebSite and WebAppPool. With the server it can look those up on our machine instead of relying on memory.

Notice the last words: our machine. The server only knows the resources and adapters installed where it runs. Therefore, it is important to install the modules first, for example WebAdministrationDsc, or the assistant won't see them.

Set it up

Every client starts the same process. Only the JSON wrapper around it differs.

VS Code with GitHub Copilot

Create .vscode/mcp.json in your workspace:

{
  "servers": {
    "dsc": {
      "type": "stdio",
      "command": "dsc",
      "args": ["server"]
    }
  }
}

Open Copilot Chat in Agent mode, click the tools icon and check that the DSC server shows up in the list.

Claude Code

claude mcp add --scope project dsc -- dsc server

Everything after -- is the command that starts the server. With --scope project the entry is written to .mcp.json in your project root, so you can commit it and share it with your team. That file looks like this:

{
  "mcpServers": {
    "dsc": {
      "command": "dsc",
      "args": ["server"]
    }
  }
}

Run claude mcp list to verify the server is connected.

Try it

Give the agent a concrete task and tell it to use the server.  For example:

Write a DSC v3 configuration document in YAML that installs IIS on Windows Server, creates an application pool, a website on port 8080 and a web application. Use the DSC MCP server to check which resources and adapters are available and what their schemas look like. Use dependsOn between the resources. Don't run anything.

The agent should look up the resources first and then write the document. You can see each tool call in the client. Then do what we did in the earlier parts: run dsc config test and check the result before you apply anything.

Some other things to try:

  • Make sense of an export. Paste the output of dsc config export from Part 3 and ask the assistant to trim it into a desired-state document for the services you care about
  • Check an expression. Ask it to evaluate a configuration expression before you put it in your document
  • Explore. Ask what resources are available for a task, like the documentation's example "How can I manage Windows registry settings?"

Stay in control

An agent that can call invoke_dsc_resource can change your machine. A few habits keep this safe:

  • Mind the permissions. The server is started by your AI agent, so it runs with the permissions of that tool. Use a sandbox or limit the list of available tools.
  • Review the tool calls. Most clients ask for approval before a tool runs. Don't auto-approve the invoke tools.
  • Test first. Use dsc config test and dsc config set --what-if before a real set and try it on a test machine before production. The DSC documentation says this as well: always validate generated configurations in a test environment.
  • Read what it wrote. The assistant is guessing less, but it still guesses. You are responsible for the document that runs.

Wrapping up the series

We started with what DSC is and how 3.0 differs from the earlier versions. Then we managed a service, exported the current state, configured IIS with multiple resources and dependsOn, guarded a configuration with an assertion, and now let an AI assistant ask DSC for the facts.

DSC 3 is a completely different tool than the PowerShell DSC many of us know. Smaller, cross-platform, just data in YAML and in my opinion a lot easier to use.

There are some rough edges and the list of supported resources is still limited (but is growing). I have planned to write an extra post to share some of the issues (and solutions where available) that I encountered. 

I hope at least that this series made the switch a bit easier.

More information

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

If one anti-malware software is good, does that make two better?

1 Share

A colleague on the enterprise support team was investigating a complex failure from a customer, and after much analysis, it appeared that the problem was that the system had two different anti-malware programs installed. Let’s call then Contoso and Fabrikam. Fabrikam called a function that Contoso had detoured. Contoso’s detour thought this was suspicious, so it tried to quarantine the Fabrikam process. Unfortunately, Fabrikam had also detoured a function that Contoso was using. The result was mass confusion as the Contoso ended up calling into something that it was trying to quarantine.

Installing two anti-malware programs on the same system is like hiring two different security companies to patrol your building. If they don’t know about each other, each is going to think the other one is an intruder. If you’re lucky, their instructions are merely to report on suspicious activity.

But if you give them weapons and the authority to use them, you may end up with your two security companies pointing their weapons at each other.

In real life, you would introduce the two security companies to each other, or at least make sure they don’t patrol the same floor.

In software, this is harder to do. It’s not like you can invite two programs to lunch and have them get to know each other.

Anti-malware software typically does things that aren’t officially supported, like detouring system functions. And these detours mean that calling a system function no longer does the system thing; instead, it calls into the anti-malware software, and it might decide to do something unrelated to the system function you thought were calling, and that unrelated thing may itself start causing problems, say, by hanging. Not only is there no easy way to identify that this has happened, short of debugging an actual malfunctioning system, but even after you figure out the conflict, there’s usually no way to tell each anti-malware software to “stay on its floor.”

The post If one anti-malware software is good, does that make two better? appeared first on The Old New Thing.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories