Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164474 stories
·
33 followers

A new standard for vulnerability management in the AI era

1 Share
Windows is evolving vulnerability management as advances in AI make it possible to discover and analyze security vulnerabilities faster and at greater scale. AI is accelerating vulnerability discovery on both sides. It can help defenders find and fix vulnerabilities earlier. It can also help attackers search for vulnerabilities before fixes are available and analyze published fixes after release. All of this increases the importance of timely protection. Our approach is straightforward: lead across the vulnerability management lifecycle. We’re using advances in AI to find and fix vulnerabilities earlier, while maintaining a high-quality bar so you and your organization can deploy updates with confidence. We’re promptly publishing information about what we fix so security teams can take action. Just as importantly, we’re strengthening the systems that help organizations deploy updates quickly and respond when issues arise. Since our last communication on this topic, we have continued to advance this work across vulnerability discovery, remediation, validation, and deployment.

Finding vulnerabilities earlier

Identifying vulnerabilities before they can be exploited remains the best opportunity to reduce exposure. Microsoft receives vulnerability findings through responsible disclosure from security researchers and partners, while our engineering and security teams find issues internally. These paths come together through the Microsoft Security Response Center (MSRC), which serves as Microsoft’s central hub for vulnerability reporting, security updates and coordinated response. We are increasingly using AI to help security and engineering teams identify vulnerabilities and act on them more efficiently. One example is MDASH, an agentic code scanner that uses multiple AI models and specialized agents to find and validate potential vulnerabilities. Security and engineering teams then review the findings and determine the appropriate response, keeping human judgment and accountability central to the process. The objective is not simply to find more issues. The goal is to identify meaningful vulnerabilities earlier and make the findings more actionable. By using AI-assisted capabilities, we can distinguish relevant findings from false positives. We can give our engineers better information. As vulnerability discovery accelerates, these capabilities help us focus engineering resources on vulnerabilities that have the potential to affect customers more efficiently.

Moving from discovery to remediation faster

Finding vulnerabilities more quickly only helps if engineering processes can keep pace. We are applying AI assistance across the remediation process to help engineers assess impact, determine which versions of Windows are affected, identify variants in related code, evaluate remediation options, develop backport strategies for different versions of Windows, and build security and regression tests. Engineers remain responsible for reviewing the work, making the engineering decisions, and owning the final output. This distinction matters. Our goal is to use automation and AI to help engineers investigate and remediate issues more efficiently, not to remove engineering judgment from security decisions.

Strengthening validation

Increased discovery and remediation also require validation systems that can operate at greater scale. Windows validation combines multiple sources of evidence. Today, it’s internal flighting, functional testing, security proof-of-concept testing, application compatibility testing, and validation with OEMs, security vendors, ISVs, and customers through the Security Update Validation Program. We also apply AI-assisted capabilities to areas including test selection, test creation, triage, analysis, and reporting. Together, those signals provide evidence for engineers making release-quality decisions. Optional non-security preview updates remain an important part of this process. Organizations can install these updates on select devices before the content becomes part of the following month’s security update, providing additional real-world validation across devices, applications, hardware and configurations.

Making vulnerability discovery actionable

AI-assisted discovery is helping us find more vulnerabilities, across more code and earlier in the development process, so we can address more of them through Windows security updates. In fact, the October 2026 monthly security update addressed more than 1,100 Common Vulnerabilities and Exposures (CVEs) for Windows. The number of CVEs doesn’t tell the full story, though. We are using AI to examine more code, more deeply. The research community continues to find and report vulnerabilities. And we are prioritizing fixes in real time as vulnerabilities are identified. A higher number of CVEs does not mean Windows has become less secure. It means more vulnerabilities have been discovered and closed, reducing the opportunities attackers have to exploit them. Transparency makes those fixes more actionable. We publish CVE information for the vulnerabilities we address, whether they are reported by external researchers or identified by our own teams and AI systems. The Security Update Guide provides details on severity, impact, exploitability, and guidance for each CVE. We also make this data available in machine-readable formats, including Common Security Advisory Framework (CSAF) advisories, Vulnerability Exploitability eXchange (VEX) documents, and API, so it can flow straight into your vulnerability management and compliance tools. Security teams can use CVE information to:
  • Track which vulnerabilities are addressed on each device.
  • Prioritize which devices receive updates first based on exposure, starting with internet-facing systems, identity infrastructure, and high-value assets.
  • Measure protection in days from release, not in patch cycles.
Because Windows security updates are cumulative, prioritization should decide which devices update first, not which fixes get deployed.

When protection becomes available, the clock starts

On Patch Tuesday, Microsoft releases monthly security updates and the information and resources you need to evaluate and deploy them. This includes release notes, vulnerability information (available in the Security Update Guide), cumulative updates (through Windows Update and other deployment channels), and updated servicing media. Releasing an update changes what information is publicly available. Before an update is released, vulnerabilities are triaged through coordinated disclosure. Once the update and associated guidance become public, the fix itself can be analyzed. That means attackers might be able to use a published fix to better understand the underlying vulnerability and develop an exploit—potentially within hours. That’s why our work doesn’t stop when an update is released. We monitor diagnostic data and rollout reporting, customer support and inquiries, and feedback from social channels and forums. Automated systems help us correlate those signals and identify patterns for engineering investigation. Engineers investigate potential issues, validate their cause, and determine the appropriate response. Depending on the cause and impact, that response can include updated documentation or guidance, a workaround, Known Issue Rollback (KIR) to mitigate an affected change, or an out-of-band update. This is the lifecycle in practice: discover vulnerabilities earlier, develop and validate protections, publish them transparently, monitor their performance after release, and respond quickly when needed. But there is one part of that lifecycle Microsoft cannot complete alone: getting those protections onto devices.

Reducing your exposure window

Microsoft engineering systems are one half of the equation. Deployment is the other. The time between an update becoming available and reaching your devices is part of your security posture. A recent article by Anthropic1 noted that N-day exploits (the time between when vulnerabilities are disclosed but only patched on some devices) is a “patch gap”, as large language models now accelerate developing N-day exploits in hours not days as in the past. This has created a heightened risk threat for devices in the “patch gap”. Yet some organizations still take weeks to deploy updates. Diagnostic data from August 2026 showed that, among a measured Windows enterprise sample, fewer than half of devices had installed the security update two weeks after release, and about one in four still had not installed the update after four weeks. That gap between available protection and deployed protection is the exposure window we need to close. We are seeing organizations move in the right direction, accelerating rollout, moving to supported versions of Windows, and adopting newer update management and servicing capabilities. But faster deployment needs to become the standard, not the exception. Organizations should focus on four practical areas:
  • Stay on supported versions and install updates promptly after they are released.
  • Reduce unnecessary exposure and use security baselines to implement well-tested, industry-proven configurations.
  • Maintain endpoint detection and apply available mitigations.
  • Establish effective response and recovery practices.
Of those, staying current is foundational. Shortening the time between when Microsoft publishes a fix and when devices receive it reduces how long a known vulnerability remains unpatched. Newer, supported versions of Windows and modern management tools provide capabilities designed to make updating faster and less disruptive. For Windows 11, Windows Autopatch provides update management through Microsoft Intune, including staged deployments and reporting. For eligible devices, hotpatching can apply monthly security updates without a restart, while standard cumulative baseline updates are required periodically. Hotpatching also provides a path to faster protection for Windows Server while reducing restart requirements. Windows Server 2025 supports hotpatch updates2 across eligible Azure, Azure Local, and Azure Arc-connected environments, with Azure Update Manager providing patch orchestration. Organizations running older supported versions of Windows client or Windows Server should continue to keep those environments current and use the update management capabilities available to them. Where extended security updates are necessary, treat them as a bridge while moving to a supported version, not as a substitute for modernization. The goal is simple: turn an available fix into deployed protection as quickly as possible. Reduce the update deployment window wherever possible instead of treating security updates as a task that can routinely wait.

Leading at the pace of change

AI is changing the pace of vulnerability management. It gives defenders new ways to find vulnerabilities, analyze code, and develop protections. At the same time, it can shorten the time between public disclosure and potential exploitation. At Microsoft, our commitment is to stay ahead of that change. We are expanding AI-assisted vulnerability discovery, helping engineers move more efficiently from validated findings to fixes, strengthening validation, and monitoring updates after release. We are also investing in the tools and servicing capabilities that help organizations deploy protection faster. As we apply AI across this lifecycle, human judgment and accountability remain fundamental to how we build and service Windows. Our request of every organization is to move with urgency. Stay on supported versions, maintain layered protections, monitor security guidance, and make reducing the time from release to deployment a security priority. Vulnerability management will continue to evolve as AI advances. We intend to lead that evolution, share what we learn along the way, and give customers the information and tools they need to act. But protection ultimately depends on both sides moving quickly: our ability to find, fix, validate, and publish protections, and your ability to deploy them.
1. Measuring LLMs’ impact on N-day exploits. Jun 8, 2026. Anthropic 2. Hotpatch updates for eligible Windows Server 2025 machines connected through Azure Arc are available at no additional cost. Windows Server 2025 Datacenter: Azure Edition does not require Azure Arc for hotpatching and has hotpatch updates enabled by default.
Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Job listings for week ending 11/06

1 Share

Job postings that came across my desk, slack, email, discord, etc this week.

The post Job listings for week ending 11/06 appeared first on Leon Adato.

Read the whole story
alvinashcraft
17 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Call For Papers Listings for 11/06

1 Share

A collection of upcoming CFPs (call for papers) from across the internet and around the world.

The post Call For Papers Listings for 11/06 appeared first on Leon Adato.

Read the whole story
alvinashcraft
26 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Stop Copy-Pasting Your Life Into AI

1 Share

☀️ For Everyone · Practical AI for life and work

No technical background needed. Just useful ideas and experiments you can try yourself.

Builders: expect practical examples of using AI, rather than code or technical deep dives.


How do you actually use your AI?

Be honest, how do you use your AI today? For most people I talk to, it’s still a chat window. They open it and start typing (or, if they’re a bit more advanced, they talk to it using dictation). But the problem is that every time you start a new chat, you need to give it context.

Many times you ask the AI about something and you have to paste in an email, a screenshot of your calendar or whatever it is, just to get the answer you need. And you go through this cycle every single time.

If you think about it, that’s a very reactive way of using AI. It sits there waiting for you to remember to ask, and when you do, it only knows what you happen to feed it. Besides all the manual work (and sometimes I even wonder whether doing it yourself would be faster!), you’re the one deciding what context the AI gets, so you’re restricting it to whatever you paste in.

Now imagine if, instead of you taking a screenshot of your calendar or copying an email, the AI was actually connected to your email. It wouldn’t just look at the one email you pasted, it would go and look for your other conversations with that person, so its answer is grounded in a lot more context. For your calendar, it might look at similar meetings you’ve had, or spot a pattern you hadn’t noticed.

When your AI is connected to your data, a very different capability comes online. What would take you hours of digging, it does in seconds, and you’re not constrained anymore. Many times we don’t do something just because we know it will be really hard and time-consuming, but when your AI can go and get all of this itself, just imagine what it can do!

Let me give you a couple of real examples from my own week.

  • Replying to an old contact — a friend I’ve known for years messaged me asking what’s next for me. Before drafting a reply, my AI went back through our earlier WhatsApp chats and picked up context I hadn’t mentioned such as that we’d signed an NDA to look at a startup idea together and he’d invited me to a product demo. So it understood he wasn’t just making small talk, he was genuinely asking whether I was free to get involved. The draft it wrote was about my actual situation, not a generic “I’m exploring options”.

  • Inviting people to this blog — when I launched AI with Marlon, I asked my AI to help me pick who to invite. Instead of just taking my contact list at face value, it went through my message history to work out who each person actually was to me. It flagged a friend who had already subscribed, addressed an old colleague the way I’d normally talk to him, and left out family and the tradespeople in my contacts, without me having to spell any of that out 😅

In both cases I didn’t have to explain a thing. The context was already there, because the AI could go and find it.

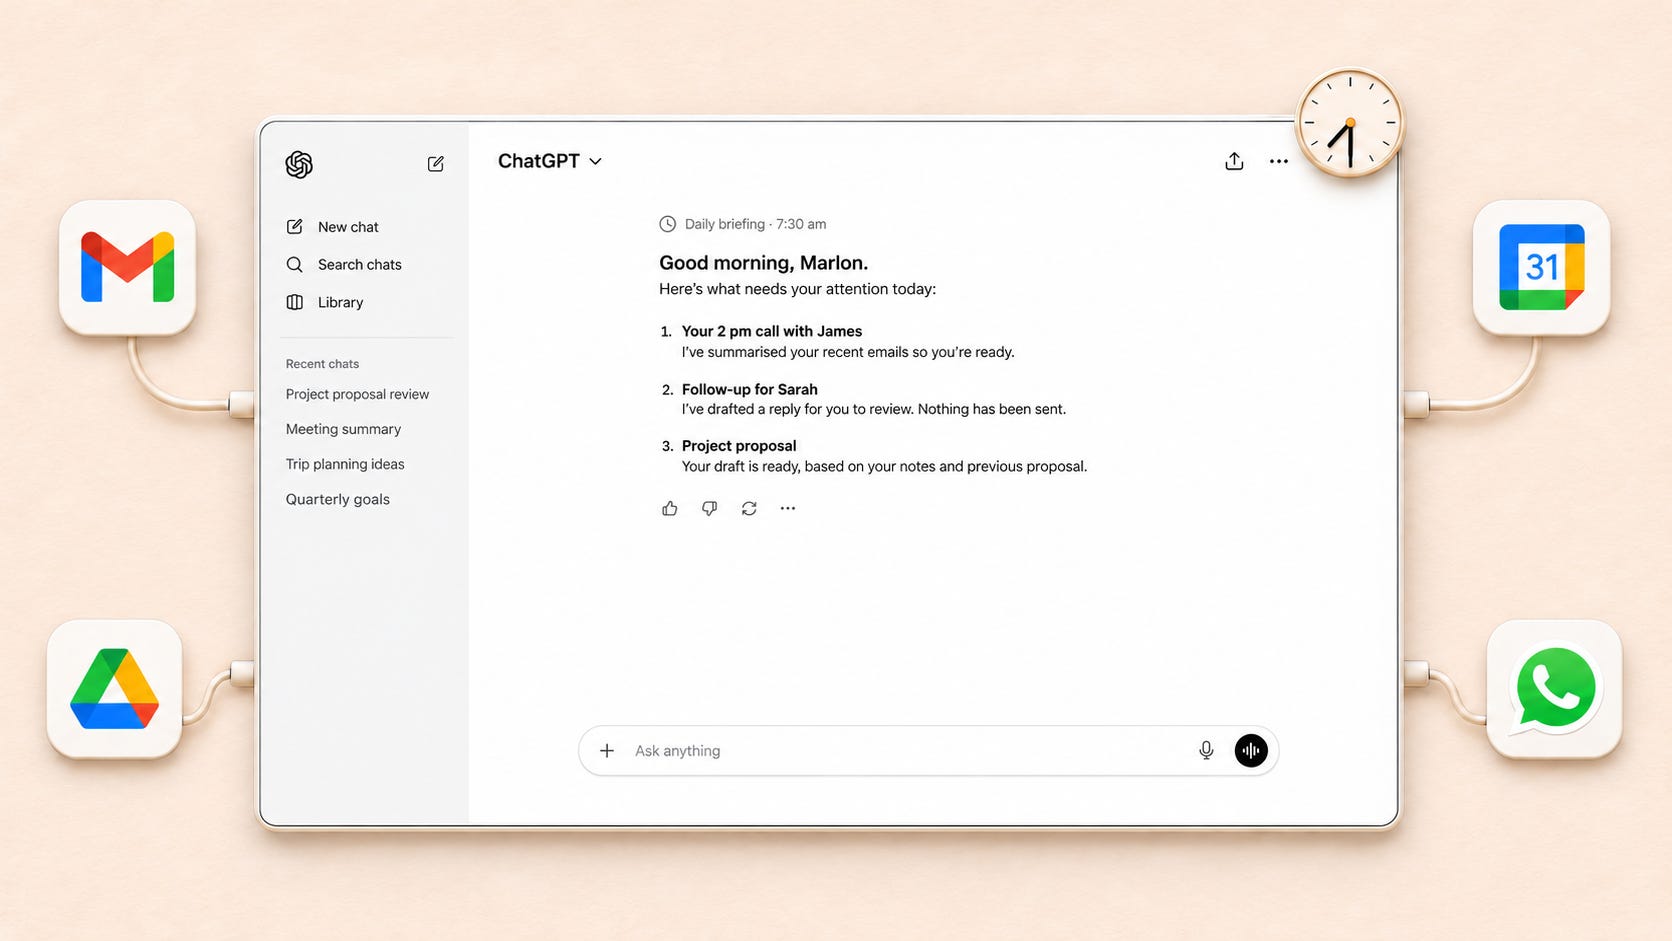
And that’s only half the story. Once your AI is connected, you can flip it from reactive to proactive: instead of waiting for you to ask, it checks your inbox, keeps an eye on your calendar and nudges you before something slips. In this article I’ll show you how to do both. First connect it to your world, then put it to work on a schedule so it starts looking out for you 😉

Thanks for reading AI with Marlon! Subscribe for free to receive new posts and support my work.

So why does context matter so much?

Imagine you hire a brilliant new assistant. Super smart, has read pretty much everything, and is ready to help. But on their first day you don’t give them access to your email, your calendar or any of your files. Every time they want to help, they have to come and ask you. Something simple like, “When are you free on Thursday?”, still takes your time to answer.

Yea, I guess, they’d still be useful, but you’d quickly wonder why you hired them. And that’s exactly how most people use AI today!!

Your AI knows a lot about the world, but it knows nothing about your world until you let it in.

The good news is that letting it in has become really easy. ChatGPT, Claude and Gemini all let you connect your email, calendar and files easily, and most of the other apps you use can now be connected too. All you have to do is ask it to! Let’s go through it.

Where do you start?

I would start by connecting with the three things your life already runs on:

  • Your email - where your conversations live. Your AI can look up what you’ve actually discussed with someone, so its answers are grounded in your real history. And if you’re not much of an email person? Connect your messaging app instead.

  • Your calendar - where your events live, so your AI knows what’s coming up, how long it takes etc..

  • Your files - so your AI can help you do things. Example if you need to draft a client proposal, it can pull up your last one and your notes, and have a first draft.

Each of the three big AIs has its own name for these connections, which doesn’t help, but it’s really the same idea everywhere:

You’ll be asked to sign in with your Google (or Microsoft) account and approve access, and that’s it.

Once connected, it’s not just reading. In ChatGPT, Gmail can search, summarise and draft replies, and send them from your address once you approve. Claude can draft emails and send, reply to and forward them, asking for your approval first by default. And Gemini reads your Gmail, Calendar and Drive once you switch on the Google Workspace app.

image.png

And don’t worry, connecting your email doesn’t mean your AI will suddenly start firing off emails to all your contacts! By default, these tools ask before taking actions like sending an email, though exactly how depends on the app and the permissions you’ve given it. My advice: keep “ask me first” switched on for anything that sends, books or deletes, at least until you trust it. And yea, you can always disconnect any app at any time.

So what’s this MCP thing?

As you start connecting apps, you might come across the term MCP, short for Model Context Protocol. Think of it a bit like USB-C for AI: a common way to plug different tools and apps into your assistant.

A connection can let your AI search for information or do things in an app, depending on what that connection supports and what you allow. MCP helps standardise those connections, which is why the same app can often plug into ChatGPT, Claude and Gemini. You don’t need to understand what’s happening behind the scenes to use them, just like you don’t need to understand USB-C to plug in your headphones!

So, what about all your other apps I use?

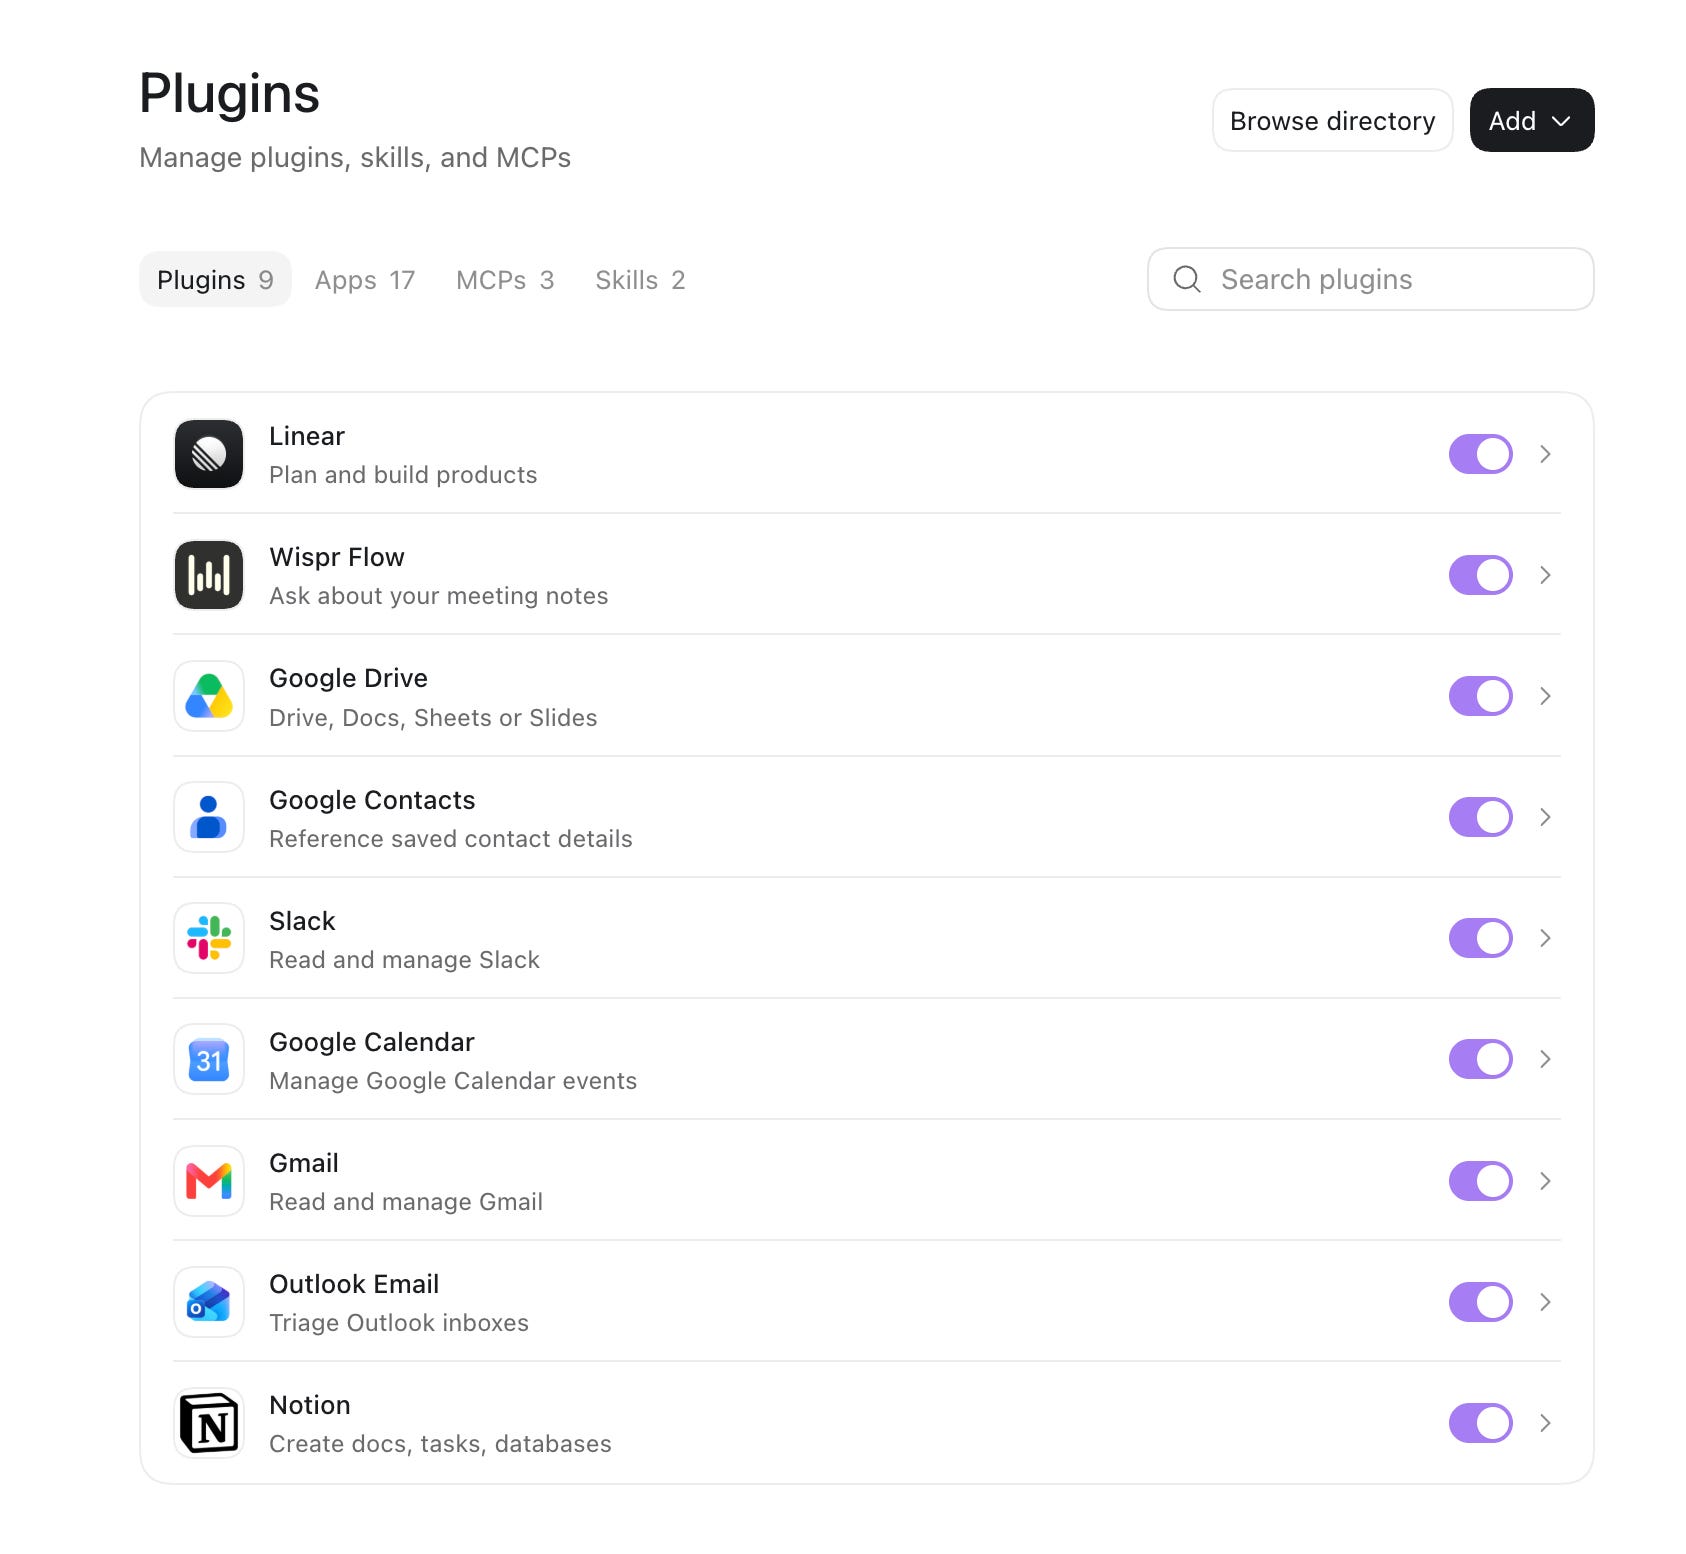
Email and calendar are just the start. Think about all the other apps your life runs on: your notes app, Slack, your to-do list, Spotify, the tool you use at work every day. A growing number of apps now have a connector (most of them built on MCP), and each AI has a directory, a bit like an app store, where you can find the apps you use and connect them:

A few tips before you go connecting everything:

  • Just ask your AI first — rather than going hunting through settings, simply ask ChatGPT or Claude something like “can you connect to my Notion?” Many times it will go and find the right plugin or connector for you and walk you through setting it up.

  • Browse the official directory — think of it like the App Store or the Play Store, but for your AI. Each one has its own, so you can scroll through, see what’s there and connect with a couple of taps. Where you can, connect from there rather than from random links, and if you do add a custom one, make sure you trust who’s behind it.

  • Check what it can do, not just what it can see — some connections only read, others can also create, send or change things. Have a quick look at the permissions when you connect.

What if your app doesn’t have a connector?

Some things will probably never have a connector. Your kid’s school portal, the council page for bin collections, your energy account, the gym booking site... we all have a few of those. This is where computer use comes in, and honestly, it’s one of the things I’m most excited about. With computer use, you can actually rely on your AI to go and do the job for you, rather than just handing you a bunch of text and instructions to follow yourself.

Computer use simply means the AI uses a browser (or your computer) the same way you would. It looks at the screen, clicks, types and moves between pages. So if there’s no plug for an app, you can teach your AI to go and get what it needs itself.

Let me give you an example of why this matters so much. Say you need to fill in a long application form on a website: a visa, a mortgage, a school place, a grant, whatever it is. All the information it asks for already exists somewhere. Your passport details are in a PDF on your drive, your address history is in old emails, your employer’s details are in a contract on OneDrive. So what do you do? You open everything, go hunting through your emails and files, and copy it all across, field by field. An hour later, you’re still on it - and wondering “WHY DOES IT HAVE TO BE THIS HARD!!!” we’ve all been there!

Now imagine your email and your files are already connected to your AI. It can go and search for that information itself. The only missing piece is the form, and that’s exactly what computer use is for. You give your AI the link to the form, it goes through your emails and files, works out what goes where, and fills it in for you. You leave it to do its thing, come back, review every field and press submit yourself.

Connections give your AI the knowledge. Computer use gives it hands.

And once you start looking, these are everywhere: booking a few appointments across different sites, updating your details on a portal that has no app, comparing prices across five shops and putting it all in one place. All the boring, fiddly stuff in between that you’d normally do yourself.

Here’s how each of the three handles it:

A few things to keep in mind when you start using it:

  • Connector first — if an app has a proper connection, that’s usually quicker and more reliable. Computer use is perfect for filling the gaps.

  • You stay in charge of sign-ins — it works with the sites you’re already logged into, so you do the logging in.

  • Start simple — something like checking the school portal for new messages is a great first job, and once you’re comfortable, let it fill in forms for you.

  • Keep your computer on — with Claude, your computer needs to be awake and the desktop app open while it works.

OK, I’m connected. Now what?

The best way to feel the difference is to ask something you could never have asked before. Here are a few prompts to try. They work in all three, though what each can actually pull in depends on what you’ve connected:

Look at my calendar for next week. Which days are overloaded,
and how can I optimize my focus time? 

I have a call with [name] at [time]. What have we talked about
over email recently, and is there anything I still owe them?

Is there anything in my inbox that needs action before Friday?
Keep it to a short list.

To give you a feel for it, here’s how I actually use my own main AI assistant, Chief, which I run on Grok Bot (of course I just asked Chief for the examples rather than remembering myself!). Nothing fancy, it’s just connected to my apps:

  • “Who’s waiting on me?” — it reads my Gmail and Outlook and tells me exactly who’s owed a reply, like an old friend asking whether my plans have changed, or someone needing my confirmation before a filing deadline.

  • “Set up lunch with [a friend] and invite him” — it creates the event, adds his email and sends the invite. While it’s in there, it even spots things like a duplicate hold I can delete.

  • “Any messages I should know about?” — WhatsApp and LinkedIn come into the same picture, and it flags anyone who’s waiting on me - for these ones I use ‘Computer use’ as I couldn’t do it via MCP.

Remember what I said at the start about reactive vs proactive? Notice that all of these are still me asking. That’s already super useful, but it’s reactive. The AI only works when I remember to ask. The really interesting part starts when your AI becomes proactive and starts checking things for you, nudging you before something slips. And for that, you need schedules.

From reactive to proactive: putting your AI on a schedule

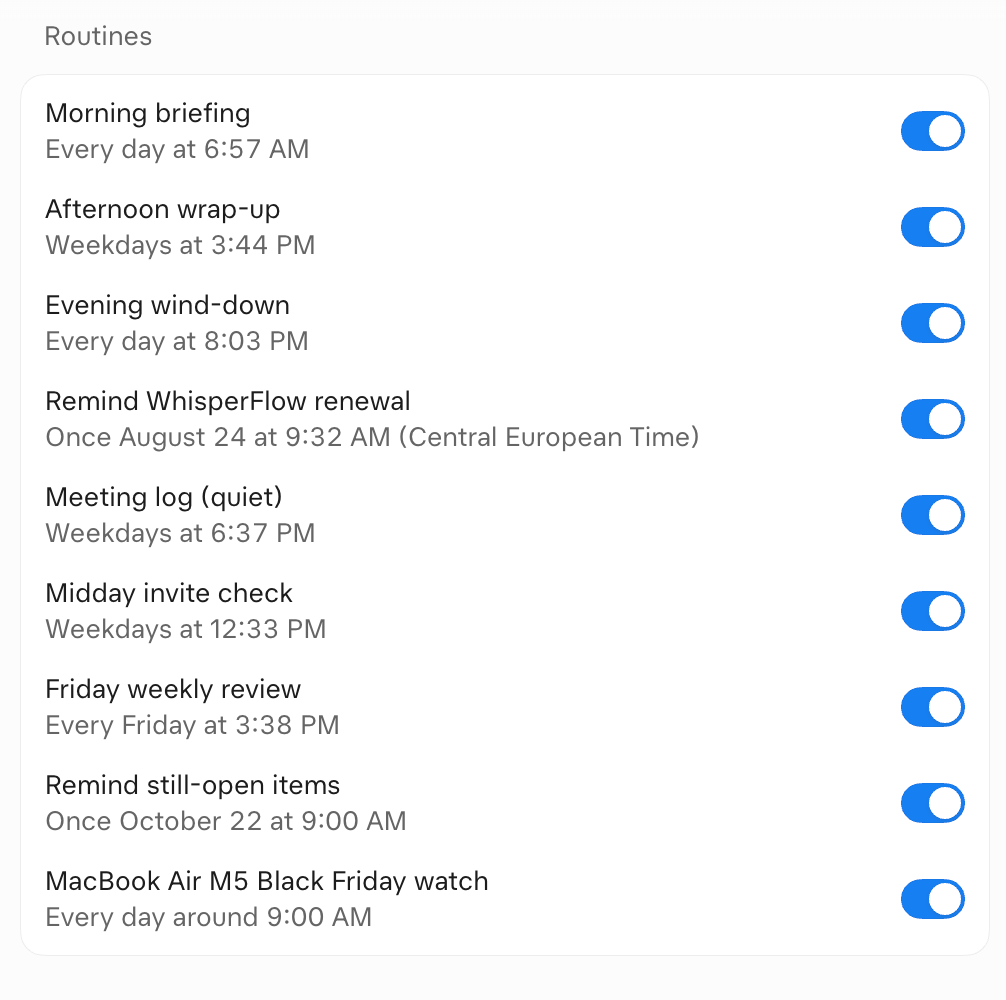
A schedule is simply a prompt that runs on its own, at a time you choose, using all the connections you’ve just set up. Every morning, every couple of hours, every Friday afternoon. Some people call these AI loops, and once you start using them, you’ll see ideas for them everywhere.

For example, Chief tracks my meeting hours against my targets and warns me when I’m getting close to the limit, and it’s keeping an eye out for Black Friday deals on a MacBook Air, only pinging me when the price drops. I never ask for any of that, it just happens.

The good news is that all three support schedules:

How do you set one up?

These days, you just tell your AI. No settings, no forms. For example, this is roughly the one I use to keep my meetings in check:

Every weekday at 7:30am, look at my calendar for the next five
working days. If any day has more than 4 hours of meetings,
suggest which meetings I could shorten or move, and draft a
short note to each organiser. Don't send anything until I say so.

The AI sets up the schedule itself. Every morning I get a short message with its suggestions, and all I have to say is “yeah, do it” or “no, let’s leave it for now”. If you read about Tempo, this is a simpler version of the same idea. The approach works in all three, but what each can connect to and do, and on which plan and in which country, still differs.

If you ever want to tweak a schedule by hand, change the time, pause it or delete it, each one has a place for that:

  • ChatGPT: the Scheduled page in the sidebar.

  • Claude: Scheduled in the sidebar.

  • Gemini: Scheduled in the sidebar on gemini.google.com.

A couple of tips from my own experience:

  • Keep it quiet: tell it to only message you when something actually needs your attention, otherwise you’ll just create another inbox to ignore 😅

  • Ask before acting: let it suggest and draft, and approve anything that gets sent.

  • Start with one: a morning brief of your calendar and anything urgent in your inbox is a great first schedule. Then add another when you notice yourself checking the same thing over and over.

Screenshot from Chief’s schedules

image.png

So, where do you start?

Start small. Today, connect your email and your calendar, and try one of the prompts above. And once that feels natural, set up your first schedule, even if it’s just a short morning brief. You’ll be surprised how different your AI feels once it actually knows what’s going on in your life, and starts looking out for you without being asked.

And this matters more than ever. We’re now seeing a whole wave of always-on bots: Claude has Duet, OpenAI has dots and SpaceXAI has Grok Bot (these are all just weeks or a few months old, so it’s still very early days). They take everything in this article to the next level, but under the hood they run on exactly the same two things, connectors and schedules. Get comfortable with those now and you’ll be ready for whichever one you end up using. And I must admit, I’m completely hooked on mine 😅

In future posts I’ll deep dive into each of my agents: Chief, Vita and Coach Milo. How I set them up, what they’re connected to and which schedules they run, so you can model your own agents the same way I did mine.

Until then, go connect your world and put it to work, you won’t look back!! Trust me!

Special thanks to Claude for helping me research and write this article :)

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Blazor WASM vs Server vs Hybrid: Which Render Mode Should You Use?

1 Share

Blazor gives you four render modes and a Hybrid option, and the names don’t make the choice straightforward. For those familiar with Blazor, the previous split between “Blazor Server” and “Blazor WebAssembly” projects is gone. Since .NET 8, a Blazor Web App is one app that picks a render mode per page, or per component. This post explains each mode, its trade-offs, and when to pick it.

Razor vs Blazor

First, for those new to .NET, a common question I get asked: what’s the difference between Razor and Blazor? (They both end in “azor” so they have to be the same thing, right?)

Razor is the templating syntax, the mix of HTML and C# you write in .razor and .cshtml files. Blazor is the UI framework that takes Razor components and makes them interactive, on the server, in the browser through WebAssembly, or inside a native app. For the syntax itself, I covered what Razor is separately. The rest of this post is about Blazor render modes.

One app, four render modes

The previous model gave you two project types, “Blazor Server” and “Blazor WebAssembly,” and you picked one up front. The latest model gives you a single Blazor Web App, and every component adopts a render mode that decides where it runs and whether it’s interactive.

There are four:

Render mode Where it runs Interactive?
Static Server (static SSR) Server No
Interactive Server Server, over SignalR Yes
Interactive WebAssembly Browser, WASM Yes
Interactive Auto Server first, then browser Yes

You set a render mode with the @rendermode directive. On a page definition:

@page "/dashboard"
@rendermode InteractiveServer
<h1>Dashboard</h1>

Or on a single component instance, so one page can mix modes:

<Weather @rendermode="InteractiveServer" />
<Chart @rendermode="InteractiveWebAssembly" />

The Blazor Web App template adds @using static Microsoft.AspNetCore.Components.Web.RenderMode to _Imports.razor, which is why you can write InteractiveServer instead of the full RenderMode.InteractiveServer.

You enable the interactive modes in Program.cs. This turns on all three:

builder.Services.AddRazorComponents()
.AddInteractiveServerComponents()
.AddInteractiveWebAssemblyComponents();
// ...
app.MapRazorComponents<App>()
.AddInteractiveServerRenderMode()
.AddInteractiveWebAssemblyRenderMode();

Anything using Interactive WebAssembly or Auto must live in a separate client project, the one whose name ends in .Client, so it compiles into the downloadable bundle. The template sets this up when you opt into WebAssembly interactivity.

Prerendering is on by default for the interactive modes, so the server paints the initial HTML either way and the component becomes interactive once its runtime is ready.

Interactive Server

Interactive Server renders the component on the server and keeps a real-time SignalR connection, called a circuit, open to the browser. Each click and keystroke travels to the server, which runs your C#, diffs the UI, and sends back the changes.

What you get:

  • Almost nothing to download, so the app is interactive right away.
  • Direct access to your database, secrets, and internal services, with no API layer in between.
  • The normal server-side debugging experience.

The trade-offs:

  • Every interaction is a network round trip, so latency may be a (negative) factor users on slow connections.
  • The server holds UI state for every active circuit, which costs memory and turns scaling into a capacity question.
  • A dropped connection stalls the UI until it reconnects, and offline doesn’t work.

Pick Interactive Server when your users are close to your server, such as internal line-of-business apps and admin tools, and you want the shortest path to running C# end to end.

Interactive WebAssembly

Interactive WebAssembly runs the component in the browser. The .NET runtime and your app bundle download once, get cached, and after that your C# runs client-side with no server round trip for UI events.

What you get:

  • Instant interactions after load, because they run locally.
  • Offline support, PWA packaging, and static hosting on a CDN.
  • Less server load, since the client does the work.

The trade-offs:

  • The first visit pays for the runtime download and a cold start, so initial load is slower.
  • You’re bound by the client’s resources.
  • Nothing in the browser is secret. Keep connection strings, API keys, and privileged logic out of client code and behind an API, the same as a JavaScript SPA.

If you run into problems, my notes on debugging Blazor WASM may help.

Pick WebAssembly when you need offline support, want to cut server cost, or are building something CDN-friendly and app-like.

Interactive Auto

Auto combines the other two. On the first visit, the component renders with Interactive Server, so the user gets interactivity immediately. The WebAssembly runtime and bundle download in the background and cache. On the next visit, the component runs client-side.

@page "/counter"
@rendermode InteractiveAuto
<button @onclick="() => count++">Clicked @count times</button>
@code {
private int count;
}

You get a fast first load and, over time, the responsiveness and server offload of WebAssembly. Two things to know. Auto decides per component when that component first loads, and it keeps that choice while the component stays on the page, so it won’t switch modes mid-session. And because the same component can run on the server or the client, your code has to work in both places, which rules out server-only dependencies.

Auto is a good default for general-purpose apps that want a fast first load without giving up WebAssembly later.

Static SSR

Not everything needs to be interactive. As a long-time static site lover (this blog for example), I prefer this option.

Static Server rendering emits HTML with no circuit, no WASM, and no event handling. It’s the default when a component doesn’t set a mode, and it fits content-first pages: marketing pages, blog posts, docs, anything a search engine should read. You can still drop an interactive island into a static page by giving one child component a @rendermode, or add client-side behavior to static output with a library like htmx. Where plain HTML works, it’s faster and cheaper than interactivity.

Coming in .NET 11, static SSR handles more than it used to. Forms get instant in-browser validation without a server round trip or a WebAssembly download, enabled by default for any static SSR form with a DataAnnotationsValidator. QuickGrid also gains URL-based paging and sorting through query strings, so a data grid no longer forces an interactive render mode. Both close common gaps that used to push people toward Interactive Server or WebAssembly. If you handle form posts directly, I covered plain HTML forms and antiforgery in Blazor SSR separately.

Blazor Hybrid

Everything above assumes a browser. Blazor Hybrid doesn’t. Here your Razor components run inside a native app, a .NET MAUI app on Windows, macOS, iOS, or Android, rendered by a BlazorWebView control. There’s no WebAssembly and no SignalR circuit. The components execute directly in the app’s .NET process with full access to native device features and the local filesystem.

Hybrid reuses your Blazor components and C# to ship a native application instead of a web one. If you’re building an installable desktop or mobile app, Hybrid fits. If it lives at a URL, use one of the web render modes.

Picking a mode

Your situation Reach for
Content-first, SEO-driven pages Static SSR
Internal app, users near the server, direct data access Interactive Server
Offline support, PWA, CDN hosting, low server cost Interactive WebAssembly
Fast first load and client-side speed Interactive Auto
Installable desktop or mobile app built with web skills Blazor Hybrid

In a Blazor Web App these aren’t exclusive. One app can serve a static marketing page, an Interactive Server admin panel, and an Auto-rendered dashboard. You choose per page or per component, and you can change your mind later by editing a directive instead of rebuilding the project.

Thanks for reading and sharing my posts with friends and colleagues. Cheers.


Written by Khalid Abuhakmeh. If this guide helped your workflow, feel free to buy me a coffee.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Central Agentic Ops (CAO)

1 Share
Monitor and govern agentic workflows across repositories
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories