Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164029 stories
·
33 followers

232: The Hidden Cost of Being a High Achiever

1 Share

The Mentorship Maximizer Matrix: How to Score Every Mentor on Fit and Commitment, and the Move to Make Next

Lisa landed a conversation with a VP four levels above her.

She came back celebrating. I asked, “What’s your follow-up plan?”

Silence.

She was about to let the best career opening she’d had in years end as a great chat. And she’s not alone. Plenty of engineering leaders have a mentor. Far fewer are actually getting mentored. They meet for coffee once a quarter, and nothing changes.

It’s not your mentor’s fault. Mentorship is mentee-led, and the difference is what you do next.

Most engineers treat a mentor the way a free solo climber treats the guy at the base of the wall. Ask for a few tips, say thanks, then turn around and climb alone. Great mentorship is climbing with a partner who knows the route and brings the rope.

In this episode I walk through the three monster mistakes mentees make, then draw the Mentorship Maximizer Matrix: score every mentor on fit and commitment, find which of four boxes they’re in, and make that box’s move. That’s how Lisa went from a hallway conversation to a VP mentor, and how a mentor named Josh became the sponsor behind one of my biggest promotions.

Your mentor can hand you the rope. Only you can clip in.

The Happy Engineer Podcast

LISTEN NOW

Back to ALL EPISODES


What You’ll Learn


The Three Monster Mistakes Mentees Make

You don’t have world-class mentors, either none at all or one HR assigned you who’s following someone else’s formula. You don’t meet, or you meet once a year over coffee instead of at the gemba, where your mentor can see the real work. And you don’t ask for what you actually want, so you end up treating your mentor like a curated version of Google.


You’re Not Alex Honnold

Free soloing El Capitan is one of the greatest athletic feats of all time, and it’s how most engineers run their careers: a few climbing tips at the base of the wall, then up the rock face alone. There’s one Alex Honnold. The rest of us climb further, waste less energy and survive the slips when we’re roped to a partner who knows the route.


The Mentorship Maximizer Matrix: Fit × Commit

Fit is whether a mentor has the results, skills and experience you want, and shares your values. Judge it against your vision, not their job title. Commit is how much they’re actually investing in you right now. Once-a-year coffee is low commit, however senior they are.


Four Boxes, Four Moves

Bad fit, low commit: move on. Thank them and close it out, the way I opted out of an HR-matched mentorship early in my career. Bad fit, high commit: dig for gold. When my mentor Steve ran out of promotion advice, we switched to what Steve was a guru at: personal investing. Perfect fit, low commit: ask for more. That’s where Lisa was, and one courageous ask changed it. And if your mentor says they only meet quarterly, respect the boundary and invite them to more anyway. Let them say no. Don’t say no on their behalf. Perfect fit, high commit: make them proud. The most generous thing you can give a mentor is applied advice, and a report back on what it did.


How a Mentor Becomes a Sponsor

Josh and I worked together for years. I kept asking for more, kept digging for gold, and kept making him proud. When a Whirlpool reorg created a key moment, Josh became the sponsor who helped me land a huge promotion at a young age. The top-right box is where you want every mentor’s name to end up, because it’s where sponsors come from.


Your Move This Week

Take the names of your mentors, not theoretical ones, and plot each one on the matrix. Then make the move for each box this week. If your matrix is empty, it’s time to go fishing, and the Life Raft episode is the place to start.

About Zach White

Zach White is the founder of Oasis of Courage and the host of The Happy Engineer podcast, now in its second season with more than 200 episodes published.

He holds mechanical engineering degrees from Purdue and the University of Michigan and spent his corporate career as an engineering leader at Whirlpool before leaving in 2019 to coach full time. Since then he has coached more than 300 engineering leaders at over 200 companies — big tech to rust belt, and everything in between.

His flagship program, the Lifestyle Engineering Blueprint™, is a 12-week coaching program that helps engineering managers and directors get promoted without handing over their nights and weekends to do it. He also runs an invite-only Mastermind for Blueprint graduates and hosts OACO Live.

He built all of it around one belief: you shouldn’t have to sacrifice your life to reach your potential at work.


Links & Resources

Free download — The Mentorship Ask Scripts
Know your move but not what to say? The exact words for every ask, from the first message to a stranger to asking a mentor to become your sponsor. → https://toolkit.oasisofcourage.com/mentorship-scripts

Work with Zach
A 15-minute conversation about where you’re stuck and what to fix first. Book a free Career Growth Audit → https://calendly.com/oaco-client-success-team/career-clarity-call

Watch next

  • Ep 175: all three monster mistakes, unpacked in depth → [EP 175 PAGE URL]
  • Ep 229: Forget Networking. Build Your Career Crew. Empty matrix? Start by filling your life raft → https://oasisofcourage.com/crew

Connect
Follow Zach White on LinkedIn → https://www.linkedin.com/in/thezachwhite/

FULL EPISODE TRANSCRIPT:

Please note the full transcript is 90-95% accuracy. Reference the podcast audio to confirm exact quotations.

Having a mentor doesn’t mean you’re actually getting mentored. I’ve coached over 300 engineering leaders, and I’ve seen one courageous ask turn a conference handshake into a director opportunity.

I’ve also seen leaders meet their mentors for coffee year after year after year without moving forward. And the difference? It’s what the mentee There’s 3 monster mistakes that can keep you on the wrong side of that equation.

Let’s see if you’re making one and then get clear on the action that you need to take to maximize the value of mentorship for your engineering career.

Expand to Read Full Transcript

And by the way, if you’ve been meeting with your mentor for months, maybe even years, and you’re still having those same career conversations, something needs to change. And sometimes the hardest part is just knowing how to ask for what you need, what to say when asking a new leader to be your mentor. That’s why I’ve created a free set of mentorship scripts. These are for engineers who want to be intentional about career growth and just feel stuck on knowing what to say. You’ll have the language that you can adapt to approach the right person and explain the kind of guidance that you need and that you’re looking for. Grab those scripts for free in the description, in the show notes right now, and let’s get cracking on these 3 monster mistakes. The first mistake is the most obvious one. And unfortunately, out of the 300+ leaders who I’ve coached from IC to VP across the board, it’s the most common. It’s that you don’t have world-class mentors. You just don’t have them. And there’s 2 sides to this mistake. One is having no mentors, period. The second is that they’re really not world-class. You have someone who was assigned to you by HR, perhaps you joined one of the corporate matching mentorship programs. And frankly, that person is not supporting the success that you desire. They’re not actively creating new results for you because they’re just following the formula that was laid out by someone else. And yes, they’re generous and they want to give back, they do. Uh, have a desire to see you succeed, but they may not be the actual person who you need in your corner. So whether it’s you have zero people in your life raft as a mentor supporting you, or the people who you have frankly are just riding along in that boat instead of actively rowing in support of your success, if you do not have a tribe of world-class mentors in your corner, that is a monster Mistake for you as an engineering leader, no matter what level you are at. If you’re a junior individual contributor all the way to director and VP, we all need those mentors. Mistake number 2 is that you have the mentor and you don’t actually meet. This is amazing how often I’ll say, hey, do you have a mentor? And the engineer will say back to me, yes, I do. And I’ll say, well, how often do you connect? And it’ll be twice a year, maybe once a quarter, or, oh, I don’t remember the last time that I met with my mentor. It’s like, well, that’s, that’s not a mentor. Once a year doesn’t move the needle. All right. Yes, it’s good to stay in touch with past mentors who may be able to come back and support you in a key moment, but you need cadence. All right, you need cadence and you need an environment when you meet that allows the right conversation to happen. What cadence is right will depend on what you’re seeking to accomplish. And in just a moment, I’ll share with you the importance of how those things fit together. But on the environment piece, I think it’s a huge mistake that most mentorship meetings are coffee chats or going out to lunch. Sometimes the most valuable thing you can do is bring your mentor into your work environment. Go to the Gemba, go look at the work itself and get their insights, their coaching, their mentorship, their advice right there in the thing that matters most. Mistake 1 is you don’t have the mentors. Mistake 2 is you don’t meet with the mentors you have in the right cadence and in the right way. And mistake 3? You’re there with a great world-class mentor. You’re meeting in the right environment, but you don’t have the courage to ask for what you really want. Mistake 3, you don’t ask for what you want and what you need. This is another monster mistake that mentees make all the time. You get this close to something that could have radically shifted the trajectory of your career, And you didn’t have the courage to ask for it. Or worse, you don’t know what you need to ask for in the first place. Huge, huge miss, huge bummer. It’s almost like people treat their mentors like a curated version of Google. They just ask questions and get information back, and they settle for this transactional relationship with a mentor to get information from them. That frankly you could have gotten 90% of from ChatGPT or Claude, and you’re not digging into the right topics in the right way, and you’re not asking for the support that you really need. 3 monster mistakes. You don’t have world-class mentors. You don’t meet with your world-class mentors in the right cadence and in the right way. And you don’t ask your mentors for what you really need. Want and need. I’m curious, which of those 3 best describes you? Is it 1, 2, 3, or all of the above? What is the challenge that you’ve faced with mentors in your career? And if you wanna go deeper on this, I’ve got an entire podcast episode where I take 20 minutes and unpack these 3 really deeply. If you feel stuck and trapped on these, if you’re in the audio podcast, it’s episode 175, and here on YouTube, Uh, we’ll get that linked up in the description if you want to watch that next and go deeper, but we need to make sure we’re not making these mistakes so we can move on to actually maximizing the mentors that we have. So let me show you the Mentorship Maximizer Matrix. This is a really simple and powerful tool for how you can take the mentors in your life and turn them into leaders who are supporting your success. But I need to remind you first, You’re not Alex Honnold. If you don’t know who Alex Honnold is, he’s a free solo rock climber, and he did an incredible special by that name, Free Solo, showing how he climbed El Capitan with no rope. It is absolutely ridiculous. I would encourage you to go check that out. It’s one of the greatest athletic feats of all time, and it’s the way most engineers want to run Their career. They think that they’re Alex. They meet a mentor at the base of the wall and they ask their mentor for some climbing tips. And they say, hey, how did you do that section up there when you climbed this really hard mountain? And then they say thank you to their mentor and they turn around and they walk to the wall and they free solo the rock face. That’s the way that engineering leaders, whether you’re a manager, director, I see it all the time. They go to their mentor to ask for climbing advice, and then they go climb on their own. Great mentorship is not like that. Great mentorship is climbing with an experienced partner who knows the route, knows where to place the anchors, and can hand you the rope to clip into. Okay? You’re gonna climb further. It’s gonna take less energy. It’s way safer. So when you slip, you don’t fall to the bottom because the truth is you’re not Alex Honnold. You’re not the one in a million engineer. You’re not that person. Maybe you think you are, and if you are, awesome. But the truth is there’s one Alex Honnold and there’s all the rest of us, and there’s no point climbing that face alone in your career. So let’s get into the mentorship. Maximizer matrix. There are 2 dimensions, and I want you to grab your notebook and draw along because you need to be marking where your current mentors are at on this matrix. The first dimension, let’s talk about this x-axis. It’s fit. It is fit. You can have a mentor who is frankly a bad fit. You and that person don’t get along. You and that person are not Really able to support each other. They cannot help you with the things that you want. And on the other end would be someone who’s a perfect fit. That’s the ideal. That’s what we want. This leader has the results that you want to accomplish. Remember, that’s the key distinction of a world-class mentor is that they have actually achieved the results that you want. So bad fit to perfect fit is really obvious in finding a great mentor. But the vertical axis on this matrix is their level of commitment to you. If you have a mentor who is low commit, that’s a problem. They’re not investing into you. And on the other end is somebody who is highly committed to your success. Highly committed. This is the problem with a lot of mentorship relationships is that you’ve got somebody who could help you a lot, but they’re not committed to helping you. And as a mentee, we just sit back and say, well, there’s nothing I can do about that because they’re the mentor and I’m the mentee. What am I supposed to do, Zach? Well, that is not true. That is not true at all. Let’s talk about what action you need to take based on where your current mentors map into this Matrix. First one, let’s talk about low commit, bad fit. It’s pretty obvious if you’re in this quadrant, if the name of your mentor lands in this quadrant, that you’ve got a problem. All right. This person is really not able to support your success, and they’re really not that invested into your success anyway. So why would we continue to use our time and energy here? The answer is simple. The action to take is move on. Move on. Have the courage to tell that mentor, thank you for the support that you’ve given me. It has been extremely helpful. I appreciate you. And I think our mentorship relationship has run its course. For me, I had this experience early in my career when I joined one of those HR mentor matching programs. I filled out a few questions. Let’s be honest, it was not Match.com. I don’t know how they were pairing people up, but somehow I ended up getting matched with a mentor who will remain nameless for the sake of protecting their reputation here. And at the end of the day, I felt there was very little this person had to offer me. Their career path had been very different than the direction I wanted to go. They did not have tremendous success or results to speak of in their own career. And the other people I was asking were like, hey, Probably wouldn’t spend too much time around that person. That’s not someone you want to hitch your wagon to. So I went through the minimum required sessions as part of that HR program, and when it came time to either continue or opt out, I said thank you and opted out. If you’re in a similar situation, just have the courage to say no, to let them know that that’s the end of the relationship, and move on. Now the next two. Quadrants are a bit trickier because you’re halfway to what you want. You may have a mentor who’s really committed. They’re willing to invest in you, but they’re not a great fit. The conversations, maybe they’re not clicking. You just don’t vibe with that person. Maybe the results that they’ve had in their career are not aligned with the direction that you want to go. So it’s not really that great. Maybe you’re on the deep technical side and they’re more on the product side and it’s not working, or the opposite. You want to move more towards the commercial and business end of the engineering career ladder, and they’re more interested in keeping you in deep technical work. Whatever the reason is, it’s a bad fit. Or the opposite, you may have someone who’s a perfect fit, but man, you just can’t get their time. You can’t get their focus and their energy. That person is unavailable, or at least so far has not been open to committing to you. When you’re in one of these 2 quadrants, it can be tough to know what to do because you don’t want to let that relationship go. Let’s start with the high commit, bad fit. I think this one is actually the more common situation that I see. When you’re in this quadrant, the action that you need to take is to dig for gold. Dig for gold. What I mean is to explore other ways that this committed mentor can help you. I remember a mentor named Steve who supported me at Whirlpool Corporation, and after I’d gotten a couple of promotions, Steve didn’t have much more to offer me around the idea of career development. We were actually peers on the org chart by this time, so asking him for continued advice on how to get promoted to a level he’d never reached didn’t make sense, but— Steve was committed. He really enjoyed and supported me in a great way. So I started digging for gold. What else is Steve great at? And it turns out he was a guru when it came to personal investing, understanding Whirlpool’s 401 plan, you know, personal investing and just financial strategies and financial intelligence in general. So we shifted our mentorship away from getting promoted and into me learning from him about investing strategies. If you have somebody with great experience who you connect with in some ways, but it’s just not quite a fit for your goals and what you want right now, go dig for gold. Maybe that person can help you in another way. What about low-commit, perfect fit? This is that VP, this is that director, this is that person at another company who’s a thought leader. You’ve seen them on LinkedIn. Who oh, they’re they’re the perfect person. They’re the person who you want to be when you grow up. They’re the person who has all the success, all the reputation that you want to emulate. It’s a perfect fit. But even getting in the same room as that person can be tough. Maybe they don’t even know your name yet. Well, here’s what needs to happen: the action for you to take when you’re here. It’s one of. Courage. You must have the courage to ask for more. Remember the leader I mentioned, Lisa, from the intro of this conversation today? She was invited to go along and represent a project that she was working on at a major engineering conference. The VP of product was also at the conference. This was a female engineering leader who’d made it to the vice president level, and Lisa really wanted that opportunity to have a conversation with the VP, and she got it at that conference. And Lisa was in my coaching program and she came back and was celebrating the win. She said, ha, you’re not gonna believe this. I got to go to the event and While I was there, got to have a conversation with the vice president and was celebrating that win. And so I asked as her coach, I said, amazing, what’s your follow-up plan? A few seconds of silence, no response. Lisa hadn’t even considered the possibility that a follow-up might be available, right? This was totally out of her league. This is a person who was at the time, I think, 4 levels above her. in the org chart, right? There’s no way this VP would want to mentor Lisa, right? Well, how do we know if we don’t have the courage to ask? So I said to Lisa, hey, do you want this person to be your mentor if you could? And Lisa was like, of course. I mean, that would be amazing. This is a perfect fit. This person’s career path is almost exactly the path that I would love to follow. I said, okay, it’s time to make that courageous Ask. Now’s the perfect time. You have the relationship, you just met face-to-face and had this conversation. Go ask for more. Lisa did. The VP was ecstatic to serve as her mentor, and now Lisa is in line for a director opportunity. The same could happen for you if you have the courage to do it. Dig for gold. Ask for more. If you’re currently in one of these 2 quadrants, that is your objective to push you into the place that we all want to be, the top right, where you have that perfect fit and a high commit. So what do you do in that situation? So let’s jump back out to our matrix. And by the way, if you’re thinking, I have the courage to make that ask, I just don’t know what to say, remember to grab the scripts. That are totally free there in the show description. So you can get past that hurdle of knowing what to say and just get on with the actions. But when you’re in this 4th and best quadrant, perfect fit, high commit, you’ve got a leader with results that you can aspire to and emulate and who’s helping you and actively supporting you. You have that cadence of meeting, everything’s going great. Well, what do you do now? It’s like I hit the, I hit the jackpot. I’ll tell you exactly what to do. The most generous thing that you can give a mentor is applied advice. Do what they say and make those mentors proud. Make them proud. Make that mentor proud that they invest in you. Give them the feedback. Hey, I just want to say thank you for what you’ve been supporting me on. I took the actions that you suggested. I’ve gotten these tremendous results. Things are going well for me. Things are looking up for me. And I just want to let you know how much I appreciate what you’re investing into me. And I’m going to continue to take action, to challenge myself, to grow. And I just want to let you know how much that means. Wow. That’s what you want to do. When you think about what can I generously give back To my mentors when they’re giving of themselves into me. This is what it is. Give them the pleasure of knowing that their investment into you was not in vain, that it was not a waste. Go make them proud. And I’ll tell you the other reason this is super important is because this upper corner right here of the matrix, that’s the place you want every one of your mentors’ names to end up. So that you can ask them to be your sponsor in those moments that really matter. And I’ll do a whole separate conversation, separate episode talking about sponsorship later. But for today, just know that our goal is to move our mentors up into this top right quadrant where we can make them proud. And you want every single name of your mentors to land in that box. Now, If you haven’t already, take your list of mentors and let’s plot them on this chart. If you have somebody whose name is down here in the bottom left, have them, you know, say thank you and move on. Let them go. Cut them loose. If it’s a bad fit, low commit, let’s move on. If your mentors’ names are up here where they’re really committed, but it’s a bad fit, it’s time for you to take a new action in how you engage. To go dig for gold. If it’s in the ask for more bucket, go get the scripts, get clear, get courageous, and make that ask. Don’t just settle for whatever they gave you as their way of doing mentorship. I’ve heard this a lot. Yeah, but Zach, my mentor said they’re only available to meet quarterly. I get it. We’re going to be very respectful of that boundary For them. And we’re also going to ask them and invite them to something more. Let them say no. Don’t say no on their behalf. And if you have mentors in this make ’em proud box, then let’s push it all the way as far as we can so that you have a list of mentors who, even after the mentorship is over, you can go back to and pick up the conversation and asking for advocacy. And sponsorship in those moments that matter. This is how you maximize mentorship. If you activate this, I promise you, you’re gonna be ahead of 99% of other leaders out there who don’t have mentors, don’t meet with their mentors, and don’t ask for what they want and need. And I can tell you from my own experience that this works. I had a mentor named Josh. Josh and I were together for years. I kept asking him for more and more insights. I kept digging for gold if it ever felt like we were running out of things to explore. No matter what stage I was at in my career, Josh continued to invest in me. He was giving me time. He was up there in that top right, and I kept doing everything possible to make him proud. And when a key moment came that Whirlpool went through a reorg, Josh became that sponsor for me who helped me to land my first senior manager of engineering role. When who knows what would’ve happened otherwise. You see, investing in that relationship and asking for the things that I wanted and needed, making sure that Josh knew the direction I wanted to steer my career led to a huge promotion, a huge pay raise, and a huge opportunity for me at a really young age in my engineering career. This works. Mentors matter. And please remember, you are not Alex Honnold. Go and build that tribe of mentors for you. And notice, when you look at this diagram, every kind of mentor relationship you have sits in one of these 4 boxes, and every box has a next move. None of those moves is sit back and wait. Get proactive, go take action, and create the mentorship that you need. So let’s do a rapid recap. There’s 3 monster mistakes mentees make, and I don’t want you to make them. Number 1 is you don’t have world-class mentors. Number 2 is that you don’t meet with them on a regular cadence or in the right way to create momentum. And number 3 is that at the end of the day, you just don’t ask for the things that you actually want and need to get to where you want to go. And then you can take the names you have and put them onto the Mentorship Maximizer Matrix. Be honest with yourself. Score those mentors by name. This is not conceptual. This is with names, not with theoreticals, not with nice-to-haves. Take the names of your mentors, score them on fit. Is it a bad fit or is it a great fit, a perfect fit? Do they have the results, the skills, the experiences that you want? Can they impart that? And do they share your values? Is it fun to meet with them? All right, use your vision and values as the basis for fit, not their job title. And then score on the commitment. How much time and energy are they actually investing into you? Be honest with yourself. And remember, please, once a year coffee is not high commitment. That is a low commit. So you’re going to score each of the names on this Mentorship Maximizer Matrix. And your job is to make the quadrant move that’s listed here this week. Is it time to move on? Time to dig for gold? Ask for more or make them proud. Take that action now. Put the action in place. And look, if you have no names, if you’ve got an empty matrix, then it’s time to go fishing. It’s time to start building that tribe of mentors. All right. And if that’s you, go back and check out my episode on the life raft because you need to stop thinking you’re Alex Honnold and start Filling your life raft with the people who can support you. Now, my guess is if you’ve listened this far, you’re aware that a story like Lisa’s or a story like mine with Josh, yes, the mentorship is a critical factor to helping us create those inflection points and the success, but there’s more to the story. There’s an entire set of systems and strategies required for you to create rapid momentum in your engineering career to get that next promotion. It’s not just about mentorship. Your success requires a whole host of strategies, systems, and tools. And if you want to see that complete picture, if you want to see all of what it takes, then I’d encourage you next to go check out my Director Promotion Plan. It’s the fastest way that I know to help you achieve that next promotion that you’re looking for in a way that’s aligned with your vision, your values, your purpose. Whether you want to make it to director and beyond, or you’re still a senior engineer looking for that first manager role, the Director Promotion Plan is going to walk you through all of the strategies, the systems, the barriers, the things that I’ve seen that hold people back from getting to that next level. Go check that out. It’s absolutely free, and it’s the most comprehensive look at the way that we approach coaching here within the Oasis of Courage. So check out the Director Promotion Plan if you want to see how mentorship fits into the complete picture of your career success. And until next time, don’t forget, get out there and crush comfort, create courage, and let’s do this.


Back to ALL EPISODES

The post 232: The Hidden Cost of Being a High Achiever appeared first on OACO.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Issue 774

1 Share

Comment

I don’t normally enjoy throwing shade on other dev communities, but it’s hard not to be a little bit smug around our Android friends these days. Foldable phones have been around for 8+ years, but it took iPhone Duo, and more importantly, the Apple Developer Community, to fully open the floodgates of creativity and get the general public excited about the new experiences that foldable devices enable.

I check aggregators like beardfm.app and foldhunt.com daily, and new Duo-inspired apps just keep popping up. Granted, not all of them are great. In fact, a lot of these apps rely heavily on the hinge gimmick and arguably don’t offer much long-term value to users. But that doesn’t concern me that much. We’ve been living in bleak vibecodetown for a while now, and it’s in those gimmicks and that whimsy that I still find a spark of humanity. So keep them coming!

Speaking of gimmicks, the new MacBook Pro with a touch screen was announced on Wednesday. And I feel…a bit conflicted about it. The hero image on apple.com, with a person playing the piano on the MacBook’s screen, is outright ridiculous. But I can certainly get behind the use case of interacting with the simulator using touch input. This can be especially helpful when testing document-based apps with multi-touch workflows. And the PROLED XDR Display specs do look impressive. I really want to see it in person!

Just don’t expect me to play the piano on it 🤏

– Alex Ozun

Your coding agents need a Mac too

Claude Code can write Swift all day, but without Xcode it can’t prove the build actually passes. That’s why more teams are moving agents into a cloud development environment on Mac with Apple silicon, running the same stacks and caches as CI. This on-demand session covers how Remote Dev Environments work as shared infrastructure for developers and AI agents, where MCP fits in, and why fast builds matter even more when agents are the ones waiting on feedback. Watch it on demand.

News

Apple unveils MacBook Pro with PROLED XDR Display and Touch on Mac

As I already mentioned in the commentary section, Apple just announced its first MacBook with Touch. Conveniently, the announcement is accompanied by 3 new Tech Talks. I think these talks will be interesting both to developers who maintain macOS apps and want to adapt them for touch input, and to those who are looking at the new Macs as consumers and want to better understand the new touch-enabled affordances they offer: Design for touch on Mac, Bring Touch to your Mac app, Bring Live Activities to Mac


Apple forced to change app store rules in a win for roughly 15 million Australian users

Federal Court of Australia has ordered Apple to open up its devices to other app stores as it ruled that the restriction was anti-competitive.

Our Aussie editor Andyy Hope shares his thoughts: ‘Personally, I don’t think this is going to be that big of a deal in the day-to-day life of Australians, nor do I think that “Aussie App Store™” will ever take off. But I’m always open for more free market ideas.’

Design

Design the interface for functionality not familiarity

Jeff Johnson shares his thoughts on the design philosophy (or lack thereof) behind the new touch-enabled Macs. I concur with his point that touchscreens on Macs have more in common with the frustrating touch interfaces in cars than the well-motivated ones on phones and tablets.


Pocket Casts on iPhone Duo

Alex Grebenyuk, whom many readers will know as the developer behind the popular Nuke library, shares his experience adapting Pocket Casts for iPhone Duo. I really appreciate the generous number of screenshots that demonstrate the multitude of design decisions that went into the adaption process. And the Harder Than It Looks sections contains an important insight: ‘Duo also exposed a bigger gap: parts of the app needed more love on a big screen […] That will take more than one release’.

I think all the recent Day One support announcements have made us somewhat desensitised to the fact that adapting our apps isn’t always feasible in a single one-shot release.

Code

Closing Up: Why I’m making some of my projects closed-source

When Daniel Saidi writes about open-source vs closed-source development, both areas in which he’s found success, I pay attention. In this article he shares what motivated him to archive his popular open-source OnboardingKit library, and create a separate closed-source version with a commercial license. To nobody’s surprise, the decision was largely driven by the impact AI is having on open-source development. I respect Daniel’s decision, and recommend giving the article a read to get the full picture.

Business and Marketing

Don’t Launch to an Empty Room

Many developers are working on new apps right now, perhaps looking to ride the Duo hype wave, and will soon face the challenge of catching their audience’s attention. Jordan Morgan offers timely tips on how to launch your apps in an environment where everyone and their mother is shipping apps and competing for attention.

Tools

Feedler | The Smart RSS Reader

As you can probably imagine, I’m subscribed to tons of RSS feeds. Despite being a long-time user of NetNewsWire, I’m always on the lookout for interesting new RSS readers. This Feedler launch announcement caught my eye. As far as I can tell, it was developed largely in ‘stealth’ mode, so I was pleasantly surprised by how polished it is at launch. Kudos to the developer!

And finally...

Ok, can we please be serious and stop cracking jokes? 😅

Read the whole story
alvinashcraft
17 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

AI-Native Observability Patterns and Anti-Patterns

1 Share
AI-native observability requires teams to make both production systems and AI-driven workflows explainable through connected, verifiable telemetry. This Refcard explores patterns for preserving trace context, standardizing telemetry with OpenTelemetry, grounding AI-assisted investigations in evidence, and instrumenting agentic workflows end to end. You’ll also learn how common anti-patterns — including aggressive sampling, semantic noise, unsupported AI summaries, and unobservable agent execution — can weaken incident analysis and make automated findings harder to trust.
Read the whole story
alvinashcraft
37 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

I Turned Off CI for Pull Requests. Here's Why

1 Share

You can turn off cloud CI for pull requests and still block merges on a green check. Run the build and tests locally, post a signoff commit status with Basecamp's gh-signoff extension, and make GitHub require that status to merge. My repo has merged 833 pull requests this way since June, with cloud CI running only on main.

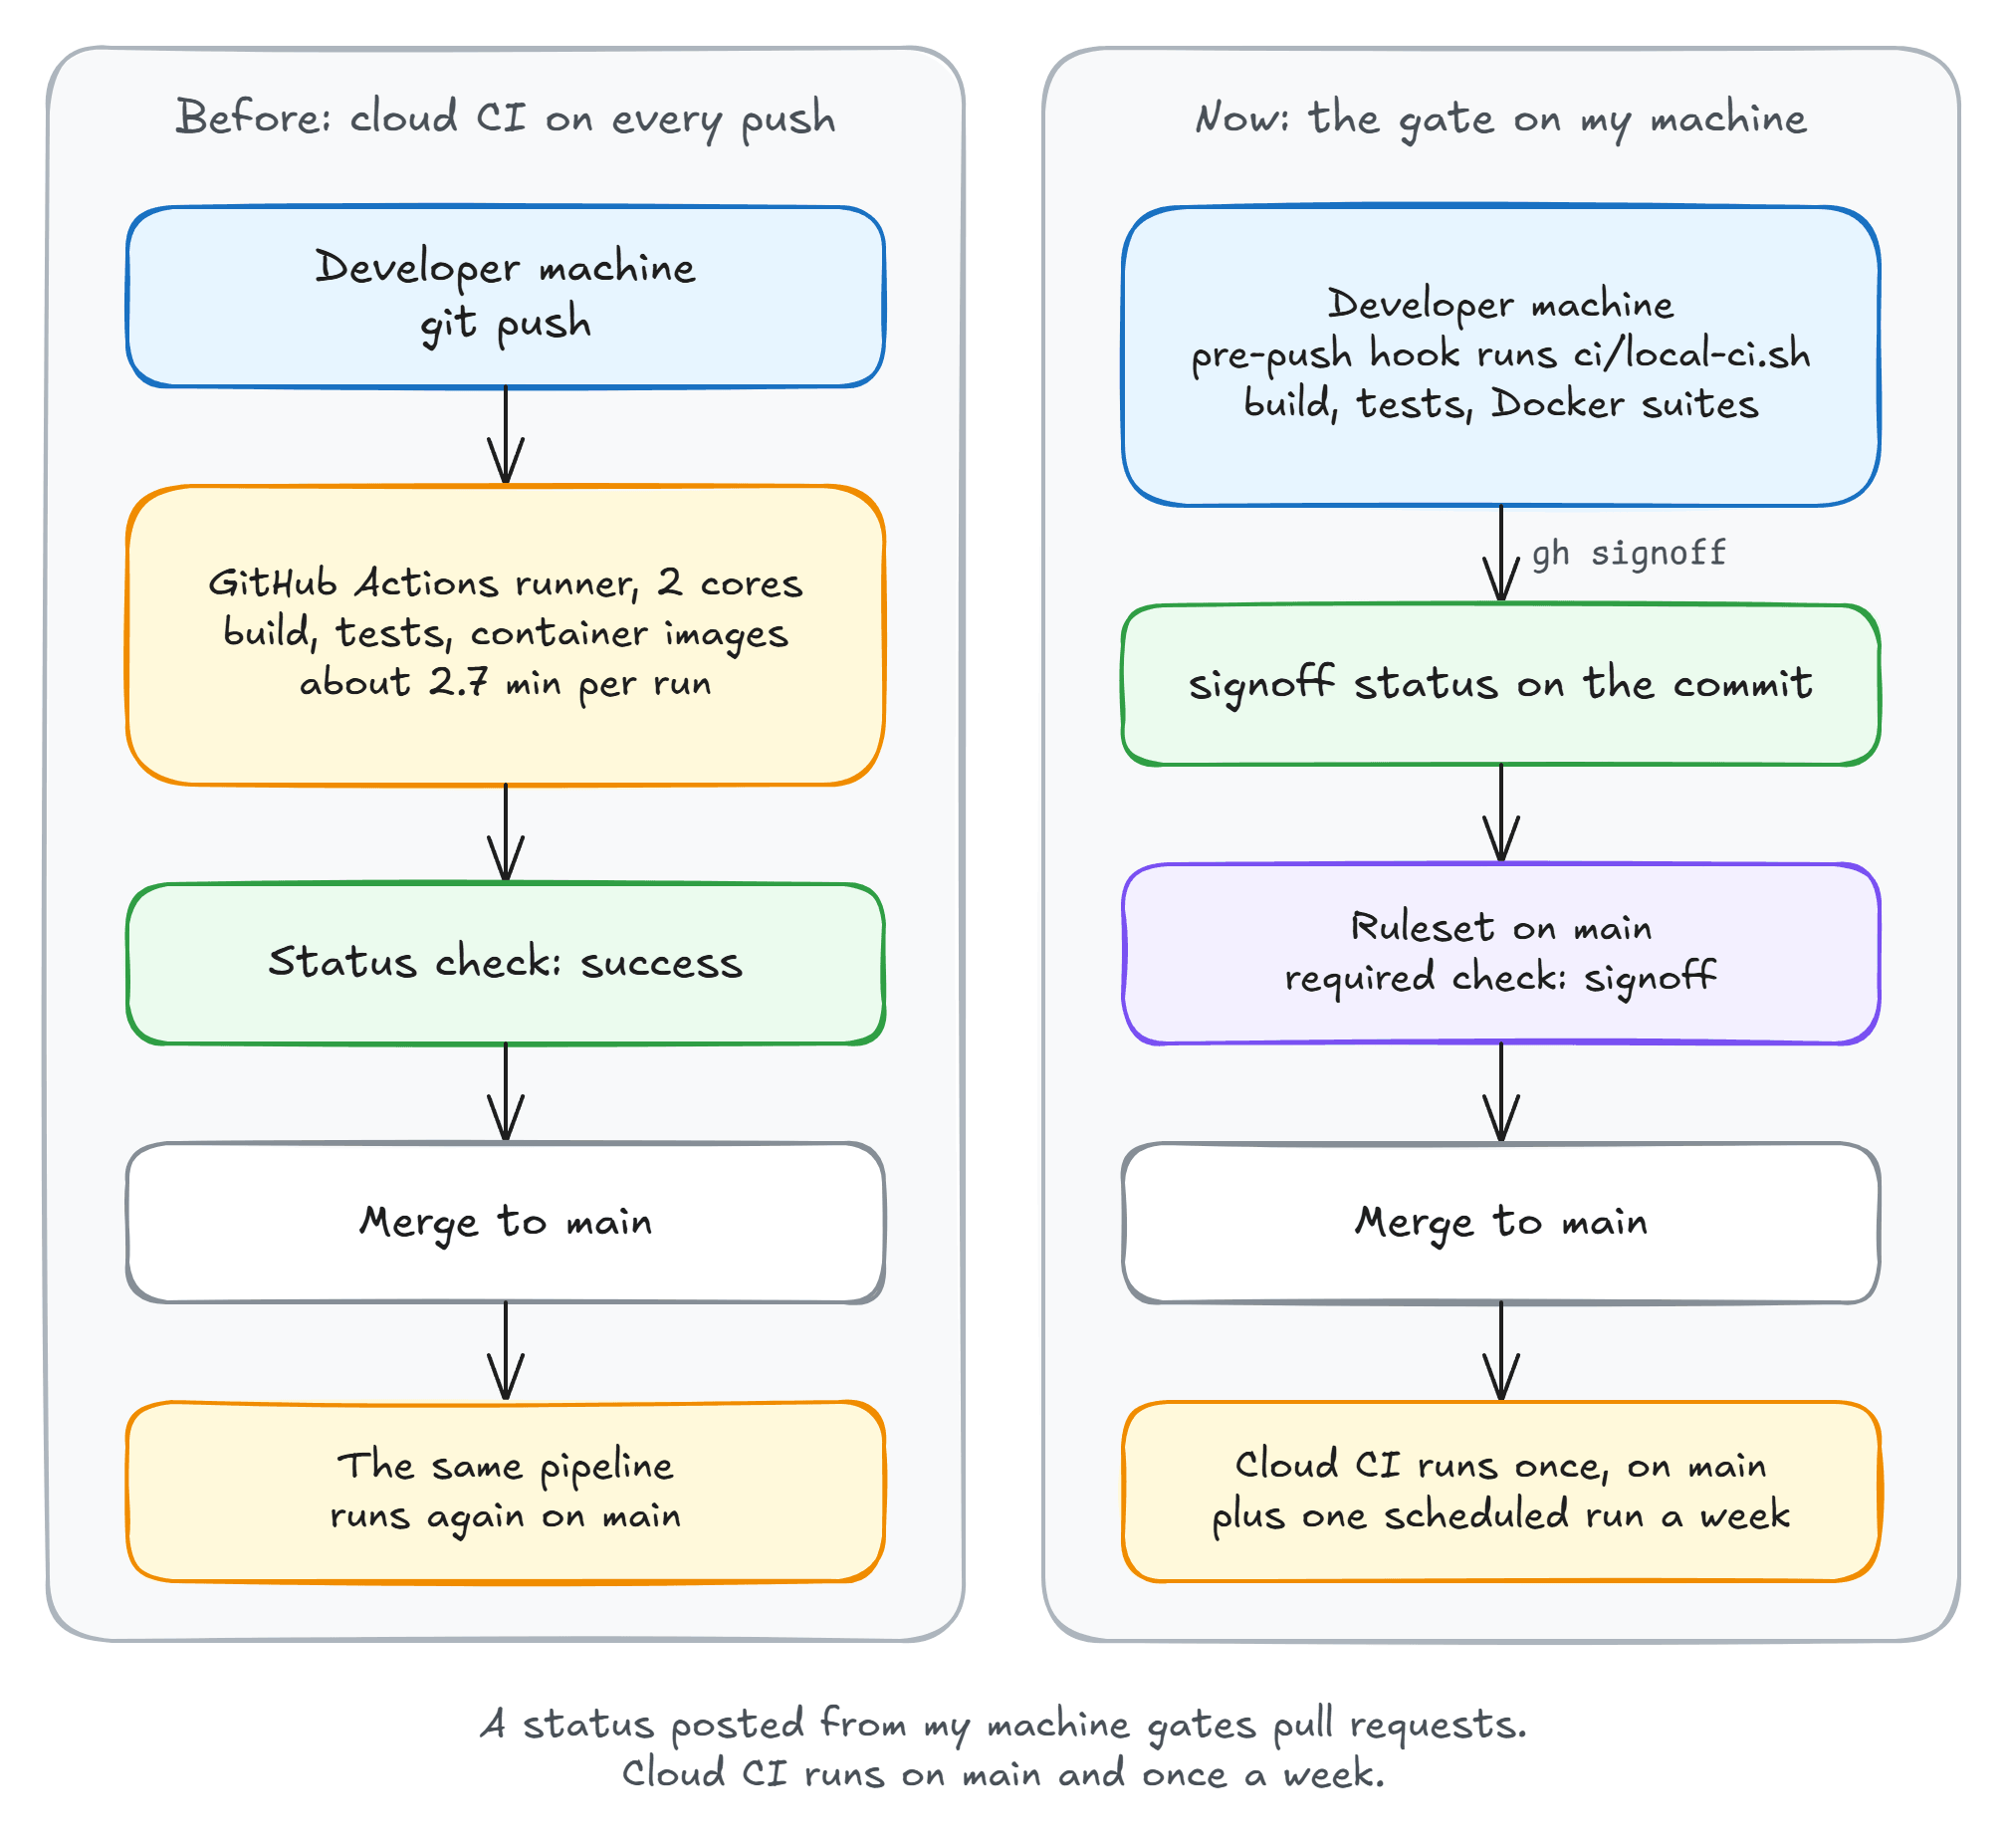
In June this year, the GitHub Actions bill for the Katabench repo was growing, and waiting for CI was seriously slowing down my work. Every pull request ran the .NET build, the tests, and the container image builds. And it would run the same steps again on every merge to main. In the 19 days before I changed it, that workflow ran 588 times for pull requests alone, about 2.7 minutes each on a 2-core runner.

I turned the pull_request trigger off and moved the gate to my own machine. Four months and 833 merged pull requests later, I haven't looked back.

Cloud CI on every push versus a local pre-push hook, a signoff status, and cloud CI only on main.

What DHH Did With HEY

In April 2024, DHH wrote that 37signals was moving continuous integration back to developer machines. The remote CI run for HEY, their email app, took about five and a half minutes. His Linux desktop ran the same checks in less than half that time.

I found this idea quite interesting while searching for solutions to my slow CI problem.

His argument was about cores. A developer machine has far more of them than a rented CI runner, so the same suite finishes faster. He was also clear that this doesn't fit a codebase the size of Shopify or GitHub.

That still leaves the green check on the pull request. GitHub calls it a status check: a named pass or fail mark on one commit.

Basecamp released gh-signoff, an extension for the GitHub CLI that posts one from your terminal.

I gave it a try.

The Gate Is a Shell Script

The smallest version of my local gate, ci/local-ci.sh in a .NET repo:

#!/bin/sh
set -eu

marker="$(git rev-parse --git-dir)/ci-passed"

if [ "$(cat "$marker" 2>/dev/null)" = "$(git rev-parse HEAD)" ]; then
  echo "gate already passed for $(git rev-parse --short HEAD)"
else
  dotnet build MyApp.slnx -c Release -warnaserror
  dotnet test tests/MyApp.Tests -c Release --no-build
  dotnet format MyApp.slnx --verify-no-changes
  git rev-parse HEAD > "$marker"
fi

if [ "${1:-}" = "--signoff" ]; then
  gh signoff
fi

Here is what each part does, if shell scripts are new to you. The first line runs the file with sh, which ships with Linux, macOS, and Git for Windows. set -eu stops the script at the first failing command or unset variable, so gh signoff only runs when every check passed.

$(...) runs a command and pastes its output into the line, so marker is the path of ci-passed inside the .git folder.

The if compares the hash in that file with the current commit, and 2>/dev/null hides the error when the file doesn't exist yet. When they match, the script skips the checks. Otherwise the three dotnet commands run, and > writes the commit hash into the marker file.

${1:-} is the script's first argument, or empty when there was none. With --signoff, it ends by posting the status.

Put whatever your existing CI runs in here, especially integration tests using Docker.

Let Git Run It Before Every Push

A git hook is a script that git runs at a fixed point. pre-commit runs before git creates a commit, and pre-push runs before it sends your commits to GitHub. If the hook exits with an error, git cancels the commit or the push.

Git reads hooks from .git/hooks, which isn't committed, so a fresh clone has none. The fix is a committed folder and one config line per clone:

git config core.hooksPath .githooks

With that in place, .githooks/pre-push runs the gate:

#!/bin/sh
exec sh ci/local-ci.sh

Run chmod +x .githooks/pre-push before committing it, or git skips the hook.

Notice that the hook doesn't pass --signoff. At that point the commit only exists on my machine, and gh signoff refuses to post a status for a commit GitHub doesn't have yet.

So I push first, and the hook runs the checks on the way out. Then I run sh ci/local-ci.sh --signoff, which finds the marker from the hook run, skips the checks, and posts the status.

GitHub sees the commits and the status, but never the hook. It can't tell whether the hook ran before the push, and git push --no-verify skips it.

So the hook catches my mistakes early, but it can't protect the branch. That job belongs to a rule on GitHub's side.

One Required Check

GitHub can refuse to merge a pull request until named checks pass on its latest commit. That setting is a branch protection rule, or in its newer form, a ruleset.

A workflow job posts a status check when it finishes, and anyone with push access can post one through the API without running anything. That is all gh signoff does.

You can set up the gate with two commands:

gh extension install basecamp/gh-signoff
gh signoff install

install creates a ruleset on main that requires a status named signoff and blocks force pushes. The required-check rule, as the GitHub API returns it:

{
  "type": "required_status_checks",
  "parameters": {
    "required_status_checks": [{ "context": "signoff" }],
    "strict_required_status_checks_policy": true
  }
}

The strict flag is the setting GitHub calls "Require branches to be up to date before merging". With it on, GitHub won't merge my pull request if main has moved since I signed off. I have to rebase, run the gate again, and post a new signoff.

That's extra work with several branches open, but the checks always ran on the code that gets merged.

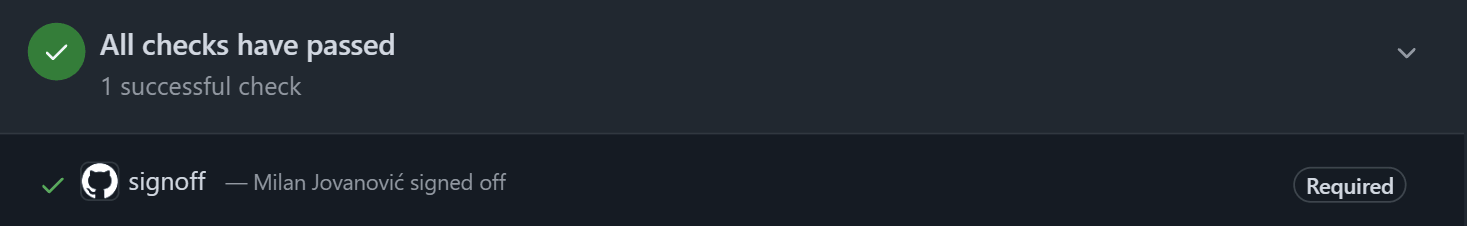
This is how the pull request shows the status:

Pull request checks: All checks have passed, 1 successful check, signoff, Milan Jovanović signed off, Required

The status belongs to one commit. If you push another commit, GitHub will block the pull request until the signoff gate runs on the new commit.

What Still Runs in the Cloud

Here's what the trigger block looks like in my workflow file:

on:
  push:
    branches: [main]
  schedule:
    - cron: '0 6 * * 1'
  workflow_dispatch:

There is no pull_request trigger anymore. The pipeline runs once per merge to main, on a clean runner with none of my caches, my SDK, or my Docker images. It's the one run that doesn't take my word for it, and it checks the exact commit that landed on main.

The merge run can't block a bad signoff, because it starts after the merge. If something slipped through, main goes red and I fix it right away. That is the cost of this setup.

A signoff status proves that someone with push access posted it, and GitHub records who. The script posts it only after a green run, but anyone with push access can type gh signoff on its own, and a repository admin can bypass the ruleset outright.

On my repo that's me and my coding agents, whose instructions forbid --no-verify and a signoff outside the script. A team has to agree on the same rule.

The schedule entry runs the pipeline every Monday, even when nothing was merged that week. My pipeline scans the container images, so that run is how I find out about a new CVE in a base image.

And we've had plenty of CVEs disclosed recently. In October alone, .NET shipped security patches and an out-of-band fix twelve days later for a Brotli decoder bug, and curl fixed a use-after-free in HTTP/2 uploads.

workflow_dispatch adds a Run workflow button for a full run on demand.

Summary

Running CI in the cloud on every pull request is still a good default. You get a clean machine, and nobody on the team can fake the result.

But I was paying for that with minutes of waiting on every push, plus a growing Actions bill. My test suite finishes on my machine in a few minutes, so the trade didn't make sense anymore.

A script runs the checks and ends with gh signoff, and a pre-push hook runs it before every push. On GitHub's side, a ruleset on main requires the signoff status, and one workflow still runs in the cloud after each merge.

This setup can't handle pull requests from forks, because posting a status needs push access. If you maintain an open-source project, keep cloud CI for outside contributors and use signoff for the core team.

To try this, start with the script. Once it runs green in a few minutes, add the hook and the ruleset, then change the trigger block.

I covered the cloud version of this pipeline in an earlier issue.

Thanks for reading.

And stay awesome!


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Compromised eMudhra Certificates: Update Your JetBrains IDEs, ReSharper, .NET Tools, Toolbox App, and Gateway Now

1 Share

Summary

  • The private keys of eight eMudhra intermediate certificates were compromised. A network attacker could use them to impersonate websites and services that JetBrains tools connect to.
  • JetBrains IDEs, the Toolbox App, Gateway, and ReSharper are affected because they use the trust store of the bundled JetBrains Runtime (JBR). For IDEs, the embedded browser (JCEF) is also affected. Operating system updates don’t protect against this issue. 
  • The Toolbox App and JetBrains IDEs use a background service, jetbrainsd. It has its own built-in list of trusted certificates and is fixed separately, in jetbrainsd 0.9.9728.
  • At the time of publishing, we are not aware of any exploitation of this issue against JetBrains users.

Available fixed versions

The issue is fixed in the following versions:

  • IntelliJ IDEA: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.6.2, 2025.2.6.4.
  • PyCharm: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.6.2, 2025.2.6.3.
  • PhpStorm: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.6.2, 2025.2.6.3.
  • RubyMine: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.6.2, 2025.2.6.3.
  • WebStorm: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.6.2, 2025.2.6.3.
  • Rider: 2026.3 EAP 9, 2026.2.4, 2026.1.5.3, 2025.3.5.3.
  • CLion: 2026.3 RC, 2026.2.4.1, 2026.1.5.2, 2025.3.6.3, 2025.2.6.3.
  • DataSpell: 2026.1.3.1, 2025.3.3.1, 2025.2.4.1.
  • DataGrip: 2026.3 RC, 2026.2.6.1, 2026.1.4.1, 2025.3.6.1, 2025.2.6.1.
  • GoLand: 2026.3 RC, 2026.2.4, 2026.1.5.1, 2025.3.5.2, 2025.2.6.3.
  • RustRover: 2026.3 EAP 8, 2026.2.5, 2026.1.4.1, 2025.3.7.1, 2025.2.6.1.
  • Gateway: 2026.3 RC, 2026.2.4, 2026.1.4, 2025.3.3, 2025.2.6.
  • ReSharper: 2026.3 EAP9, 2026.2.4, 2026.1.5.3, 2025.3.5.3.
  • Toolbox App 3.9.1, 3.8.2.

The 2025.2.6.* updates for all IDEs now contain only the JBR fix. They will get a separate hotfix for the JCEF problem. Until then, use a workaround to disable JCEF in your IDE (see instructions below).

IDE versions 2025.1 and earlier, and Toolbox App 3.7 and earlier, will not receive this fix. You must update to a fixed version.

Details

In October 2026, the private keys of eight intermediate certificates issued by the certificate authority eMudhra were compromised. An attacker who can intercept your network traffic could use them to impersonate websites and services.

Full details of the incident.

JetBrains IDEs check certificates against the trust store of their bundled runtime, JetBrains Runtime (JBR), so updating your operating system doesn’t protect against this issue. We’ve integrated Oracle’s fixes for CVE-2026-91403 and CVE-2026-114820 into JBR as-is. The updated runtime blocks the compromised certificates and no longer trusts these root certificates:

  • emSign ECC Root CA – G3
  • emSign Root CA – G1
  • emSign Root CA – G2
  • AAA Certificate Services

In the fixed versions of 2025.3 and later, the embedded browser now receives Chrome’s certificate updates, which block the compromised certificates (CVE-2026-118696). It downloads them from Google’s update servers shortly after the IDE starts. If your network blocks access to Google’s update servers, the embedded browser stays unprotected. In this case, turn it off as described below.

The Toolbox App and JetBrains IDEs also install a background service, jetbrainsd. Its list of trusted certificates is built into the service itself, so updating JBR doesn’t fix it. We’ve released a separate fix in jetbrainsd 0.9.9728, tracked as CVE-2026-118697. Only one copy of jetbrainsd runs for each user, and a newer version always replaces an older one. Updating any app that includes jetbrainsd 0.9.9728 fixes it for all JetBrains apps.

What you should do: Update now

The fix is available in the latest versions of JetBrains IDEs, from 2025.2 up to 2026.3 RC. The upcoming 2026.3 release will include it too. Updating to the latest bugfix release of your current version is enough. Versions 2025.1 and earlier will not receive a fix. If you use one of them, please update to one of the versions above.

If you use ReSharper or other JetBrains .NET tools, update them to the latest version.

Important for Toolbox App users: versions 3.7 and earlier won’t receive this fix. If you’re on 3.7, update to version 3.9.1 or 3.8.2.

If you use JetBrains Gateway, update it to one of the following versions: 2026.1.4, 2025.3.3, 2025.2.6.

If you use JetBrains Runtime directly, update to one of the fixed builds: jbr25.635.79, jbr25.508.41, jbr25.329.142, jbr21.1163.125, jbr21.1038.91.

In rare cases, the IDE will no longer connect to a server whose certificate chains to one of the removed root certificates. The server’s owner will need to replace the certificate.

If you can’t update right away

Clean your certificates manually

The Java runtime bundled with these IDEs and Toolbox App still trusts two eMudhra-related root certificates. If you can’t update the IDE, give it a cleaned copy of its certificate list and turn off its built-in browser, which has its own list that can’t be changed. It takes about five minutes and is fully reversible.

  1. Copy the certificate list from the IDE folder to your home folder:
    macOS: <IDE>.app/Contents/jbr/Contents/Home/lib/security/cacerts
    Windows / Linux: <IDE>/jbr/lib/security/cacerts
     
  2. Remove the two affected roots, using the keytool in the IDE’s jbr/bin folder:
    keytool -delete -keystore <copy> -storepass changeit -alias "comodoaaaca [jdk]"
    keytool -delete -keystore <copy> -storepass changeit -alias "emsigneccrootcag3 [jdk]"
     
  3. Open Help | Edit Custom VM Options, add this line, then restart the IDE:
    -Djavax.net.ssl.trustStore=<full path to the copy>
    Important: write the full path, with no ~, no variables, and no quotes. A wrong path silently leaves you unprotected.
     
  4. In Settings | Tools | Server Certificates, make sure “Accept non-trusted certificates automatically” is off.
     
  5. Linux only: update the ca-certificates package.

What to expect: If the IDE shows an “untrusted server certificate” dialog for an eMudhra certificate, click Reject.

Disable JCEF in your IDE

To workaround the JCEF problem in 2025.2.6.4 and previous versions, or in any version if your network blocks Google’s update servers:

  1. Open Search Everywhere -> Actions
  2. Type “Registry”
  3. Open Registry
  4. Search for ‘ide.browser.jcef.enabled’ key
  5. Switch it off
  6. Restart

Note: Turning off the embedded browser affects features that use it, for example, Markdown and HTML previews and Jupyter notebook output. Some plugins may also stop working correctly. After you update to a fixed version, turn ide.browser.jcef.enabled back on and restart the IDE.

Update jetbrainsd background service

The Toolbox App and JetBrains IDEs use a background service, jetbrainsd. It has its own built-in list of trusted certificates, so updating JBR doesn’t fix it, and the workarounds above don’t apply to it.

The fix is in jetbrainsd 0.9.9728. You get it when you install or update a fixed version of the Toolbox App or an IDE and start it. Only one copy of jetbrainsd runs for each user, and the newest version replaces older ones. So updating the Toolbox App fixes jetbrainsd for all your IDEs, even if you can’t update the IDEs themselves.

If you can’t update the Toolbox App or an IDE, update jetbrainsd manually:

  1. Download the archive for your platform and check its SHA-256 checksum with shasum -a 256 (macOS), sha256sum (Linux), or Get-FileHash (Windows PowerShell):
  2. Unpack the archive and run jetbrainsd once without arguments. It replaces the older version. To unpack, use tar -xzf. On Windows 10 and later, tar is built in.
    • Linux: ./jetbrainsd/bin/jetbrainsd
    • macOS: ./jetbrainsd.app/Contents/MacOS/jetbrainsd
    • Windows: .\jetbrainsd\bin\jetbrainsd.exe
       
  3. Check the installed version. It should be 0.9.9728 or later:
    • Linux: "${XDG_DATA_HOME:-$HOME/.local/share}/JetBrains/Daemon/bundles/current/jetbrainsd/bin/jetbrainsd" --version
    • macOS: "$HOME/Library/Application Support/JetBrains/Daemon/bundles/current/jetbrainsd.app/Contents/MacOS/jetbrainsd" --version
    • Windows (PowerShell): & "$env:LOCALAPPDATA\JetBrains\Daemon\bundles\current\jetbrainsd\bin\jetbrainsd.exe" --version

Also check

Your project JDKs and any tools that bring their own runtime, such as Node.js, Python, or Go, use their own trust stores. Update them as their vendors recommend.

Support

If you have any questions about this issue or have trouble updating, please contact our Support team.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Why AI Agents Fail in Production: The Data Layer Problem

1 Share

Most enterprise AI agent projects look impressive as a demo but never reach production. When these projects stall out, the usual explanation is that the model underperformed, the prompts were wrong, or the use case was too ambitious. But often, the real problem lies deeper. It’s the data layer.

An AI agent that can’t remember what it did in a previous session, that can’t be audited when it makes a consequential decision, and can’t access live operational data without calling three separate APIs doesn’t have a model problem. It has an infrastructure problem. And the Couchbase AI Data Plane™ is built to solve it.

Why do AI agents fail between pilot and production?

According to Gartner, organizations will abandon 60% of AI projects unsupported by AI-ready data through 2026. In most cases, the model isn’t the problem. A pilot looks good in a demo environment, then breaks down in production because the organization lacks a unified data plane built for agent speed. Agents end up reaching across disconnected systems for memory, context, and tools, and every hop adds latency, cost, and risk.

Three specific failures account for most of what goes wrong.

Agent amnesia – the memory problem

An agent that can’t remember what it did last session, what a user told it two minutes ago, or what it already tried in a multi-step workflow is not a production agent. It’s a stateless function that happens to use an LLM. Every session starts from scratch, users repeat themselves, and the agent repeats mistakes it already made.

Agent amnesia occurs when an agent’s memory is fragmented across separate caches, vector databases, session stores, and in-context window state, with no unified layer to manage them as a coherent whole. The agent technically has access to information in pieces, but it can’t maintain a consistent, personalized understanding of a user or a task over time.

The governance gap – the observability problem

In regulated industries, “the agent decided” is not a defensible explanation for a consequential decision. For every agent action, the engineering team must be able to answer the questions: What data did the agent access? Which tools did it invoke? What prompt was it operating from? Which version of that prompt? 

If the engineering team can’t answer those questions, then the security and legal teams can’t trust the agent in production.

Tracing and auditing agent behavior isn’t a model problem. It’s a data problem. When tools, prompts, and agent function calls aren’t logged in a structured, queryable format, auditing agent behavior becomes a manual reconstruction effort rather than a straightforward query. Teams need the observability infrastructure to trace each action, understand how the agent reached a decision, and produce an auditable record when compliance, security, or legal teams need answers.

Integration cost – the point-solution problem

A production AI agent typically needs access to a vector store for semantic retrieval, a cache for fast context lookup, a session store for short-term memory, a document store for operational data, and a tool registry for governed function calls. When each is a separate system, integration overhead is significant. You deploy five systems, maintain five APIs, manage five sets of credentials, and face five potential points of failure on every agent inference call.

Each point solution was probably the right decision when you added it. But together, they become a fragmented infrastructure that causes the agent to fail when one component falls behind, goes down, or drifts out of sync with the others.

What is the Couchbase AI Data Plane?

The Couchbase AI Data Plane is the governed data and memory layer that gives production AI agents persistent memory, governed access to data and tools, and consistent context from the cloud to the edge. It collapses the five separate point solutions described above into one platform that’s built on Couchbase Capella and is available across cloud, self-managed, hybrid, and edge deployments.

The AI Data Plane has these three core components that directly address the three potential failure areas discussed above:

Agent Memory

Agent Memory gives AI agents persistent recall across sessions, users, and frameworks. Memory is structured across three levels that work together. Short-term memory holds the current conversational context and active task state. Long-term semantic memory stores observations and facts as vector embeddings for cross-session retrieval. Profile memory stores structured user attributes (like preferences and permissions) for deterministic, low-latency lookup.

When an agent with proper memory asks, “What did we discuss last time?” or “Does this user prefer metric or imperial units?” it retrieves a real answer from a governed store rather than generating a hallucinated one. Over time, the agent becomes more personalized because its memory reflects each user’s actual interaction history, not a fresh context window.

Memory in the AI Data Plane is not a bolted-on vector store. Every memory block is a JSON document containing an embedding vector, a natural language summary, a structured context object, a timestamp, and a configurable time-to-live for retention compliance. The system stores, retrieves, and governs these memory blocks alongside the agent’s other operational data.

Agent Catalog

The Agent Catalog is the governed registry where every tool, prompt, and agent function used in a production application is stored, versioned, and made inspectable. It gives regulated enterprises the visibility they need to trust agents in production.

When an agent makes a decision, the Agent Catalog records which tool it called, which prompt version it used, what data it accessed, and the result. Those records are vectorized and indexed so that teams can search agent behavior semantically. “Show me all sessions where the agent invoked the payment tool without user confirmation” is a real query, not a hypothetical. 

The Agent Catalog also makes development faster. Instead of each team building a new agent from scratch, the Agent Catalog makes existing tools and prompts discoverable. With semantic search over the catalog, a team can find and reuse a tool another team already built.

Governed data access via MCP Server

The Couchbase MCP Server implements the Model Context Protocol (MCP), the open standard that defines how AI models connect to external tools and data sources at runtime. MCP gives agents a governed, discoverable interface to invoke capabilities without hardcoding an integration for every tool.

Rather than giving the agent direct database credentials, the MCP Server enforces role-based, tool-level access control. The agent can query what it’s authorized to query, invoke the tools it’s authorized to invoke, and nothing more. The AI Data Plane’s audit infrastructure logs every invocation.

How unified data infrastructure changes what agents can do

The difference between an agent running on fragmented point solutions and one running on the Couchbase AI Data Plane isn’t primarily a performance difference. It’s a capability difference.

An agent with unified memory, governed tool access, and fast semantic retrieval in one layer can do things that a fragmented agent can’t. It can recognize a returning user across channels without the user identifying themselves, resume a complex multi-step task from exactly where it left off after a session interruption, refuse a request that falls outside its authorized scope and explain why, and surface the exact prompt and tool invocation that produced a specific output when a compliance team requests an audit.

None of these capabilities require a better model. They simply require a data layer designed for agent workloads, not one assembled from systems designed for something else.

The AI Data Plane also runs where production workloads actually run. For enterprises with edge deployments, field service applications, or always-on requirements, the same data layer available on Couchbase Capella extends to self-managed, hybrid, and edge environments. Couchbase Lite and Couchbase Edge Server support these deployments with bidirectional sync and consistent governance across every tier.

What this looks like in practice

The value of the AI Data Plane becomes clear when you see how its components work together in a real application. Consider a customer service agent that needs to deliver personalized support while keeping its actions secure, consistent, and auditable.

A customer service agent powered by the Couchbase AI Data Plane opens every interaction with the customer’s preference profile from Agent Memory, retrieves semantically relevant context from prior sessions using vector search, invokes authorized tools through the MCP Server to look up orders or update records, and logs every action through the Agent Catalog for compliance review. When the session ends, it writes the outcome back to the customer’s long-term memory so the next interaction builds on it.

Compare that to the same use case on fragmented infrastructure. This time, the agent has no memory of prior sessions unless the developer has pre-loaded a summary into the context window (which has a token cost, a latency cost, and is limited by window size). Tools are invoked through hardcoded API calls with no centralized audit trail. And compliance teams requesting a review of a specific interaction have to reconstruct what happened from logs spread across five systems.

The agent in the first scenario gets smarter over time. The agent in the second scenario starts from the same point on every call, regardless of how many interactions it has handled.

FAQs

What is the Couchbase AI Data Plane? The Couchbase AI Data Plane is the governed data and memory layer for production AI agents. It provides persistent agent memory across sessions, governed tool access through MCP Server, a centralized Agent Catalog for prompt and tool governance, semantic caching, and vector search, all on one platform available across cloud, self-managed, hybrid, and edge deployments.

Why do AI agents fail between pilot and production? The most common causes are fragmented agent memory (agents that can’t remember prior sessions or maintain personalized context), lack of observability (no structured log of which tools and prompts the agent used and why), and point-solution sprawl (five separate systems for vector search, caching, session state, operational data, and tool registries). These are data infrastructure problems, not model problems. You can watch this on-demand webcast to learn more about the difference.

What is Agent Memory in Couchbase? Agent Memory is the persistent memory layer in the Couchbase AI Data Plane. It stores agent state at three levels: short-term memory for the current conversational context, long-term semantic memory as vector embeddings for cross-session retrieval, and profile memory for structured user attributes. Every memory block includes a JSON document with an embedding, a natural language summary, a structured context object, a timestamp, and a configurable retention TTL.

What is the Agent Catalog? The Agent Catalog is the centralized registry in the Couchbase AI Data Plane where tools, prompts, and agent functions are stored, versioned, and made inspectable. It records every tool invocation, prompt version, and data access event in a structured, queryable format, enabling compliance audits and making existing tools discoverable and reusable for teams building new agents.

Does Couchbase AI Data Plane support edge and always-on deployments? Yes. The AI Data Plane is available on Couchbase Capella and extends to self-managed, hybrid, and edge environments through Couchbase Lite and Couchbase Edge Server. They provide bidirectional sync and consistent governance at every tier.

What is MCP and how does it relate to the AI Data Plane? MCP is the Model Context Protocol, an open standard that defines how AI models connect to external tools and data at runtime. The Couchbase MCP Server implements MCP as part of the AI Data Plane, giving agents a governed, auditable interface for tool invocation with role-based access control enforced at the server layer rather than in application code.

The post Why AI Agents Fail in Production: The Data Layer Problem appeared first on The Couchbase Blog.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories