Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164420 stories
·
33 followers

Before replacing LINQ, read what it becomes

1 Share

TL;DR: Replacing a LINQ predicate in the Azure Service Bus receiver removed a repeated delegate allocation. Going further helped some inputs and hurt others. The useful part of that work was learning what the query became and which costs mattered to the SDK, not finding a reason to stop using LINQ.

One of the Azure Service Bus changes I worked on started with a short LINQ expression in the receiver. It was readable, did what it needed to do, and sat on a path that completed messages. The interesting cost only became obvious when I looked at the generated code.

This is the kind of small change I had in mind in the first post. A few lines can be worth investigating when they run for every message. That does not make the same change worthwhile in setup code, and it certainly does not make Any something to avoid.

The source looked harmless

The code was in the Azure Service Bus Advanced Message Queuing Protocol (AMQP) receiver. It accepted message lock tokens as strings, converted them to Guid values, and checked whether any belonged to a message received through the request-response link. Those messages have to be settled through that link instead of the regular receive link. I have left both settlement paths out of the sample so we can focus on the lookup.

private readonly ConcurrentExpiringSet<Guid> _lockedMessages = new();

private Task CompleteInternalAsync(IEnumerable<string> lockTokens)
{
    Guid[] lockTokenGuids = lockTokens
        .Select(token => new Guid(token))
        .ToArray();

    if (lockTokenGuids.Any(lockToken =>
        _lockedMessages.Contains(lockToken)))
    {
        // Settle through the request-response link
        return Task.CompletedTask;
    }

    // Settle through the receive link
    return Task.CompletedTask;
}

The public API used IEnumerable<string> deliberately because an SDK should accept a broad range of callers. That choice also hides the concrete collection type from this method.

The delegate was the interesting part

The predicate passed to Any accessed an instance field, which meant the delegate needed a reference to the current object. In the runtime targeted by the original contribution, the compiler created that instance-bound Func<Guid, bool> each time the method ran.

// Decompiled code, with unrelated generated code omitted
private Task CompleteInternalAsync(IEnumerable<string> lockTokens)
{
    Enumerable.Any(
        Enumerable.ToArray(
            Enumerable.Select(
                lockTokens,
                <>c.<>9__2_0 ??
                    (<>c.<>9__2_0 = new Func<string, Guid>(
                        <>c.<>9.<CompleteInternalAsync>b__2_0)))),
        new Func<Guid, bool>(<CompleteInternalAsync>b__2_1));

    return Task.CompletedTask;
}

[CompilerGenerated]
private bool <CompleteInternalAsync>b__2_1(Guid lockToken)
{
    return Enumerable.Contains(_lockedMessages, lockToken);
}

The generated Select delegate uses the ?? assignment to cache one instance. The predicate passed to Any instead contains new Func<Guid, bool> directly, so every call creates another delegate.

That difference is easy to miss when reading the original expression. Looking at the decompiled version helped me connect the lambda in my source to an object created on every call. This translation from convenient C# syntax into simpler constructs is called lowering. It became a useful way to check what I thought the code was doing.

My first change left the conversion alone and replaced only the predicate.

Guid[] lockTokenGuids = lockTokens
    .Select(token => new Guid(token))
    .ToArray();

foreach (Guid lockTokenGuid in lockTokenGuids)
{
    if (_lockedMessages.Contains(lockTokenGuid))
    {
        return Task.CompletedTask;
    }
}

The loop removed that delegate allocation and made the early exit explicit. The benchmarks covered arrays, lists, sets, lazy enumerables, and several input sizes. In that comparison, every shape got faster and allocated less. A single-element array went from 129 nanoseconds and 240 bytes to 93 nanoseconds and 144 bytes. That was a useful result for a change small enough to explain in review.
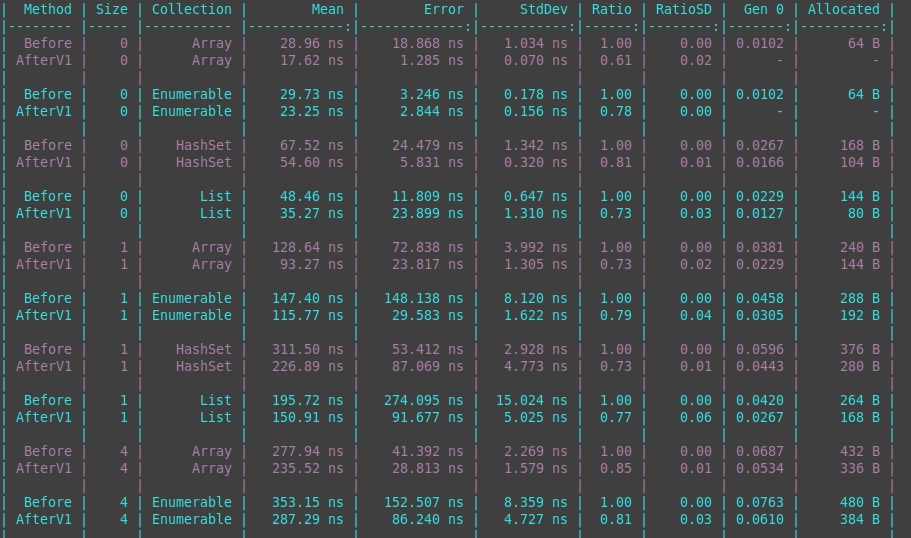
Benchmark comparing LINQ Any with a foreach loop in the AMQP receiver
The original benchmark found a useful win in this runtime and workload. It did not establish a universal rule about LINQ.

I would remeasure this on a newer runtime

I would not take those numbers as a reason to make the same change in a .NET 10 application. The original contribution targeted an older runtime, and LINQ has kept improving since then. The source can stay the same while the work underneath it changes.

LINQ uses specialized iterator types for combinations such as arrays with Select, lists with Skip and Take, or a Where followed by Select. Those types preserve information about the source and earlier operators, allowing later operations to fuse work or skip it entirely.

The .NET 10 performance article has a good example: source.OrderBy(...).Contains(value) can search the underlying source without sorting it. Ordering cannot change whether a value exists. Other Contains specializations avoid reversing, distinct processing, or extra iterator layers. Several of those chains are dramatically faster than they were on .NET 9.

That is why I want the target framework beside the benchmark result. Otherwise I may end up maintaining a hand-written replacement for work the runtime no longer does.

The next change needed more context

There was still more collection work in the receiver. The method accepted IEnumerable<string>, which hid information about the input. A List<T> enumerated directly can use its struct enumerator. The same list exposed as IEnumerable<T> may involve interface dispatch or boxing, depending on the operation and runtime.

Narrowing the public API was not the answer. The SDK needed to keep accepting inputs that were not materialized collections. Internally, though, knowing the count would let the code allocate the final array once and combine the conversion and lookup.

The second version kept any IReadOnlyCollection<string> as-is and copied everything else into an array. That gave the internal method a count, but it also introduced a cost for callers passing a lazy sequence. Including that input in the benchmark mattered.

public Task CompleteAsync(IEnumerable<string> lockTokens)
{
    IReadOnlyCollection<string> readOnlyCollection = lockTokens switch
    {
        IReadOnlyCollection<string> asReadOnlyCollection => asReadOnlyCollection,
        _ => lockTokens.ToArray(),
    };
    return CompleteInternalAsync(readOnlyCollection);
}

private Task CompleteInternalAsync(IReadOnlyCollection<string> lockTokens)
{
    int count = lockTokens.Count;
    Guid[] lockTokenGuids = count == 0 ? Array.Empty<Guid>() : new Guid[count];
    int index = 0;
    foreach (string token in lockTokens)
    {
        Guid tokenGuid = new Guid(token);
        lockTokenGuids[index++] = tokenGuid;
        if (_lockedMessages.Contains(tokenGuid))
        {
            return Task.CompletedTask;
        }
    }

    return Task.CompletedTask;
}

Sets benefited most, and lists improved modestly. A four-element HashSet<string> went from 225 nanoseconds and 280 bytes to 80 nanoseconds and 128 bytes. An empty lazy enumerable went from 20 to 31 nanoseconds because it now had to be copied into an array first. Four-element arrays also measured slower, likely because the loop now enumerates them through an interface instead of indexing the array directly.
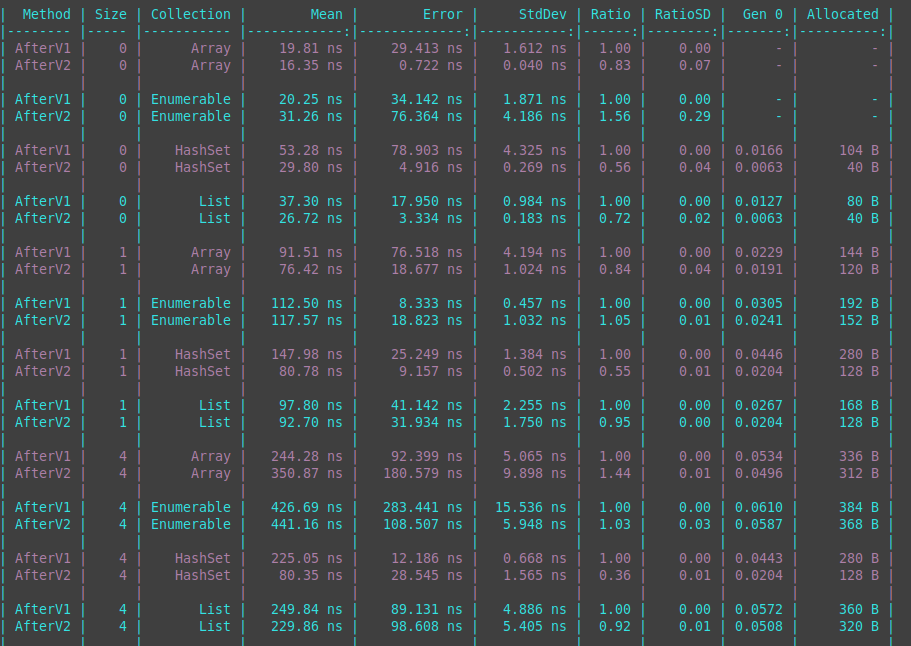
Benchmark comparing the foreach version with the collection-aware version of the AMQP receiver
The collection-aware version helped sets and lists, but lazy enumerables and larger arrays paid for it.

This was no longer the straightforward win of the first change. Production callers overwhelmingly passed materialized collections, which made the trade-off acceptable for this SDK. The benchmark showed me where the costs moved. Knowledge of the callers was what made the decision possible.

What I look for now

After working through changes like this, I read a hot-path query with a few more questions in mind. What concrete source reaches it? Does a lambda capture the instance or local state? How many times is the input enumerated, and does the next operation really need a materialized copy?

A decompiler helps when I cannot answer those questions from the source. An allocation profiler tells me whether the generated delegates or iterators appear often enough to investigate. I then compare the alternatives on the target framework and inputs that matter to the application.

The smaller collection changes still need to earn their place

Not every investigation needs the larger rewrite above. Sometimes the collection already exposes enough information to avoid an allocation or a copy. These are the smaller changes I would consider once collection work appears in the profile.

  • Represent empty arrays with Array.Empty<T>() and empty enumerables with Enumerable.Empty<T>(). Modern C# collection expressions may provide an equally efficient and clearer form for the target type.
  • Give a collection its final capacity when the count is already known. Repeated growth allocates larger backing storage and copies existing elements.
  • Keep concrete collection types available inside a measured hot path when their specialized enumeration matters. Do not narrow a public API merely to save an internal type check.
  • Use pattern matching or Enumerable.TryGetNonEnumeratedCount when code needs a count but should not walk a lazy sequence just to obtain one.
  • Delay creating a collection until the method knows it needs one. Validate boundary conditions and take early exits first.

Lower-level tools such as CollectionsMarshal, MemoryMarshal, and Unsafe can expose backing memory or remove checks. They also bypass abstractions and safety guarantees. I would reach for them only after ordinary collection code remains visible in the profile and tests protect the assumptions.

Keep the readable query until evidence objects

LINQ remains my default for code where it expresses the operation clearly. I replace it when a profile points at the query, inspection explains the cost, and a benchmark shows that the replacement earns its maintenance burden.

That threshold is higher for a twenty-line collection refactoring than for a four-line loop. It is also higher in application setup code than in an SDK path executed for every message.

The part of this contribution I keep coming back to is the difference between the two changes. Removing one delegate was easy to justify. Reshaping the collection handling needed knowledge of the SDK’s callers. Both started in the same few lines of LINQ, but they asked very different things of the people maintaining the code.

Further reading

The .NET 10 performance article is the best starting point for seeing how much LINQ behavior has changed since the original SDK contribution, and for the curious, you can already take a sneak peek at the .NET 11 performance improvements.

Common questions

Should I stop using LINQ on hot paths?

No. Profile and benchmark the exact query first. Modern LINQ has many source-specific and operator-specific optimizations.

Do I need to read assembly?

Usually not. A decompiler and an allocation profiler often reveal enough. Assembly becomes useful when the remaining question concerns bounds checks, vectorization, inlining, or another just-in-time compiler decision.

What should I remember?

The generated work and production context decide whether the syntax needs replacing.

Read the whole story
alvinashcraft
16 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Inside GitHub’s new Git storage architecture

1 Share

Last week at GitHub Universe, we announced our new Git storage architecture, capable of handling thousands of writes per second with reads that scale on demand. Through internal testing, we’ve demonstrated the ability to support 5,000 concurrent agents working on a repository, sending 7,200 pushes per second to a repo, all while serving read traffic with consistently low latency. This new architecture is the foundation for GitHub to support agentic development for hundreds of millions of developers, and we’ve been building it underneath GitHub while it keeps running.

Over the past year, agents changed what a busy repository looks like on GitHub. In our first post in this series, we laid out the two principles behind our next-generation Git storage architecture: minimize coordination, and decouple storage from compute. In our last post, we covered the bridge: moving 99.99999% of repositories into Azure, scoping the write quorum to individual references, and standing up virtual replicas backed by Azure Blob Storage.

We also left off with an observation: very little of a write needs to be ordered. Git objects are immutable and named by their contents, meaning two writers can store them at the same time without agreeing on anything. The part of a push that needs agreement is the reference update, and a reference update is tiny in comparison. Virtual replicas were the first step toward building around that, and the means by which we onboard repositories to the new architecture.

The rest of the architecture builds on that observation. Only reference updates need agreement. That lets the parts of Git infrastructure that used to be tightly coupled (storing data, serving requests, and maintaining repositories) scale independently. For developers, Git stays Git: they push, fetch, and branch the same way, with the same protections in place. Below, we walk through the requirements behind the design, follow a request through the system, and dive deep into two of its components.

Building for agent scale

We think about the scale of the GitHub platform along two axes:

  1. Horizontal scale is how many developers and agents can work across many repositories. Many of GitHub’s current approaches on this axis have been battle-tested over the years and are carried forward to the new architecture: partitioning of tenants across infrastructure, isolation and/or fairness enforcement of tenant traffic, and load-aware routing, to name a few.
  2. Vertical scale is how many developers and agents can work on one repository. As agents write more code, we expect individual repositories to get larger and busier, so most of our requirements came from the vertical axis.

Today, the busiest repositories on GitHub.com receive at most dozens of writes in a single second, typically in short bursts. As more of that work shifts to agents running in parallel and around the clock, we expect those bursts to become a sustained rate within the next year. Each push leads to more reads: CI runs, deployment systems pull the new commit, and other agents fetch it for context. This read fan-out results in a large amplification effect on overall traffic that scales with writes.

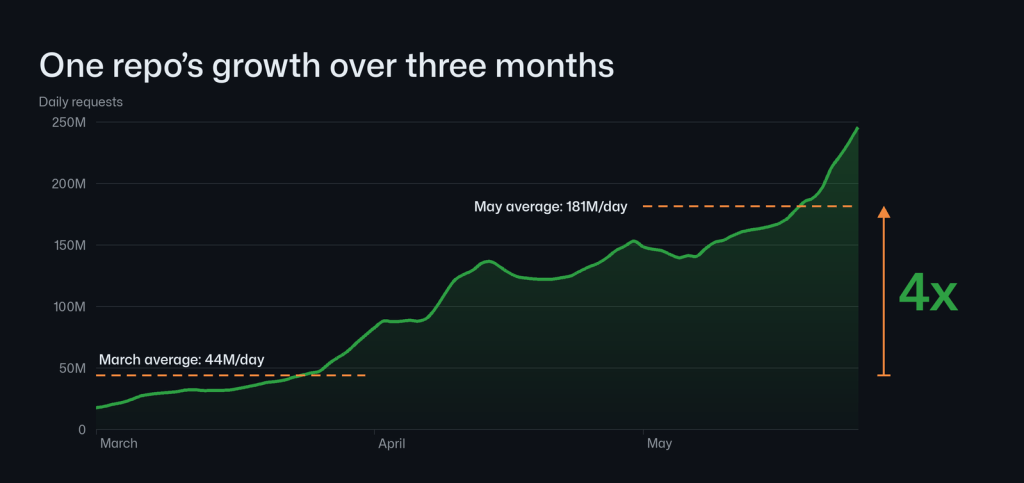
We’re already seeing this trend play out on repositories at the top of the curve. The chart below shows daily requests to one repository on GitHub from March to May, when its traffic grew about 4x. Its growth has continued on an exponential trajectory since then.

Line chart of daily requests to a single repository from March through May 2026. The March average is 44M requests per day and the May average is 181M requests per day, about a 4x increase.

We have to plan for a world where agent-driven development keeps accelerating at this speed. Instead of planning for the next increment, we set a target of at least two orders of magnitude more scale. For a single repository, that meant the new architecture needed to:

  • Accept thousands of writes per second.
  • Support multiple writer nodes. There are two reasons for this:
    • Experience has taught us that indexing incoming packs and checking object connectivity are the most CPU-expensive parts of a write, and that cost scales with the size of the write, so a single node will become compute-bound quickly.
    • Spreading that work across many nodes improves fault tolerance and shortens recovery when a node fails.
  • Minimize commit latency. An agent waits on each push before it moves to its next step.
  • Record changes in order for each reference with the ability to quickly linearize across references. A virtual replica that falls behind needs to catch up by downloading only the data it needs to serve the incoming request.
  • Keep reads cheap when nothing has changed, which is the common case given the read-to-write ratio.
  • Let each component scale independently.

On top of that, the system had to be able to improve overall reliability and scale globally.

Introducing “Project Rubicon”

In May of 2026, hot on the heels of the initial Azure migration, we started working on a design that could meet those demands. We tried several approaches. In all of them, pack data lived in Azure Blob Storage, and in some we experimented with keeping reference state there too. We’ll cover some of the trade-offs we found below, but we settled on a design we felt maximized throughput while preserving the correctness, durability, availability, and latency guarantees a platform like GitHub requires. We called it “Rubicon,” a nod to the point of no return the industry crossed with agentic development.

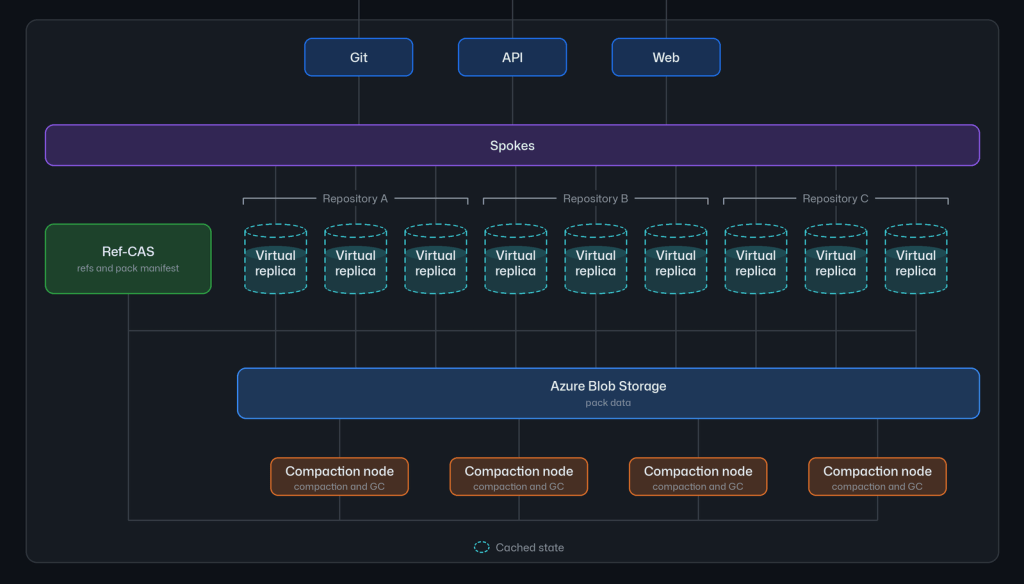
Let’s walk through Rubicon from the top down. Many things stay the same: requests from Git clients, the API, and the web UI arrive at Spokes, which still handles routing and load balancing, and serves the internal API that the rest of GitHub uses to read and write repository data. Spokes also maintains its role as a placement and balancing service, maintaining the partitioning, isolation, and tenant fairness required for horizontal scale. The data plane underneath Spokes, in contrast, is new.

Architecture diagram. Git, API, and Web requests pass through Spokes to groups of virtual replicas per repository. Virtual replicas hold only cached state. Ref-CAS stores refs and the pack manifest, and Azure Blob Storage stores pack data. Compaction nodes compact and garbage collect packs in Blob Storage and update the pack manifest in Ref-CAS.

Spokes routes each request to one of a small group of virtual replicas assigned to that repository. Virtual replicas are a single fleet of disposable compute that serves reads, writes, or both. A virtual replica’s local disk is a cache that can be rebuilt at any time.

Spokes routes a repository’s traffic to the same virtual replicas when it can, which keeps their caches warm and latency low, but nothing about correctness depends on a request landing on any particular virtual replica. When a virtual replica goes away, the repository’s other virtual replicas keep serving, and a replacement fills its cache as traffic arrives.

When a repository gets busy, we add more virtual replicas. Separately, a fleet of compaction nodes works in the background, directly against Blob Storage and Ref-CAS, to merge each repository’s packs and remove unreachable objects. That work never runs on a virtual replica, meaning their CPU and memory can be almost entirely dedicated to serving requests.

Durable state lives in two places:

  1. Git objects, in the form of packs and auxiliary read acceleration data, live in Azure Blob Storage.
  2. References and the list of packs that make up the repository (the pack manifest) live in a separate replicated log service we call Ref-CAS (for “Reference Compare-and-Swap”).

Let’s walk the architecture from the perspective of a write and a read:

  • Write: a virtual replica indexes the incoming pack and uploads it to Blob Storage, then commits one transaction to Ref-CAS that lists the pack in the manifest and updates the references. Later, a compaction node merges that pack with others to keep reads fast.
  • Read: a virtual replica checks its reference version with Ref-CAS, pulls the packs it needs from Blob Storage into its cache, and serves the read from there.

There are many distinct approaches we’ve taken within the new architecture, from the software stack on the virtual replicas to how traffic routing and workload scheduling are tuned for different use cases (e.g., many small repos vs. one large one). Let’s dive deep into two components of the architecture and tell their stories centered on the two design principles.

Minimizing coordination: mutating reference state at high throughput

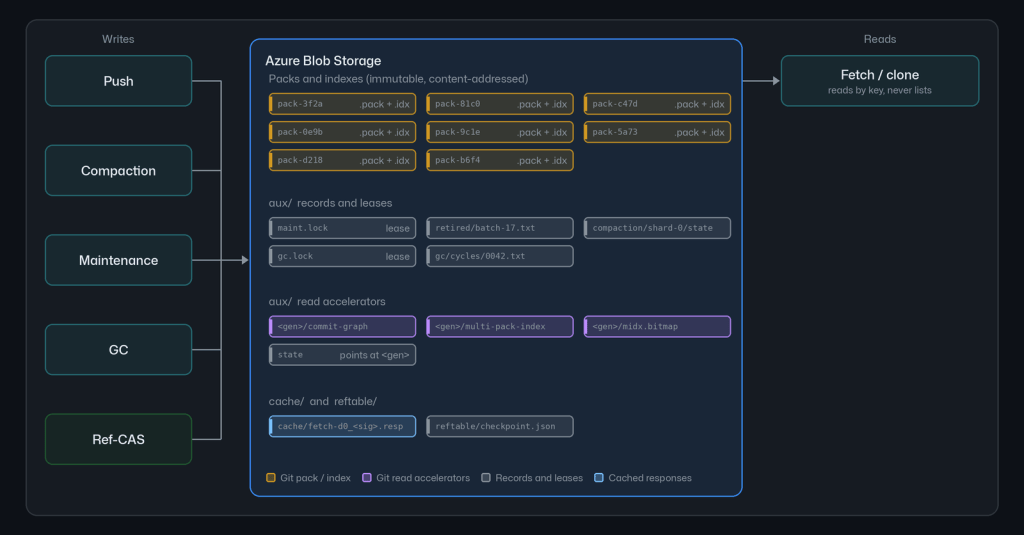
Object storage services like Azure Blob Storage are incredibly good at what they do, and natural fits for many data-heavy applications like source code storage. They are durable and replicated, hold as much as we need them to, have a relatively low cost per byte, and deliver exceptionally high aggregate throughput so long as traffic is spread across many keys. As a result, nearly everything durable in the new Git storage architecture lives in Azure Blob Storage, including:

  • Packs and indexes written by pushes, compaction, and garbage collection.
  • Various read accelerators (like multi-pack indexes, reachability bitmaps, and some custom formats) that our maintenance process builds from those packs.
  • Records that let compaction and garbage collection resume or audit their work, along with the leases that compaction nodes use to claim work.
  • Cached responses for frequently repeated fetches.
  • Checkpoints for the reference state of the repository, though not the authoritative state used to serve requests.
Diagram of one repository's data in Azure Blob Storage. Push, Compaction, Maintenance, GC, and Ref-CAS write into it, and fetches read from it by exact key. It holds packs and indexes, records and leases, read accelerators such as the multi-pack index and reachability bitmap, cached fetch responses, and reference checkpoints.

Most of that data is written once to a distinct key and never changes afterward, which is what makes it highly suitable for Blob Storage.

References are the opposite. A busy repository’s references are a relatively small piece of state that many writes race to update at the same time. That access pattern is harder to serve from Blob Storage, and our first prototypes showed us why. Object storage for this kind of workload is an intuitive choice, and one that works well up to a certain level of scale: conditional writes give a compare-and-swap for free, and the data is already durable and replicated. However, we ran into a difficult set of choices, illustrated below by two approaches we tried.

Our first approach was a write-ahead log for all of a repository’s references, indexed by a single blob. Every update is a conditional write against that blob. It’s correct, and reads are cheap: a virtual replica asks whether the blob has changed, and if it hasn’t, it’s done. Writes are where it falls short. Only one conditional write to a blob can be in flight at a time, so even when we batch every push that arrives during a write into the next one, the repository’s write ceiling is one write per round trip to a single blob. In practice, this netted us write throughput in the mid-hundreds per second.

Our second approach split the references across several segment blobs, with each reference hashing to one of them. Writes to references in different segments no longer wait on each other, which raises the ceiling. But a read now has to check every segment to know whether anything changed, and it’s only as fast as the slowest segment. We’d traded write latency for read latency, and reads outnumber writes by orders of magnitude. We can visualize this by showing multiple writes and a read side by side:

Neither option met every requirement, so we built something else: a replicated log service dedicated to references, or the Ref-CAS service. This is the (small) consensus group we said at the end of the last post was still somewhere in the stack. Here’s how it works.

Each reference update in Ref-CAS is a compare-and-swap committed by a quorum. A transaction locks only the references it touches, checks that each one still has the value the writer expects, and becomes visible once a majority of the log’s replicas have recorded it. Agents mostly push to their own branches, so most updates don’t contend, and they replicate in parallel. When two pushes do update the same reference, only one will append to the log.

Each commit to Ref-CAS gets a log sequence number (LSN), and the repository’s version is the LSN of its latest commit. Reads start with a version check against that version. A virtual replica sends the version of the reference state it already holds. If that version is still current, the reply carries no references at all, and an unchanged repository costs a single comparison. If the virtual replica is behind, it gets back the current references and version, along with pointers to pack data and anything else that needs to be known, such as when the last garbage collection cycle occurred.

Unlike the consensus group in our legacy architecture, Ref-CAS never holds or validates object data. It only stores pointers to it. A virtual replica uploads a push’s pack to Blob Storage before it commits the reference transaction. A reference only ever points at objects that are already durable.

These approaches allow us to transact reference state alone in the tens of thousands of operations per second, and provide a baseline for additional annotations on the replication log that help reads decide what to download for a given request.

But supporting thousands of writes per second on a single repository creates a second-order problem: maintaining the performance of reads and writes. For that, we needed a different approach to compaction.

Decoupling storage from compute: compaction at thousands of writes per second

Every push adds a pack to Blob Storage. Git can serve a repository from many packs, but each additional pack makes lookups slightly more expensive, so the pack count can’t grow without bound. In our legacy architecture, compaction runs on the same replicas that serve traffic, and it has to run on every replica. In the new architecture, it runs entirely in the background on separate nodes, directly against durable storage, using the Ref-CAS service to notify virtual replicas of the evolving state.

Compaction nodes each claim ownership over a subset of the repository’s data via a lease, which allows us to scale compaction horizontally. Here’s how one compaction node works through a single shard of a repository’s packs:

The node first takes a lease on the shard in Blob Storage, so only one node compacts a shard at a time. Meanwhile, virtual replicas keep uploading packs and listing them in the pack manifest. The node reads the manifest to find new packs and collects them into an open segment, which is effectively a holding ground for data about to be compacted. When the segment reaches a defined limit based on pack count, size, or age, it seals the segment so it accepts no new packs, then combines its packs into fewer, larger ones. While compaction happens, the next segment for the shard can begin capturing its input packs. Before anything is published, the node checks that the new packs contain exactly the same objects as the inputs. It then uploads the new packs and adds them to the manifest. A second transaction removes the inputs from the manifest, and cleanup deletes them later.

To scale out, this process runs independently for many shards at once. Each pack’s hash maps to a shard, so adding shards and nodes adds compaction throughput. A compacted pack that’s still under the size limit goes back into a shard by its own hash and merges again, so packs grow in tiers until they reach the limit. The net result is an effectively flat pack count while pushes climb:

Compaction merges packs, but it keeps every object. Garbage collection is the step that removes objects nothing references anymore, like the ones left behind by deleted branches and force-pushes. In our new architecture, garbage collection works very similarly to compaction by using dedicated workers to handle the compute-heavy portion. It also has a few special behaviors for safely removing data, which are worthy of their own discussion.

Using these approaches, we’ve been able to consistently demonstrate a flat latency curve as writes climb, and we have other planned optimizations to make the compaction and garbage collection processes themselves more performant.

What comes next

The two principles we started with let each part of this architecture scale on its own. We scale reads and writes by adding virtual replicas. Ref-CAS orders each reference independently instead of the whole repository. We scale maintenance by adding compaction nodes. Our goal is for every repository, from one developer’s side project to the busiest monorepo, to run on the same architecture with no special handling for the busy ones. Repositories don’t stay small. A side project can pick up a fleet of agents overnight, and it shouldn’t need a migration or special handling from us to keep up. One architecture also means every improvement we make reaches every repository at once.

This foundation lets us do a lot more. We’re focused on three areas next: scaling the architecture beyond what we can predict we’ll need today, making agents more efficient at the work they do on GitHub, and evolving Git itself for agentic development.

Improving the architecture

We have plans to take this architecture further. Each of these improvements lets a repository handle more activity while reducing the work behind each request:

  • Read only what’s needed. Fetch a single object from Blob Storage instead of the whole pack that holds it.
  • Organize packs by type. Group commits, trees, and blobs into their own packs. Many requests then touch less data.
  • Partial replicas. Serve requests without every pack on local disk.
  • Materialized views. Keep repository data in ready-to-use forms, like prepared archives, a near-live shallow copy of the default branch, and agent session context stored alongside each commit.
  • Global replicas. Place replicas in any region, close to the workloads that use them. Reads stay within bounded staleness of the latest write.
  • Scale to zero. Grow and shrink the fleet with the repositories that are actually active.

Efficient agent operations on GitHub

Scaling the infrastructure is one side of supporting agents. The other side is making each agent operation cheaper: fewer bytes to fetch, fewer round trips, and less waiting on changes. Each of these fast-follow items builds on the storage work in this post:

  • Work without a clone. Many agent tasks never need a full working tree. They need a handful of files and enough context to make a change. They can read both straight from the server.
  • Atomic commit API. Land a multi-file change in one operation. The whole change commits, or it’s rejected cleanly on conflict.
  • Event streams. Agents and the systems around them work best with real-time information. A generic event stream lets them subscribe to changes and react as they happen.

Improving Git for agents

We also have work to do in Git itself. GitHub has been a longtime contributor to the Git project, and we’re not stopping now. A few examples of the work we’re excited to continue:

  • Lightweight clones. Partial clone, shallow clone, and sparse checkout each let an agent fetch less. Each one has gaps. They don’t always work well together, either. We want to improve each piece and make them fit.
  • Remove hidden scaling costs. Git still has code paths that slow down much faster than the repository grows. Recent releases fixed several of them, but we expect to find more.
  • Faster history walks. Metadata like the commit-graph can answer merge-base and reachability questions without walking every commit. That matters most when an agent’s API call turns into Git work on the server.
  • Avoid common gotchas. Agents make the same mistakes developers do. Git can catch more of the common ones and warn before they cause damage.

Agents have changed how software gets built. GitHub and Git are changing with it. We’re excited to take this new architecture across the starting line. It’s available in a limited private preview now, with a broader rollout early next year. We can’t wait to see what teams build when the number of agents working on a repository is limited by their ideas. We’ll keep evolving Git and GitHub alongside our customers and the Git community.

The post Inside GitHub’s new Git storage architecture appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
23 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

LangGraph After the Crash: Checkpoints, Pending Writes and Recovery

1 Share
Read the whole story
alvinashcraft
30 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

AutoMapper 16.3.0 and 15.1.4 Released with Security Fixes

1 Share

Today I pushed out AutoMapper 16.3.0 and 15.1.4. Both releases fix two security issues, so if you're on either 16.x or 15.x, you should upgrade.

Security

Back in March, 16.1.1 fixed a denial of service issue where mapping a deeply nested, self-referential object graph could exhaust the stack (GHSA-rvv3-g6hj-g44x). The fix applied a default MaxDepth of 64 to self-referential maps, and setting MaxDepth yourself was the recommended mitigation.

It turned out that several mapping paths still didn't enforce MaxDepth. Mapping deeply nested data through any of them could still throw a StackOverflowException. You can't catch that exception, so it takes down the whole process.

Constructor parameters (GHSA-6vhm-j9h7-f9gh). When the destination is built through its constructor, as with positional records, MaxDepth was ignored completely. That held for both the default and an explicit value. Thanks to @mcambria, who found it while writing a test to confirm the MaxDepth mitigation actually worked, and reported it responsibly.

Other recursion paths (GHSA-gpwp-5797-mjff). While investigating that report, we went looking for other ways around MaxDepth and found a few:

  • derived maps (Include / IncludeBase) didn't inherit MaxDepth
  • members typed as object or an interface didn't get the default limit
  • nested Dictionary<string, object> and ExpandoObject sources weren't depth-tracked at all
  • recursive ConvertUsing ignored MaxDepth

With these releases, derived maps inherit MaxDepth and get the default limit. Recursion that MaxDepth can't bound now fails with an InsufficientExecutionStackException instead of crashing the process.

That last part is a behavior change. If you map extremely deep graphs through those paths, you'll now get an exception where before you'd have gotten a process crash. I'll take a catchable exception over a dead process any day. Polymorphic graphs are also now cut off at the base map's MaxDepth, so if yours legitimately go deeper than 64 levels, set MaxDepth explicitly.

Applications that map untrusted, deeply nested input through these paths are the ones at risk. See the advisories for full details and workarounds.

Other fixes in 16.3.0

16.3.0 also picks up everything that's landed since 16.2.0:

  • a fix for Context.Items are only available... exceptions with self-referential maps, which depended on registration or warmup order (also backported to 15.1.4)
  • a 30-day renewal grace period for license keys, which logs a warning instead of an error
  • clearer license validation messages for malformed keys and IdentityModel version mismatches
  • Condition on ForAllMembers now receives the source member value rather than the converted one when the types differ, matching the documented behavior. A null in a nullable source member now shows up as null instead of 0 or false. This is a behavior change, so check any conditions that relied on
    the old value.

Release notes:

NuGet:

Enjoy!

Read the whole story
alvinashcraft
42 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

A database is a store for global variables

1 Share

Databases are for storing global variables. We usually call them “rows” or “records” instead, but they’re definitionally global variables: any part of your program can read or write them. Isn’t this kind of weird? It’s common programming advice that global variables are bad, and yet many elegant programs rely on databases. Either the common advice is wrong, or there’s something special about databases that makes them the exception to the rule.

What’s so bad about global variables? Here’s the two main1 reasons, in my view:

  • They allow any part of your program to implicitly send data to any other part instead of passing it around via function signatures
  • They couple different parts of your program: if one part depends on a variable having some value, any other part can break it

Both of these apply to databases. Any part of your program that makes a query can send and receive data from any other part of your program. In practice this happens all the time: one function will save some data on a record, and another one will check for it. And if you haven’t seen bugs where some piece of code makes some incorrect expectation about the shape2 of a database column, you haven’t been working on web systems for long enough.

So why aren’t database-backed apps in terrible architectural shape? In the rest of this post I’ll consider some options.

First, we could bite the bullet: maybe all database-backed apps really are a mess. This is surprisingly plausible. When I think about the systems I’ve worked on that haven’t involved a database, they’re usually much cleaner and more elegant. If managing state is the hardest thing about designing software — and I think it is — then systems that manage less state are going to be better-designed. However, this doesn’t explain everything. Database-backed apps aren’t that bad, and even in database-backed apps, we try to avoid introducing regular global variables3, so in practice we treat global variables as worse.

Second, we could say that databases offer ACID guarantees that mitigate the damage of global variables. Unlike regular global variables, databases offer a consistent view of state and the ability to atomically change multiple pieces of state together. I don’t really buy this. The problem with global variables is not just that they can get out of sync, it’s that they exist at all. If you think this is the difference, you are committed to thinking4 that if you stick a mutex around a global variable then it suddenly becomes acceptable.

Third, we could say that databases are more explicit. Mutating or reading a global variable looks like ordinary code, but database queries need some connection object to be passed in and some query function to be invoked. When you’re scanning through code, you can see where the database queries are at a glance5. Not so for global variables. This does actually kind of mitigate the implicit-coupling problem. Maybe regular global variables would be better if you had to set and get them with long, involved function calls.

Fourth, we could say that databases are less flexible. A global variable could store anything: a function, a class, an image, and so on. A database just stores data. I can buy this explanation for untyped languages. Global Ruby variables that could be reassigned from a string to a hash table are far more terrifying than a “global” database column that could change from one string to another string. But since the advice to avoid global variables applies to typed languages as well, I don’t think this could be the reason why databases are better.

Fifth, we could say that we know how to use databases. For instance, whenever I read from a database, I reflexively check the type of the column so that my code doesn’t make assumptions that aren’t guaranteed by the database. There are use-cases that I would never even consider using a database for (e.g. to track a counter in a loop, or to store the name of the .env file where my config is stored). In other words, we have norms and customs6 around using databases that minimize a lot of the damage that global variables can cause. There’s nothing inherent about databases that make them better, it’s just how we use them in practice.

Overall I think the third and fifth reasons are most convincing: databases are better because they’re more explicit and because we only tend to use them for a limited set of purposes. It’s interesting to note that these reasons are contingent, not inherent. A codebase which had conventions around global variable use7 could also fulfil these conditions. Would this make global variables fine, or at least no worse than a database? I think so.

I don’t recommend you go out and start putting global variables in your programs. It’s more interesting to note the meta-point here: that two pieces of common software engineering dogma — avoid global variables and use a database for state — are partially inconsistent. Most software design knowledge is still just a pile of loose heuristics. I don’t really know how to build software and you don’t either. As I’ve written about before, we should therefore all be very suspicious of engineers who appeal to “best practice” without being able to give concrete reasons, even in cases as obvious as “global variables are bad”.


  1. For instance, concerns about readability and tracing follow from the first reason. I don’t really buy reasons like “it’s not thread-safe” or “global variables might shadow local variables”: any architectural problem that can be trivially solved with a mutex or a linter is not a real problem.

    ↩
  2. For instance, that a string supports 4-byte UTF-8, or that a column can/can’t be NULL.

    ↩
  3. You could say we avoid introducing global variables because databases are essential and global variables are not. In theory you could replace any global variable by threading a local variable through, but you do need a database if you’ve got gigabytes of structured data to manage. However, that doesn’t explain why database-backed apps still tend to be better-designed than apps with many global variables.

    ↩
  4. I’m not saying this is necessarily wrong. The argument would go something like “well, if you implement a simple in-memory database for your global variables, that is better!”

    ↩
  5. This is only sort of true. If you’re designing a system, you’d be well-advised to make it as true as you can. While I love Rails, my main beef with ActiveRecord is that it makes queries invisible.

    ↩
  6. To be fair, some of these are guaranteed by the fact that the database exists over the network.

    ↩
  7. Plus types, probably, and concurrency controls if we’re not in a single-threaded language.

    ↩
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Help Shape the Future of .NET: Take the 2026 .NET Developer Survey

1 Share

It’s that time of the year! The 2026 .NET Developer Survey is open, and we’d love to hear about your experience. The survey takes about 15 minutes to complete, and your feedback helps the .NET team understand where to invest next.

As a thank you for your time, eligible U.S. residents who complete the survey and leave their email address at the end can enter for a chance to win .NET swag!

Your feedback helps us build a better .NET

We want to understand what it’s like to use .NET in your everyday work. Where does it make things easier? What’s harder than it should be?

Your answers help us understand how you use .NET and what would make it work better for you. Hearing from more developers helps us see which challenges are widely shared, including ones that might not come up in GitHub issues or community conversations.

You don’t need to be using the latest release to contribute. Maintaining an older application is just as much a part of .NET development as starting a new project, and we want that experience reflected in the feedback.

A thank you for participating

Eligible U.S. residents can enter a sweepstakes for a chance to win one of 10 .NET branded swag packages, each with an approximate retail value of $15 USD. To enter, complete the survey and provide your email address when prompted at the end. Ten winners will be selected at random and notified at the email address they provided.

The survey welcomes developers worldwide. Entering the sweepstakes is optional.

Thanks for sharing your feedback, and please pass the survey link along to other .NET developers, especially those who might not otherwise see it.

No purchase is necessary to enter the sweepstakes. Only open to residents of the United States and Puerto Rico ages 18 and older at the time of submission. Survey closes and sweepstakes ends November 16, 2026 at 5 p.m. PST.

The post Help Shape the Future of .NET: Take the 2026 .NET Developer Survey appeared first on .NET Blog.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories