 Log in

Nvidia’s C.E.O., Jensen Huang, admitted to having an affair with a suspected Chinese corporate spy. Everything that means for him and the A.I. industry, and what happens next.

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


Rajveer Prasad: The Agile Team That Turned Overtime Into a Quality Problem
Read the full Show Notes and search through the world's largest audio library on Agile and Scrum directly on the Scrum Master Toolbox Podcast website: http://bit.ly/SMTP_ShowNotes.
"Working harder and working longer is not helping anyone. It's just making what we do more difficult and complex." - Rajveer Prasad
Rajveer worked with a retail organization moving into SAP HANA, with teams spread across geographies and cultures. The team wanted to help, so they worked evenings, weekends, and extra hours to keep commitments alive. At first, the organization did not demand that behavior, but once it became visible, it became the new normal. The downstream effect was predictable: bad planning, overcommitment, reduced testing, skipped regression, failed integrations, rework, and a rising defect rate. Rajveer gathered data to show the cause and effect, then worked first with leadership because expectations had already been formed outside the team. Once stakeholders understood that the "faster" approach was degrading quality, Rajveer brought the data to the team and created a stricter operating routine. The team needed slack, a five-day working rhythm, and permission to say no so they could improve quality instead of competing against themselves.
In this segment, we talk about SAP HANA, technical debt, and sustainable pace.
Self-reflection Question: Where is your team using extra hours to hide a planning or quality problem?
Featured Book of the Week: The Goal by Eliyahu M. Goldratt
Rajveer has read and listened to The Goal by Eliyahu M. Goldratt many times, and each pass gives him a new angle on bottlenecks, flow, and the theory of constraints. For him, the book is foundational because it teaches Scrum Masters to look beyond local effort and see how the system shapes outcomes. As Rajveer puts it, "Every time I'm going through the book, I'm thinking slightly different."
[The Scrum Master Toolbox Podcast Recommends]
🔥In the ruthless world of fintech, success isn't just about innovation—it's about coaching!🔥
Angela thought she was just there to coach a team. But now, she's caught in the middle of a corporate espionage drama that could make or break the future of digital banking. Can she help the team regain their mojo and outwit their rivals, or will the competition crush their ambitions? As alliances shift and the pressure builds, one thing becomes clear: this isn't just about the product—it's about the people.
🚨 Will Angela's coaching be enough? Find out in Shift: From Product to People—the gripping story of high-stakes innovation and corporate intrigue.
[The Scrum Master Toolbox Podcast Recommends]
About Rajveer Prasad
Our guest today is Rajveer Prasad, founder of OAKKTREEUNII. He's spent years helping aspiring and working project managers and Scrum Masters break into IT delivery — and grow once they're there — through real projects, real interview prep, and real accountability. He's mentored hundreds through career changes most people call impossible. Welcome, Rajveer
You can link with Rajveer Prasad on LinkedIn.
Download audio: https://traffic.libsyn.com/secure/scrummastertoolbox/20261110_Rajveer_Prasad_Tue.mp3?dest-id=246429
Pennsylvania, USA


Our fast_float library parses numbers such as -731.51 into binary floating-point values. It is part of GCC’s C++ standard library, among others. It is fast: often a few nanoseconds per number.
Parsing a number means making decisions. Is there a sign? How many digits are there? Where is the decimal point? Is the processor rounding in the default mode? Each decision is a branch in the code. Modern processors do not wait to know the outcome of a branch: they guess, and they keep working. When they guess right, the branch is nearly free. When they guess wrong, they throw away the work done since the branch, and that costs 15 to 20 cycles.
When all your numbers look alike, the processor guesses right. When they do not, it guesses wrong often. Consider a column of gains and losses: the sign is random. The processor cannot guess it, and it pays for its mistakes on about half of the numbers.
You often know things about your data that the parser cannot know. So we are adding performance hints to fast_float. You pass them as a template argument:
using fast_float::performance_hints;
double value;
auto answer = fast_float::from_chars<performance_hints::unpredictable_sign>(
    input.data(), input.data() + input.size(), value);
There are three hints, and you may combine them with |:
unpredictable_sign: the signs come in random order. The parser then handles the sign without a branch.short_numbers: each number is given alone (the range holds just the number) and most numbers have at most 8 characters, such as42.5or-3.75, in varying shapes. The parser then reads all 8 characters at once with a few bitwise operations, without a branch on the number of digits or the position of the decimal point.assume_round_to_nearest: your program never changes the rounding mode, so the parser does not check it.
The hints never change the results, with one exception. If you promise assume_round_to_nearest and some code in your program changes the rounding mode, some results will be wrong.
The hints work with fast_float::from_chars, fast_float::from_chars_advanced and fast_float::integer_times_pow10. Without hints, nothing changes.
How much do they help? I generated four kinds of data, 100,000 numbers each:
- price changes, two decimals and random signs, such as
-731.51or42.07; - account balances, two decimals and random signs, but longer, such as
-731271.51; - sensor readings, all positive, but in varying shapes, such as
7,1042,42.5and0.375; - regular prices, always the same shape, such as
12.34.
I parse them on an Intel Xeon Gold 6338 (Ice Lake) with GCC 15, and on an Apple M4 Max with Apple clang 17. I report millions of numbers parsed per second: higher is better.
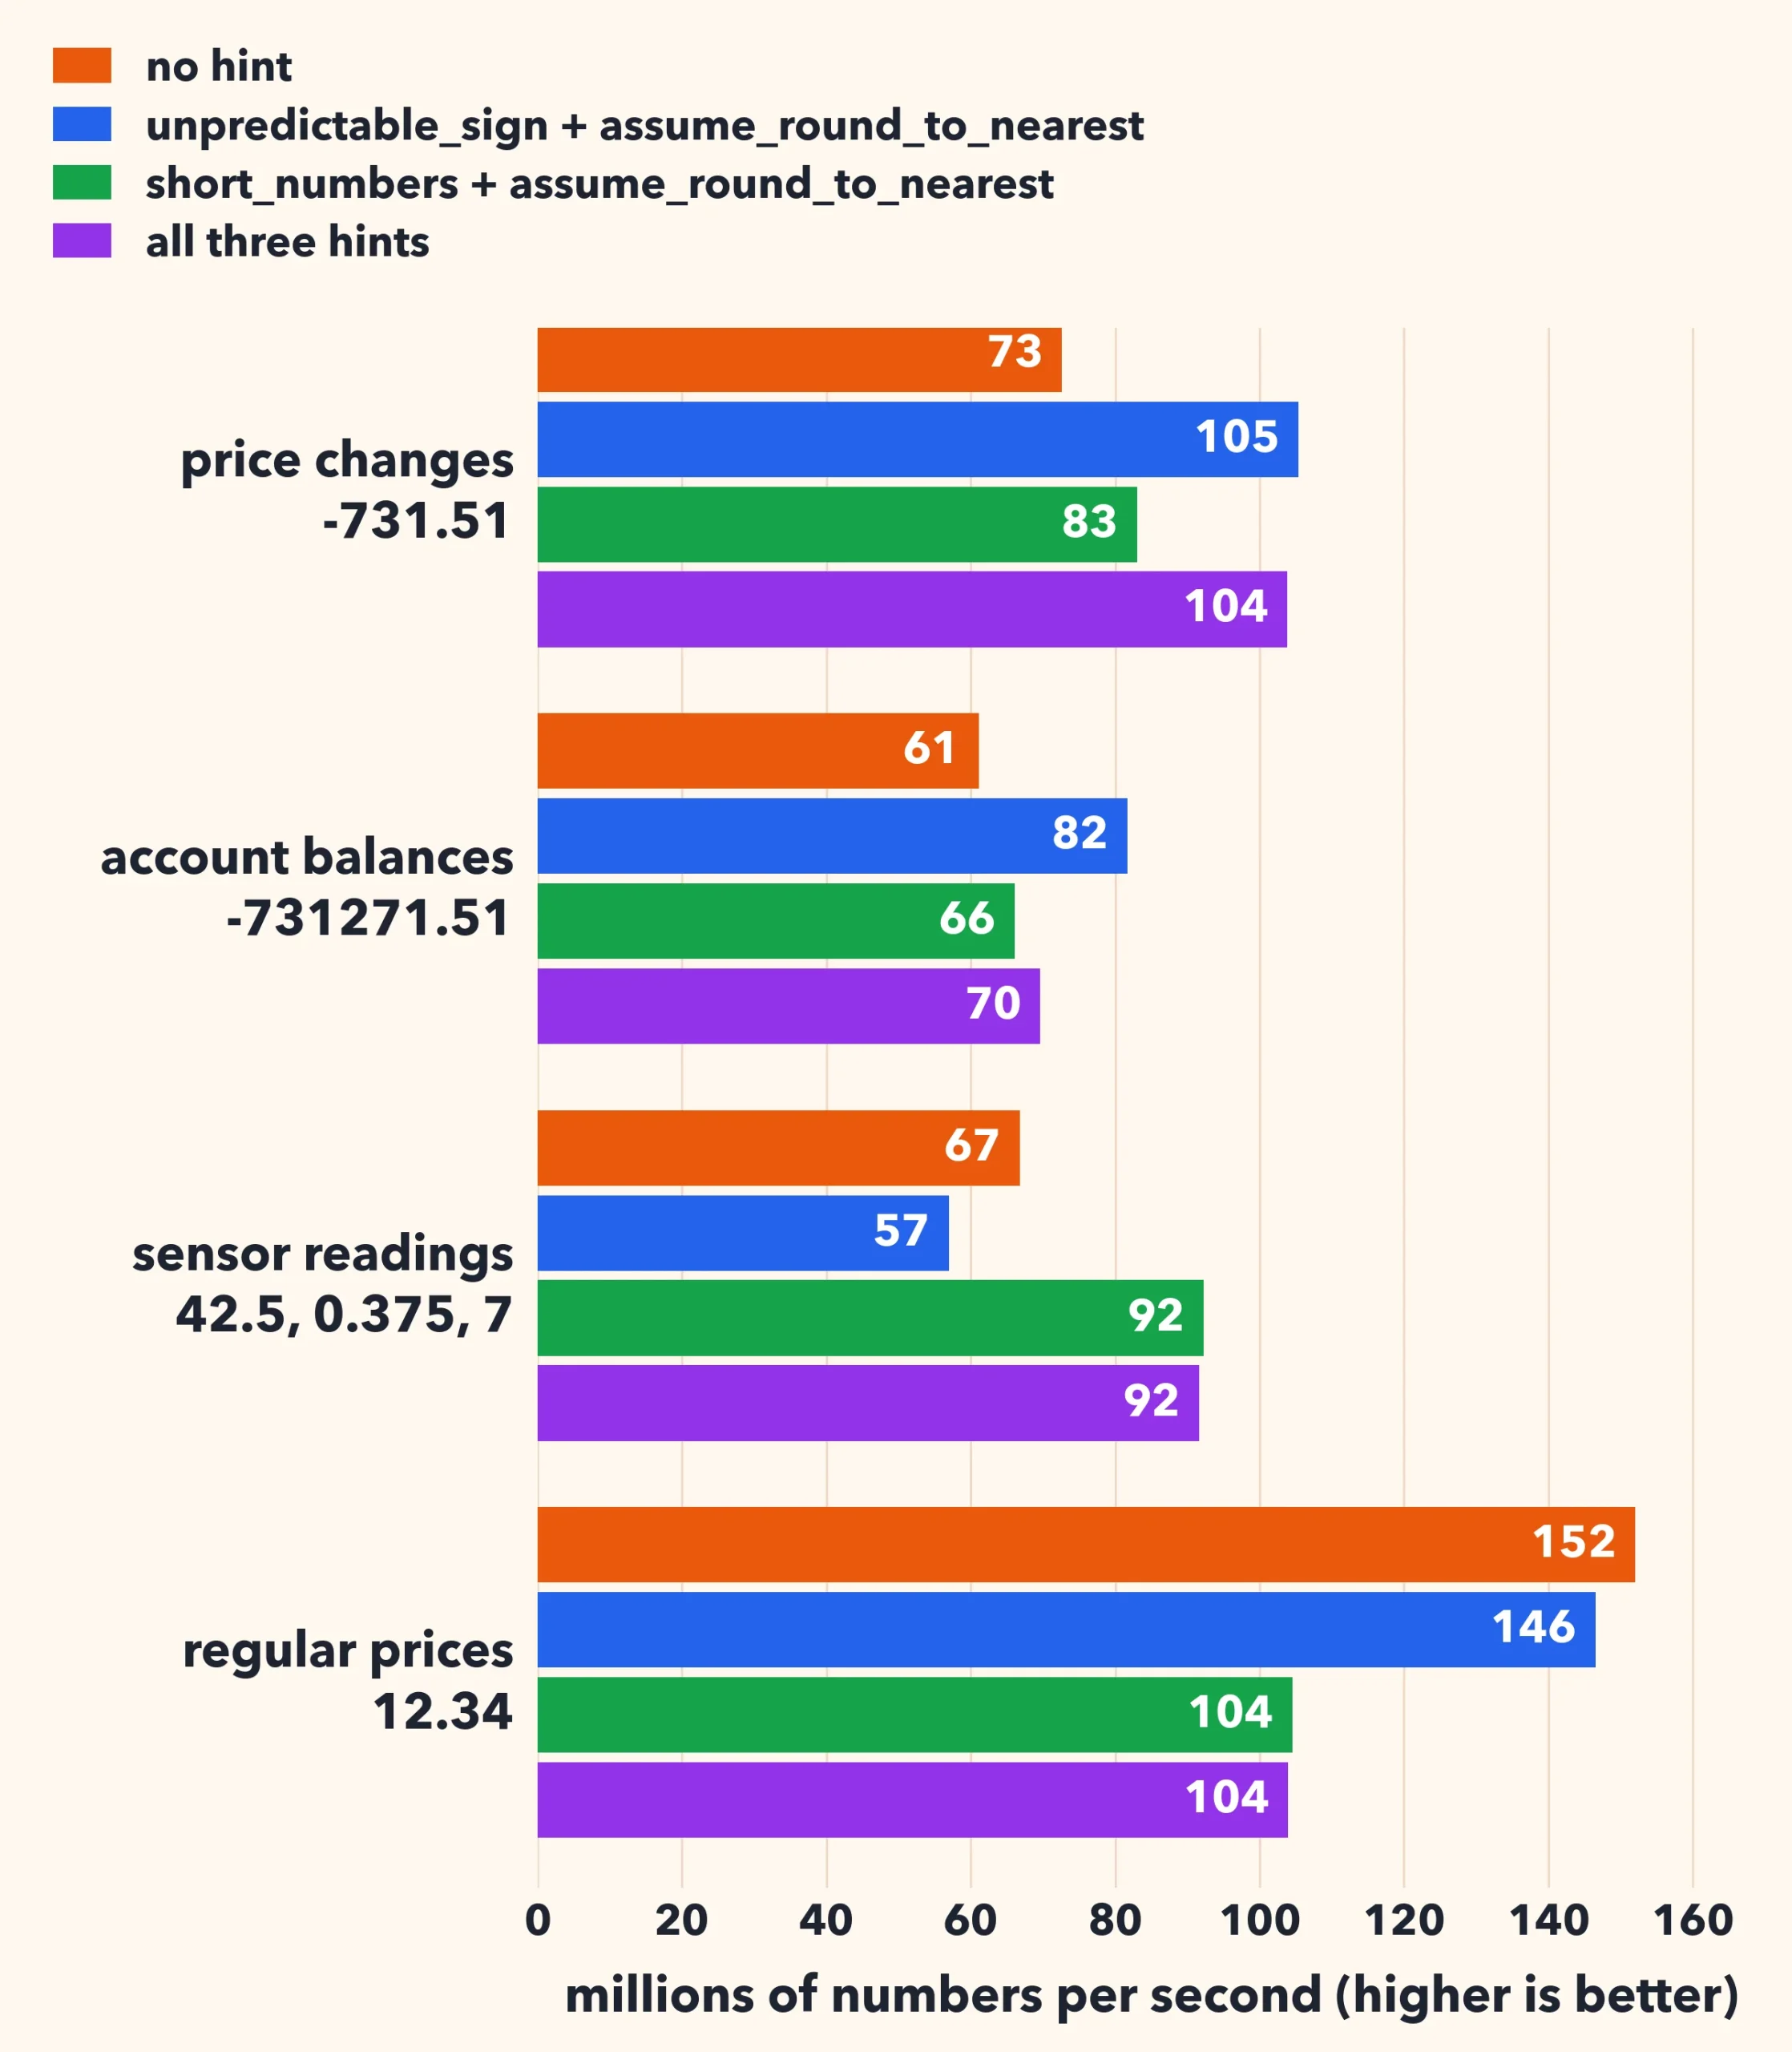
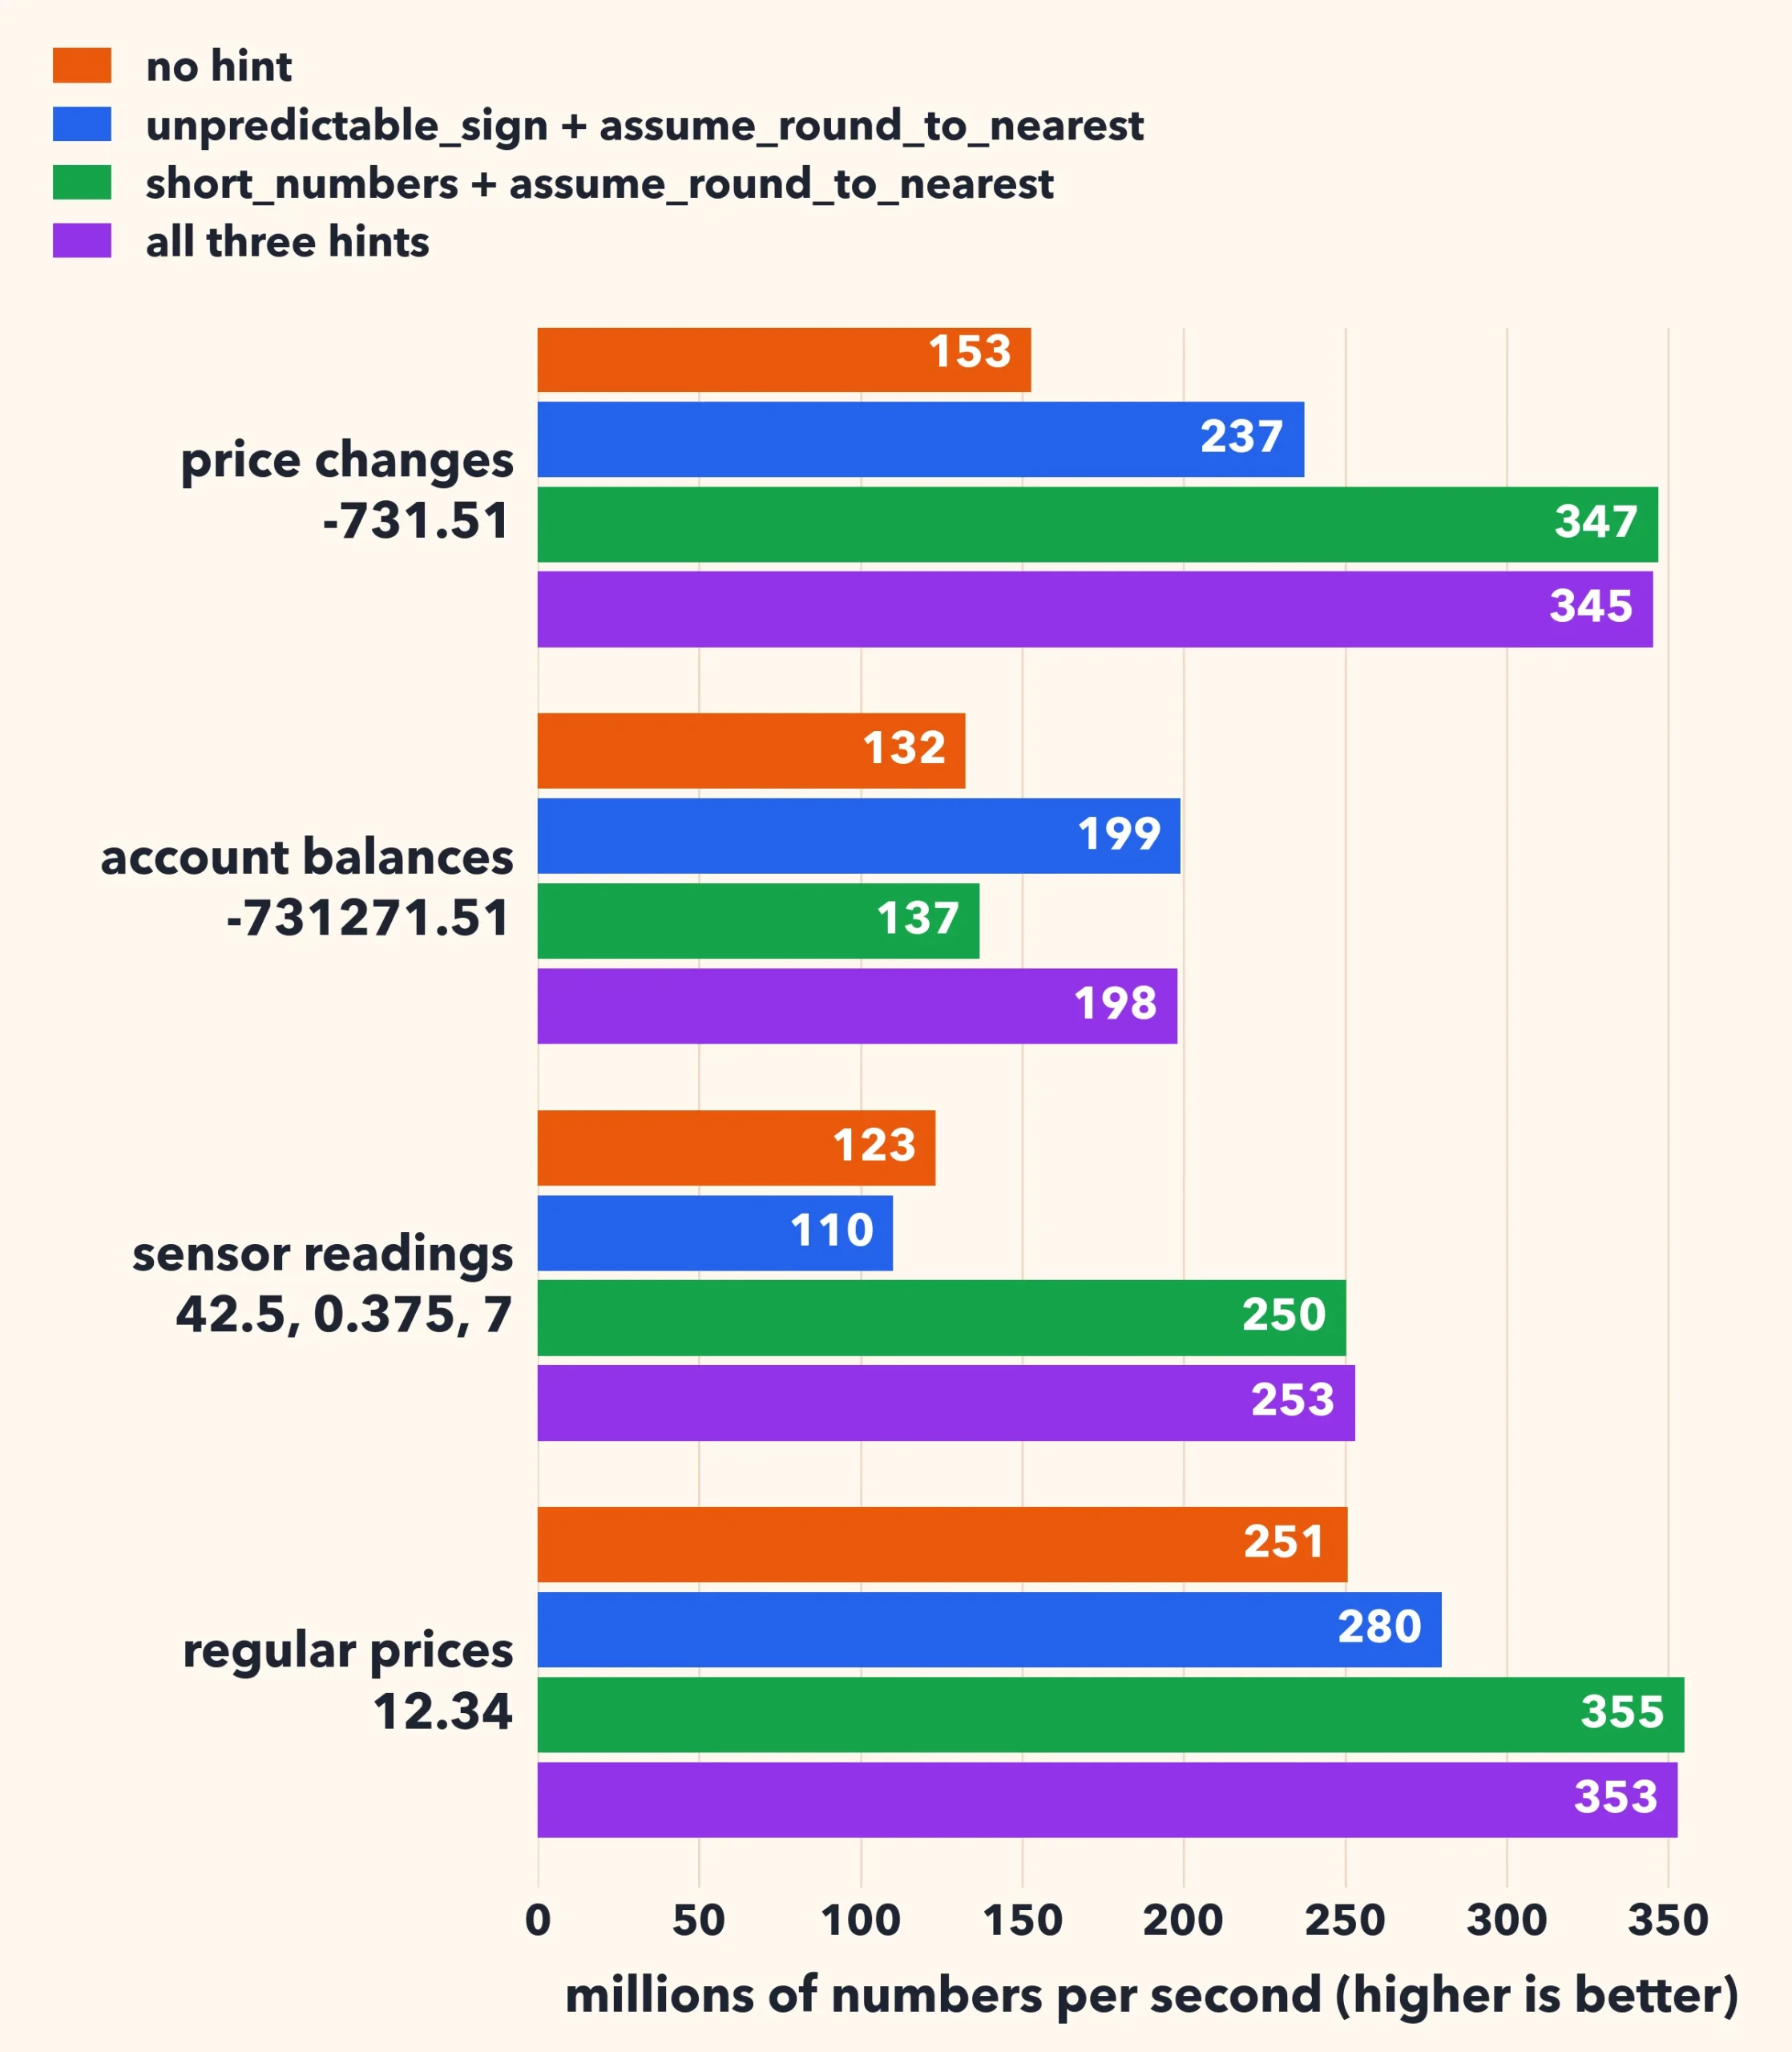
Each kind of data has its own best combination.
Price changes have random signs and short numbers. On the Intel processor, adding unpredictable_sign and assume_round_to_nearest goes from 73 to 105 million numbers per second. All three hints do as well (104 million), and they are best on the Apple processor, going from 153 to 345 million numbers per second: more than twice as fast. Without hints, the Intel processor mispredicts a branch on 60% of the numbers. With all three hints, the mispredictions disappear.
Account balances also have random signs, but the numbers are too long for short_numbers. Here unpredictable_sign with assume_round_to_nearest is the right choice: from 61 to 82 million numbers per second on the Intel processor, and from 132 to 199 million on the Apple processor. Adding short_numbers makes things worse on the Intel processor (70 million): the hint does not apply to these numbers, yet we pay for it.
Sensor readings have no sign, but their shapes vary. Here short_numbers is the key: from 67 to 92 million numbers per second on the Intel processor, and from 123 to 250 million on the Apple processor. The hint unpredictable_sign is harmful: there is no sign to predict, and the branch-free code is more work. On the Intel processor, it goes down to 57 million.
Regular prices are the easy case: all positive, always the same shape. The processor guesses everything right. On the Intel processor, the best choice is no hint at all (152 million numbers per second), and short_numbers makes things much slower (104 million). The Apple processor is different: short_numbers still helps, from 251 to 355 million numbers per second.
With Clang 21 on the Intel processor, the results are similar: the same hints win on the same data.
So the hints are not free. They trade branches, which are cheap when the processor guesses right, for more instructions. They pay off when the processor would guess wrong.
The hints are currently in a pull request.
Pennsylvania, USA
This blog post is originally published on https://blog.elmah.io/mcp-server-vs-rest-api-when-should-you-use-each/
REST APIs have long been the default way for applications to expose functionality, but AI agents change how clients discover and use it. The Model Context Protocol (MCP) gives agents a standardized way to find and call external tools and services, which makes it easy to confuse with REST. This post covers how the two differ and when to choose each.
What is a REST API
REST (Representational State Transfer), RESTful APIs or RESTful web APIs are application programming interfaces (API) that follow REST architectural constraints for communication between client and server. In a REST API, each endpoint performs a specific operation using standard HTTP methods (GET, POST, PUT, DELETE). A typical interaction includes the client sending a request, the server responding at the designated endpoint route, and the connection closing.
Key characteristics of REST API
REST APIs are built on the REST principles and have the following characteristics.
Statelessness
One defining property of a REST API is statelessness, in which each request must include all the information needed to process it. As a result, servers do not need server-side sessions or data related to the client request.
Uniform Interface
Resources reside at the same address (URI) and their representations have a consistent format. Any client, such as a web front end or mobile app, interacts with the API through a uniform interface. Responses use a universally supported format, predominantly JSON, that any consumer can interpret.
Predictable nature
In the REST API, the same input produces the same output. Calling the API with a filter returns the same response every time for the same data state. This behavior matters for compliance and auditing for regulated industries where data auditability is required.
Client-Server Decoupling
In a REST API design, the client and server are independent. The client knows the URI of each resource, which is the only way to interact with the server. Similarly, the server application must pass the requested data to the client and should not change anything on the client.
Cacheability
REST APIs support caching to store data in client- or server-side caches. Caching provides a performance edge over calling endpoints repeatedly or re-executing methods.
Layered System Architecture
In REST APIs, requests and responses pass through different layers. Calls and responses don't connect directly; several intermediaries are involved in the communication loop.
Where REST API offers advantages
REST APIs are general-purpose communication solutions between clients and servers. Any client, whether a web application, mobile app or a microservice, can use another system's functionality or data. It has maturity of 20-odd years and several tools built around it: OpenAPI specifications, Swagger UI, Scalar UI, CDNs, and rate limiters. REST API provides common ground for business integration, where two companies can use each other's facilities, like a weather API, Twilio messaging, and LLM prompting. All of these are easier because REST APIs have a deterministic, universal structure for requests and responses. You know the URL, have an API key for authorization, and you're done integrating in one go.
For traditional applications, a REST API is ideal. Developers know the endpoints to use on the client. Endpoints are an abstraction of the server. Both sides use the documentation to understand each other, so there's no need to dig into details and complexity. A mobile developer doesn't need to know how tables are normalized, what logic is in the code, or which ORM the server uses.
Traditional systems also benefit from their architecture, which supports HTTP caching, content delivery networks, load balancers, and API gateways for REST. You get low latency and high throughput due to its architecture, lightweight JSON data format, and caching ability.
What does REST API lack?
As LLM-powered agents rise, traditional applications fall short. All the data transfer that has been done via REST API for decades does not match the new kind of user. By design, REST APIs serve human developers who hardcode endpoints in the client. However, agents are different clients, bringing the following gaps.
Limited runtime discoverability
REST endpoints do not tell users what they do. We have an OpenAPI specification, but it is static and does not offer LLMs the ability to discover descriptions at runtime. OpenAPI is basically an API description/documentation format rather than a runtime interaction mechanism.
Limited support for multi-turn interactions
There is no standard REST mechanism for an API to suspend an operation and request additional user input or approval as part of the same protocol interaction. Applications can implement such workflows themselves, but that requires additional application-level logic.
Inconsistent integration patterns across APIs
Different APIs expose different endpoint structures. Authentication, parameter formats, endpoint naming, pagination, error formats, filtering, naming, and workflows vary application to application. Humans know them from documentation and handle them manually. However, automated consumers have to rely on individual adapters' own assumptions and edge cases for every API they use. This complexity grows when an agent needs to work across many services.
High context and tool-definition overhead
REST API principles are designed for composability and discoverability for humans. Usually, APIs have atomic endpoints, and developers combine them for a task. Integration and iteration are cheap and deterministic as developers do this. This overwhelms AI agents, which pay a token cost for every tool definition. The issue isn't that REST is badly designed for models. It's that traditional REST APIs were designed around application-to-application interaction, while LLM agents have additional context and reasoning constraints.
What is MCP
Model Context Protocol is an open-source standard introduced by Anthropic in 2024 that connects AI applications to external data sources, tools, and workflows. MCP is to AI applications what USB-C is to laptops. A laptop with USB-C ports can connect to any peripheral (monitors, drives, power supplies) regardless of manufacturer, because they all share a common standard. Similarly, AI chatbots like Claude, Gemini and ChatGPT, development assistants like Visual Studio Code, Cursor, Windsurf, Claude Code and many others support MCP, enabling build once and integrate everywhere.
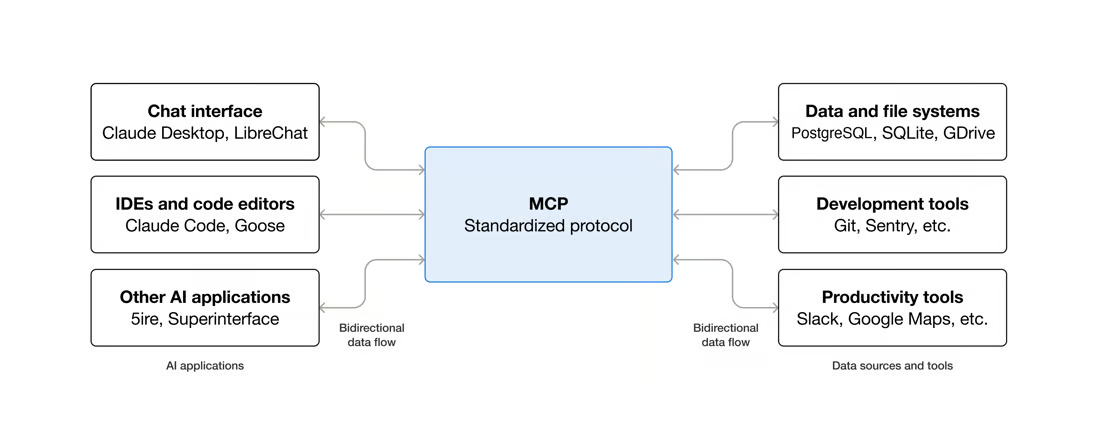
Key characteristics of MCP
MCP defines a standardized protocol for AI applications to interact with external systems with the characteristics listed below.
Standardized primitives
MCP servers expose three primary types of capabilities:
- Tools are executable functions that an AI application can invoke. A tool can perform an operation, query data, call an external service, or trigger an action. A tool contains definition including a name, description, and parameters it accepts.
- Resources provide data or contextual information to an AI application. They can represent files, database content, documents, or other information that a server makes available to clients.
- Prompts are predefined reusable prompt templates that servers can provide to guide interactions with the AI model.
An MCP server may or may not expose all three independent primitives. It can provide only the capabilities its use case requires.
Runtime capability discovery
MCP provides standardized methods for clients to discover the capabilities exposed by a server. For example, a client can call the tools/list to retrieve a list of the tools available from an MCP server.
Consider the example below where a tool definition has its name, description, required validation and JSON Schema describing its input parameters.
{
  "name": "get_weather",
  "description": "Get current weather information for a location",
  "inputSchema": {
    "type": "object",
    "properties": {
      "location": {
        "type": "string",
        "description": "City name or coordinates"
      }
    },
    "required": ["location"]
  }
}
The same discovery model applies to resources and prompts through resources/list and prompts/list. This lets clients obtain a machine-readable description of the capabilities the server exposes at runtime.
Structured tool invocation
After discovering a tool, an MCP client can invoke it using the standardized tools/call operation. The client supplies the tool name and the arguments defined by the tool's input schema.
For example, an MCP server could expose a create_support_ticket tool. The AI client provides structured arguments such as the customer's ID, issue description, and priority. The server validates the request, creates the ticket in the underlying system, and returns the result through the MCP protocol.
MCP defines how tools are exposed and invoked, not how they work internally. A tool can query a database, call an API, execute application code such as a .NET method, or interact with another external service.
Resources and contextual data
Resources provide a standardized way for MCP servers to expose information to clients. A resource can represent content such as a document, file, database record, or other application data.
Resources are identified by URIs and can provide structured or unstructured content. Clients can discover available resources and retrieve their contents through the MCP protocol.
Stateful sessions
MCP supports stateful client-server sessions. During initialization, the client and server negotiate protocol versions and capabilities before normal interactions begin.
A session can then contain multiple protocol interactions, allowing the client and server to maintain protocol-level state throughout the connection. MCP also defines lifecycle messages, notifications, and capability negotiation as part of the session model. Sessions maintain context across multiple tool calls within a workflow.
Human-in-the-loop interactions
MCP defines interaction mechanisms that allow servers to request additional information or authorization from the client when required.
For example, a server can request user input through an elicitation interaction, or a client can be asked to obtain authorization before a sensitive operation proceeds. These mechanisms allow MCP interactions to include additional steps rather than being limited to a single request followed immediately by a final result. Human involvement is a recommended approach when a workflow is done by an AI.
Standardized protocol communication
MCP uses JSON-RPC 2.0 for messages exchanged between clients and servers. The protocol defines standardized requests, responses, and notifications for operations such as initialization, capability discovery, tool invocation, and resource access.
This provides a common communication model for MCP clients and servers while leaving the implementation of the underlying business logic to the server.
Where MCP offers advantages
MCP offers the following advantages for AI stack.
Reduced integration maintenance
An MCP server provides a standardized interface for exposing capabilities to compatible AI clients. Any changes in the tools or resources are handled on the server side. MCP requires less work in maintenance. You have to build once, and it is compatible with all AI agent clients. For example, an organization can change how a search_customer tool retrieves its data without changing the tool's interface used by the AI application, provided the published contract remains compatible. So you need no changes on the client side.
Adaptive task execution
MCP allows AI applications to discover available tools and their input schemas. The application can access structured information about the operations it can use. This information allows an application to select tools based on the task at hand, rather than requiring every possible workflow to be explicitly encoded in application logic.
For example, a customer says "my order never arrived." The agent decides it needs order status, shipping-carrier tracking, and the refund policy. Each piece of information may require different endpoint calls or have different parameters. It pulls those, then either explains the delay, issues a replacement, or escalates to a human if the case is unusual.
More focused information for models
MCP tools can return results specifically shaped for the task an AI application is performing. A tool does not have to expose the complete response produced by an underlying system, its implementation can retrieve, filter, transform, and format the information before returning it. This can reduce the irrelevant information the model needs to process.
MCP vs. REST APIs: Distinctions
Architectural Differences
The difference starts from the core architecture between the two.
| Dimension | REST API | MCP |
|---|---|---|
| Protocol | HTTP-based API using methods such as GET, POST, PUT, and DELETE |
JSON-RPC 2.0-based protocol for MCP interactions |
| Primary abstraction | Resources and HTTP endpoints | Tools, resources, and prompts |
| Capability discovery | Commonly described through OpenAPI or other documentation | Runtime discovery through MCP protocol operations such as tools/list and resources/list |
| Schema | OpenAPI can describe request and response schemas | Tool definitions use JSON Schema for their inputs |
| Communication | Requests sent to resource-oriented URLs | Requests sent as protocol methods such as tools/call |
| Lifecycle | HTTP request/response model | Protocol-defined lifecycle and capability negotiation; the 2026-07-28 revision uses a stateless request model |
| Underlying systems | Can directly expose application and data operations | Can expose capabilities backed by databases, APIs, files, services, or application logic |
Interaction Differences
| Step | REST API | MCP |
|---|---|---|
| 1. Determine available operations | Client uses known API endpoints and documentation/schema | Client can discover capabilities exposed by the server |
| 2. Select operation | Application code determines which endpoint to call | AI application can select an available tool based on the task |
| 3. Construct request | Application constructs the HTTP request and payload | Client invokes the MCP operation with structured arguments |
| 4. Process result | Application handles the HTTP response | Client processes the tool/resource result |
| 5. Next operation | Application code determines the next request | AI application can use the result as context for subsequent tool selection |
The difference lies in where the decision about available capabilities and the next operation can be made: REST clients commonly encode this logic in application code, while MCP provides protocol mechanisms for exposing capabilities that an AI application can discover and invoke.
Discovery Mechanisms
| REST API | MCP | |
|---|---|---|
| Typical mechanism | API documentation, OpenAPI, SDKs, or other descriptions | MCP discovery operations |
| When discovered | Often during development or client configuration | Can be discovered at runtime |
| What is discovered | Endpoints, operations, parameters, schemas | Tools, resources, prompts, and their associated metadata |
| Example | OpenAPI describes GET /customers/{id} |
tools/list returns available tool definitions |
| Client behavior | Client/application is generally built around known API operations | AI application can inspect available capabilities before selecting a tool |
Performance Trade-offs
Different architectures and working mechanisms also have distinct performance characteristics. Consider the table
| Dimension | REST API | MCP |
|---|---|---|
| Protocol overhead | HTTP request/response overhead | MCP adds protocol-level message handling on top of its transport |
| Single operation | Can be very direct when the client already knows the endpoint | Includes MCP protocol processing and tool invocation |
| Discovery overhead | Depends on how API documentation/schema is obtained | Capability discovery introduces additional protocol interactions when needed |
| Payload size | Depends on API response design | Depends on how the MCP server shapes the tool/resource result |
| LLM context | Depends on what the application supplies to the model | Tool descriptions and returned results become part of the model-facing context |
| Overall workflow | Application controls the sequence of API calls | AI application may dynamically select and chain capabilities |
MCP should therefore not be characterized as inherently faster or slower than REST. Relevant performance characteristics depend on what you measure. A direct API call may have less protocol overhead than going through an MCP server, while the overall cost of an AI workflow also depends on capability discovery, the number of tool calls, response size, model inference, and backend operations.
REST API and MCP: Partnership, Not El Clásico
Considering the AI stack and future trends, REST API and MCP are not two poles, but two friends that work together in a comprehensive modern solution.
MCP as an AI-friendly layer over REST
MCP exposes tools that an AI agent can call. For most tools, it translates each invocation into the corresponding REST API request. APIs remain a great interface for an application to share its features and data with other applications, such as your system providing available flight information. MCP adds a layer on top for a universal protocol. It handles discovery and tool semantics for such endpoints. Tool invocation executes the remaining operations specified by the API server. In other words, REST APIs are a common way for an application to provide an interface, while MCP makes that interface usable and discoverable for AI agents. MCP server you use in Stripe, Salesforce, Slack, GitHub, or Notion is typically a thin, intelligent layer over native APIs. To meet AI-powered development, layer the API with MCP.
Design endpoints for agent tasks
A REST API has atomic endpoints for single tasks. Human developers use each get_user, get_orders, and get_shipments separately and integrate them in place. Human iteration is cheap, they can go to the documentation and find the right endpoint to use. Our automated consumers have expensive iteration, it must load every tool description into their context window. Every extra tool costs tokens and latency on every single interaction.
Keep this in mind when designing MCP with an API. Many single-purpose endpoints like get_user, get_orders, and get_shipments will hurt token price and performance. Expose a single endpoint, track_order(email), that does the job of all 3 internally and returns a complete, contextualized response.
Authentication: REST Flexibility vs. MCP standardization
REST APIs support several authentication methods, such as OAuth 2.0, bearer tokens, custom headers, Single Sign-On (SSO), 2-Factor authentication, Passwordless authentication, mutual TLS and API keys. Such a wide range of options offers you reliability for every requirement. However, each has complexity and needs its own implementation.
MCP takes a more standardized approach for remote authorization. It follows OAuth 2.1 with PKCE as the standard. MCP has gone through a lot of evolution since its inception. Maintainers have identified bottlenecks in the authorization implementation, for which MCP adopted authorization-server discovery, token validation, and scoped access. The current 2026-07-28 revision also includes changes around issuer validation, credential binding, and authorization scopes. Permission restriction matters because AI acts on behalf of the user. To achieve this, MCP can support authorization at the server or individual-tool level, allowing sensitive capabilities to require authorization while leaving other capabilities public.
MCP does not replace authentication or authorization, but it standardizes the interface between the AI application and the MCP server, while the underlying service can retain its own authentication and authorization model.
Use A Hybrid REST and MCP Architecture
For many production systems, the practical choice is not REST or MCP but REST and MCP. You shouldn't turn your existing APIs upside down for MCP. Existing REST APIs can continue serving applications, integrations, scheduled jobs, webhooks, and other deterministic workloads, while an MCP server provides an AI-friendly interface to the same underlying capabilities. MCP servers expose tools, resources, and prompts that AI applications can discover and use.
Design a hybrid model where REST can handle high-volume data ingestion, business logic abstraction, webhooks, and application-to-application integrations. An MCP layer can then expose higher-level capabilities such as querying customer information, checking an order, generating a report, or initiating an approved workflow. Both interfaces can ultimately operate on the same backend services and data.
Future Trends in APIs and Protocol Innovation
What we have been observing since the dawn of LLMs is that more and more applications are adopting AI in their workflow. Major technology companies like Google, Meta, Amazon and many others have integrated artificial intelligence into their core applications to enhance search, productivity, and user experience. This trend paved the road to other companies. In the future, we expect to see:
- APIs will become more agent-aware, and APIs will increasingly be designed for both traditional applications and AI agents as software gains new types of consumers.
- AI agents will become active API consumers. Instead of only retrieving data, agents will increasingly discover capabilities, make decisions, and perform actions through APIs.
- Natural-language interaction will grow, where users will increasingly interact with applications through conversational interfaces rather than navigating every workflow manually.
- Hybrid API architectures will become common where REST will continue serving traditional clients, while protocols such as MCP provide a standardized interface for AI agents.
- API capabilities will become more discoverable and future APIs will provide richer descriptions of available operations, inputs, outputs, permissions, and constraints so agents can use them reliably.
- Applications will increasingly adopt self-optimizing pipelines that adjust based on performance feedback and enhance user experience.
REST API vs MCP: When to use what?
We have seen architectural and usage differences between REST API and MCP. Now the question arises: which one fits where?
When to choose REST API
- Web and mobile applications where the client is user-written and developers know what to call.
- High-volume and performance-sensitive data retrieval where HTTP caching, CDNs, load balancing, and other established HTTP infrastructure can reduce latency and improve scalability.
- Public or broadly accessible APIs where compatibility with standard HTTP clients and existing API tooling is a priority.
- Microservices where backend services exchange data through stable and well-defined API contracts.
Go for MCP when
- AI is your consumer where you're building for Claude, ChatGPT, Cursor, or any LLM-powered tool
- Agent workflows require user confirmation. MCP supports interactions where a tool can pause during a workflow and obtain additional input or approval before performing a sensitive, destructive, or costly operation.
- You want reusable AI integrations. An MCP server can expose your existing capabilities through a standardized interface that multiple MCP-compatible clients can use.
Conclusion
Your applications may not be restricted to human users. AI-powered agents are increasingly a new species that interact with your applications. Your backend REST APIs were enough for the traditional request cycle, but AI's dawn brought a new standard for applications: MCP. We discussed each of them in detail and compared the differences. In this post, I shared how you can use REST API and MCP together as they're complementary layers in today's AI stack. Then I pointed out which one suits which scenario. My final recommendation in this ever-evolving ecosystem is to selectively and gradually add MCP to the applications where an AI agent will be part of the equation.
Pennsylvania, USA

What MCP authorization looks like when AI agents call APIs directly, and whether agent auth still needs DCR or CIMD.
Pennsylvania, USA

C# is a modern, object-oriented language from Microsoft that runs on .NET. This cheat sheet covers the syntax you reach for every day: variables, control flow, collections, classes and records, pattern matching, LINQ, async/await, and null handling, each with a short, copy-paste example you can adapt. It targets current .NET (.NET 10 / C# 14), so every snippet uses modern idioms like top-level statements, collection expressions, and records.
Most “C# cheat sheets” stop at if statements and for loops. This post keeps going, because the features that make
C# productive day to day (LINQ, async/await, records, and pattern matching) are the ones beginners like you need
the most.
Bookmark it, skim the headings, and jump to what you need when you need it.
An important note for beginners: C# is a highly expressive language, with many ways to do the same task. There is no true “one way” to do anything. The style and aesthetic of your codebase is your choice or the choice of your team. While many teams default to Visual Studio style (the settings that ship with Visual Studio), some choose to pick and choose the C# features that work best for their situation. But remember, most importantly, have fun and be productive!
C# Hello World and Program Structure
Modern C# uses top-level statements: no class or Main boilerplate required. The file is the entry point.
Console.WriteLine("Hello, World!");Create and run it with the dotnet CLI. dotnet new console scaffolds a project whose Program.cs already contains that line, and dotnet run builds and runs it:
$ dotnet new console -o HelloWorld$ cd HelloWorld$ dotnet runHello, World!That single line is a complete, runnable program on modern .NET. When a project grows, you organize code into
namespaces, classes, and files, but you never need the old static void Main ceremony just to get started.
C# Project and Solution Structure
A C# project is a folder with a .csproj file at its root. That file is XML, and it tells the build what kind of output to produce, which .NET version to target, and which packages to reference.
<Project Sdk="Microsoft.NET.Sdk"> <PropertyGroup> <OutputType>Exe</OutputType> <TargetFramework>net10.0</TargetFramework> <Nullable>enable</Nullable> <ImplicitUsings>enable</ImplicitUsings> </PropertyGroup> <ItemGroup> <PackageReference Include="Serilog" Version="4.1.0"/> </ItemGroup></Project>You rarely edit this by hand; dotnet add package and your IDE update it for you. A typical project folder looks like this:
HelloWorld/├── HelloWorld.csproj├── Program.cs└── bin/ and obj/ # build output, keep out of source controlA solution (.sln) groups related projects so you can build and open them together, for example a web API, a class library of shared code, and a test project. Create one and add projects with the CLI:
$ dotnet new sln -n Shop$ dotnet sln add src/Shop.Api src/Shop.Core tests/Shop.TestsImplicitUsings adds common using directives (like System and System.Linq) automatically, which is why the Hello World example never imported anything. Nullable turns on the nullable reference type checks covered later in this cheat sheet.
C# Namespaces
A namespace groups related types and helps you avoid name collisions. Two libraries can each define a Timer class as long as those classes live in different namespaces. Modern C# declares one with a file-scoped namespace: a single line at the top of the file, no braces.
namespace Shop.Orders;
public class Order{    public int Id { get; set; }}
The older block form wraps the types in braces, and you’ll still see it in existing code:
namespace Shop.Orders{ public class Order { }}Bring a namespace into scope with a using directive at the top of a file:
using System.Text;   // StringBuilder is now available by nameusing Shop.Orders;   // your own namespaces work the same way
var sb = new StringBuilder();var order = new Order();
A global using imports a namespace across the whole project, so you declare it once instead of in every file. A GlobalUsings.cs file is a common home for them:
global using System.Text;The ImplicitUsings setting in your .csproj is a bundle of global usings that .NET adds for you, which is why
Console and List<T> work without any using line. Without them, your files would repeat the same using directives over and over, since these types are so commonly used. When two
namespaces define a type with the same name, use the fully qualified name to disambiguate, like System.Timers.Timer versus System.Threading.Timer.
C# Variables and Data Types
Declare a variable with its type, or use var to let the compiler infer it. The most common built-in types are below.
The choice is a matter of preference, but many developers use var for brevity, readability, and the ability to change types
later with less effort.
int count = 5; // 32-bit integerlong big = 9_000_000_000; // 64-bit integerdouble price = 3.14; // 64-bit floating pointdecimal money = 9.99m; // 128-bit, use for currencybool isReady = true; // true / falsechar letter = 'A'; // single UTF-16 unitstring name = "Khalid"; // textvar inferred = "also a string"; // compiler infers the type| Type | Use for | Example |
|---|---|---|
int |
Whole numbers | 42 |
long |
Large whole numbers | 9_000_000_000 |
double |
General decimals | 3.14 |
decimal |
Money and exact decimals | 9.99m |
bool |
True/false | true |
char |
A single character | 'A' |
string |
Text | "hello" |
Use decimal (not double) for money, because double can’t represent values like 0.1 exactly. Underscores like 9_000_000_000 are digit separators and are ignored by the compiler.
C# Operators
// arithmeticint sum = 2 + 3;        // 5int remainder = 7 % 3;  // 1
// comparisonbool equal = a == b;bool greater = a > b;
// logicalbool both = x && y;     // AND (short-circuits)bool either = x || y;   // OR  (short-circuits)bool not = !x;          // NOT
// null handlingstring value = input ?? "default";   // null-coalescingint? length = text?.Length;          // null-conditionalinput ??= "fallback";                // assign if null
C# Strings and String Interpolation
Use $"{variable_name}" for string interpolation, the readable way to build strings from values.
string name = "Khalid";int count = 3;
string message = $"{name} has {count} posts.";   // "Khalid has 3 posts."string upper = name.ToUpper();                    // "KHALID"bool has = name.Contains("hal");                  // truestring[] parts = "a,b,c".Split(',');              // ["a", "b", "c"]string joined = string.Join("-", parts);          // "a-b-c"bool empty = string.IsNullOrWhiteSpace("  ");     // true
For multi-line text, use raw string literals (triple quotes), which keep quotes and backslashes literal:
string json = """ { "name": "Khalid", "active": true } """;A word of caution: string.Length counts UTF-16 code units, not the characters a person sees, which matters for emoji and non-Latin scripts. I cover this in measuring Unicode string lengths with C#.
C# Control Flow: if, switch, and Loops
// if / else if / elseif (score >= 90) grade = "A";else if (score >= 80) grade = "B";else grade = "C";A switch expression is the modern, concise alternative when you’re mapping an input to a value:
string label = status switch{ 1 => "Active", 2 => "Paused", _ => "Unknown" // _ is the default case};The common loops:
for (int i = 0; i < 5; i++)    Console.WriteLine(i);
foreach (var item in items)    Console.WriteLine(item);
while (condition)    DoWork();
do    DoWorkAtLeastOnce();while (condition);
Reach for foreach by default when you’re iterating a collection; use for when you need the index.
C# Collections: Arrays, Lists, and Dictionaries
Modern C# uses collection expressions ([...]) to create arrays and lists.
// arrayint[] numbers = [1, 2, 3, 4, 5];
// List<T> — resizableList<string> names = ["Ada", "Alan"];names.Add("Grace");names.Remove("Alan");int total = names.Count;
// Dictionary<TKey, TValue> — key/value lookupsDictionary<string, int> ages = new(){    ["Ada"] = 36,    ["Grace"] = 45};ages["Alan"] = 41;bool found = ages.TryGetValue("Ada", out int age);
// HashSet<T> — unique valuesHashSet<int> unique = [1, 2, 2, 3]; // {1, 2, 3}| Collection | Use for |
|---|---|
T[] (array) |
Fixed-size sequence |
List<T> |
Resizable sequence |
Dictionary<TKey, TValue> |
Key-based lookups |
HashSet<T> |
Unique values, fast membership tests |
Prefer TryGetValue over indexing a Dictionary directly, since a missing key throws a KeyNotFoundException.
This is just a limited set of data structures, and .NET and the ecosystem contain many more. If you find yourself wanting a different storage mechanism, check out NuGet for other data structures, or you can always build your own.
C# Methods
// a method with a return valueint Add(int a, int b) => a + b;        // expression-bodied
// void method, no return valuevoid Log(string message) => Console.WriteLine(message);
// optional and named argumentsvoid Greet(string name, string greeting = "Hello")    => Console.WriteLine($"{greeting}, {name}!");
Greet("Ada");                      // "Hello, Ada!"Greet("Ada", greeting: "Hi");      // "Hi, Ada!"
// params: variable number of argumentsint SumAll(params int[] values) => values.Sum();SumAll(1, 2, 3, 4);                // 10
C# Classes, Records, and Structs
A class is a reference type and the workhorse of C# Object-Oriented Programming. Primary constructors let you declare constructor parameters right on the class.
public class Account(string owner){    public string Owner { get; } = owner;    public decimal Balance { get; private set; }
    public void Deposit(decimal amount) => Balance += amount;}
var account = new Account("Khalid");account.Deposit(100m);
A record is a reference type built for immutable data. You get value equality, a readable ToString, and nondestructive copies with with for free.
public record Movie(int Id, string Name, string Service);
var a = new Movie(1, "Dune", "max");var b = a with { Service = "netflix" };   // a copy with one changebool same = a == new Movie(1, "Dune", "max"); // true (value equality)
A struct is a value type, copied by value, and best for small, immutable data like coordinates.
public readonly struct Point(int X, int Y);Rule of thumb: use a record for data you pass around, a class for objects with behavior and identity, and a struct only for small values where copying is cheap.
C# Properties
Properties expose data with optional logic. The shortest form is an auto-property.
public class Person{ public string Name { get; set; } // read/write public int Age { get; init; } // set only during construction public string Greeting => $"Hi, {Name}"; // computed, read-only}init accessors allow object-initializer syntax while keeping the property immutable afterward:
var p = new Person { Name = "Ada", Age = 36 };The field keyword (C# 14) lets an accessor reach the compiler-generated backing field directly, so you can add logic without declaring a separate field by hand:
public string Name{ get; set => field = value?.Trim() ?? ""; // "field" is the backing field}C# Inheritance, Interfaces, and Polymorphism
public interface IShape{    double Area();}
public class Circle(double radius) : IShape{    public double Area() => Math.PI * radius * radius;}
public abstract class Animal{    public abstract string Speak();}
public class Dog : Animal{    public override string Speak() => "Woof";}
Polymorphism means a variable of the base type can hold any derived instance and call the right override at runtime:
Animal animal = new Dog();Console.WriteLine(animal.Speak()); // "Woof"Favor interfaces for describing capabilities (what a type can do) and keep inheritance shallow.
C# Pattern Matching
Pattern matching tests a value’s shape and extracts data in one step. It’s worth learning early.
// type pattern with "is"if (value is string text)    Console.WriteLine(text.Length);
// switch on patternsstring describe = input switch{    0 => "zero",    > 0 and < 10 => "small",       // relational + logical patterns    int n => $"number {n}",         // type pattern    null => "nothing",    _ => "something else"};
// property patternsstring Classify(Movie m) => m switch{    { Service: "max" } => "Max original",    { Id: > 100 } => "high id",    _ => "other"};
C# Null Handling and Nullable Reference Types
With nullable reference types enabled (the default in new projects), the compiler warns you when a reference might be null. A ? marks a type that is allowed to be null.
string? maybeNull = GetNameOrNull();
// null-conditional: returns null instead of throwingint? length = maybeNull?.Length;
// null-coalescing: supply a fallbackstring name = maybeNull ?? "Anonymous";
// null-coalescing assignmentmaybeNull ??= "default";
// null-forgiving: "I know this isn't null" (use sparingly)int definite = maybeNull!.Length;
C# 14 also adds null-conditional assignment: you can assign through ?. so the write happens only when the left side isn’t null.
// assigns only if customer isn't null; GetCurrentOrder() is skipped otherwisecustomer?.Order = GetCurrentOrder();Leaning on ?. and ?? eliminates most NullReferenceException bugs before they happen. For the full picture of what #nullable enable emits, how to clear CS8618 without null!, and where null still slips through at runtime, see my upcoming deep dive on C# nullable reference types.
C# Exception Handling
try{    var text = File.ReadAllText("config.json");}catch (FileNotFoundException ex){    Console.WriteLine($"Missing file: {ex.FileName}");}catch (Exception ex){    Console.WriteLine($"Something failed: {ex.Message}");}finally{    // always runs, exception or not    Console.WriteLine("Done.");}
// throw when input is invalidArgumentNullException.ThrowIfNull(input);
Catch the most specific exception types first, and avoid swallowing a bare catch without logging or rethrowing. For the full picture, including throw vs throw ex, when filters, and custom exception types, see our upcoming guide on C# try/catch exception handling.
Performance note: Exceptions are very expensive, so avoid throwing them unnecessarily. “Expensive” means more memory allocations, slower execution, and added garbage-collection pressure. If you find yourself using exceptions for control flow, consider refactoring your code to use a different approach.
C# LINQ
LINQ (Language Integrated Query) lets you filter, transform, and aggregate collections with readable, composable queries. If you only learn one “advanced” feature from this cheat sheet, make it this one.
using System.Linq;
int[] numbers = [1, 2, 3, 4, 5, 6];
var evens = numbers.Where(n => n % 2 == 0);        // 2, 4, 6var doubled = numbers.Select(n => n * 2);          // 2, 4, 6, 8, 10, 12int sum = numbers.Sum();                            // 21int max = numbers.Max();                            // 6bool any = numbers.Any(n => n > 5);                 // truevar firstEven = numbers.First(n => n % 2 == 0);     // 2var ordered = numbers.OrderByDescending(n => n);    // 6, 5, 4, ...var list = evens.ToList();                          // materialize results
LINQ is lazy: nothing runs until you iterate the result (or call ToList, ToArray, Count, etc.). That means you can build up a query in pieces without touching the data until you need it.
C# Async and Await
async/await lets you perform I/O (network calls, file reads, database queries) without blocking a thread. An async method returns a Task (or Task<T>), and await unwraps the result when it’s ready.
public async Task<string> FetchAsync(string url){    using var client = new HttpClient();    string body = await client.GetStringAsync(url);    return body;}
// calling an async methodstring html = await FetchAsync("https://example.com");
// run work concurrently, then wait for all of itTask<string> a = FetchAsync("https://a.com");Task<string> b = FetchAsync("https://b.com");string[] results = await Task.WhenAll(a, b);
If a method performs any I/O, make it async and await it all the way up the call stack. Reading files is a common
case; see reading a file in C# for the synchronous and async variants side by side.
C# File Input and Output
The System.IO.File class handles most file work in one line, no extra packages required.
using System.IO;
// writeFile.WriteAllText("notes.txt", "Hello, file!");
// readstring text = File.ReadAllText("notes.txt");string[] lines = File.ReadAllLines("notes.txt");
// asyncawait File.WriteAllTextAsync("notes.txt", "Hello again");string again = await File.ReadAllTextAsync("notes.txt");
// check existencebool exists = File.Exists("notes.txt");
For the full set of read methods and their memory trade-offs, see C# read file: ReadAllText, ReadAllBytes, and more. To bundle files together, see creating a zip file with .NET.
C# Enums
An enum is a named set of constant values, far clearer than passing around magic numbers.
public enum Status{    Active,     // 0    Paused,     // 1    Archived    // 2}
Status current = Status.Active;
string label = current switch{    Status.Active => "Running",    Status.Paused => "On hold",    _ => "Done"};
C# Generics
Generics let you write one type or method that works with any type, with full type safety and no casting.
// a generic methodT First<T>(IList<T> items) => items[0];
// a generic classpublic class Box<T>(T value){    public T Value { get; } = value;}
var box = new Box<int>(42);int number = box.Value;   // strongly typed, no cast
You already use generics every time you write List<string> or Dictionary<string, int>. For a deeper guide to generic classes, methods, constraints, and generic math, see our upcoming post on C# generics explained.
Where You’ll Find C#
C# runs almost everywhere through .NET, which is cross-platform and open source. Here are the main places it shows up.
Web Apps and APIs
ASP.NET Core builds web apps, REST and GraphQL APIs, and real-time apps with SignalR. Blazor lets you write interactive browser UIs in C# instead of JavaScript, running on WebAssembly or over a server connection.
Desktop Apps
For Windows desktop software, you have WPF, Windows Forms, and WinUI. For cross-platform desktop, Avalonia and the Uno Platform target Windows, macOS, and Linux from one codebase.
Mobile Apps
.NET MAUI builds native iOS and Android apps (plus macOS and Windows) from a single C# project, sharing UI and logic across platforms.
Games
C# is the scripting language of Unity, one of the most widely used game engines in the world, and it also drives Godot through its C# bindings. Everything from mobile games to major console titles ships on Unity.
Cloud and Services
C# is a first-class language on Microsoft Azure and runs well on AWS and Google Cloud. It’s common for background workers, serverless functions, microservices, and gRPC services, with containers and Kubernetes fully supported.
IoT and Devices
.NET runs on single-board computers like the Raspberry Pi, and the .NET IoT libraries talk to sensors, displays, and GPIO pins. .NET nanoFramework pushes C# all the way down to microcontrollers like the ESP32.
Data, AI, and Tooling
C# powers CLI utilities, build pipelines, and developer tools, and libraries like ML.NET and the Microsoft.Extensions.AI packages bring machine learning and LLM integration into .NET apps.
How Do I Start Learning C# as a Beginner?
If you’re brand new, here’s a focused path through this cheat sheet:
- Install the .NET SDK from dotnet.microsoft.com and run
dotnet new consoleto create your first project. - Master the basics first: variables, control flow, methods, and collections. That’s enough to write real programs.
- Then learn the “productivity four”: classes/records, pattern matching, LINQ, and
async/await. These are where C# starts to feel powerful. - Build something small, like a to-do app, a file renamer, or an API that returns JSON. You learn far more by shipping than by reading.
You don’t need to memorize any of this. Keep the page open, write code, and the syntax sticks through use.
C# Tooling: SDK, IDEs, and Debuggers
The .NET tooling is one of the best reasons to pick C#: a single cross-platform SDK, three mature IDEs, and a debugger that lets you change code while the program is still running.
Everything starts with the dotnet CLI, which ships with the .NET SDK. You can create, build, run, test, and package a project without ever opening an editor.
dotnet new console -o MyApp # scaffold a console appcd MyAppdotnet add package Serilog # add a NuGet dependencydotnet run # build and rundotnet test # run the test suitedotnet format # fix formatting and styleFor day-to-day work, pick the editor that fits your setup:
| Tool | Platform | Best for |
|---|---|---|
| Visual Studio | Windows, Mac | The full-featured IDE: deepest debugging, profiling, and designers |
| VS Code + C# Dev Kit | Windows, Mac, Linux | A fast, lightweight editor with solid C# support |
| JetBrains Rider | Windows, Mac, Linux | A cross-platform IDE with powerful refactorings and analysis |
All three give you IntelliSense (type-aware completion), inline error highlighting, and one-click refactorings like rename and extract method.
The debugger is the part I’d miss most on other stacks. Set a breakpoint, run, and you can:
- Step through code line by line and inspect every variable.
- Hover a variable to see its live value, or pin it to a watch window.
- Change a value mid-run, or edit the code itself and keep going with Hot Reload and Edit and Continue, no restart required.
- Set conditional breakpoints that only trigger when, say,
id == 42.
Roslyn analyzers run as you type, flagging bugs and style issues before you ever build, and many offer a one-keystroke fix. The Debugger.Launch() method even lets you attach a debugger on demand from your own code.
Frequently Asked Questions
Is C# hard to learn for beginners?
C# is one of the more beginner-friendly compiled languages. It has clear, readable syntax, world-class tooling (Visual Studio, VS Code, and JetBrains Rider), and detailed compiler errors that tell you what’s wrong. Modern features like top-level statements let you write a working program in a single line, so you can start small and grow.
What is C# used for?
C# is used to build web apps and APIs (ASP.NET Core), desktop apps, cross-platform mobile apps (.NET MAUI), games (Unity), cloud services, and background/console tools. It runs on Windows, macOS, and Linux through .NET.
What is the difference between a class and a record in C#?
A class is a reference type suited to objects with behavior and identity. A record is a reference type optimized for immutable data: it gives you value-based equality, a readable ToString, and nondestructive copying with the with expression. Use a record when the object is essentially a bundle of data you pass around.
What is the difference between C# and .NET?
C# is the programming language; .NET is the platform it runs on. .NET provides the runtime that executes your code and the base class libraries (collections, file I/O, networking, LINQ, and more). You write C#, and .NET runs it.
Do I need Visual Studio to write C#?
No. You only need the free .NET SDK and any editor. Visual Studio, Visual Studio Code with the C# Dev Kit, and JetBrains Rider all work well, and you can compile and run from the command line with dotnet run.
Wrapping Up
The fastest way to internalize any of this is to keep the page open while you build something and reach for each feature as the need comes up.
For deeper dives on specific topics, explore my other posts on converting strings to numbers, reading files in C#, and C# records and the with keyword.
Thanks for reading, and please leave a comment below. Follow me on Mastodon at @khalidabuhakmeh for the latest .NET news and tutorials.
Written by Khalid Abuhakmeh. If this guide helped your workflow, feel free to buy me a coffee.
Pennsylvania, USA
Next Page of Stories