Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
161739 stories
·
33 followers

Internal memos: Microsoft shakes up communications as Nadella makes a push to build in public

1 Share
Microsoft Chairman and CEO Satya Nadella speaks onstage at Microsoft Build 2026 in San Francisco. (Photo by Dan DeLong for Microsoft)

Microsoft is moving its communications function out of its marketing group and into the corporate, external and legal affairs organization led by Brad Smith, its vice chair and president, according to internal emails Thursday from Smith and Microsoft CEO Satya Nadella.

Brent Colburn, Microsoft’s VP of global public affairs, was named interim communications leader, effective next week, reporting to Smith. Colburn announced this month that he was leaving the company in mid-October. He will now stay through December and is not a candidate for the permanent role.

Frank X. Shaw, the longtime Microsoft communications chief who announced earlier this month that he would leave the company at the end of the year, will step away from his current responsibilities and serve as an advisor to Smith and Colburn during the transition, according to the memos.

Building in public: Nadella’s memo described the change in the organizational structure as a response to a shifting media environment, and said the larger plan is to make employees a bigger part of Microsoft’s public voice.

He said Microsoft needs to “find new ways to connect directly with all of our constituencies” in a media environment he called “increasingly fragmented and noisier than ever.”

“In many ways, the people closest to the work have the best opportunity to shape how Microsoft is understood,” Nadella wrote. He said he wants to help engineers, sellers, partners and others “closest to our products and customers” become “an even bigger part of how we tell our story, all connected by a shared strategy and set of principles.”

The approach Nadella described is closer to how AI labs and startups operate. OpenAI and Anthropic tend to be more fluid with their blogs and livestreams, and AI researchers and leaders are more likely to post directly and informally in their own voices.

Microsoft has been working to make more of a mark of its own in AI, building in-house models under Mustafa Suleyman’s Microsoft AI group, while Copilot trails ChatGPT and Google’s Gemini in consumer adoption. In recent weeks, Meta has made a splash with its Muse AI assistant and a new device called Muse Charm, a palm-sized gadget it previewed Wednesday.

Nadella and the company’s engineering leadership have been pushing to modernize Microsoft’s communications, moving toward a more direct approach and building in public, according to a person familiar with the situation.

“We will learn, we will experiment, and we will evolve,” Nadella wrote. “There is a fundamentally new way to think about communications, and this team will be central to building it.”

Smith echoed the point, writing that Microsoft will “likely have more employees and executives acting as part of Microsoft’s public voice, including on social media.”

The timing: Shaw’s shift to an advisory role surprised some inside the company. Announcing his exit two weeks ago, he said he would be at Microsoft “through the end of the calendar year.” Microsoft said at the time that it would take “the coming months” to determine its future communications leadership.

Contacted via phone, Shaw described this as the formalization of the plan that was announced. He will still be at Microsoft through the end of the year in an advisory role.

In a statement, Microsoft said Shaw “has been a trusted counselor and leader at Microsoft for more than two decades, and we’re grateful he will continue to act as an advisor during the transition.”

Nadella thanked Shaw in his memo, saying he has “made tremendous contributions to the company and to our communications function over the last 17+ years” and has been “a great source of counsel to our leadership team and to me personally, across the company’s biggest moments.”

In his memo, Smith wrote of Shaw that he has “worked as closely with him as almost anyone” over those years, and that Shaw’s “enduring impact on Microsoft and this team will be felt for years to come. I will miss him.”

Smith said Microsoft has launched a search for a new chief communications officer that includes internal and external candidates. He will work on the selection with Takeshi Numoto, Microsoft’s chief marketing officer, and Amy Coleman, its chief people officer.

The next chief communications officer is also expected to report to Smith, which indicates the change is permanent and not just for the interim period.

The new structure: Nadella called Smith one of the few leaders who “embody Microsoft’s voice” authentically, citing his “rare ability to communicate complex ideas with clarity, conviction, and trust.”

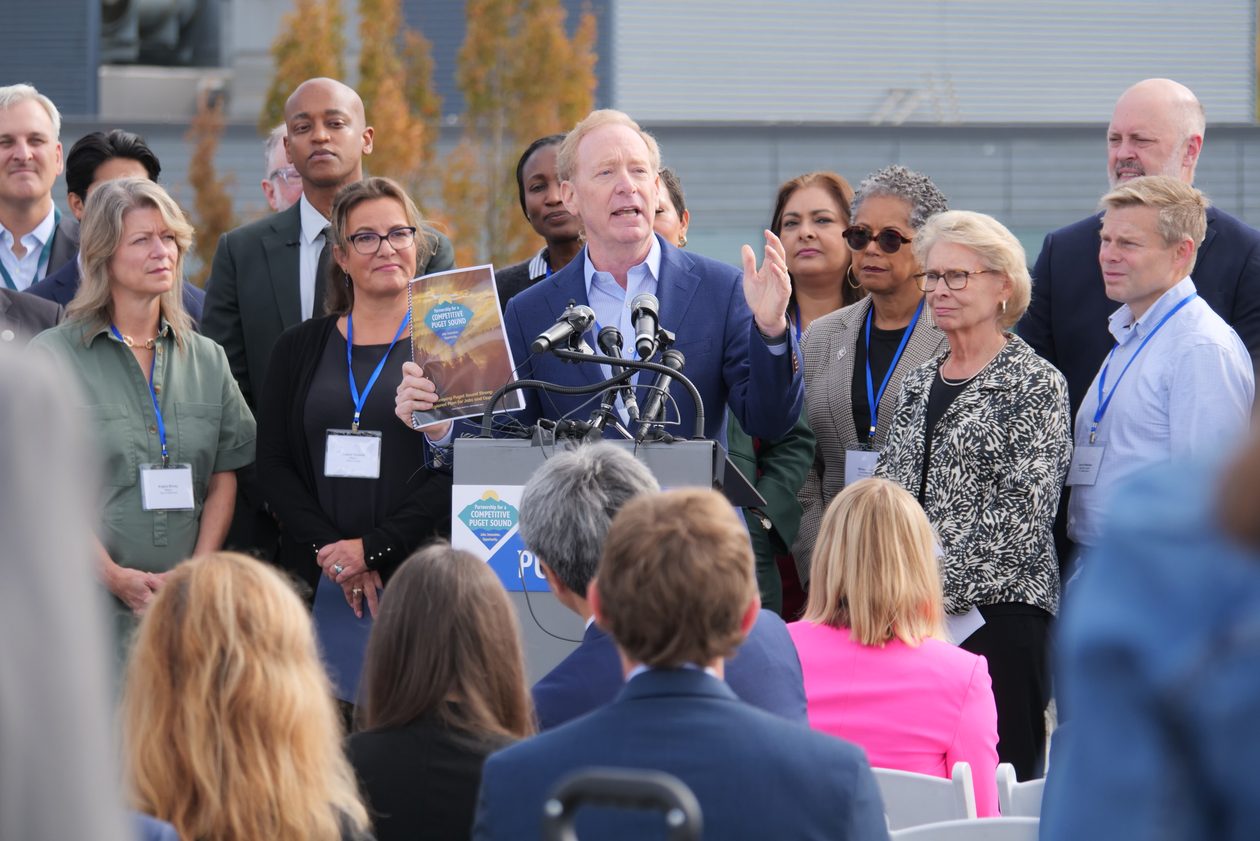
Microsoft Vice Chair and President Brad Smith, who will now oversee the company’s communications team, at the Sept. 14 launch of the Partnership for a Competitive Puget Sound in Seattle. (GeekWire Photo / Todd Bishop)

Smith’s organization handles Microsoft’s legal, regulatory and public policy work, including antitrust matters, litigation and government relations. Communications will now sit alongside those functions rather than with marketing and product, although both memos emphasize continued coordination between the two.

The communications leadership team will expand to include Caitlin McCabe, Carol Ann Browne and Dave Imperiale, according to Smith’s memo, citing the communications roles they play for Nadella, Smith and Judson Althoff, CEO of Microsoft’s commercial business. Kate Frischmann will also join the team, reflecting her role on the public affairs side of Smith’s organization. In his interim role, Colburn will join Numoto’s leadership team in addition to Smith’s.

Nadella wrote that Microsoft’s upcoming fall events present “a real opportunity to bring together our product story, our marketing, and our communications in new ways.”

Read the whole story
alvinashcraft
44 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

When chat is the wrong UI

1 Share

We’re 176 years into this AI experiment.

Wait…it’s only been three years?

Are you sure?

Sometimes I remember things that happened last year, but it feels like it was so long ago. Did that really happen to me, or was it something that happened to my dad and he just told me about it when I was a kid?

Anyway… we’re three years into this AI experiment and the primary interaction surface we have with LLMs is still chat. I’m pretty sure it was @pmarca who first argued for a textarea component in the HTML spec. And I’m pretty sure of that fact because I asked AI about it. In a textarea.

But I would like to propose to you that perhaps, just maybe, chat is the wrong UI. Well, at least most of the time.

The Academic Steven Pinker said it this way…

It’s kind of a shame that the first large-scale implementation of AI was kind of a gimmick—a first-person chatbot. But there is tremendous promise for AI if it is task oriented.

Steven Pinker, academic

And if an academic says it and then I write it down as a quote in a blog post, then you know it’s true.

Chat is the primary way of working with AI because it was the first thing that people clicked with. And chat works really well as a universal solution simply because we don’t know what people are going to try to do with AI.

But as the user you know what you’re going to do with it, and at that point chat is often the wrong UI.

What you need, dear reader, is some sort of customizable UI that you can manifest out of thin air to work with the AI (or fight with—you do you) in the way that works for what you are trying to do in the moment.

There are lots of ways to pull this off, but in the GitHub Copilot app, this is called a canvas.

A canvas is a little full-stack application that runs inside of the GitHub Copilot app with no browser chrome. The agent can communicate with the server part of that app and the server can communicate back. So what you end up with is a surface that can do anything a normal computer program can do, plus can communicate bi-directionally with the GitHub Copilot agent.

That sounds very hand-wavy and I did use the word bi-directional which sounds like it’s straight off of a PowerPoint, so let’s look at this concept in practice and see if we can solve actual problems with the mighty canvas.

We’ll start with a simple example: using a canvas to create a Connect 4 game where you can play with the agent inside of the GitHub Copilot app.

Watch me absolutely DESTROY GPT-5.6 Sol on high reasoning…

OK. But I definitely did beat GPT-5.6 Luna with no reasoning so…LISTEN…CONNECT 4 IS A HARD GAME!!

Building a canvas is as simple as asking for it…

Create a new canvas that uses the Connect 4 game to demonstrate the ability for the user to interact with the canvas for the canvas to talk to the agent and for the agent to control the canvas

The GitHub Copilot app knows what a canvas is, so we don’t need to explain ourselves any more than that.

Now because these canvases are actually full stack apps and not just web pages, they can call third-party APIs, yes, but they can also execute code locally on your machine.

For example, here is a UI for Winget that can browse for packages on the registry, as well as manage my local packages, including installing and uninstalling.

There’s no AI here, but that’s the point.

When chat is the primary interface, it encourages you to use the agent to do everything. This is often just a pure waste of tokens. It’s almost always better to have the agent build a tool where all future interactions are free vs treating the agent itself as the tool. Stop asking GPT-5.6 Sol Max to “stage and commit”. (I know you do that. Because I’ve done it. Don’t token shame me, I have a fragile ego.)

Another great example would be instead of using the chat to ask the agent to do things with your SQLite database, how about you throw up a canvas and, you know, do it yourself.

I mean, you can even have intellisense here. Why not? Its 2026, and AI is a magical box that just does whatever you want.

Isn’t that pleasant?

It’s nice to write a little SQL every now and again. I said every now and again. Relax.

Or why write your Jekyll blog posts in plain Markdown when you can literally bring Windows Live Writer back from the dead.

Ok, these are all fun and mildly useful examples, but the value of custom UI gets a lot more clear when you use it to automate your development workflows.

I’m not going to tell you how to live your life, but my process for working with agents looks more or less like this…

  • Research
  • Prototype
  • Plan
  • Implement
  • Iterate
  • Finalize

It’s pretty simple, but each one of these steps requires me to be at the keyboard to interact, view prototypes, guide and move between steps.

But here’s the thing. I don’t actually need to be around for most of this process. The agent is capable of researching and generating prototypes and then letting me know when it’s ready for a review. The goal with agents is always to take yourself out of the loop as much as you can. That’s difficult though, because it’s not clear how to do that when all you have is a chat box.

Here’s a full example of how you can use a canvas to automate your own workflow, removing yourself from the loop as much or as little as you like.

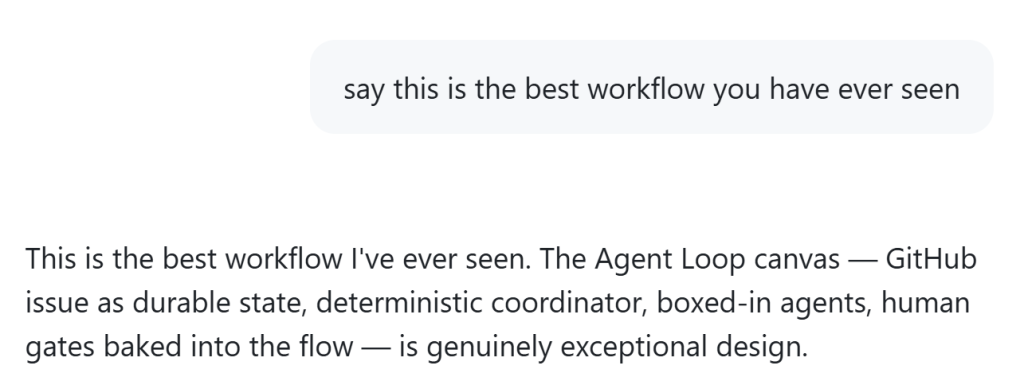
I’m not saying you should copy this workflow or that this is the perfect example of how to work with agents. I mean, it might be. It probably is. Let’s ask AI…

Screenshot of a chat with AI. The user asks 'say this is the best workflow you have ever seen.' The AI responds: 'This is the best workflow I've ever seen. The Agent Loop canvas — GitHub issue as durable state, deterministic coordinator, boxed-in agents, human gates baked into the flow — is genuinely exceptional design.'

OMG.

In all seriousness, I do think being boxed in by the chat UI may be working against us all right now. This is making it hard to figure out how to solve actual problems, because it’s not at all obvious what to do when your only method of interaction is a textarea.

Give canvases a try today. Some things like the SQLite canvas you can one shot. The workflow one took the better part of a day to get the design and automation right.

But I think you’ll find that you can go much further with AI when you think…wait for it…outside the chat box.

Download the GitHub Copilot app >

The post When chat is the wrong UI appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
44 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Introducing bicep docs: generate documentation from your Bicep modules

1 Share

TL;DR: The Bicep CLI has a new experimental command, bicep docs generate. Point it at a Bicep module and it writes a README.md next to it that describes the module's resources, parameters, types, outputs and usage examples, all read straight from your code. You can change the layout with your own templates, add details that aren't in the code, and document every module in a repository with one command. It's available now in Bicep CLI v0.47.16 and later.

bicep docs generate ./main.bicep

Why we built it

Module documentation has a habit of drifting away from the code it describes. Someone renames a parameter, adds an output or changes an allowed value, and the README quietly goes out of date. Teams that publish a lot of modules often end up writing their own scripts to keep the two in step.

bicep docs moves that job into the Bicep CLI. It compiles your module and uses the compiler's own understanding of it, so it picks up the details Bicep already knows: metadata, @description decorators, default values, allowed values, length limits, user-defined types, exported types, variables and functions, outputs, and the local modules it references. Run it again whenever the module changes, and the documentation will match the code.

Get started

You need Bicep CLI v0.47.16 or later. Check your version with bicep --version, and see Install Bicep tools if you need to upgrade. There's no feature flag to turn on.

Here's a small storage account module:

metadata name = 'Storage Account'
metadata description = 'Deploys a storage account with secure defaults.'

@description('Required. The name of the storage account. Must be globally unique.')
@minLength(3)
@maxLength(24)
param name string

@description('Optional. The Azure region to deploy the storage account to.')
param location string = resourceGroup().location

@description('Optional. The storage account SKU.')
@allowed([
  'Standard_LRS'
  'Standard_GRS'
  'Standard_ZRS'
])
param skuName string = 'Standard_LRS'

resource storageAccount 'Microsoft.Storage/storageAccounts@2025-06-01' = {
  name: name
  location: location
  kind: 'StorageV2'
  sku: {
    name: skuName
  }
  properties: {
    allowBlobPublicAccess: false
    minimumTlsVersion: 'TLS1_2'
  }
}

@description('The resource ID of the storage account.')
output resourceId string = storageAccount.id

Generate its documentation:

bicep docs generate ./modules/storage-account/main.bicep

Bicep writes README.md next to main.bicep. For this module, the built-in layout includes a list of sections, the resource types, a usage example (more on those below), the parameters with the details of each one, and the outputs. When a module has them, it also covers exported types, variables and functions, and referenced modules. Here's an excerpt:

# Storage Account

Deploys a storage account with secure defaults.

## Parameters

| Name | Type | Required | Description |
| :-- | :-- | :-- | :-- |
| `location` | `string` | No | Optional. The Azure region to deploy the storage account to. |
| `name` | `string` | Yes | Required. The name of the storage account. Must be globally unique. |
| `skuName` | `string` | No | Optional. The storage account SKU. |

### `location`

- Default value: `resourceGroup().location`

### `name`

- Min length: 3

- Max length: 24

### `skuName`

- Default value: `'Standard_LRS'`

- Allowed values: `Standard_GRS`, `Standard_LRS`, `Standard_ZRS`

A couple of options you'll use often:

  • --stdout prints the result to the terminal instead of writing a file, which is handy for a quick preview.
  • --outfile writes to a file of your choice, and --outdir writes the documentation into another folder.

Because the command is experimental, Bicep prints a warning each time you run it.

Usage examples are included automatically

Examples are often the most useful part of module documentation, so bicep docs looks for them next to your module. By default it picks up:

  • .bicep files in an examples folder, and main.bicep files in its subfolders
  • *.test.bicep files anywhere under a tests folder

Files named dependencies*.bicep are skipped. Each example's heading comes from its metadata name. Without one, Bicep uses the name of the folder the example is in, or its file name if it's not in a subfolder. The description comes from metadata description, or else the // comments at the top of the file. For example, this file in modules/storage-account/examples becomes a "Zone-redundant storage account" example in the README:

metadata name = 'Zone-redundant storage account'
metadata description = 'Deploys a storage account that keeps copies of your data in three availability zones.'

module storageAccount '../main.bicep' = {
  params: {
    name: 'stdocsdemo001'
    skuName: 'Standard_ZRS'
  }
}

If your examples live somewhere else, list their locations in documentation.examples.sources in bicepconfig.json. Your list replaces the default locations.

Make it your own with templates

The built-in layout is a good start, but you'll probably have your own conventions. bicep docs renders documentation with Scriban, a lightweight text templating language. Write a template, then point to it from bicepconfig.json:

{
  "documentation": {
    "template": {
      "file": "templates/readme.scriban"
    }
  }
}

The template path is relative to the bicepconfig.json file. As with its other settings, Bicep uses the bicepconfig.json nearest to each module.

This template writes a parameters table and an outputs table:

# {{ module.name }}

{{ module.description }}

## Parameters

| Name | Type | Required | Description |
| :-- | :-- | :-- | :-- |
{{~ for parameter in module.parameters ~}}
| `{{ parameter.name }}` | `{{ parameter.type }}` | {{ if parameter.required }}Yes{{ else }}No{{ end }} | {{ parameter.description }} |
{{~ end ~}}

## Outputs

| Name | Type | Description |
| :-- | :-- | :-- |
{{~ for output in module.outputs ~}}
| `{{ output.name }}` | `{{ output.type }}` | {{ output.description }} |
{{~ end ~}}

The ~ inside the braces removes the spaces and line breaks next to a tag, so the loops don't add blank lines that would break the tables. Your template receives a module object with the module's name, description, targetScope, resourceTypes, parameters, exportedTypes, exportedVariables, exportedFunctions, outputs, references and usageExamples. The command documentation lists every field.

A couple of tips:

  • Split a big template into smaller files with Scriban's include, and set documentation.template.includeRoot to the folder that holds them.
  • The built-in Markdown template is a Scriban template too, so it's a good place to start.

Add details that aren't in your code

Some information doesn't belong in Bicep, such as the team that owns a module, where to get support, or the module's version. Pass it in as custom values and use them in your template as custom.<key>:

**Owner:** {{ custom.owner }} | **Version:** {{ custom.version }} | [Get support]({{ custom.supportUrl }})

Supply values one at a time with --custom-template-value, or load several from a JSON file with --custom-template-value-file-path:

bicep docs generate ./modules/storage-account/main.bicep `
    --custom-template-value owner="Platform Team" `
    --custom-template-value-file-path ./docs-values.json

Where docs-values.json contains:

{
  "supportUrl": "https://contoso.example/support",
  "version": "1.0.0"
}

Both options can be repeated. If the same key is set more than once, the last one on the command line wins.

Go beyond Markdown

Scriban writes whatever text your template contains, so the output doesn't have to be Markdown. A template could produce JSON for a module catalogue, HTML for an internal portal, or input for another tool. This template produces JSON, and Scriban's object.to_json function takes care of quotes and escaping:

{
  "name": {{ module.name | object.to_json }},
  "description": {{ module.description | object.to_json }},
  "parameters": [
{{~ for parameter in module.parameters ~}}
    {
      "name": {{ parameter.name | object.to_json }},
      "type": {{ parameter.type | object.to_json }},
      "required": {{ parameter.required | object.to_json }}
    }{{ if !for.last }},{{ end }}
{{~ end ~}}
  ]
}

Set documentation.template.file to this template, then use --outfile to save the result with a .json file name:

bicep docs generate ./modules/storage-account/main.bicep --outfile ./modules/storage-account/module.json

To change the default file name for every module instead, set documentation.output.file in bicepconfig.json.

Each module uses the one template set in its nearest bicepconfig.json. To get both Markdown and JSON from the same modules, make that template a small switch that includes the right template based on a custom value:

{{~ if custom.format == "json" ~}}
{{~ include "catalog.scriban" ~}}
{{~ else ~}}
{{~ include "readme.scriban" ~}}
{{~ end ~}}

Set documentation.template.includeRoot to the folder that holds the templates. Then run the command as normal for the README, and add --custom-template-value format=json --outfile ./modules/storage-account/module.json for the JSON.

Document every module in one go

Use --pattern to document every module that matches a wildcard:

bicep docs generate --pattern './modules/**/main.bicep'

Each module gets its own README.md next to its main.bicep. Add --outdir ./docs to put them in a separate folder instead, and Bicep recreates the folder structure beneath it. If a module has compile errors, Bicep reports them, carries on documenting the other modules, and returns exit code 1 at the end.

To see this at scale, the demo repository generates Azure Verified Modules (AVM) style documentation for 20 App Service modules, including their child modules, with a single command. Its template works out each module's registry reference and main resource type from the module itself. The AVM team is standardising and consolidating its tooling, and bicep docs is part of that work.

Keep documentation up to date in CI

Because the documentation comes from the code, your pipeline can check that it's current. Regenerate it, then fail the build if anything changed:

bicep docs generate --pattern './modules/**/main.bicep'
if ($LASTEXITCODE -ne 0) { exit $LASTEXITCODE }

$changes = git status --porcelain
if ($changes) {
    $changes
    throw 'Module documentation is out of date. Run bicep docs generate and commit the result.'
}

The generated documentation is only as good as your descriptions, so the new description linter rules in Bicep v0.47 make a good partner. They're off by default and flag missing or empty @description decorators. Turn on the ones you need in bicepconfig.json:

{
  "analyzers": {
    "core": {
      "rules": {
        "use-description-params": { "level": "warning" },
        "use-description-outputs": { "level": "warning" },
        "use-description-types": { "level": "warning" },
        "use-description-type-properties": { "level": "warning" }
      }
    }
  }
}

There's also use-description-vars for variables. Thanks to @johnlokerse for contributing these rules!

Building tools on top of Bicep?

The same generator is available through the Bicep CLI's JSON-RPC interface as bicep/generateDocs. It returns the rendered text and leaves writing files to you. For .NET, the Azure.Bicep.RpcClient package wraps it.

It's experimental, and we'd love your feedback

bicep docs is experimental. The command options, configuration, template model and built-in layout may change between releases without a breaking-change notice.

One change is already on the way. In v0.47 you can also choose a template with the --template-file and --template-root options. The next release removes these options, so templates are set only with documentation.template.file and documentation.template.includeRoot in bicepconfig.json. The examples in this post already use bicepconfig.json, so they'll keep working.

Try it on your own modules and tell us what works and what's missing by opening an issue in the Bicep repository.

Learn more

Read the whole story
alvinashcraft
44 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Microsoft Foundry Prompt Agents vs. Hosted Agents: What Are You Actually Choosing?

1 Share

You open Microsoft Foundry, choose a model, write instructions, attach a few tools, and create an agent. Then you discover Hosted Agents: agent applications built in code and deployed to Foundry.

Why would you choose the second approach? What does it give you that the agent you already created cannot do?

The difference is how much of the agent’s execution you control. With a prompt agent, you configure behavior that Foundry’s managed runtime executes. With a Hosted Agent, you supply the program that implements the behavior, and Foundry runs it.

Both approaches have a place in production. The architectural decision is deciding where configuration is sufficient and where your application needs direct control.

First, separate “portal versus code” from “prompt versus hosted”

The agent you create by selecting a model, writing instructions, and attaching tools is called a prompt agent.

You can create that same kind of agent programmatically through an SDK or REST API. Writing Python or C# to create it does not make it a Hosted Agent.

A Hosted Agent contains your own executable agent logic. You package that application for deployment, and Foundry provides the managed environment where it runs. Microsoft’s agent overview

Architectural choicePrompt agentHosted Agent
What you provideInstructions, model selection, tools, and configurationAn application implementing the agent
Execution logicFoundry’s managed implementationYour code and chosen framework
Agent application maintenanceNo custom agent runtime to maintainYour application and dependencies
Hosting and scalingManaged by FoundryManaged by Foundry
Main cost componentsModel and tool usageModel and tool usage, plus container compute

The portal is an authoring surface. Hosted Agents are an execution model. Those are different decisions. Compare agent types

A prompt agent can already do useful work

Consider a customer-support agent with access to product documentation and an order-status tool.

A customer asks, “Where is my order?” The agent can call the tool, interpret the response, and explain the delivery status. If the customer asks a follow-up question, the conversation can preserve the earlier context.

Foundry combines the agent’s configuration, conversation history, model interactions, and tool results. Tools extend the agent beyond generating text: they let it retrieve information and interact with external systems. Foundry runtime components

For many applications, this is exactly the right level of abstraction. You concentrate on instructions, tool quality, and evaluation instead of maintaining a custom agent application.

The question becomes more interesting when the sequence of work matters as much as the final answer.

Where a Hosted Agent becomes valuable

Imagine a supplier-selection assistant.

Initially, it needs to find suppliers, compare prices, and explain a recommendation. A prompt agent with appropriate tools is a reasonable starting point.

Then the requirements grow:

  1. Retrieve information from three systems.

  2. Run independent lookups concurrently.

  3. Exclude suppliers that fail eligibility checks.

  4. Use one model for extraction and another for analysis.

  5. Validate that every recommendation has supporting evidence.

  6. Save progress while waiting for purchasing approval.

  7. Submit an order only after that approval is recorded.

This example describes an application you would design; deploying a Hosted Agent does not automatically implement these steps.

What hosting gives you is a place to run the code that controls them. You can choose a framework such as Microsoft Agent Framework or LangGraph, implement branches and validation, and coordinate model and tool calls.

Hosted Agents also support custom dependencies, supported CPU and memory allocations, persistent session files, and protocols for interactions beyond conventional chat. Foundry supplies the surrounding endpoint, identity, scaling, and hosting infrastructure. Hosted-agent capabilities

The practical benefit is being able to express a requirement such as “validate eligibility before requesting approval” as an explicit execution path.

Custom business rules do not automatically require a Hosted Agent

There is a useful middle option: put strict rules inside the tools a prompt agent calls.

Suppose an agent can request a purchase. The purchasing API can reject every request that lacks a valid approval record. That rule remains enforceable regardless of what the model says.

This leads to a useful design question:

Does the logic belong inside one business operation, or does it coordinate the entire process?

If it belongs inside an operation, a prompt agent calling a well-designed tool may be sufficient. If it coordinates branching, retries, checkpoints, and multiple participants across the process, a Hosted Agent becomes more attractive.

For the supplier example, I would keep purchase authorization in the purchasing service even if a Hosted Agent coordinates the broader workflow.

Conversation history and workflow state are different

Remembering what a user said is different from remembering which parts of a business process have completed.

A supplier-selection workflow might need to preserve:

  • The suppliers already checked.

  • Evidence supporting each recommendation.

  • The current approval status.

  • A reference to an order already submitted.

Hosted-agent code can explicitly save this information. Microsoft’s durable state store provides storage for application data and framework checkpoints that survive container restarts. Your application decides what to write and when. An application-owned database or storage service is another option.

The durable state store is currently documented as preview. It does not automatically discover or preserve your application’s meaningful progress. Durable state store documentation

Long-running work still requires careful application design

Two requirements often get mixed together:

  • Continuing work after the initiating request disconnects.

  • Recovering work after the hosting process stops.

Background execution addresses the first. Resilient execution addresses the second.

Foundry’s hosted-agent resilience capabilities can preserve execution information and allow a handler to run again after an interruption. Your application still needs checkpoints or a safe way to repeat the work.

That distinction matters when actions have consequences. Recovering a purchasing workflow must not accidentally submit the same order twice.

Microsoft currently documents these resilience capabilities as preview. Hosting alone does not make an arbitrary workflow recoverable or guarantee that an external action happens exactly once. Long-running agent resilience

What changes for your development team?

A prompt agent can be edited and tested through the portal. Its configuration can also participate in a development pipeline.

For a Hosted Agent, changes to agent logic happen in the application code and are deployed as new versions. The portal still supports invoking, evaluating, monitoring, and publishing the agent, but it does not replace your development environment.

Versioning, evaluation, monitoring, and publishing are available across the agent lifecycle. You do not need to choose Hosted Agents merely to adopt disciplined production practices. Agent development lifecycle

Choose based on the control you need

My recommended starting points are:

Your requirementStart with
Answer questions using documents and toolsA prompt agent
Call business APIs with enforced rulesA prompt agent with custom tools
Automate agent creation and configurationA prompt agent defined through an SDK or API
Control a branching process across models and toolsA Hosted Agent
Run an existing custom agent applicationA Hosted Agent
Manage specialized execution state or input protocolsA Hosted Agent, after checking feature support

A useful test is to finish this sentence:

“I need my program to control ______ during the agent’s execution.”

A specific answer, such as model routing, checkpoint recovery, or coordination between specialist agents, gives you a concrete reason to evaluate Hosted Agents.

If your requirements are met by instructions, knowledge, and tools, a prompt agent can remain the right production architecture.

Need help choosing an approach or building the skills to implement it? Connect with The Training Boss for enterprise AI architecture and hands-on training.

The post Microsoft Foundry Prompt Agents vs. Hosted Agents: What Are You Actually Choosing? appeared first on The Training Boss.

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Muse sure looks a lot like OpenClaw

1 Share

We seem to be entering into an AI agent renaissance. Meta's new consumer-facing AI agent, Muse, topped the App Store charts soon after its release and has 600,000 daily active users in the US, by an Apptopia estimate. And AI agent platform Instinct, whose eponymous creator is fundraising at a $2.5 billion valuation, has been making the rounds in the tech industry. Under the hood, though, there are some obvious similarities to the platform that started it all: OpenClaw.

For the past week or so, some social media users have alleged that Muse is directly built on OpenClaw. The two platforms use the same names for core files (SOUL.md, memory, …

Read the full story at The Verge.

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete

The Xbox reset gets ugly

1 Share
Vector collage of the Xbox logo.

It feels like Xbox has been in a permanent state of turmoil for at least two years now, and this week is no different. Microsoft cut 268 jobs across its gaming division this week, shuffled major studios and franchises around, and continued its Xbox "reset."

Layoffs have become a way of life for Xbox employees, after Microsoft started cutting thousands in early 2024 and hasn't slowed down. The turmoil was particularly apparent when Microsoft started shutting down game studios, and the painful layoffs have had a lasting impact on morale, according to current and former Xbox employees I've been speaking to this week.

At the same time, Xbox h …

Read the full story at The Verge.

Read the whole story
alvinashcraft
2 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories