It’s good to be back home after a fun and exhausting week in Japan. It was touch and go on those flights thanks to that temporary shutdown. Enjoy today’s reading list which features some very opinionated advice.
[blog] Designing an Engineering Strategy. Most of what people call “strategy” is in reality, a vague vision or a set of various tactics. This post recounts some good descriptions of how to discover the core problem to solve.
[blog] MCP vs CLI vs Skills: What Each Costs in Context. The OpenRouter team makes the point clear that sending every tool definition on every turn is very wasteful. Read this post for the data, and advice.
An anonymous reader quotes a report from ProPublica: When Stanley Black & Decker, one of the world's largest tool companies, got hit with President Donald Trump's tariffs last year, the firm made clear that it would be sharing the pain with its customers. The Connecticut-based company raised prices again and again, moves its executives said were necessary because of the new fees on imports. Now, after the Supreme Court struck down Trump's most sweeping tariffs earlier this year, the company is getting at least $298 million refunded. Instead of sharing that bounty with its customers, however, the firm has chosen different recipients: Its own leaders. The company is one of at least nine that have disclosed that they are using their refunds not to pay back the cash-strapped consumers who generally covered much of the tariff costs through higher prices, but to give bonuses, according to a ProPublica analysis of thousands of securities filings and earnings calls for publicly traded companies.
Other recognizable companies include the owners of discount department stores TJ Maxx and Marshalls and the golf equipment brand Titleist. Dozens of other firms have said little about how they plan to use the money other than to characterize the windfall as the kind of earnings they use to determine executive bonuses. The Trump administration has not publicly detailed which companies are getting the roughly $170 billion in refunds or how much they've asked for, and it has denied ProPublica's requests for this information. But reporters found some of these details while reviewing the disclosures of thousands of publicly traded companies.
Some have described vague plans to pay the money forward by, for example, "returning tariff refunds to our members through pricing," though they generally don't say whether that involves price cuts or limiting future increases. Others are paying back businesses they sold products to because they had itemized receipts that detailed the tariff markups. But consumers hoping for refunds appear to be largely out of luck. With the help of artificial intelligence, ProPublica identified companies that said they planned to refund customers with their tariff windfalls. Almost all of them deal with other businesses, not consumers. "Executive bonuses are probably the least just way to use this money because it wasn't anything the executives did that they should be rewarded for. It was a government mistake that resulted in a refund," said Gregory Germain, a corporate law professor at Syracuse University. "It really explains why it's so important for the government, when they're doing something like this, to think it through to make sure consumers don't pay extra money and not get it back."
Developers use AI coding agents in the same codebases day after day, yet agents often start each session from scratch: rediscovering familiar facts, loading unused tools, and repeating unsuccessful approaches.
TokenEconomizer is an open-source plugin that learns from an agent’s past sessions in a repository to reduce waste in future sessions, without modifying the agent or its underlying model.
Across 277 real bug-fixing tasks, TokenEconomizer reduced costs by 18.4–30.9% across multiple AI coding agents. Costs fell in every repository tested, while task success rates remained broadly stable.
AI coding agents are increasingly help developers fix bugs and build features largely on their own, but every interaction with their models consumes tokens. In each session, an agent sends instructions, tool descriptions, and session history to its model. Most efforts to reduce this cost focus on individual tasks. Yet developers return to the same repositories, giving agents an opportunity to learn from previous work. Without that learning, an agent may repeatedly rediscover how to run tests, load tools it never uses, or spend dozens of turns revisiting the same error.
In our paper, TokenEconomizer: Experience-Driven Black-Box Cost Control for Coding Agents, we ask a simple question: can experience in a repository help an agent solve future tasks more efficiently? TokenEconomizer, an open-source plugin from UC Berkeley, Microsoft Research, and Microsoft Security, turns completed sessions into guidance for subsequent ones. It reduces waste without changing the agent or its underlying model, so developers can use it alongside the coding agents they already rely on.
Figure 1. Each finished session teaches TokenEconomizer something about the repository, so later sessions cost less tokens.
Where the tokens go
We first profiled Claude Code on 60 tasks from SWE-Bench, a benchmark of real bug fixes in open-source Python projects, running each repository’s tasks in sequence. Three kinds of waste recurred:
Rediscovering the same facts. After a repository had accumulated at least five completed tasks, 30% of tool calls repeated an action from an earlier task in that repository. Only 7% matched an action in another repository’s history.
Paying for unused tools. The agent received 23 tool descriptions on every turn, but 16 were never called.
Getting stuck on failures. The 17% of tasks that failed accounted for 32% of the spending.
We also tested three popular open-source plugins, each built around a fixed cost-saving strategy. Each lowered costs in some repositories but not others. Together, these findings suggest that effective cost control must adapt to the repository, rather than apply the same strategy everywhere.
Microsoft Research StorY
OptiMind: When the system meets the floor
A three‑month pilot in a Midwestern bottling plant shows what happens when AI moves beyond chat and into decision-making, where constraints shift, stakes are real, and answers must hold.
After each session, TokenEconomizer reads the session’s log and updates what it knows about the repository. It then acts through three mechanisms, using only interfaces the agent already provides, as illustrated in Figure 2.
Micro-skills capture repository-specific knowledge in one-line notes. TokenEconomizer identifies recurring patterns across sessions and proposes corresponding notes. They are added to the agent’s starting context only after several sessions have confirmed the pattern, and retires the note if later evidence contradicts it.
Tool pruning removes tools that repository history suggests the agent is unlikely to use, while always retaining core tools for running commands and editing files. Removed tools can be restored if needed.
Failure-loop intervention watches for an agent that keeps hitting the same failure. A judge model decides whether the agent is truly stuck or still making progress. If it is stuck, the agent gets a short note suggesting a different approach. In the open-source plugin, if the agent is still stuck after the note, TokenEconomizer alerts the developer rather than stopping the work itself.
Figure 2. TokenEconomizer works alongside an unchanged coding agent. Micro-skills add learned facts, tool pruning trims the loaded tools, and failure-loop intervention redirects stuck work. Each finished session updates all three.
The controller is designed to revise its decisions as new evidence arrives. Reported savings also account for the cost of TokenEconomizer’s own model calls.
Saving costs in every repository
We evaluated TokenEconomizer on 277 SWE-Bench tasks from six repositories, using five different AI coding agent and model combinations. For each repository, TokenEconomizer started with no prior session history.
TokenEconomizer lowered the average cost by 18.4–30.9%, as shown in Figure 3, and saved the most in all 30 repository-combination pairs without performance loss. By contrast, lowering the model’s reasoning effort saved similar or larger amounts but led to substantial performance degradation.
Figure 3. On SWE-Bench, TokenEconomizer lowered mean cost per task by 18.4–30.9% across five agent–model combinations (left), while Pass@1 rose in four of them (right).
Savings grow as experience accumulates. Early tasks can cost more while TokenEconomizer learns, but cumulative costs fell below the default in every repository by the sixth task, shown inFigure 4. Each mechanism contributes savings on its own, and combining all three delivers the largest reduction.
Figure 4. Cumulative cost change relative to default over each repository’s tasks, using Claude Code. Starting with no history, every repository becomes cheaper by the sixth task.
The savings also carried over to sequential web development, with costs 16.0–21.2% lower on Web-Bench. On security auditing, where every task is in a new repository, costs were 6.4–19.6% lower.
Looking ahead
TokenEconomizer opens a path toward coding agents that learn not only how to solve tasks, but also how to spend computation more effectively. Its lightweight controller shows how experience can improve efficiency without changing the underlying agent or model.
The open-source plugin makes these directions accessible to developers and researchers. It is designed to run alongside existing AI coding agents without modifying their underlying models, requires no API key of its own, and keeps what it learns on the developer’s machine. We invite the community to use it as a starting point for exploring agents that become more resourceful with experience, adapting how they work, as well as what they know.
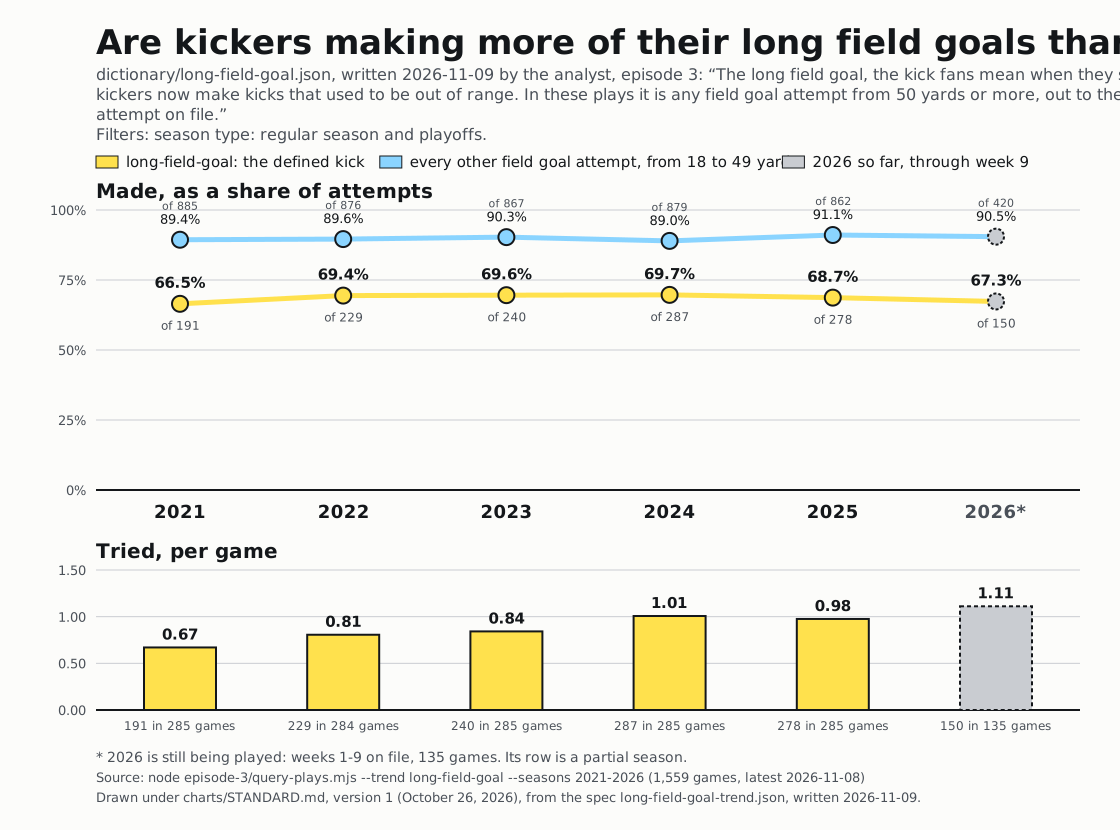
“Kickers are too good now” sounds plausible when long field goals keep making the highlights. But in the November 9 episode of The Monday Morning Agent, our AI analyst found that long kicks went through at roughly the same rate across the seasons on file. Coaches were attempting them more often. We gave the agent written visualization standards so its charts would show both success rates and attempts per game, with the context readers need to judge the claim.
Decide how to draw the trend before seeing the answer
We started with two charts of league-wide field goal success rates. One began in 2024, with a vertical axis starting around 84%. The line climbed to 85.6%, and the improvement looked dramatic.
The other included every season from 2021 onward, started the vertical axis at zero, and showed the attempt count beneath each point. Success rates stayed around 84% to 86%. The recent rise looked much smaller in that context.
Changing the starting year and axis made the recent improvement look larger. Before your agent draws a trend, decide which choices it can make. Otherwise, it can produce a persuasive picture without giving readers the context to assess it.
Keep the definitions when you add a new capability
The dictionary from episode two still applies. During a rehearsal, that earlier agent refused the kicking claim because its dictionary could describe a rush but couldn’t describe a kick. We expanded what it could define while keeping the requirement to use a saved definition.
This time, the play descriptions named field goals and included distances. We still had to decide where “long” starts. A recognizable play name doesn’t settle how to group it for analysis.
We examined distance bands separately. Kickers made roughly 95% of attempts under 40 yards. Success rates hovered around 80% for attempts from 40 to 49 yards and around 70% for those from 50 to 59 yards. Combining them into one rate can hide the differences the question asks about.
Make the chart standard specific enough to enforce
We introduced eight rules. Every trend includes all seasons on file, and axes start at zero. Each point shows its underlying count. Yellow identifies the subject of the claim, blue identifies the comparison, and gray marks the current season.
The chart title asks a question rather than announcing a conclusion. A source line gives the exact command that produced the data, so readers can rerun it. The chart shows only values the tool printed, without added trend lines or numbers typed by hand. Every chart uses the same layout, with success rates above attempts per game.
Writing these standards down gives the agent consistent instructions and gives readers a familiar way to compare results across episodes. Choose standards that fit your analysis, then specify how you’ll check each one.
Test a chart that breaks the rules
A written standard needs a way to enforce it. We added a renderer, the program that turns the agent’s chart specification into a picture. It checks the chart specification against the rules before drawing the chart and refuses specifications that break them.
We deliberately requested a trend beginning in 2023. The renderer refused because the first season on file was 2021. Its response identified the rule instead of producing the shortened chart.
Give your agent a request that violates a standard and inspect the response. That check shows whether the restriction works when the agent tries to produce an output.
Show how much evidence sits behind each rate
The longest kicks need particular care. The episode’s current-season sample contained only nine attempts in the group of kicks from 60 yards or farther. The next kick could noticeably change that rate. Displaying counts beside percentages helps readers distinguish a small sample from hundreds of attempts.
Showing success rates alongside attempts per game helped explain the ruling. In these plays, long kicks weren’t consistently becoming more successful; coaches were trying them more often. More attempts give fans more opportunities to see a long field goal go through.
We also corrected episode two’s results after finding an error in the tool. Our defined substitute for the tush push had a conversion advantage of 10.1 percentage points overall and 9.7 without Philadelphia, replacing the previously reported 8.3 and 7.8. Chart standards help readers inspect results, but we still have to check the calculations behind them.
Next up: “The Pundit Audit”
On November 16, we’ll add a second agent to independently audit an audience-selected claim. We’ll examine where the agents disagree and how they investigate the evidence. The agent doing the analysis shouldn’t also grade its own work.
O’Reilly members can sign up on the O’Reilly learning platform to join us live on November 23, 8:00am–8:45am PT / 11:00am–11:45am ET. Everyone can follow along on Radar every other Monday, with a brief pause for the holidays. Watch episode three above, and we’ll build on it in the next session.
Imagine a CSS karaoke machine that displays a ball bouncing on text that incrementally highlights, based on progress through via speech recognition and running that kind of animation as a single predictable, holistic effect driven by one progress value.
This guide walks developers through setting up Agent Anomaly Detection on the Gemini Enterprise Agent Platform to monitor AI agent telemetry and catch behavioral risks. It demonstrates how to deploy a sample customer support agent, trigger out-of-scope security findings, and configure proactive alerts using Cloud Monitoring and Security Command Center.
 Log in