 Log in

At nine o'clock, the salon has an appointment available next Tuesday. At nine-oh-one, someone holds it while deciding. At nine-oh-six, that hold expires. Nothing about next Tuesday's opening hours changed, but the answer to “can I book this?” changed twice in…

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA

The nail salon has two manicure seats, and one is empty. Can it take a gel appointment at ten? Perhaps. Someone qualified to provide that service must be working, free for the whole treatment, and allowed to serve this client. An empty seat answers only one of…
Pennsylvania, USA
AI-generated code arrives without a label. Food does not. So here is the label, one serving being one pull request, and what to check before you swallow it.
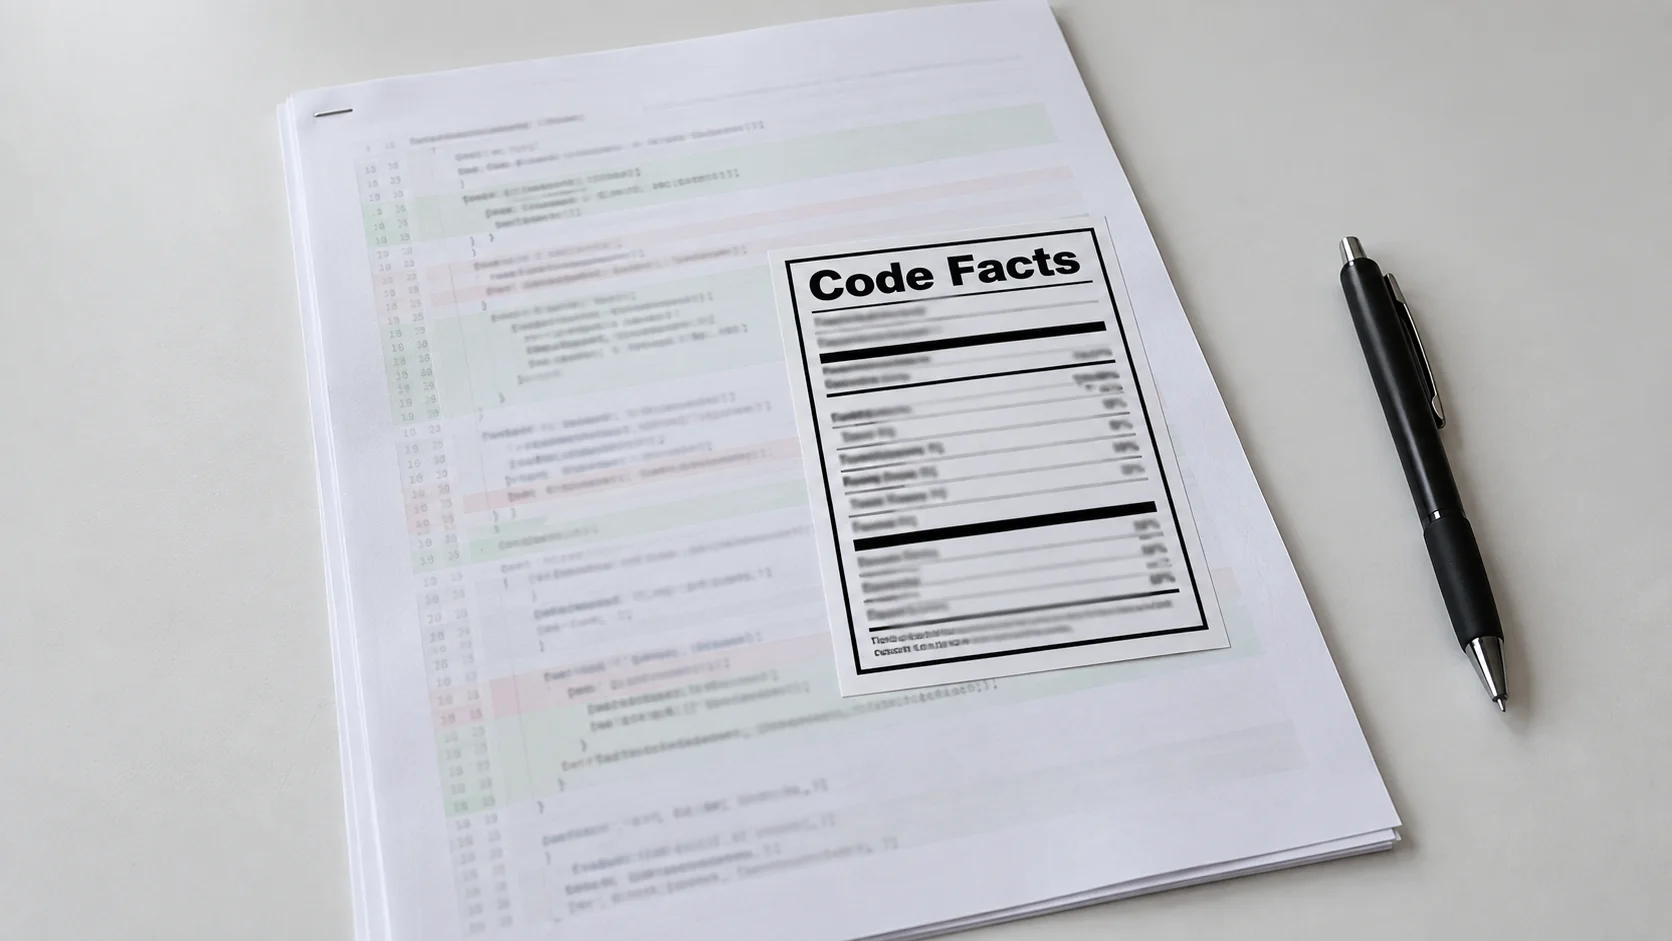
You can’t buy a packet of biscuits without being told what’s in it. You can merge four hundred lines from a model with no disclosure at all.
That seems backwards. The biscuits can’t drop a table.
So I made the label. It has no percentages, on purpose. Nobody has honest ones yet, and a made-up number on a label is worse than a blank.
The label for AI-generated code
Code Facts
Serving size: 1 pull request (about 400 lines)
Servings per model session: varies
Servings per model session: varies
Check before merging
ConfidenceHigh
Backed by a test that was runVerify
Backed by the model saying soAssume
Behaviour changed silentlyCheck
Default values alteredRead the diff
Error now swallowedRead the diff
Error handlingTrace
Catches and logsFine
Catches and continuesStop
Dependencies addedCount them
Assumptions about your dataList them
Unique where it isn’tQuery it
Never NULL where it isQuery it
Security surfaceWalk it
Comments that describe intentKeep
Comments that describe the obviousDelete
Not a significant source of context about why the old code was the way it was. This label carries no percentages because there are no honest ones. Levels are what to do, not how likely.
Print it. Stick it on the monitor. The rest of this post is the ingredients list, one line at a time.
Ingredient: confidence
Model output reads as certain whether it’s right or wrong. That’s the whole problem in one sentence.
So separate two kinds of confidence. There’s confidence backed by a test you watched run, and confidence backed by the sentence “this should work”.
The first is a fact. The second is a mood.
The check: for every claim of “handles the edge case”, find the test. No test, no claim.
Ingredient: behaviour changed silently
This is the one that bites in production. The model was asked to fix a bug and, while it was there, tidied something.
The tidy changed a default. Or reordered two operations. Or made a retry that used to stop after three attempts go forever.
None of that is in the description of the change, because the model doesn’t know it matters.
The check: read every line of the diff that isn’t the fix. Those are the ones to worry about. The fix you were expecting.
Ingredient: error handling
Models love a try block. They also love an empty catch.
Code that catches an error and carries on looks robust in review. It’s the opposite. It has turned a loud failure into a quiet one, and quiet failures are found by customers.
The check: for each catch, ask what happens next. If the answer is “nothing, it continues”, that’s a stop.
Ingredient: dependencies
Ask for a date parser and you may get a library. Ask for a retry and you may get a framework.
Each one is a thing you now maintain, patch, and explain to security.
The check: count the new imports. For each, ask whether twenty lines of your own would have done. Usually they would.
Ingredient: assumptions about your data
This is my corner of the world, so here’s where I get specific.
The model has never seen your data. It writes as though customer IDs are unique, email addresses are present, and dates are in one time zone.
Your database knows better. It has a column called Email with 4,000 NULLs and a customer who exists twice.
The check: every assumption the code makes about the shape of data is a query you can run. Run it. The query takes a minute and the outage takes a weekend.
Ingredient: security surface
Concatenated SQL. Secrets in a config file “for now”. An endpoint that accepts anything because the model was told to make it work.
None of it is malicious. All of it is the shortest path to green, which is what the model was optimising for.
The check: trace every input from the outside world to the place it touches storage. If a string travels that whole way unchecked, stop.
Ingredient: comments
Two kinds. Comments that explain why, which are gold. Comments that restate the line below, which are noise the model produces by the yard.
Keep the first kind. Delete the second on sight, because it hides the first.
What the label can’t tell you
Why the old code was the way it was.
Sometimes a strange line is a scar from an incident. The model removed it because it looked wrong. It looked wrong because the reason was in someone’s head, not in a comment.
No label fixes that. Only the habit of asking, before you delete something odd, whether anyone remembers why it’s there.
How to use this on Monday
Paste the label into your pull request template. Make the author, human or otherwise, fill in the right-hand column.
The point isn’t the form. The point is that “verify” and “assume” become words people say out loud in review.
I write about systems that answer confidently and the people who have to check them. That’s the subject of my book AI: Nobody’s in There. But we’re still in here. All thirty essays are free to read online, and the paperback is on Amazon.
A label is not a warning, it is a list of the questions worth asking.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
First appeared on AI-Generated Code: The Nutrition Label It Should Come With
Pennsylvania, USA

I had a pair of excellent chats with customers here in Japan today. Both were interested in the “how” of AI-first teams. They had some questions I couldn’t answer well—specifically around gathering requirements for agents—that led me to do some productive research this afternoon. Maybe a blog post on the way.
[article] Gemini 4 Carbon: Developer Guide. I like the callouts here for when to use this frontier model, and when Argon is the right choice.
[blog] Gemini 4 Carbon and /swarm. Want a team of agents to attack a problem? That’s what /swarm is for in Antigravity. Get orchestration and visualization out of the box.
[article] Why Leaders Need to Rethink Their Approach to AI Oversight. Leaders respond to AI with more oversight and governance, and wonder why employees hesitate to use it. Provide trust and agency too.
[blog] Introducing Claude Whiteboards, Claude Sheets, and Claude Data. Model API consumption alone isn’t enough to sustain revenue and growth. Natural to see Anthropic shift attention to higher-margin businesses like office productivity.
[blog] Don’t just flag it, fix it: How to run CodeMender in your pull requests. Generate code however you want, but don’t skimp on security practices. Throw this in the mix for code fixes during the PR.
[blog] Hiring Junior Engineers. Good advice. Like Lyft, many companies are hiring for mindset, not just hard skills. But if you’re going for an engineering opening, you’ll need to prove that you’ve created production-quality code.
[blog] Bootstrap your next agent database instance in 2 Seconds. Your agent may need a database. If it does, get one that scales to zero and handles bursts.
[article] Panic over cloud capacity is out of hand. The clouds aren’t full. Simmer down. Yes, certain AI compute is oversold or pre-committed, but we’re all open for business.
[blog] The State of Go in 2026: What Changed In the Golang Ecosystem Since Last Year. Looks healthy to me. Experienced developers who like the language, eagerly embrace modern AI tools, and count more on the standard library versus needing to embed a ton of third-party packages.
[blog] Introducing the Multimodal Knowledge Agent benchmark. This appears to be a useful benchmark. Quality AND cost matter here.
Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:

Pennsylvania, USA


Pennsylvania, USA
Next Page of Stories