Jensen Huang’s exit from Nvidia marks the start of a harder line on China, chip export controls, and corporate power in Washington. NLW breaks down the fight over chip policy, the congressional hearings ahead, the doubts about the spy claims, and what Nvidia’s leadership change means for the AI industry. This main-only cut has no headlines section, so the third sentence covers the market reaction and the new Nvidia leadership instead.
^ I asked Claude to crop the hero image above with the terminal window and it gave itself a Canadian South Park character vibe
Uno Platform 7.0 is out, and it’s a big one. The release blog has the headline numbers (about 2x faster and 5x smaller than 6.7), plus a pile of platform and rendering work that deserves its own posts.
This post is about a companion release that landed the same week: the Uno Platform Studio agent plugin got its 7.0.0 release. If you read my Agent Skills post, we wrote a single skill to teach an agent about MVUX selection. The plugin is that same idea at a much bigger scale, and I’ve been neck deep in that repo for a while now.
Let’s walk through what’s in it, how to install it, and what it will and won’t do for you.
What’s in the Plugin
The plugin is called uno-platform-studio and it has three parts:
The Studio agent. Describe what you want in plain language: a new app from a brief, a feature for an existing app, or a binding, state, or navigation bug. It plans the work, builds and runs the first feature before repeating the pattern, and finishes with a report.
Nine skills. A workflow skill (uno-build-app), a router (uno-platform), and seven domain skills: uno-mvux, uno-navigation, uno-toolkit, uno-themes, uno-authentication, uno-kiota, and uno-testing.
Claude Code hooks. While your app is running, they keep the agent on Hot Reload instead of rebuilding after every edit.
It installs in Claude Code, GitHub Copilot CLI, GitHub Copilot in VS Code, and OpenAI Codex CLI. Agents without plugin support (Cursor, Gemini CLI, Windsurf, Cline, and others) can copy the same skills from the repo’s skills/ folder.
Why Nine Skills Instead of Sixty-Two
The first releases of this plugin shipped one skill per topic. Sixty-two of them. That looked tidy on paper, and then I measured it.
An agent picks a skill from its name and description alone, and every host caps how much room that listing gets. Claude Code budgets roughly 1% of the context window for it and drops the descriptions once it goes over. My 62 skills added up to about 27,000 characters of listing text. In a live session with other plugins installed, 56 of the 62 Uno skills reached the model as bare names with no description. So they never triggered on natural phrasing.
Sound familiar? It’s the same problem from my Agent Skills post, just one level up. A skill the agent doesn’t pick might as well not exist.
The fix was to fold the 62 into six domain hubs. Each hub has a keyword-rich description, a topic map, and the critical rules. The old per-topic skills didn’t go anywhere. Each one became a short reference file inside its hub, and the agent reads it only when the task calls for it. The PR description has all the details, but these are the numbers that mattered:
Skills in the listing62→6Before, 56 of the 62 reached the model as bare names.
Listing text27k→5.3k
8k budget
Characters of names and descriptions, against Codex's 8,000-character fallback budget.
Before and after folding 62 skills into six hubs, from PR #157.
The plugin has grown to nine skills since then, with the build workflow, authentication, and Kiota added. There are 94 reference files across them today, and uno-toolkit alone has 32.
For Copilot in VS Code, add unoplatform/studio to the chat.plugins.marketplaces setting and install uno-platform-studio from the agent-plugins picker. In Claude Code, run /reload-plugins if it asks, then /skills to check that they showed up.
The plugin's nine skills in Claude Code's /skills list, filtered to uno
The plugin doesn’t bundle the two MCP servers it leans on, the Uno docs MCP and the Uno App MCP. They come with the Uno tooling. If you need a refresher on the difference between them, I’d start with the Uno MCP vs App MCP blog post and the setup docs.
Meet the Studio Agent
Don’t start with the skills. Start with the agent, which ships as uno-dev today:
1
2
3
4
5
# Claude Code
claude --agent uno-platform-studio:uno-dev

# GitHub Copilot CLI
copilot --agent uno-dev
Then tell it what you want. The README’s example is “Build me a reading tracker with a yearly goal setting.”
Codex plugins can’t bundle agents yet (openai/codex#18988), so there you copy codex/uno-dev.toml into .codex/agents/ yourself. A small chore, but worth knowing about.
The agent itself is thin. It loads the uno-build-app skill, which owns the process: discover, define a contract for the feature, implement one complete feature, build it, start it, exercise it, and only then repeat the pattern. The skill has a list of rules that do not bend, and these are the ones I’d call out:
Read the project first. Existing apps keep their architecture, navigation, and theme, so an MVVM app stays MVVM.
Exercise the first feature in the running app before copying its pattern.
Never claim a check you didn’t run.
Every control gets an automation id, written with the element and not as a later pass.
The testing skill drives the app by automationId in a single call, with no visual tree snapshot first. A control without one costs the agent a snapshot or a coordinate click every single time.
Then there’s the one that keeps Studio’s own UI out of your screenshots. In an app the agent creates, it adds this to App.xaml.cs:
Otherwise the Hot Reload indicator and the Hot Design button sit on top of the app in every Debug screenshot and under every pointer click. In an existing app it asks you first.
The Studio agent mid-run on the reading tracker, checking each step in the running app through the App MCP
The end of every run is a report that separates what ran, what failed, and what couldn’t run. The closing line is one of three fixed sentences, so the agent can’t say “done” when a required check never happened. In my reading tracker test runs it was “Implementation complete; verification incomplete.”, followed by the list of checks that hadn’t run.
The end of the completion report: what passed, what didn't run, the bugs it fixed, and the closing line
Is It Worth the Extra Time?
I compared the hubs alone against the hubs driven by the Studio agent on that reading tracker prompt, three runs each. Both built an app every time. The difference was what happened afterward.
Measure
Hubs alone
Studio agent
Tests written
none
24 to 32
App MCP responses per run
5 to 6
14 to 26
Bugs found by using the app
none reported
every run
Median cost
$2.60
$7.30
Median time
5.8 min
15.6 min
The reading tracker prompt, three runs per side, from PR #148.
The bugs were real ones, found by actually using the app. A yearly goal that never persisted. Escape deleting a book. A Remove button that did nothing. Then the agent fixed them.
It isn’t free, though. The agent costs nearly three times as much per run and takes nearly three times as long. Three runs a side shows the direction, not a precise size, so treat those as ballparks. The PR description has the full table.
Stop Rebuilding the App
If you’ve watched an agent work on a UI, you’ve seen the loop: edit XAML, rebuild, relaunch, navigate back to where you were, check, repeat. Every one of those restarts costs real time, and Hot Reload is sitting right there.
The Claude Code hooks push the agent toward it. There are two:
SessionStart. In an Uno project, it reminds the agent that a running app is edited through Hot Reload and not rebuilt, and to look for a running app before the first build. In any other folder it prints nothing.
PostToolUse. After the agent edits a .xaml or .cs file, it asks the DevServer whether the running app picked up the edit and passes the answer along.
That second hook runs a command from the new uno-devserver app family that the 7.0 release blog mentions for driving running apps from scripts, CI, and agents. The docs even use it as their example for a hook:
The exit code tells the story. Zero means there’s nothing left to do, usually because the edit applied. One means it isn’t running in the app, and the output says why. Three means a rude edit, and only a restart will pick it up. Four means it’s still on its way. So the agent asserts on the change, fixes the compile errors the status reports, or restarts only when it actually has to.
The hook also says nothing before the app exists. Reminding the agent on every scaffolding edit just taught it to skim the reminders. I covered what the App MCP can do once the app is up in the App MCP tidbit.
What to Know Before You Try It
A few honest caveats:
The hooks are Claude Code only. Copilot and Codex don’t load them, so there the same rule rides along as text in the skills.
App MCP tools depend on your license. A Community license lacks uno_app_element_peer_action and uno_app_get_element_datacontext, which are Pro or Business. The testing skill has fallbacks (pointer clicks instead of peer actions) and reports DataContext assertions as not run.
Release builds can’t be driven by the App MCP. The testing skill verifies them through the platform accessibility tree on Windows and Android. Everywhere else it falls back to a static review and labels it unverified.
The version tracks the SDK. Plugin 7.0.x targets Uno.Sdk 7.0. Marketplace installs use the release tag, and main can describe things that only exist in the next SDK.
Conclusion
The skills got the agent to look in the right place. The plugin wraps a process around them: a workflow, a way to check the work against the running app, and a report that has to admit what it couldn’t verify. It’s still young, so if a skill gives you wrong or missing guidance, please open an issue.
Try it on a small app first and let me know what it gets wrong.
GLM-5.3-Flash combines linear and sparse attention, a mixture-of-experts design, and manifold constrained hyperconnections. A scaled-down version with 25 million parameters can be built in Python and trained on a standard CPU.
We just published a course on the freeCodeCamp.org YouTube channel that will teach you how to build and train a multimodal language model from scratch, covering both pre-training and post-training. The course is from @vukrosic, and all of the code, slides, and experiments are in the GitHub repository linked in the video description.
The model uses a 260-token byte-level vocabulary, a 192-token context, and a small vision encoder that turns a 32 by 32 image into 16 tokens.
In this course, you will learn:
Tokenization & Embeddings Why a small model needs a small byte-level vocabulary and how weight tying shares one matrix between the embeddings and the output head.
Linear & Sparse Attention How linear attention keeps a fixed-size memory of recent tokens while every fourth layer uses sparse attention with an indexer to find distant details.
Mixture of Experts How tokens are routed to a few chosen experts plus a shared expert that learns information common to every token.
Adding Vision How images are split into patches with 2D RoPE and merged into image tokens so the model can recognize digits.
Pre-Training Experiments How data diversity, interleaving, and curriculums affect learning, including how interleaving helps prevent catastrophic forgetting.
Reinforcement Learning How to design reward functions, compute advantages as in GRPO, update only the final layers, and test group size, temperature, and seeds.
After reinforcement learning, the model goes from solving 0 of 24 Python tasks to 16 of 24.
Many systems log their data as JSON, one record per line (NDJSON). GitHub, for example, publishes every public event on its site that way through GH Archive: about a gigabyte per hour. Suppose you want to know which repositories received the most stars over eight hours. That is 7.6 GB of JSON, 2.2 million events.
In Python, the obvious code reads each line with the json module:
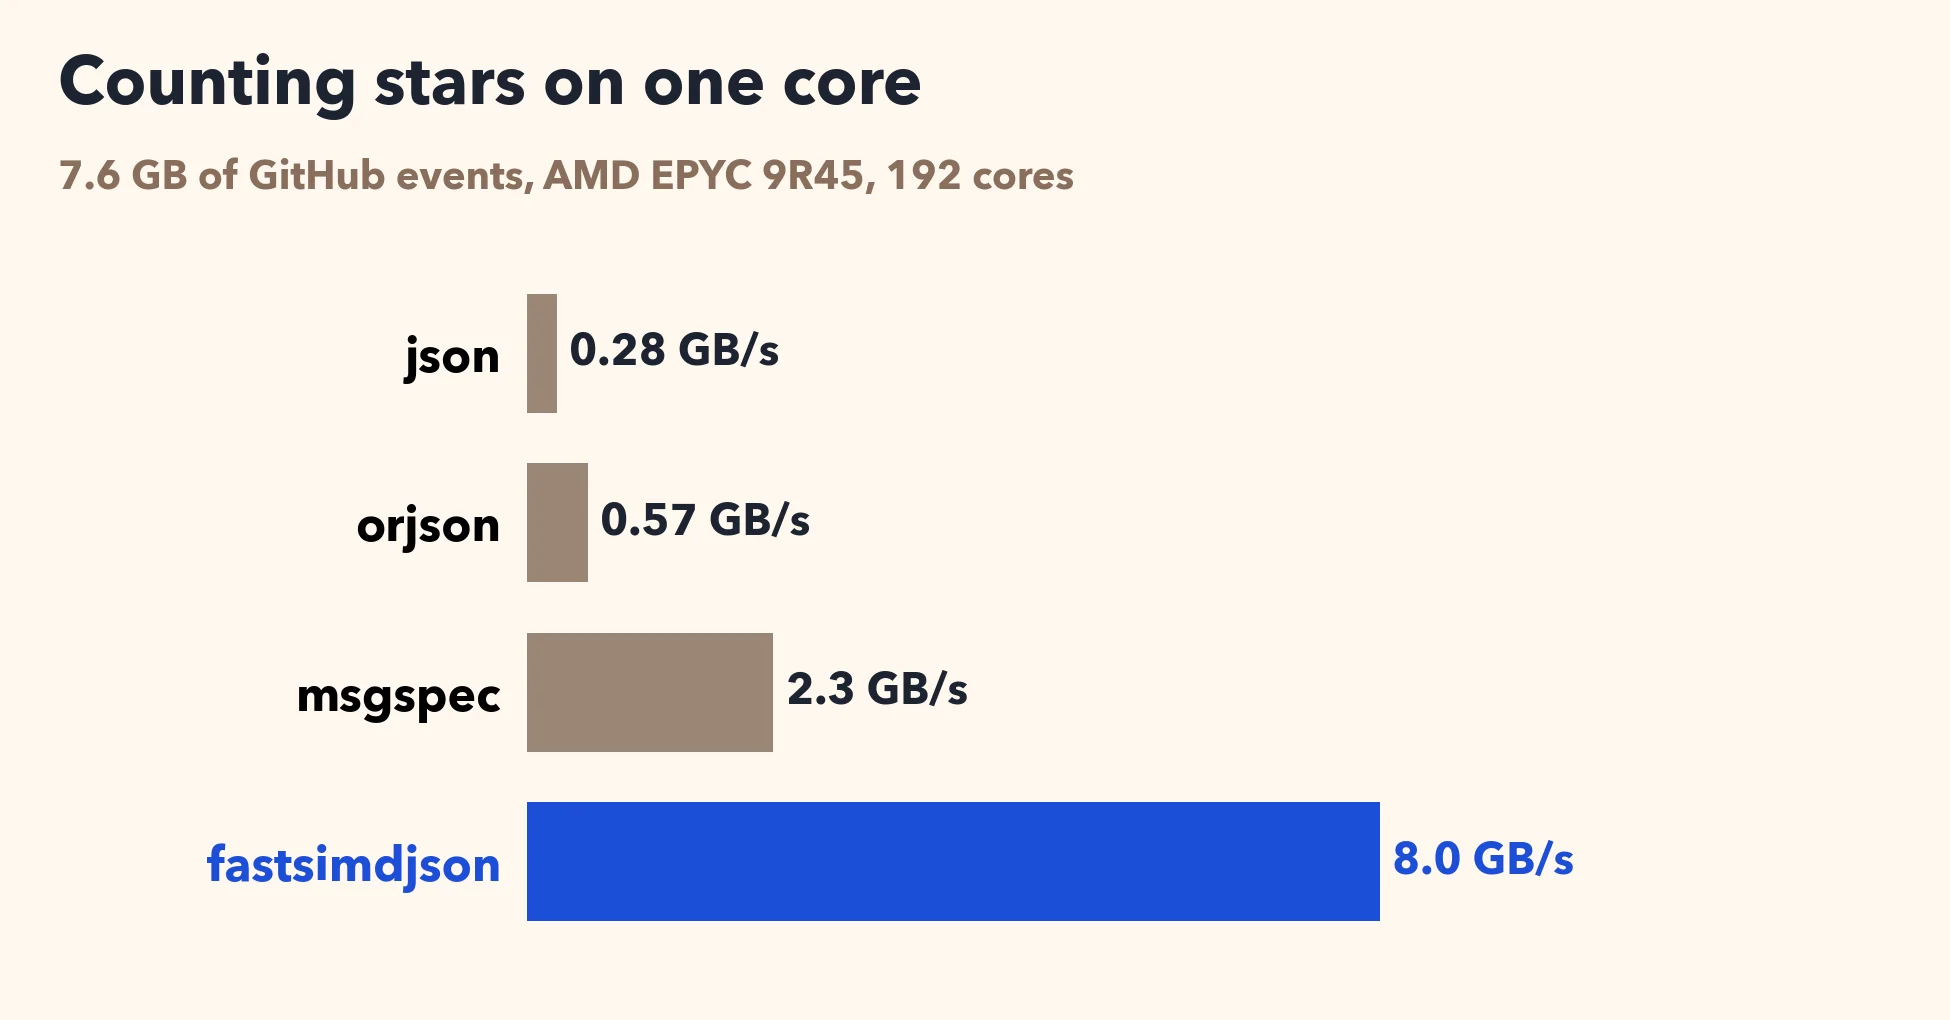
It runs at 0.28 GB/s: 27 seconds for this file. The orjson package is twice as fast. The msgspec package, which decodes only the fields you declare, is eight times as fast.
A server has many cores, but a Python process with the GIL runs Python code on one core at a time. The usual answer is a pool of processes: cut the file in pieces, give a piece to each process, and add up their counts. Each process returns a small table, so little has to come back.
Python 3.14 has a free-threaded build (python3.14t) without the GIL: threads run Python code at the same time. The fastsimdjson library is threaded. You give it the data and a function. It parses the records on many threads, and calls your function on the thread that parsed the record. You name the fields you want. It reads only what leads to them, and your function receives those values, not the whole record.
The variable data is the file, mapped in memory. The two paths are the event type and the repository name. The drop_none parameter leaves out the records that are not stars.
I ran this on an AWS instance (c8a.metal-48xl) with two AMD EPYC 9R45 processors, 192 cores, using Python 3.14.10, orjson 3.13 and msgspec 0.22. The file is mapped before the clock starts. On one core, fastsimdjson reads 8 GB/s, three and a half times as fast as msgspec.
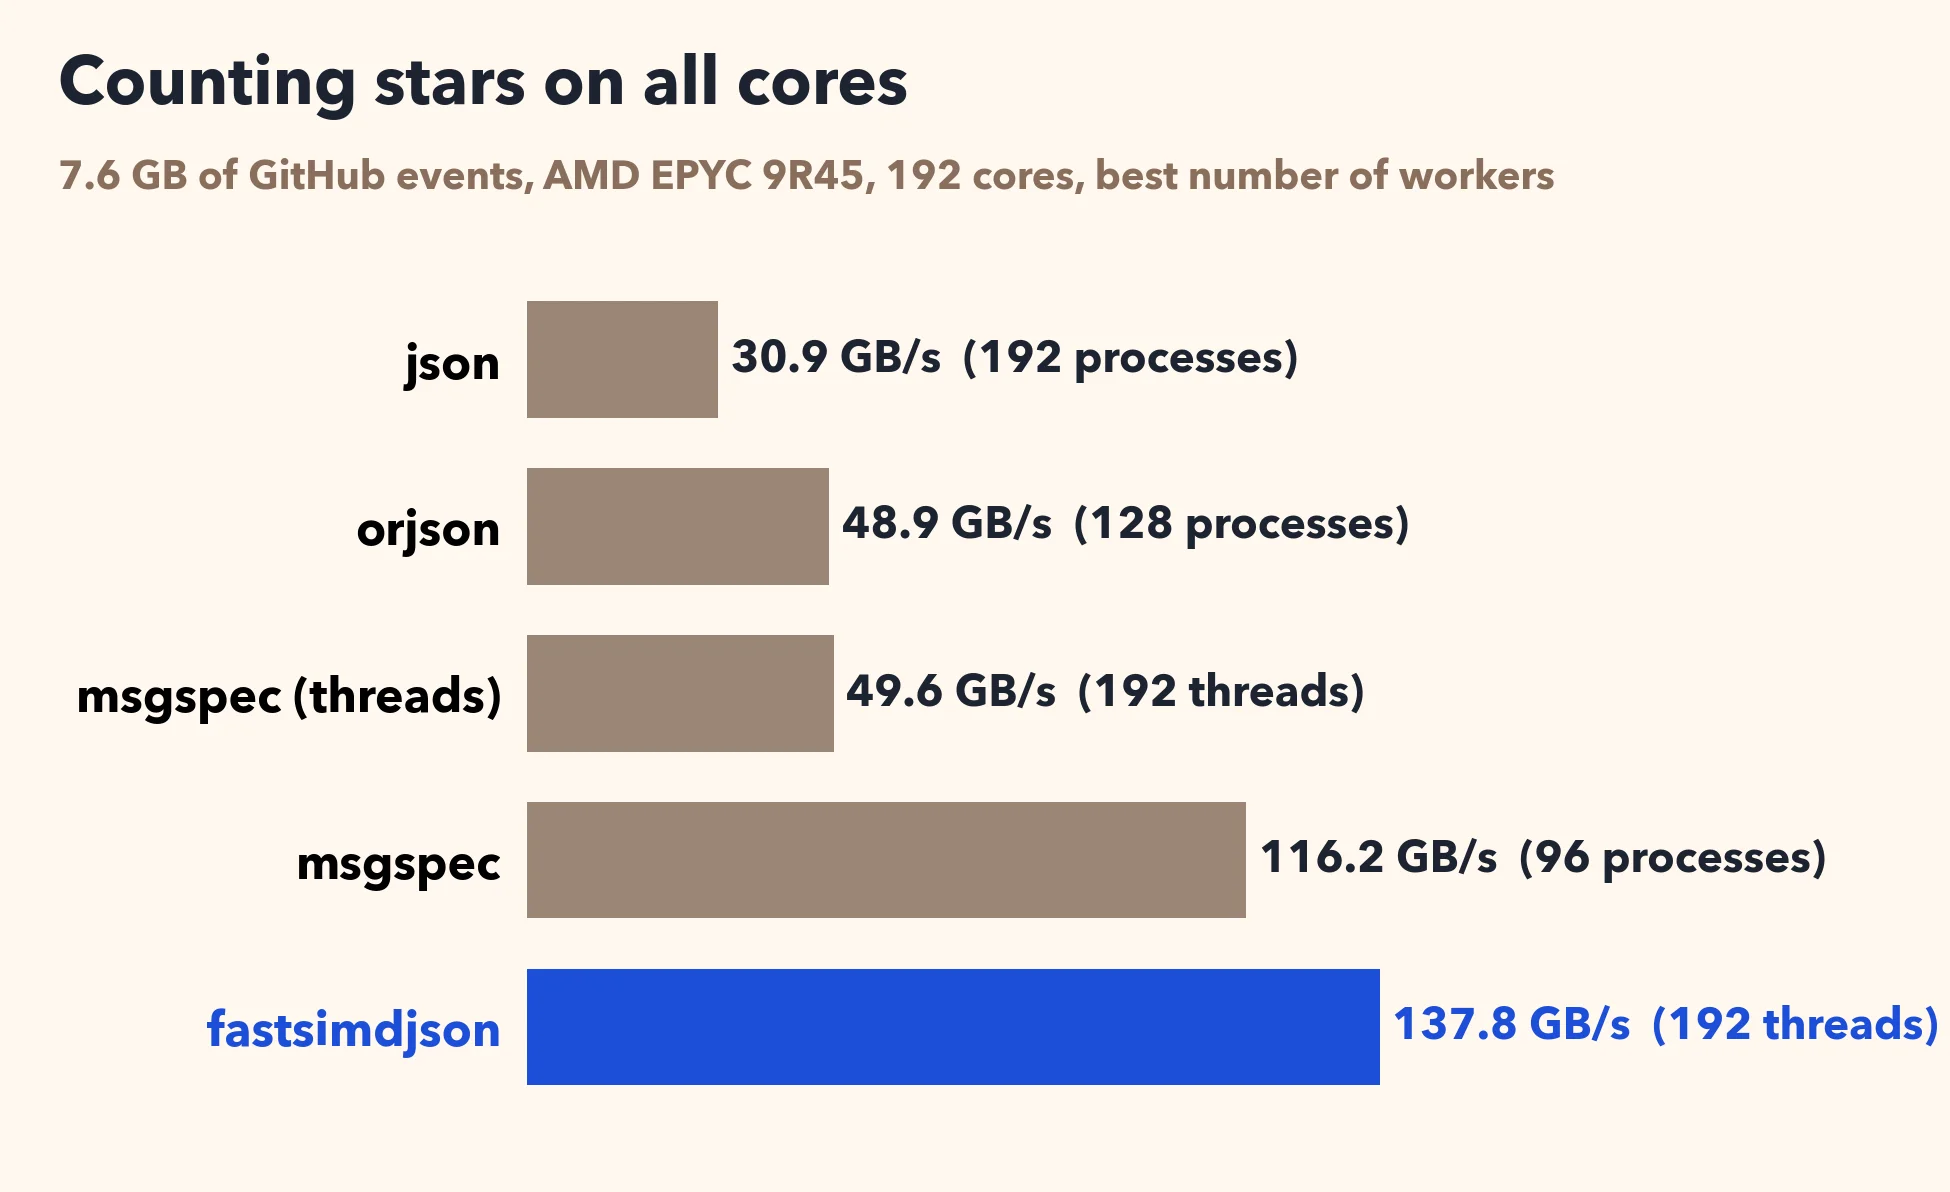
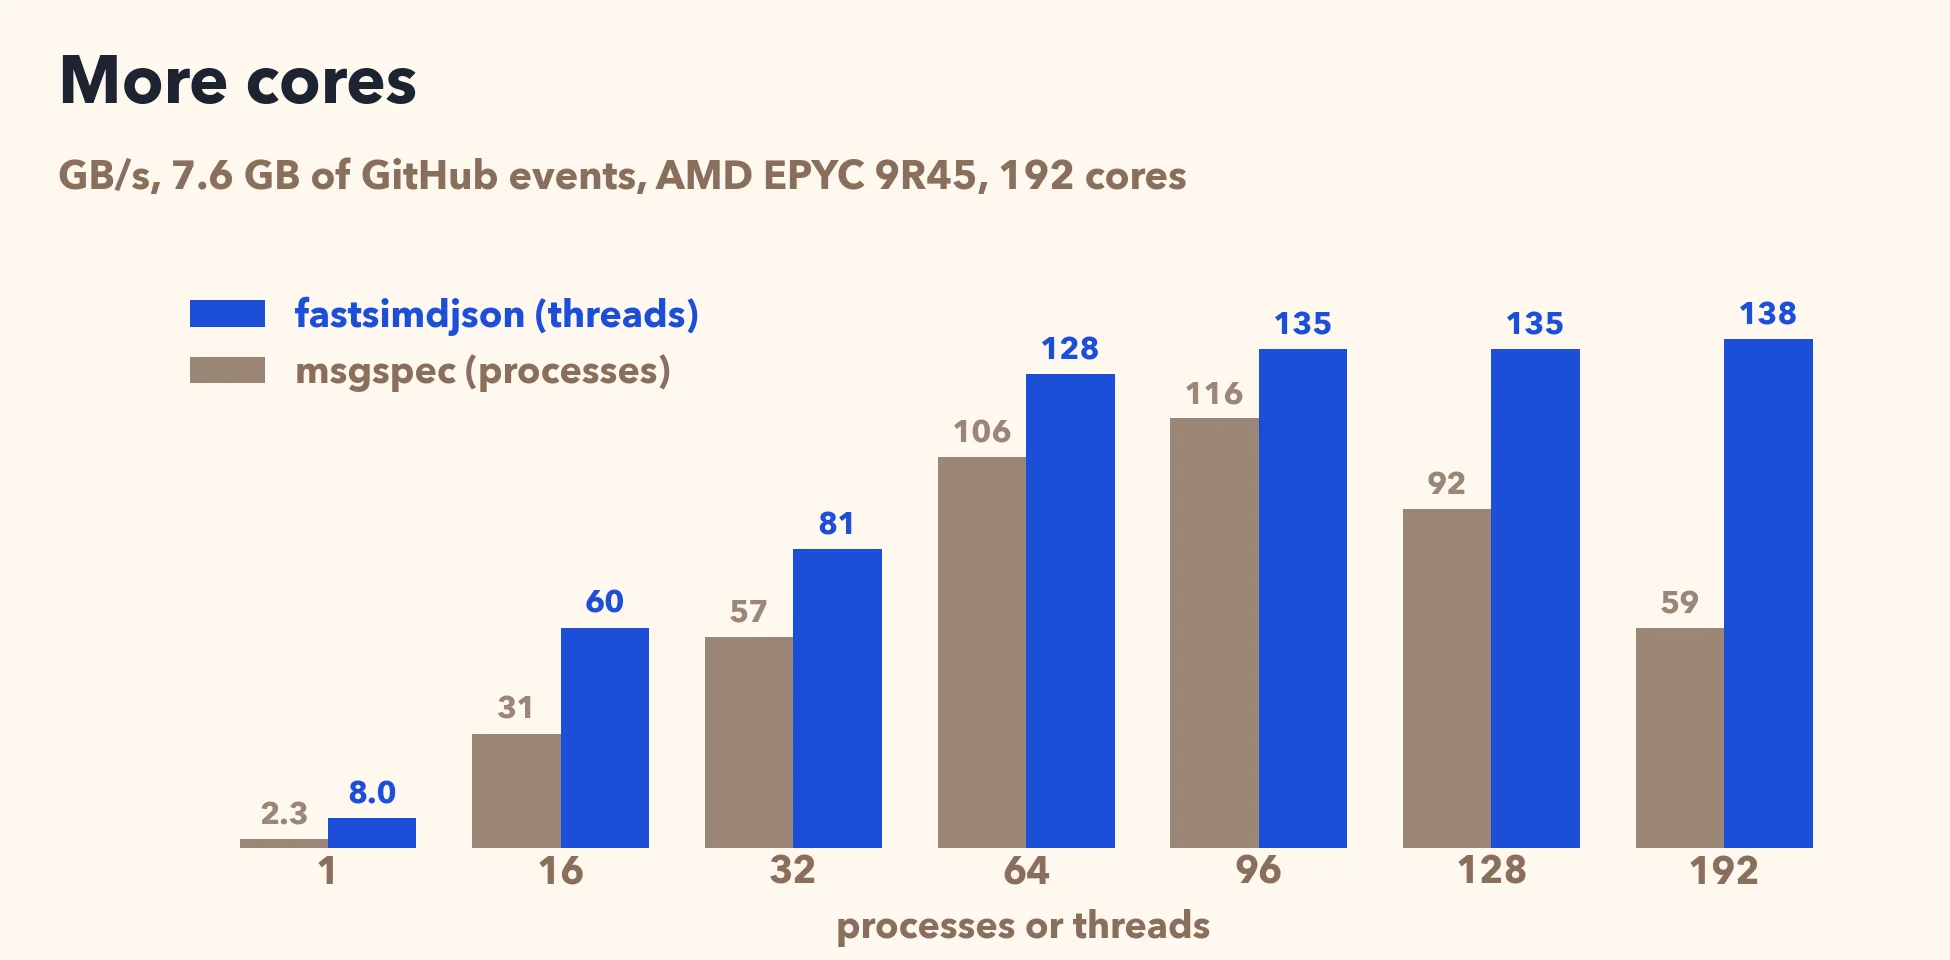
With 192 threads, fastsimdjson counts the stars in the 7.6 GB in 55 milliseconds: 138 GB/s. The best pool of msgspec processes reaches 116 GB/s, at 96 processes. More processes make it slower.
fastsimdjson is ahead at every worker count. The lead shrinks from three and a half times on one core to about 20%.
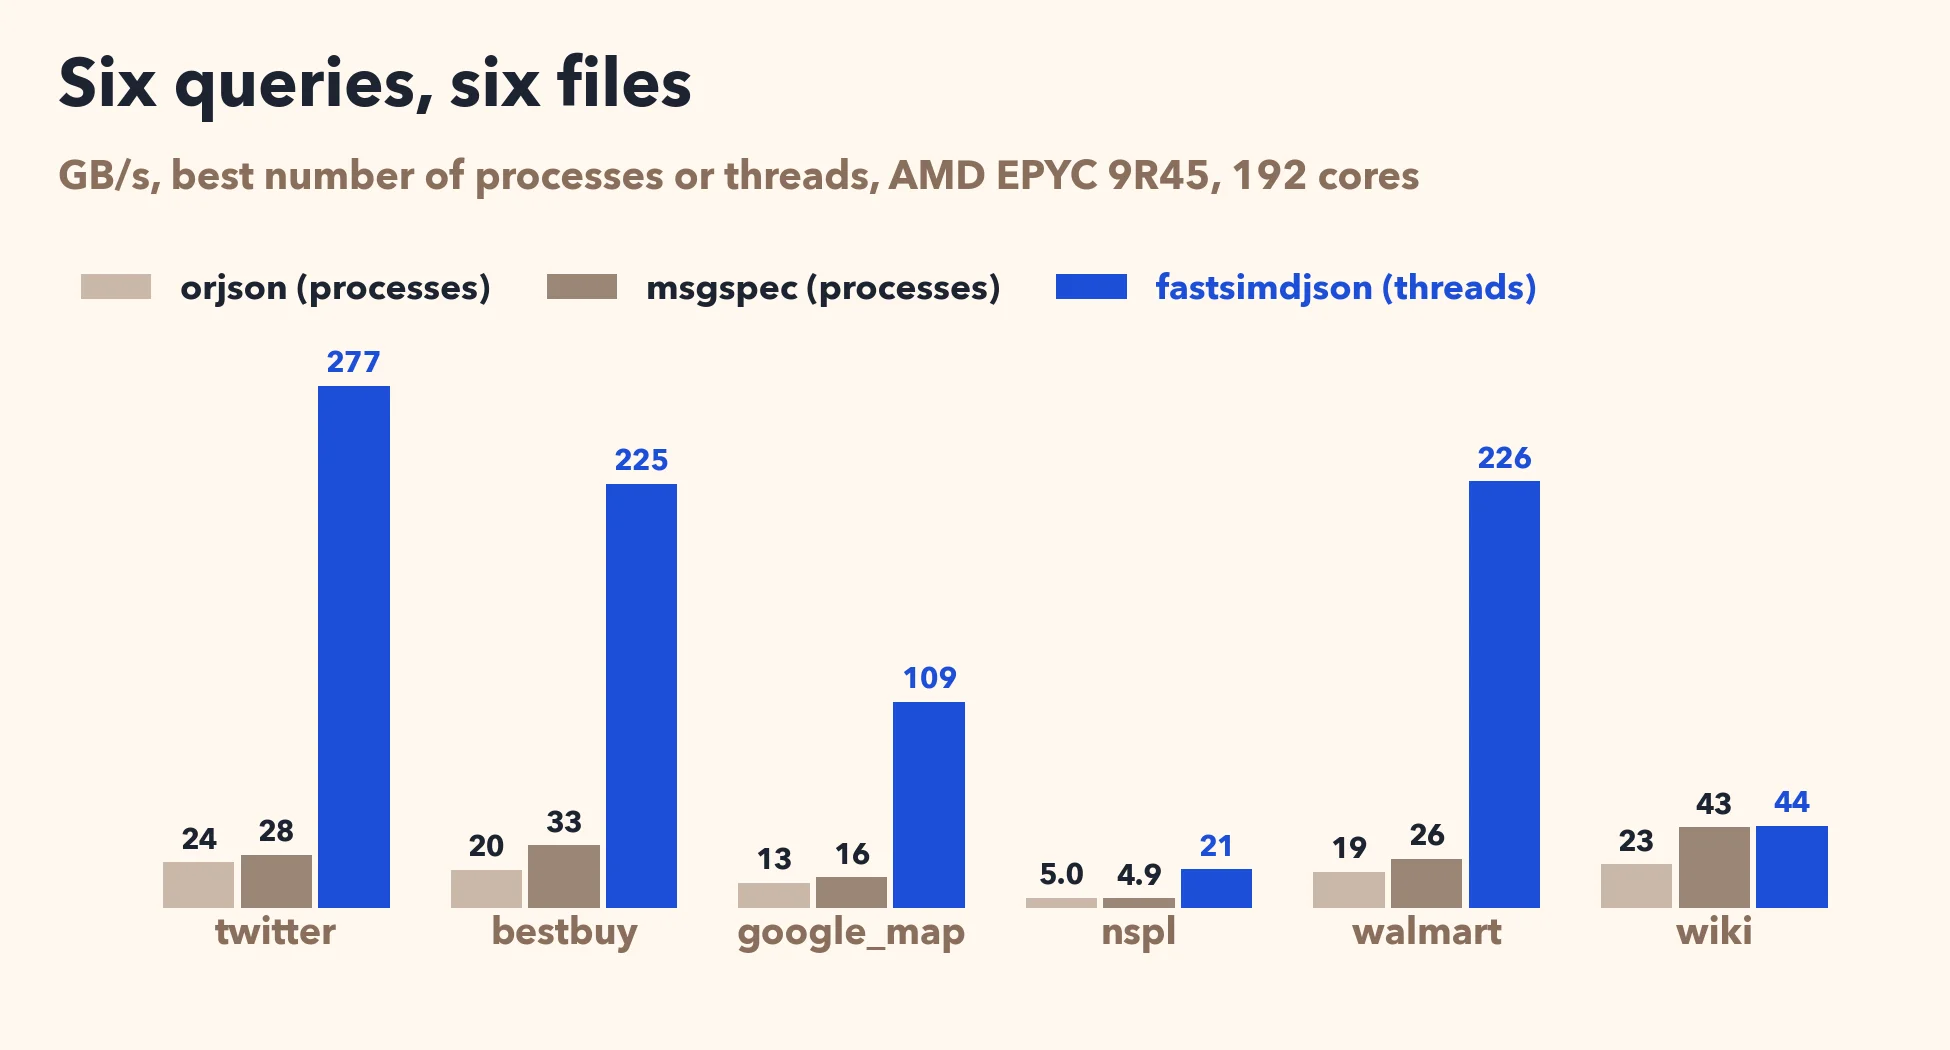
Counting is the best case for processes, because little comes back. Often you want the values themselves. I took six files of about a gigabyte from an existing benchmark (Pison), and pulled a field or two from every record. On the twitter file, fastsimdjson reaches 277 GB/s. Four of the six files pass 100 GB/s. The other two are slower: one stays near 20 GB/s, still about four times as fast as msgspec, and one is a tie.
PasswordBox.Password is not a dependency property, so binding it throws. Attached property vs. CommandParameter, compared on button state and plaintext left.
An operator who cancels a queued job is racing the worker that is about to start it. Deleting the queue message or setting a status column does not decide that race, and a worker that reads the status and then writes over it can start a job that was canceled a few milliseconds earlier. Make the claim that starts the job and the cancellation that stops it competing conditional writes on the same row, so at most one of them can move the job out of the queue. Add a second conditional write before the first effect that cannot be taken back. After the claim, treat cancellation as a request to stop, not a change of state, and record what each request found and what the attempt it lost to went on to do. Hold recovery, leases, and the outbox to the same conditional-write rule, so queued work is recovered rather than stranded and an uncertain delivery is never blindly repeated.
 Log in