Giving an agent a sandbox also means deciding which files it will work on. You can share a checkout from your host, give it a separate working directory for a task, or keep the repository entirely inside the sandbox. Each arrangement changes how you, the human, participate in the work.
You might want to watch the diff in your local editor and make changes alongside the agent, or give it room to manage several tasks while you review the results. sbx supports both. The way you organize the checkout can change as you ask the agent to take on more of the work.
Mounting a repository from your host
Sharing a checkout puts the agent in the working tree you already use. Run sbx run from your project directory, and it mounts that directory at the same absolute path inside the sandbox:
$ cd ~/my-project
$ sbx run claude
Open a file in your local editor while the agent works on it, and you’ll see changes as they happen. Git works from either side, so you choose whether you want to let the agent make commits or you do it yourself. Development servers on your host can pick up the edits through hot reload, using the runtime and dependencies installed on your host.
This fits close collaboration on one task. The coordination cost comes from sharing that working tree: switching branches changes the files the agent sees, and your edits become part of its ongoing work. If you want to switch to something unrelated while the agent continues, you’ll need another checkout.
[!NOTE] Dependencies written into the shared checkout are shared too. Packages with native binaries, such as esbuild, may work in the Linux sandbox and fail on a macOS or Windows host. Reinstalling on the host can reverse the problem. Keep separate dependency installations, or run the app consistently in one environment.
Give each task a separate working tree
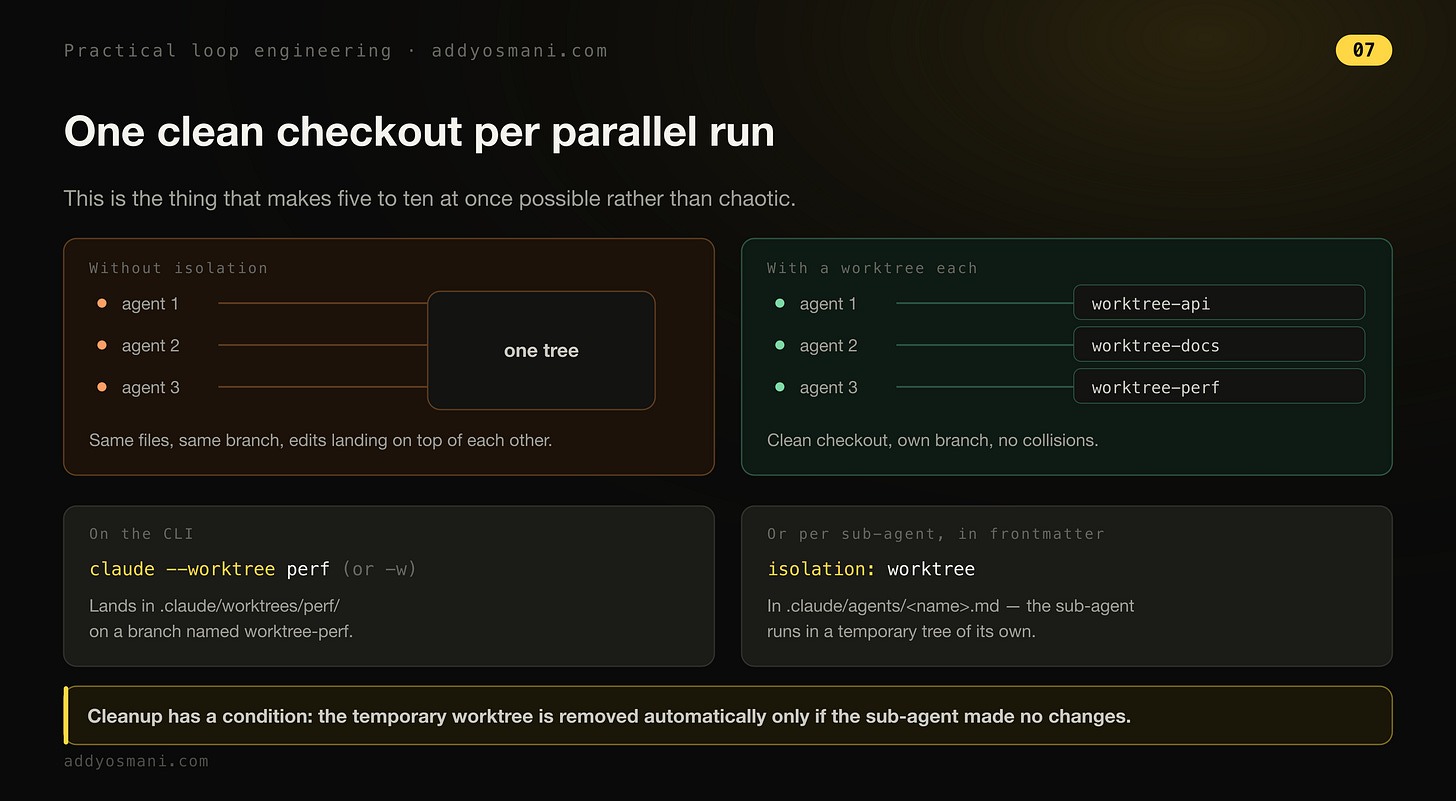
Git worktrees give each task a directory and branch. You can mount each worktree in its own sandbox, while your original checkout remains available for other work. The agent’s edits appear in the worktree. You can inspect either with your local editor and development tools. Each task also gets its own running environment, with tools to prepare and a sandbox and worktree to clean up afterward.
There is a Git limitation with mounting only a linked worktree. Its .git file points to metadata outside the mount, which the agent can’t reach. It can edit files, but checking status, branching, and committing have to happen on the host. The future of software development still needs you to run git status.
sbx supports a clone mode that gives the agent a separate checkout with Git available inside the sandbox. You keep your local project, but sbx mounts the host source as read-only and creates an independent clone for the agent. Its branch changes and dependency installations stay in its checkout.
Bringing the result back becomes a handoff. While the sandbox is running, you can fetch committed branches through the Git remote sbx adds on your host. Or the agent can push to the repository’s remote and you can retrieve the branch through your usual Git workflow. Your local editor and development server see the changes after you bring them into your checkout.
Keep the project inside the sandbox
A mountless sandbox has no host workspace directory attached. Clone the repository inside it, and the sandbox holds the checkout and its development environment. Your host copy of the project shares no connection with the sandbox checkout.
This workflow resembles working on a remote development machine. Agents connect to the project environment, and you can open a shell with sbx exec or connect an editor to the sandbox over SSH. Changes and dependency installations stay separate from your host. To bring work back, you push a branch to the Git remote.
One sandbox per project can be a useful mental model here. The project and its tools persist across agent sessions and sandbox restarts. An agent can create worktrees per feature it’s working on, push branches, and create pull requests for review. Starting another task doesn’t require you to prepare another host worktree and sandbox, and the agent has Git access in each working directory. Clone mode supports this internal-worktree approach too.
Those tasks share tools and services, so running servers or changing the environment still needs coordination. Separate sandboxes are useful when tasks need independent environments as well as separate files. Branches alone don’t isolate simultaneous edits in one working directory.
That independence adds some distance when you want to try the result. Your usual local editor isn’t looking at these files, and a development server running inside the sandbox needs a published port to reach it from your browser.
For a web app preview, ask the agent:
Start the development server on port 8080, bound to 0.0.0.0.
Then publish the port from another terminal on the host:
$ sbx ports my-sandbox --publish 8080:8080
Open http://localhost:8080 in your browser. It’s possible to work interactively this way, but there’s more ceremony than opening a project already on your filesystem.
An environment file can make setup repeatable, selecting tools and cloning the repository at creation with something like the community github-clone kit. Recreating the sandbox then gives you a fresh environment. Push or copy out work you want to retain first: removing a sandbox deletes files held only there.
Choose the repositories for the job
An API change might need a corresponding frontend change, or another repository might provide useful reference material. You can mount several directories into one sandbox, with read-only access for reference repositories. Local editing and previews remain available, but each writable checkout needs branch and change coordination. Task-specific checkouts also leave directories to clean up afterward.
A workspace manager such as jganoff/wsp can assemble selected repositories for a task. Mounting that workspace gives the agent the projects it needs together. These are standard clones with their own Git metadata, so the agent retains Git access, unlike a mounted linked worktree.
The same scope fits inside a mountless sandbox: clone the repositories needed there and keep the whole workspace in the sandbox. The number of repositories and where their files live are separate choices.
Combine the choices to suit the work
The checkout’s location, the sandbox’s lifetime, and the repositories it contains are choices you can combine. You can keep a project sandbox around for many tasks, or mount a workspace assembled for one job. What suits you may change when you want to work more closely with the agent, or give it more room to manage the work itself.
The following article originally appeared onAddy Osmani’s Elevate blogand is being republished here with the author’s permission.
The way that I typically work is I have anywhere between five and ten agents working at the same time in parallel. There are going to be some tasks that I’m very happy to delegate fully to agents, as long as I have a very clear idea of the stopping conditions and the constraints around them. And then there are going to be some tasks where I am going to want to keep a closer eye on and code-review what the agent is doing.
You’ve probably heard about loop engineering. I talked about it a couple of months ago when I wrote a big blog post about it.
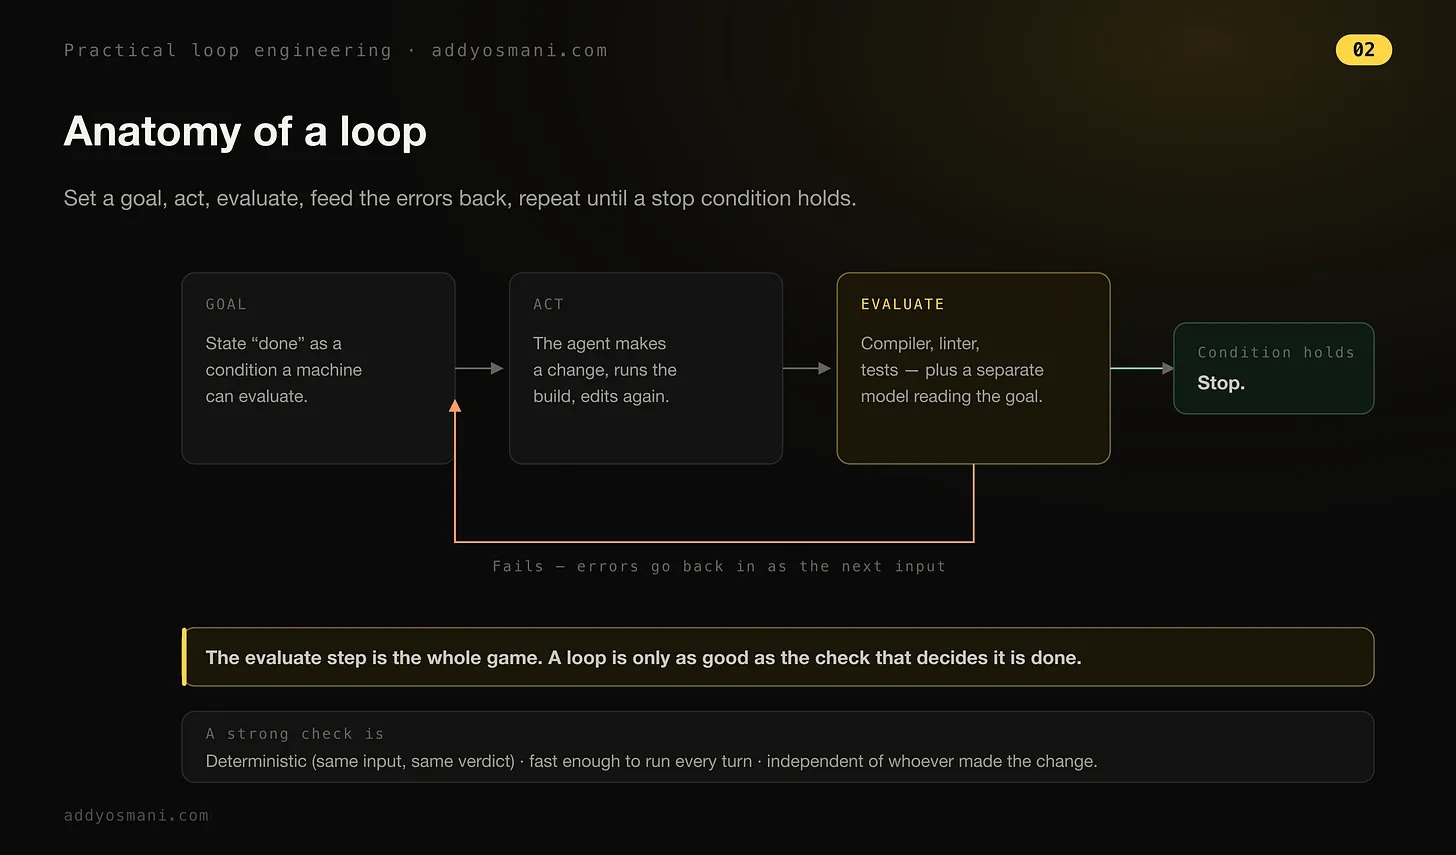
A loop is an autonomous, self-correcting feedback cycle where an AI agent repeatedly acts, tests its results, and adjusts its approach until a specific goal is met.
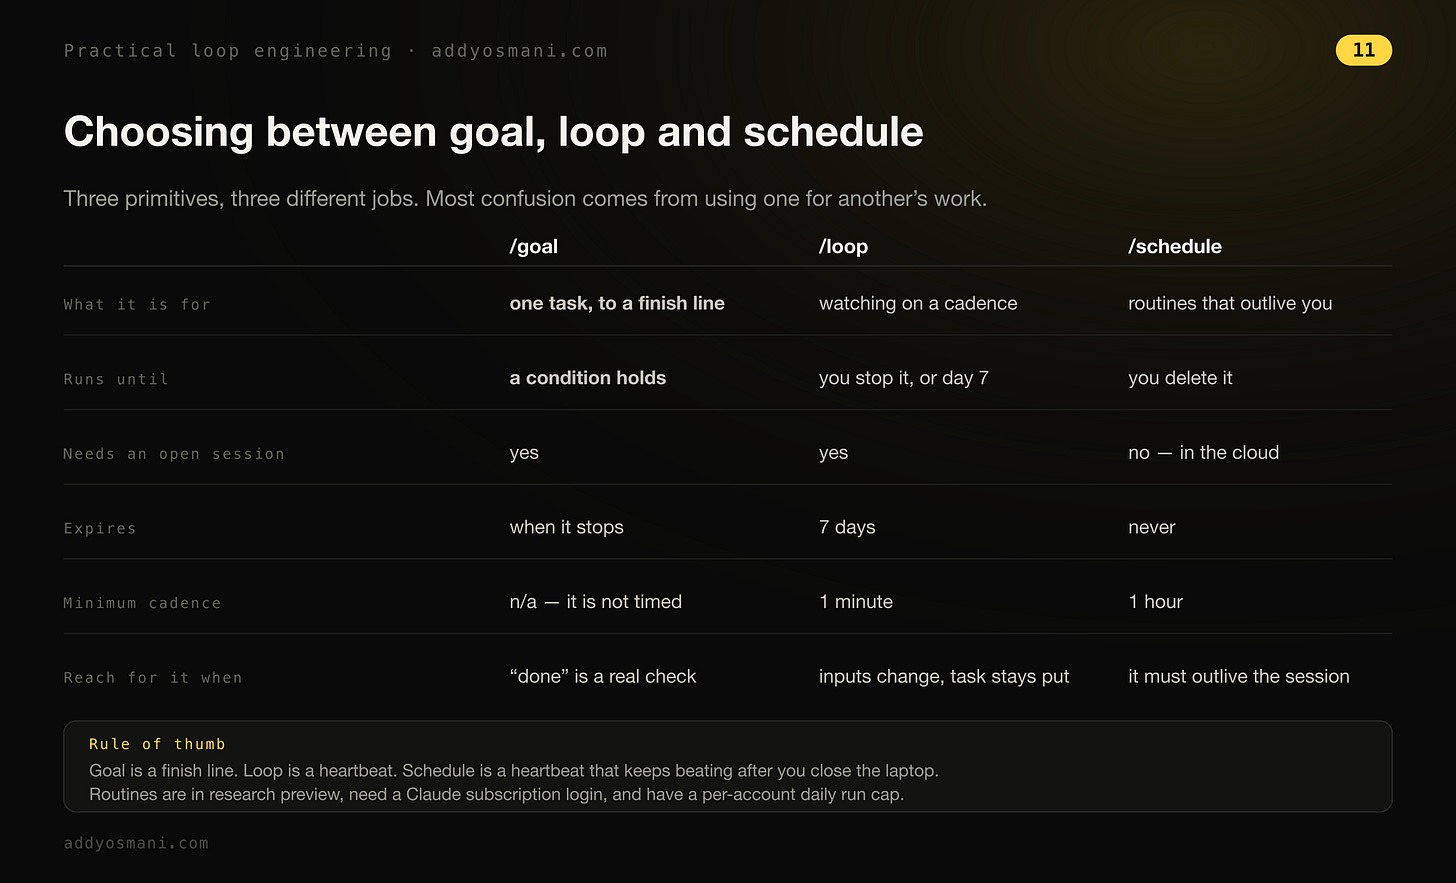
There are now basically two core primitives you can think about. In Claude Code you have a goalprimitive, which can drive a single bounded task forward until you’ve got a particular goal, like a measurable finish line that’s been met. And then loop reruns on a timer or a fixed interval, so you can use it to schedule changes.
Before the primitives were primitives
I remember back before we had primitives baked into Claude Code and Codex: Loop engineering was heavily about setting up your own bash loop, a hand-rolled thing. That’s how I approached it. And you might remember earlier in the year, a number of us were playing around with the Ralph loop by Geoff Huntley. We were experimenting, we were sharing our workflows, we were sharing what worked and what didn’t, but it was largely on some of our personal projects where, if we ran into a wall, it didn’t really have a big cost to us.
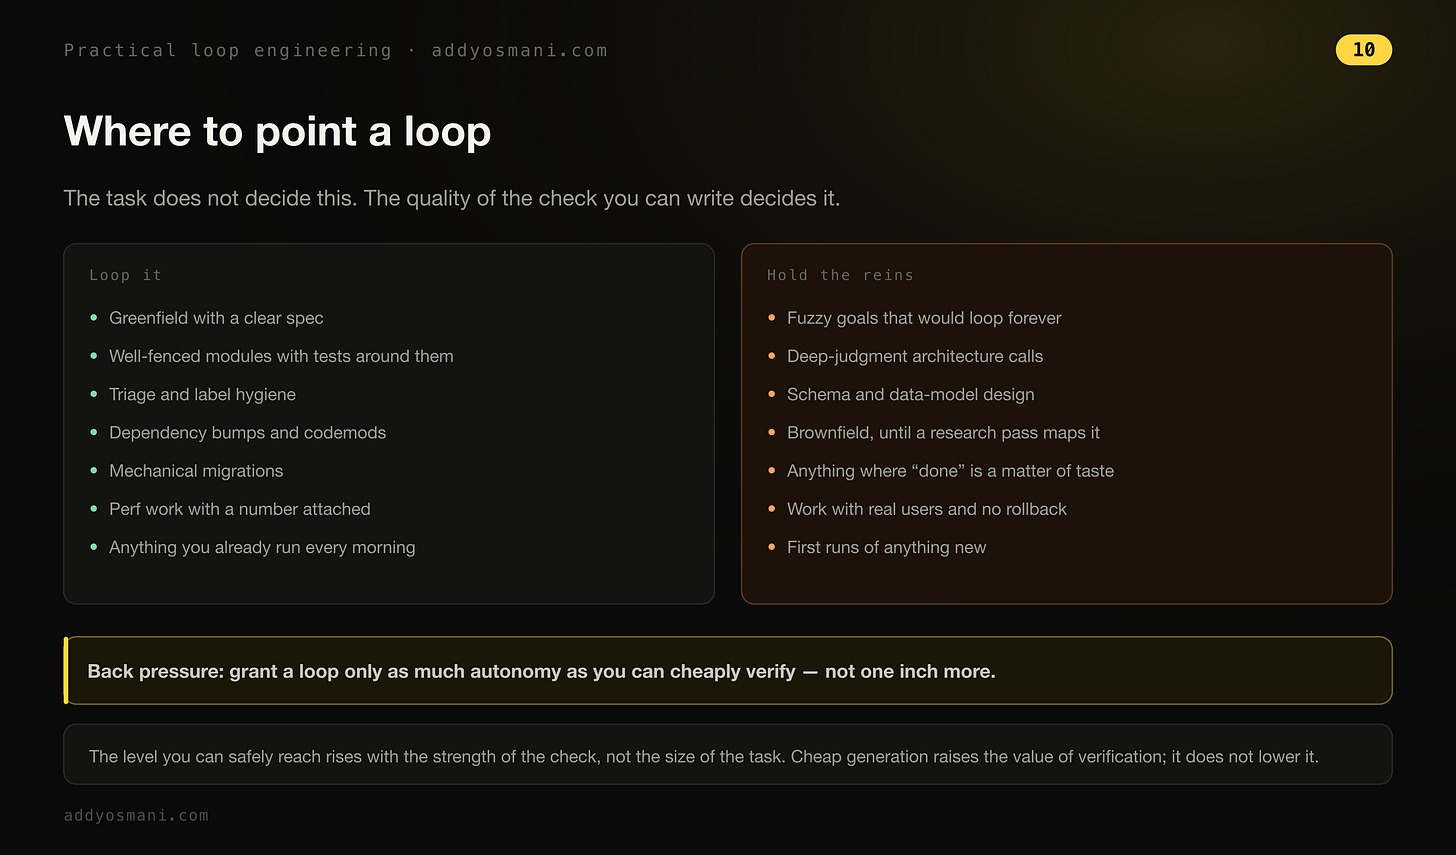
And as we’ve tried to see what patterns and what aspects of loop engineering are now a little bit more baked, I think we have a clearer idea of how you babysit it. I can now largely rely on the output of the primitives in Claude Code and Codex. We’ve come a little way. But at the same time we need to be very diligent, because loop engineering, where you kind of leave it sitting alone and haven’t really thought about whether the end goal or the constraints have been well defined, can leave you in a problematic state. This is why there’s nuance when deciding to use it for an evergreen codebase without users or without as much historical complexity as a brownfield bank codebase.
How the Claude Code team frames loops
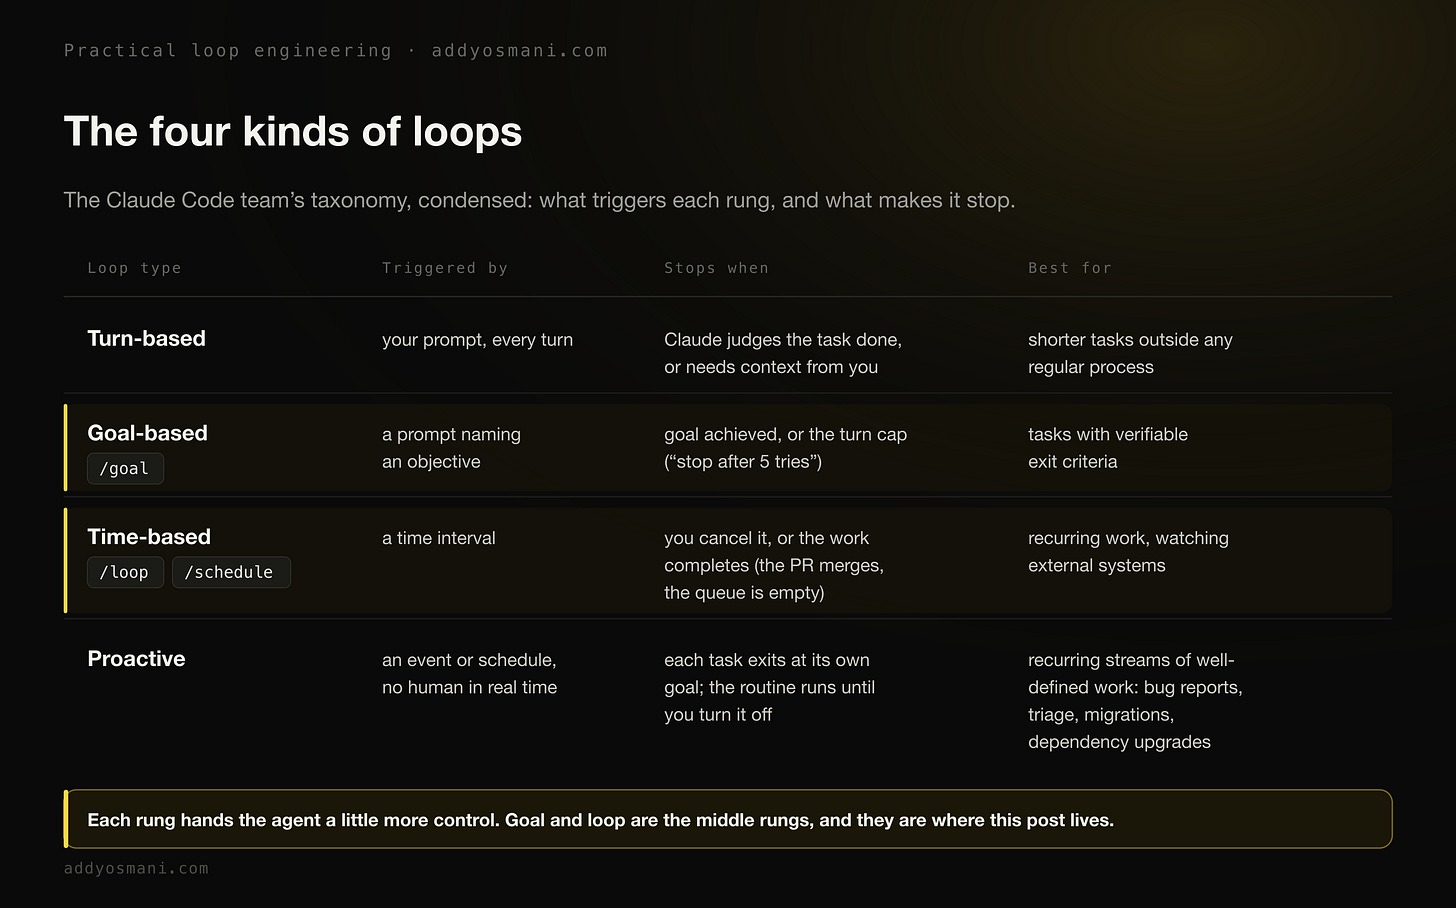
The Claude Code team published their take on four kinds of loops, and it lines up with how I use the primitives (their write-up). Before we get to it, here’s my quick summary:
On the Claude Code team, we define loops as agents repeating cycles of work until a stop condition is met. We categorize a few different types of loops based on how they are triggered, how they are stopped, what Claude Code primitive is used, what type of task is most appropriate for each. Not all tasks require complex loops; start with the simplest solution and use these patterns selectively.
Every prompt you send starts a manual loop with you directing each turn. Claude gathers context, takes action, checks its work, repeats if needed, and responds. We call this the agentic loop. For example, ask Claude to create a “Like” button. It reads your code, makes the edit, runs the tests, and hands back something it believes works. You then manually check the work, and write the next prompt.
Their write-up walks each rung.
On goal-based loops:
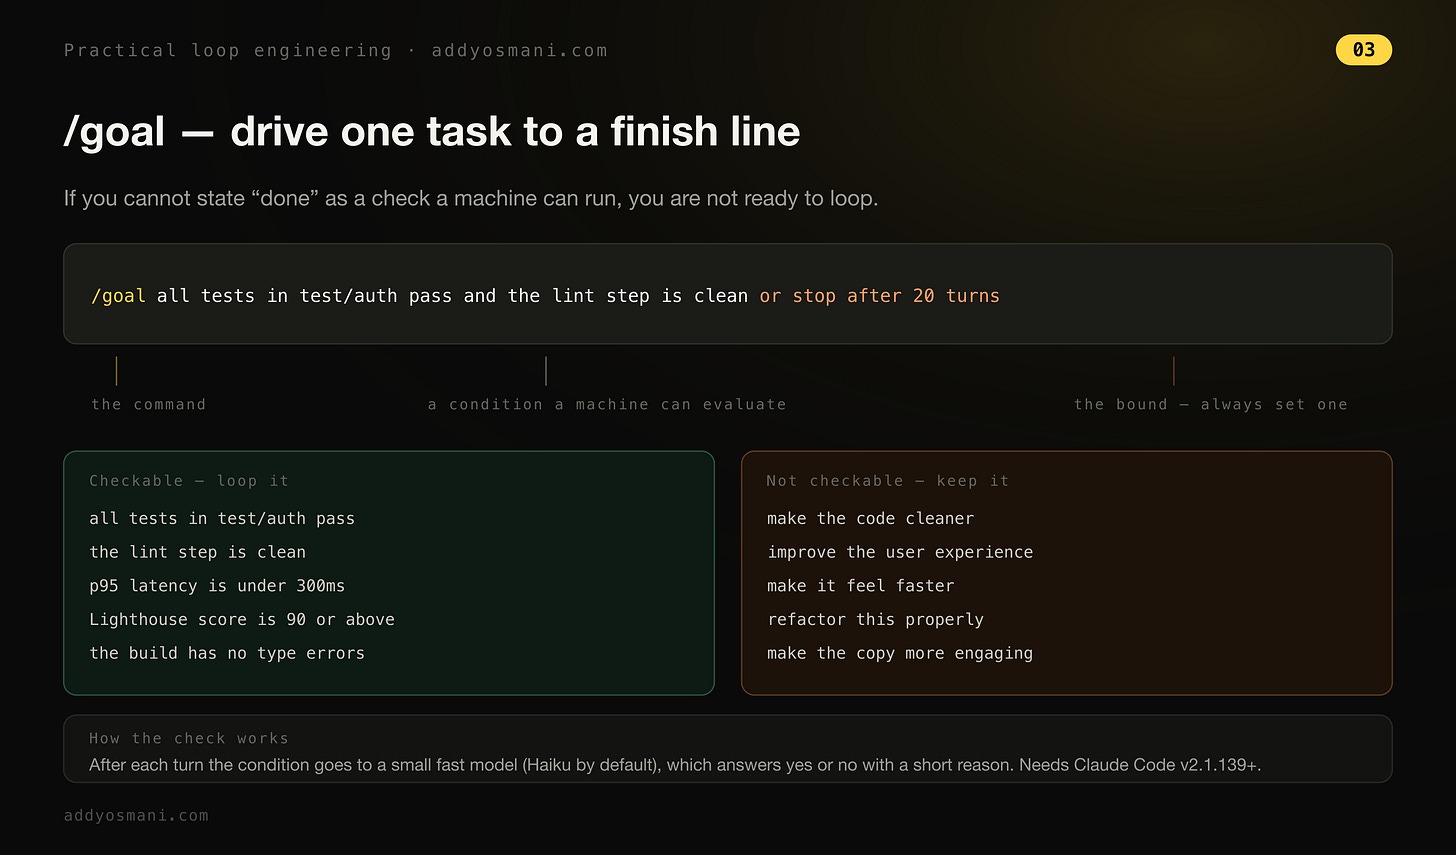
Sometimes, a single turn is not enough, especially for more complex tasks. Agents do better when they can iterate. You can extend how long Claude keeps iterating by defining what done looks like with /goal. When you define the success criteria, Claude doesn’t have to make a determination on what is “good enough” and end the loop early. Each time Claude tries to stop, an evaluator model checks your condition and sends it back to work until the goal is met or a number of turns you define is reached. This is why deterministic criteria, such as number of tests passed or clearing a certain score threshold, are so effective. For example: /goal Get the homepage Lighthouse score to 90 or above, stop after 5 tries.
On time-based loops:
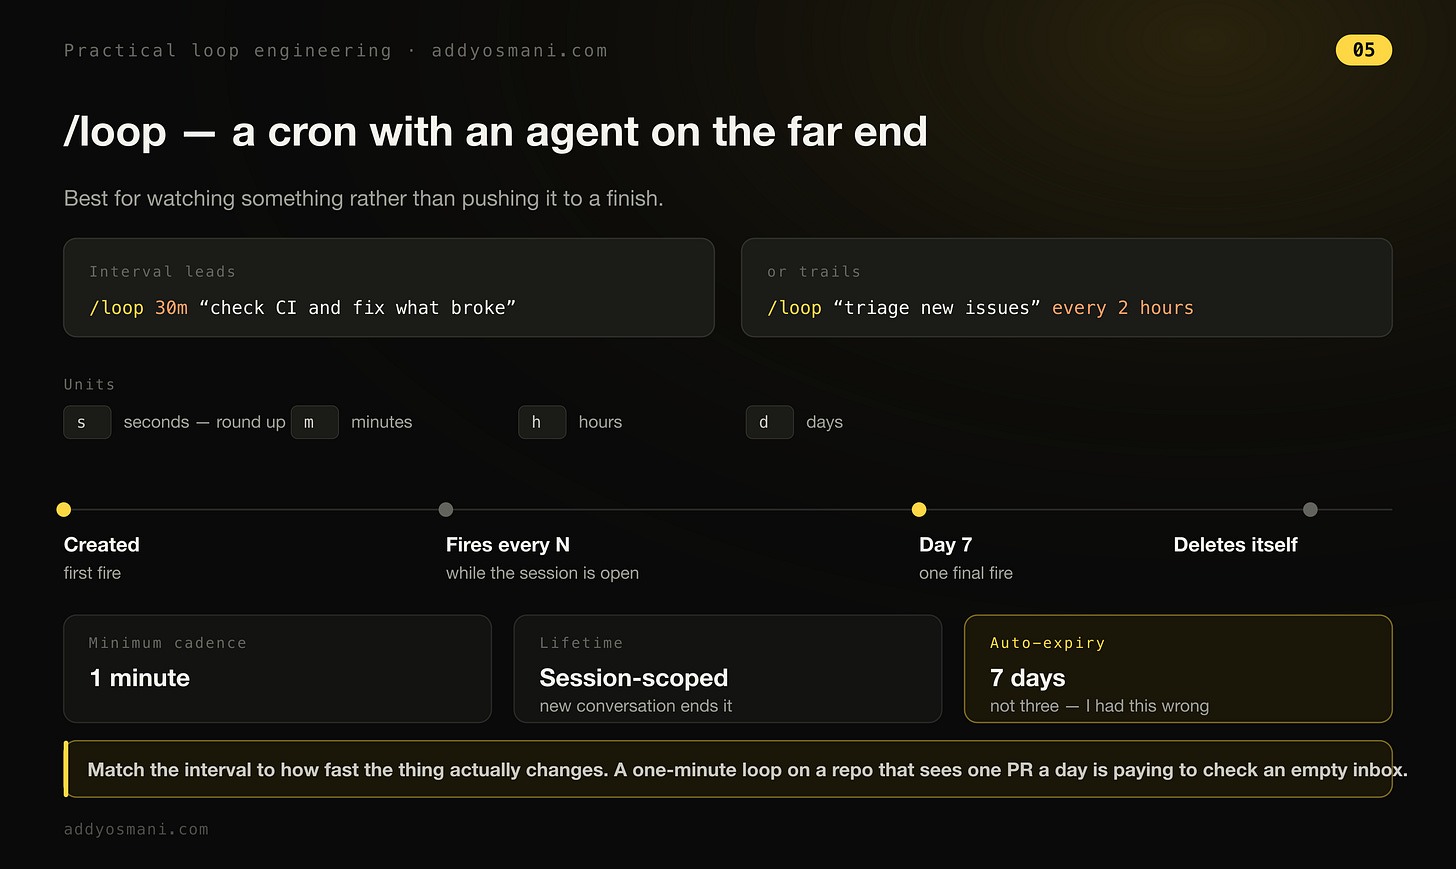
Some agentic work is recurring: the task stays the same and only the inputs change. For example, summarizing Slack messages every morning. Other work depends on external systems, and a simple way to interface with one is to check it on an interval and react to what changed. For example a PR, which may receive code reviews or fail CI. For these, you can trigger when Claude runs with /loop, which reruns a prompt on an interval. For example: /loop 5m check my PR, address review comments, and fix failing CI. /loop runs on your computer, so if you turn it off, it stops. You can move the loop to the cloud by creating a routine with/schedule.
And on proactive loops, the top rung:
Triggered by an event or schedule, with no human in real time. Stop criteria: each task exits when its goal is met. The routine itself runs until you turn it off. Best used for recurring streams of well-defined work: bug reports, issue triage, migrations, dependency upgrades. Managed usage by routing routines to smaller, faster models and using the most capable model for judgment calls.
Their verification advice is worth lifting whole, because it moves the manual checking into something Claude applies itself:
---
name: verify-frontend-change
description: Verify any UI change end-to-end before declaring it done.
---
# Verifying frontend changes
Never report a UI change as complete based on a successful edit alone.
Verify it the way a human reviewer would:
1. Start the dev server and open the edited page in the browser.
2. Interact with the change directly. For a new control (button, input,
   toggle): click it, confirm the expected state change, and screenshot
   before/after.
3. Check the browser console: zero new errors or warnings.
4. Use the Chrome Devtools MCP, run a performance trace and audit
   Core Web Vitals.
If any step fails, fix the issue and rerun from step 1 - do not hand
back partially verified work.
Goal
The way that I use goal is for building any specific piece of work until it’s proveably done. For example, you can use a goal to say: “Make sure that this experience loads in five seconds, keep going until it’s done.” And it will continue to use an independent evaluation check to keep checking if the completion criteria has been met. What’s better is to be even more specific about what tooling is being used.
As for real goals that I’ve run to a number, there’s a few things that I’ve done. I’ve used goals for running through GitHub issues: “Review and close the last 10 issues,” or “Review and move the last 10 issues forward,” something like that. And that’s semi-open-ended, right? Or “Let’s make this page load 50% faster.” Sometimes that works well, sometimes it doesn’t, but it’s really about the experimentation.
Loop
Loop is a little bit more of a scheduler, so it keeps an eye on something or repeatedly executes a pattern on some cadence. Think of it a little bit like a cron. It’s best for doing things like polling logs or monitoring external states. You could use it for potentially checking in. If there are repetitive tasks you find yourself doing on some cadence, loop is pretty good for that.
What I delegate, and what I watch
I use probably between five and ten agents every day. Typically I’ll max out at about five concurrently. And some of those tasks might be ones that are a little bit safer. So maybe it’s: “Hey, I implemented this feature, go write the documentation for it.” Or “Go double check that we have sufficient test coverage.” Or something in that vein. If I’m working on a more complex problem, and I’ve given it a good spec, or what I think is a good spec, and tried to give it some stopping conditions, there’s still a reasonable chance it may not get everything right, so I would try to watch it more closely. If the task involves anything just a little bit sensitive, whether it is “I’ve given this access to a system,” or whether the feature happens to touch authentication, or something related to security or finance, I’ll definitely be watching that closely.
Generally speaking, I do think we’re going to get to a place where folks are increasingly comfortable with delegation, as long as they’re able to have these clear ways of verifying that their goal or their stopping condition has been met. But you do still need to take a look at the code, at the thing that’s being generated, to make sure that it’s meeting your mark.
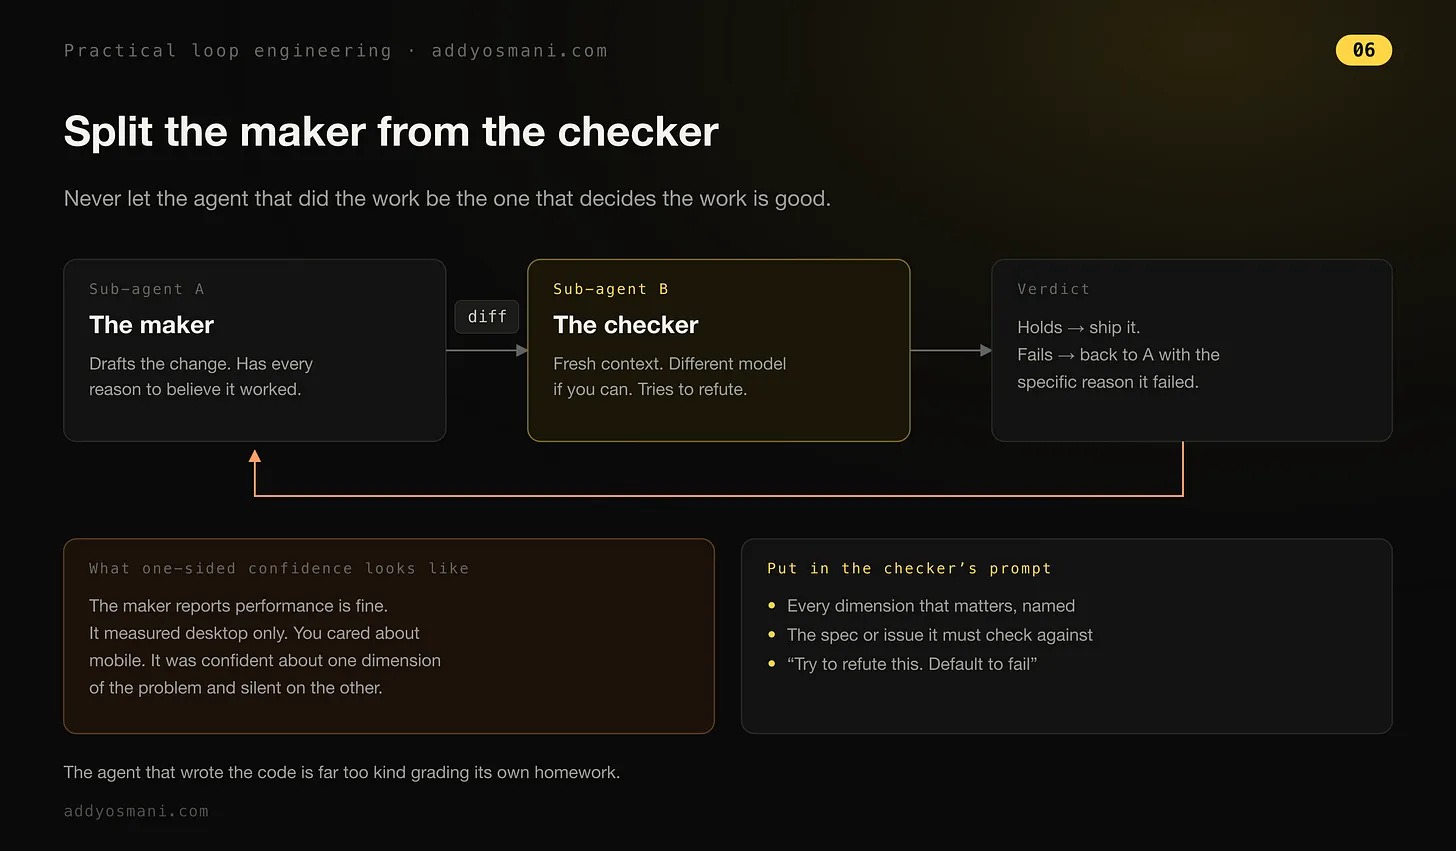
The other habit that matters is not letting the agent that did the work decide the work is good. One subagent drafts the change; a separate one verifies it.
Sometimes an agent can be confident about something, and a verifying agent can catch things that are unexpected. If an agent thinks that the baseline performance of an experience it has generated is actually fine, but it’s only evaluating performance based on desktop, and you actually care about the experience on mobile, that might mean the agent is being very confident about one dimension of the problem but not the other.
And I learned this one the hard way. I was curious to figure out: Is there something that we’re missing that we haven’t gotten direct feedback on from our users, either in an issue tracker or in a comment somewhere? And so I asked it to go and take a look at some of our competitors and put together a list, and some PRs, not pushed, but some PRs locally, of what solving some of those gaps might look like. And I almost pushed some of those changes. But I didn’t actually look at them closely enough. I read through its research, but I didn’t look at the implementations closely enough. So I delegated the task, but I was close to delegating the judgment as well. When I actually looked through the changes, what I realized is that it would introduce a lot of additional complexity for our users, for, I thought, not all that much gain. And so I feel like you need to sometimes check that you are not delegating the taste and the judgment to your agent. You’re delegating the task, and then you are actually checking back that it’s meeting your bar.
The evaluator sitting behind goal is not that checker, by the way. It doesn’t look at the content to see if it’s good or bad in any way, shape, or form. All it does is examine the conversation transcript to see if the hard rules you specified have been met.
/goal Refactor the data-fetching layer in Dashboard.tsx until
Lighthouse performance score is >= 92 and LCP is under 1.8s as
shown by the Lighthouse CLI output. Do not change the public API
of any hooks. Each turn must improve at least one reported metric;
abort if two consecutive turns show no improvement. Stop after 10 turns.
The workflow I run every day
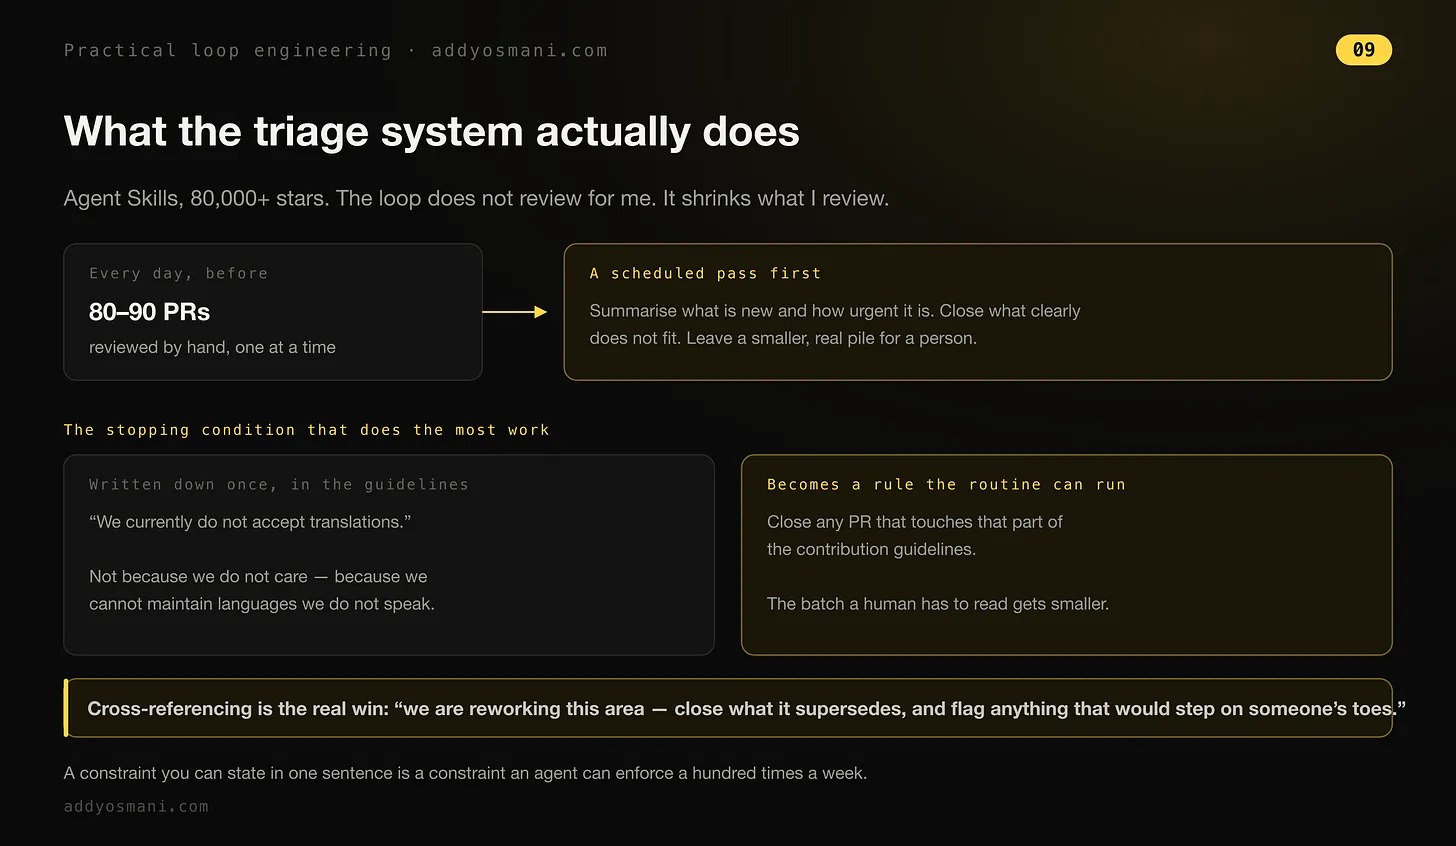
One of the workflows that I do every day: I have a popular open source repository called Agent Skills. We’ve got over 80,000 stars, and up until recently we were getting anywhere from 80 or 90 pull requests that we had to review a day. And so every day I would go and spend some time checking on this. Now with loop, what you can do is say: “Well, every 24 hours or every 12 hours check the GitHub repository for any new open issues and provide a summary of their urgency,” or “Provide a first pass review,” or anything like that.
/loop every 1h "Check the GitHub repository for any new open issues.
Provide a bulleted summary of their urgency."
Combining loops and goals
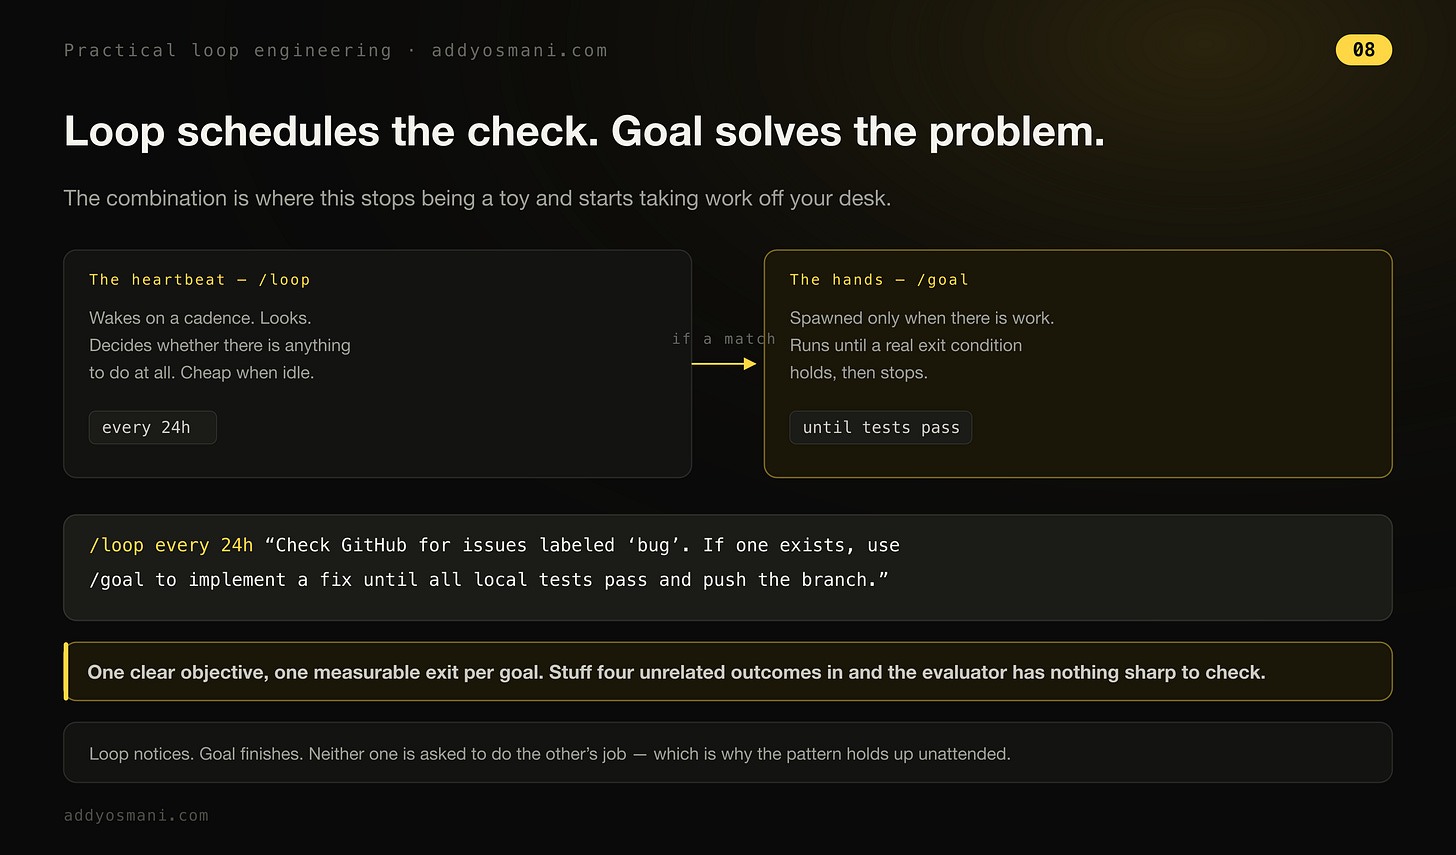
Now you can also sort of combine loops and goals. So you use loop to schedule a check, and then goal to solve the problem. So you can say something like: “Loop for every 24 hours, check GitHub for issues labeled bug. If one exists, use goal to implement a fix until all local tests pass and push the branch.”
/loop every 24h "Check GitHub for issues labeled 'bug'. If one exists,
use /goal to implement a fix until all local tests pass and push the branch."
But also keep in mind that goal has got some limitations around just how much you can cram in there.
Claude Code team’s write-up also has a composed example that shows where this is all heading:
The primitives above, along with other Claude Code features likeauto modeand dynamic workflows (research preview) can be composed into a loop for long-running work. For example, to handle incoming feedback, you can use: /schedule (research preview) to run a routine that checks for new reports, /goal to define what done looks like, and skills to document how to verify it.Dynamic workflowsto orchestrate agents that triage each report, fix it, and review the fix. Auto mode so the routine runs without stopping to ask for permission. Putting it together, a prompt could look like this: /schedule every hour: check the project-feedback channel for bug reports. /goal: don’t stop until every report found this run is triaged, actioned, and responded to. When fixing a bug, use a workflow to explore three solutions in parallel worktrees and have a judge adversarially review them.
What the triage system actually does
Inside the PR triage, when I have loops and goals working together for me, what I end up having is a system that allows me to continue accepting PRs and issues, being able to stay on top of what is coming on my plate every day, and especially being able to cross-reference. That’s been a really big deal for me. If I want to work on a particular goal of, “Hey, we’re going to be redoing this part of the system,” and I need to make sure that any issues that happen to touch it are closed as a result of this rework, or that we’re not stepping on anyone else’s toes, I can make sure that that’s well defined.
Scheduled tasks are really useful for regularly just reviewing new PRs and closing things that clearly don’t fit. One good stopping condition, for example: We have a set of contribution guidelines, and our contribution guidelines include things like, “Hey, we currently don’t accept translations.”
And it’s not that we don’t care, it’s that they’re difficult for us to maintain because we don’t speak all the languages that often come in. And so if we tell it to close any issues or close any PRs that happen to touch that aspect of our contribution guidelines, that’s something that can do really well when it’s on that schedule. And so it reduces the overall batch of things that we need to review.
What loops don’t buy you
I’m often asked what loop engineering is not a great fit for. Generally speaking, if you don’t have a clear idea of what the end-state/done/good means for your completion, it may not be the right pattern for your work. For example, a vague goal would be “Keep going until this UI design is good.” What does that mean? Good to who? How is it being evaluated? Tasks that require human taste, subjective design, or open-ended creative exploration aren’t a good fit. When you have a pretty clear idea of the goal, I think loops are a good option to consider.
The fine print
One classic sign that you’ve got a loop spinning in place is the same command being tried over and over without any change in the result. Give the same command a third time with no change from the second and it’s probably time to stop.
One bit of fine print worth knowing: Recurring loops expire seven days after creation. I’d been telling people it was three days. It’s seven. And loops are session-scoped, so they stop when you start a new conversation, though resuming that session with –resume or –continue brings back any recurring task still inside its seven-day window. If you need something that outlives your session, /schedule runs it in the cloud.
If there’s a check you already run every morning by hand, that’s your first loop. Mine was the pull request pile.
Your developers want to use the best AI agents for the job. As an engineering leader, you need to know who has access, what’s being used, and what it costs. Air Governance brings access, usage, and spend management together in one place.
In this livestream, we’ll explore how to configure policies for agents such as Claude Agent, Codex, and Junie, set spending limits, and review analytics on AI usage, impact, and cost. You’ll see how these settings follow developers across JetBrains IDEs, the CLI, and Air on the web.
We’ll also share practical rollout tips and answer your questions in a live Q&A.
Speaking to you: Viktor Kiselev, Lead Product Manager for Air Governance, and Guillaume Garnier, Product Manager for AI Analytics.
Scott, Wes, and CJ report live from GitHub Universe in San Francisco, breaking down GitHub’s re-architecture for agent-scale traffic, the GitHub Copilot app, Copilot Fusion, Projects, Automations, and AI push protection. Plus hacked conference badges, a USB-C lanyard, and the Syntax macropad.
You can write an empty default constructor as span() = default or as span() {}. It can have remarkable effects on performance.
structspan{constchar*p;intlen;constchar*end;span()=default;// or span() {}span(constchar*s,intn):p(s),len(n),end(s+n){}};
The constructor span() = default on its first declaration makes span trivial. The constructor span() {} is user-provided, so span is not trivial.
Constructor
Declaration
What happens
Members
span() = default
span s;
nothing
uninitialized
span() = default
span s{}
the whole object is zeroed, padding included; the constructor does not run
zero
span() {}
span s;
the empty constructor is called; the compiler can delete the call
uninitialized
span() {}
span s{}
the empty constructor is called; the object is not zeroed
uninitialized
An example
This span is a start pointer, a length, and an end pointer. A box holds one span. The expression box() value-initializes that span. The loop assigns a value-initialized box when i reaches n, and otherwise a span of length i + 1:
With span() = default, GCC 16 stores the end pointer, rbx, straight into the box. The start pointer and the length go through a temporary, and the first 16 bytes of that temporary are copied back.
I time the best of five runs of 100 million spans, on one core of an Intel Xeon Gold 6548N (Emerald Rapids), with -O2 -march=x86-64. My code is available.
compiler
span() = default
span() {}
GCC 14.3
1.73 ns/span
1.74 ns/span
GCC 15.2
7.75 ns/span
1.73 ns/span
GCC 16.2
8.04 ns/span
1.73 ns/span
clang 21
1.75 ns/span
1.74 ns/span
With GCC 15 and GCC 16, the = default version is over four times slower.
 Log in