 Log in
What makes SQL Server 2025 AI-ready, and what does that mean for your applications? Bob Ward explores native vector capabilities, embedding generation, and retrieval-augmented generation (RAG) patterns using T-SQL with local or cloud AI models. See optimized locking in action and discover developer features including native JSON support, regular expressions, change event streaming, and Data API builder. Through application examples, Bob connects these capabilities with security, disaster recovery, and Fabric mirroring. The session also explores SQL Server on Azure Local, including an architecture that keeps data, applications, and AI within a sovereign environment.
|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|


Pennsylvania, USA

Software development is evolving fast.
Agentic Workflows with Contextual AI can be powerful.
But why single Agent when you can have a team?
Meet Squad - human lead AI Agentic team. 🔥
Check out how to use Squad for Uno Platform dev. 🚀
✅ Agent Squad with clear responsibilities
✅ Team roster, routing & charters for guidance
✅ Agnostic Model preferences | History of decisions
✅ Grounded in Uno Platform Skills & MCP Tools
✅ Longer context window | Delegation of tasks
Your Agent factory runs in parallel.
You build software with higher confidence! 💪
Learn more:
Squad: https://bradygaster.github.io/squad/
Uno Platform: https://platform.uno/
Uno Platform Blogs: https://platform.uno/blog/
Uno Platform Docs: https://platform.uno/docs/articles/intro.html
Uno Platform Discord: https://discord.com/invite/XjsmQHdKfq
Pennsylvania, USA


Cloudflare is going all-out to ensure that AI coding agents can check their work without exhausting available computing resources, leading a new effort to bring Microsoft’s TypeScript compiler to Rust.
But whatever you do, don’t call it a fork.
Taking to X, Cloudflare’s director of engineering Christoph Nakazawa confirmed that the company is taking ownership of tsrs, a Rust port of TypeScript that it claims is up to eight times faster, and uses 70% less memory than TypeScript 7.0.
Microsoft’s own TypeScript compiler is reaping the benefits, too, with the teams sharing optimizations as they work to keep the two implementations in sync.
“We are not forking TypeScript — we are working with the TypeScript team and as a result 7.1 is already ~2.5x faster, too,” Nakazawa writes.
That “port vs fork” message runs throughout the accompanying blog post, co-authored by Nakazawa and fellow Cloudflare engineers Boshen Chen and Dimitri Mitropoulos, who go to great lengths to explain that they very much see TypeScript as Microsoft’s to continue steering.
“To be clear, we are not forking TypeScript. We believe the TypeScript team should remain in full control of the language’s design and direction.”
“To be clear, we are not forking TypeScript,” they write. “We believe the TypeScript team should remain in full control of the language’s design and direction. They have maintained a long-term vision while guiding TypeScript’s adoption across the JavaScript community. We do not want to change that.”
Why Rust, when Microsoft already has Go?
Developed and released by Microsoft back in 2012, TypeScript extends JavaScript with a type system that helps developers catch errors before their applications run. However, checking those types can consume considerable computing resources, particularly in large projects where multiple AI agents may be writing and validating code simultaneously.
Microsoft addressed some of those performance problems in July with TypeScript 7.0, replacing its JavaScript-based compiler with one written in Go and delivering roughly tenfold speed improvements.
As The New Stack previously reported, Microsoft had considered Rust for the rewrite, but concluded that reproducing TypeScript’s existing architecture in Rust would introduce significant complications around memory management and compatibility.
The performance gains reported for tsrs make for an interesting comparison with Microsoft’s own Go implementation. Commenting in a Hacker News discussion about the Rust port, Daniel Rosenwasser, Microsoft’s principal product manager for TypeScript, notes that “a lot of the speed does not just come down to language choice,” adding that “some of what is going to make TS 7.1 faster and leaner… actually comes from optimizations discovered in tsrs.”
“Some of what is going to make TS 7.1 faster and leaner… actually comes from optimizations discovered in tsrs.”
Separately, Rosenwasser announced TypeScript 7.1 beta earlier today, detailing substantial speed and memory optimizations.
Cloudflare, for its part, sees another opportunity in Rust, particularly its compatibility with WebAssembly (Wasm). Go can compile to Wasm, but it has to bring its garbage collector along. Rust offers more direct control over memory, reducing the overhead of running development tools in resource-constrained environments. For Cloudflare, that could make it easier to run complete development environments inside browsers and isolated Workers sandboxes, where AI agents can write, check, and build applications.
The move also fits into Cloudflare’s growing JavaScript ecosystem. As The New Stack reported last week, the company has been assembling an extensive collection of JavaScript tools and expertise, including through its acquisition of VoidZero in June and the recent release of Void, an open-source platform for deploying and managing AI-built applications.
With that in mind, it’s the Cloudflare and VoidZero teams who are are now developing tsrs as part of Oxc, VoidZero’s Rust-based JavaScript toolchain, with plans to integrate it into other developer tools.
Owner and operator: A tsrs origin story
It’s worth noting that the tsrs project began just last month at restaurant software company Owner.com, where head of AI developer experience Max Schwenk says he faced a 37,000-file TypeScript backend. Writing in a blog post published on Monday, he notes that Microsoft’s Go compiler consumed 19 GiB of memory and took 80 seconds for a single-threaded check, restricting how many coding agents could work concurrently.
With multiple agents generating code simultaneously, the resource demands made it difficult for each to check its changes independently, forcing Owner.com to experiment with cloud-based development environments and other compromises.
“For a coding agent to be maximally productive, it needs to be able to validate its work in the tightest possible loop,” Schwenk writes.
After running into limits while trying to improve the Go compiler’s memory usage, Schwenk tried something somewhat more ambitious: use Anthropic’s Claude Opus 5.5 to recreate the compiler in Rust. He would direct the experiment and evaluate the results, leaving the implementation entirely to AI agents.
“I wrote zero code,” Schwenk writes. “Not ‘barely any’. Zero.”
“I wrote zero code. Not ‘barely any’. Zero.”
And the results came remarkably quickly. Schwenk says he deployed more than 20 AI subagents in parallel, waking the following morning to a functioning typechecker. Further optimizations brought Owner.com’s typechecking time down to roughly seven seconds in CI, and across more than a dozen public projects, Schwenk reports tsrs running 2.5 to five times faster than Microsoft’s newer Go compiler nightly, while using about a third as much memory.
Agentic rewrites in Rust
In truth, the tsrs project is just the latest example of AI agents being enlisted for substantial Rust migrations. As The New Stack reported last month, GitHub used its own Copilot agents to rewrite its coding-agent runtime in Rust, while Anthropic had previously used Claude agents to help migrate its Bun JavaScript runtime from Zig to Rust.
Elsewhere, Meta has also used AI to help port the React Compiler to Rust, while in September OpenAI revealed two engineers used Codex and GPT-5.5 to rebuild its Habitat storage service in Rust.
But such rapid, AI-assisted rewrites raise questions about how developers verify that the resulting software behaves as intended. For a TypeScript compiler, that means ensuring it catches the same errors as Microsoft’s implementation. Schwenk says the project uses TypeScript’s conformance tests, deliberately introduces errors into real projects and runs Miri, a tool for detecting memory-safety problems in Rust. Those checks have already uncovered a memory bug that appeared only in an optimized build.
“A faster compiler that finds fewer errors is a broken compiler with good marketing.”
“A faster compiler that finds fewer errors is a broken compiler with good marketing,” Schwenk writes.
Maintaining compatibility, it’s fair to say, will be an ongoing challenge. Cloudflare plans to borrow the AI-assisted approach behind Vinext, its Vite-based reimplementation of the Next.js web framework, where agents monitor Next.js for changes, run compatibility tests, and propose fixes when differences emerge. Some discrepancies remain in tsrs, including the order in which diagnostic messages are displayed.
“We will apply the same process to TypeScript, taking extreme care that we don’t introduce diverging behaviors from upstream TypeScript,” the Cloudflare authors write.
The post “We are not forking TypeScript”: Cloudflare spearheads Rust port written by agents, for agents appeared first on The New Stack.
Pennsylvania, USA

“We switched to event driven architecture. Now we can’t debug anything.”
A member of my channel shared a post with me where a team went all in on event driven architecture and ran into a bunch of problems.
The thing is, they’re not wrong about the pain they experienced. But the problems weren’t directly because of event driven architecture. They were mostly caused by how they understood it and how they were applying it.
So let’s break down the five pain points they had, why they had that pain, and how you can avoid it.
YouTube
Check out my YouTube channel, where I post all kinds of content on Software Architecture & Design, including this video showing everything in this post.
Where They Started
Before switching to event driven architecture, they had a REST based system. Really, that just means HTTP in this case, with services calling other services.
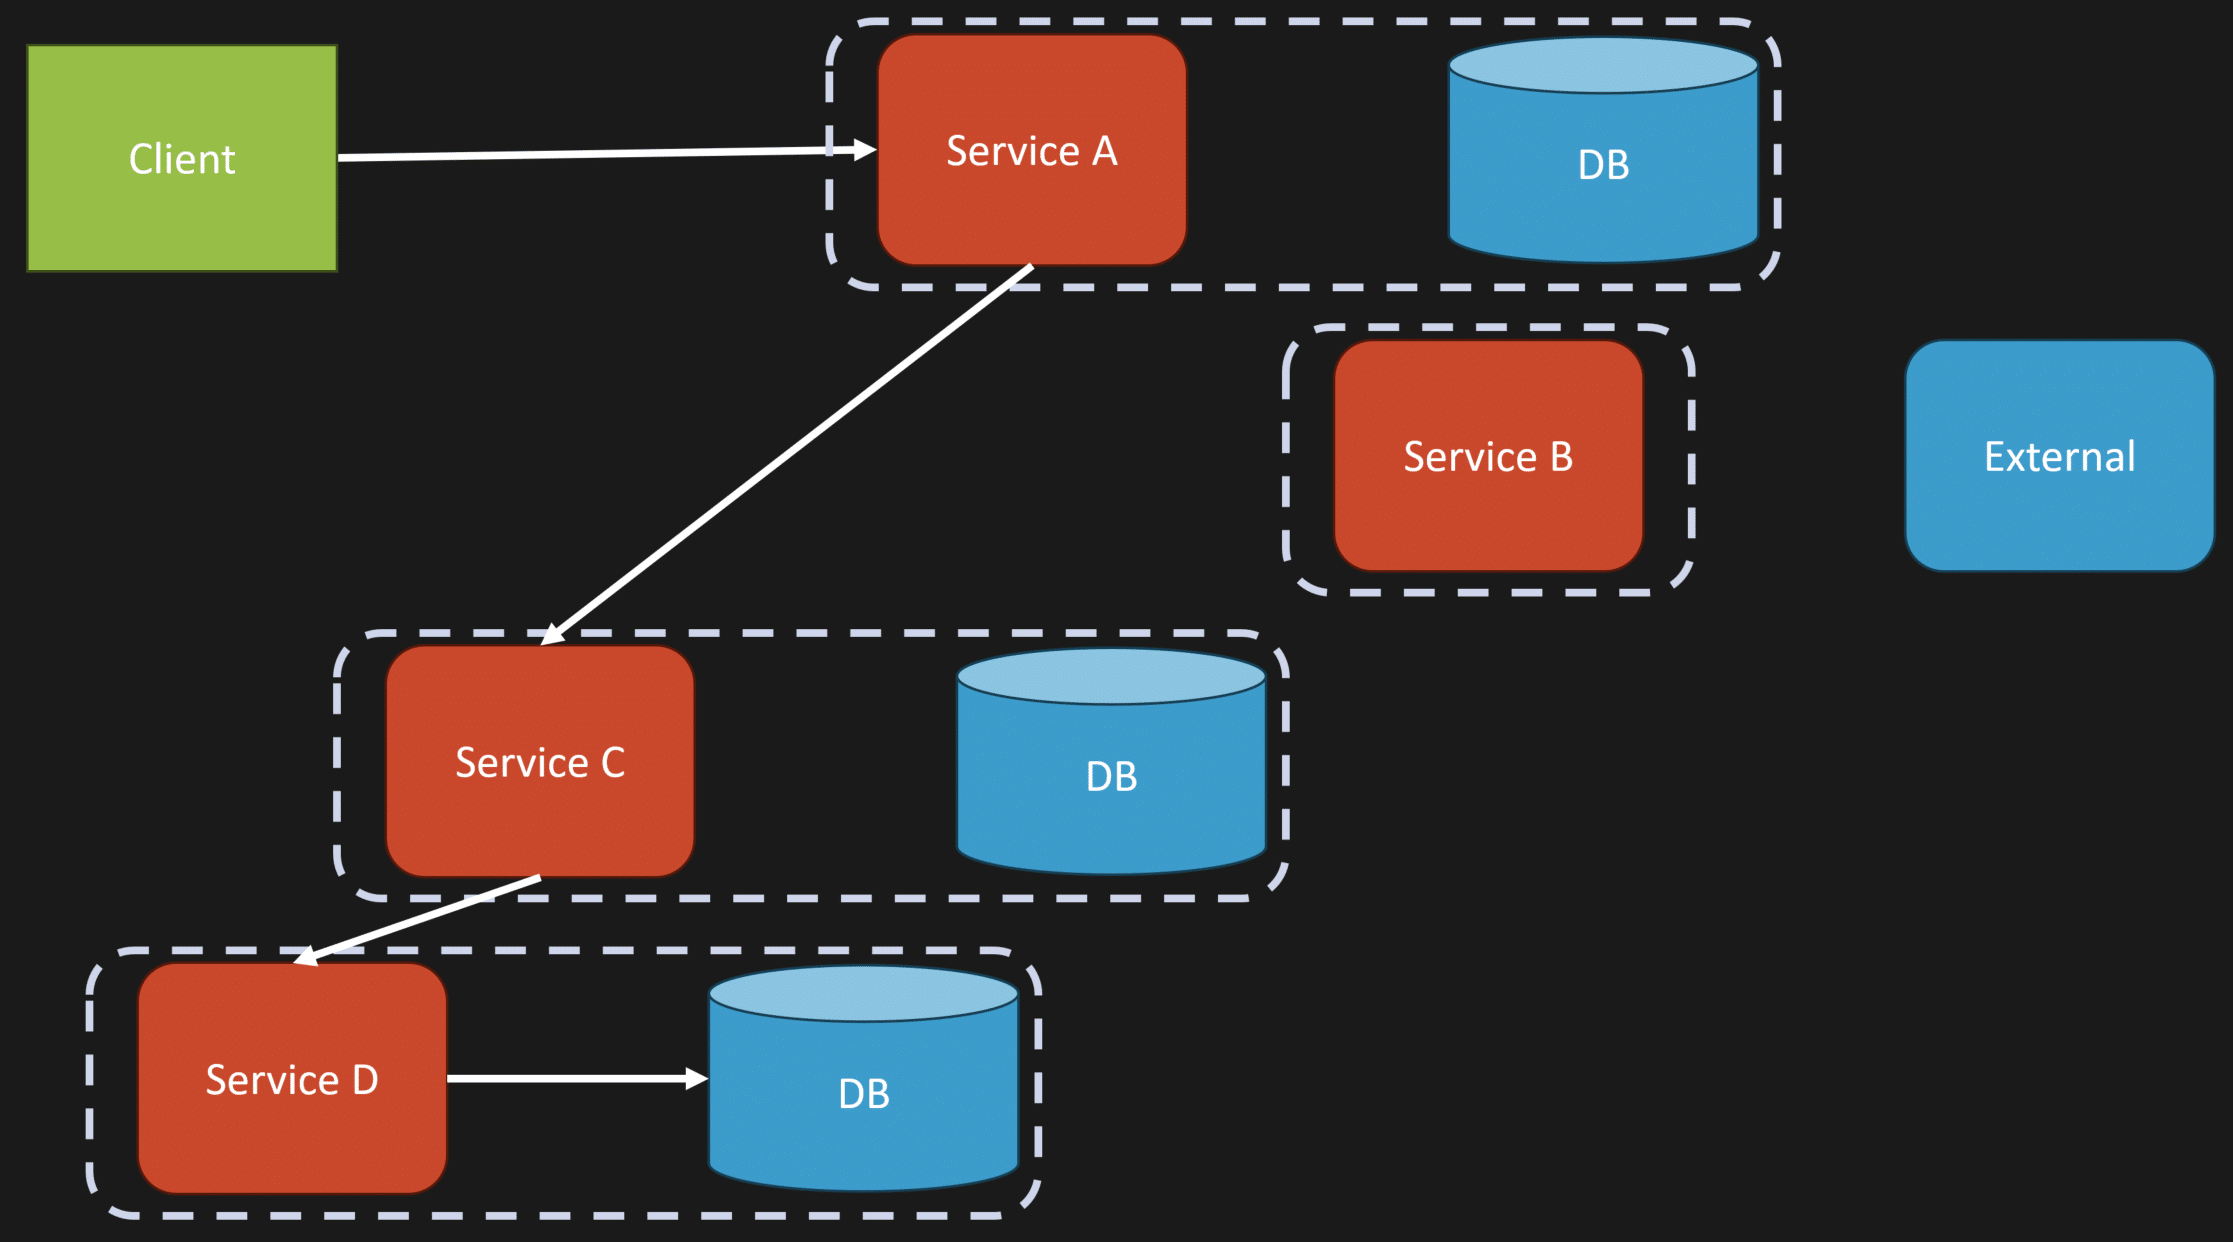
Imagine a client makes a request to Service A. Service A updates its database and then calls Service B. Service B might call something external. Service A also calls Service C, which has its own database. Maybe Service C calls Service D.
Eventually all of this works its way back until a response is returned to the client.
If that sounds like a disaster, well, it was.
They described it as a spaghetti mess of cascading HTTP calls, versioning nightmares between contracts across all these different services, and a very brittle orchestration layer.
So they moved toward asynchronous messaging and Kafka.
That solved some problems, but it introduced others. Or more accurately, it exposed some misunderstandings.
Problem 1: Tracing Ended at Kafka
Their first problem was tracing, specifically tracing asynchronous workflows.
With their existing HTTP based system, maybe the frontend called the ordering service, which called the payment service, which called the email service.
Using something like OpenTelemetry along with Zipkin, Jaeger, or another tracing tool, they could see that entire flow.
Then Kafka came into the picture.
Now the order service produces an event, and you have multiple services listening to different topics. Maybe the payment service handles something. The email service handles something else. The inventory service does something else.
For them, that completely broke their visibility into what was happening as part of the workflow.
This is absolutely a pain. You need good visibility and good tracing in any distributed application.
But OpenTelemetry works just as well in an asynchronous system as it does in a synchronous system using HTTP between services.
This should not be the problem.
What they likely had was a tooling problem.
They may have come from a more mature web framework where tracing was already integrated and simply worked out of the box. Then they moved to asynchronous messaging where their tooling didn’t provide the same experience.
Depending on what you’re using, that tracing should also work with asynchronous messaging.
I see this often when people use the SDK directly for whatever messaging system, event log, or message broker they’re using instead of leveraging a messaging library that already has this functionality built in.
To me, this is largely a tooling issue. Tracing asynchronous messaging is a solved problem. You just need tooling that actually supports it.
Problem 2: Dead Letter Queues Became Garbage Dumps
Their second problem was dead letter queues.
They sound helpful. You have somewhere to isolate messages that failed.
But in their case, they became a graveyard of mystery failures.
Dead letter queues are great, but they’re just storage.
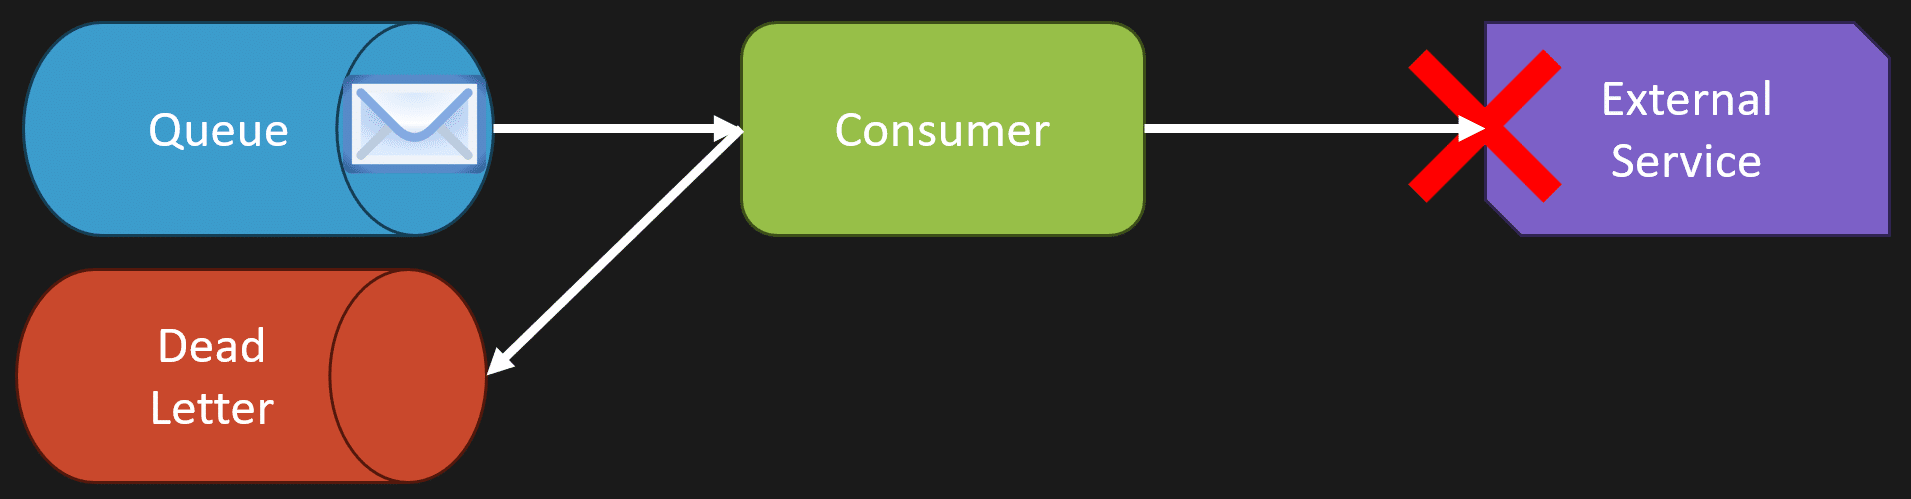
Imagine you have a queue with a consumer processing messages. As part of processing a message, that consumer needs to call an external service.
The external service is failing.
Maybe you have a retry with some type of backoff. It tries again. It still fails.
Eventually you move that message to a dead letter queue.
That dead letter queue is simply somewhere to put the message so you can deal with it later. Maybe somebody manually retries it after the underlying problem has been resolved.
But a dead letter queue without any way to inspect the message, replay the message, or see the errors and exceptions that occurred while processing it is basically a black hole.
It isn’t useful by itself.
You need visibility into why the message failed. You need to correlate that message with the error or exception that actually occurred.
Do you need to fix something in your code?
Is it a poison message that will never succeed?
Was there simply a transient failure while calling an external service, and if you process the message again now that the service is available, everything will work?
You need visibility into both the failure and the message itself.
Again, this comes back to tooling and observability.
Problem 3: Fire and Forget Equals Debug and Regret
I have to admit, I like that title.
Their comparison was that REST is like ordering at a restaurant. You place an order and wait for confirmation.
You sure about that?
I actually use restaurants all the time to explain asynchronous workflows.
You arrive at a restaurant and whoever greets you brings you to a table. They don’t stand beside your table waiting for you to decide what you want to order.
They go perform some other action. Maybe they greet another customer and bring them to another table.
The entire workflow is full of asynchrony.
Eventually the wait staff takes your order and enters it into the point of sale system. That communicates to the kitchen that there’s an order that needs to be prepared.
The kitchen picks that up asynchronously and starts cooking your meal.
When the order is ready, there’s effectively another message saying that the food is ready to be picked up. Somebody gets it and brings it back to you.
It’s full of asynchronous workflows. You just need to embrace that.
But the biggest red flag in their example, and something I see over and over again, was that they were forcing everything to be an event and everything to be asynchronous.
It doesn’t need to be.
Not Everything Is an Event
They described events as throwing a note into a room and hoping somebody reads it.
Not really.
What they’re describing is publish-subscribe, and that’s the point.
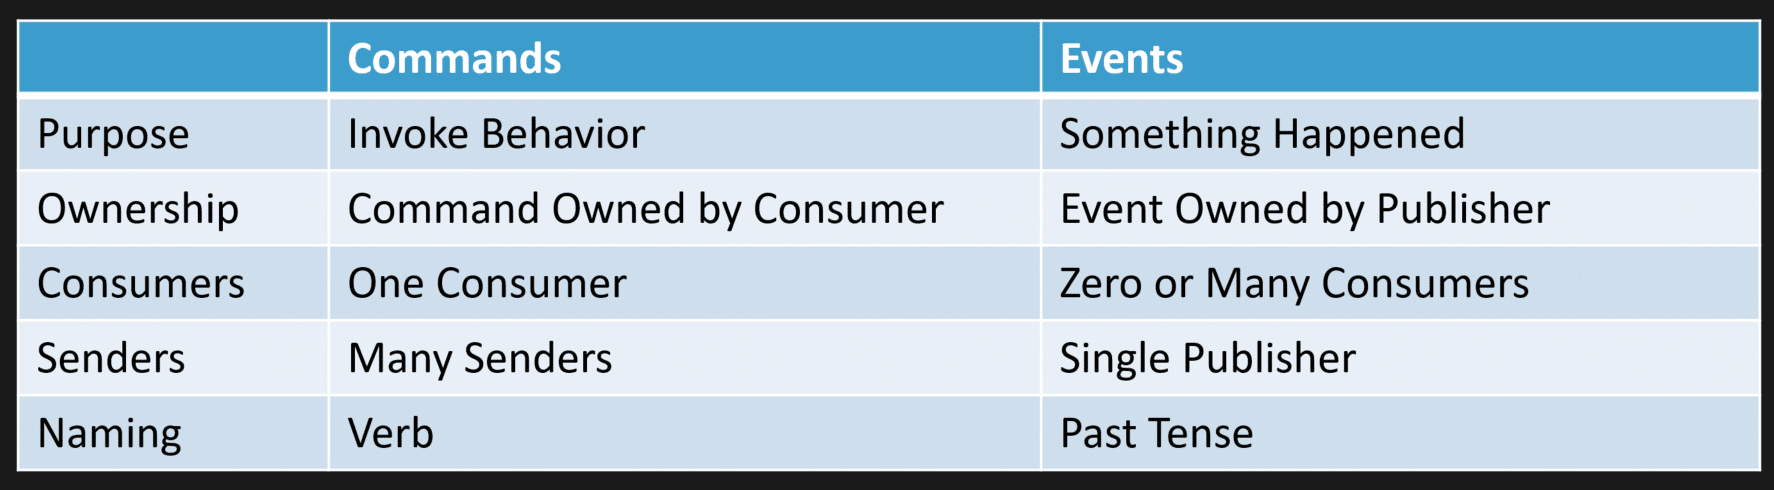
Events are facts. Something happened.
If you publish an event, you as the producer don’t care if there are any consumers.
There might be no consumers. There could be a thousand consumers.
As the publisher, it doesn’t really matter.
You own the schema because you’re producing the event. The event represents something that occurred inside your boundary.
That’s very different from a command.
Commands are about invoking behavior.
A command is owned by the consumer because there should be one boundary responsible for handling that command. There could be many different senders depending on how you define your boundaries, but there is one logical consumer.
Commands are generally named using verbs because they represent actions you want to invoke.
Events are different.
Events are facts. Something happened and you’re notifying some other part of your system.
Events are owned by whoever publishes them because the event occurred within that particular boundary. There is one publisher, but there can be zero to many consumers.
Events are generally named in the past tense because they represent things that already occurred.
Commands and events have different utility. They’re different concepts.
Not everything needs to be asynchronous, just like not everything needs to be an event.
Some things naturally need to be synchronous.
Queries are an obvious example.
In their original HTTP based system, they were synchronously calling different services to perform different actions. That doesn’t mean you replace every one of those calls with an event.
You have to understand what can be fire and forget and what requires an immediate response.
There’s also the option of an asynchronous request and reply when you actually need it.
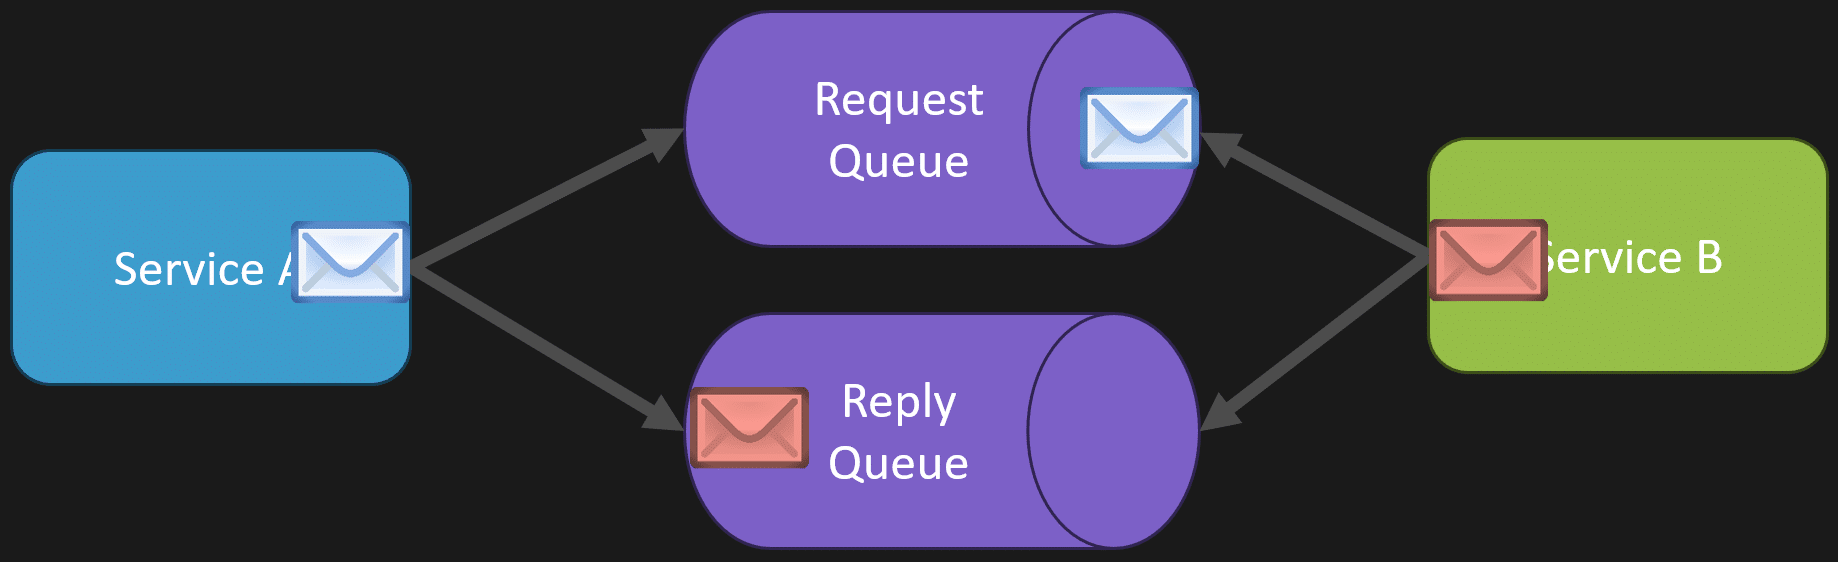
Maybe Service A sends a request that Service B processes asynchronously. Once Service B completes the work, it sends a reply message to a separate queue.
Service A consumes that reply and correlates it back to the original request.
Now it understands the outcome of that asynchronous processing.
That pattern can be completely reasonable. The problem is using it everywhere when you don’t actually need it.
Problem 4: Eventual Consistency Is Like Eventual Accountability
Another great title.
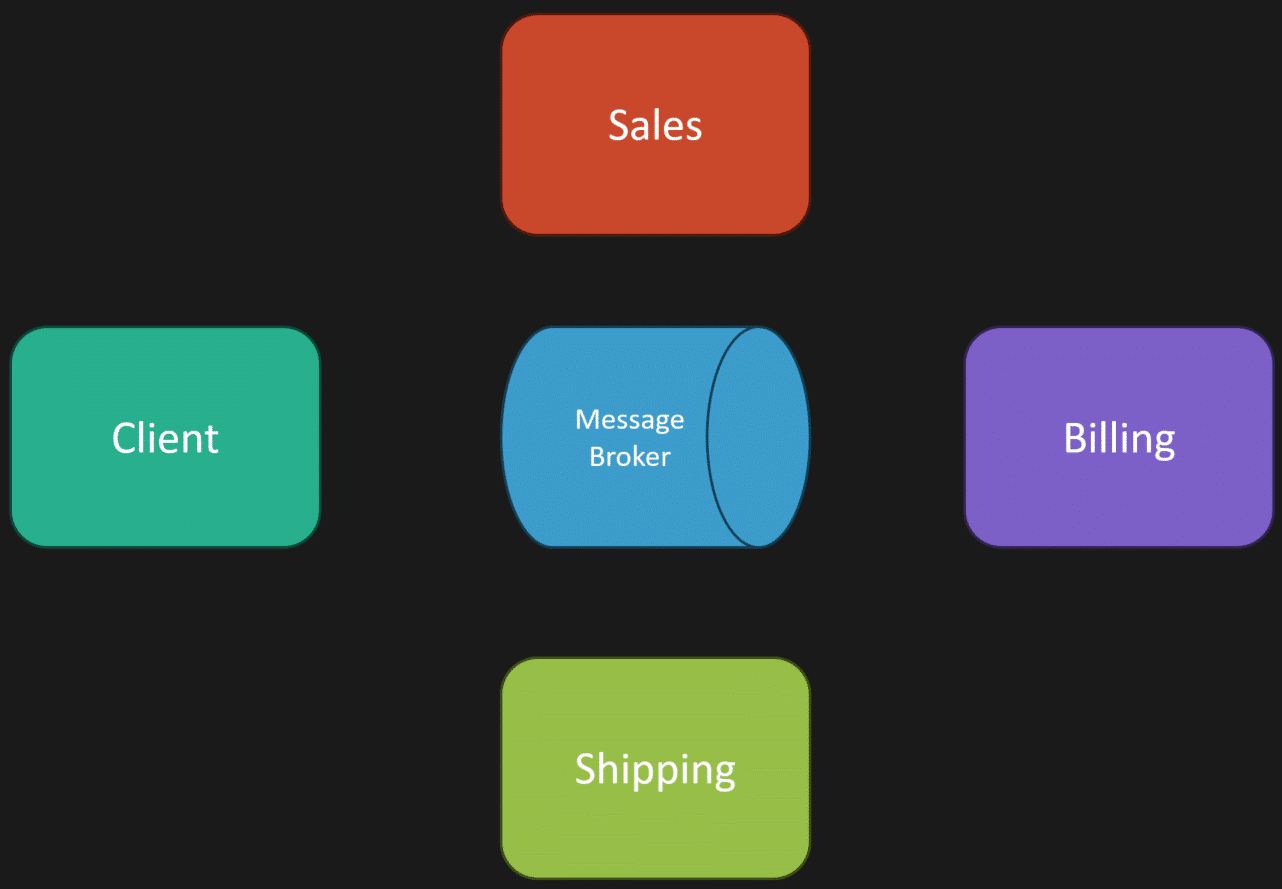
Imagine an order flows through four different services.
An order is placed. Inventory gets reserved. Payment gets charged. A confirmation email gets sent.
Then something fails.
Now you need to compensate.
Maybe you need to restock the inventory. Maybe you need to refund the payment. Maybe you need to cancel some other action that already occurred.
Absolutely. This is a problem.
Coordinating what happens when one part of a longer workflow fails can get complicated.
How do you know what completed?
What failed?
What compensating action needs to happen next?
This is exactly what the saga pattern is intended to address in an asynchronous workflow.
But here’s the thing: this isn’t necessarily easier in a synchronous system.
Think about having one long procedural workflow filled with service calls and try catch blocks.
Call one service. That succeeds.
Call another service. That succeeds.
Call the third service. It fails.
Now start figuring out which previous operations need to be undone. Add some nested error handling and compensating logic around all of it.
That can become a mess too.
The advantage of an asynchronous workflow is that you can have state associated with the saga. You can understand what has completed, what hasn’t completed, and where something failed.
Combined with dead letter queues and proper observability, you can see what’s actually happening.
Again, we come back to visibility and tooling.
Problem 5: Testing Became a Nightmare
Their final problem was testing.
Unit tests were fine, but integration tests became painful.
Now they were spinning up Kafka, mocking consumers and producers, and waiting for asynchronous side effects.
The problem here is trying to test everything across boundaries.
Remember, events are contracts. They’re not conversations.
They don’t go two ways.
This goes back to the distinction between events and commands.
Are you trying to invoke something?
Or are you telling some other part of your system that something happened?
From the producer’s point of view, what are you actually responsible for testing?
Are you publishing the event you’re supposed to publish?
That’s your responsibility.
From the consumer’s point of view, are you consuming that message and processing it correctly?
That’s what you need to test.
You don’t necessarily need one massive integration test that spins up your entire distributed system and verifies every side effect across every boundary.
Understand the contracts between those boundaries and test the responsibilities on each side.
Event Driven Architecture Isn’t Your Architecture
This is the part that gets missed.
Event driven architecture isn’t your architecture.
It’s just part of it.
It isn’t a full system replacement where you take every HTTP call you currently have and replace it with an asynchronous event.
That’s not the point.
A system can have synchronous communication, asynchronous communication, commands, events, queries, request reply messaging, and other patterns all working together.
It’s about the outcomes you’re trying to accomplish.
Not following a pattern everywhere because you decided your system is now “event driven.”
Join CodeOpinon!
Developer-level members of my Patreon or YouTube channel get access to a private Discord server to chat with other developers about Software Architecture and Design and access to source code for any working demo application I post on my blog or YouTube. Check out my Patreon or YouTube Membership for more info.
Related Links
The post 5 Event Driven Architecture Problems (And How to Avoid Them) appeared first on CodeOpinion.
Pennsylvania, USA

Introducing the Oracle AI Database Vector Store Connector, Oracle .NET AI Skills, and new Deep Data Security features

Key Takeaways
- ODP.NET 26ai (23.26.3) and the Oracle AI Database Vector Store Connector are now available for .NET developers.
- The connector lets applications store, search, update, and delete vectors in Oracle AI Database and supports Microsoft Agent Framework.
- Expanded Oracle Deep Data Security features allow applications to manage access for human users and AI agents through end-user names and lookup keys.
- Oracle .NET AI skills provide reusable guidance that helps coding agents create ODP.NET applications using Oracle best practices.
I’m excited to announce ODP.NET 26ai (23.26.3) and the production release of the Oracle AI Database Vector Store Connector, expanding support for AI agent development.
These releases add new AI agent, skills, and security capabilities for Oracle .NET developers. With the Oracle AI Database Vector Store Connector, .NET applications can search, create, read, update, and delete vectors directly in Oracle AI Database.
The connector also integrates with Microsoft AI technologies, including Microsoft Agent Framework, to support AI agents, large language model (LLM) applications, Model Context Protocol (MCP) solutions, and workflows.
ODP.NET 23.26.3 extends Oracle Deep Data Security support for agentic AI by adding end-user names and lookup keys to security contexts. These additions give developers more flexible ways to create and manage security contexts for both users and AI agents.
Finally, we’ve released Oracle .NET AI developer skills to help AI coding agents build robust ODP.NET applications faster while following Oracle best practices.
Oracle AI Database and ODP.NET offer a broad set of capabilities for C# data applications, including performance, high availability, security, data management, scalability, and AI. The challenge is that developers need time to learn these capabilities and apply the right practices.
Oracle AI skills help agents apply that guidance directly when generating application code, improving developer productivity while helping teams avoid common implementation pitfalls.
Let’s take a closer look at these new capabilities and the benefits they provide.
Oracle AI Database Vector Store Connector

The Oracle AI Database Vector Store Connector for .NET is now generally available in the Oracle.VectorData NuGet package. It provides out-of-the-box support for standard .NET vector operations, so existing C# AI applications can use Oracle AI Database to store and retrieve vectors with minimal code changes.
The connector also exposes Oracle AI Database 26ai capabilities beyond basic vector storage, including multiple vector distance functions and vector index types that most databases don’t offer. This gives .NET developers access to a broader set of vector search options directly from their applications.
The new Oracle connector also supports Microsoft Agent Framework, an SDK and runtime for building, orchestrating, and deploying multi-agent AI systems. It combines simple agent abstractions with enterprise-ready capabilities.
Microsoft Agent Framework applications can use Oracle AI Database as a vector store for retrieval-augmented generation. Because the framework uses the same vector store libraries as .NET, existing connectors such as Oracle’s can integrate with little or no additional customization.
To learn more about the Oracle AI Database Vector Store Connector, explore the documentation or try the sample applications.
- Documentation: Using the Oracle AI Database Vector Store Connector
- Documentation: Oracle AI Database Vector Store Connector Classes
- Samples: AI Agent Framework Chat App and AI Vector Hotel Search App
The connector supports both .NET and .NET Framework and uses ODP.NET for database access.
While the connector supports Oracle Database 19c and later, I recommend Oracle AI Database 26ai for its broader vector search and AI agent capabilities, with additional features delivered in quarterly releases. One of its most important capabilities is Deep Data Security, designed to help secure applications for the agentic AI era.
That brings us to the second major Oracle .NET enhancement in this release: expanded Deep Data Security integration.
ODP.NET Deep Data Security End-user Names and Lookup Keys

Agentic AI can perform complex tasks, but it often requires broad, dynamic access to data, increasing security and compliance risk. Enforcing authorization in the database reduces duplicated application logic and keeps access rules consistent across applications, agents, and tools.
Oracle Deep Data Security provides unified, database-native policy enforcement for both conventional and AI applications. ODP.NET 23.26.2 first added support for passing Deep Data Security end-user security contexts from .NET applications. I covered this integration in more detail in a previous blog post.
Deep Data Security plays a critical role in AI by helping prevent autonomous agents from exposing sensitive information or making unauthorized data changes. Enforcing security policies in the database provides a consistent control point instead of relying on every application to govern AI agents correctly and stay up to date on new practices.
In the vibe-coding era, AI can generate applications quickly, cheaply, and with extensive customization. That can produce many variations of the same application, some of which may be rarely updated. Centralized database security helps keep access policies consistent across all of them.
With so many applications, thorough code and security reviews may become less consistent. AI coding agents also may not understand an organization’s specific end-user authorization rules unless those rules are explicitly provided.
Oracle Deep Data Security Usage Scenario
Consider a human resources database. Employees should see only their own salary and, where appropriate, the salaries of their direct reports. Sensitive identifiers, such as Social Security numbers, should be restricted to the individual they belong to. Employees may be allowed to update their home address, but not their salary.
Building all of these business, security, and legal rules into every AI application is difficult to maintain. Centralizing authorization in the database helps prevent unintended data exposure and unauthorized changes across applications and agents.
That’s where Oracle Deep Data Security comes in. By enforcing security at the database level, organizations can simplify policy setup, maintenance, and auditing. Developers can also place less trust in individual applications, which actually makes it easier to build and deploy securely.
ODP.NET Deep Data Security End-user Names and Lookup Keys
In the latest release, ODP.NET Deep Data Security adds support for end-user names and lookup keys in end-user security contexts. This gives applications more flexible ways to manage user and AI agent access. An external application identity can now be mapped to a database session without requiring a corresponding account in an external identity and access management system, such as Microsoft Entra ID.
A Deep Data Security end-user name can represent a human or AI agent authenticated by the application, rather than a traditional database user account. The end-user name can be used in a security context instead of a user access token.
A lookup key gives Oracle Deep Data Security a unique identifier for an application-managed end user. It maps the authenticated identity to the appropriate database policies, data roles, and data grants, enabling fine-grained access enforcement.
The lookup key is automatically generated when an end-user security context is created with an end-user name. The .NET security context then contains the lookup key, database access token, and end-user name.
Here’s a C# example that creates the security context using an end-user name. You can see the context created with the CreateWithTokenAndName method and end-user parameter.
/* Setup an end user for the security context in lieu of a user access token.
* Create the user:
  CREATE END USER deepsec_end_user;
* Create data grant to give limited HR schema access to the end user:
  CREATE DATA GRANT enduser_grant AS SELECT (ALL COLUMNS EXCEPT salary) ON hr.employees TO deepsec_end_user;
*/

// Read database token from file.
string midtierToken = GetMidtierToken();
// Create security context with deepsec_end_user.
OracleEndUserSecurityContext securityCtx = OracleEndUserSecurityContext.CreateWithTokenAndName(midtierToken, "deepsec_end_user");

// Create and open connection. Deep Data Security requires a TCPS connection.
// low_privilege_user only has connection privileges.
OracleConnection conn = new OracleConnection("user id=low_privilege_user;password=<PASSWORD>;data source=oracle");
conn.Open();
// Set security context on connection
conn.SetEndUserSecurityContext(securityCtx);

// Execute SQL
using (var command = new OracleCommand("SELECT FIRST_NAME, SALARY from hr.employees", conn))
{
  using (var reader = command.ExecuteReader())
  {
    while (reader.Read())
    {
      // Deepsec_end_user has access to employee first names but not salaries based on data grant.
      // Salary data will return as null values.
      Console.WriteLine("Name: " + (reader.IsDBNull(0) ? "<NULL>" : reader.GetString(0)));
      Console.WriteLine("Salary: " + (reader.IsDBNull(1) ? "<NULL>" : reader.GetString(1)));
    }
  }
}
Managed ODP.NET and ODP.NET Core 23.26.3 both support Oracle Deep Data Security end-user names and lookup keys.
Learn more in the ODP.NET Deep Data Security documentation.
Oracle .NET AI Skills for More Productivity
Perhaps the biggest gain in developer efficiency comes from AI skills. These reusable Markdown files contain instructions, knowledge, and workflows that extend AI agents for specific tasks or domains. Our focus here is ODP.NET and Oracle AI Database development and optimization.
My team has published an Oracle .NET AI skills file for use with AI tools and coding assistants. You can use it as is or adapt it to your project. It works with new or existing managed ODP.NET, ODP.NET Core, and Oracle EF Core applications.
We plan to continue expanding the Oracle .NET AI skills over time.
These Oracle .NET AI skills are part of the Oracle AI Skills repository, which covers a broader range of Oracle products and services, including Oracle AI Database. The repository also includes an Oracle AI Database skills file for improving database code and design, including PL/SQL, SQL, and security.
You can use individual skill files to focus on specific areas, such as performance or high availability, or combine them to improve your application more holistically.
Get Started with New AI Features
You can start building AI applications with ODP.NET 23.26.3 and the Oracle AI Database Vector Store Connector today. Download them from NuGet Gallery:
You can also download the Oracle .NET AI skills from GitHub:
Give them a try to accelerate Oracle .NET AI development and build better applications with less effort.
#OracleDotNet
FAQs
- What is the Oracle AI Database Vector Store Connector?
It is a .NET connector that lets applications use Oracle AI Database to store and retrieve vector data with minimal code changes. It’s available in production. - Which AI technologies does the connector support?
It works with .NET vector libraries and Microsoft Agent Framework for AI agents, LLM applications, MCP solutions, and related workflows. - How does Deep Data Security help AI applications?
It enforces authorization in the database, helping prevent agents and applications from accessing sensitive data or making unauthorized changes. - What are Oracle .NET AI skills?
They are reusable instruction files that help AI coding assistants build and optimize ODP.NET, ODP.NET Core, and Oracle EF Core applications.
New ODP.NET Releases for AI Agent Development and AI Skills was originally published in Oracle Developers on Medium, where people are continuing the conversation by highlighting and responding to this story.
Pennsylvania, USA


Xbox CEO Asha Sharma is planning new rounds of layoffs for sometime this month, November, and January, according to Fortune. In July, as part of an organizational "reset," Sharma announced planned layoffs affecting 3,200 staffers over the course of Microsoft's 2027 fiscal year, including 1,600 cuts at that time, and in September, Microsoft laid off around 260 employees. Sharma's changes have also included letting Double Fine and Compulsion Games become independent again, though Senua developer Ninja Theory may close.
The report also touches on speculation that Xbox may be spun off or sold, and Judson Althoff, the CEO of Microsoft's commerci …
Pennsylvania, USA
Next Page of Stories