 Log in

The Agents CLI Extension System enables developers to use frameworks like LangChain, LangGraph, or custom enterprise stacks while retaining a unified deployment and evaluation workflow. It details a first-party LangChain template that scaffolds, runs, and deploys agents without requiring the Agent Development Kit (ADK). Additionally, it demonstrates how platform teams can author custom extensions to enforce policies such as automated software bill of materials (SBOM) scans during deployment.
|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


This article follows Comparing Qwen and Gemma on the Low End, which ran Qwen3.5-2B and Gemma 4 E2B with thinking off. Here both models think, on the same card, the same llama.cpp binary and the same 4-bit files.
https://github.com/xbill9/qwen-dev/tree/main/local-llamacpp-1650ti-qwen352b-q4_0
Thinking is worth 17.7 points to Qwen3.5-2B on BFCL tool calling and nothing measurable to Gemma 4 E2B. On GSM8K math, thinking alone adds 3.7 points to Qwen, a range that includes zero. With both models thinking, Gemma still leads by 10.3 points on math and 5.0 on tool calls. Qwen's thinking runs to a median of 7,607 tokens per math answer against Gemma's 808.
What is this project trying to Do?
The first article found Gemma 4 E2B ahead of Qwen3.5-2B on every task, with thinking off for both. Qwen3.5 is built to think, so the first question a Qwen user asks is what happens with thinking on.
This article answers it on the GTX 1650 Ti, a 4 GB laptop card, for the two generation tasks: GSM8K math word problems and BFCL simple tool calls. Both models run as 4-bit GGUF files: Qwen's standard Q4_0 and Gemma's QAT Q4_0.
At This Point You Should Have…
- An NVIDIA GPU with a CUDA driver — here a GTX 1650 Ti (4 GB, Turing)
- llama.cpp built with CUDA — commit
7182ef71ehere - The two GGUF files from the first article:
Qwen3.5-2B-Q4_0.ggufand Gemma'sgemma-4-E2B-it-q4_0-exact.gguf - Python 3 for the task runner — the system
python3, no virtualenv - The repository cloned, and
jev-tpu-v5e1/holdinggen_eval.py
Step 1 — Turn Thinking On
One server flag turns thinking on for both models:
llama-server -m Qwen3.5-2B-Q4_0.gguf --host 127.0.0.1 --port 8080 -ngl 99 \
  -c 131072 --parallel 4 -ctk f16 -ctv f16 -fa 1 -t 6 -tb 12 --reasoning on --metrics
llama-server puts the thinking in message.reasoning_content and the answer in message.content. Only content is scored; the task runner keeps the thinking in each record for reading later.
-c 131072 --parallel 4 gives each of 4 slots 32,768 tokens, so a request has room to think. The server log confirms the split:
0.01.412.127 I srv load_model: initializing, n_slots = 4, n_ctx_slot = 32768, kv_unified = 'false'
Step 2 — Use Each Vendor's Sampling Settings
The thinking-off runs used greedy decoding. With thinking on, greedy decoding breaks Qwen. On 16 GSM8K problems with an 8,192-token limit:
trial-greedy-8k/gsm8k-qwen.jsonl: n=16 limit=8192 right=5 hit_limit=11 ends_in_loop=9 still_thinking=11
Qwen got 5 of 16 right. It hit the limit on 11, every one still thinking, and 9 of those ended in one sentence repeated dozens of times:
    Wait, I need to check if the prompt requires the thinking steps to be in the final output. Yes.
    Okay.
    Wait, I need to check if the prompt requires the thinking steps to be in the final output. Yes.
    Okay.
Qwen's model card gives settings for thinking mode, and Gemma's generation_config.json gives its own:
Qwen3.5-2B, thinking mode for text tasks: temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
Gemma 4 E2B: "temperature": 1.0, "top_k": 64, "top_p": 0.95
Each model ran at its own vendor's settings. gen_eval.py merges them into every request from one variable:
JEV_SAMPLING='{"temperature":1.0,"top_p":0.95,"top_k":20,"min_p":0.0,"presence_penalty":1.5,"repeat_penalty":1.0}' \
JEV_GEN_MAX_TOKENS=32000 python3 gen_eval.py run http://127.0.0.1:8080 Qwen/Qwen3.5-2B gsm8k gsm8k-qwen.jsonl \
  --ids gsm8k-300-ids.txt --concurrency 4
Step 3 — Give Thinking Room
Qwen's card recommends an output length of 32,768 tokens for most queries. Both models got a 32,000-token limit on both tasks.
At that length Qwen's math takes hours on this card, so GSM8K is a fixed random 300 of its 1,319 problems, drawn once with a fixed seed and used for both models. BFCL is all 400. With thinking off, the 300 score Qwen at 0.730 and Gemma at 0.927, against 0.734 and 0.901 on all 1,319: the sample matches the full set for Qwen and favours Gemma by 2.6 points. Gemma's math leads below are about 3 points larger than the full set would give: with thinking off its lead is 16.7 points on all 1,319 and 19.7 on the 300.
Step 4 — Score Both Models
Each model with thinking on is paired question by question against its own thinking-off records on the same 300 problems and 400 requests, with a 95% range from 10,000 resamples:
| GTX 1650 Ti | Qwen off | Qwen on | Gemma off | Gemma on |
|---|---|---|---|---|
| GSM8K, 300 | 0.730 | 0.827 | 0.927 | 0.930 🥇 |
| BFCL simple, 400 | 0.688 | 0.838 | 0.917 🥇 | 0.887 |
| Thinking on − thinking off | Change | 95% range |
|---|---|---|
| Qwen, GSM8K | +0.097 | +0.043 to +0.150 |
| Qwen, BFCL | +0.150 | +0.100 to +0.198 |
| Gemma, GSM8K | +0.003 | −0.023 to +0.030 |
| Gemma, BFCL | −0.030 | −0.058 to −0.005 |
| Gemma's lead over Qwen | GSM8K | BFCL |
|---|---|---|
| Both thinking off | 19.7 points | 23.0 points |
| Both thinking on | 10.3 (6.3 to 14.3) | 5.0 (1.3 to 9.0) |
| Gemma off, Qwen on | 10.0 | 8.0 |
- Qwen rises 9.7 and 15.0 points, both ranges clear of zero.
- Gemma is level on math and loses 3.0 points on tool calls. Gemma with thinking off still beats Qwen with thinking on.
- On BFCL, Qwen now calls the tool. Replies with no tool call fall from 88 of 400 to 8. Its misses are now mostly wrong argument values.
Step 4 changed two things at once: thinking, and greedy decoding to each vendor's sampling. Step 5 separates them.
Step 5 — Separate Thinking From Sampling
One more run holds the sampling and turns thinking off: the same server, files, limit, problems and settings as Step 4, with --reasoning off. The greedy runs kept the first article's 2,048 and 512-token limits, and the sampled runs had 32,000, so the first step changes the sampling and the limit together. Three runs per model, compared in pairs:
| GTX 1650 Ti | Greedy, thinking off | Vendor sampling, thinking off | Vendor sampling, thinking on |
|---|---|---|---|
| Qwen, GSM8K | 0.730 | 0.790 | 0.827 |
| Qwen, BFCL | 0.688 | 0.660 | 0.838 |
| Gemma, GSM8K | 0.927 | 0.910 | 0.930 🥇 |
| Gemma, BFCL | 0.917 🥇 | 0.885 | 0.887 |
| Change, 95% range | Sampling and limit | Thinking alone |
|---|---|---|
| Qwen, GSM8K | +0.060 (+0.003 to +0.117) | +0.037 (−0.013 to +0.087) |
| Qwen, BFCL | −0.028 (−0.068 to +0.013) | +0.177 (+0.128 to +0.228) |
| Gemma, GSM8K | −0.017 (−0.047 to +0.010) | +0.020 (−0.010 to +0.050) |
| Gemma, BFCL | −0.033 (−0.055 to −0.013) | +0.003 (−0.025 to +0.030) |
- On tool calls, thinking is the whole of Qwen's gain: +17.7 points. With thinking off, Qwen still answers 83 of 400 in prose; with thinking on, 8.
- On math, thinking adds 3.7 points to Qwen, a range that includes zero. The other 6.0 points come with the sampling and the longer limit together. Greedy, 26 of 300 replies reached the 2,048-token limit, 24 of them with no loop at the end; with the card's settings and 32,000 tokens, 4 of 300 reached the limit. Scored as right, those 26 would put greedy at 0.797, level with the sampled 0.790.
- Gemma's 3-point BFCL loss is the sampling. Gemma's greedy replies stayed well inside both limits (longest 1,586 tokens on math, 92 on tool calls), so for Gemma that column is sampling alone. Thinking changes neither of Gemma's scores beyond its range.
At matched settings Gemma leads by 12.0 and 22.5 points with thinking off, and by 10.3 and 5.0 with thinking on.
Step 6 — Count What Thinking Costs
From the records and the task runner's own wall times, 4 requests at a time:
qwen gsm8k: n=300 right=248 wall_s=36269.8 wall_min=604.5 wall_h=10.07 s_per_right=146.2 tokens_total=3407907 tokens_per_right=13742 tokens_median=7607
qwen bfcl: n=400 right=335 wall_s=1456.4 wall_min=24.3 wall_h=0.40 s_per_right=4.3 tokens_total=109946 tokens_per_right=328 tokens_median=160
gemma gsm8k: n=300 right=279 wall_s=1872.6 wall_min=31.2 wall_h=0.52 s_per_right=6.7 tokens_total=270970 tokens_per_right=971 tokens_median=808
gemma bfcl: n=400 right=355 wall_s=949.5 wall_min=15.8 wall_h=0.26 s_per_right=2.7 tokens_total=117153 tokens_per_right=330 tokens_median=284
| GTX 1650 Ti, thinking on | Qwen | Gemma |
|---|---|---|
| GSM8K reply, median tokens | 7,607 | 808 🥇 |
| GSM8K tokens per right answer | 13,742 | 971 🥇 |
| GSM8K seconds per right answer | 146.2 | 6.7 🥇 |
| GSM8K, 300 problems | 10.1 hours | 31 minutes 🥇 |
| BFCL tokens per right answer | 328 🥇 | 330 |
On math, Qwen spends about 14 times Gemma's tokens and 22 times its time for each right answer. On tool calls the two spend the same tokens.
31 of Qwen's 300 math replies used all 32,000 tokens; 20 of them were still thinking and 21 ended in repeated text. Scoring all 31 as right gives Qwen 0.913, still below Gemma's 0.930.
🔎 Tip: Do Not Run Qwen Greedy
Greedy decoding is the usual setting for repeatable scores. With thinking on it loops Qwen: 9 of 16 math problems ended in repeated text, and 5 of 16 were right against 12 of 16 at the card's settings. Use the card's settings, and keep presence_penalty in them; it is the one aimed at repetition.
🔎 Tip: The Token Limit Covers the Thinking
max_tokens counts thinking tokens as well as the answer. A limit sized for thinking-off answers (512 for tool calls, 2,048 for math here) cuts a thinking model off mid-thought, with an empty content. Size the limit, and each slot's share of -c, for the thinking.
Compare and Contrast
| GTX 1650 Ti, thinking on | Qwen3.5-2B Q4_0 | Gemma 4 E2B QAT Q4_0 |
|---|---|---|
| GSM8K / BFCL | 0.827 / 0.838 | 0.930 / 0.887 🥇 |
| Gain from thinking alone | +3.7 / +17.7 | +2.0 / +0.3 |
| Gain from sampling and limit | +6.0 / −2.8 | −1.7 / −3.3 |
| GSM8K median reply | 7,607 tokens | 808 tokens 🥇 |
| GSM8K, 300 problems | 10.1 hours | 31 minutes 🥇 |
| Greedy thinking | loops | runs 🥇 |
So, Which One?
Gemma 4 E2B, with thinking off and greedy decoding. It scores higher than Qwen with thinking on, on both tasks, and answers math in a fraction of the time.
If you use Qwen, use its card's sampling settings, and turn thinking on for tool calls: it is worth 17.7 points there for few tokens. On math, thinking adds 3.7 points that may not be real, at 14 times Gemma's tokens per right answer. Leave Gemma's thinking off for these tasks; it gains nothing.
Summary
The goal of this article was to measure Qwen3.5-2B and Gemma 4 E2B with thinking on, where the first article ran them with thinking off. The key to the solution was running each model at its vendor's thinking-mode sampling with room to think, and a third run with the same sampling and thinking off, so that thinking's effect is measured with everything else held, question by question. The results were:
- 🟢 Thinking lifts Qwen on tool calls: +17.7 points on BFCL, with replies that skip the tool down from 83 to 8.
- ⚠️ On math, thinking adds little to Qwen: +3.7, a range that includes zero; the other +6.0 came with the card's sampling and the longer limit together.
- ❌ Thinking does not lift Gemma: +2.0 on GSM8K and +0.3 on BFCL, neither clear of zero.
- 🟢 Gemma still leads: by 10.3 and 5.0 points with both thinking, and by 10.0 and 8.0 with only Qwen thinking.
- ⚠️ Qwen's math thinking is expensive: 13,742 tokens and 146 seconds per right answer, against Gemma's 971 and 6.7.
- ⚠️ Greedy decoding loops Qwen's thinking; its card's sampling settings fix it.
Scope: one GTX 1650 Ti (4 GB), llama.cpp 7182ef71e, the same Q4_0 files as the first article, measured 2026-10-18 and 2026-10-19. Two tasks: GSM8K on a fixed random 300 of 1,319 problems and BFCL simple on all 400; the classification suite was not run with thinking on. The two sampled runs used each vendor's thinking-mode sampling and a 32,000-token limit, 4 requests at a time, once per model; the greedy thinking-off records are from the first article's runs, with 2,048 and 512-token limits, 8 at a time. Thinking with greedy decoding was run on 16 problems only. Each sampled setting was run once, and a re-run gives different text, so the 95% ranges cover the choice of questions but not run-to-run variation. With --reasoning off, Gemma still wrote reasoning on 26 of 400 sampled BFCL replies, 25 of them right; the greedy runs have none. The task prompts and scoring code were written for this repository's Gemma work.
The strategy for measuring thinking on Qwen3.5-2B and Gemma 4 E2B on a local GPU was validated with an incremental step by step approach.
References
Pennsylvania, USA

In the ongoing retrospective series I have kicked off on LinkedIn and YouTube about the maturation of the web platform, I am going to be focusing on how Boston and Cambridge served as ground zero for modern front-end engineering between 2008 and 2013.
We will talk about the launch of HTML5 Boilerplate, the transition to automated build systems, and the moments JavaScript went from a despised browser toy to an enterprise-grade discipline.
Before you can fully appreciate why we spent so much energy building those tools, you have to understand the hostile operating environment we were trying to escape.
If you entered front-end engineering in the last decade, you grew up believing browsers are cooperative runtimes. You think a rendering engine is broken if a CSS flexbox rule behaves unexpectedly on mobile Safari.
Let me take you back to an era when the web platform was pure trench warfare.
1. Table Layouts and the Load-Bearing Spacer GIF
Before CSS layouts stabilized, we did not align elements with math or anything approaching an elegant solution. We built layouts through structural abuse. If a client needed a header, a navigation sidebar, and a three-column content area, that meant nesting <table> tags seven layers deep.
To prevent empty table cells from collapsing, every commercial website on earth carried an invisible architectural wedge: the transparent one-pixel GIF (spacer.gif). You set its width and height explicitly in HTML attributes to physically pry open cells like a car jack. Miss one closing tag, and the entire page shattered into disconnected tiles.
2. DHTML and the ActiveX Precursor to AJAX
In the late nineties and early 2000s, “Dynamic HTML” was the buzzword. In practice, DHTML was just marketing speak for Netscape and Microsoft waging open warfare inside your script files.
Netscape 4 gave us document.layers. Internet Explorer gave us document.all. If you wanted an element to move across the screen, you sniffed the user-agent string and maintained two parallel codebases in the same file.
Asynchronous data loading was even wilder. Back in August 2008, I wrote an article titled “Some Internet Explorer Innovations You Probably Forgot About While Waiting for IE6 to Die.” It hit the front page of Digg(? Slashdot? One of those.) My argument was straightforward: despite everything IE got wrong, Microsoft effectively invented AJAX.
Before fetch() or standardized XMLHttpRequest, you did not invoke a native browser API. In Internet Explorer, you initialized an actual Windows COM component: new ActiveXObject("Microsoft.XMLHTTP"). You had to wake up the underlying Windows operating system just to update a fragment of text without triggering a full page reload.
3. The Mark of the Web
Local development during the Windows XP Service Pack 2 era came with its own brand of security theater. If you opened a local HTML file directly from your hard drive that contained any JavaScript, Internet Explorer threw an aggressive yellow warning banner across the viewport and froze script execution.
The official Microsoft workaround was a magic comment pasted at the very top of your HTML:
<!-- saved from url=(0014)about:internet -->
The 14 represented the exact character count of about:internet. If your character count was off by one, the parser disregarded the directive and your local scripts remained locked down.
4. The Occult Arts: hasLayout, zoom: 1, and DirectX Filters
Once CSS finally took over layout, Internet Explorer 6 introduced developers to hasLayout. It was an undocumented internal engine flag. If an element lacked layout, margins doubled on floats, background colors vanished, and containers refused to contain their children.
To fix it, we resorted to superstition. You injected zoom: 1 or height: 1% into your stylesheets. The properties had no logical business being there, but they tricked Trident into setting that internal flag to true.
Transparent PNGs were worse. IE6 rendered 24-bit alpha channels as solid matte-gray or baby-blue blocks. In a 2006 tutorial I published on cross-browser PNG transparency, the only viable solution was running proprietary Microsoft DirectX filters:
filter: progid:DXImageTransform.Microsoft.AlphaImageLoader(src='image.png', sizingMethod='crop');
It destroyed scrolling performance, broke hyperlink click targets, and required hasLayout to be toggled on just to render the graphic.
Why We Built What We Built
We did not invent modern front-end tooling because we were bored and wanted complex build pipelines. We built automated builds, linting, reset sheets, and boilerplates because we spent our twenties writing duct tape around runtimes that actively fought us.
The next time your build step throws a type warning or a CSS grid gap requires a minor fallback, take a breath. It beats debugging spacer.gif and toggling zoom: 1 at 2:00 AM.
Pennsylvania, USA

Today I took my YouTube Player open source under the MIT license. Looking forward to the community contributions and opinions.
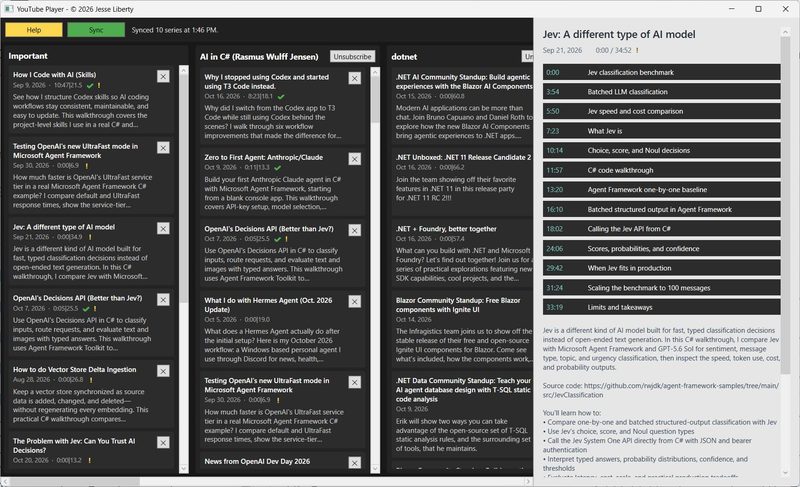
- Marks videos as started or completed
- Displays your progress and total time for video, along with date and other meta-data
- Single click on card displays details
- If details contain chapters, clicking on a chapter brings you there
- Double-click on video and go to where you left off
- Mark videos as important (and see all important videos listed together)
- Delete videos from your list to avoid clutter
- Drag and drop lists of videos to reorder
- Drag and drop cards within list
The source offers two versions: Desktop and Web. Please read CONTRIBUTING.md before contributing to the project.
Note: Much of the code was written by AI and is offered as is (AI makes mistakes, so proceed with caution). For more, please read the Readme.md file.
Pennsylvania, USA

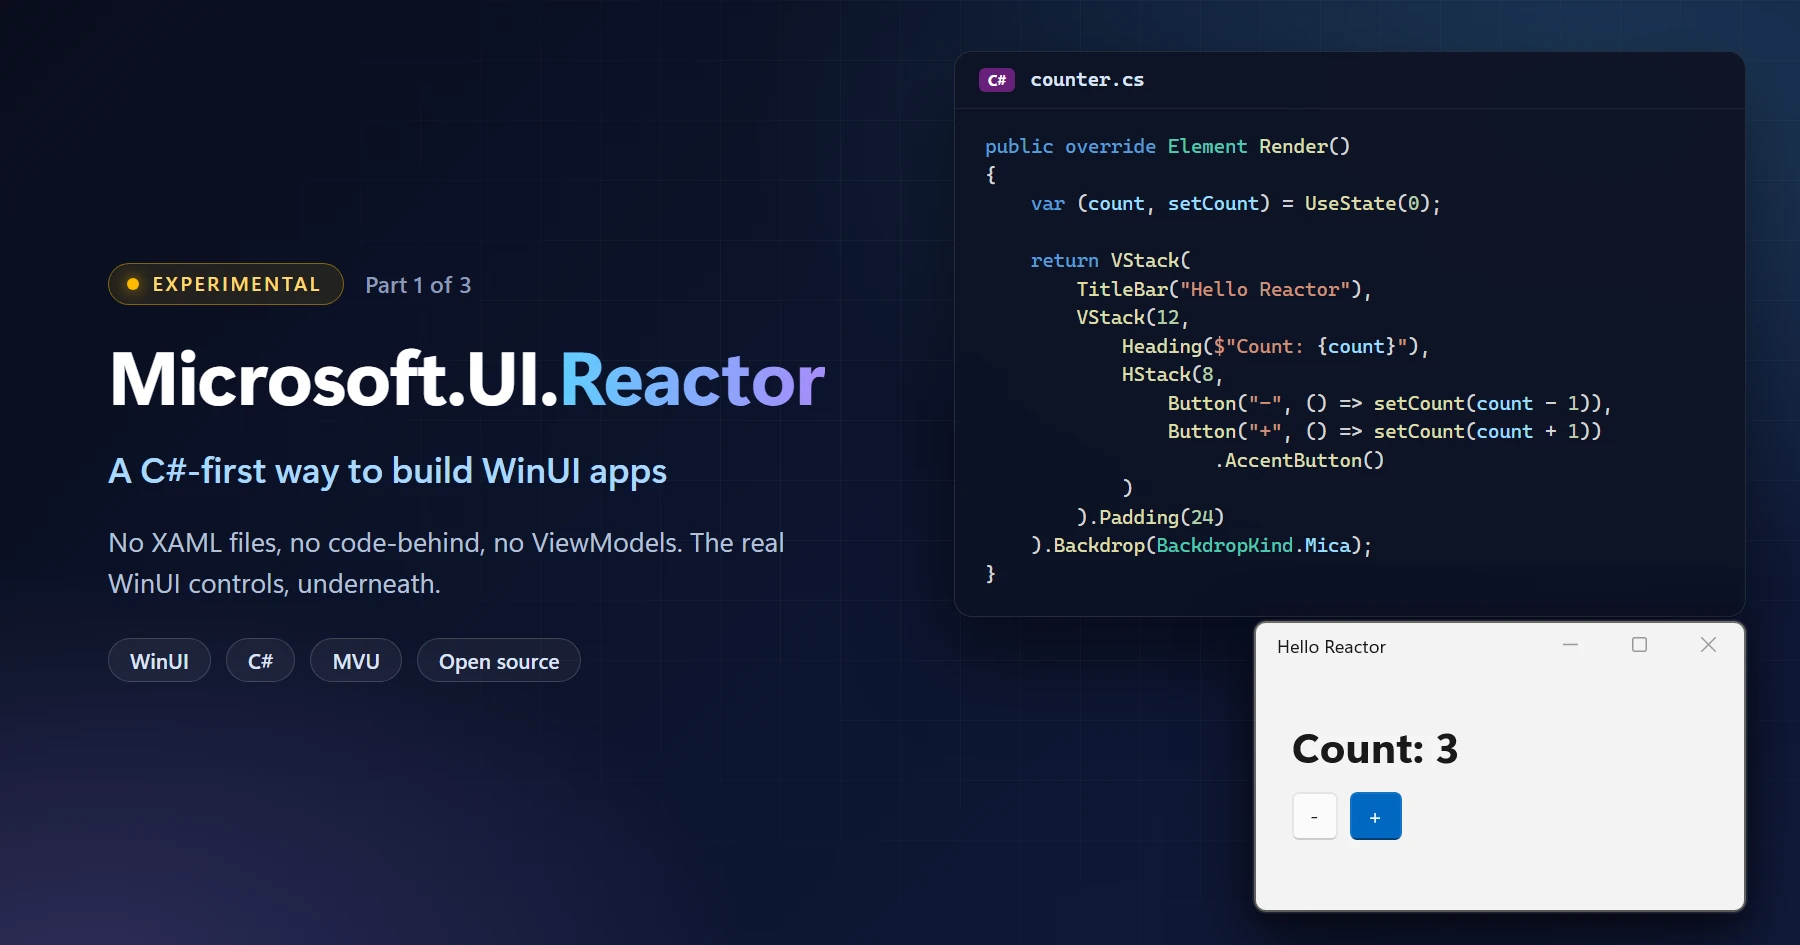
If you caught our session at Microsoft Build 2026 or you’ve been watching the repo, you’ve seen this one taking shape in public for a while now, and a lot has changed since Build. Here’s the longer tour: Microsoft.UI.Reactor, an experimental C# framework that brings the MVU (Model-View-Update) pattern to WinUI desktop apps. No XAML files, no code-behind, no ViewModels.
Two things before the fun part. Reactor is experimental: no support policy, no API guarantees, published this early on purpose because we’d rather hear we got the design wrong now than once people have shipped on it. And it is not a replacement for XAML or MVVM, which we’ll come back to.
Now the fun part.
What is Reactor?
Reactor is not a new UI platform. There is no new renderer and no fork of anything. Reactor renders WinUI controls and primitives: write Button, TextBox, NavigationView, or TreeView and you get the real WinUI control, laid out by the same panels, themed by the same resources, inspected by the same tools. A few pieces are ours, like the flex layout panel, but those are built on the same primitives your XAML app uses. What you ship is as close to the platform as it gets.
What changes is how you describe them, and the pattern you use to do it.
XAML apps are usually built with MVVM (Model-View-ViewModel): state lives on a view model, it announces changes, and bindings pull the new values into controls. Reactor uses MVU (Model-View-Update): state lives in one place, an update function returns the next state, and the view is a plain function of that state. Elm popularized it; React, SwiftUI, and Jetpack Compose are all variations on it.
Neither is a newer version of the other. They’re two established patterns with different trade-offs, and WinUI can now run both.
So instead of writing markup that gets compiled into a control tree, you write a C# function that returns an immutable description of what the UI should look like right now. Reactor diffs that description against the previous one and patches only what actually changed on the real controls underneath.
Why are we doing this? To find out how far MVU can go on WinUI, and whether it makes WinUI feel familiar to developers who already think that way. If you’ve built UI with React, React Native, SwiftUI, or Jetpack Compose, the usual WinUI path starts with learning a markup language and a binding engine, and we want to find out whether Reactor can remove that step. UI written as plain C# also turned out to be easy for coding agents to read, write, and check, so we now design for agents as well as people. And Reactor gives WinUI a place to experiment: new controls and patterns get tried here first, and the ones that prove themselves are candidates to land in WinUI itself, where they’ll work for XAML apps too. None of this is about replacing anyone: not XAML, and not you.
Here is an entire Reactor application. Not a piece of one, but the whole thing, including its package reference and build settings:
#:package Microsoft.UI.Reactor@0.1.0-preview.16
#:property OutputType=WinExe
#:property TargetFramework=net10.0-windows10.0.22621.0
#:property UseWinUI=true

using Microsoft.UI.Reactor;
using Microsoft.UI.Reactor.Core;
using static Microsoft.UI.Reactor.Factories;

ReactorApp.Run<MyApp>("Hello Reactor", width: 340, height: 200);

class MyApp : Component
{
    public override Element Render()
    {
        var (count, setCount) = UseState(0);

        return VStack(
            TitleBar("Hello Reactor"),
            VStack(12,
                Heading($"Count: {count}"),
                HStack(8,
                    Button("-", () => setCount(count - 1)),
                    Button("+", () => setCount(count + 1))
                        .AccentButton()
                )
            ).Padding(24)
        ).Backdrop(BackdropKind.Mica);
    }
}
Save that as counter.cs and run it:
winapp run counter.cs
A real WinUI window opens, with a real TitleBar, a TextBlock and two Buttons, and the counter works.

Those #: lines at the top are .NET 10’s file-based apps: package references and build properties live in the same file as the code, which makes for a quick way to try things. A more complex app uses a normal project, and there’s a template for that; see Try it below. The Reactor code doesn’t change either way.
If that snippet made you feel something (either “oh, finally” or “absolutely not”), hold onto that reaction. Both answers are useful to us, and there’s a comment box waiting at the end of the post. First impressions are data we can’t get any other way, and there’s plenty more below to react to.
By the way, what’s winapp?
Quick aside, since it’s the first command in this post. winapp is Microsoft’s CLI for Windows app development: scaffolding, package identity, MSIX packaging and signing. It works with any framework targeting Windows, not just Reactor. v0.7.0 just shipped, and it’s what lets you run a .cs file directly like we did above. We use it for every sample in this series because it handles the boilerplate. Prefer dotnet? Everything here works there too, with a flag or two more: dotnet run counter.cs -a x64 -p:WindowsAppSDKSelfContained=true. That runs it as a plain unpackaged app, though. Package identity and MSIX packaging are what winapp adds.
The same app, side by side
Let’s be fair about this comparison, because unfair comparisons are how frameworks get a reputation they don’t deserve. We’ll write the XAML version the way a good XAML developer would actually write it in 2026: x:Bind, and the MVVM Toolkit‘s source generators doing the heavy lifting.
The XAML version. Five files and a project, at minimum: the window’s markup, its code-behind, a view model, App.xaml and App.xaml.cs to bootstrap it, and a .csproj to build it. You don’t need to read the code to follow along, but here are the three files that hold the counter:
Show
MainWindow.xaml, MainWindow.xaml.cs, and CounterViewModel.cs
<!-- MainWindow.xaml -->
<Window x:Class="CounterApp.MainWindow"
        xmlns="http://schemas.microsoft.com/winfx/2006/xaml/presentation"
        xmlns:x="http://schemas.microsoft.com/winfx/2006/xaml"
        Title="Hello XAML">
    <Window.SystemBackdrop>
        <MicaBackdrop />
    </Window.SystemBackdrop>
    <StackPanel>
        <TitleBar x:Name="AppTitleBar" Title="Hello XAML" />
        <StackPanel Spacing="12" Padding="24">
            <TextBlock Text="{x:Bind ViewModel.CountText, Mode=OneWay}"
                       Style="{StaticResource TitleTextBlockStyle}" />
            <StackPanel Orientation="Horizontal" Spacing="8">
                <Button Content="-" Command="{x:Bind ViewModel.DecrementCommand}" />
                <Button Content="+" Command="{x:Bind ViewModel.IncrementCommand}"
                        Style="{StaticResource AccentButtonStyle}" />
            </StackPanel>
        </StackPanel>
    </StackPanel>
</Window>
// MainWindow.xaml.cs
public sealed partial class MainWindow : Window
{
    public CounterViewModel ViewModel { get; } = new();

    public MainWindow()
    {
        InitializeComponent();
        ExtendsContentIntoTitleBar = true;
        SetTitleBar(AppTitleBar);
    }
}
// CounterViewModel.cs
public partial class CounterViewModel : ObservableObject
{
    [ObservableProperty]
    [NotifyPropertyChangedFor(nameof(CountText))]
    public partial int Count { get; set; }

    public string CountText => $"Count: {Count}";

    [RelayCommand] private void Increment() => Count++;
    [RelayCommand] private void Decrement() => Count--;
}
The Reactor version. The MyApp class from earlier. A more complex app has a .csproj too, but the counter itself is one class, in one language.
Now: that XAML is good XAML. The source generators erase most of the boilerplate that made MVVM famous. But look at what’s still true:
- The value flows across three files and two languages before it reaches a pixel.
{x:Bind ViewModel.CountText}is a string that the XAML compiler has to be taught to understand. RenameCountTextfrom C# and you’d better hope your tooling follows.- The state lives in a class whose entire reason to exist is being observed.
- “What does this screen look like when
Countis 5?” is a question you answer by reading three files and mentally running a binding engine.
In Reactor, that last question has a very boring answer: read Render(). It’s a function. Give it a count, it gives you a UI. That’s the whole idea, and most of what Reactor is good at follows from it.
One question before we move on: does this style look like it would suit something you’re working on, or does it look like more trouble than the XAML version? Both are useful answers. “I’d stay with XAML for this screen” is a perfectly good one: we’re trying to learn which kinds of screens each model fits, not which one wins. Comments are open.
So what do you actually get?
Beyond “fewer files,” which is nice but not a strategy: everything is compile-time. No binding failures in the output window at runtime, and renaming a property updates every usage, because every usage is C#. State lives next to the UI that uses it, so there’s no ViewModel class and no PropertyChanged plumbing. And a good deal comes in the box: flexbox layout via a faithful C# port of Meta’s Yoga engine, commanding, navigation, theming tokens, localization, a DataGrid, and a docking system.
The one worth calling out is tooling. Because your UI is ordinary C#, the entire Roslyn toolchain points at it, and we’ve shipped 60+ Reactor-specific analyzers covering hooks, accessibility, theming, commanding, and performance. They catch the things that are mechanically detectable but invisible in markup: a list item missing a key, a hook called inside an if, a hard-coded brush that won’t survive dark mode, an icon-only button a screen reader would announce as “button”. You find out three seconds after you type it, not three weeks before ship.
Where XAML fits
WinUI is the foundation. XAML is a first-class way to use it, it isn’t being deprecated, and it’s still getting active investment. The XAML + MVVM model fits a large part of the WinUI user base, and the tooling, designer, templating, guidance, and third-party control ecosystem built around it aren’t going anywhere. WinUI development is moving into the open on GitHub, and platform tools like the winapp CLI are built for any framework targeting Windows, not for Reactor. Reactor sits on top of all of it.
So the two models coexist on purpose. If you’re shipping XAML/MVVM, keep shipping it. If you want MVU with no XAML, Reactor gets you there on the same runtime and the same controls. And if you want both, they interoperate in both directions, in the same process and the same visual tree, so nobody has to pick a side.
Missing a control? Any other WinUI control, third-party or your own, can be wrapped as a Reactor element and used like the built-in ones.
It’s open source. All of it.
Everything is on GitHub under the MIT license: microsoft/microsoft-ui-reactor. Framework code, design specs, sample apps, the full test suite, the CLI, the analyzers, and the VS Code extension. Clone it, build it, break it, tell us about it.
This isn’t a one-off. It’s the same direction WinUI itself is heading: it has been moving its day-to-day development into the open on microsoft/microsoft-ui-xaml, so the community can see the roadmap, follow the work, and contribute to the platform directly. Reactor was born in that world rather than being retrofitted into it: it has been public from its first commit, and there is no internal branch where the “real” work happens.
Same team. Same repo culture. Same belief that the Windows developer platform gets better faster when you can see it being built.
Reactor isn’t just running in our own samples. OpenClaw’s Windows companion app uses it in production for its chat, on by default. That app is open source too, so you can read exactly how a shipping app puts Reactor to work.
Try it
You’ll want the .NET 10 SDK and the winapp CLI (v0.7 or later, which is where running a .cs file directly arrived):
winget install Microsoft.WinAppCli
The fastest path is the one you already read. Save the counter from the top of this post as counter.cs and run it:
winapp run counter.cs
That builds the file, generates a package manifest from the #:property directives at the top of it, and launches the app with real package identity, not a loose .exe.
Prefer to stay in dotnet? dotnet run counter.cs -a x64 -p:WindowsAppSDKSelfContained=true builds and runs the same file, unpackaged. Add a #:package Microsoft.Windows.SDK.BuildTools.WinApp@* line and dotnet run gives you the packaged launch too, which is exactly what winapp is doing under the hood.
When you want a real project rather than a scratch file:
winapp new -t reactor -n MyApp
cd MyApp
winapp run
That scaffolds a packaged app (Package.appxmanifest, assets, publish profiles, the lot) and installs the WinUI template pack for you if you don’t have it. Debug builds also pull in the Reactor devtools. Four templates are available, all experimental: reactor (blank), reactor-mvu (state, actions, and a reducer wired up), reactor-navview, and reactor-tabview. Run winapp new --list to see the rest, including the XAML ones: the same CLI scaffolds both.
Prefer Rust?
The idea isn’t tied to C#. Over in windows-rs, the Rust for Windows project, we’re running the same experiment in Rust: windows-reactor is a declarative WinUI library where components own their state, controls send typed messages back, and only the WinUI controls that changed get updated.
It’s early days there too, and it’s already on crates.io. Different language, same native controls underneath.
What we’d like to know
“Let us know what you think” is the emptiest sentence in developer relations, so here are the actual questions keeping us up at night. Answer any one of them in the comments and you’ve moved this project forward:
- Does the DSL read well at scale? Twelve lines look great. Does a 400-line screen? We’re actively working with the C# language team, and the syntax can still change, but only while the experimental label is on.
- Where does it break down? Which control, which layout, which scenario made you reach for XAML instead? That’s the single most valuable thing you can tell us.
- Is interop good enough? If you can’t adopt this incrementally inside an existing app, it doesn’t matter how nice the greenfield story is.
- Is this a bad idea? If you think WinUI doesn’t need this, we want that comment too. A well-argued “no” from a working Windows developer is worth more to us right now than a dozen stars.
The experimental label stays on for the next few months while we iterate in public. Every line of code is fair game: the DSL syntax may shift, controls may come and go, the layering may get reorganized. This is the window where feedback changes the design instead of getting filed under “breaking change, too late.”
Wherever you’re most comfortable, in rough order of how little effort it costs you:
- The comments below: lowest friction, no account needed, and we read every one
- Discussions & issues: github.com/microsoft/microsoft-ui-reactor/issues
- Repo: microsoft/microsoft-ui-reactor
- Guide: microsoft.github.io/microsoft-ui-reactor
Next month
No counters. We’ll tour the twenty-odd real apps living in the repo: a registry editor, a chat client, an IDE with tear-off docking panes, then build a full minesweeper board from an empty folder. And once you’ve watched it hold up under 256 interactive controls, we’ll answer the question we already know you’re going to ask: where does the state actually live when there’s no ViewModel to put it in.
Until then: clone it, build something small, and tell us where it hurts. That’s the whole ask.
Happy coding!
The post Microsoft.UI.Reactor: a C#-first way to build WinUI apps appeared first on #ifdef Windows.
Pennsylvania, USA

Over time, knowledge has been passed down in various forms. Before writing was invented in ancient Mesopotamia (modern-day Iraq), laws, history, myths, songs, and other information were all transferred from generation to generation orally. This was done either via instructions or storytelling (especially folktales and events that had happened over time).
But another common method of knowledge transfer is from teacher to student, whether formally or informally. We’ve seen this throughout time as well: the Bible recorded that Jesus had twelve disciples whom he taught daily from the start of his mission to his death. Socrates taught Plato. Plato went on to establish an academy in Athens, where he taught Aristotle for twenty years. Aristotle revolutionized science, logic, and politics. And the list goes on.
A 21st-century example of this is deep learning AI lineage. During the 20th-century AI winter, when we thought neural networks were a dead end, this teacher-student lineage kept the dream alive.
Geoffrey Hinton, regarded as the father of AI, ran a lab where he taught Yann LeCun, Ilya Sutskever, and others. Yann LeCun went on to invent the convolutional neural network (CNN), while Ilya Sutskever co-founded OpenAI before leaving for Safe Superintelligence Inc.
While the concept of knowledge transfer between humans is quite familiar, how about knowledge transfer from machine to machine? This is known as "model distillation."
In this article, I'm going to break down what model distillation is. We'll explore the techniques it uses, and I'll walk you through how to implement it from scratch using PyTorch.
By the end, you'll understand how to train smaller, more efficient models and how distillation compares to other compression techniques like quantization and pruning.
What We'll Cover
Prerequisites
To follow along, you should have the following:
A GitHub Repository: The complete implementation of the project is available here, and you should clone it to follow along.
Basic familiarity with Python and object-oriented programming concepts (for example, working with classes).
An overview of deep learning fundamentals. You should understand concepts like epochs, forward propagation, loss function, and so on.
PyTorch Basics: While I'll explain each code section for you, basic familiarity with PyTorch tensors and training loops will be helpful.
A development environment: You should have Python installed on your machine. I'll be using Visual Studio Code as my editor, but you can use any editor or IDE of your choice.
Hardware: For this project, we'll be using a relatively small dataset so a standard CPU will work well.
What is Model Distillation?
Model distillation (or knowledge distillation) is an approach that aims to pass on the learned behavior of a large, highly accurate model to a smaller, computationally efficient model that's better suited for practical deployment.
Distillation is a compression technique where a smaller model (known as the student) learns to mimic the output of a larger, more complex model (the teacher). The goal is for the student model to achieve a level of performance close to the teacher, but with significantly fewer parameters, making it more efficient for deployment. (Source)
Why is Model Distillation Necessary?
At the time of this writing, both closed-source and open-source models are trained on trillions of parameters. These are the internal configuration variables that models learn automatically from training data. This immense number of parameters makes it extremely difficult and expensive to run without proper funding. Models consume large amounts of energy and require expensive hardware.
With distillation, we can transfer the learnings of these frontier models to smaller, more efficient models, making them easier and cheaper to use.
Model Distillation Techniques
The distillation technique used depends on the knowledge that's being transferred. Some methods transfer only the final prediction. Others transfer internal representation, attention maps, reasoning steps, or even the entire behavior of the teacher model.
These are some of the techniques:
Response-Based Distillation
Originally introduced by Geoffrey Hinton in his paper Distilling the knowledge in a neural network, this is the classic teacher-to-student distillation. Before diving deep into how it works, there are a few concepts you need to understand about model training: hard labels and soft labels.
Hard labels deal strictly with fixed categorical targets. When a picture of a dog is fed into a model and it's asked to predict if it's a dog, cat, or horse, it predicts it's a dog, given the result as Dog(1), horse(0), and cat(0). There's no probability as to what percentage or features of the picture look like a cat or a horse.
But we also have soft labels, which deal with probability. When the same picture is fed to a model using soft labels, it can predict that the picture has a 0.85 probability of being a dog, a 0.10 probability of being a cat, and a 0.5 probability of being a horse.
In response-based distillation, instead of training the student model with hard labels, it also learns from the probability of the teacher model's output (soft labels). The student can learn that the picture is a dog, but it also learns that the picture also slightly resembles a cat and barely resembles a horse.
This additional information is called dark knowledge. It enables the smaller model to copy the behavior of a larger, more accurate teacher while maintaining high performance.
Some of the advantages of response-based distillation are that it's easy to implement, it's very stable, and it works well with image classification. But there are some drawbacks, the major one being that it ignores what happens inside the network.
That is, response base distillation only looks at the output layer (the probabilities), so the student has a "black-box" relationship with the teacher model. It learns what the teacher decides, but not how it comes to that conclusion. Using the previous example, it learns the probability of what feature is a dog, cat and horse but not the underlying principle or workings of how that conclusion was made.
Feature-Based Distillation
This technique transfers the internal feature representation of the larger model rather than transferring only the final output.
An easy way to think about this is to imagine that you're a student of a great math tutor. The tutor gives you a math problem and shows you their final result. You might eventually guess the right formula, but you're mostly just learning to memorize output.
But if the tutor requires you to look at their notebook and see their work, you're learning the tutor's exact thought process.
In feature-based distillation, during training, the student model is required to produce hidden layer activations that match those of the tutor using Mean Squared Error (MSE). With mean squared error, the student model isn't just rewarded for correctly guessing the final output. It's also penalised if its internal function system doesn't match that of the teacher model.
This method is heavily used in convolutional neural networks, vision transformers, object detection, and so on.
The drawbacks of this method are that since the student has to extract and store internal feature map of the teacher model at every training iteration, memory and power consumption can quickly escalate. This makes it very expensive to run.
Attention Distillation
In this approach, instead of the student model copying all the neurons, it observes where the larger model pays attention and copies those neurons.
In transformer models, which are models that try to make sense of a sentence instead of paying attention to individual words, attention maps indicate which input tokens or regions the model considers most important when making predictions. The student tries to reproduce those maps or the distribution of the teacher model. This shows the student where to "look" when trying to solve a problem.
The drawback of attention distillation is substantial overhead in both training time and hardware resource. This is because metrics like Mean Squared Error (MSE) and Kullback-Leibler (KL) divergence need to be calculated. These metrics act as a loss function that tells a model exactly how much it's prediction or internal representation differs from the teacher model. Making this calculation across massive attention tensors contribute significantly to resource consumption.
Self-Distillation
A model is also capable of training itself. This involves knowledge transfer from an earlier version to a later version. It can also involve the transfer of knowledge between different layers in the network.
An advantage of this is that the model can become better without necessarily growing in size, reducing the cost of using a larger model to train the student model.
How to Implement Knowledge Distillation in PyTorch.
To showcase how model distillation works in real time, we'll be training a teacher and then a student model using the MNIST dataset and classifier with PyTorch.
The dataset contains about 70,000 greyscale images of handwritten digits. We'll train the teacher, then freeze it while we train a student using hard labels and soft targets from the teacher.
Note that the MNIST dataset is a relatively small dataset, so our distillation gains might not be much. But this project showcases the distillation workflow, and it will give you a good background to run larger datasets.
To run this project, you'll need the following Python packages:
| Package | Purpose |
|---|---|
torch |
The core deep learning framework we'll use to build and train neural networks. |
torchvision |
Provides datasets like MNIST and image utilities. |
numpy |
Numerical computations and array operations. |
matplotlib |
Plotting graphs and visualizing the visual images/results. |
tqdm |
Displays progress bars during training. |
For this project, I'll be working with the Visual Studio Code editor, but you can use any other code editor of your choice.
This is our project structure. I'll be explaining the folders and files below alongside the code for our project.
knowledge-distillation/
│
├── data/
│
├── models.py
│
├── engine.py
│
├── losses.py
│
├── train_teacher.py
│
├── train_student.py
│
├── train_distilled_student.py
│
├── evaluate.py
│
├── visualize.py
│
├── utils.py
│
├── plots.py
│
├── requirements.txt
│
└── README.md
First in our folder structure is our data folder. This contains our MNIST dataset.
Our models.py file defines the architecture of every neural network used in the project. It contains the teacher network class and student network class. Each class defines layers, forward propagation, and how data flow through the network.
import torch
import torch.nn as nn
import torch.nn.functional as F

class TeacherNet(nn.Module):

    def __init__(self):
        super().__init__()

        self.flatten = nn.Flatten()

        self.fc1 = nn.Linear(28 * 28, 1024)
        self.fc2 = nn.Linear(1024, 512)
        self.fc3 = nn.Linear(512, 256)
        self.fc4 = nn.Linear(256, 128)
        self.fc5 = nn.Linear(128, 10)

    def forward(self, x):

        x = self.flatten(x)

        x = F.relu(self.fc1(x))
        x = F.relu(self.fc2(x))
        x = F.relu(self.fc3(x))
        x = F.relu(self.fc4(x))

        logits = self.fc5(x)

        return logits


class StudentNet(nn.Module):
    """
    Smaller neural network (Student)
    """

    def __init__(self):
        super().__init__()

        self.flatten = nn.Flatten()

        self.fc1 = nn.Linear(28 * 28, 128)
        self.fc2 = nn.Linear(128, 10)

    def forward(self, x):

        x = self.flatten(x)

        x = F.relu(self.fc1(x))

        logits = self.fc2(x)

        return logits
The utils.py file prepares the dataset and answers the question, "Where does the dataset come from?" Here, we download the MNIST dataset, normalize the images, and create our training and testing loader.
from torchvision import datasets, transforms
from torch.utils.data import DataLoader


def get_dataloaders(batch_size=64):
    """
    Downloads MNIST (if needed) and returns
    training and testing DataLoaders.
    """

    transform = transforms.ToTensor()

    train_dataset = datasets.MNIST(
        root="data",
        train=True,
        download=True,
        transform=transform
    )

    test_dataset = datasets.MNIST(
        root="data",
        train=False,
        download=True,
        transform=transform
    )

    train_loader = DataLoader(
        train_dataset,
        batch_size=batch_size,
        shuffle=True
    )

    test_loader = DataLoader(
        test_dataset,
        batch_size=batch_size,
        shuffle=False
    )

    return train_loader, test_loader
The engine.py file contains the reusable learning algorithm and helps with how training happens. It receives the model.py code and trains it.
import torch
from tqdm import tqdm


def train_one_epoch(
    model,
    dataloader,
    criterion,
    optimizer,
    device,
):
    model.train()

    running_loss = 0

    progress = tqdm(dataloader)

    for images, labels in progress:

        images = images.to(device)
        labels = labels.to(device)

        optimizer.zero_grad()

        outputs = model(images)

        loss = criterion(outputs, labels)

        loss.backward()

        optimizer.step()

        running_loss += loss.item()

        progress.set_description(
            f"Loss {loss.item():.4f}"
        )

    return running_loss / len(dataloader)


def evaluate(model, dataloader, device):

    model.eval()

    correct = 0
    total = 0

    with torch.no_grad():

        for images, labels in dataloader:

            images = images.to(device)
            labels = labels.to(device)

            outputs = model(images)

            _, predicted = torch.max(outputs, dim=1)

            total += labels.size(0)

            correct += (predicted == labels).sum().item()

    accuracy = 100 * correct / total

    return accuracy


def predict(model, images, device):

    model.eval()

    with torch.no_grad():

        images = images.to(device)

        outputs = model(images)

        _, predictions = torch.max(outputs, dim=1)

    return predictions

def train_distillation_epoch(
    teacher,
    student,
    dataloader,
    optimizer,
    device,
    loss_fn,
    temperature=4.0,
    alpha=0.5,
):
    """
    Train the student using a frozen teacher.
    """

    teacher.eval()
    student.train()

    running_loss = 0

    progress = tqdm(dataloader)

    for images, labels in progress:

        images = images.to(device)
        labels = labels.to(device)

        optimizer.zero_grad()

        # Teacher predictions (NO gradients)
        with torch.no_grad():
            teacher_logits = teacher(images)

        # Student predictions
        student_logits = student(images)

        # Combined loss
        loss = loss_fn(
            student_logits=student_logits,
            teacher_logits=teacher_logits,
            labels=labels,
            temperature=temperature,
            alpha=alpha,
        )

        loss.backward()

        optimizer.step()

        running_loss += loss.item()

        progress.set_description(
            f"Distill Loss {loss.item():.4f}"
        )

    return running_loss / len(dataloader)
The losses.py file defines how the model measures its mistake. Since a neural network learns by minimizing loss, for baseline visualize used CrossEntropyLoss, and for knowledge distillation, we introduced distillation_loss().
Inside this file, we combined hard labels and soft targets using cross entropy and k1 divergence. This is where Geoffrey Hinton's algorithm lives.
import torch
import torch.nn as nn
import torch.nn.functional as F

cross_entropy = nn.CrossEntropyLoss()


def distillation_loss(
    student_logits,
    teacher_logits,
    labels,
    temperature=4.0,
    alpha=0.5,
):
    """
    Geoffrey Hinton's Knowledge Distillation Loss

    Parameters
    ----------
    student_logits : output from student model
    teacher_logits : output from teacher model
    labels         : ground-truth labels
    temperature    : controls softness of probability distribution
    alpha          : weight between hard and soft losses
    """

    # Hard Label Loss
    hard_loss = cross_entropy(student_logits, labels)

    # Teacher Soft Targets
    teacher_probs = F.softmax(
        teacher_logits / temperature,
        dim=1
    )

    # Student Soft Predictions
    student_log_probs = F.log_softmax(
        student_logits / temperature,
        dim=1
    )

    # KL Divergence
    soft_loss = F.kl_div(
        student_log_probs,
        teacher_probs,
        reduction="batchmean"
    )

    # Final Distillation Loss
    loss = (
        alpha * hard_loss
        +
        (1 - alpha)
        * (temperature ** 2)
        * soft_loss
    )

    return loss
The train_teacher.py file is to train the teacher network. After running this for the first time, we don't train the teacher again.
import torch
import torch.optim as optim

from models import TeacherNet
from utils import get_dataloaders
from engine import train_one_epoch, evaluate
from losses import cross_entropy

device = torch.device(
    "cuda" if torch.cuda.is_available() else "cpu"
)

train_loader, test_loader = get_dataloaders()

teacher = TeacherNet().to(device)

optimizer = optim.Adam(
    teacher.parameters(),
    lr=0.001,
)

epochs = 10

for epoch in range(epochs):

    loss = train_one_epoch(
        teacher,
        train_loader,
        cross_entropy,
        optimizer,
        device,
    )

    accuracy = evaluate(
        teacher,
        test_loader,
        device,
    )

    print(
        f"Epoch {epoch+1}/{epochs}"
        f" | Loss: {loss:.4f}"
        f" | Accuracy: {accuracy:.2f}%"
    )

torch.save(
    teacher.state_dict(),
    "teacher.pth",
)

print("\nTeacher saved successfully.")
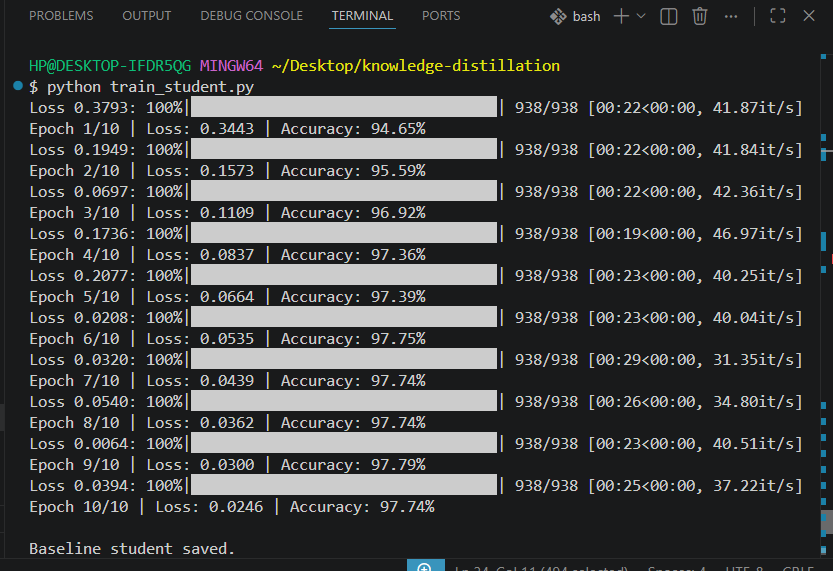
The train_student.py file is where we train the student. It's identical to that of the train_teacher except it's a smaller network and no teacher guidance is implemented here. This gives the baseline accuracy of how the student will perform without the teacher.
import torch
import torch.optim as optim

from models import StudentNet
from utils import get_dataloaders
from engine import train_one_epoch, evaluate
from losses import cross_entropy

device = torch.device(
    "cuda" if torch.cuda.is_available() else "cpu"
)

train_loader, test_loader = get_dataloaders()

student = StudentNet().to(device)

optimizer = optim.Adam(
    student.parameters(),
    lr=0.001,
)

epochs = 10

for epoch in range(epochs):

    loss = train_one_epoch(
        student,
        train_loader,
        cross_entropy,
        optimizer,
        device,
    )

    accuracy = evaluate(
        student,
        test_loader,
        device,
    )

    print(
        f"Epoch {epoch+1}/{epochs}"
        f" | Loss: {loss:.4f}"
        f" | Accuracy: {accuracy:.2f}%"
    )

torch.save(
    student.state_dict(),
    "student_baseline.pth",
)

print("\nBaseline student saved.")
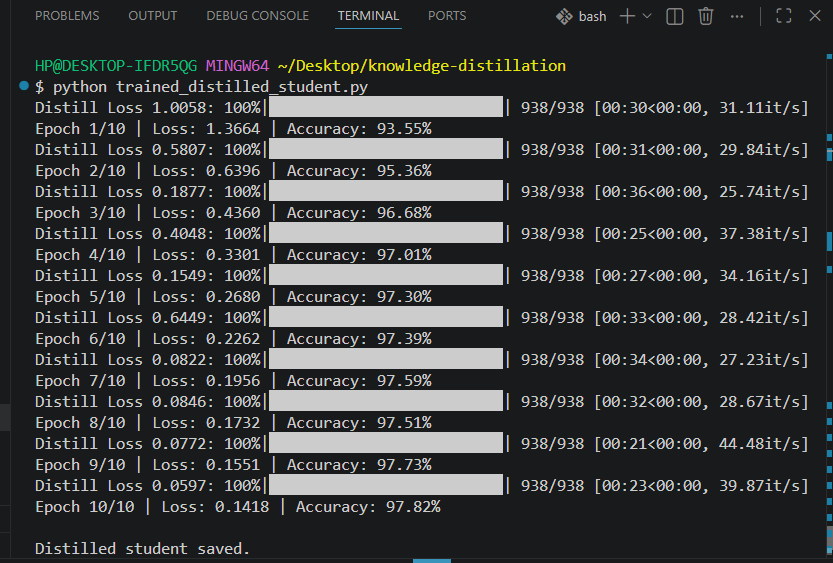
The train_distilled_student.py is the heart of this code. In this file, we teach the student using both labels and the teacher's knowledge. Here, we implement response-based knowledge distillation.
import torch
import torch.optim as optim

from models import TeacherNet, StudentNet
from utils import get_dataloaders
from engine import (
    train_distillation_epoch,
    evaluate,
)
from losses import distillation_loss

device = torch.device(
    "cuda" if torch.cuda.is_available() else "cpu"
)

train_loader, test_loader = get_dataloaders()

# Load Teacher
teacher = TeacherNet().to(device)
teacher.load_state_dict(
    torch.load(
        "teacher.pth",
        map_location=device,
    )
)

teacher.eval()

# Student
student = StudentNet().to(device)

optimizer = optim.Adam(
    student.parameters(),
    lr=0.001,
)

epochs = 10

for epoch in range(epochs):

    loss = train_distillation_epoch(
        teacher,
        student,
        train_loader,
        optimizer,
        device,
        distillation_loss,
        temperature=3,
        alpha=0.7,
    )

    accuracy = evaluate(
        student,
        test_loader,
        device,
    )

    print(
        f"Epoch {epoch+1}/{epochs}"
        f" | Loss: {loss:.4f}"
        f" | Accuracy: {accuracy:.2f}%"
    )

torch.save(
    student.state_dict(),
    "student_distilled.pth",
)

print("\nDistilled student saved.")
The evaluate.py measures how well a trained model performs. Here, we simply load the model, load test data, predict, and compute the accuracy.
import torch

from models import TeacherNet
from utils import get_dataloaders
from engine import evaluate

device = torch.device(
    "cuda" if torch.cuda.is_available() else "cpu"
)

_, test_loader = get_dataloaders()

teacher = TeacherNet().to(device)

teacher.load_state_dict(
    torch.load(
        "teacher.pth",
        map_location=device,
    )
)

accuracy = evaluate(
    teacher,
    test_loader,
    device,
)

print(
    f"Teacher Accuracy: {accuracy:.2f}%"
)
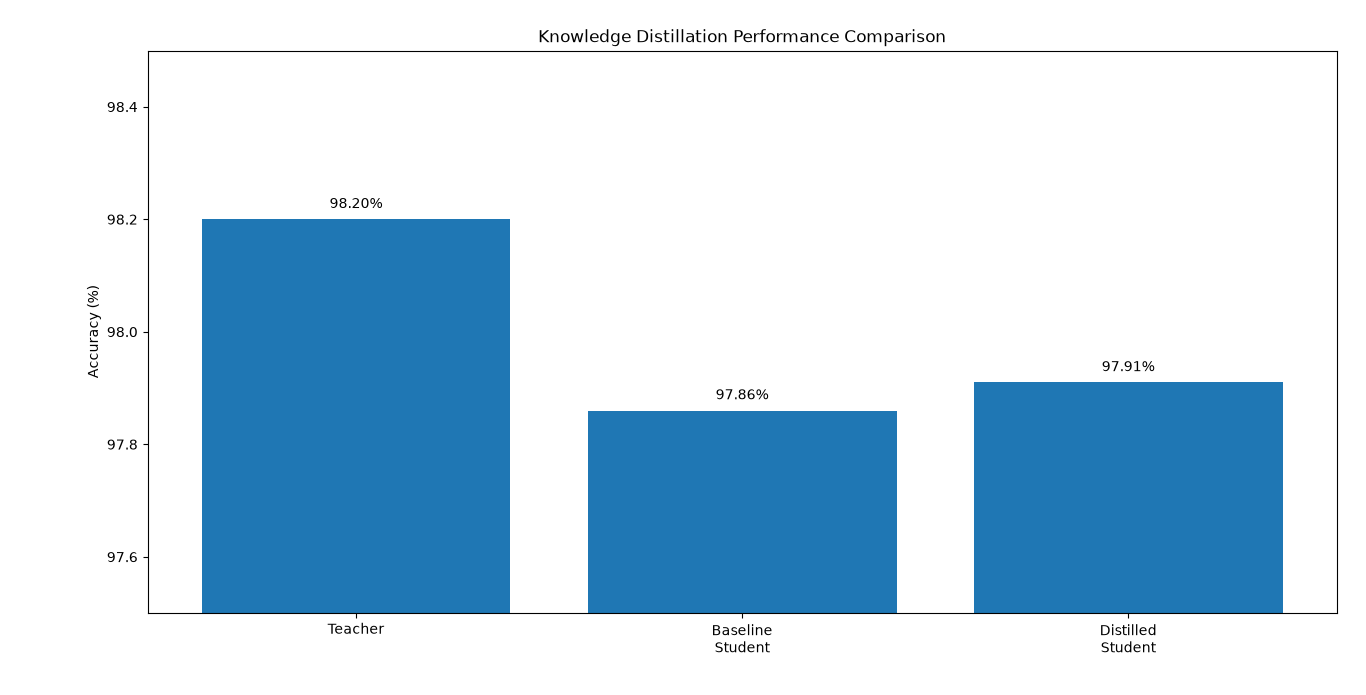
The visualize.py file is to present our findings visually. We use the Python package matplotlib to visualise the results of our teacher, baseline student, and distilled student.
import matplotlib.pyplot as plt

models = [
    "Teacher",
    "Baseline\nStudent",
    "Distilled\nStudent"
]

accuracy = [98.20, 97.86, 97.91]

plt.figure(figsize=(7,5))
plt.bar(models, accuracy)

plt.title("Knowledge Distillation Performance Comparison")
plt.ylabel("Accuracy (%)")

for i, v in enumerate(accuracy):
    plt.text(i, v + 0.02, f"{v:.2f}%", ha="center")

plt.ylim(97.5, 98.5)

plt.tight_layout()
plt.savefig("accuracy_comparison.png", dpi=300)
plt.show()
You can see the entire workflow of our program below so you understand how everything comes together:
                       utils.py
                          │
                 Load MNIST Dataset
                          │
                          ▼
                     models.py
             TeacherNet / StudentNet
                          │
                          ▼
                     losses.py
  Cross Entropy + Distillation Loss Function
                          │
                          ▼
                     engine.py
    Generic Training and Evaluation Functions
             ┌────────────┼────────────┐
             │            │            │
             ▼            ▼            ▼
  train_teacher.py  train_student.py  distilled_student.py
             │            │            │
             ▼            ▼            ▼
   teacher.pth  student_baseline.pth  distilled.pth
                          │
                          ▼
                     evaluate.py
              Compute Final Accuracy
                          │
                          ▼
                    visualize.py
     Generate Charts and Experimental Figures
How to Evaluate the Results
Now, let's check and evaluate our results. These are screenshots from running ten epochs for each of the networks: the teacher, student, and distilled student network.
Teacher Network: After 10 complete cycles, we attained an accuracy of 98.20%.
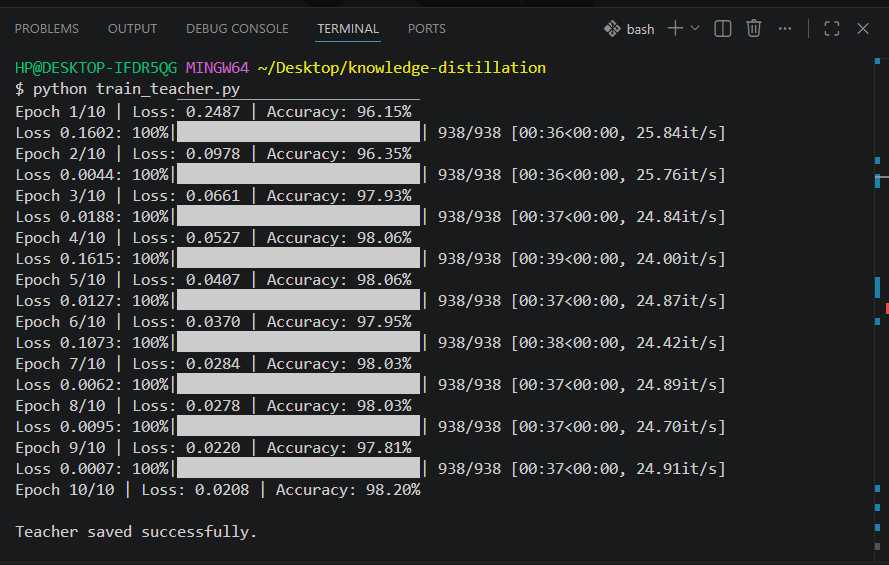
Student Network: After 10 complete cycles, we attained an accuracy of 97.74%. This is a pretty good performance for a smaller network without the teacher model.
Distilled Student Network: After 10 complete cycle, we attained an accuracy of 98.20%. We had an improvement from 97.74% achieved without the teacher's model knowledge.
Check out the chart below that shows how each model performed:
Other Approaches for Reducing Model Size
Now that we've seen what model distillation is with real-world code examples. Let's look at other approaches that developers are taking to reduce the size of large language models to save on latency, memory footprints, and compute cost and how they differ from distillation.
We have three other major approaches for this:
Quantization
Quantization achieves efficiency by strictly reducing the bit-width of the underlying data types used to store numerical weight and activations of the neural network. It targets the memory bandwidth bottleneck rather than the model architecture.
In simple terms, quantization can change a 32-bit number to 8-bit numbers, which saves about 75% of the file size.
A real-world example of how quantization differs from distillation is trying to save resources like ink and paper when printing a textbook. Distillation summarizes the textbook, while quantization prints the exact thing but uses a lower-resolution font to save ink and paper.
Pruning
Pruning operates on the principle that large language models often have too many redundant and low-impact parameters on the network. By removing weak connections, models can become smaller and faster.
For the textbook analogy, the pruning process is like going through the textbook and ripping off pages or chapters that you feel aren't needed.
Low-Rank Factorization
This is a mathematical process that uses linear algebra to simplify the matrix multiplication that dominates the deep learning architecture.
With the textbook example, this process involves rewriting complex sentences into simpler, shorter formulas that mean the same thing.
Choosing which method to use depends on the bottleneck you're trying to solve. Quantization generally works well for memory challenges, while pruning and distillation are designed to reduce computation time.
Conclusion
Knowledge transfer is as fundamental to artificial intelligence as it is to human history. Just as Aristotle built upon the teachings of Plato, today's efficient, deployable neural networks rely on the foundational "dark knowledge" extracted from massive, compute-heavy teacher models.
While training trillion-parameter frontier models requires immense hardware and financial resources, knowledge distillation ensures that the practical benefits of these advancements aren't locked behind massive computational bottlenecks.
As we demonstrated with the PyTorch MNIST experiment, even a simple response-based distillation can help a smaller network punch above its weight class by learning from the soft probabilities of a larger teacher.
When combined with other optimization techniques like quantization and pruning, distillation provides a clear pathway for deploying highly capable AI on edge devices, mobile phones, and consumer-grade hardware.
Thank you for reading! Please check out my YouTube channel, where I post videos on AI-related content.
References:
What does it mean to distill a machine learning model or LLM?
AI Insights: Model Distillation from the Department for Science, Innovation and Technology
Model distillation for LLMs: A practical guide to smaller, faster AI
Distilling knowledge in a neural network by Geoffrey Hinton
Pennsylvania, USA
Next Page of Stories