Log in

Understand C# event contracts with practical payload and decision examples, explicit notification timing, no-subscriber defaults, and failure boundaries.

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|
Understand C# event contracts with practical payload and decision examples, explicit notification timing, no-subscriber defaults, and failure boundaries.


The motif of the picture up above is the old saying “the cobbler’s children have no shoes.” In the case of JasperFx Software, we’re a software development consultancy that hasn’t done enough (yet) to automate our own business. Now that development is pretty cheap with our new fangled AI tools, I’m looking to take our existing JasperFx portal application and grow it into a complete CRM tool we can use to basically automate all the annoying paperwork I don’t enjoy doing and generally get the business to be much more organized as we’re growing.
Two decades ago I worked for a software consultancy that I’d argue was one of the best on the planet, but who also had an absolutely dreadful homegrown T&E system someone had hacked together with Lotus Notes. The irony was lost on nobody there.
At the same time, we’ve made a ton of releases lately around “Event Modeling” or “Spec Driven Development” (okay, I’m not sure I buy into that second one and we’re really just building out an optimized Critter Stack way to do BDD that’s hopefully optimal for AI agents). These new capabilities are a bit spread out and we don’t yet have a ton of content showing this new stuff off.
We do have an existing tutorial on Event Modeling with the Critter Stack on the Wolverine documentation site, but I generated it with Opus just to have something that tied everything together on the website and it reads like something obviously generated with AI and not enough human editing yet (the JasperFx AI Skills do this already, but that’s of course optimized for AI agents).
To kill a couple birds with one stone, I’ve started working on a new version of the JasperFx CRM using the Critter Stack that I’m going to mostly build in public and use that effort to dogfood our new Critter Stack capabilities and to build out a new set of tutorials on Event Modeling with the Critter Stack that we expect to eventually land on the JasperFx Software website. So far I’m thinking:
And from there, I think we could lift lots of small sample usages to demonstrate Wolverine & Marten usage
I’m thinking I’ll try to do the stumbling and fumbling drafts on this blog, then publish the finished product to jasperfx.net with the sample application in CritterStackSamples.
And folks, I’m happy to take requests or feedback!

Dynamic applications can adapt workflows in real time as tasks change, reducing user navigation and repetitive input and providing agents with structured paths.
Most application workflows are designed in advance. We decide which screen comes first, which fields appear on a form and what happens after someone clicks submit. The path may branch based on role or account state, but the application still follows behavior we programmed in advance.
AI gives us room to adapt a workflow while a task is in progress. For example, a model can interpret what the user is trying to accomplish, retrieval can bring in relevant context and an agent can inspect application state before deciding which action to request. The interface can then surface the information or controls that fit the current task.
This is the idea behind a dynamic application. Parts of a workflow can change based on user context, application state and agent activity, while the application keeps control of permissions, validation and business rules.
Consider an expense application. A standard flow might ask a user to upload a receipt, enter the merchant, select a category, choose a cost center and submit the expense for review. Some steps exist because the application needs information it cannot resolve on its own.
With an AI-powered workflow, a model can extract the merchant and total from the receipt. Application code can load the employee’s cost center, while retrieval can find the policy that applies to the expense. If the only missing value is a project code, the interface can ask for that value rather than showing the full form.
We’ll still need the same validated expense record before submission, but the application can adapt how we get there based on the information already available. This separation means we can keep workflow states and business rules in code while allowing the AI layer to help choose the most useful next step.
| Application responsibility | AI-assisted responsibility |
|---|---|
| Define valid workflow states | Interpret the current task |
| Enforce permissions | Select from permitted capabilities |
| Validate records and tool arguments | Extract values from unstructured input |
| Apply policy limits | Retrieve and summarize relevant policy |
| Execute state changes | Prepare or recommend the next action |
For an application to adapt effectively, it needs to understand more than the immediate request. It also needs context about the task taking place.
Much of that context already exists in systems we build today. The frontend knows which record is open, which view is active and what the user selected. The backend knows the user’s permissions, account state and related records. Retrieval can add documentation or policy, while application-managed memory can supply preferences that remain useful across sessions.
Take a support engineer opening a billing case. The application already knows the customer, the disputed invoice, and the engineer’s permissions. An agent can inspect recent payments and retrieve the refund policy. Instead of opening several tabs and gathering the same information by hand, the engineer can start with the invoice mismatch and the relevant policy in view.
It’s important to keep in mind that we should still limit the context passed to the model. Sending an entire customer record adds token cost and may expose fields the current task does not need. The backend should assemble the smallest useful context for the request, just as it filters data for any other application feature.
The same principle applies to tools. A billing agent may need get_payment_history and get_refund_policy, but it doesn’t need access to every operation in the support system. Context and capabilities should always match the task.
When building dynamic applications, we’ll generally want to avoid generating the whole UI dynamically because that makes the experience harder to predict, test, and maintain. Instead, we can keep the interface grounded in components we already control, then use context to decide which component should appear for the current task and workflow state.
Suppose a support application has three contextual panels:
type SupportPanel =
  | {
      type: "invoice_comparison";
      invoiceId: string;
      paymentIds: string[];
    }
  | {
      type: "refund_approval";
      requestId: string;
      amount: number;
      evidenceIds: string[];
    }
  | {
      type: "customer_timeline";
      customerId: string;
      eventIds: string[];
    };
If an agent finds a duplicate charge, the backend can return an invoice_comparison panel. The frontend then maps that panel type to the corresponding component. If the workflow later requires approval, the backend can return refund_approval, and the same region updates to show the approval interface. The frontend still owns the layout, accessibility behavior, loading states, and controls for each component.
function renderSupportPanel(panel: SupportPanel) {
  switch (panel.type) {
    case "invoice_comparison":
      return <InvoiceComparison {...panel} />;

    case "refund_approval":
      return <RefundApproval {...panel} />;

    case "customer_timeline":
      return <CustomerTimeline {...panel} />;
  }
}
This pattern gives us a useful form of personalization as well. Two people can open the same record and need different information because they have different responsibilities. A support engineer may need the conversation history and refund controls, while a billing specialist may need payment history and policy details.
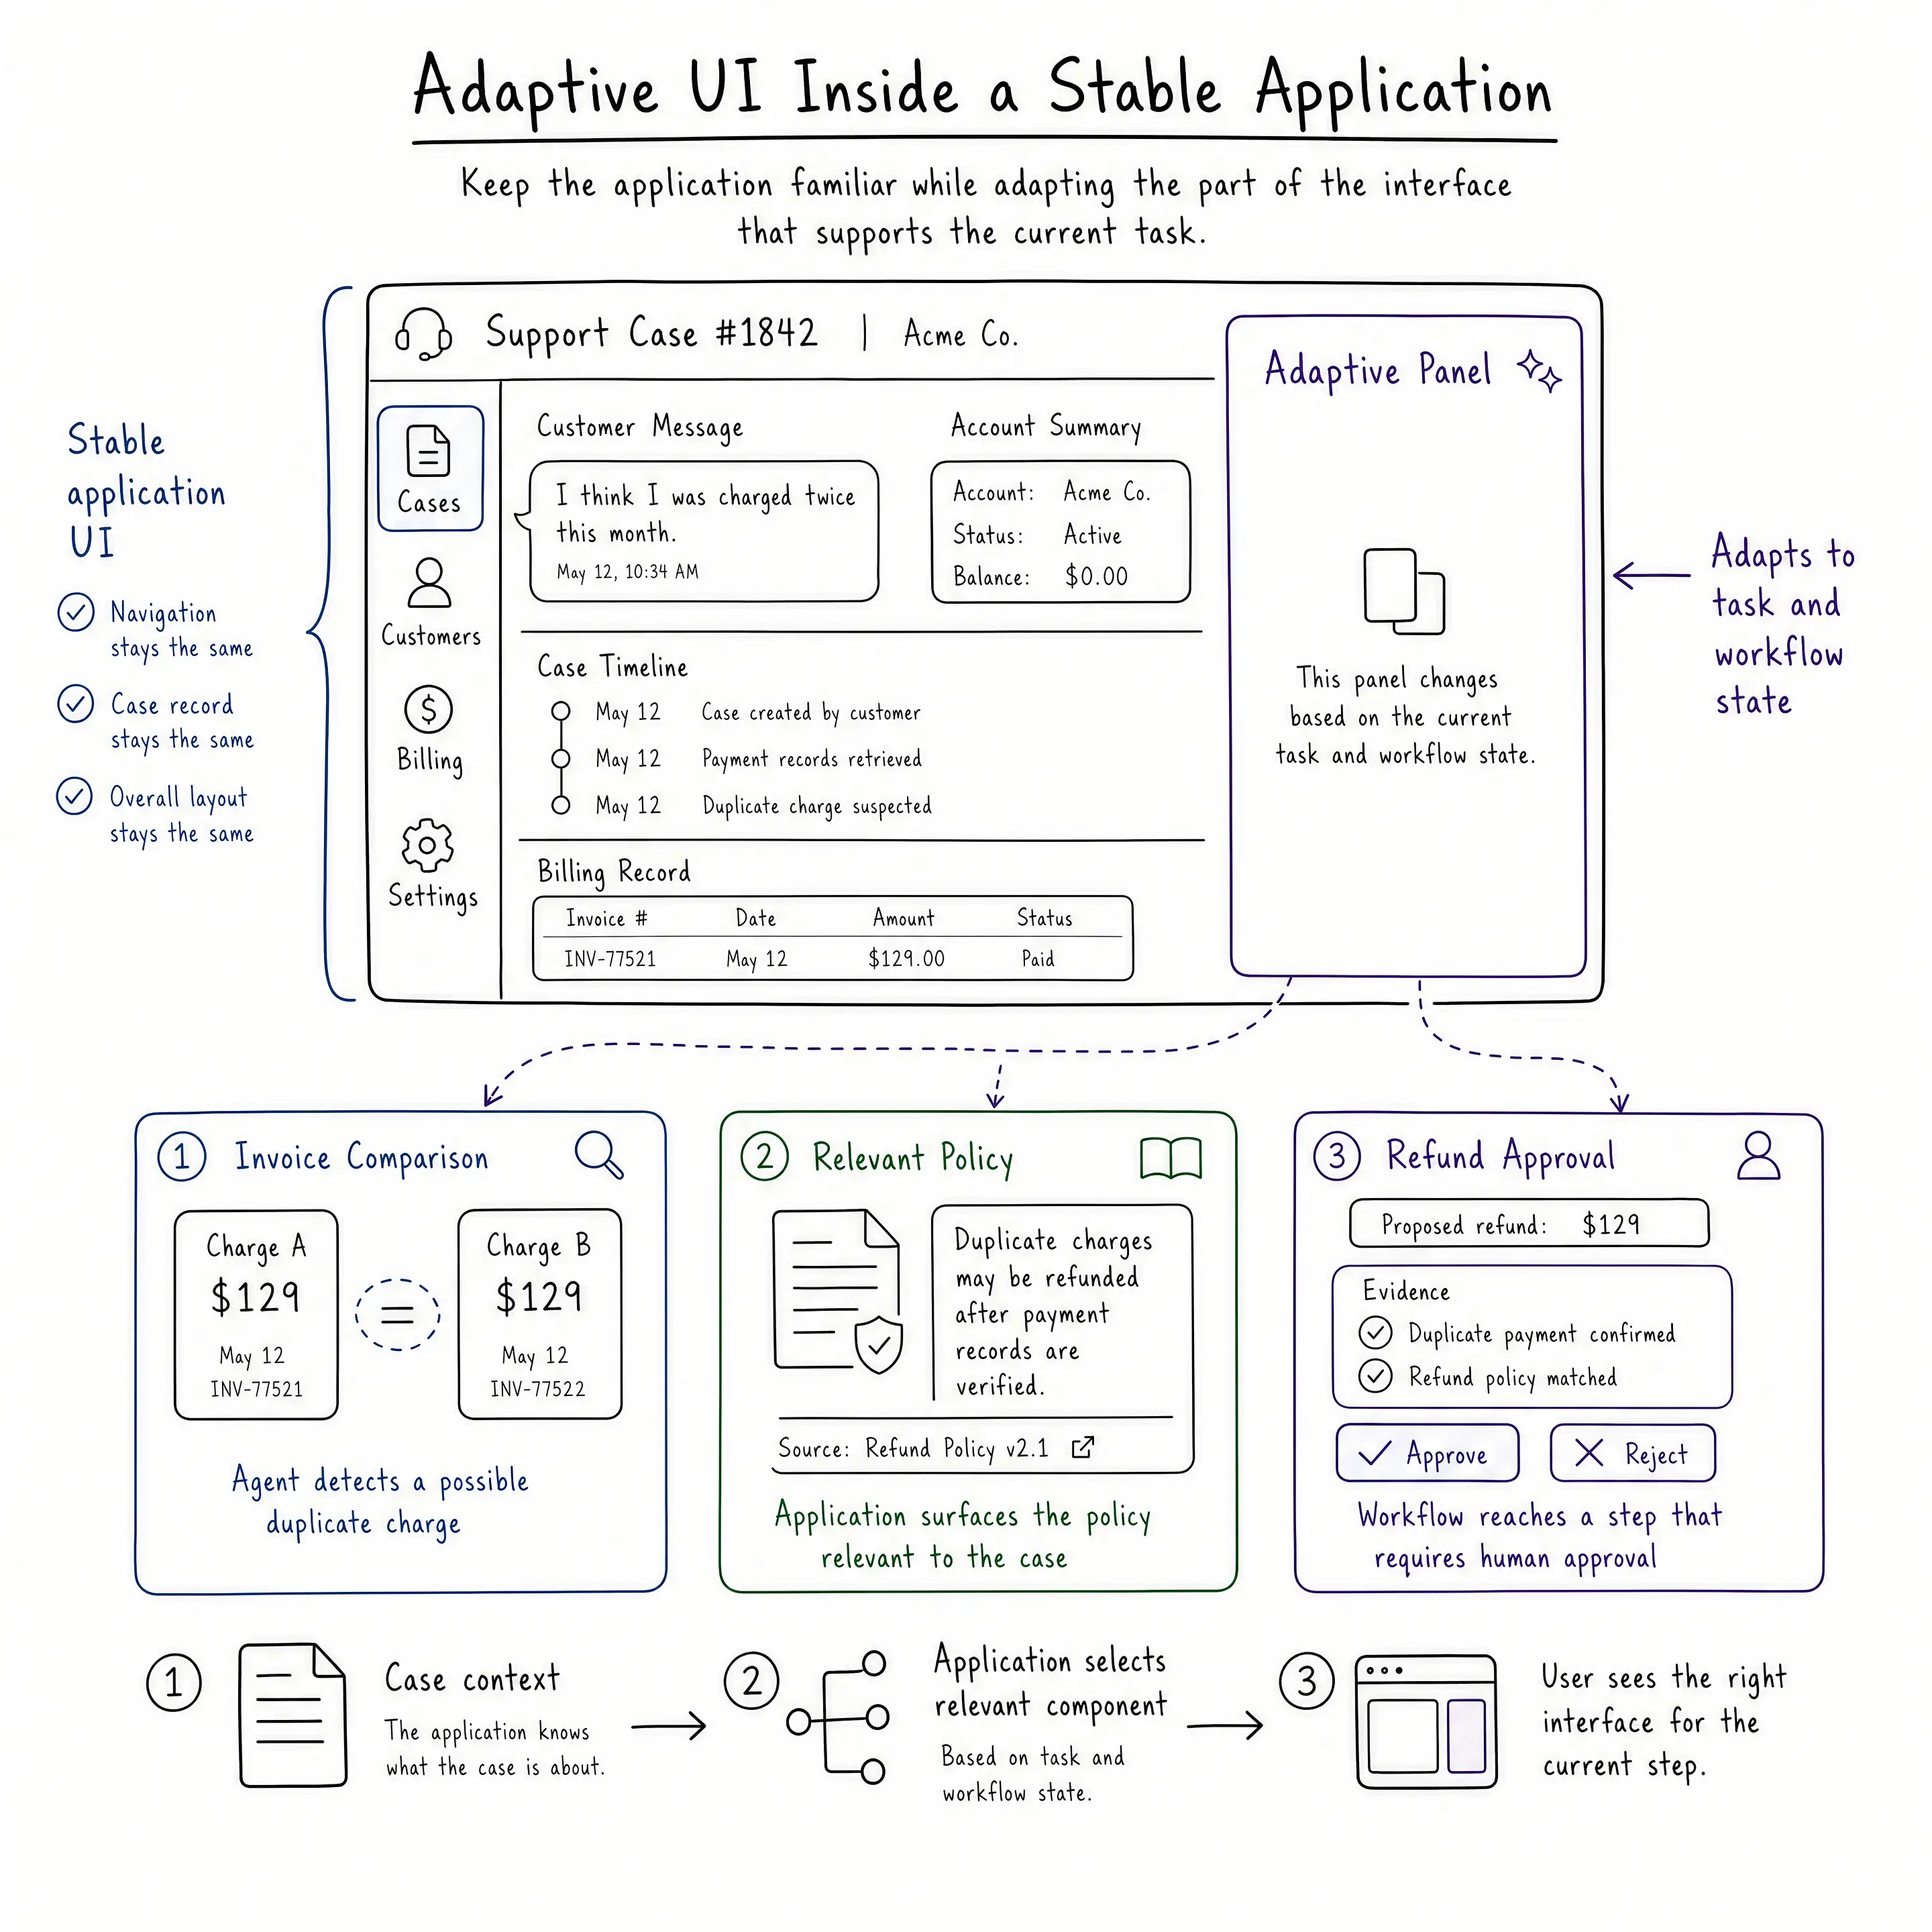
So far, we’ve looked at how the interface of a dynamic application can adapt based on context. The same idea extends to workflows where an agent is actively completing work on the user’s behalf. An agent can receive a goal, choose tools and progress through several steps, with each step potentially changing application state while the user remains on the same screen.
Imagine an agent helping with the billing case example we’ve discussed above. It reads the payment history, retrieves the refund policy and confirms that the customer was charged twice.
If the amount falls within its delegated limit, the agent may prepare a refund. If the amount requires approval, the workflow should pause and surface that decision in the interface.
A chat transcript can describe what the agent is doing, but the application already has a better place for most of this information. The invoice view can mark the duplicate payments, the approval can appear beside the refund amount, and the activity history can record what the agent checked and what action it requested.
This gives us several interface states to design for:
These states connect the agent to the workflow instead of placing its work inside a separate assistant panel.
Dynamic workflows still need fixed boundaries. The interface may adapt, and the agent may choose its route, but application code should enforce permissions, policy and valid state transitions.
Let’s consider a refund request. The model may prepare the amount and reason, but the backend can route that request according to business policy:
function routeRefund(
  request: RefundRequest,
  context: SupportContext,
) {
  authorize(context.user, "refund:create");

  if (!context.policyMatches || request.amount > 200) {
    return { status: "escalated" };
  }

  if (request.amount > 25) {
    return { status: "awaiting_approval", request };
  }

  return { status: "execute", request };
}
With the above, the interface can render a different state for each outcome. A small refund can proceed, a larger one can pause for approval, and a request outside policy can move to a human owner.
The model does not decide how much authority it has since execution limits need to be predictable and enforceable. Tool permissions, schema validation and policy checks enforce that boundary outside the model.
We can bring the pieces together with the refund example we’ve discussed in this article. To start, assume a support engineer opens a billing case and asks:
Can we refund this charge?
A dynamic application can handle the request as follows:
The interface adapted during the conversation, but the billing case remained the same product surface. The agent gathered context through structured tools and presented explanations alongside the records the support engineer was reviewing. The user received a task-specific view without having to navigate through several support screens.
This is the useful middle ground for dynamic applications. We can make workflows responsive to intent and context without making the application itself unpredictable.
Dynamic applications can adapt parts of a workflow as the task changes. The application can use current UI state, account data, retrieved knowledge and agent activity to decide what information and controls belong in front of the user.
For users, this can reduce navigation and repeated data entry. For agents, it creates structured paths into the same capabilities that power the interface. Both consumers work against the same backend rules for permissions, validation and execution.
As applications serve both people and agents, this balance is important. The workflow can adapt in real time, while the application remains responsible for what each participant can see, change and approve.
For more on building AI-powered applications and agents with Progress, check out the following resources:
What happens when companies can grow without hiring as many people? And what happens when the tools driving that change become available to the people trying to understand it?
I have followed Dror Poleg for his writing on technology, work and the economy. For Factory Life, Hugo and I invited him to share both his view of what is changing and the AI tools he has built to support his research.
Dror showed us a personal system that collects information, helps him find patterns and keeps track of his own predictions. He also talked about the choices he makes about what to delegate and what to keep for himself.
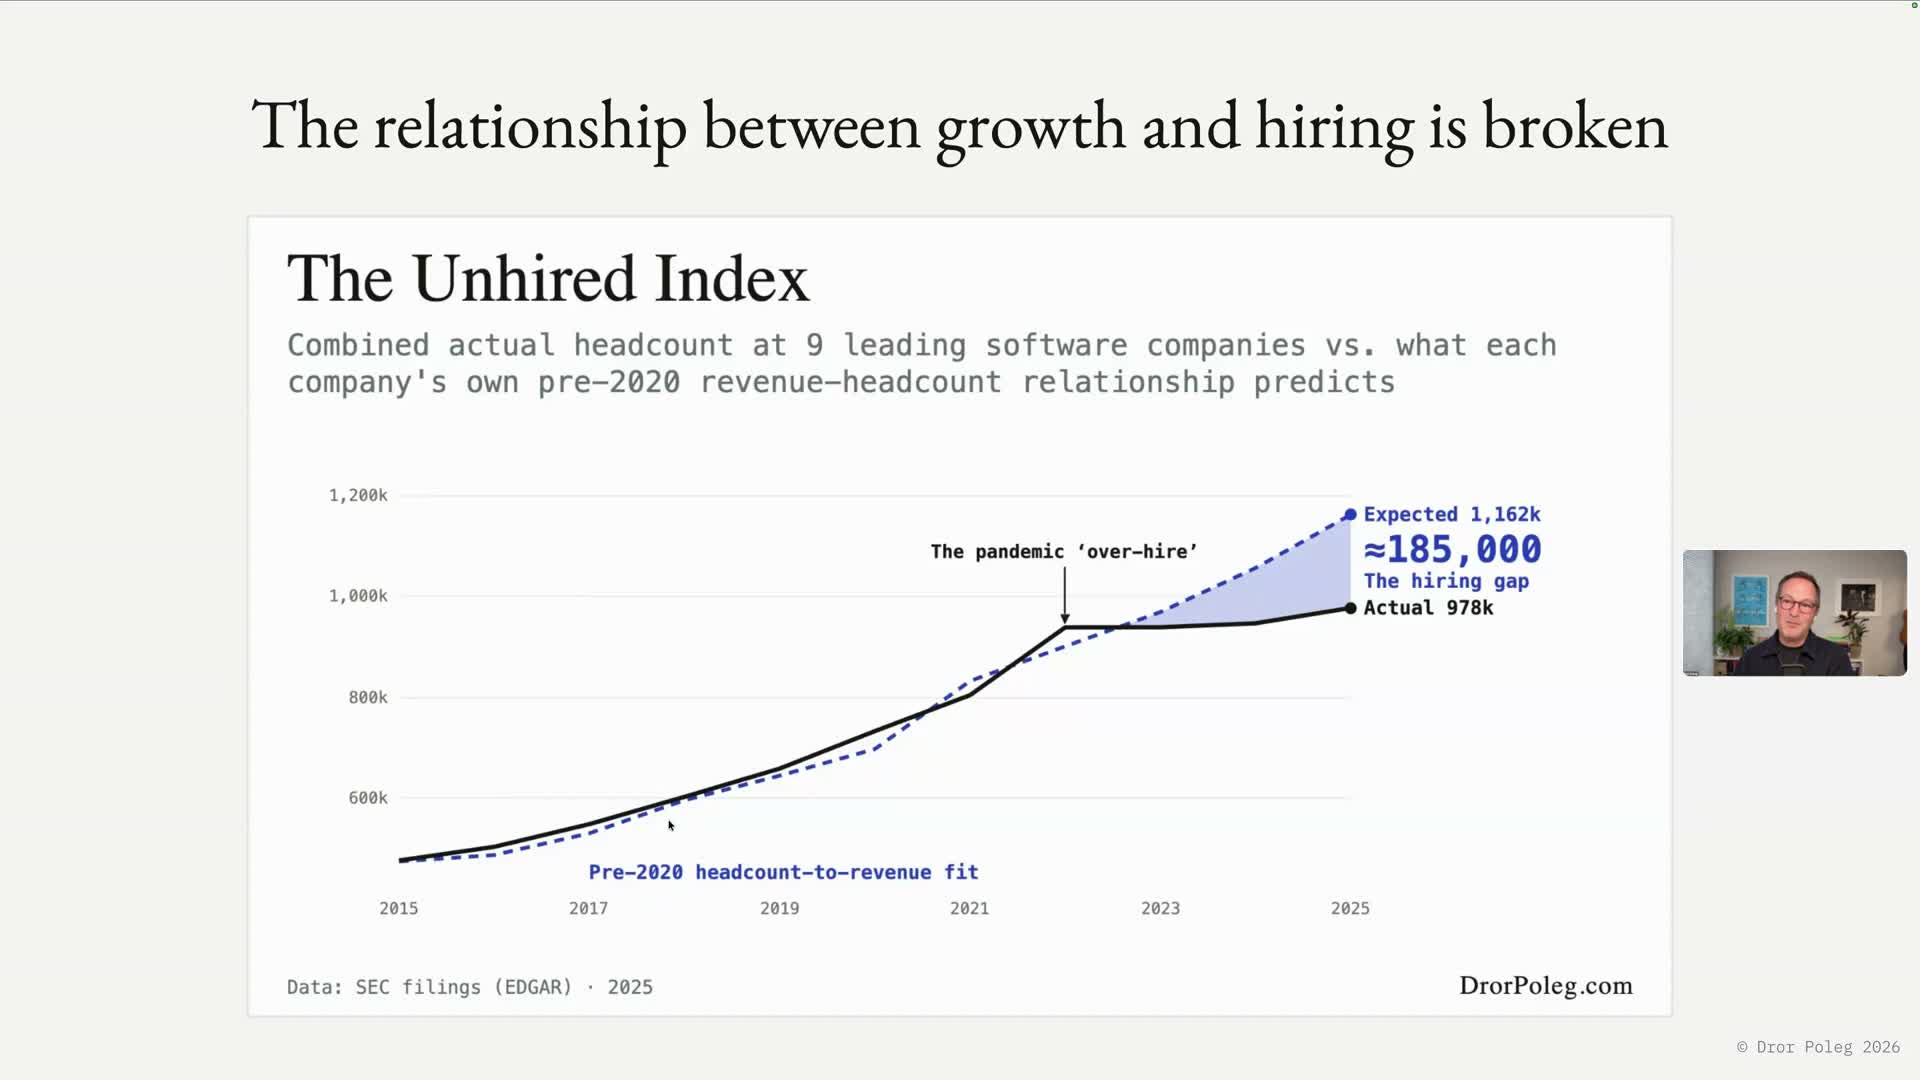
Dror began with a striking change in the relationship between revenue and headcount at large software companies. His “Unhired Index” compares the number of people nine companies employ with the number their earlier relationship between revenue and employment would have predicted.
His estimate suggests a substantial gap. That is an interesting signal, though it does not tell us how much of the change AI caused. Hiring during the pandemic, the subsequent correction and other shifts in how companies operate all complicate the picture. Dror was careful about that distinction.
He also discussed signs of pressure on entry-level work. Even if new roles appear over time, the transition matters: people need a way into a profession and opportunities to build experience. A discussion about the total number of jobs can miss what happens to the people trying to find a first one.
“Even if the jobs remain, often the quality of the job changes.”
For a company leader, this raises a question beyond how many roles a new tool can save. If experienced people can do more with agents, how will the next generation acquire the experience the organisation will need?
Dror’s own use of AI starts with a problem many of us recognise: there is more to read, track and remember than one person can comfortably manage. His system gathers information from sources he chooses and helps him decide what deserves his attention.
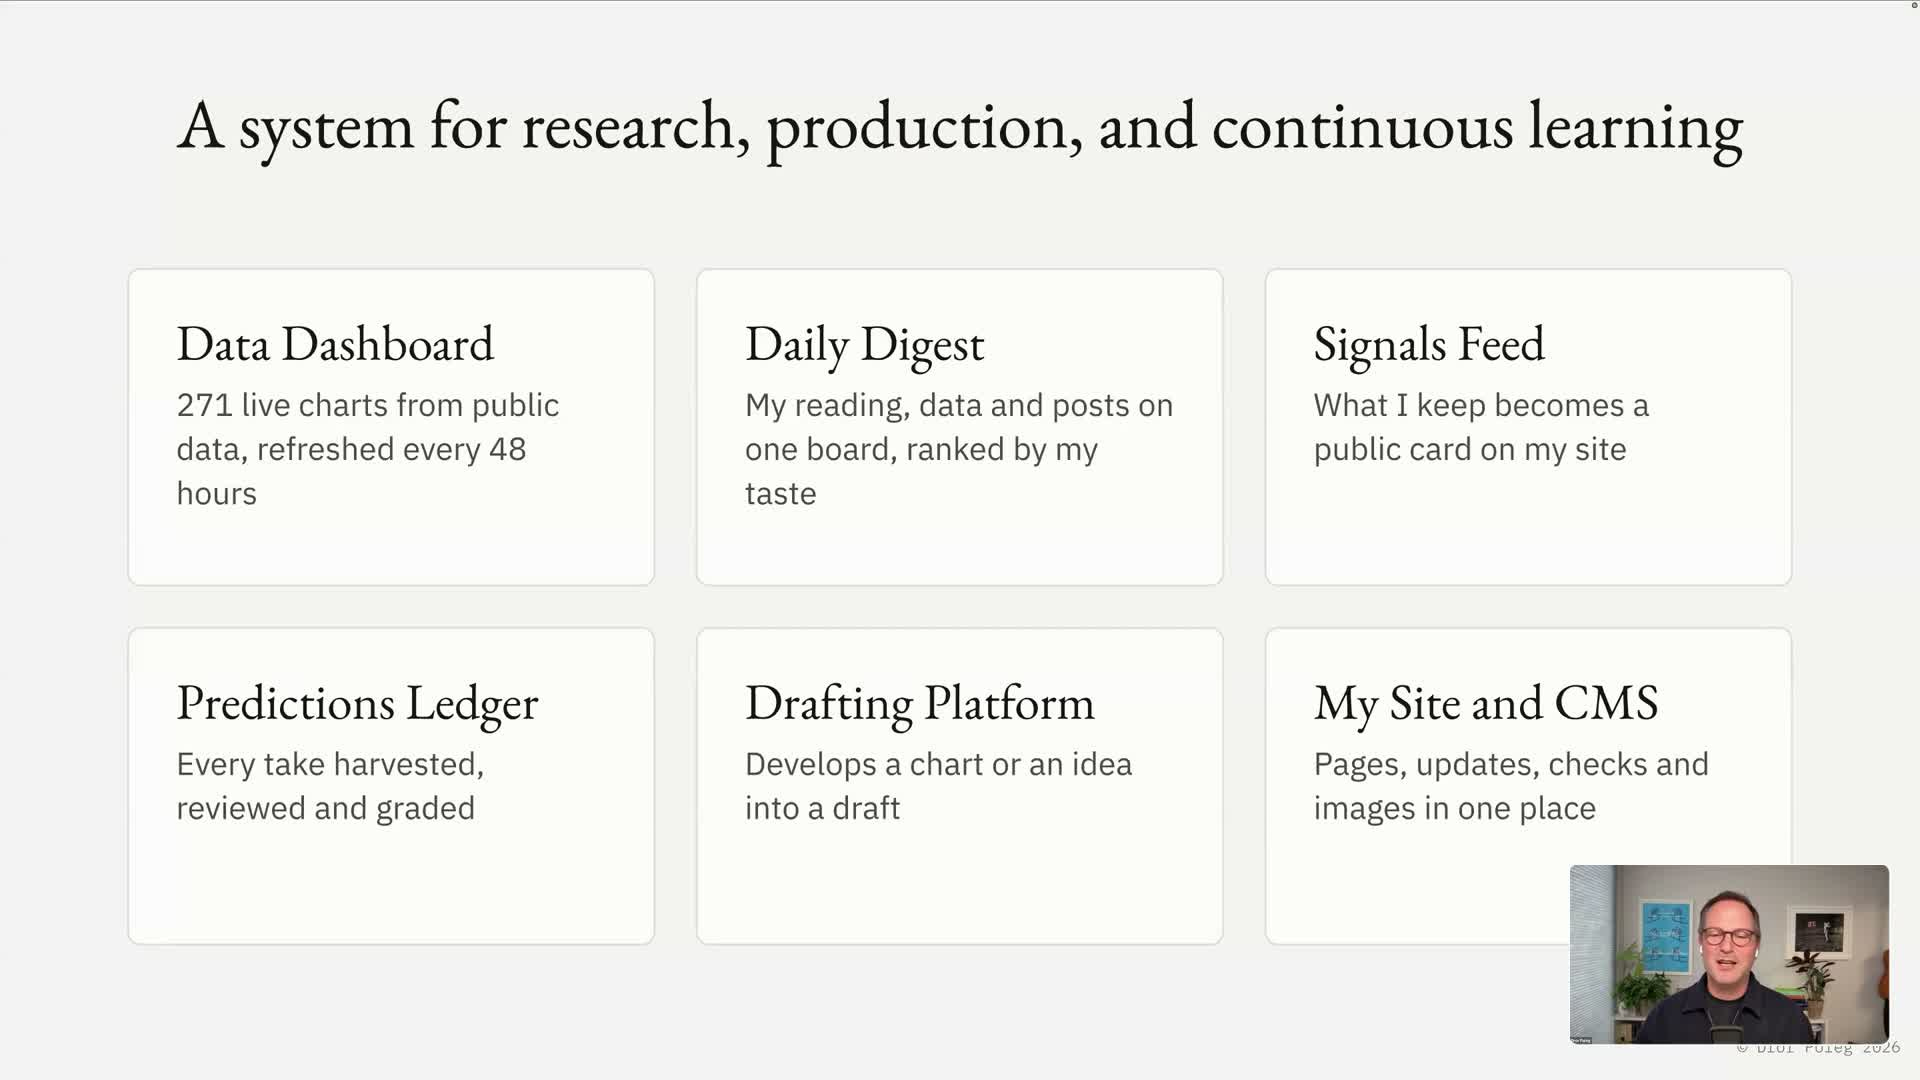
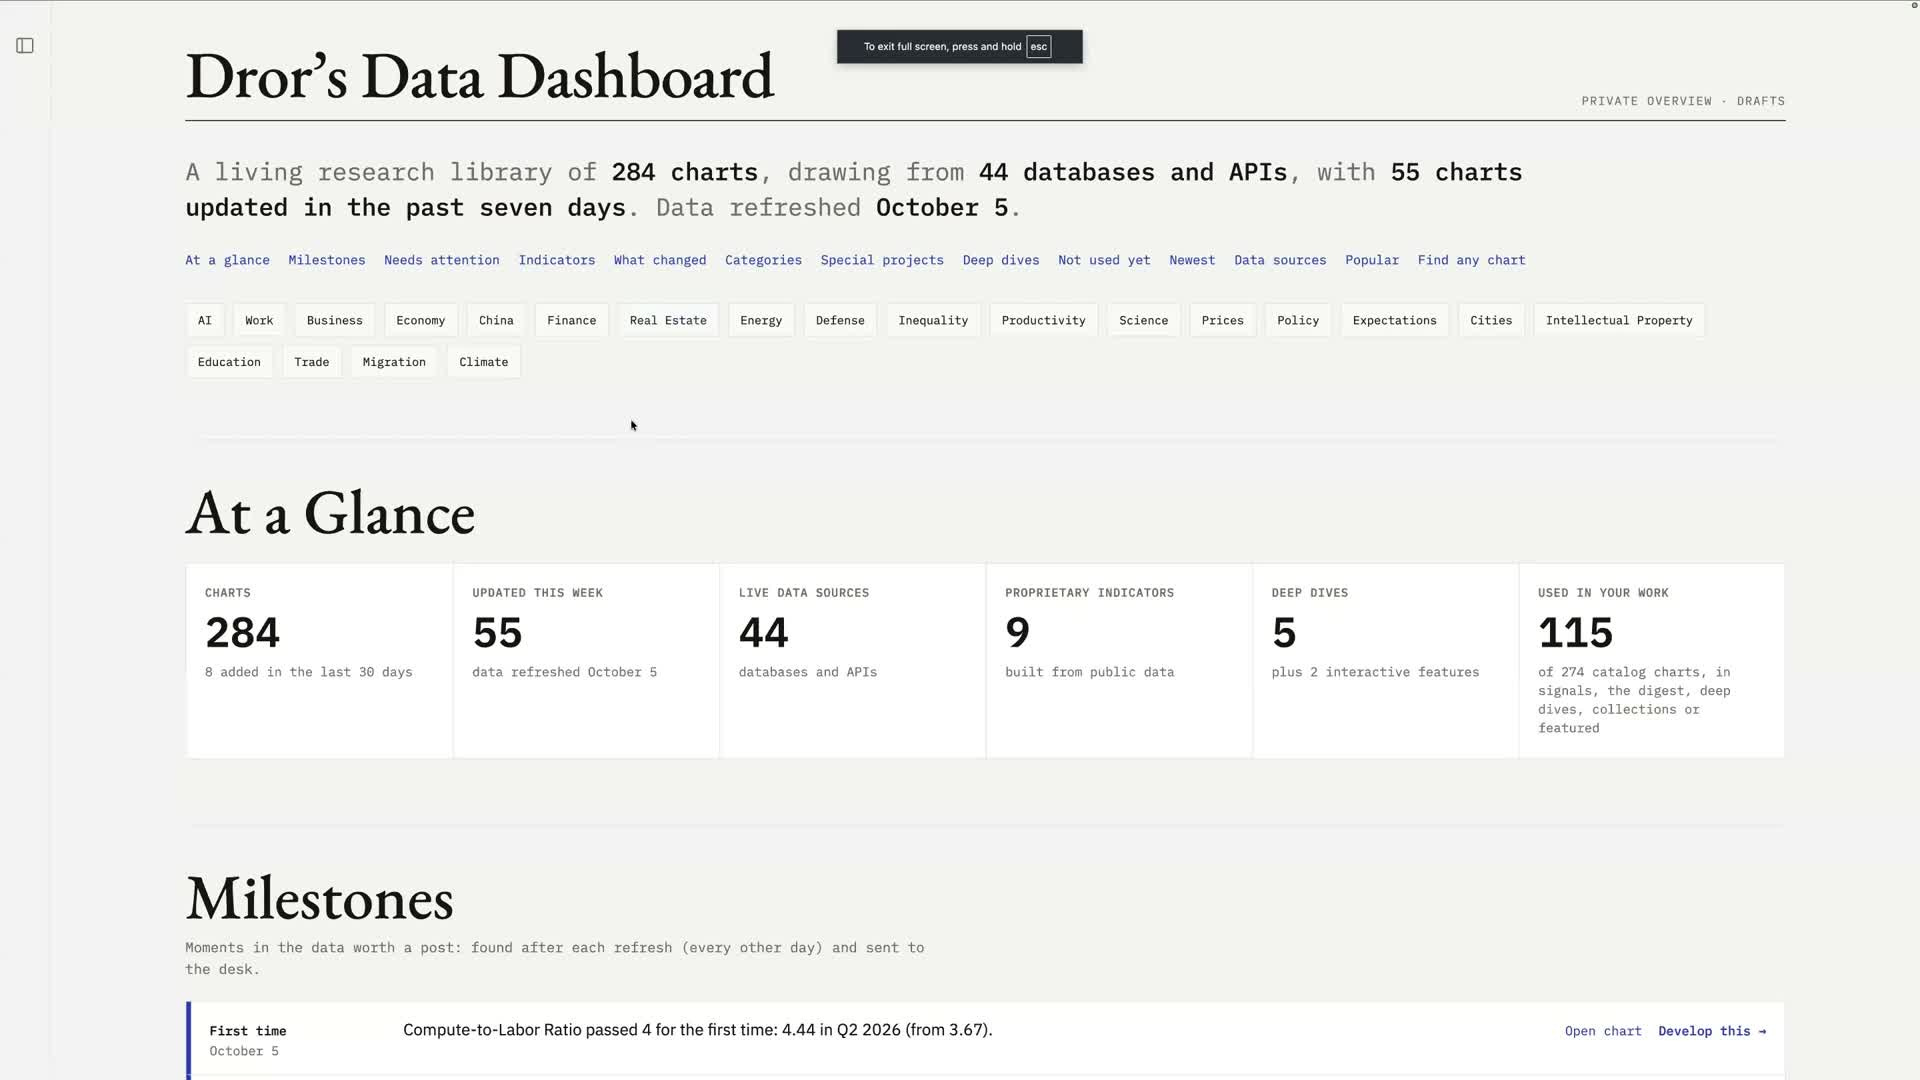
One part is a data dashboard. It collects information from dozens of sources and proposes charts. Dror can inspect what is behind them and decide which ones are worth using. The system helps him find material; the judgement about what it means remains his.
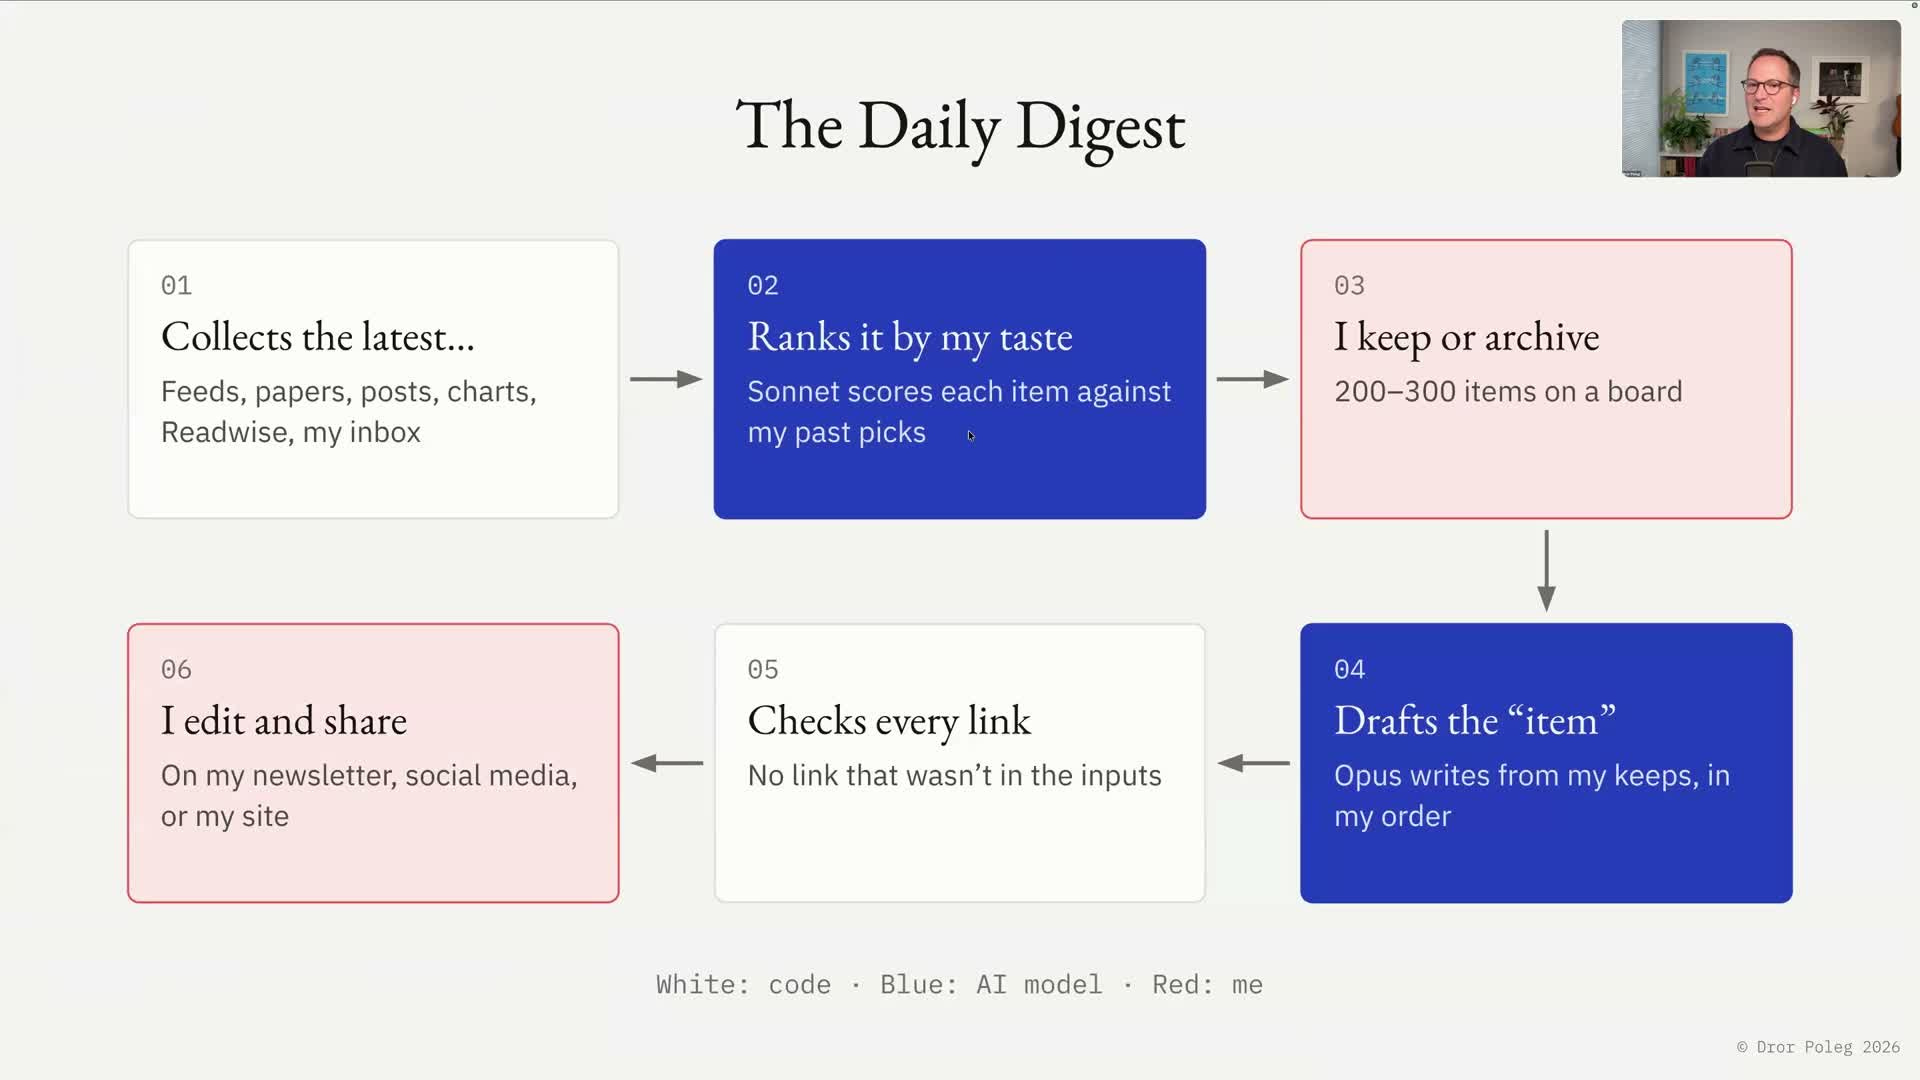
Another part is a daily digest. It gathers feeds, papers, posts, highlights and material from his inbox, then ranks items against his interests. Dror keeps or archives the suggestions. The system can prepare a draft from the items he selects and check that its links come from the supplied material. He edits and decides what to share.
“I decide what to keep and what to archive.”
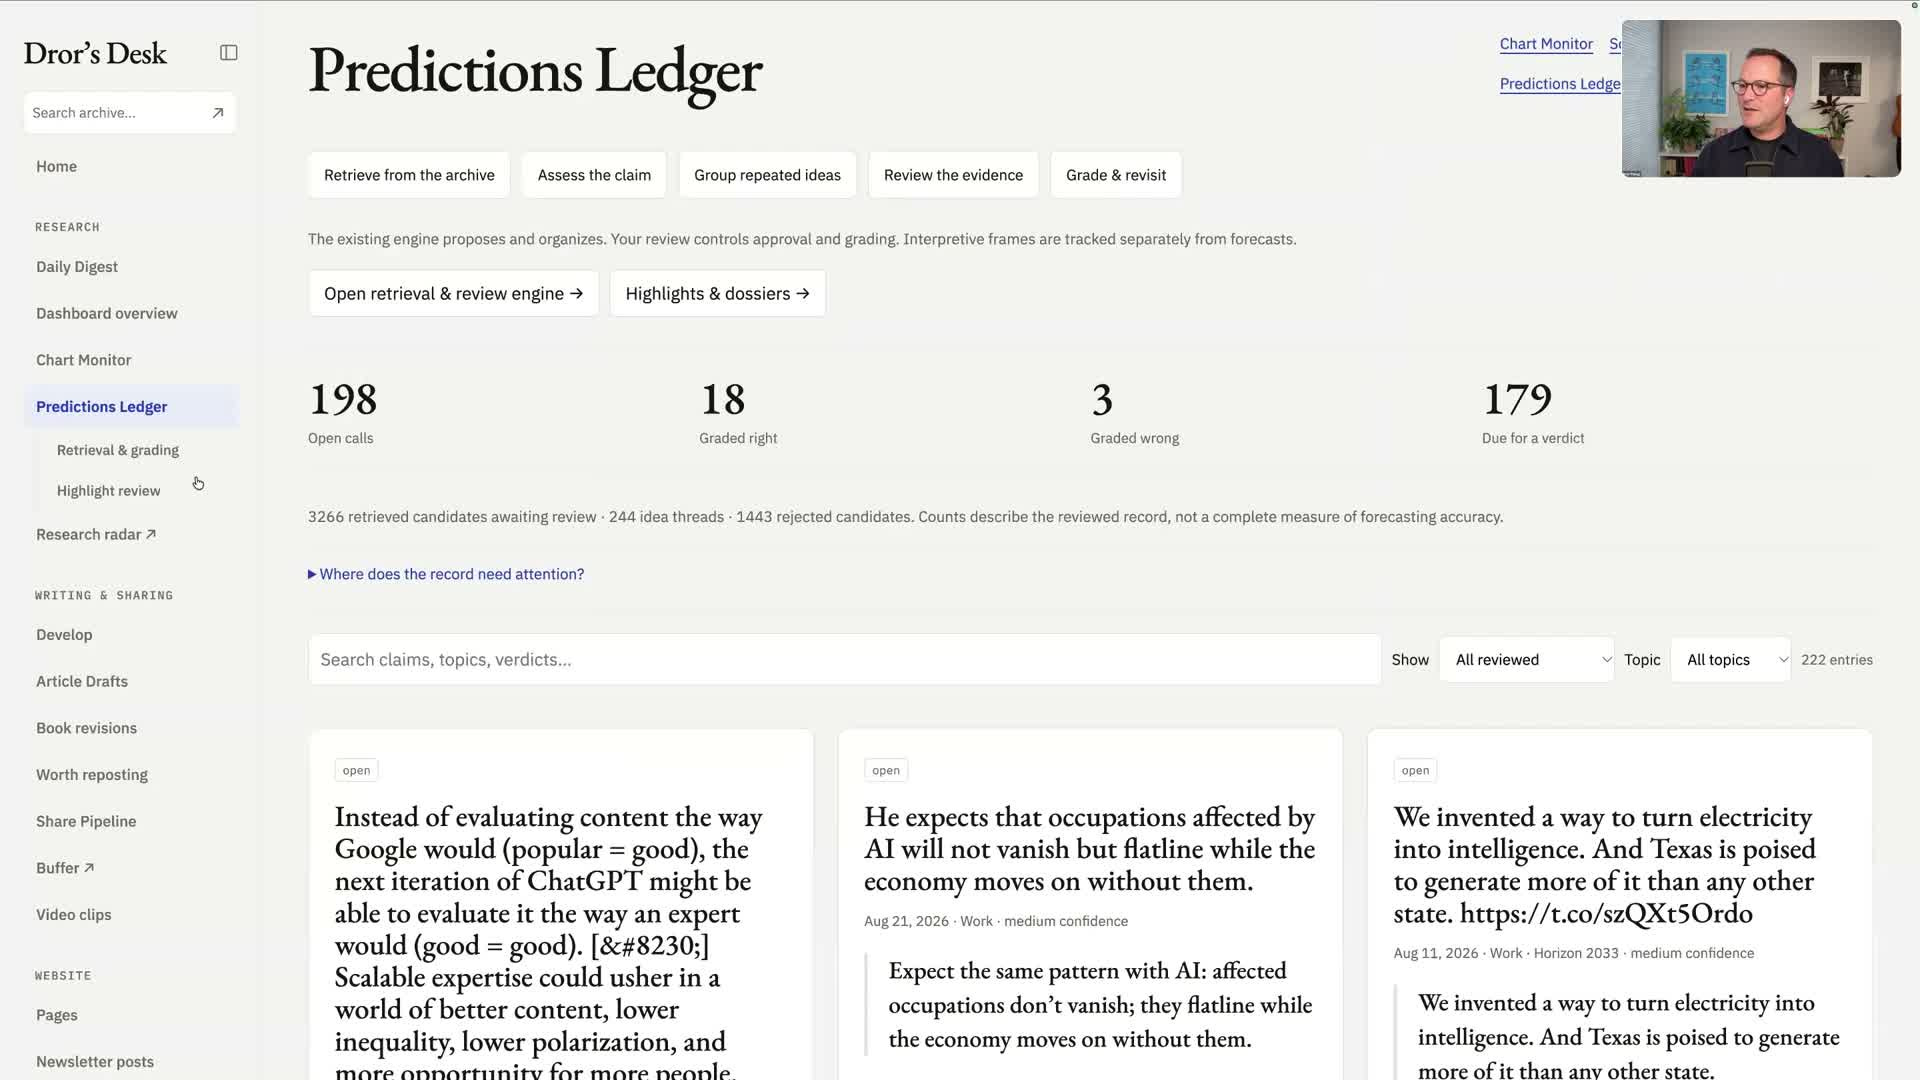
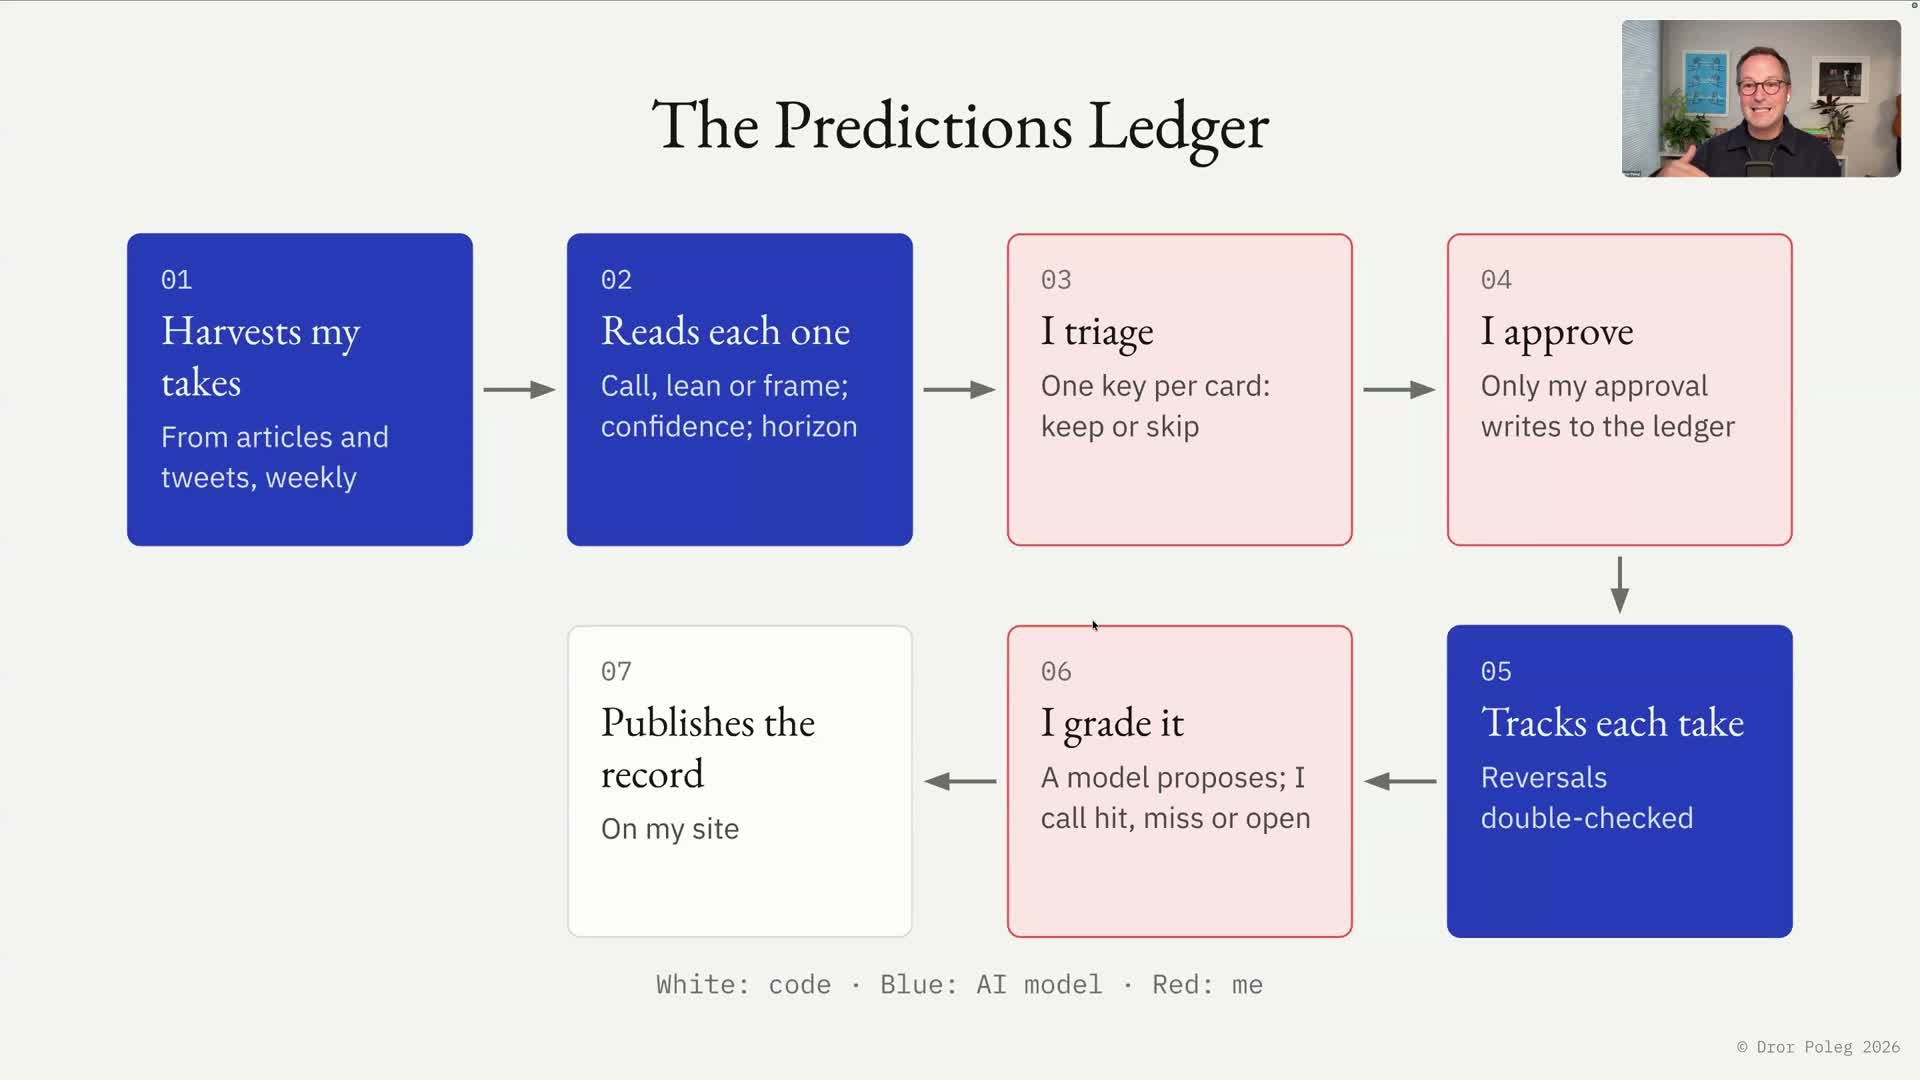
He also built a predictions ledger. It looks through his past writing and talks for claims about the future, proposes entries and helps him track what happened. The ledger keeps a record of what he said before the outcome was known, making it easier to revisit and assess his predictions.
A separate drafting tool helps him research an idea and prepare a brief. Dror said he had not published an article from it as written. The distinction matters: a tool can help gather material and develop an argument without taking over the author’s judgement.
AI is useful in Dror’s workflow, but he does not ask a model to handle every step. He uses ordinary code for checks that can be stated as rules: for example, making sure a link came from an input rather than being invented. He also described tests and additional checks on claims.
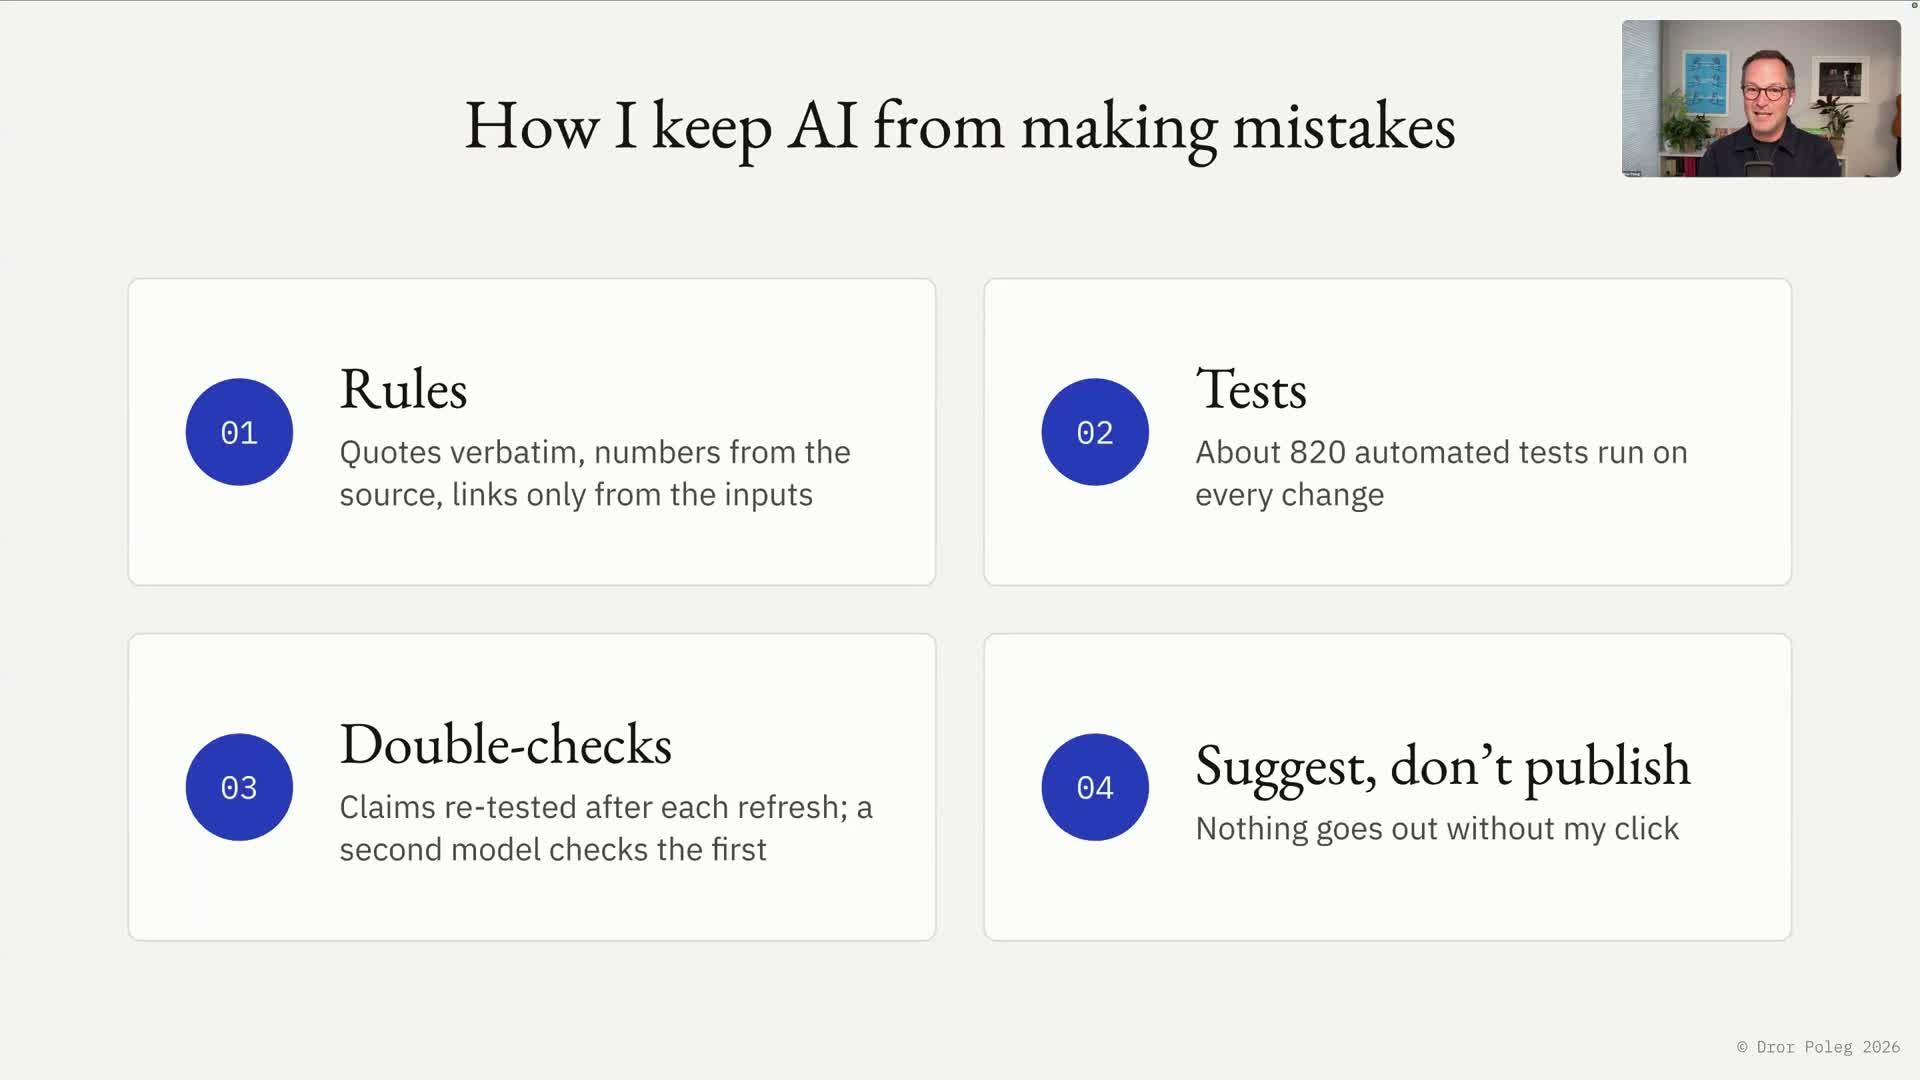
Those checks reduce particular risks; they do not prove that every interpretation is right. Someone still needs to judge whether a source is reliable, whether a chart supports the conclusion and whether the result is worth publishing. In Dror’s system, nothing goes out without his decision.
This is a useful way to think about AI in any organisation. Start with the work and decide what each part requires. A model can help with a task that calls for interpretation. A conventional programme can enforce a rule. A person can make the decision that needs context, responsibility or taste.
Dror’s talk connected his research with his own practice. He studies the consequences of AI while building with it. Working on the system gives him direct experience of what the tools can do, where they fail and how much direction and checking they need.
“For me, the main value here was in the building itself.”
That experience does not settle the bigger economic questions. It does offer a way to ask better ones. Instead of treating AI as a single capability that either replaces a job or leaves it untouched, we can look at the work: what can be delegated, what needs a check and what a person becomes able to do with the time and capacity that remain.
In the discussion, Dror returned to the importance of making those choices deliberately. He uses AI to go deeper into questions that interest him while keeping control of his own thinking and what he publishes.
“I don’t want it to replace me or think for me.”
Dror Poleg is an economic historian and author who writes about how technology changes work, places and markets. His forthcoming book explores the new rules of work, wealth and power. He is also the author of Rethinking Real Estate.
You can explore his research, charts and essays on his website, and subscribe to his newsletter for his writing on AI, work and the economy. He also shares updates on X and LinkedIn.
Hugo and I are teaching Build Your Agentic Software Factory again from 1–11 March 2027.
You’ll set up a factory of your own, give agents work and context, check what they produce and build a working application. We’ll work together in live workshops, with office hours for questions. You can bring your own idea, and you don’t need coding experience to take part.
Connect an existing C# MCP server to Claude Code using stdio or HTTP, then understand configuration scope, tool discovery, authorization, and failure evidence.