Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
163234 stories
·
33 followers

Coding Agents Guess Which Tests to Run. They Should Look It Up.

1 Share

I’ve been updating trunkbaseddevelopment.com for coding agents, with Claude doing much of the typing. One section is now about AI coding agents committing straight to the trunk. That’s what you get if you remove the pull-request requirement and let a diaspora of agents in worktrees, VMs and containers race each other to HEAD. Those agents need fast local builds to win that race. Fast local builds on a big codebase need Test Impact Analysis (TIA). So I asked Claude a simple question: when you’re working in a repo with a too-large test suite, how do you pick which tests to run?

What a coding agent actually does

The answer was candid. Unless the repo provides it, there’s no coverage map and no record of which tests touched which lines last time. There’s no familiarity carried over from yesterday’s session either, unless someone wrote it into a CLAUDE.md or a memory file. What it does instead is reason from the diff:

  1. By naming conventions: Foo.java to FooTest.java, foo.py to test_foo.py, a __tests__ folder next door.
  2. By who uses what changed: grep for the changed symbols and take the callers, importers and subclasses, one or two hops out, and their tests.
  3. By module scope: go test ./pkg/thing/..., mvn -pl module, a single pytest directory.
  4. By graph-aware tooling where it exists: bazel query 'rdeps(...)', nx affected, jest --findRelatedTests. It trusts these most, because they are real dependency data and not its own reading of the code.
  5. By widening when unsure: a change to a base class, config or serialization means running the bigger subset, or everything.

That’s TIA by inference. It’s the same thing a decent senior developer does in their head, and to be fair it’s quite good. Where it goes wrong is predictable: coupling that grep can’t see. Reflection, dependency injection wiring, annotation- and config-driven behaviour, string-keyed lookups, serialized formats, SQL, anything across a process boundary. A coverage-derived map catches those because it records what actually ran. The agent is inferring from text.

Claude also admitted to a behavioural risk. Like a hurried human, an agent under pressure to finish drifts towards running too few tests and declaring victory. The protection is the same as for the hurried human: the full suite runs in CI after the commit lands, and the agent says plainly which subset it ran.

Its own conclusion was the one I’d hoped for: given a real TIA map, it would rather query that than guess. TIA turns test selection from the agent’s judgement into data it can look up. Agents committing at volume may be the strongest argument for TIA yet.

Well of course, the pace of development of agentic coding means these gripes will be out of date soon, but it’s worth captureing the here and now.

Recap: what TIA is

I wrote The Rise of Test Impact Analysis for Martin Fowler’s site, and before that Reducing Test Times by Only Running Impacted Tests here. Briefly: run the suite with coverage instrumentation, record which production source files each test exercises, and store that as a map. For a given change, look up the tests that touch the changed files and run only those before the commit/push. The full suite still runs in CI afterwards. The subset is usually a small fraction of the whole, so the pre-push build gets fast again without anyone deleting tests or skipping the build.

DAG build systems like Bazel, Buck and Nx get much of the same benefit from their dependency graphs. I went through that in Google-style DAG build systems. TIA is the route for everyone using Maven, Gradle, MSBuild, npm and the rest.

The catch: maps are costly

TIA maps aren’t free:

  • Building one is slow: You run the whole suite instrumented, ideally per test, which is slower than a normal run.
  • They go stale, quickly:: Every commit makes the map slightly out of date. Most teams settle for rebuilding it nightly, or every N commits.
  • Costly plumbing: It has to be stored, keyed to commits, and fetched by whoever (or whatever) wants it.
  • Coverage is noisy: The same test can cover slightly different lines from run to run. This is especially true in legacy codebases.

The staleness tradeoff is reasonable, though. A stale map mostly misses brand-new tests and newly introduced coupling, and the full CI run after the commit catches those soon after. A map that is a day old and right 98% of the time beats a guess, and CI is the backstop for the other 2%, unless your CI is using the same TIA map for an elapsed time or “cloud minutes” reduction too.

Where TIA pays, and where it doesn’t

How much TIA saves depends on the shape of the codebase.

Good fit: Business applications are wide and shallow.

Hundreds of features, each test exercising a thin slice through them, and most changes touching one slice. Change the discount rules and you have a few dozen impacted tests out of thousands. The map pays for itself many times over. This is most of the enterprise software in the world, and most of what coding agents are being pointed at.

Bad fit: Programming-language implementations are narrow and deep.

Compilers, interpreters and VMs put nearly every test through the same core: lexer, parser, type checker, code generator, runtime. Change anything in that core and the map says “run everything”. That’s correct, but useless. TIA only helps there for changes at the edges, like a single standard library function or one diagnostic message. The tests are often data rather than code, too: source files in the language, with golden outputs. The useful question is “which language features does this input use?”, not “which test methods hit this line?”.

Language repos have their own techniques instead:

  • Tiered suites: a small, fast smoke/conformance set before the push, with the big corpus left to CI.
  • Tagging tests by language feature: touch closure codegen, run the closure tests. That’s TIA done by hand from domain knowledge rather than from coverage. Coding agents happen to be decent at it.
  • Parallelism and sharding: when selection can’t cut the work, spread it out.

Not yet an observed habit

On trunkbaseddevelopment.com I have a page of observed habits of teams practicing Trunk-Based Development. Running the build locally before the push is one of them, and has been since the late 90’s. TIA isn’t one yet. It’s been possible for over a decade, and the people who adopted it rate it, but I can’t honestly say it’s something you see in most trunk-based teams making business solutions.

It should be. Agents are now doing much of the committing, many of them at once, all chasing the same HEAD. The local build is what keeps the trunk green, and the speed of the local build is what decides who wins the race to commit. An agent that guesses which tests to run is doing what we always did. An agent that can look it up is doing what we always should have.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Semicolon is on the App Store

1 Share

Semicolon is out. It’s an iPhone and iPad app for practicing the parts of programming that interviews still test.

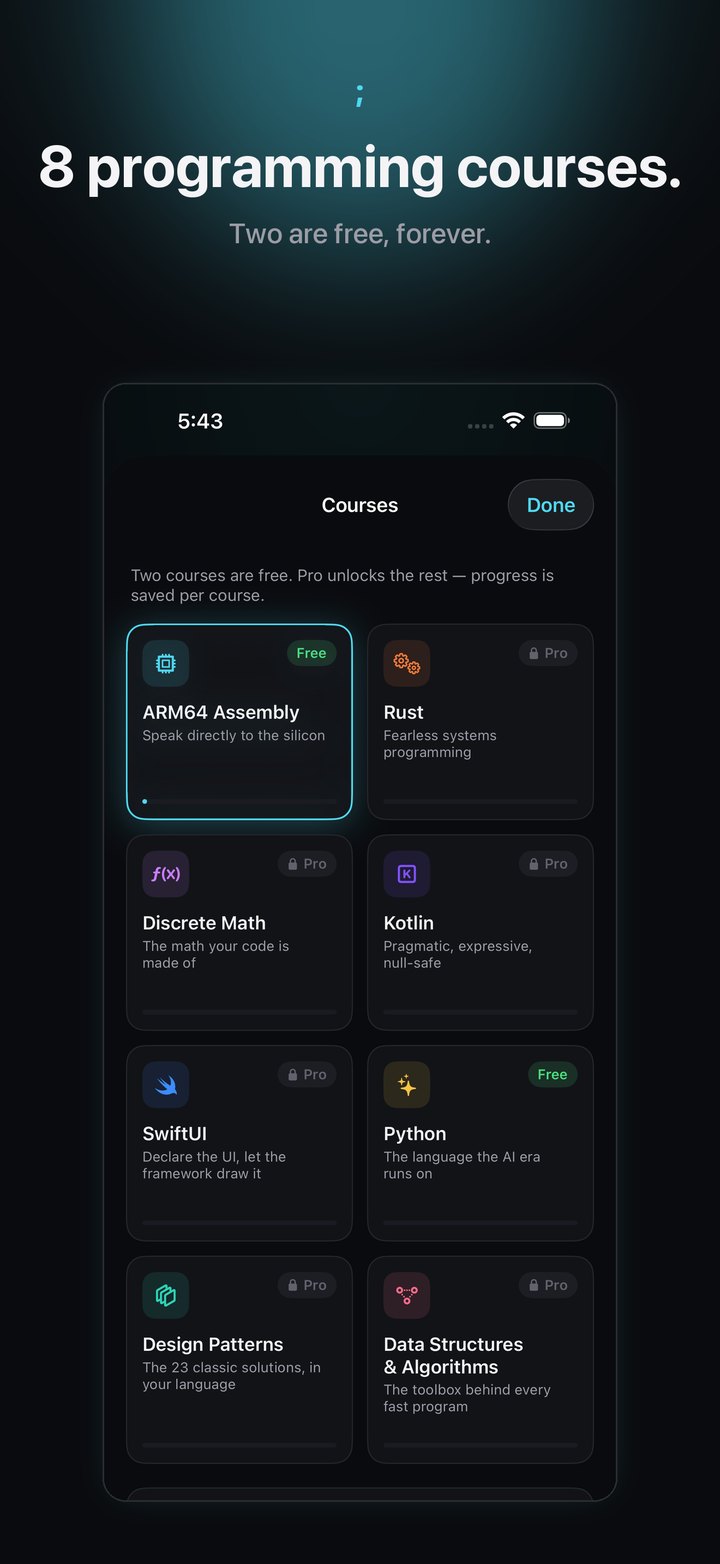
The Semicolon course list on iPhone, showing eight programming courses with ARM64 Assembly and Python free

More and more code gets written with an LLM’s help, and I don’t expect that to change. A company can assume you’ll use a model, but it still needs someone who can read what the model wrote, find the bug in it, and decide whether it’s any good. That takes a solid grasp of the fundamentals, and fundamentals fade quickly once you stop typing them out yourself. Semicolon is a way to keep them sharp.

Figuring out what a seasoned developer should know is a hard problem. I talked to many other senior software engineers to come up with this list of skills. They demonstrate competence, and they’re the fundamentals that help you work with LLMs more effectively.

What’s in it

There are eight courses with 24 sections each: ARM64 assembly, Python, Rust, Kotlin, SwiftUI, discrete math, design patterns, and data structures and algorithms.

I picked them because each one shows you understand something essential.

Assembly and Rust are about what the machine is doing. In assembly you work with registers and memory directly. In Rust you have to understand ownership before the compiler will let you do anything. I chose ARM64 because that’s the architecture in phones and in Apple silicon.

Python is what most people reach for when they work with a model, and it’s a common language for interviews.

Data structures and algorithms, discrete math, and design patterns are the material interviews have always drawn on. They’re also the vocabulary you use to talk to a model about code and to judge what it gives back.

Kotlin and SwiftUI cover the two mobile platforms. I expect local models to end up running on phones over the next few years, so these are the languages you’d use to build for them.

How it works

Every exercise uses real code. Depending on the lesson, you might pick the right answer, fill in a blank, fix a bug, predict what a snippet prints, or write a function. After each answer you get an explanation of why it’s right or wrong. A concept page is one tap away if you get stuck mid-exercise. If you already know a section, you can test out of it with a timed challenge.

Lessons are short, so a lesson a day is realistic.

Price

ARM64 assembly and Python are free. A single purchase of $24.99 adds the other six courses. There’s no subscription, no ads, and no account to create. Your progress stays on your device. There are no hearts or lives and no streaks to protect.

Try it

Semicolon: Learn to Code on the App Store

If you try it and like it, a rating on the App Store helps a lot. If something breaks or a lesson is wrong, the support page is the way to reach me. More about the app is on the Semicolon page.

Read the whole story
alvinashcraft
27 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Event Sourcing: Is our Projection Code fast enough?

1 Share

In this part of my event sourcing series, we take a quick, pun intended, look at how fast the projector we saw in the last post actually runs. The projector gets a list of events as input and projects them into a single value, representing the latest state. This code runs a couple hundred times a second in our system, so it needs to run fast.

The benchmark result

I ran a Benchmark.Net benchmark on my machine, with the following results:

The different cases:

  • CreateOnly: only a single create event exists in the event stream
  • Many: 1 create event, followed by 500 update events in the event stream
  • WithDeletes: a create event, an update event, and a delete event
  • WithOutOfOrderEvents: a create event, 4 update events in incorrect order, and a delete event -> events need sorting
  • WithOverrides: a create event, followed by 3 update events

These cover our typical cases.

Is it fast enough?

To answer this question, we need to look at what else is typically happing around the pure projection:

  • get the events from the database (typically takes 6 to 20ms in our production system)
  • project the events (as see above, typically below a micro second)
  • compute something based on these events (nano seconds to milli seconds)

So the projection times really don’t matter much in the whole picture. Allocations are probably the bigger concern because of garbage collection runs when Gen 1 memory is used (I’m looking forward to .Net 11 and the corresponding F# version to improve this).

Deep dive: the benchmark code

I dump the whole code here. When tinkering with the projection code, I add a second [Benchmark] that calls a duplicate of the original projection code so that I can compare the old and new versions:

namespace Benchmark.CreateProjection

open System
open BenchmarkDotNet.Attributes
open Calitime
open Calitime.TimeRocket
open Calitime.TimeRocket.Projections

open Calitime.TimeRocket.Projections.ValueProjection
open Calitime.Zeit

type EventId = EventId of Guid

type Override = { Value : string }

type EventData =
    | Created
    | Override of Override
    | Delete
    | Rejected of RelatedEventId : EventId

type Event =
    {
        Id : EventId
        Application : Application
        Data : EventData
    }

type Projection = { Value : string }

type Override2 = { Value : string }


[<MemoryDiagnoser>]
type CreateProjectionBenchmark() =

    let projectAction (event : Event) =
        match event.Data with
        | Created -> CreateProjectionAction.Creates { Projection.Value = "created" }
        | Override o -> CreateProjectionAction.Updates (fun _ -> { Projection.Value = o.Value })
        | Delete -> CreateProjectionAction.Deletes
        | Rejected _ -> CreateProjectionAction.Skip

    let configuration =
        {
            ProjectionActionConfiguration = CreateUpdateDelete projectAction
            GetApplication = fun e -> e.Application
        }

    let eventsFSharpCreatesOnly =
        [
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "18.01.2021 08:00"
                Data = Created
            }
        ]

    let eventsFSharpWithOverrides =
        [
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "18.01.2021 08:00"
                Data = Created
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "19.01.2021 08:00"
                Data = Override { Override.Value = "1" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "20.01.2021 08:00"
                Data = Override { Override.Value = "2" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "21.01.2021 08:00"
                Data = Override { Override.Value = "3" }
            }
        ]

    let eventsFSharpWithDeletes =
        [
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "18.01.2021 08:00"
                Data = Created
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "19.01.2021 08:00"
                Data = Override { Override.Value = "1" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "20.01.2021 08:00"
                Data = Delete
            }
        ]

    let eventsFSharpWithOutOfOrderEvents =
        [
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "18.01.2021 08:00"
                Data = Created
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "20.01.2021 08:00"
                Data = Override { Override.Value = "2" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "19.01.2021 08:00"
                Data = Override { Override.Value = "1" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "22.01.2021 08:00"
                Data = Override { Override.Value = "4" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "21.01.2021 08:00"
                Data = Override { Override.Value = "3" }
            }
            {
                Event.Id = Guid.NewGuid () |> EventId
                Application = Application.parse "23.01.2021 08:00"
                Data = Delete
            }
        ]

    let manyEvents =
        [
            {
                Event.Id = Guid.generateNew ()
                Application = Application.parse "18.01.2021 08:00"
                Data = Created
            }
            for i in 1 .. 500 do
                {
                    Event.Id = Guid.generateNew ()
                    Application = Application.parse "18.01.2021 08:00" |> fun (Application time) -> time.PlusTicks i |> Application
                    Data = Override { Value = i |> string } 
                }
        ]


    [<Params("CreateOnly", "WithOverrides", "WithDeletes", "WithOutOfOrderEvents", "Many")>]
    member val Case = "" with get, set

    member val FSharpEvents : Event list = [] with get, set

    [<GlobalSetup>]
    member this.GlobalSetup() =
        this.FSharpEvents <-
            match this.Case with
            | "CreateOnly" -> eventsFSharpCreatesOnly
            | "WithOverrides" -> eventsFSharpWithOverrides
            | "WithDeletes" -> eventsFSharpWithDeletes
            | "WithOutOfOrderEvents" -> eventsFSharpWithOutOfOrderEvents
            | "Many" -> manyEvents
            | _ -> failwith "unknown value for Case"

    [<Benchmark(Baseline = true)>]
    member this.FSharp() =
        let _ = ValueProjector.project configuration (this.FSharpEvents |> EventsForProjection)
        ()
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Memory-efficient JSON in .NET 10 web APIs with PipeReader

1 Share

This blog post is originally published on https://blog.elmah.io/memory-efficient-json-in-net-10-web-apis-with-pipereader/

What happens when your ASP.NET Core API needs to deserialize a JSON payload containing one million objects? The JSON serializer has a lot of work to do, such as building the resulting object graph and managing memory allocation. That can put noticeable pressure on memory and the garbage collector (GC). .NET 10 introduces PipeReader support in System.Text.Json, providing a pipeline-based way to feed JSON data directly into the serializer. It provides an alternative to the traditional stream-based processing.

Memory-efficient web APIs using .NET 10's zero-copy JSON improvements

In this article, I will show the differences between the two approaches and test them against execution time, memory allocation, and GC load.

What is zero-copy?

Zero-copy refers to the technique of processing data across memory spaces without making redundant copies in memory. By avoiding duplicate copies, the program drastically reduces CPU overhead, conserves RAM, and eliminates Garbage Collector (GC) pressure, achieving a remarkable boost in performance.

Analyzing .NET 10 web API JSON improvements

As always, I will keep things simple. I am using a minimal API with a JSON dataset, let's begin.

Step 1: Create project

dotnet new webapi -n ZeroCopyJsonDemo -f net10.0
cd ZeroCopyJsonDemo

Step 2: Create models

Reading model

namespace ZeroCopyJsonDemo.Models;

public class TelemetryReading
{
    public DateTime Timestamp { get; set; }

    public double Temperature { get; set; }

    public double Humidity { get; set; }
}

Model for request

public class TelemetryRequest
{
    public string DeviceId { get; set; } = string.Empty;

    public List<TelemetryReading> Readings { get; set; } = [];
}

Step 3: Create a large JSON file

To simulate a large JSON dataset, I am adding an endpoint that does it

app.MapGet("/create-json", () =>
{
    var payload = new TelemetryRequest
    {
        DeviceId = "device-001",
        Readings = Enumerable.Range(1, 1_000_000)
            .Select(i => new TelemetryReading
            {
                Timestamp = DateTime.UtcNow.AddSeconds(i),
                Temperature = 20 + i % 10,
                Humidity = 40 + i % 20
            })
            .ToList()
    };

    var json = JsonSerializer.SerializeToUtf8Bytes(payload);

    File.WriteAllBytes("large.json", json);

    return Results.Ok(new
    {
        SizeMB = Math.Round(json.Length / 1024d / 1024d, 2)
    });
});

It generates 1 million readings and writes them to a JSON file.

Step 4: Write testing methods

static async Task<object> MeasureNormal()
{
    GC.Collect();
    GC.WaitForPendingFinalizers();
    GC.Collect();

    var allocatedBefore = GC.GetTotalAllocatedBytes(true);

    var gen0Before = GC.CollectionCount(0);
    var gen1Before = GC.CollectionCount(1);
    var gen2Before = GC.CollectionCount(2);

    var stopwatch = Stopwatch.StartNew();

    await using var stream = File.OpenRead("large.json");

    var result =
        await JsonSerializer.DeserializeAsync<TelemetryRequest>(stream);

    stopwatch.Stop();

    var allocatedAfter = GC.GetTotalAllocatedBytes(true);

    return new
    {
        ExecutionTimeMs = stopwatch.Elapsed.TotalMilliseconds,

        AllocatedMemoryMB = Math.Round(
            (allocatedAfter - allocatedBefore) / 1024d / 1024d, 2),

        Gen0Collections = GC.CollectionCount(0) - gen0Before,
        Gen1Collections = GC.CollectionCount(1) - gen1Before,
        Gen2Collections = GC.CollectionCount(2) - gen2Before
    };
}

For a fair benchmark, I enforced garbage collection. It will test a normal traditional approach. Then, recorded memory allocation and time with a stopwatch. The line:

await using var stream = File.OpenRead("large.json");

opens the JSON file as a normal .NET Stream. While, the next line deserializes it using System.Text.Json into TelemetryRequest returning as a result.

Finally, I got the total memory allocation, time elapsed and Garbage collector usage by the differences. The

/ 1024d / 1024d

converts bytes to MB.

static async Task<object> MeasurePipeline()
{
    GC.Collect();
    GC.WaitForPendingFinalizers();
    GC.Collect();

    var allocatedBefore = GC.GetTotalAllocatedBytes(true);

    var gen0Before = GC.CollectionCount(0);
    var gen1Before = GC.CollectionCount(1);
    var gen2Before = GC.CollectionCount(2);

    var stopwatch = Stopwatch.StartNew();

    await using var stream = File.OpenRead("large.json");

    var reader = PipeReader.Create(stream);

    var result =
        await JsonSerializer.DeserializeAsync<TelemetryRequest>(reader);

    await reader.CompleteAsync();

    stopwatch.Stop();

    var allocatedAfter = GC.GetTotalAllocatedBytes(true);

    return new
    {
        ExecutionTimeMs = stopwatch.Elapsed.TotalMilliseconds,

        AllocatedMemoryMB = Math.Round(
            (allocatedAfter - allocatedBefore) / 1024d / 1024d, 2),

        Gen0Collections = GC.CollectionCount(0) - gen0Before,
        Gen1Collections = GC.CollectionCount(1) - gen1Before,
        Gen2Collections = GC.CollectionCount(2) - gen2Before
    };
}

Again, enforcing garbage collection so both tests start from the same state. Now instead of giving the Stream directly to JsonSerializer, we give it the PipeReader. Then System.Text.Json's serializer deserializes directly from the PipeReader. One important part is to complete the pipe reader after we are done with.

await reader.CompleteAsync();

Step 5: Create benchmark endpoint

app.MapGet("/benchmark", async () =>
{
    var normal = await MeasureNormal();
    var pipeline = await MeasurePipeline();

    return Results.Ok(new
    {
        Normal = normal,
        Pipeline = pipeline
    });
});

That is a simple, minimal endpoint to run both measures.

Step 6: Run the project

dotnet run -c Release

For benchmarking, I ran it in Release mode.

Step 7: Prepare the JSON file with the endpoint

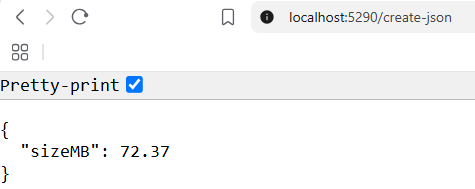
create-json

The endpoint generated alarge.json file of size 72MB which is not ideal to represent a real large file but is considerable for the demo.

Step 8: Navigate to the benchmarking endpoint

Result

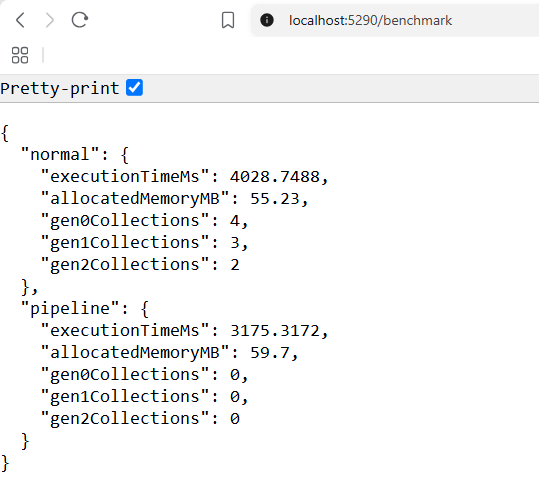
Run /benchmark 5–10 times, ignore the first run because of JIT warm-up, and compare the later results. A single execution is not a reliable performance benchmark.

We're creating a pipeline reader around the file stream. .NET 10 allows System.Text.Json to deserialize JSON directly from a PipeReader. So instead of us doing something like:

var bytes = await ReadEntireRequestBody();

and then passing those bytes to the JSON serializer, we're allowing the serializer to consume the pipeline. So functionally, both endpoints do the same thing. We're not changing the API's behavior. We're changing how the request body is consumed. We utilized the .NET 10 power ofPipeReader that allows System.Text.Json to consume JSON from a pipeline, which can help avoid unnecessary buffering and copying in suitable workloads.

One improvement is in garbage collector usage. During deserialization, .NET has to create a very large object graph that requires allocations. To clean temporary allocations and other working data, GC has to jump in. While the buffering/consumption model of PipeReader can process the input incrementally without creating enough additional GC-triggering pressure during this run. The lower GC pressure resulted in 21% faster results.

Conclusion

We discovered one major .NET 10 improvement in JSON processing. The pipe reader with System.Text.Json changes the game for large dataset parsing. With the example API project, we observed changes in execution time and GC pressure, showing that .NET 10 optimized the job with its zero-copy capabilities. If you're deserializing large JSON payloads or using a high-throughput endpoint, prefer the PipeReader overload. You trade a small amount of extra raw allocation to avoid LOH churn and GC pauses, which is almost always the better trade in a hot request path than its traditional counterpart.

Code: https://github.com/elmahio-blog/ZeroCopyJsonDemo.git


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Apache Ant Deployments with Octopus

1 Share

Apache Ant is a Java-based build tool that has been around for over 20 years. Despite its age, Ant is still actively developed and used in many enterprise deployments. Octopus can be used to deploy Ant applications with a few simple steps. This post will demonstrate how to deploy a sample Ant application using Octopus.

Prerequisites

Download the sample application from this GitHub repository. The releases provide ZIP files that can be uploaded to the Octopus built-in feed:

Built-in feed

Preparing the Ant tooling

Ant was first released in 2000 and predates many popular DevOps tools like Docker by many years. While execution containers are a great solution for exposing Ant and its dependencies to your Octopus workers, we’ll make the assumption here that teams using Ant may not have implemented Docker in their deployment workflows.

Instead, Ant and its dependencies will be exposed to the Octopus workers by extracting portable versions of Ant and Java into the working directory as a step is executed.

Start by downloading a binary distribution of Ant from the Apache Ant website. At the time of writing, the file you will download is called apache-ant-1.10.18-bin.zip.

Octopus requires a strict filename structure for packages uploaded to the built-in feed. The filename must be in the format <package-name>.<version>.<extension>. For example, apache-ant.1.10.18.zip. So rename the file you downloaded to apache-ant.1.10.18.zip before uploading it to the built-in feed.

Ant requires a JDK to run. There are many JDK distributions available, but for this example, we’ll use the Azul Zulu OpenJDK distribution. We’ll assume that the workers are running Windows, so download the ZIP distribution of the JDK. At the time of writing, the file you will download is called zulu27.28.101-ca-jdk27.0.0-win_x64.zip. Rename the file to zulu27.28.101.zip before uploading it to the built-in feed.

You must now have 3 packages in the built-in feed:

Built-in feed with all packages

Running Ant in a deployment step

Ant is run as part of a script step in an Octopus deployment. The script step will extract the Ant and JDK packages into the working directory, set the JAVA_HOME environment variable, and append both Ant and Java to the session Path variable. This allows Ant to be executed on a worker without requiring any installation of Ant or Java on the worker itself:

# 1. Define explicit working directories
# Note that the Ant and JDK packages include their own versioned subfolders, so we need to include those in the path.
# The versioned subfolders are unique to the package version, so if you update the package version, you'll need to update the path here as well.
$workDir   = Get-Location
$antBinDir = "$workDir\apache-ant\apache-ant-1.10.18\bin"
$javaDir   = "$workDir\zulu\zulu27.28.101-ca-jdk27.0.0-win_x64"

# 2. Set JAVA_HOME and explicitly append BOTH Java and Ant to the session Path
$env:JAVA_HOME = $javaDir
$env:Path = "$antBinDir;$javaDir\bin;" + $env:Path

# 3. Verify the binary actually exists where we expect it
if (-not (Test-Path "$antBinDir\ant.bat")) {
    Write-Error "Could not find ant.bat at: $antBinDir"
    Exit 1
}

# 4. Change directory to your app folder
cd antdemo

# 5. Run Ant using the call operator (&) to force PowerShell to resolve the executable path
& ant.bat compile
& ant.bat jar
& ant.bat run

The three packages (the Ant Demo application, the Ant binary distribution, and the JDK) are included as Referenced Dependencies. This ensures the packages are downloaded and extracted into the step’s working directory:

Referenced dependencies

Running the deployment

At this point, you can create a release of the project and deploy it to an environment. The deployment log will show the output of the Ant commands as they are executed:

Ant output

Conclusion

Executing Ant as part of an Octopus deployment is straightforward. By using the built-in feed to provide Ant and its dependencies, you can run Ant on any worker without requiring any installation of Ant or Java on the worker itself. This approach allows teams to deploy Ant applications consistently and repeatably by leveraging Octopus Deploy.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Continuous Delivery Office Hours Ep.11: Haute culture

1 Share

In the previous episode, we discussed modernizing legacy architecture, including the hazards of the rewrite, architectural strategies, and team design considerations.

This episode looks at “haute culture”, or high-performance organizational culture, and its profound impact on software delivery.

Watch the episode

You can watch the episode below, or read on to find some of the key discussion points.

Watch Continuous Delivery Office Hours Ep.11

Posters aren’t culture

Everyone has worked for an organization that attempted to define their identity through poster campaigns, entrance halls decorated with inspirational quotes or word clouds, and mugs adorned with the “five pillars of our culture”.

I worked for an organization that launched the RON campaign. Do it “right”, do it “once”, do it “now”. Of course, none of these happened, as the slogans bore no relation to the reality of the work.

In too many cases, there’s a systematic gap between the organization’s aspirational, publicly stated culture and employees’ lived experience. In fact, when an organization is dysfunctional, the list of values becomes an admission of exactly what is missing: “We value trust, respect, and work-life balance” means you’ll be micromanaged, treated like a child, and made to work long hours.

Meanwhile, the real culture is built from tiny interactions that reinforce what leaders value and what they don’t.

Every tiny interaction reinforces the real culture. The way your boss talks to you, whether they listen to your opinions, and how they respond when you flag a potential problem all set the scene for culture. Even when interactions aren’t aggressive, they can still stifle the crucial component of a healthy culture: information flow.

Here’s an example. You go to your boss and say, “Our test automation is missing a few really crucial areas that could cause us a problem in the future.” Your boss responds by tasking you with filling that gap. While you’re pleased to have permission to fix this, you now have a bunch of more work to juggle, and maybe it would have been better not to say anything.

As soon as people hesitate to share potential problems, you switch from fixing things before they go wrong to firefighting afterward.

Theoretical foundations

High-performing software teams understand the old models of organizational sociology. They understand Douglas McGregor’s principles of human motivation (from The Human Side of Enterprise, though more often encountered in Dan Pink’s book, Drive), and they understand Ron Westrum’s Typology of Organizational Culture.

You can use these models to shift focus to the structural mechanics of workplace culture, and retire the posters, mugs, and mousepads.

McGregor challenged the view of traditional management, which uses rewards and punishment as the tools of motivation. Instead, McGregor asserted that individuals want to do good work and are more satisfied when they deliver quality outcomes, which means they don’t need to be cajoled by management.

The perfect complement to McGregor’s views on motivation is the three categories of culture shared by Ron Westrum:

  • Pathological: A culture with high anxiety, information hoarding, and strict power hierarchies. Messengers are punished or otherwise discouraged from sharing uncomfortable truths.
  • Bureaucratic: These organizations have rigid channels, compartmentalization, and protocols, so information moves slowly along inflexible routes.
  • Generative: The ideal culture has optimal information flow and cross-functional collaboration. Everyone is encouraged to share risks early, without fear of repercussions.

Information flow is the signal of organizational health, with generative environments actively protecting “messengers”; people who flag potential risks and issues. This helps identify problems early and resolve them before they cause damage. Conversely, pathological leaders destroy information flow through intimidation, like an executive engaging in silent staring contests when they are told a date can’t be met unless scope is changed. This coercive dynamic works its way down the hierarchy, becoming the default mode of operation for managers and supervisors.

Suppressing information flow doesn’t change reality. Dates are missed, software ships with known faults, and the fundamentals of physics still apply. The only difference is the realization comes far later, often when it’s too late to prevent damage.

Bad news is crucial operational data, not the result of difficult or negative employees. A leader’s response to this information should be: “Thank you for bringing this up, because sharing this information will help us stop this from becoming a major mistake.”

Fixed scope and arbitrary deadlines

There’s a classic iron triangle in project management that says quality is constrained by three variables: scope, time, and cost, and you can pick any two. This idea presents a neat view of a classic problem in software engineering: the notion that fixing time, cost, and scope doesn’t work.

The reality is a little different from this picture, which leads many project managers to believe you can trade quality for reduced time and cost. The failure demand that results increases future costs and time, so it doesn’t work as a medium- or long-term strategy. Many teams have fallen into the trap of rushing to meet an arbitrary deadline, resulting in a flood of bugs and rework, which increases pressure on the next set of tasks. This cycle is destructive if repeated.

The mismanagement of software tasks, particularly the use of project management approaches designed to cajole teams into unreasonable delivery expectations, inevitably leads to reduced information flow. Project managers share the plan is at risk and are ordered to “make it happen”; developers flag that some work items won’t be completed on time and are told: “well, they have to be.” Eventually, nobody shares these risks, but they happen all the same.

Traditional project management techniques were created to surface the reality of a project, but were used in attempts to force impossible realities. Instead of being cartographers, diligently mapping the territory they explored, project managers believed they could draw the map first, then change millions of hectares of land to match what they imagined.

Feedback is oxygen

Our founder, Paul Stovell, said this to me: “Feedback is oxygen.” That’s true when you’re developing software and need to know whether what you’re building helps users achieve their goals. It’s true throughout the process, whether that’s feedback from linters, tests, security scans, or employees who have spotted trouble ahead.

While it’s true that a healthy generative culture is better for workers, it’s also better for the organization. When information flows, everyone gets better results. Even your CFO.

Happy deployments!

Continuous Delivery Office Hours is a series of conversations about software delivery, with Tony Kelly, Bob Walker, and Steve Fenton.

You can find more episodes on YouTube, Apple Podcasts, and Pocket Casts.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories