Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164917 stories
·
33 followers

Available today: Anthropic Claude Fable 5.2 in Microsoft Copilot

1 Share

Claude Fable 5.2, the latest version of Anthropic’s Fable model, is now rolling out in Copilot Cowork and Copilot Studio. It expands the choice of frontier models in Copilot, so your teams can match the model to the work as they hand more complex tasks to AI. 


A model is only as useful as the context it works with. In Copilot, Work IQ grounds Fable 5.2 in your organization’s files, meetings, chats, and business data—within your existing permissions—so responses reflect your actual work rather than the prompt alone. That makes answers more accurate and easier to trust. 

Get started today 

Fable 5.2 is now rolling out to eligible users in Copilot Cowork and Copilot Studio. 

Admins stay in control: they can manage access and set availability for their organization in the Microsoft 365 admin center. Availability may vary by region and organization.  

You can follow the rollout on the AI at Work Roadmap and in the Microsoft 365 Copilot release notes. 

For details on the model itself, read Anthropic’s announcement of Claude Fable 5.2. 

Read the whole story
alvinashcraft
17 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Deploying an AI Application on Azure Container Apps

1 Share

AI applications often start as prototypes running locally on a developer’s machine. A Streamlit application may work perfectly in a development environment, but making it accessible to users introduces a different set of infrastructure and operational considerations.

From an infrastructure engineer’s perspective, the key questions are:

  • How do we package the application?
  • Where do we store and manage container images?
  • How do we securely manage API keys and secrets?
  • How do we expose the application to users?
  • How do we scale it as usage increases?
  • How do we automate deployments and future releases?
  • How do we monitor and troubleshoot the application after deployment?

This article walks through the end-to-end deployment lifecycle of an AI application using Azure Container Apps (ACA), focusing on infrastructure, security, deployment and operational responsibilities rather than application development.

1. Understanding the Architecture

Before starting the deployment, it is important to understand how the different components fit together.

At a high level, the deployment follows this flow:

Application Source Code → Container Image → Azure Container Registry → Azure Container Apps → Azure OpenAI

Additional Azure services provide identity, security, networking and operational capabilities around the application.

High-level architecture

The responsibilities of the major components are:

Azure componentPurpose
Azure Container Registry (ACR)Stores and manages container images
Azure Container Apps EnvironmentProvides the managed environment for container applications
Azure Container AppsHosts and runs the application containers
Microsoft Entra IDProvides identity and authentication
Managed IdentityEnables passwordless access to supported Azure services
Azure Key VaultSecurely stores application secrets
Azure MonitorProvides monitoring and metrics
Log AnalyticsStores and supports analysis of application and platform logs
Azure OpenAIProvides AI model inference capabilities

The overall infrastructure lifecycle can be summarized as:

Package → Build → Registry → Deploy → Secure → Scale → Automate → Monitor

2. Start with a Clear Application Handoff

As an infrastructure engineer, I should not need to redesign the application before deploying it.

The application team should provide a deployment-ready application package with the following information:

  • Application source code
  • Dockerfile
  • Dependency file, such as requirements.txt
  • Application listening port
  • Required environment variables
  • External service endpoints
  • Health-check requirements
  • Expected CPU and memory requirements
  • Authentication and integration requirements

For example, a Streamlit application commonly uses port 8501.

It is important to establish clear ownership between the teams.

Application team responsibilities:

  • Application functionality and business logic
  • Application dependencies
  • Application-level configuration
  • Application testing
  • Application-level troubleshooting

Infrastructure team responsibilities:

  • Container build infrastructure
  • Container registry
  • Azure resource provisioning
  • Identity and access management
  • Secrets management
  • Networking and ingress
  • Application deployment
  • Scaling and monitoring
  • CI/CD infrastructure

This separation prevents an infrastructure deployment activity from unintentionally becoming an application development task.

3. Containerize the Application

Before deploying an application to Azure Container Apps, we need to package it as a container image.

The Dockerfile defines how the application is packaged, including its base image, dependencies, working directory and startup command.

From an infrastructure perspective, the following items should be validated:

  1. Is the expected base image being used?
  2. Are application dependencies installed successfully?
  3. Is the correct application port configured?
  4. Does the application listen on 0.0.0.0 rather than only localhost?
  5. Is the container configured to run as a non-root user wherever possible?
  6. Are sensitive files and credentials excluded from the image?

For example, build and test the container locally:

Build the image:

docker build -t ai-app:v1 .

Run the container:

docker run -p 8501:8501 ai-app:v1

Podman can also be used in environments where Docker is unavailable or not permitted.

For a Streamlit application, ensure that the application startup configuration listens on all interfaces:

streamlit run app.py --server.address=0.0.0.0 --server.port=8501

Before introducing Azure into the troubleshooting process, validate that the container starts and the application is accessible locally.

The objective at this stage is simple:

Can the application run successfully as a container?

If not, resolve the container or application startup issue first. Introducing Azure Container Apps at this point adds another troubleshooting layer.

4. Store the Container Image in Azure Container Registry

Once the container image has been validated, it needs to be stored in a registry that Azure Container Apps can access.

For an Azure-native deployment, Azure Container Registry (ACR) is a suitable option.

The deployment flow now becomes:

Application Code → Build Container → Test Container → Push Image to ACR → Deploy to Azure Container Apps

One convenient option is to build the image directly using ACR.

az acr build \ --registry <ACR_NAME> \ --image ai-app:v1 \ .

This command builds the image from the current directory and pushes it to the specified Azure Container Registry.

For production deployments, avoid relying exclusively on a mutable tag such as latest.

Prefer traceable image versions:

ai-app:v1 ai-app:v2 ai-app:v3

For automated deployments, the image can also be tagged using a source commit ID or build number.

For example:

ai-app:build-1025

The complete image reference will look like:

<ACR_NAME>.azurecr.io/ai-app:v1

This makes it easier to identify which application version is deployed and simplifies rollback and troubleshooting.

Infrastructure consideration: Ensure that Azure Container Apps has the appropriate permissions to pull images from the private registry. Managed identity with the required ACR permissions can be used instead of maintaining registry credentials.

5. Deploy the Application to Azure Container Apps

Once the container image is available in ACR, the next step is deploying it to Azure Container Apps.

Two important concepts need to be understood.

Azure Container Apps Environment

The Container Apps Environment provides the managed hosting boundary for container applications.

It provides shared capabilities such as networking, logging and integration with the underlying managed platform.

Multiple container apps can run within the same environment.

Azure Container App

The Container App represents the actual application deployment.

It contains the configuration required to run the workload, including:

  • Container image and version
  • CPU and memory allocation
  • Environment variables
  • Ingress configuration
  • Target application port
  • Secrets
  • Scaling configuration
  • Health probes

The deployment structure can be visualized as:

For a Streamlit application, the Container Apps target port should match the port on which the application listens inside the container.

At this stage, the infrastructure team owns the hosting configuration while the application code remains within the application team's ownership.

6. Secure Application Secrets

This is one of the most important considerations when deploying AI applications.

AI applications frequently require credentials to access Azure OpenAI, external APIs or other services.

A simple rule should always be followed:

Never store production API keys or credentials inside application source code or container images.

Avoid hardcoded credentials:

API_KEY = "xxxxxxxx"

Production credentials should also not be committed to source repositories through .env files.

There are three important approaches to consider.

Option 1: Managed Identity

Where the target Azure service supports Microsoft Entra authentication, use Managed Identity instead of storing application credentials.

For example, an application can authenticate to supported Azure services using its assigned identity.

Option 2: Azure Key Vault

When an application requires a secret, such as an API key or connection string, store it centrally in Azure Key Vault.

Access should be controlled through Managed Identity and appropriate RBAC permissions.

Option 3: Azure Container Apps Secrets

Azure Container Apps supports application-level secrets that can be referenced by container environment variables or mounted as files.

It can also reference secrets stored in Azure Key Vault using Managed Identity.

A recommended secret-management flow is:

The objective is to minimize the number of long-lived credentials that application and infrastructure teams need to manage.

7. Configure Managed Identity

Managed Identity helps reduce credential-management overhead and eliminates the need to maintain application credentials for supported Azure integrations.

For example, the access pattern can look like this:

Instead of storing a service principal password or application credential, the application uses its assigned identity to authenticate.

For Azure OpenAI, assign the appropriate role, such as Cognitive Services OpenAI User, when using Microsoft Entra authentication.

For Key Vault, assign Key Vault Secrets User when the application identity needs to retrieve secrets.

The exact role depends on the target service and the operations the application needs to perform.

From an infrastructure perspective, the principle is straightforward:

Grant only the permissions required by the application.

This follows the principle of least privilege and reduces unnecessary access across the Azure environment.

8. Configure Ingress and Application Connectivity

Once the application is deployed, users need a way to access it.

Azure Container Apps provides managed ingress capabilities, allowing applications to be exposed through HTTPS without manually managing an application gateway for every basic deployment scenario.

The infrastructure team needs to decide whether the application should be accessible through:

  • External ingress – Accessible through a public application endpoint, subject to configured access controls.
  • Internal ingress – Accessible within the Container Apps Environment and its supported internal networking configuration.

Before enabling ingress, validate the following:

  • Is ingress enabled?
  • Should the application be internal or external?
  • Does the target port match the application listening port?
  • Is HTTPS configured correctly?
  • Does the application require additional authentication?
  • Are network restrictions required?
  • Are outbound connections to dependent services permitted?

A common deployment issue is a healthy container that is not reachable because the application listening port and the Container Apps target port do not match.

For connectivity troubleshooting, validate the path in order:

This helps determine whether the issue is related to ingress, networking, container configuration or the application itself.

9. Plan Scaling Before Production

Getting one container running is only the first step.

The next question is:

What happens when multiple users start accessing the application?

Azure Container Apps supports replica-based scaling using configurable scaling rules, including HTTP traffic and other supported KEDA-based triggers.

Infrastructure teams should consider:

  • Minimum replicas
  • Maximum replicas
  • CPU allocation
  • Memory allocation
  • Scaling triggers
  • Concurrent requests
  • Expected user traffic
  • Application startup time

For an interactive application, maintaining a minimum replica count may be appropriate when avoiding cold-start latency is important.

However, AI applications introduce another important consideration.

The container application is not necessarily the bottleneck.

Azure OpenAI has its own model deployment capacity, quota and throttling considerations.

Therefore:

Increasing Container Apps replicas does not automatically increase Azure OpenAI model capacity.

Scaling decisions should consider two separate layers.

Application capacity:

  • Container Apps replicas
  • CPU and memory
  • Request concurrency
  • Application-level performance

AI model capacity:

  • Azure OpenAI deployment capacity
  • Model quota
  • Token throughput
  • Request throttling
  • Retry and backoff behavior

Load testing should be performed to establish appropriate limits rather than simply configuring a high maximum replica count.

10. Consider Stateful Application Behaviour

Interactive applications may maintain user or session state during execution.

This becomes particularly important when the application scales horizontally.

With a single replica, user interactions are handled by one running application instance.

With multiple replicas, requests may potentially be handled by different instances depending on the ingress and session configuration.

The infrastructure and application teams should establish one important detail:

Is application state stored only inside the container, or is it persisted externally?

If application or session state must survive container restarts, scaling events or deployments, an external persistence mechanism should be evaluated.

Container memory and local container storage should not be treated as durable application storage.

For Streamlit and similar interactive applications, the application team should also validate session handling and WebSocket connectivity under the expected ingress and scaling configuration.

This discussion should happen before increasing the application's replica count.

11. Validate the Manual Deployment Before Automating It

It can be tempting to start immediately with CI/CD pipelines.

However, from an infrastructure perspective, I prefer validating the complete deployment lifecycle manually before introducing automation.

The initial deployment should establish that the following process works:

Once this process is successful, the same steps can be automated through Azure DevOps or GitHub Actions.

The automated deployment lifecycle then becomes:


This approach makes troubleshooting easier because each deployment stage has already been validated independently.

The CI/CD pipeline simply automates a process that is known to work.

12. Authenticate the CI/CD Pipeline Securely

The deployment pipeline also needs access to Azure resources.

Pipeline authentication should receive the same security attention as application authentication.

Where supported, use Workload Identity Federation (OIDC) rather than maintaining long-lived client secrets in pipeline variables.

The authentication flow looks like this:

This avoids creating another permanent credential simply to automate deployment.

Pipeline permissions should also follow least privilege.

The deployment identity should have sufficient permissions to perform the required deployment operations without receiving unnecessary access to unrelated subscriptions or resources.

13. Manage Application Releases Using Revisions

Application deployment does not end with the first successful release.

There will be a version 2, version 3 and eventually another release that may need to be rolled back.

Azure Container Apps provides a revision-based deployment model.

A revision represents a version of the application configuration and container template.

For example:

Depending on the configured revision mode, the application can use single-revision or multiple-revision deployment.

Multiple-revision mode is particularly useful when implementing controlled traffic splitting, blue-green deployments or canary releases.

This allows infrastructure teams to validate a new application version before directing all production traffic to it.

Combined with traceable container image tags, revisions make it easier to answer a common operational question:

Which application version is actually running?

A rollback strategy should also be defined before production deployment.

14. Monitoring and Operational Visibility

A successful infrastructure deployment should not end with:

"The container is running."

Once users start accessing the application, the infrastructure team needs operational visibility.

At a minimum, consider monitoring the following:

Monitoring areaWhat to validate
Container healthReplica readiness and container restarts
Application logsStartup failures and application exceptions
HTTP metricsRequest volume, status codes and response latency
Resource utilizationCPU and memory consumption
ScalingReplica count and scaling activity
ConnectivityAccess to dependent Azure services
Azure OpenAIAuthentication errors, throttling and request failures

Azure Monitor and Log Analytics can provide the operational visibility needed around the deployed workload.

A practical troubleshooting sequence is:

Following this sequence prevents infrastructure, application and downstream-service issues from being mixed together.

For production environments, configure diagnostic settings and appropriate alerts rather than relying only on manual log inspection.

15. Common Deployment Issues and Troubleshooting

Here are some common issues that infrastructure engineers may encounter during an Azure Container Apps deployment.

Issue 1: Container Image Cannot Be Pulled

Possible causes:

  • Incorrect registry configuration
  • Incorrect image name or tag
  • Missing registry permissions
  • Managed Identity misconfiguration
  • Private registry connectivity issues

What to check:

  • Validate the complete image reference.
  • Confirm the image exists in ACR.
  • Check the Container App registry configuration.
  • Verify the required registry pull permissions.

Issue 2: Application Starts and Immediately Restarts

Possible causes:

  • Missing environment variables
  • Incorrect startup command
  • Missing application dependencies
  • Missing secrets
  • Insufficient CPU or memory

What to check:

  • Container console logs
  • Container Apps system logs
  • Application startup configuration
  • Environment variable references
  • Resource allocation

Issue 3: Application Is Deployed but Not Reachable

Possible causes:

  • Incorrect target port
  • Application listening only on localhost
  • Ingress disabled
  • Incorrect internal or external ingress configuration
  • Network restrictions

What to check:

  • Container Apps ingress configuration
  • Application listening port
  • Application binding address
  • Network connectivity
  • HTTPS endpoint

Issue 4: Azure OpenAI Returns Authentication Errors

Possible causes:

  • Managed Identity not enabled
  • Incorrect role assignment
  • Incorrect endpoint configuration
  • Unsupported authentication method
  • Missing application configuration

What to check:

  • Managed Identity assignment
  • Azure RBAC permissions
  • Azure OpenAI endpoint
  • Application authentication configuration

Issue 5: Azure OpenAI Returns HTTP 429 Responses

Do not immediately assume that the Container App needs more replicas.

Investigate:

  • Azure OpenAI deployment capacity
  • Model quota and throughput
  • Request frequency
  • Token consumption
  • Retry and exponential backoff configuration

The important distinction is:

Container scaling and AI model capacity are two different things.

Final Thoughts

Deploying an AI application is about much more than getting a container to start.

From an infrastructure perspective, the complete lifecycle involves packaging, registry management, identity, deployment, security, scaling, automation and monitoring.

Azure Container Apps provides a managed container platform that allows infrastructure teams to focus on these operational responsibilities without having to manage the underlying Kubernetes infrastructure.

For a Streamlit-based AI application, a practical implementation approach is to start small:

Get one container running securely → Configure Managed Identity → Validate secrets and connectivity → Configure ingress → Test scaling → Automate deployment → Implement production monitoring.

This incremental approach keeps application and infrastructure responsibilities clear and makes troubleshooting considerably easier.

The goal is not simply to get an AI application running.

The goal is to make the deployment:

Secure. Repeatable. Observable. Scalable. Production-ready.

Read the whole story
alvinashcraft
24 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Direct Native Interop in Flutter 3.50: Let’s understand it!

1 Share

It’s time to say goodbye to platform channel boilerplate and call native code directly from Dart!

Flutter 3.50 is here, and one feature I’m personally very excited about is direct native interop going stable!

If you have ever written a platform channel, you know the drill. A channel name string in Dart. The same string again in Kotlin. The same again in Swift. And if any one of them doesn’t match, you find out at runtime with a MissingPluginException. We all have been there 😅

With Flutter 3.50, that changes. Let’s understand what it is and how to use it!

What is Direct Native Interop?

Until now, the standard way to talk to Android or iOS from Flutter was platform channels. Your Dart code sends a message, it gets serialized, it reaches the native side, native code does the work, and the reply comes back the same way. Every call is async and pays this cost.

Direct native interop means your Dart code calls Java, Kotlin, or Objective-C APIs directly, using type-safe Dart bindings generated for you.

In simple words, calling a native API becomes just like calling a normal Dart function. No channel names, no MethodCall switch, no Future for something that should be a simple function call.

What’s new in Flutter 3.50?

  • JNIgen (for Java and Kotlin) is now production-ready.
  • FFIgen (for Objective-C) is now production-ready. Swift works too, as long as your Swift code is exposed to Objective-C using @objc.
  • A Pigeon Native Interop (Preview) that generates type-safe bindings on top of both.
  • You can call native code synchronously, and even from background isolates.

PS: This was possible because of the thread merge that started in Flutter 3.29. Dart code now runs on the platform’s main thread on Android and iOS (and later on desktop too), so there is no wall between Dart and native anymore.

How to use it?

Let’s take the classic “show a toast” example.

Earlier, with a platform channel, you had to write Dart:

const channel = MethodChannel('com.example/toast');
Future<void> showToast(String message) async {
await channel.invokeMethod('showToast', {'message': message});
}

And Kotlin in MainActivity:

MethodChannel(
flutterEngine.dartExecutor.binaryMessenger,
"com.example/toast",
).setMethodCallHandler { call, result ->
if (call.method == "showToast") {
val message = call.argument<String>("message")
Toast.makeText(this, message, Toast.LENGTH_LONG).show()
result.success(null)
} else {
result.notImplemented()
}
}

Now, with JNIgen, you just need 3 steps:

Step 1: Add the packages:

flutter pub add jni jni_flutter
flutter pub add dev:jnigen

As of today (10th November 2026), the latest versions are jni 1.1.2, jni_flutter 1.0.4 and jnigen 1.0.1.

Step 2: Create a config file, tool/jnigen.dart:

import 'dart:io';
import 'package:jnigen/jnigen.dart';
void main(List<String> args) async {
final packageRoot = Platform.script.resolve('../');
final generator = JniGenerator(
input: Input(
classes: ['android.widget.Toast', 'java.lang.CharSequence'],
androidSdk: AndroidSdk(
addGradleDeps: true,
androidExample: packageRoot,
),
),
output: Output(
dart: DartOutput(
path: packageRoot.resolve('lib/android_utils.g.dart'),
structure: OutputStructure.singleFile,
),
),
);
await generator.generate();
}

Step 3: Run dart run tool/jnigen.dart and call Android directly from Dart:

import 'package:jni/jni.dart';
import 'package:jni_flutter/jni_flutter.dart';
import 'android_utils.g.dart';
void showToast(String message) {
Toast.makeText$1(
androidApplicationContext,
message.toJString().as(CharSequence.type),
Toast.LENGTH_LONG,
)!.show();
}

That’s it! No Kotlin file, no channel. And notice that it returns void, not Future<void>. It's a direct call!

The $1 suffix is how JNIgen handles Java method overloads, since Dart doesn't have overloading. Always check the generated file to make sure you picked the right one.

On iOS, it’s the same idea with FFIgen. You generate bindings from the Objective-C headers (for example, Apple’s EventKit) and use them like this:

final store = EKEventStore();
final start = NSDate.date();
final end = NSDate.dateWithTimeIntervalSinceNow(30.0 * 24 * 60 * 60);
final predicate = store.predicateForEventsWithStartDate(
start,
endDate: end,
);
final events = store.eventsMatchingPredicate(predicate);

You can find complete examples in the official Flutter native interop demos (android_toast_demo and ios_calendar_demo).

Already using Pigeon?

You can try the new Native Interop (Preview) by turning it on in your Pigeon file. Pigeon then runs JNIgen and FFIgen for you:

@ConfigurePigeon(
PigeonOptions(
kotlinOptions: KotlinOptions(useJni: true),
swiftOptions: SwiftOptions(useFfi: true, ffiModuleName: 'Runner'),
),
)

Keep in mind that it is still a preview: it supports Android, iOS and macOS only (no Windows or Linux), and @TaskQueue is not supported. Check out the Pigeon Native Interop guide for the full setup.

Advantages of Direct Native Interop

  • Type safety: No more string-based method names. If something is wrong, the compiler tells you.
  • Synchronous calls: Get results directly, without await.
  • Better performance: No serialization and no thread hops. Great for frequent calls or large data.
  • Less code: You can use Android SDK or Apple framework APIs without writing a native wrapper.

Things to keep in mind

Direct interop takes you closer to native, so there are a few rules to follow:

  • Memory: On Android, every Java object you hold in Dart uses a JNI global reference, and there is a limit of around 50,000. Call .release() in dispose() for long-lived objects. On iOS, use WeakReference to avoid reference cycles.
  • Threads: Synchronous doesn’t mean free. Slow calls on the main thread will still drop frames, so move heavy work to a background isolate. Also, UI-related Objective-C calls must run on the main thread.
  • Type checks: Dart’s is and as don't check the native runtime type. Use .isA(Foo.type) and .as(Foo.type) instead.
  • R8 / ProGuard: Release builds can strip classes that are only used from Dart. Add @Keep to your own Kotlin classes and methods.
  • Build first: JNIgen needs your Android app to be built at least once before generating bindings.
  • Swift: FFIgen talks to Swift through Objective-C, so classes need @objc and should extend NSObject. Pure Swift interop (swiftgen) is still experimental.

Should I migrate my platform channels now?

No need to rush! If your platform channel code works well and is tested, it’s not suddenly bad code. Please don’t feel pressured to rewrite it.

Use direct interop for new native integrations, or for calls where you really need sync results or better performance. If you maintain a plugin, a planned migration in a future major version is totally fine. Your users will thank you for stability.

Also, a big thank you to the Dart and Flutter teams and to everyone in the community who tested this early and reported issues. That’s the reason it’s stable today 💙

Hope you enjoyed this article!

Doubts? Feel free to drop a message @AbhishekDoshi26
Checkout abhishekdoshi.dev for more info 💙

Don’t stop, until you are breathing!💙
- Abhishek Doshi

Direct Native Interop in Flutter 3.50: Let’s understand it! 💙 was originally published in Flutter Community on Medium, where people are continuing the conversation by highlighting and responding to this story.

Read the whole story
alvinashcraft
41 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Container Strategy: Running Containers and Actually Governing Them Are Two Different Things

1 Share
I'd bet just about everyone has at least one containerized workload running in production by now. Plenty of organizations have several flavors of Kubernetes spread across a handful of clusters, too. If you're not there yet, you probably will be soon, because AI is helping developers and platform engineers build + ship software faster than any of us expected. What I keep running into when I talk with clients (and work alongside them) is that the end-to-end container strategy is where things...

Read the whole story
alvinashcraft
54 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Compiling Local LLMs in WSL 2? This 2-Line Config Tweak Cuts CUDA Build Times in Half

1 Share

If you have ever compiled a local large language model runtime like llama.cpp, vLLM, or custom CUDA kernels inside Windows Subsystem for Linux (WSL 2), you have probably noticed something frustrating. Even on a multi-core processor paired with a fast NVMe SSD and an NVIDIA RTX graphics card, parallel CMake and Ninja builds inside WSL often take twice as long as they do on a native Ubuntu installation.


The culprit is not virtualization overhead from Hyper-V, but two conservative default settings buried inside WSL's per-distribution /etc/wsl.conf and global %USERPROFILE%\.wslconfig files. Here is how disabling automatic Windows path injection and switching WSL's memory reclamation mode from aggressive cache dropping to gradual reclaim cuts parallel C++ and CUDA compile times in half.


WSL 2 .wslconfig and wsl.conf Tweaks to Double Local LLM and CUDA Compile Speeds
Accelerating local AI compilation in Windows 11 WSL 2: Eliminating 9P Windows PATH lookups in /etc/wsl.conf and tuning RAM and VFS cache reclamation in .wslconfig.


Table of Contents


  • Kill 9P $PATH Traversal Overhead: Setting appendWindowsPath=false inside /etc/wsl.conf stops CMake, Ninja, and nvcc from scanning dozens of slow /mnt/c/ Windows directories on every compiler fork.
  • Preserve Warm VFS Build Caches: Switching autoMemoryReclaim from its aggressive dropCache default to gradual in %USERPROFILE%\.wslconfig prevents WSL from wiping cached C++ headers and ccache objects between builds.
  • Uncap the 50% RAM Ceiling Safely: Allocating 70% to 75% of host RAM in .wslconfig stops parallel CUDA cicc and ptxas threads from hitting swap.vhdx disk thrashing or OOM crashes.
  • Stay on Native ext4.vhdx Storage: Compiling inside ~/projects on the Linux virtual disk instead of /mnt/c/ avoids Plan 9 over Hyper-V socket penalties while keeping full CUDA GPU passthrough.
  • Respect the 8-Second VM Restart Rule: Always run wsl --shutdown and wait 8 seconds so the Hyper-V utility VM reloads both configuration files cleanly.


Why Stock WSL Silently Chokes Parallel CUDA and C++ Builds

When you compile custom inference engines like llama.cpp (with GGML_CUDA=ON), vLLM, or FlashAttention to power local Retrieval-Augmented Generation (RAG) pipelines or local Model Context Protocol (MCP) servers, the build system spawns thousands of short-lived compiler, assembler, and linker processes. Even on a high-end PC configured with our modern Windows 11 developer workstation guide, default WSL 2 settings sabotage that workload in two invisible ways.


First, WSL automatically injects your entire Windows host PATH into the Linux environment, forcing every subprocess lookup to cross the virtual machine boundary over a slow Plan 9 (9P) file server. Second, WSL caps your Linux virtual machine at just 50% of your physical RAM while defaulting its memory reclamation engine to dropCache, which ruthlessly purges cached header files the moment a compilation step pauses.


The Per-Distro Interop Tweak That Stops Plan Nine Path Stalls

Run echo $PATH inside a stock Ubuntu WSL terminal and you will see dozens of /mnt/c/Program Files/... entries appended at the tail end. Whenever CMake, Ninja, pkg-config, or nvcc checks for helper binaries or compiler wrappers during a multi-threaded build, Linux stats each directory in $PATH—crossing the Hyper-V socket into Windows NTFS via DrvFs (Plan 9 protocol) thousands of times per minute.


As documented in the official Microsoft Learn WSL configuration guide, you can eliminate this bottleneck per distribution by editing /etc/wsl.conf inside your Linux shell (`sudo nano /etc/wsl.conf`) and adding these exact sections:

  • [boot] with systemd=true to keep background services like Ollama managed cleanly.
  • [interop] with enabled=true and appendWindowsPath=false to strip slow /mnt/c/ folders from $PATH while still allowing you to invoke explicit Windows binaries by full path when needed.
  • [automount] with enabled=true, options="metadata,umask=22,fmask=11", and ldconfig=true so Windows-supplied NVIDIA CUDA libraries remain linked.
  • [gpu] with enabled=true and appendLibPath=true to preserve /usr/lib/wsl/lib/libcuda.so.1 GPU acceleration, as verified in the WSL-UI technical troubleshooting reference.


If you still want to launch Visual Studio Code or Windows Explorer directly from your Ubuntu prompt after disabling automatic Windows path injection, simply create a targeted symbolic link inside /usr/local/bin for those two binaries alone. That way, you keep instant desktop integration without polluting compiler lookup tables with thirty slow Windows system directories.


The Global WSLConfig Tweak for Gradual Memory Reclaim and RAM Headroom

Next, fix the virtual machine hardware ceiling by creating or editing %USERPROFILE%\.wslconfig on your Windows host (`notepad $env:USERPROFILE\.wslconfig` in PowerShell). When you compile CUDA device code for multiple NVIDIA Compute Capability architectures, each parallel cicc and ptxas compiler thread consumes 1.5 GB to 3 GB of RAM; hitting the default 50% RAM cap on a 32 GB PC forces Linux to thrash against `%Temp%\swap.vhdx` on disk.


Even worse, Microsoft's current default for [experimental] autoMemoryReclaim is dropCache, which immediately dumps the Linux Virtual File System (VFS) page cache whenever CPU activity dips—destroying incremental build speeds when switching between your terminal and Visual Studio 2026 v18.11. Add these parameters to %USERPROFILE%\.wslconfig (adjusting memory=24GB on a 32 GB PC or 48GB on a 64 GB PC):

  • Under [wsl2]: set memory=24GB, processors=16 (matching your logical cores), swap=8GB, networkingMode=mirrored, and dnsTunneling=true.
  • Under [experimental]: set autoMemoryReclaim=gradual and sparseVhd=true so WSL reclaims idle memory slowly in the background without flushing hot C++ header and ccache pages from RAM.


Why You Must Keep LLM Repositories on Native Ext Four Storage

Configuration files alone cannot save a build if your source code sits inside /mnt/c/Users/.... On systems running the latest Windows 11 26H2 update, WSL 2 runs a real Linux 6.18 LTS kernel backed by an ext4.vhdx virtual disk, which delivers near-native NVMe throughput only when files reside inside the Linux root filesystem.


Always clone your repositories (`git clone https://github.com/ggerganov/llama.cpp`) and store your GGUF weights inside ~/projects or ~/models rather than `/mnt/c/`. Also remember the golden CUDA rule for WSL 2: never install the Linux NVIDIA display driver inside Ubuntu, or you will overwrite the para-virtualized Windows stub at `/usr/lib/wsl/lib/libcuda.so.1`—install only the cuda-toolkit package inside Linux.


Comparing Default WSL Against Tuned WSL for Local AI Compilation

STOCK WSL 2 DEFAULTS (BOTTLENECKED)

Default Unconfigured WSL 2 Environment

  • Windows PATH Injection: appendWindowsPath=true forces CMake and Ninja to scan dozens of slow 9P /mnt/c/ paths.
  • VM Memory Ceiling: Capped at 50% of host RAM (16 GB on a 32 GB PC), causing nvcc swap thrashing on -j 16 builds.
  • VFS Cache Behavior: autoMemoryReclaim=dropCache flushes cached C++ headers and object files whenever the VM idles.
  • Typical llama.cpp CUDA Build: ~5 minutes 45 seconds (clean build) and sluggish incremental re-links.
TUNED .WSLCONFIG + WSL.CONF (2X FASTER)

Optimized Local LLM Workstation Profile

  • Pure Linux $PATH: appendWindowsPath=false in /etc/wsl.conf keeps all compiler lookups on native ext4.
  • Uncapped RAM Allocation: memory=24GB (on 32 GB host) allows 12 to 16 parallel nvcc threads with zero swap I/O.
  • Warm VFS Page Cache: autoMemoryReclaim=gradual retains header trees and ccache objects in RAM across builds.
  • Typical llama.cpp CUDA Build: ~2 minutes 15 seconds (clean build) and near-instant incremental rebuilds.


Applying the Eight-Second Shutdown Rule and Verifying Your Build

After saving both `/etc/wsl.conf` and `%USERPROFILE%\.wslconfig`, simply closing your Ubuntu tab will not apply the changes—Microsoft enforces an 8-second rule before a background WSL utility VM terminates. Open Windows PowerShell, run wsl --shutdown, wait a full eight seconds, and verify that wsl --list --running reports no active distributions before relaunching your terminal.


Once back inside Ubuntu, run free -h to confirm your new 24 GB RAM ceiling and echo $PATH to verify that `/mnt/c/` paths are gone while `/usr/lib/wsl/lib` remains active. Then compile llama.cpp on your native ext4 drive using cmake -B build -DGGML_CUDA=ON && cmake --build build --config Release -j 12 to experience the full two-fold speed jump firsthand.


Frequently Asked Questions (FAQ)

  1. What is the difference between .wslconfig and /etc/wsl.conf in Windows Subsystem for Linux?
    The .wslconfig file resides in your Windows user profile folder (%USERPROFILE%\.wslconfig) and configures global virtual machine settings across all WSL 2 distributions, such as RAM limits, CPU cores, swap size, and experimental memory reclamation. By contrast, /etc/wsl.conf lives inside each individual Linux distribution and controls per-distro behavior like Windows $PATH injection, DrvFs automount flags, and systemd initialization.
  2.  

  3. Why does setting appendWindowsPath=false in /etc/wsl.conf speed up local LLM compilation?
    By default, WSL appends dozens of Windows host directories mounted under /mnt/c/ into your Linux $PATH variable. When CMake, Ninja, Make, or nvcc spawns thousands of compiler subprocesses during a llama.cpp or vLLM build, Linux traverses those slow Plan 9 (9P) network-mounted Windows folders on every lookup. Disabling appendWindowsPath restricts $PATH searches to native ext4 directories, cutting subprocess spawn latency dramatically.
  4.  

  5. If I set appendWindowsPath=false, does NVIDIA CUDA GPU passthrough still work inside WSL 2?
    Yes. NVIDIA GPU para-virtualization in WSL 2 is controlled by the [gpu] enabled=true and [automount] ldconfig=true settings, which inject the Windows host driver stub into /usr/lib/wsl/lib/libcuda.so.1. Setting appendWindowsPath=false under [interop] does not affect CUDA libraries or GPU acceleration.
  6.  

  7. Can I still run Windows executables like explorer.exe or code from WSL if appendWindowsPath is false?
    Yes, as long as you keep enabled=true under the [interop] section in /etc/wsl.conf. You can either invoke Windows binaries using their full path (such as /mnt/c/Windows/explorer.exe) or symlink only the specific Windows tools you need—like VS Code—into /usr/local/bin.
  8.  

  9. Why does WSL 2 default to 50% of system RAM, and how does that hurt CUDA and C++ builds?
    Microsoft sets the default WSL 2 VM memory ceiling to 50% of host RAM to prevent background Linux containers from starving Windows desktop apps. However, compiling CUDA kernels with nvcc (cicc and ptxas) using parallel threads (-j) easily consumes 1.5 GB to 3 GB of RAM per thread. Hitting the 50% cap forces the WSL VM into heavy swap.vhdx disk thrashing or triggers the Linux out-of-memory (OOM) killer.
  10.  

  11. Why should I set autoMemoryReclaim=gradual instead of the default dropCache in .wslconfig?
    In recent WSL 2 releases, Microsoft set [experimental] autoMemoryReclaim to dropCache by default, which immediately flushes the Linux VFS page cache whenever the VM idles. Flushing the page cache wipes out cached C++ header trees and ccache objects between builds. Switching to autoMemoryReclaim=gradual reclaims idle RAM smoothly over time while keeping active build caches warm.
  12.  

  13. Why is compiling a repository inside /mnt/c/ so much slower than compiling inside ~/projects?
    Files under /mnt/c/ live on the Windows NTFS drive and are accessed across the virtual machine boundary using the Plan 9 (9P) protocol over Hyper-V sockets. Native Linux directories like ~/projects reside inside an ext4 virtual hard disk (ext4.vhdx) with direct block I/O, running metadata-heavy Git and CMake operations up to 5x to 10x faster.
  14.  

  15. What is Microsoft's 8-second rule when applying changes to .wslconfig or /etc/wsl.conf?
    Simply closing your Linux terminal window does not immediately apply configuration changes because the background WSL utility VM stays alive for at least 8 seconds after the last shell closes. To apply edits immediately, run wsl --shutdown in PowerShell, wait 8 seconds, and verify with wsl --list --running before reopening your terminal.
  16.  

  17. Should I ever install the native Linux NVIDIA graphics driver inside a WSL 2 Ubuntu distribution?
    No. You must never install a native Linux NVIDIA display driver inside WSL 2 because it overwrites the para-virtualized /usr/lib/wsl/lib/libcuda.so.1 stub provided by your Windows host driver. Install the latest NVIDIA Game Ready or Studio driver on Windows, and install only the CUDA Toolkit (cuda-toolkit) package inside WSL.
  18.  

  19. How many threads should I pass to CMake or Ninja when compiling llama.cpp in a tuned WSL 2 VM?
    Once you raise your .wslconfig memory ceiling to 75% of host RAM, divide your allocated WSL RAM (in GB) by 2 to determine the safe maximum parallel thread count for nvcc CUDA builds—for example, use cmake --build build --config Release -j 12 on a 24 GB WSL allocation so linker threads never swap.


End Note

You do not need to dual-boot Ubuntu on a separate NVMe partition just to compile local LLMs and custom CUDA kernels at full hardware speed. By stripping Windows 9P directories out of your Linux $PATH in /etc/wsl.conf, switching .wslconfig from dropCache to gradual memory reclamation, and giving your WSL 2 VM enough RAM headroom to link in parallel without swapping, your Windows 11 workstation matches bare-metal Linux build times. Have you tuned your .wslconfig for local AI development yet? Share your compile times and hardware specs in the comments below!


Verifying WSL 2 Memory Ceiling, Native ext4 Build Speed, and NVIDIA CUDA Passthrough
WSL 2 Local AI Optimization Checklist: Combining /etc/wsl.conf interop isolation, .wslconfig gradual memory reclamation, and native ext4 storage for 2x faster CUDA compilation.


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Uno Platform 7.0: 2x faster, 5x smaller, built for the agentic era

1 Share
&&

Uno Platform 7.0 is out. By commits, files, and lines changed, it is the largest release we have shipped.

AI agents can write code faster than ever. What turns that code into a great application is the foundation underneath it: how fast it runs, how small it ships, how many platforms it reaches, and how faithfully it behaves the way you and your agents expect. Uno Platform 7.0 strengthens every one of those layers.

Alongside it, we are releasing Uno Platform Studio 3.3, a workbench where developers and AI agents create applications together, built on that same foundation.

What’s new in Uno Platform 7.0:

Faster, smaller, less overhead

Compared with 6.7, Uno Platform 7.0 is about 2x faster and 5x smaller, with some core operations up to 38x faster, without changing how you work.

One engine, two backends

Every target renders through one pluggable pipeline. SkiaSharp 4 is the default, and a new WebGPU backend is available as an opt-in.

.NET MAUI, both ways

Third-party .NET MAUI controls now run on every Uno Platform target, including the web and Linux. .NET MAUI developers can bring existing apps to the browser and Linux through our .NET MAUI handlers.

UI entirely in C#

Microsoft.UI.Reactor, Microsoft’s declarative, state-driven framework, now runs on every Uno Platform target, with no XAML.

Apple TV

Extend an existing .NET application to Apple TV without rebuilding the UI or keeping a separate codebase.

.NET 11 from day one

Uno Platform 7.0 supports .NET 11 alongside .NET 10, shipped in step with Microsoft. Uno Platform is now a co-maintainer of SkiaSharp, the graphics library at the heart of its rendering pipeline.

Rich text everywhere

New RichTextBlock and RichEditBox bring rich text display and editing to every target, and widen third-party control support, including the Windows Community Toolkit.

More WinUI coverage

WinUI’s own default styles and controls ported from WinUI’s sources, including the current ItemsRepeater, the new LinedFlowLayout, and an improved TitleBar, so the APIs you and your agents already know behave the same way on every platform.

Built in step with Microsoft, Uno Platform 7.0 brings the latest .NET and Windows UI innovations to more platforms while deepening our contribution to the open-source foundations that power them.

Getting started takes minutes with Uno Platform Studio, from your browser or your desktop.

Faster~2xmedian benchmark vs 6.7
Commits5,219a new record
Files changed17,853across the repository
Lines added881,051since 6.7
Tests+3,193automated tests added
Issues closed704since 6.7

Uno Platform 7.0 by the numbers.

Faster and leaner on every target

About 2x faster and 5x smaller than 6.7

Performance was a cornerstone of this release, and you should feel it the moment you run your application on 7.0: pages come up faster, lists scroll more smoothly, and there is less memory churn. These gains come from years of optimization work under the surface.

Visual tree520×faster
Brush creation38×faster
Package size83%smaller
List scrolling60%less allocation

Uno Platform 7.0 vs 6.7, on the same benchmarks.

Uno Platform 7.0 vs 6.7, by area.
Area6.7 → 7.0
UI creationBorder 18× faster, 33% less memory
Data and listsDataContext 2.4× and ItemsRepeater 2.7× faster
LayoutAllocations down from 40 KB to 51 B
TextMeasurement 3.4 to 4.3× faster, rearrangement 6.8× faster
Startup and restoreAllocations from 7.7 MB to 3.4 MB, restore disk usage 38% lower
WebAssemblyBorder 9.5× faster, DataContext and text 2× faster, Grid allocations down to 0 B

The result is a smoother UI under load and, on battery-powered devices, real power savings.

Smooth scrolling at 120 FPS, everywhere

Scrolling is synchronized with the display’s refresh rate

Every frame counts. On a 120 Hz screen, scrolling only looks smooth when the content moves on every frame. In 7.0, scrolling is synchronized with the display’s refresh rate, so lists glide with natural momentum and flings feel native.

Mouse wheel46% → 100%frame coverage, now every frame
Touch fling57% → 100%frame coverage, now every frame
Touchpad100%every frame, instead of whole wheel steps

Frame coverage while scrolling, 7.0 vs 6.7.

iOS and iPadOS~2xsmoother scrolling, up to 120 FPS
macOS87%less main-thread usage in the stress test
Android~2xhigher frame rates on supported devices

Improvements on specific platforms.

Sample: SmoothScrolling. A 1,000-item feed in a ScrollView with a live readout of frames and fresh scroll positions per second.

One rendering engine, two backends

SkiaSharp 4 by default, WebGPU as an opt-in

A pluggable rendering architecture lets you adopt new rendering technology without rebuilding your apps, and cuts platform-specific maintenance.

Uno Platform 7.0 unifies rendering across Android, iOS, tvOS, WebAssembly, Windows, macOS, and Linux: consistent results and fixes that apply everywhere, while native features such as maps and video players stay reachable.

SkiaSharp 4 is the default

The Skia backend now ships on SkiaSharp 4 by default, the first major SkiaSharp version built with Uno Platform as a co-maintainer alongside the .NET team at Microsoft. That gives our engineers a direct role in SkiaSharp’s releases, triage, and roadmap, so issues that affect cross-platform rendering get fixed faster. On Android, Windows, and Linux it now renders through Vulkan by default.

A new WebGPU backend

WebGPU joins Skia as a rendering option in Uno Platform 7.0, available on Windows, Linux, macOS, Android, iOS, and WebAssembly. It gives you a choice in how your app is drawn, without tying you to one rendering technology.

This works because drawing now goes through a backend-neutral layer underneath the compositor. The WebGPU backend is built on wgpu-native on desktop and mobile, and on the browser’s own WebGPU support in WebAssembly. The same layer brings managed, SkiaSharp-free implementations of geometry, fonts, image decoding, and SVG.

Rendering with the WebGPU backend can bring sizeable gains. Depending on the scene, we have measured up to a 50% improvement in frames per second.

An app that uses only WebGPU ships without SkiaSharp at all, which removes about 6 MB of uncompressed native code from WebAssembly apps: smaller downloads for your users, and a more flexible foundation for future rendering technologies.

To try it, add WebGpu to your UnoFeatures and register the backend on your host builder. WebGPU is experimental and opt-in for now, so give it a spin and tell us what you build with it.

Bring your own WebGPU code. The new WebGpuCanvasElement lets you draw with your own WebGPU commands inside your UI, on the same device the rest of your app renders with and with no copy, so a custom 3D view or visualization sits beside your XAML like any other control.

Sample: DrawingBackends. The same animated Composition scene, rendered by the Skia backend (left) and the WebGPU backend (right).

.NET MAUI controls on every Uno Platform target, and .NET MAUI on the web and Linux

Another contribution to the .NET community

The .NET ecosystem is strongest when developers can build on what already exists instead of starting over, and this release takes another step in that direction.

Third-party .NET MAUI controls, now on every Uno Platform target. With .NET MAUI Embedding, Uno Platform developers have long been able to use controls from the leading .NET component vendors, such as Syncfusion, Telerik, Infragistics, DevExpress, and Esri, along with the .NET MAUI Community Toolkit, inside their Uno Platform apps. Until now, those controls only ran on the targets .NET MAUI itself supports: iOS, Android, macOS, and Windows. Uno Platform 7.0 removes that limit. The same third-party .NET MAUI controls now work everywhere Uno Platform runs, including the web and Linux, so the charts, data grids, maps, and editors you already license can follow your app to every platform it targets, without waiting for native ports or rebuilding your UI.

.NET MAUI apps in the browser and on Linux. .NET MAUI developers get the reverse: bring an existing app to the browser and Linux through our .NET MAUI handlers, and keep the third-party dependencies it relies on. Whichever framework you started with, the controls and code you have invested in now go further.

The .NET MAUI Marvelous sample on iPhone, Android, and macOS, then in the browser through the Uno Platform .NET MAUI handlers.

Microsoft.UI.Reactor, on every Uno Platform target

Declarative C# UI with hooks, no XAML

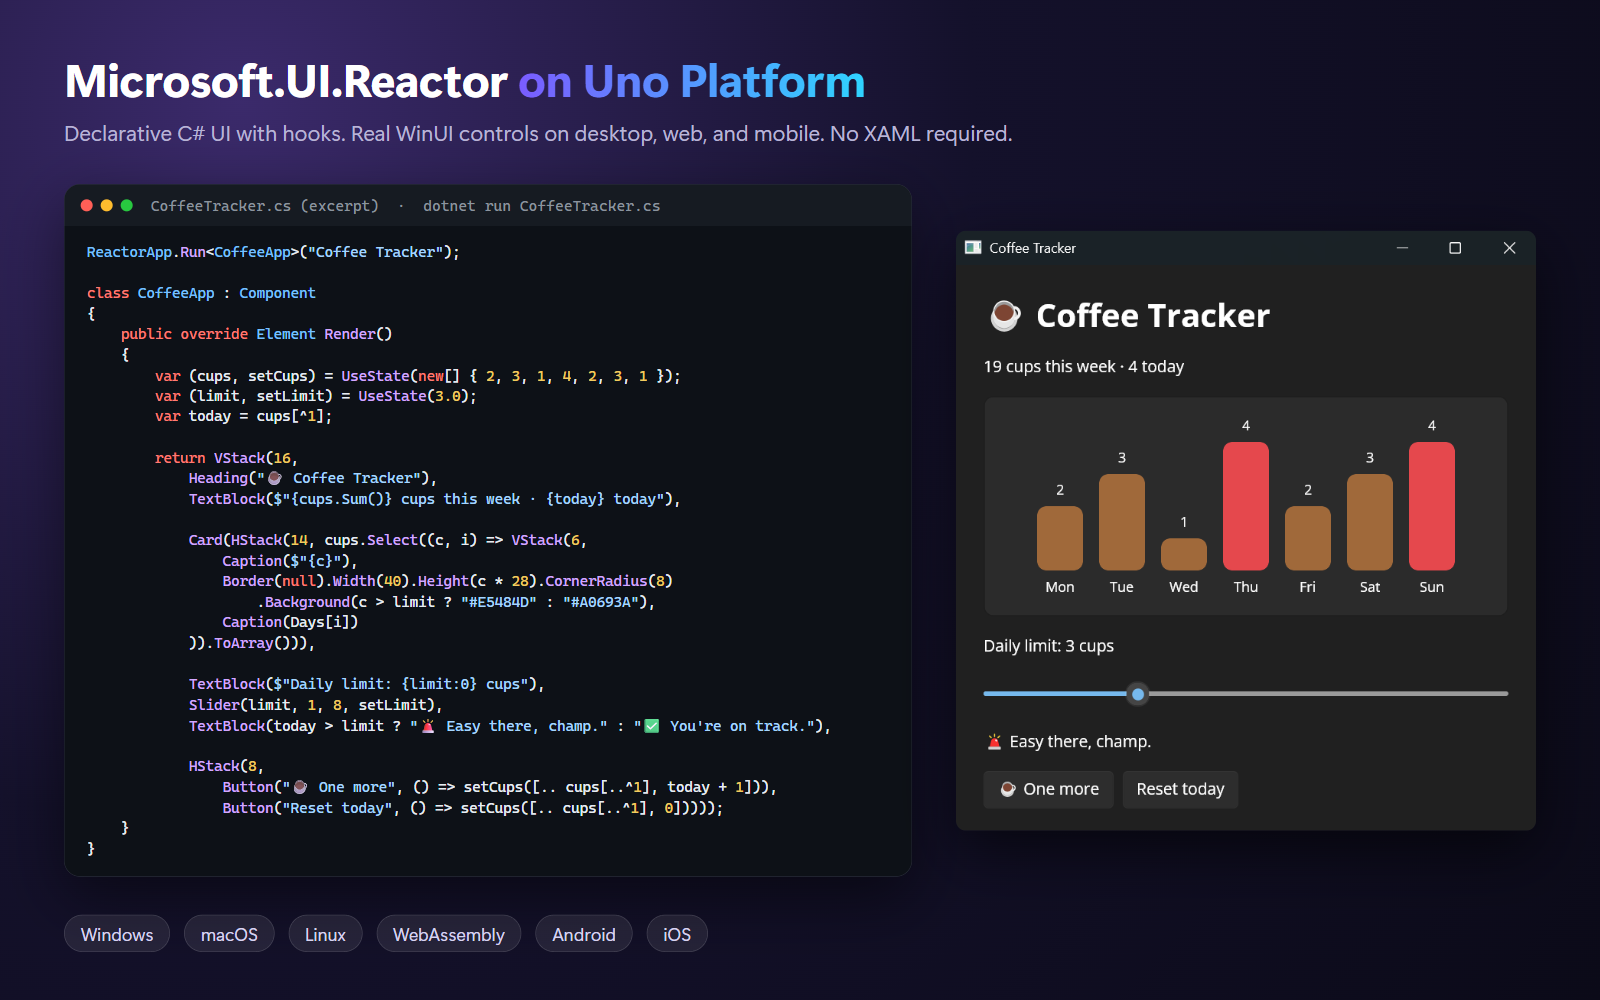
Microsoft.UI.Reactor is Microsoft’s new declarative, component-based C# framework for WinUI. There is no XAML: you describe your UI as a function of state, with hooks such as UseState and fluent modifiers, in a style that will feel familiar if you come from React, SwiftUI, or Jetpack Compose.

A Reactor component in C# next to the Coffee Tracker app it renders, with a bar chart of cups per day, and chips for Windows, macOS, Linux, WebAssembly, Android, and iOS.
A Reactor component and the app it renders, on desktop, web, and mobile.

With 7.0, Reactor apps run on Uno Platform too: on the desktop, in the browser, and on Android and iOS. Add Reactor to your UnoFeatures:

<UnoFeatures>Reactor</UnoFeatures>

Your existing XAML pages, styles, and view models stay as they are, and Reactor components render real WinUI controls in the same visual tree. Reactor support is in preview; the Reactor guide covers single-file apps and the unoapp-reactor template.

Because Uno Platform keeps a 1:1 API surface with WinUI, an automated sync brings the latest changes from the Microsoft.UI.Reactor repository over with little effort.

Apple TV, a new target platform

Same XAML, same controls, same Fluent styles

Apple TV is a new target platform in 7.0. Add net10.0-tvos to your app’s TargetFrameworks, and the same app runs on Apple TV with tvOS 15 and later: same XAML, same controls, same Fluent styles. It renders through Metal, as on iOS, and the Siri Remote drives focus navigation.

Together with Android TV, added in 6.7, your apps now reach both TV platforms.

.NET 11 support on day zero

Every head, in step with Microsoft

Uno Platform 7.0 ships full support for .NET 11 on day zero, across every head: Desktop, WebAssembly, Android, iOS, Apple TV, and Windows App SDK. Create an app with dotnet new unoapp -tfm net11.0, and uno-check installs everything you need. .NET 10 remains fully supported as the long-term support release.

Shipping this close to Microsoft’s own timeline reflects a partnership that goes both ways: Uno Platform is now a co-maintainer of SkiaSharp alongside the .NET team at Microsoft, and contributes to other parts of .NET, including the Android bindings.

See it live at .NET Conf 2026. Join us at .NET Conf 2026, the free virtual event for the launch of .NET 11, on November 12 at 4:30 p.m. EST, and see Uno Platform 7.0 running on .NET 11.

RichTextBlock and RichEditBox, on every platform

One of our earliest requests, now closed

RichTextBlock and RichEditBox are now available on every platform we support. The request dates back to one of Uno Platform’s earliest issues, #81 from 2018. Both controls bring WinUI-compatible rich text display and editing to every target, backed by extensive compatibility testing.

Sample: RichTextEditor. Typing, formatting, undo and redo in a RichEditBox, on the Windows desktop head.

Closer WinUI alignment

More controls ported straight from WinUI’s sources

Your WinUI knowledge should carry over to Uno Platform unchanged. That has been our promise from the start. Uno Platform 7.0 ports more controls directly from WinUI’s open-source code, preserving their Windows layout, selection, and automation behavior. The WinUI team has been moving fast, advancing WinUI in the open with the community, and we are glad to bring that work to the cross-platform world. What’s new:

Lists that behave like WinUI’s

ItemsRepeater, its layouts, and ItemsView are now ported from the current WinUI sources, so layout, recycling, selection, and automation match Windows, and future WinUI fixes are one re-sync away.

Photo-gallery layouts

LinedFlowLayout arranges items in justified rows of equal height, sized by their aspect ratio, with the same API as WinUI, so your WinUI XAML carries over.

A custom title bar

Add your own content with WinUI’s TitleBar, with native window behavior on Windows and macOS.

The WinUI TitleBar control on Windows desktop: back and pane buttons, the app title, a search box, a New note button, and a profile picture in the title bar.

Multiple windows on iPad

Each WinUI Window your app opens is now a real iPadOS window.

Lottie, powered by Composition

C# code generated by LottieGen now renders unmodified on every platform through WinUI’s Composition engine, with no extra packages.

Sample: LottieBuiltIn. AnimatedVisualPlayer playing hand-made Lottie files, the same sunrise animation compiled with LottieGen and loaded from JSON, and WinUI’s ProgressRing and AnimatedIcon.

Best of the rest

A few more items from a long list

This release is large, and if you have read this far, thank you. A few more items, or read the full release notes.

Built-in input validation

Display view model validation errors in bound controls automatically, with support for INotifyDataErrorInfo, {Binding}, and {x:Bind}. See input validation.

Screen readers on mobile and Linux

Android TalkBack, iOS VoiceOver, and Linux AT-SPI now work with Uno Platform’s automation tree, for accessibility and UI testing.

High contrast

Desktop apps on Windows, macOS, and Linux now adapt to the system’s high contrast settings automatically.

App automation from the command line

Use uno-devserver app to launch, inspect, interact with, and test running apps from scripts, CI pipelines, and AI agents.

Leaner packages, faster restores

Fewer dependencies, smaller apps, and about 54% less disk space for a fresh desktop Release restore.

Skeleton loading, generated from your UI

Wrap your existing XAML in a SkeletonView and the placeholders are generated from its live layout, so skeleton states stop being a separate thing to build and maintain as your UI evolves.

Leaner WebAssembly apps

A blank app now restores about 63 packages instead of 120, image decoding uses far less browser memory at runtime, and the initial load has more built-in resiliency.

Upgrading and breaking changes

Most apps upgrade by bumping the SDK version

Most apps on Uno.Sdk upgrade by bumping the SDK version, and the migrating to Uno Platform 7.0 guide walks through everything, with before and after code. The changes to plan for:

Native rendering is retired

Every target now renders through the unified pipeline, on SkiaSharp 4 or WebGPU. Native views such as maps and video players can still be embedded in your UI.

One project format

Uno.Sdk single-project apps are the only supported format, and the new UNOB0029 and UNOB0022 diagnostics guide older projects over.

Mac Catalyst is removed

macOS apps use the Desktop head (net10.0-desktop).

New defaults

Apps target net10.0 by default, with net11.0 one change away, and the Windows head uses Windows App SDK 2.4. Minimum OS versions are iOS and tvOS 15.0, Android API 24, and Windows 10 19041.

Libraries built for 6.x

Libraries built against 6.x are binary-incompatible with 7.0, so rebuild every library against 7.0. DependencyObject is now a single class, with no separate DependencyObjectStore, which is what libraries that define their own DependencyObject types will notice first.

Get started with Uno Platform 7.0

Or better, start with Uno Platform Studio

Ready to upgrade? Update the Uno.Sdk version in your global.json:

{
  "msbuild-sdks": {
    "Uno.Sdk": "7.0.x"
  }
}

Then follow the migration guide.

New to Uno Platform? Start with Uno Platform Studio.

Start in your browser or on your desktop, build alongside your preferred AI agents, see changes instantly, and validate your application on a real iOS or Android device. It is the fastest way to see what modern, cross-platform .NET development looks like.

Finally, a huge thank you to everyone who contributed code, issues, and reviews to our largest release yet, from first-time contributors to community members whose long-standing contributions have now landed.

Uno Platform 7.0 gives you more ways to build. Uno Platform Studio brings it all together. We can’t wait to see what you build next.

The post Uno Platform 7.0: 2x faster, 5x smaller, built for the agentic era appeared first on Uno Platform.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories