 Log in

After all, if they’re marked as unsafe, there’s gotta be a reason, right?

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


I’m going to try to avoid falling into the trap of making a bad pun about the season…damnit! ;-)
Welcome to the September edition of Interesting Links in the Data and AI World. It’s a bumper edition (aren’t they always), with lots and lots about Kafka and related technologies in particular this month. Oh, and AI. Obvs.
Pennsylvania, USA
The fog after a layoff shows up before the grief does, and nobody warns you about it. The mind that carried a whole career can’t hold a grocery list. It’s frightening. It’s also normal, and it lifts.
I’ve written about the last day in A Letter for the Night Your Job Ends. The money got its own post, Jobs Are Disappearing Quietly. This one is about the weeks in between, when your own mind feels like a road you can’t see.
One note first: I’m not a doctor or a therapist, and this isn’t medical advice. For twenty-five years, companies have called me on their worst day. I’ve watched a lot of people walk through the weeks after a job ends. This is what I’ve seen help.
What the Fog Feels Like
It’s a Wednesday morning, and the sun is out. You open an email from the benefits office and read the first line four times. On the fifth pass, you notice you’re holding the phone and haven’t read anything at all.
You walk into the kitchen and stand there. You came in for something. The fridge hums, and it doesn’t know either. You go back to the couch without it.
You open a job board to look at one listing. Forty minutes later, you’ve scrolled past two hundred of them and applied to none. You can’t remember a single title you saw.
The words are the worst part. For twenty years you explained your work without thinking about it. Now a plain word goes missing in the middle of a sentence. You wait for it, and it doesn’t come back.
You learn what your house sounds like at eleven in the morning. For years you were somewhere else at that hour. Now you know which floorboard creaks and when the mail truck comes. Everything you know how to do is still in there, the way the road is still there in fog.
The People Who Don’t Know Yet
Your folks call on Sunday, the way they always do. “How’s work?” “Busy,” you say. Afterward you stand in the hallway with the phone still warm, and you can’t believe how easily it came out.
They’ve bragged about your job to the neighbors for years. They still have the photo from your first day, badge clipped on, grinning like it was graduation. You can’t take that away from them yet. So you carry it for them too.
Your kid is thrilled to find you home on a Tuesday. “Are you sick?” “No, sweetheart, working from home today.” By afternoon there’s a chalk sun on the driveway and YOU’RE HOME! in big, uneven letters.
A school form comes home asking for each parent’s job. You leave your line blank and sign your name under the empty space. It’s the smallest thing you’ve done all week, and the heaviest.
Your partner says, “We’ll be fine,” in a voice working hard to sound normal. You both pretend not to notice the other one pretending. Two people who love each other, being careful in the same small house.
Somewhere in all of this, a quiet, awful question arrives: what if this is who I am now? What if the layoff took my mind along with the job? It didn’t. It only feels that way from inside the fog.
Why It Isn’t Weakness
A layoff moves a lot of things in one afternoon. Your money, your days, your name for yourself and the people you saw every morning all shift at once. Your mind puts its whole weight on the danger, so there isn’t much left for a benefits letter. That’s how people are built under threat, and it says nothing about your character.
Part of me wants to argue with this whole post. Bills don’t wait thirty days, and I know some of you can’t afford a slow month. The rules below aren’t about stopping. They’re about not making hard turns while you can’t see.
The Fog Line
On American roads, the solid white line along the right edge has a nickname. Drivers call it the fog line. When you can’t see the road ahead, you watch that line and let it guide you.
It’s the most boring thing on the road. It won’t tell you where you’re going. It keeps you on the pavement until you can see again, and right now that’s all you need from it.
For the first thirty days after a layoff, you need a fog line of your own. It’s a handful of small rules you set on a calm day, so the fog can’t argue with them. These are the ones I’d give a friend.
Rules for the First 30 Days
Low beams only. High beams make fog worse, because the light bounces back and blinds you. Trying to see the next five years does the same thing this month. Plan today and tomorrow, and let that be far enough.
No big turns. Don’t make big decisions you can’t undo in the first thirty days if they can wait. Don’t sell the house, move across the country or cash out a retirement account in a panic. If a decision can’t wait, borrow someone’s eyes and ask a person you trust to read it before you sign.
The same goes for the long email to your old manager. Write it if it helps, then save it as a draft. It reads differently in a month.
Write everything down. The fog makes memory slippery, so stop trusting yours for a while. Keep one notebook for all of it: calls, names, dates, deadlines and what the benefits office told you. When your mind drops something, the notebook catches it.
Read in small pieces. If a page won’t go in, don’t fight it for an hour. Read one page, then write one line about what it said. A forty-page severance packet can be ten short sittings, or one sitting with a friend beside you.
Put a fence around the job search. In fog, speed feels like safety, and it isn’t. Pick a start time and an end time for the search each day, and close it when the time’s up. I’d rather see you send five careful applications than fifty blurry ones.
Don’t pass anyone. Someone from your old team will post that they landed a new role in two weeks. Good for them. You can’t see their road either, and passing in fog is how people get hurt.
Tell one person where you are. Before a drive in bad weather, you tell someone your route. Do the same with one person this week. Give them the true sentence, the one you’ve been replacing with “busy.”
When to Talk to Someone
The fog after a layoff should thin out a little each week. It won’t lift in a straight line. You’ll have a clear Monday and a thick Tuesday, and that’s normal too.
Talk to a doctor or a counselor if it’s getting thicker instead of thinner after a few weeks. The same goes if you can’t sleep, can’t stop sleeping, or stop eating. Reach out if you need a drink to get through the afternoon, or if nothing feels worth doing anymore.
Look in your severance papers for an employee assistance program. Some still cover a few free counseling sessions after the last day. Asking for help in fog is pulling over, the thing driving manuals tell you to do when you can’t see.
If you ever think about hurting yourself, don’t wait for the fog to lift, and reach a person today. In the US, call or text 988 for the Suicide and Crisis Lifeline. Anywhere else, Find A Helpline lists free, confidential lines in your country. Someone is there to answer right now, and you’re worth the call.
The Fog Lifts
Morning fog doesn’t lift because you fight it. It burns off as the day warms up, a little at a time. Then, all at once, you can see the fields on both sides of the road.
The fog after a layoff works the same way. One day you’ll read a whole article and notice only at the end that you read it. You’ll pick lunch in ten seconds. The word you need will be right there, where it always was.
And one Sunday, your folks will call and ask how work is. You’ll tell them the truth, all of it, and there’ll be a long pause on the line. Then one of them will say, “We were never proud of the job. We were proud of you.”
You’ll cry in the hallway, and it’ll be the good kind. You didn’t lose your mind or your skill. You lost a job, and your head needed time to catch up.
The chalk sun is still on the driveway. The road was there the whole time.
Under all of this sits one question: who are you once the work is gone? I wrote about it in Who Are You When the Work Takes Seconds? It’s an essay about where your sense of self lives when the job stops holding it.
The essay is one of thirty in my book AI: Nobody’s in There. But we’re still in here. All of them are free to read online, and the paperback is on Amazon.
Go easy on yourself this month. You’d say the same thing to a friend.
The fog after a layoff is not who you are now, it is weather.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
First appeared on The Fog After a Layoff: Rules for the First 30 Days
Pennsylvania, USA

Today, we are announcing the general availability of DiskANN Vector Index & Search across Azure SQL Database, Azure SQL Managed Instance with the always-up-to-date update policy, and SQL database in Microsoft Fabric.
DiskANN brings scalable approximate nearest-neighbor search directly to the SQL engine. Developers can store vectors alongside relational data and combine vector similarity with the filters, joins, security policies, and transactional data their applications already rely on.
Why Vector indexes matter
Applications use embeddings to represent the semantic meaning of text, images, products, documents, and other content as vectors. Vector similarity search can then find results that are conceptually related to a user’s query, even when they do not contain the same keywords.
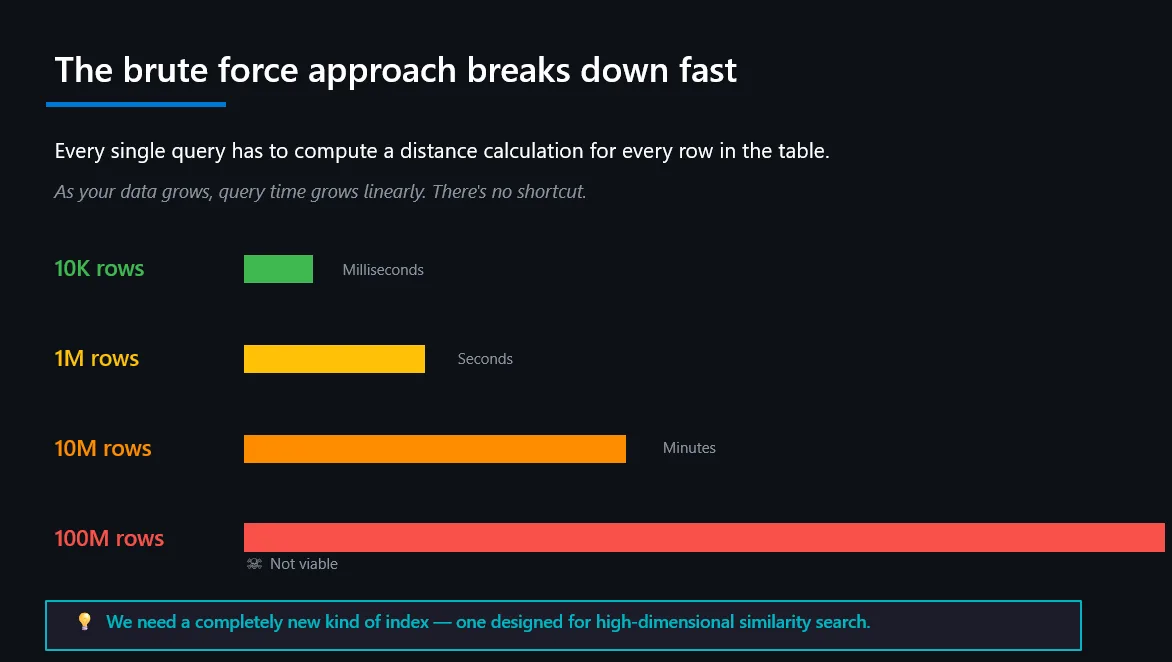
Without a vector index, exact vector search calculates the distance between the query vector and every qualifying vector. It must then identify and order the closest matches.
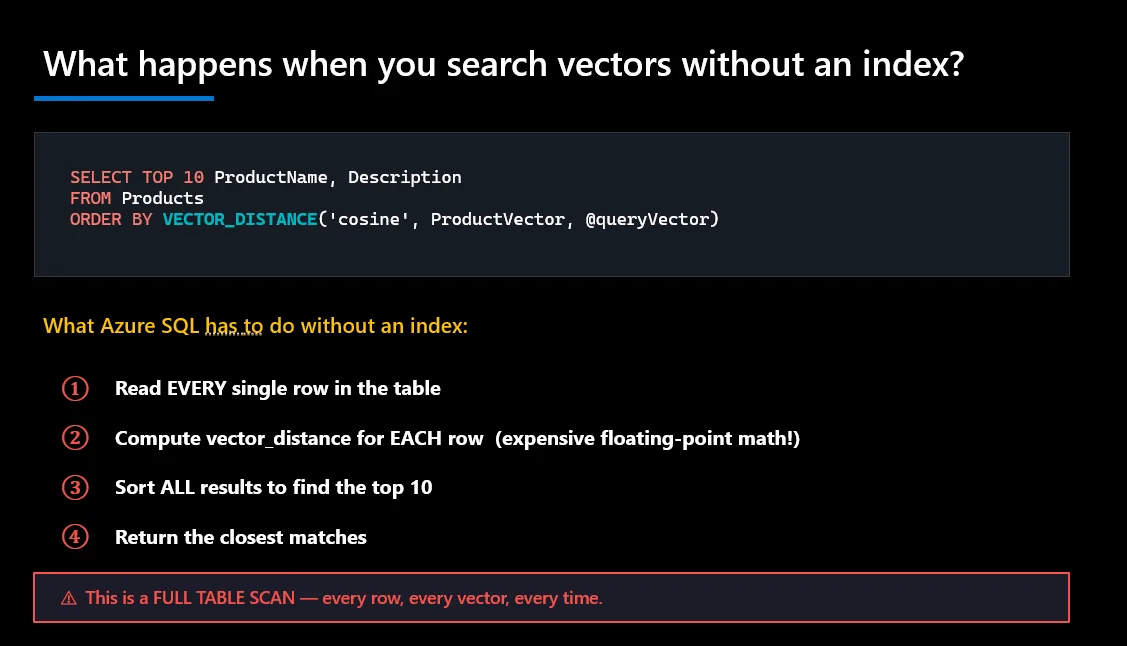
This approach can work well for smaller datasets or workloads that require exact results, but its computational cost increases as the number of vectors grows.
Efficient similarity search with DiskANN
A DiskANN vector index provides an approximate nearest-neighbor search path designed to identify relevant candidates efficiently as the dataset grows.
Instead of evaluating every vector, the index builds a navigable graph so that the database engine can navigate toward the most promising candidates. This reduces the amount of work required to identify similar results while maintaining high search quality.
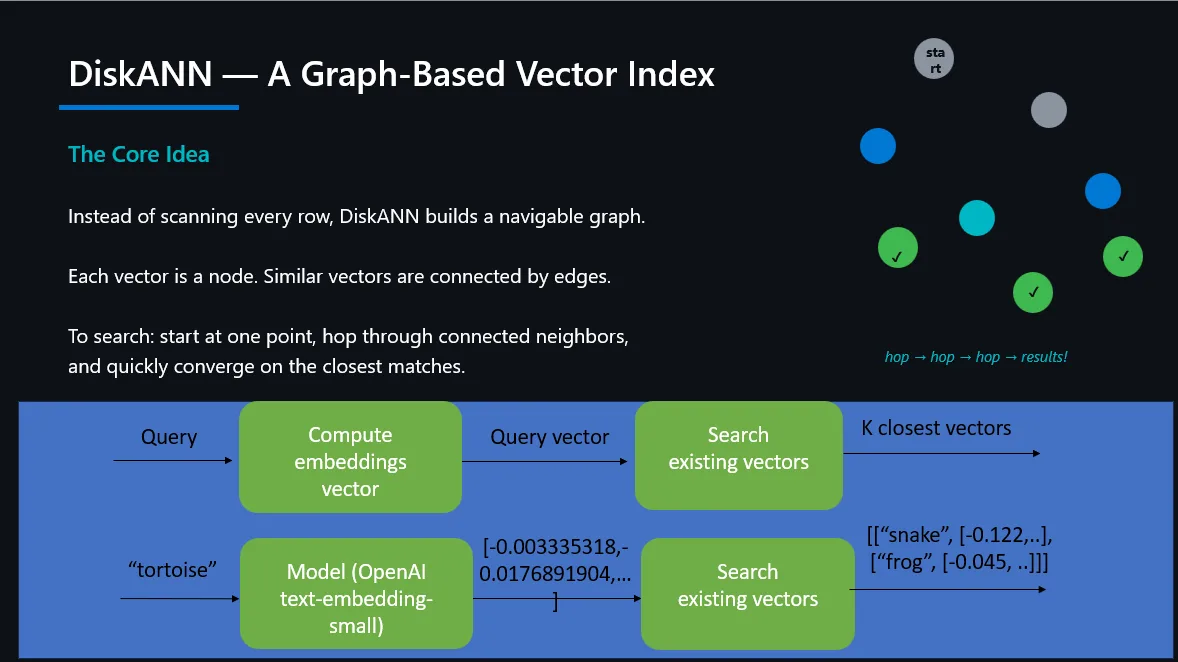
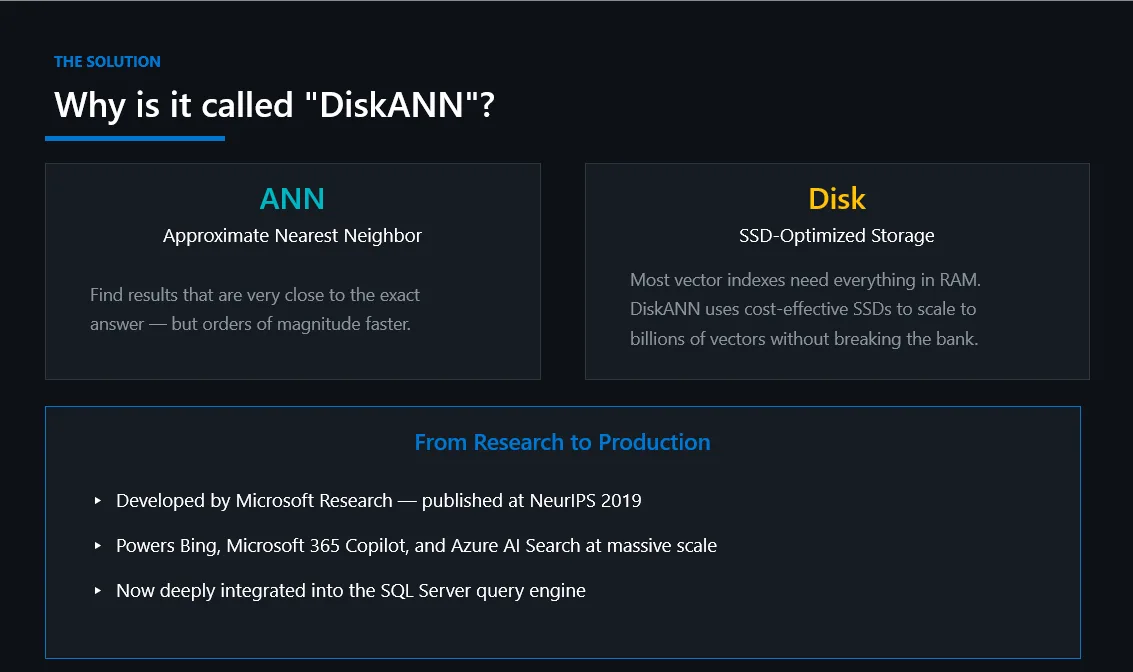
Why is it called DiskANN?
The way I like to remember it – ANN means don’t search everything, and Disk means don’t keep everything in memory More specifically the name DiskANN describes two important aspects of its design:
- ANN Approximate Nearest Neighbor: The search does not compare the query vector with every vector in the dataset. Instead, it efficiently explores the index to identify likely nearest neighbors.
- Disk: DiskANN was designed so that large vector indexes don’t have to depend entirely on expensive RAM. It can use SSD-backed storage while maintaining a relatively small memory footprint, which is what helps it scale to massive datasets
From preview to production
When we introduced DiskANN vector indexes in public preview, we invited customers to begin building vector-search applications directly on their operational data. Customer feedback helped shape the experience that is generally available today:
- DiskANN-based approximate nearest-neighbor search for large vector collections
- Full INSERT, UPDATE, and DELETE support, with asynchronous vector-index maintenance
- Iterative filtering to find the requested number of qualifying results while applying relational predicates
- Optimizer-driven execution, allowing SQL to choose between exact and approximate vector-search strategies based on the query context
- Composable T-SQL, so vector search works with existing filters, joins, business logic, and security controls
The result is vector search that behaves like part of SQL not a separate retrieval system that applications must operate and reconcile with their database. Read more here
One query from development to production
Applications can express that approximate results are acceptable using TOP (N) WITH APPROXIMATE:
SELECT TOP (10) WITH APPROXIMATE
    p.ProductId,
    p.Name,
    s.distance
FROM VECTOR_SEARCH(
    TABLE = dbo.Products AS p,
    COLUMN = Embedding,
    SIMILAR_TO = @query_vector,
    METRIC = 'cosine'
) AS s
WHERE p.IsActive = 1
ORDER BY s.distance;
The same query can continue to work as the application and its data grow. The optimizer evaluates the complete query including the data size, predicates, available indexes, and requested result count and selects an appropriate execution strategy.
Applications can therefore combine similarity search with familiar relational requirements, such as:
- Returning only products currently in stock
- Searching documents the current user is authorized to access
- Restricting recommendations by region or category
- Joining vector-search results with operational tables
- Applying existing row-level security policies
This allows developers to add semantic retrieval without giving up the relational and transactional capabilities already used by their applications. Read more here
See the evolution of vector search
In a new Data Exposed episode, we trace how Azure SQL vector search evolved as customer applications moved from prototypes toward production. The episode also demonstrates vector search across one billion vectors in Azure SQL Database Hyperscale.
Watch it here
Get started
Ready to add vector search to your application?
The post DiskANN Vector Index and Vector Search Are Now Generally Available in Azure SQL appeared first on Azure SQL Dev Corner.
Pennsylvania, USA

I have always been interested in Zero-Overhead Deterministic Exceptions from P0709, as they promised a nicer implementation model and they are much easier to integrate into JIT-compiled code. Some people forbid regular C++ exceptions, due to code size and performance concerns, which are concerns that P0709 explicitly wants to address. Unfortunately, there was no implementation available. But now, with LLMs, doing this kind of experiment is much more tractable. I basically gave the official P0709 specification to an LLM, and it built a first prototype in one shot. Admittedly my initial enthusiasm cooled down a bit after I found a lot of problems and corner cases, but after about one day of work I was able to build a reasonable prototype, which is something that would easily have taken me weeks or even months in the past. I tested it with complex code, and it handled everything fine, but note that it is still not production ready (e.g., Itanium ABI only).
That prototype now allows us to quantify the differences between
exception implementations. P0709 describes two ways to implement them:
Either pass a hidden pointer to an error state to all functions that are
marked with throws (we call this strategy
pointer here), or use the carry bit to indicate errors and
pass the error itself in registers if the bit is set (we call this
strategy carry). That is a very nifty approach suggested by
Herb Sutter, but it somewhat clashes with some of the function epilogues
(e.g., on Windows), and such a flag is not available on all platforms.
We thus introduced a third variant register here that
simply uses another unused caller-saved register as an error indicator,
which is more portable. The classic C++ exception handling mechanism we
call dynamic.
Microbenchmarks
We first run some microbenchmarks to see the overall effects. These over-emphasize the differences as the benchmarks basically do nothing besides function calls (ns per outer call):
| Test | failures | dynamic | pointer | register | carry |
|---|---|---|---|---|---|
int through 8 calls |
0% | 6.02 | 6.09 | 6.08 | 6.16 |
| 1% | 17.5 | 7.10 | 6.31 | 6.33 | |
| 10% | 101 | 7.59 | 6.85 | 6.88 | |
| 50% | 467 | 9.48 | 9.26 | 9.11 | |
| forwarding chain, 8 tail calls | 0% | 1.54 | 1.34 | 1.52 | 1.59 |
| 50% | 188 | 4.74 | 4.31 | 4.28 | |
void through 4 calls |
0% | 3.00 | 3.09 | 3.05 | 3.06 |
| 1% | 9.82 | 3.33 | 3.32 | 3.31 | |
| 16-byte struct (two registers) | 0% | 3.01 | 3.24 | 3.06 | 3.06 |
| 32-byte struct in memory | 0% | 5.40 | 6.06 | 5.75 | 5.44 |
| 1% | 11.3 | 6.03 | 5.60 | 5.43 | |
| 50% | 314 | 6.26 | 5.93 | 5.92 | |
| pointer, single call | 0% | 0.75 | 0.95 | 0.75 | 0.75 |
| 50% | 188 | 3.66 | 3.29 | 3.08 |
We notice several things. First, the pointer strategy
often has noticeable overhead due to additional memory instructions, and
is inferior to the other two. register and
carry are nearly identical, which, given the fragility of
the carry approach, means that register seems
to be the preferred choice. Compared to classical C++ exceptions,
performance of register is within 1-2% on the happy path,
where no exception occurs, and it is dramatically faster, up to orders
of magnitude, if exceptions indeed occur.
A more realistic workload
These numbers over-inflate the differences because the functions do
so little work. As a more plausible workload, we use RapidJSON and benchmark
the performance on the nativejson-benchmark,
optionally corrupting some inputs to trigger exceptions. RapidJSON can
be configured to report failures by error codes instead of exceptions;
we call that strategy codes here.
The full results are here;
we show a selection below. What the numbers basically show is 1)
deterministic exceptions with the register strategy have
the same performance and the same code sizes as explicit error codes, 2)
performance differences from traditional C++ exceptions are largely
within the noise even on the happy path, and 3) in the case of errors
they are vastly superior to traditional C++ exceptions.
Happy path: SAX parsing
MB/s, higher is better, best of 5 runs; in parentheses: change
relative to codes.
codes |
dynamic |
pointer |
register |
carry |
|
|---|---|---|---|---|---|
| canada.json | 1635.8 | 1606.6 (-1.8%) | 1665.1 (+1.8%) | 1606.1 (-1.8%) | 1603.3 (-2.0%) |
| citm_catalog.json | 2212.7 | 2216.0 (+0.1%) | 2356.3 (+6.5%) | 2206.3 (-0.3%) | 2341.5 (+5.8%) |
| twitter.json | 1365.2 | 1376.5 (+0.8%) | 1425.4 (+4.4%) | 1377.5 (+0.9%) | 1472.0 (+7.8%) |
Happy path: retired instructions per parse
Instructions (perf stat), lower is better; in parentheses: change
relative to codes.
codes |
dynamic |
pointer |
register |
carry |
|
|---|---|---|---|---|---|
| sax canada.json | 49555378 | 49903680 (+0.7%) | 50294221 (+1.5%) | 50850829 (+2.6%) | 50738702 (+2.4%) |
| sax citm_catalog.json | 20552806 | 20212949 (-1.7%) | 20761272 (+1.0%) | 20802928 (+1.2%) | 20730816 (+0.9%) |
| sax twitter.json | 11758968 | 11547972 (-1.8%) | 11799096 (+0.3%) | 11850736 (+0.8%) | 11813765 (+0.5%) |
Errors: small documents, a fraction of them corrupted
ns per document, lower is better, best of 5 runs; in parentheses:
change relative to codes.
codes |
dynamic |
pointer |
register |
carry |
|
|---|---|---|---|---|---|
| 0% | 1726.1 | 1692.2 (-2.0%) | 1729.3 (+0.2%) | 1720.5 (-0.3%) | 1721.0 (-0.3%) |
| 1% | 1707.3 | 1812.3 (+6.2%) | 1703.3 (-0.2%) | 1707.7 (+0.0%) | 1713.9 (+0.4%) |
| 10% | 1600.8 | 1848.9 (+15.5%) | 1597.3 (-0.2%) | 1598.3 (-0.2%) | 1614.3 (+0.8%) |
| 50% | 1256.5 | 1895.7 (+50.9%) | 1263.6 (+0.6%) | 1264.2 (+0.6%) | 1275.3 (+1.5%) |
| 100% | 868.6 | 1934.7 (+122.7%) | 871.8 (+0.4%) | 869.3 (+0.1%) | 882.1 (+1.6%) |
Size of the parser
Bytes of all GenericReader functions,
GenericDocument::ParseStream and parseSAX
(into which parts of the parser are inlined); in parentheses: change
relative to codes.
codes |
dynamic |
pointer |
register |
carry |
|
|---|---|---|---|---|---|
| code | 17191 | 18162 (+5.6%) | 17540 (+2.0%) | 17204 (+0.1%) | 17289 (+0.6%) |
| unwind info | 1292 | 1500 (+16.1%) | 1340 (+3.7%) | 1268 (-1.9%) | 1248 (-3.4%) |
| exception tables | 0 | 388 | 0 | 0 | 0 |
| total | 18483 | 20050 (+8.5%) | 18880 (+2.1%) | 18472 (-0.1%) | 18537 (+0.3%) |
Conclusion
Given that “exceptions” might not always be that exceptional (e.g., when parsing large amounts of user input), deterministic exceptions indeed seem to be a very good idea, and P0709 indeed should be adopted by the C++ standard. Not that this is likely to happen, given the lack of progress on this front, but now we at least have numbers to talk about.
Pennsylvania, USA
Six months ago in Atlanta, I closed my post with a promise: SQLCon is coming to Europe, and I can’t wait to see you there. This week in Barcelona, we made it happen.
Across the announcements we shared in Barcelona, SQL continues to build on the foundation enterprises have trusted for decades. This gives organizations more control where their workloads run, more room for applications to grow, and more intelligent tools for operating databases in the agentic era.
Running data and AI on infrastructure you control
For organizations across Europe, digital sovereignty has become a priority. They need greater control over where data resides without putting modern app development, performance, or AI beyond reach.
This is a reality that Microsoft SQL has been preparing for decades, steadily strengthening security, resilience, and performance across its ecosystem. Capabilities such as Transparent Data Encryption, released in 2008, Always Encrypted in 2016, and Ledger in 2022 have continued to strengthen the security and control organizations need for sovereign environments.
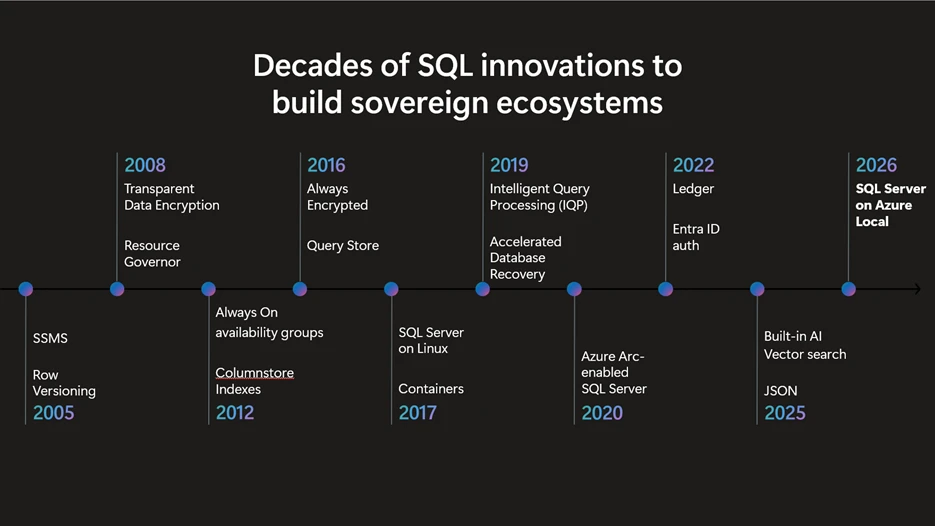
Building on this history, we’re now announcing general availability of SQL Server on Azure Local for both connected and disconnected operations.
This release brings the Azure control plane and management to customer-controlled environments, providing a consistent SQL and Azure experience for workloads that need to remain close to their applications, users, or physical operations. This includes:
- Connected deployments: Organizations can use Azure-based management while keeping workloads and data local.
- Azure Local Disconnected Operations (ALDO): Organizations get a local control plane for their private sovereign environments, supporting operations where cloud connectivity is unavailable or restricted.
For organizations that want to leverage AI in these environments, Foundry Local on Azure Local, now in preview, enables teams to build AI experiences close to their data. Applications, databases, and AI models can remain within the customer-controlled environment, so sovereignty requirements don’t put AI innovation out of reach.
For deployment options, licensing, and local AI capabilities, learn more about SQL Server on Azure Local.
Giving applications room to grow with Azure SQL Database Hyperscale
As applications mature, their demands rarely stay predictable. Workloads grow, usage patterns change, and the database needs to constantly adapt without forcing teams to rethink the application architecture around it.
Azure SQL Database Hyperscale is designed to provide flexibility while delivering the performance applications need. Azure SQL Database Hyperscale is SQL Server rearchitected for cloud scale. By decoupling compute and storage, Hyperscale gives applications room to evolve and the scale to meet more demanding workloads.
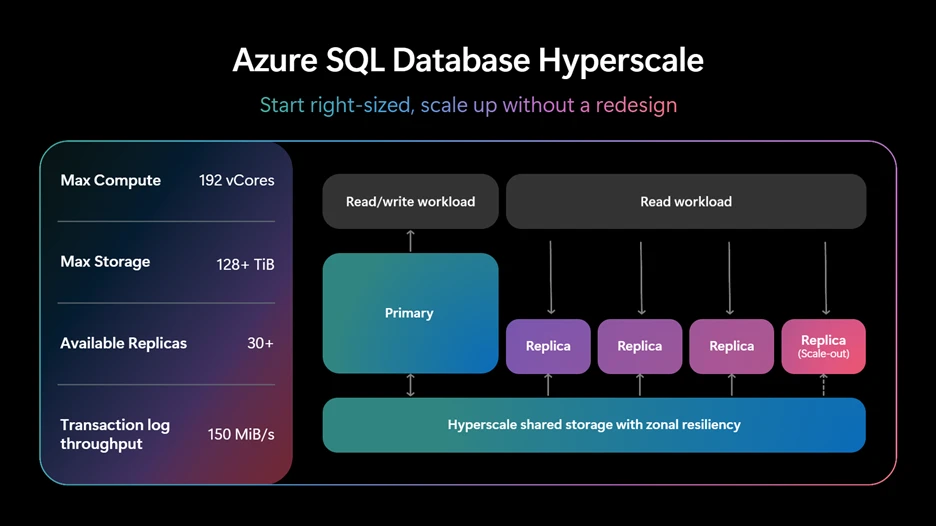
Now, we’re extending that flexibility and performance even further:
- More compute: 160 and 192 vCore Premium-series service objectives are now generally available.
- More scale and better cost efficiency: Hyperscale serverless auto-pause scales to zero and instantly resumes. Along with higher-density elastic pools, both these features are now in preview, providing cost efficiency to customers.
- Vector search: DiskANN vector indexes are now generally available, bringing high-performance vector search to operational data. SQL’s vector index now has full DML support, allowing you to modify data in vector-indexed tables while the index automatically stays updated in real-time.
- A simpler path to Hyperscale: A new Azure Arc migration experience is in preview, bringing assessment, provisioning, migration, validation, and cutover into a centralized workflow.
The scale figures become more meaningful when they represent businesses preparing for the moments when demand is highest and the tolerance for disruption is lowest. SAP Commerce Cloud offers a compelling example.
SAP and Microsoft developed a plan to migrate over 6,000 production databases to Azure SQL Database Hyperscale while prioritizing a seamless transition for customers. Hyperscale removed earlier storage and compute ceilings, giving SAP access to as many as 192 vCores and 128 TB of storage for individual databases, alongside zone redundancy supporting a 99.995 percent service-level agreement.
The result: SAP Commerce Cloud processed $17.8 billion in merchandise with 100 percent uptime during Black Friday and handled nearly 11,000 orders per minute at peak. That is the kind of growth a database platform must be ready to support.
Performance and cost
Performance must also be considered alongside cost. In an independent study commissioned by Microsoft, Azure SQL Database Hyperscale delivered up to 50 percent better price-performance than Amazon Aurora PostgreSQL under the tested conditions. The complete methodology and workload qualifications are available at Hyperscale Benchmark.
Our goal is to give customers the ability to choose a strong foundation early and keep building on it. Hyperscale combines the familiar SQL platform with an architecture that accommodates changing application needs, including new AI experiences operating directly on business data.
Turning database signals into guided action
As applications and database estates grow, signals become scattered across engines and environments, making issues harder to spot and resolve.
Database Hub in Microsoft Fabric, now in public preview, brings inventory, health, performance, security, risk, and optimization signals into a centralized view of your database estate. Administrators and developers can quickly see where attention is needed, explore aggregated or per-resource trends and opportunities through consolidated charts and dashboards, and act from within the hub using database agents.
Database agents for SQL and PostgreSQL on Azure help turn these signals into guided action. The agents reason over database signals, continuously helping administrators understand performance bottlenecks, identify optimization opportunities, recommend actions, and, within appropriate guardrails, help carry those actions forward. SQL Database Agent combines SQL’s native intelligence that includes IQP (Intelligent Query Processing), which is based on decades of domain-specific development and workload telemetry. Intelligent Query Processing, along with AI for reasoning, makes it the industry’s best DB agent.
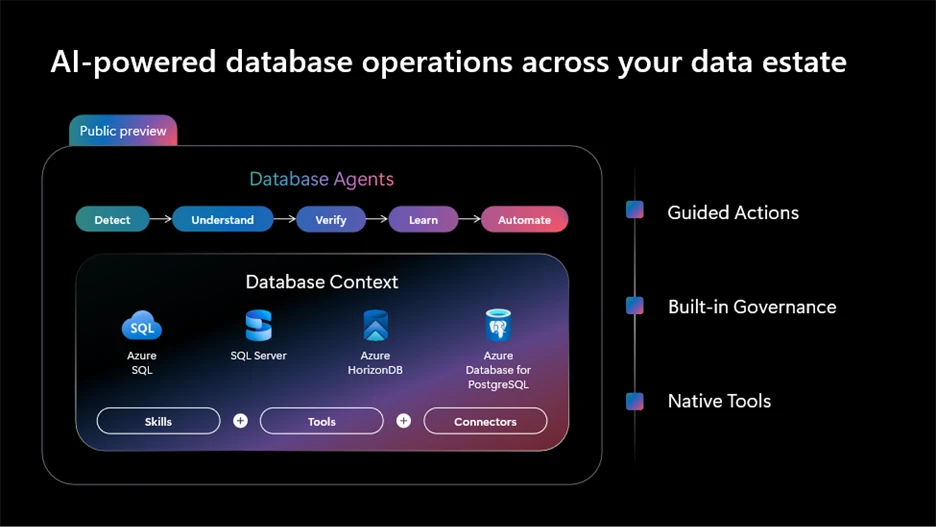
The preview experience begins with database agents for SQL in Database Hub and for PostgreSQL in Visual Studio Code, with these capabilities coming to both surfaces over time. Our vision is a consistent, extensible agent experience that works cohesively across the tools and environments developers and database professionals use, rather than intelligence tied to a single interface.
Across these agentic operations, human judgment remains central. The aim is to shorten the distance between a signal and a well-informed action while respecting existing permissions, operational guardrails, and developer control.
Bringing AI assistance into familiar developer workflows
As AI continues to become a bigger part of database development, our goal is to make it useful in the tools and workflows developers and DBAs already rely on.
Agent Mode for GitHub Copilot in SQL Server Management Studio is now generally available, helping developers reason across database objects and complete multistep tasks from a single goal or prompt. It can investigate dependencies, analyze execution plans, generate and evaluate DDL, review proposed changes, and iteratively gather context to help users move complex database work forward. SQL Projects and Schema Compare are also generally available in SSMS, alongside SQL Formatter in SSMS and Visual Studio Code, making it easier to bring database changes into source control and maintain consistent T-SQL.
We are also extending these capabilities beyond the development environment. Data API builder adds vector and JSON support to help connect SQL data with modern applications and agents through REST, GraphQL, and MCP endpoints.
Together, these announcements help teams bring AI into database development while keeping familiar tools and engineering practices at the center.
What we build next
Thank you for being part of this community. The announcements we have made at SQLCon Barcelona are a milestone, but the work that matters most is what you carry home and create with it. Whether that means revisiting your applications’ digital sovereignty needs, giving them room to grow, or finding a better way to understand and manage your data estate, we want our investment in SQL to help turn that momentum into something valuable for our users and customers. Here’s where you can start:
- Deploy SQL Server on Azure Local
- Deploy SQL Server on Azure Local Disconnected Operations
- Move your database to Azure SQL Database Hyperscale
- Try Database Hub in public preview
You can learn in greater detail about all the announcements at aka.ms/sqlconnews. Thank you for your continued trust and we cannot wait to see what you build with SQL. Until then, adios!
The post SQLCon Barcelona 2026: Advancing SQL with greater control, scale, and intelligence appeared first on Microsoft SQL Server Blog.
Pennsylvania, USA
Next Page of Stories