Log in


TLDR: Multi-agent AI systems use specialized AI agents to analyze repositories across architecture, security, performance, testing, and code quality. By combining multiple perspectives, they help teams identify risks earlier, prioritize improvements, and address technical debt more systematically.
Modern development teams ship features at an incredible pace. AI coding assistants have accelerated development even further, making it possible to generate large amounts of code in minutes.
But as repositories grow, writing code is no longer the hardest part. Maintaining quality across thousands of files, multiple services, and dozens of contributors becomes increasingly difficult.
Most teams still rely on:
- Manual code reviews,
- Static analysis tools,
- Security scans,
- Periodic architecture reviews, and
- Technical debt audits.
These practices are valuable, but they often operate as separate checks rather than providing a unified view of repository health.
A performance bottleneck might remain unnoticed until users complain.
- Architectural issues may only surface when new features become difficult to implement.
- Security vulnerabilities can go undetected until much later in the development cycle.
What teams need isn’t just faster code generation. They need a better way to understand repository health and prioritize improvements.
This is where multi-agent AI systems can make a meaningful difference.
What is a multi-agent AI system?
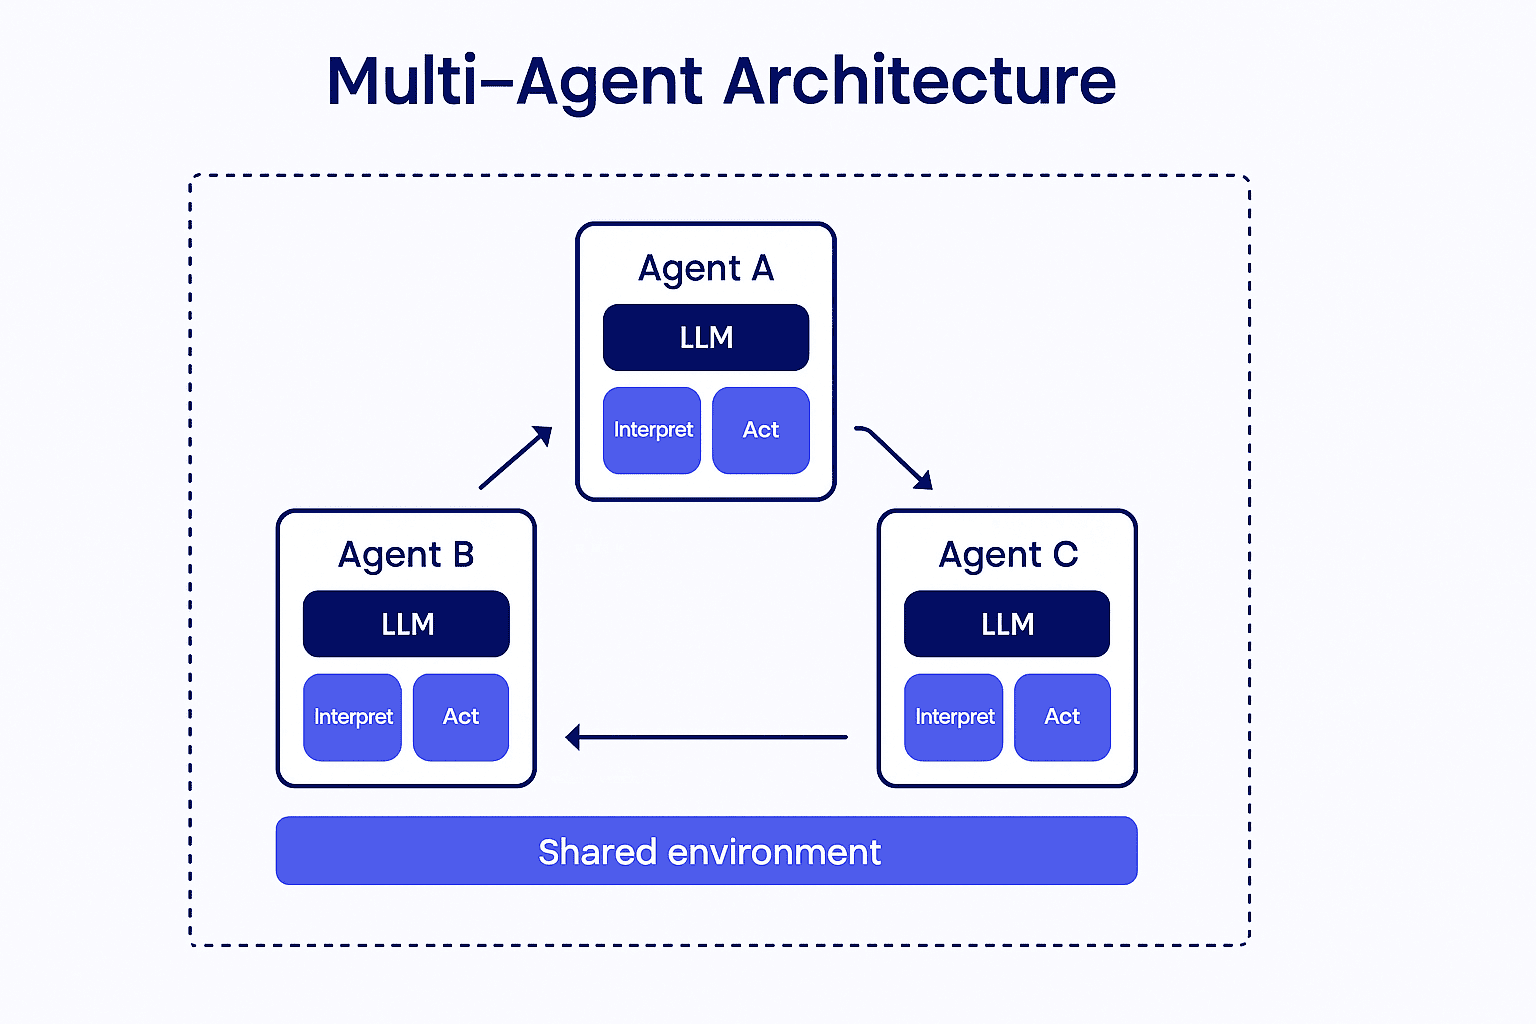
A multi-agent AI system uses multiple specialized AI agents that collaborate to analyze and improve a repository. Instead of asking one AI assistant to inspect everything, responsibilities are divided among specialized reviewers.
Different agents focus on areas such as:
- Architecture,
- Security,
- Performance,
- Testing,
- Code quality, and maintainability.
Together, they can provide broader repository coverage by analyzing different aspects of software quality simultaneously. The actual value depends on how well the agents are scoped, coordinated, and supported with relevant context.
A typical multi-agent system may:
- Analyze repository structure,
- Identify risks and bottlenecks,
- Detect quality issues,
- Recommend improvements,
- Prioritize findings, and
- Track progress over time.
This transforms governance from an occasional review activity into a more systematic engineering process.
When does a multi-agent approach make sense?
Not every repository needs a multi-agent architecture.
A multi-agent approach often makes sense when:
- The repository is large or rapidly growing.
- Multiple quality dimensions need evaluation.
- Different teams own different parts of the system.
- Audits are performed repeatedly.
- Findings must be consolidated and prioritized.
A single-agent approach may be better when:
- The repository is relatively small.
- Tasks are narrowly scoped.
- Execution cost is more important than broad coverage.
- There is limited cross-domain complexity.
The goal is not to replace simpler processes, but to introduce multiple specialized perspectives when the repository’s complexity justifies it.
Why single-agent approaches can struggle with complex repositories
A single AI assistant behaves much like a capable generalist developer. That approach works well when reviewing a component, investigating a bug, or solving a focused problem.
Modern applications, however, rarely contain isolated concerns.
For example:
- A performance improvement may introduce security considerations.
- An architectural change can affect testing coverage.
- A deployment modification may impact reliability.
As complexity grows, teams often benefit from multiple specialized perspectives.
When agents are well-scoped and properly coordinated, a multi-agent approach can provide broader coverage, reduce blind spots, and make findings easier to organize.
The goal isn’t simply finding more issues. It’s helping teams identify the issues that matter most before they become expensive problems.
Single-agent vs. Multi-agent approaches
| Aspect | Single-agent approach | Multi-agent approach |
| Responsibilities | One agent handles multiple concerns | Tasks are divided among specialized agents |
| Coordination | Simpler | Requires orchestration |
| Domain coverage | Broad but potentially shallow | Specialized across domains |
| Complexity | Lower | Higher |
| Resource usage | Usually lower | Can be higher |
| Failure handling | Fewer coordination points | More coordination and failure points |
| Best suited for | Focused tasks | Complex problems requiring multiple perspectives |
Multi-agent systems are not automatically better. They introduce additional coordination, execution, and management complexity. Their value comes when specialization provides benefits that justify that added complexity.
Multi-agent architectures in practice
Multi-agent systems are commonly implemented using either centralized or decentralized coordination.
| Architecture | Best for | Trade-off |
| Centralized | Consistent coordination and shared decision-making | Dependency on central controller |
| Decentralized | Flexible agent-to-agent collaboration | More complex coordination |
For repository governance scenarios, the choice depends on whether consistency or flexibility is the higher priority.
Specialized AI auditors for code governance
One of the biggest advantages of multi-agent AI systems is specialization. Rather than asking one agent to evaluate everything, different agents focus on different aspects of software quality.
1. Architecture auditor
Evaluates structural integrity, coupling, scalability concerns, and service boundaries.
Example: Detects excessive dependencies between services that make future changes more difficult.
2. Security auditor
Identifies hardcoded secrets, authentication risks, vulnerable dependencies, and common security weaknesses.
Example: Flags API keys committed directly into source control.
3. Performance auditor
Reviews query efficiency, resource usage patterns, response time risks, and optimization opportunities.
Example: Identifies N+1 database query patterns that may increase latency.
4. Testing auditor
Evaluates test coverage, edge-case handling, and testing gaps.
Example: Detects payment processes with insufficient automated testing.
5. Code quality and maintainability auditor
Identifies duplication, readability concerns, documentation gaps, and maintainability issues.
Example: Highlights duplicate business logic appearing across multiple services.
Together, these auditors help teams develop a more holistic understanding of repository health.
Real-world example: Auditing a large SaaS repository
Consider a SaaS platform with:
- Multiple microservices,
- Hundreds of monthly pull requests,
- Several engineering teams, and
- Growing technical debt.
The team recently adopted AI-assisted development and significantly increased delivery speed. However, repository health became harder to understand.
Sample prioritized findings
| Finding | Auditor | Priority |
| Exposed credentials in configuration | Security | Critical |
| Missing test coverage in payment process | Testing | High |
| Expensive database query affecting API response time | Performance | High |
| Increasing service coupling | Architecture | Medium |
Individually, these findings are useful. Together, they reveal broader risks that might otherwise be missed.
Instead of receiving disconnected warnings, the engineering team receives a consolidated, prioritized view of repository health.
This is where multi-agent systems provide meaningful value: helping teams move from isolated observations to informed engineering decisions.
From findings to action
Analysis alone does not improve software quality. Teams must still decide what to fix first and how to implement changes.
Refactoring and planning
A planning component can:
- Consolidate findings,
- Remove duplicate recommendations,
- Prioritize issues,
- Evaluate impact versus effort, and
- Provide implementation guidance.
Implementation support
Implementation-focused agents may:
- Suggest refactorings,
- Generate code recommendations,
- Track remediation progress, and
- Assist with follow-up work.
However, implementation should remain subject to developer review and approval, particularly for security-sensitive, architectural, or production-impacting changes.
The role of these systems is to help teams discover and organize improvements, not replace engineering judgment.
Running your first multi-agent audit in Code Studio
Getting started with multi-agent governance in Syncfusion Code Studio is straightforward. The idea is simple: create a set of specialized AI auditors, point them at your repository, and let them analyze different aspects of code quality in parallel.
Step 1: Create your AI agents
Start by creating the agents you want to use in the .codestudio/agents/ directory.
Select the Configure Custom Agents option in the chat interface. Create as many agents as required.
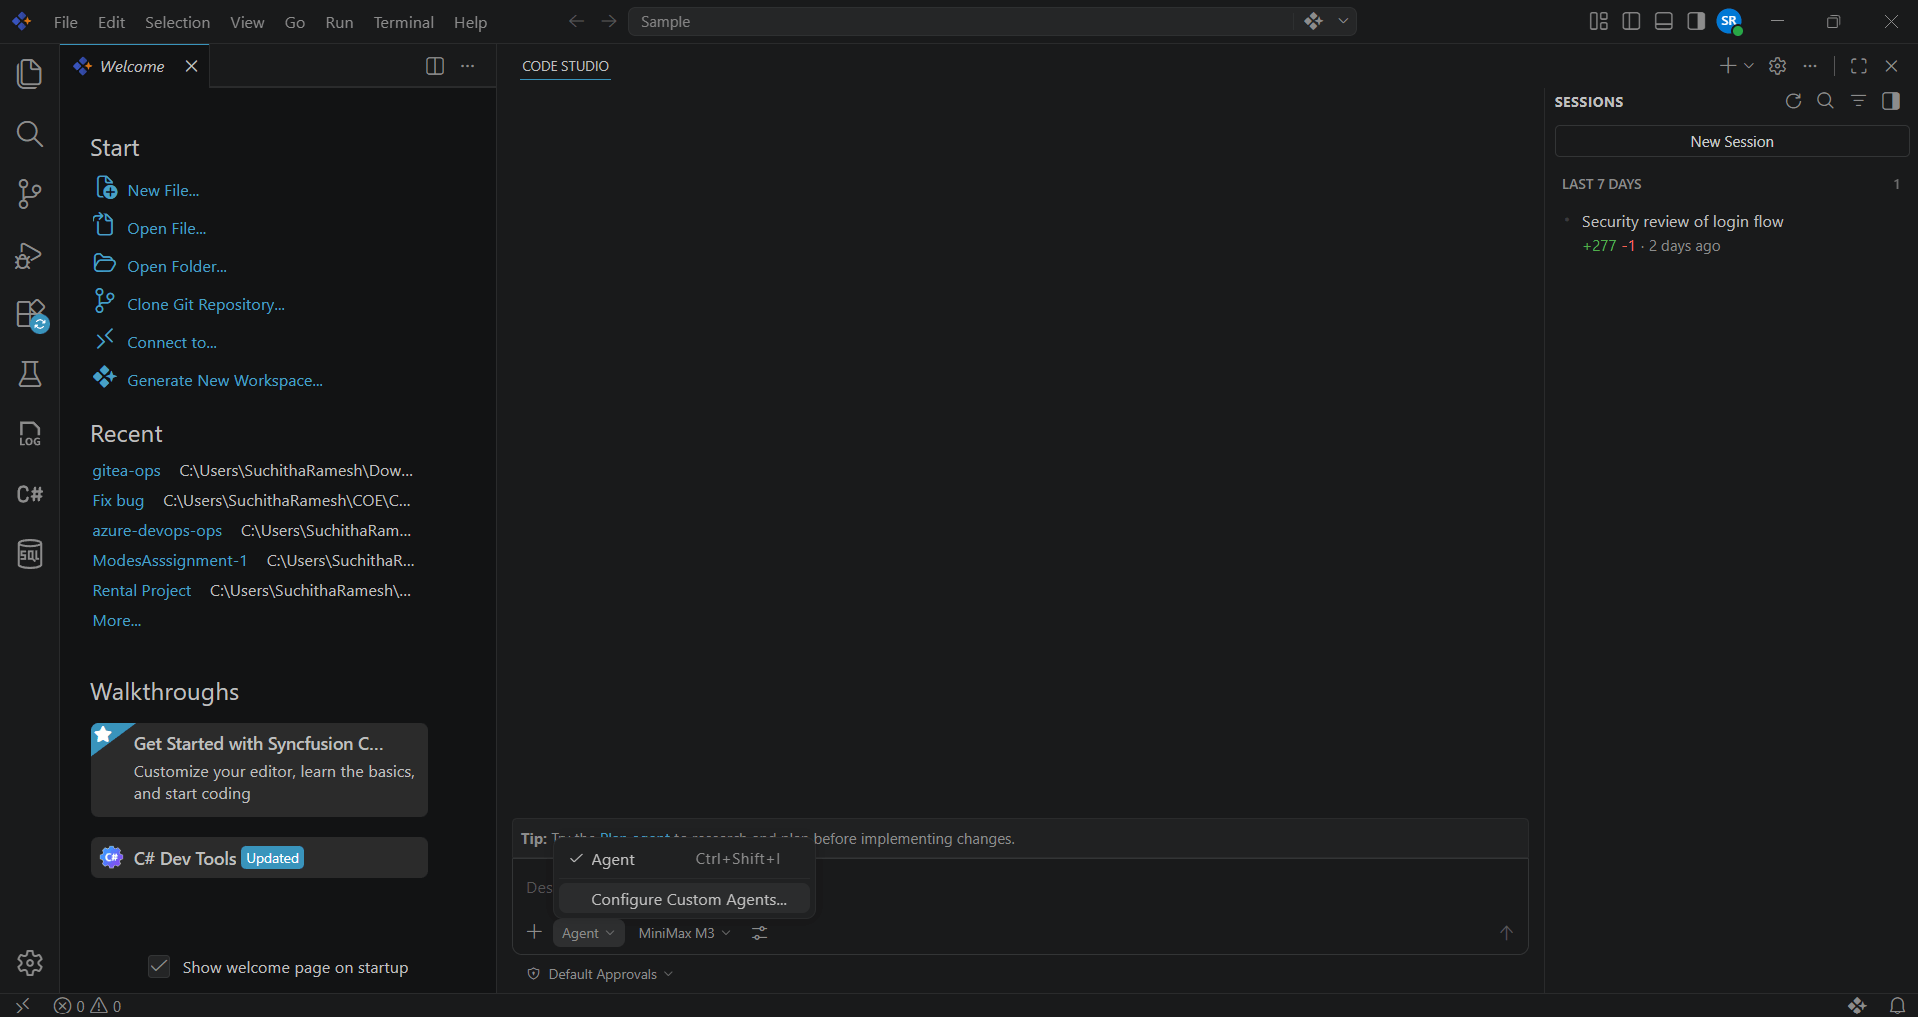
Common examples include:
- Security auditor,
- Architecture auditor,
- Performance auditor,
- Testing auditor, and
- Code quality auditor.
Each agent is defined using a simple Markdown configuration that describes its purpose and responsibilities.
Multi-agent AI systems allow each auditor to focus on a specific area, resulting in more comprehensive and actionable insights than a single general-purpose reviewer.
Step 2: Open your repository in Code Studio
Once your AI auditors are configured, open the repository you want to analyze in Code Studio and verify that your .codestudio/agents/ directory contains the agents you’ve created.
A typical structure might look like:
| .codestudio/ └─ agents/ ├─ security-auditor.md ├─ architecture-auditor.md ├─ performance-auditor.md └─ testing-auditor.md |
This directory acts as the discovery point for your audit configuration.
When an audit begins, Code Studio automatically identifies the available agents and invokes them based on their defined responsibilities. By organizing agents this way, you can easily customize the analysis for different repositories.
For example, a security-focused project might use additional security auditors, while a large enterprise application may include agents for architecture, maintainability, and DevOps reviews.
Step 3: Run a repository-wide audit
With your agents configured and repository ready, it’s time to let them get to work.
Run the following prompt in the Code Studio chat window:
Run full audit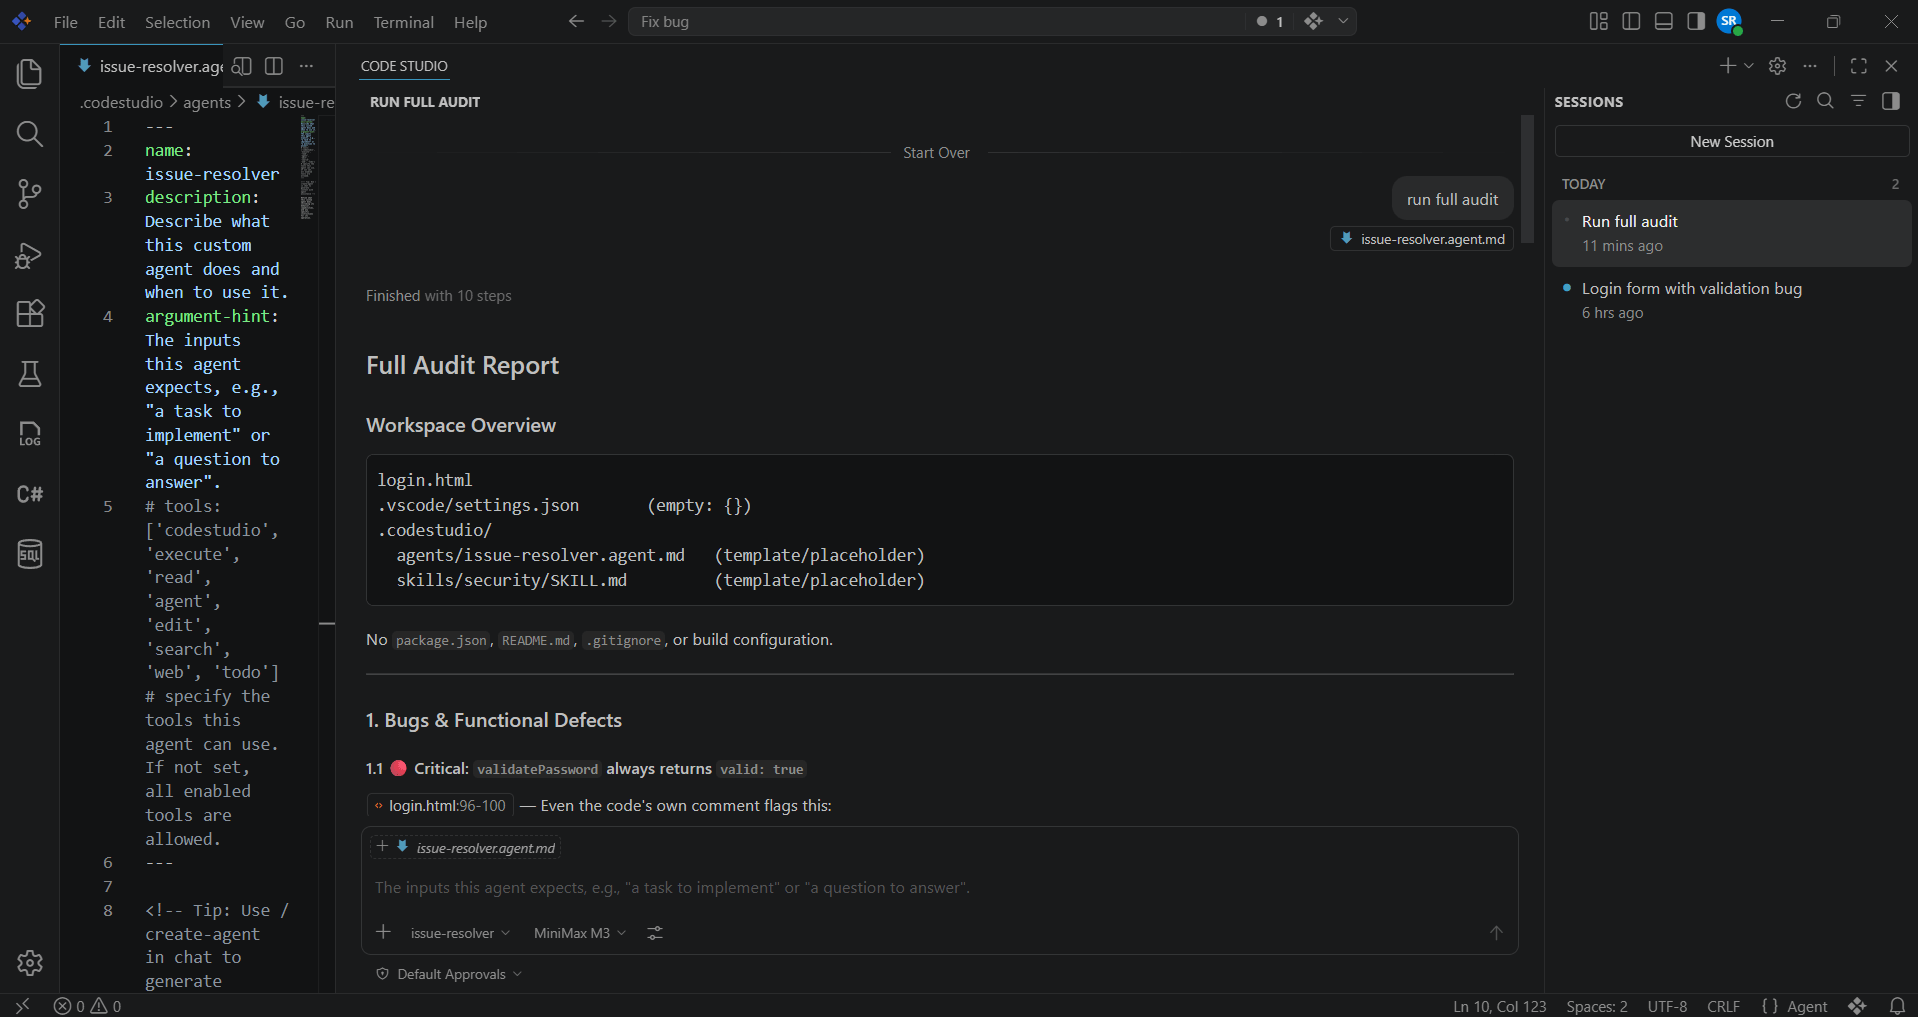
For larger repositories, you can speed up the analysis by running agents in parallel:
Run full audit --parallelThis launches all configured auditors and begins analyzing your repository across multiple areas, including architecture, security, performance, testing, maintainability, and code quality.
Rather than reviewing the codebase from a single perspective, each specialized agent focuses on its own domain and reports findings independently. This allows teams to uncover a broader range of issues in a single audit run, from performance bottlenecks and security risks to architectural concerns and testing gaps.
Step 4: Review the generated reports
After the audit is completed, Code Studio organizes findings into structured reports that help you move from issue discovery to action.
You’ll typically find reports such as:
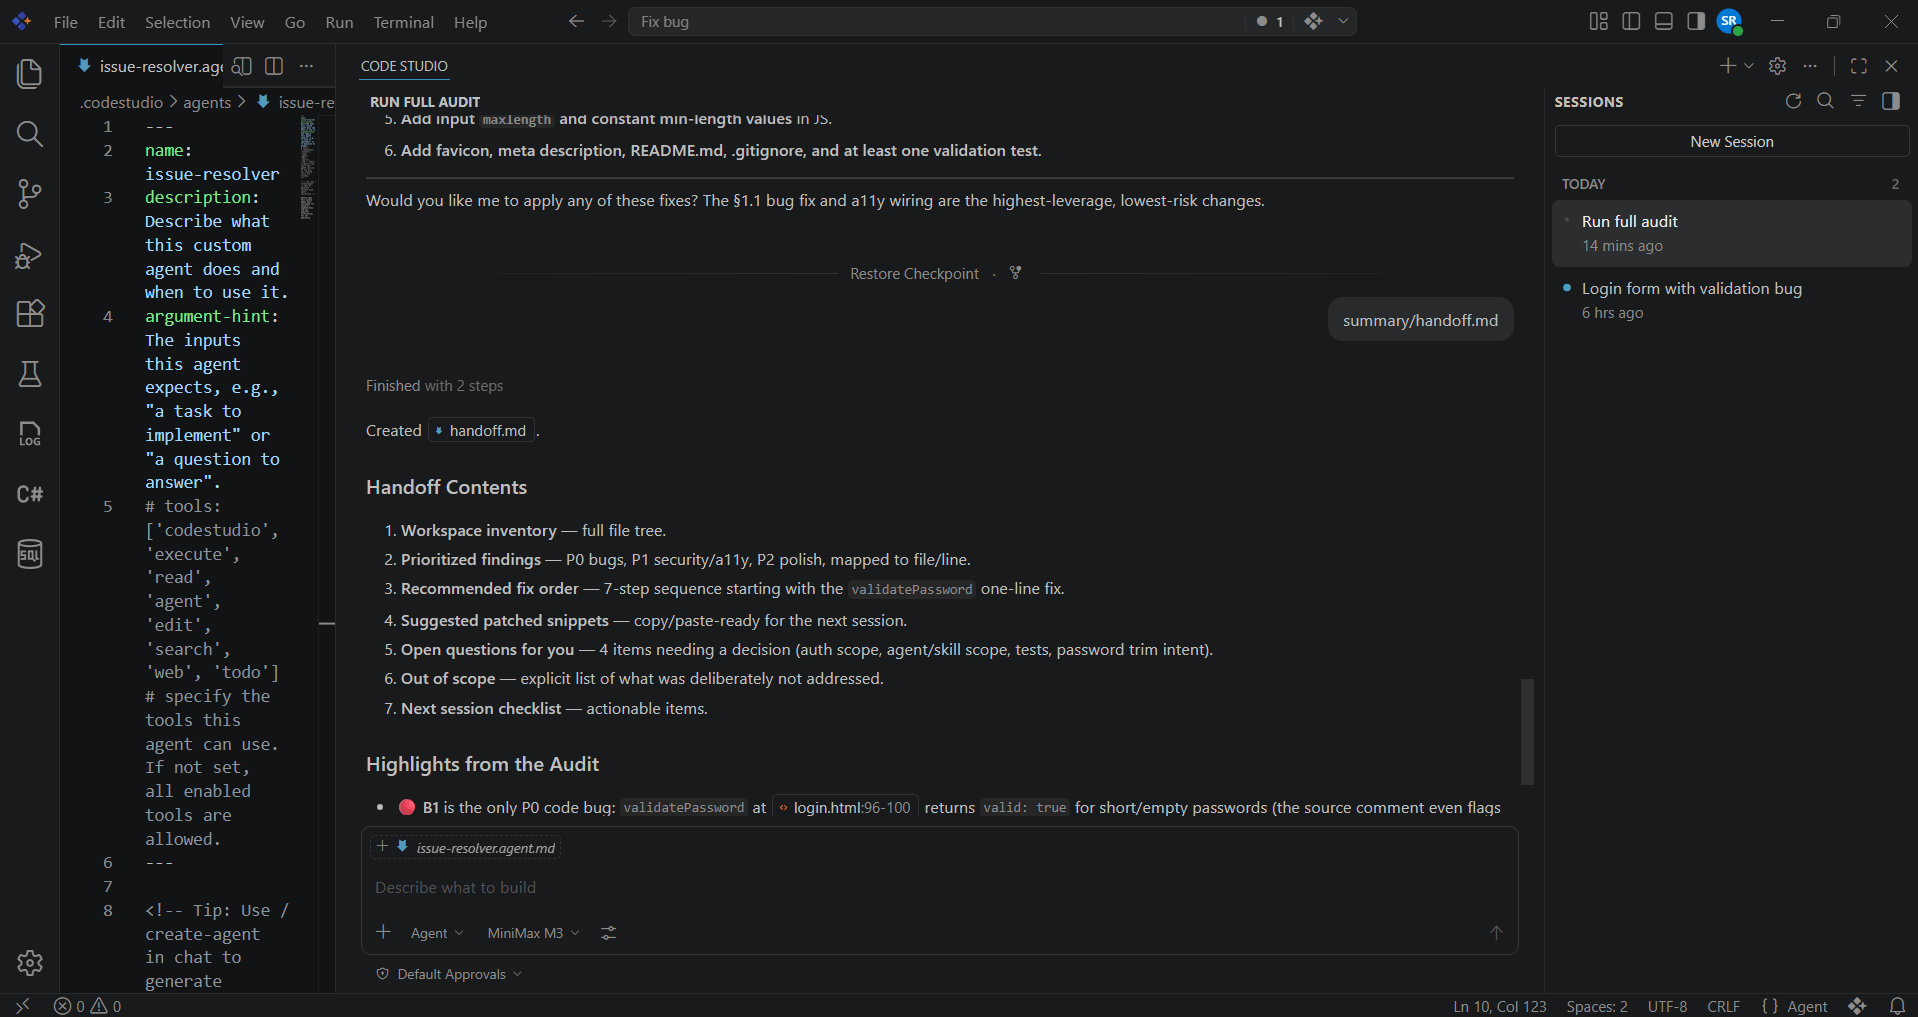
- summary/handoff.md → Overall repository health scorecard and key findings.
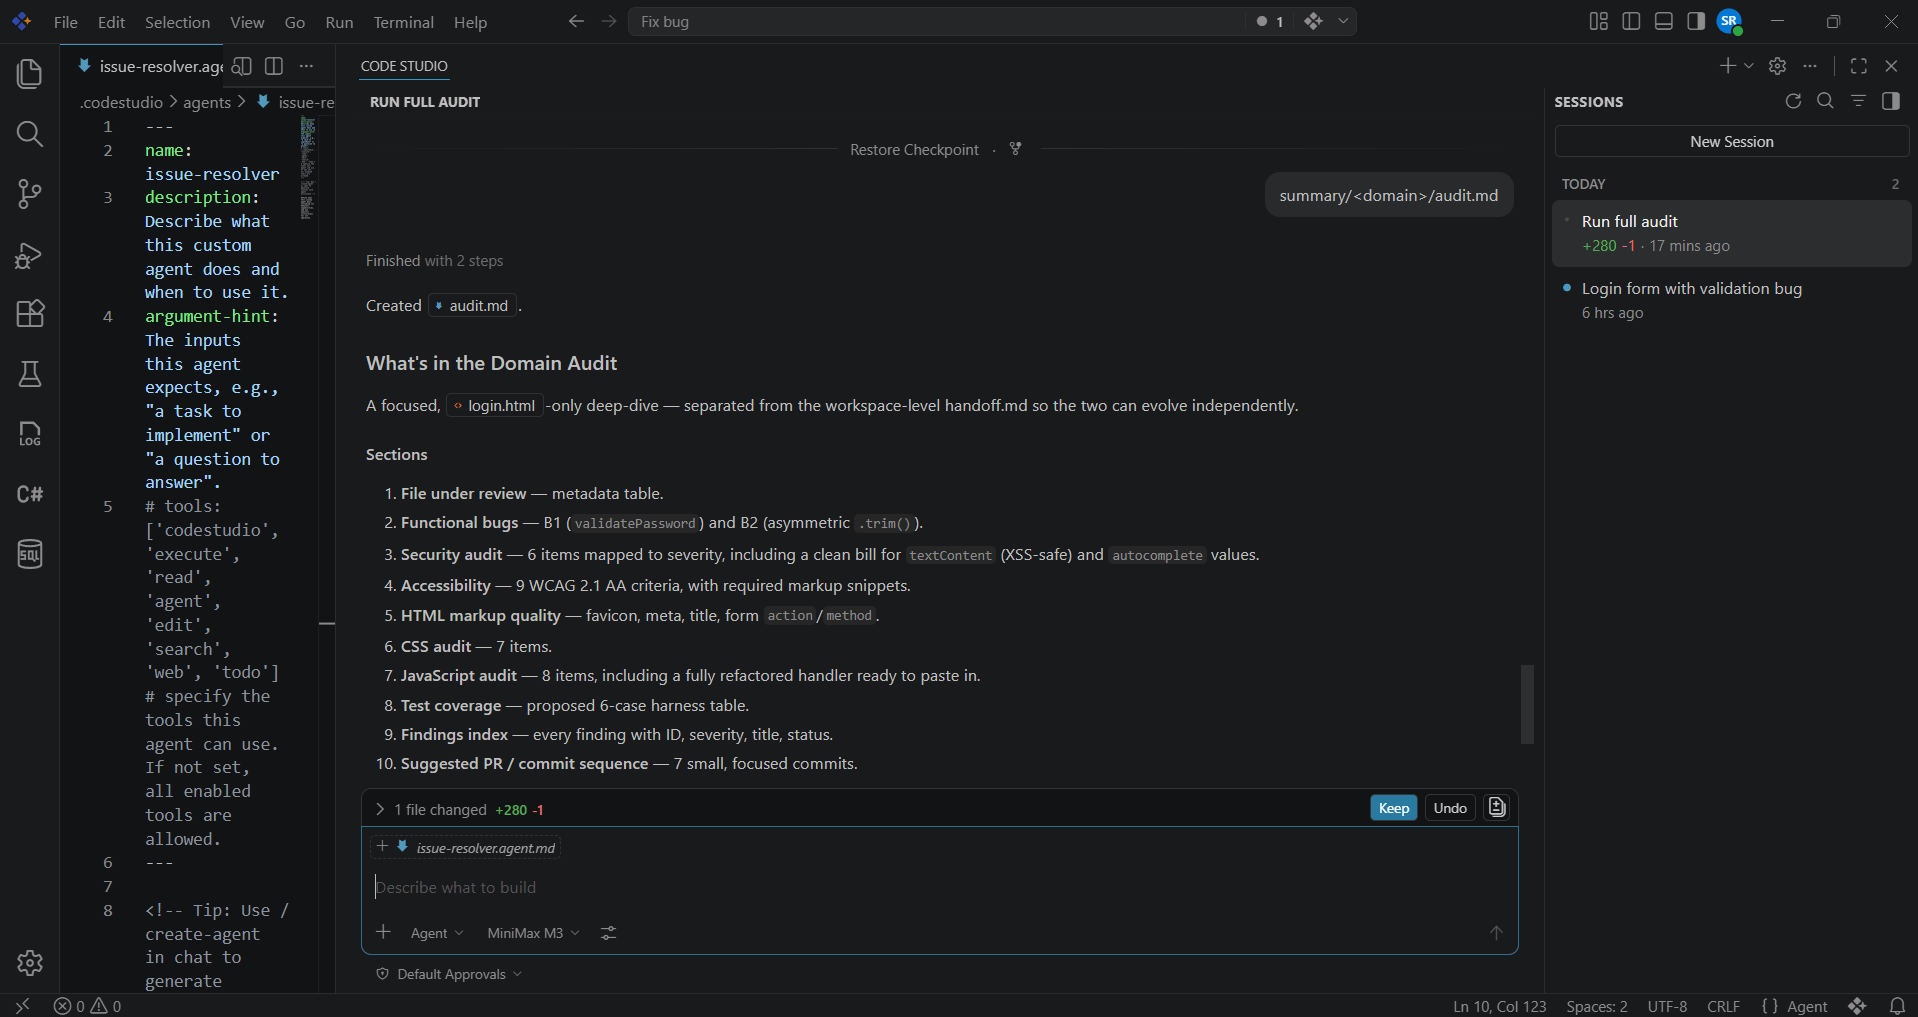
- summary/<domain>/audit.md → Detailed analysis and identified issues.
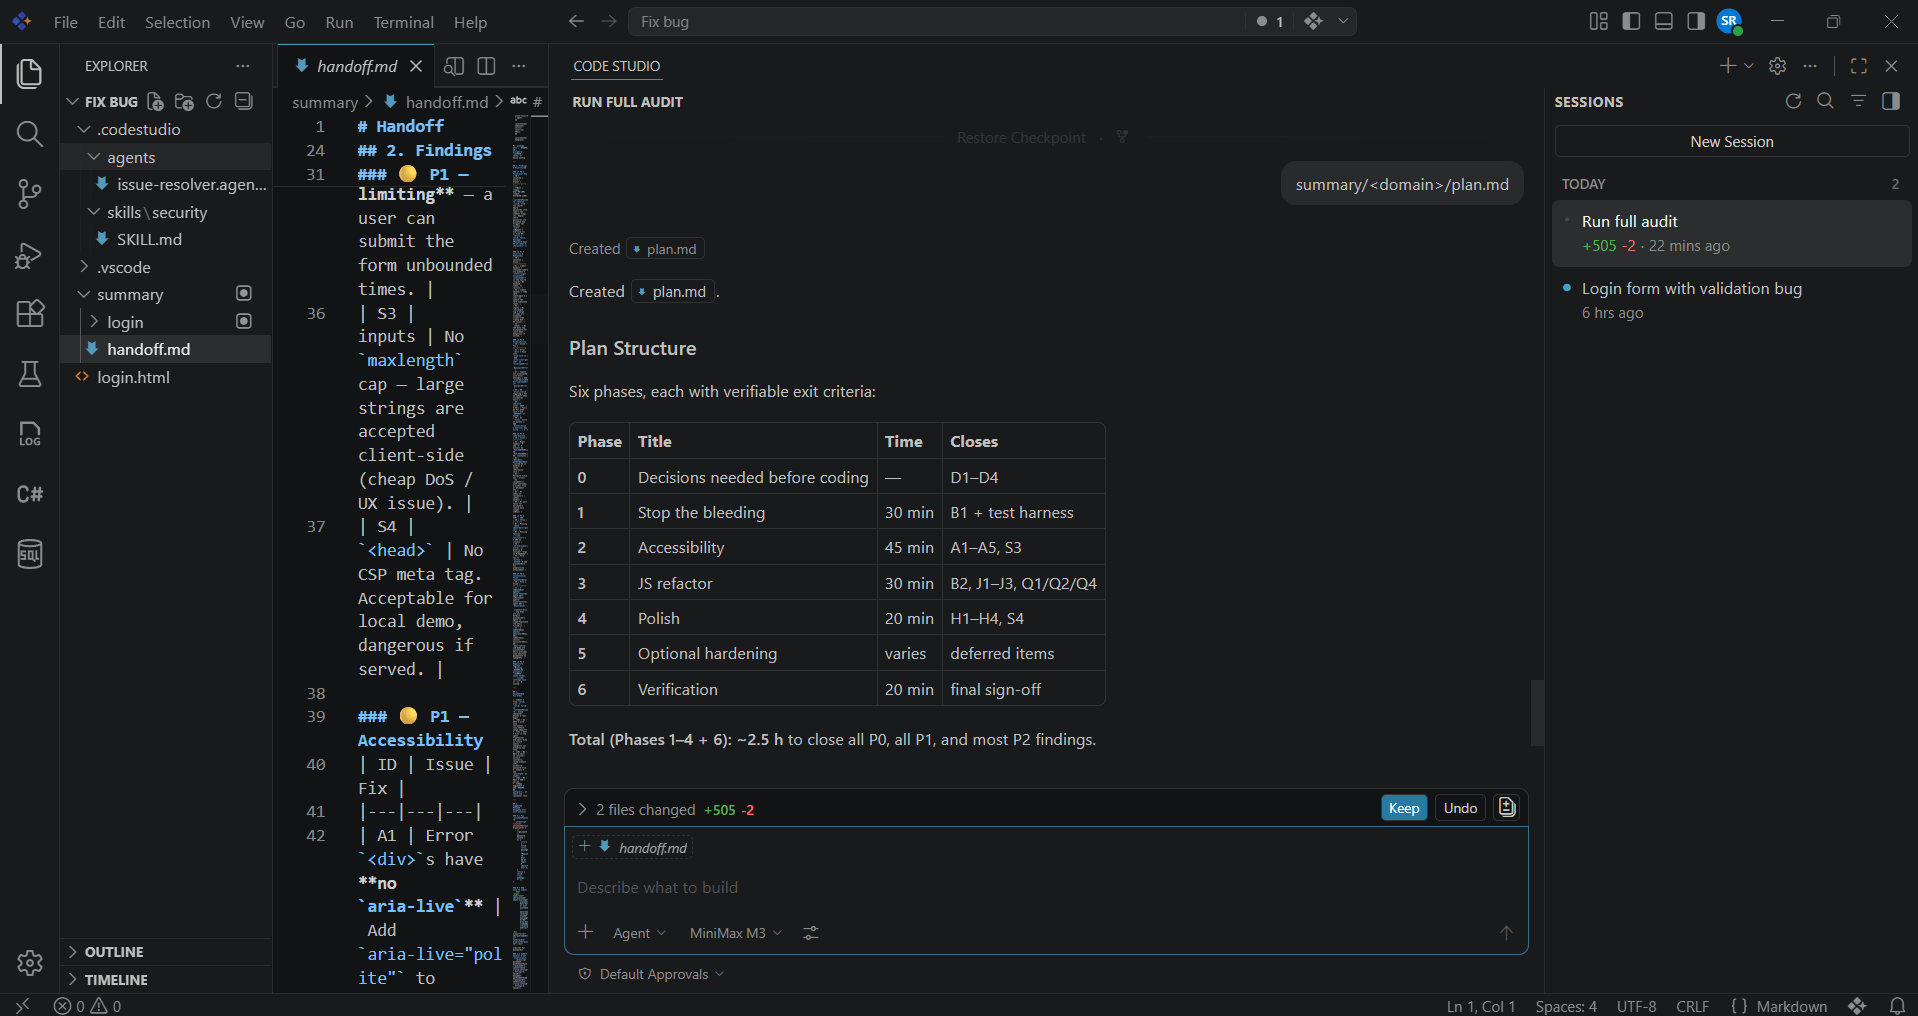
- summary/<domain>/plan.md → Recommended fixes and improvement priorities.
- summary/<domain>/progress.md → Implementation status and tracking.
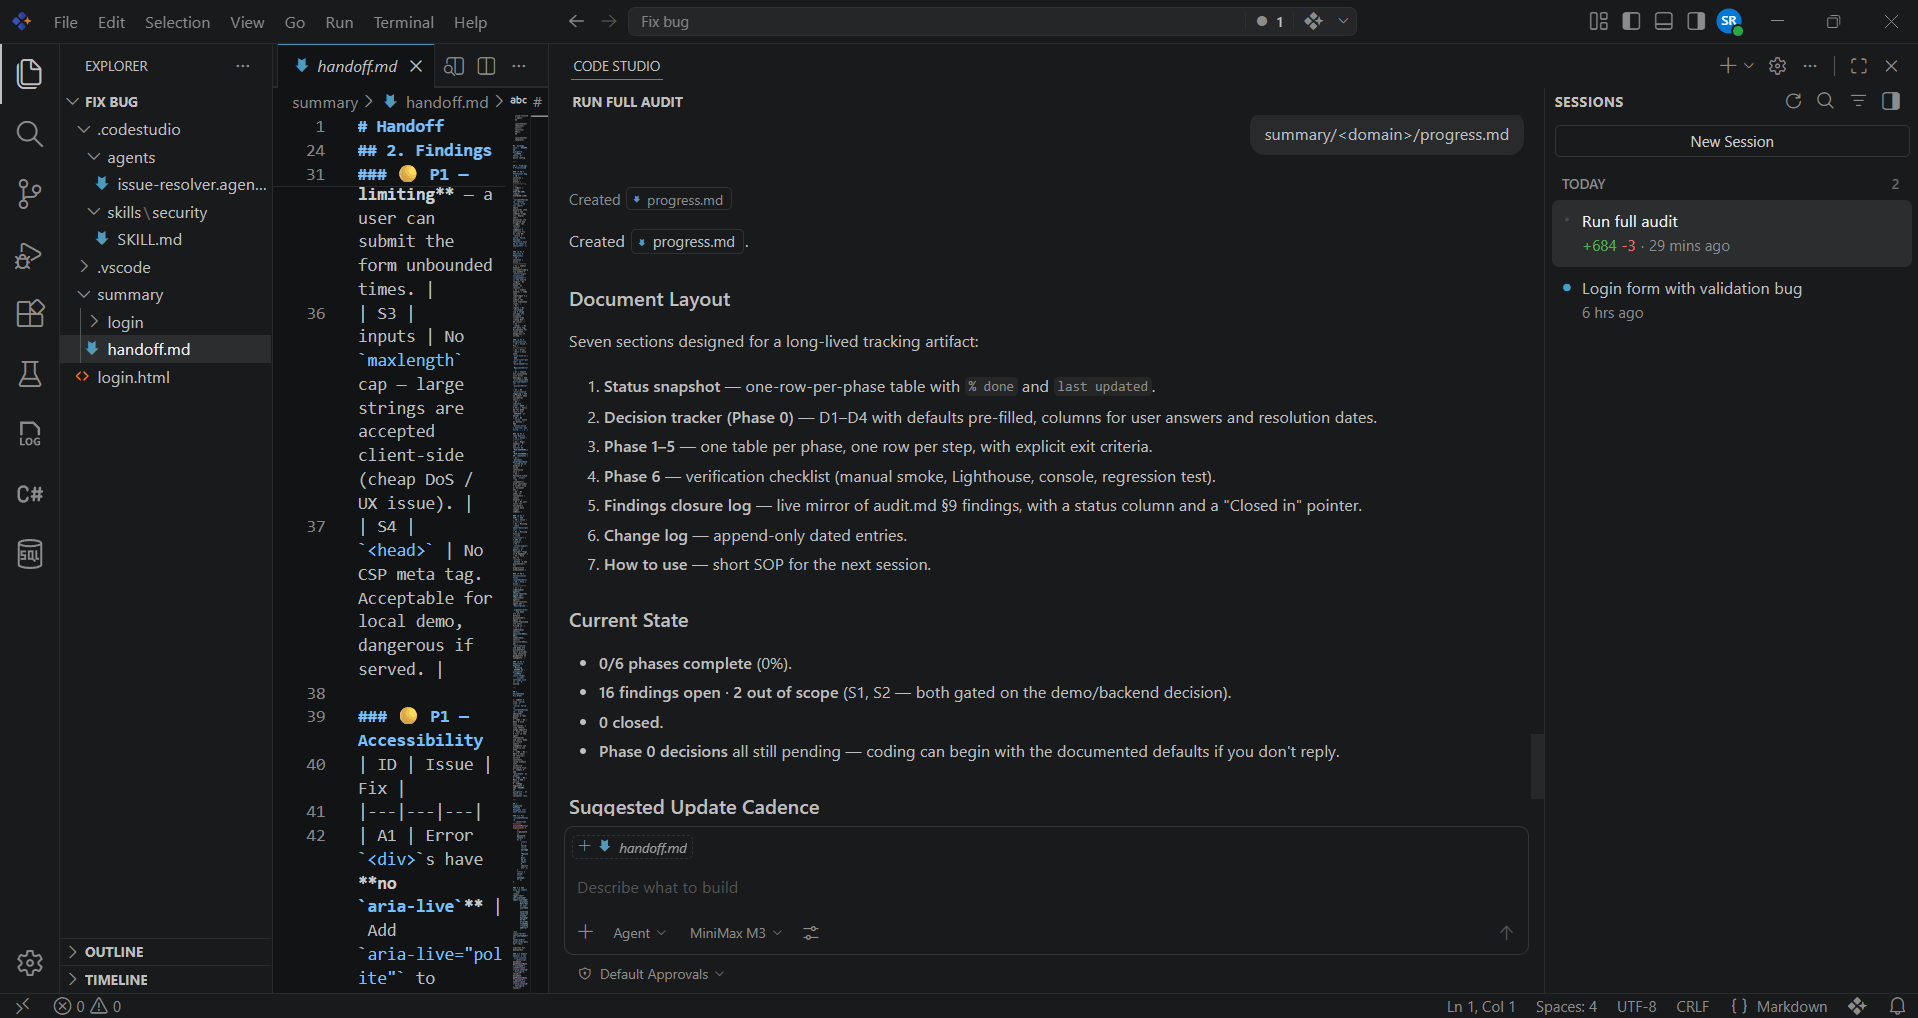
Rather than presenting a long list of isolated warnings, these reports provide context around each finding, including where it exists, why it matters, and what steps should be taken next.
Step 5: Prioritize and implement improvements
Finding issues is valuable, but the real impact comes from addressing the right ones first.
Use the generated plans to prioritize improvements based on risk, business impact, and implementation effort. Common starting points include:
- Fixing critical security vulnerabilities,
- Addressing architectural bottlenecks,
- Improving test coverage in high-risk areas, and
- Resolving performance and scalability concerns.
A key advantage of multi-agent audits is that they help teams focus on what matters most instead of working through a long, unstructured backlog. By highlighting the highest-impact issues first, engineering teams can make measurable improvements to repository health while reducing long-term technical debt.
With a prioritized plan in place, developers can move confidently from analysis to implementation, ensuring that improvements are not only identified but systematically executed and tracked over time.
Production considerations
Multi-agent systems become more useful when designed thoughtfully.
Important considerations include:
- Context-aware analysis: Agents should focus on areas relevant to the repository being analyzed.
- Duplicate finding management: Overlapping findings should be consolidated to reduce noise.
- Resource efficiency: Large repositories can increase token usage, execution cost, and runtime requirements.
- Customization: Teams often need the ability to align audits with their own engineering standards and governance practices.
- Agent scope: Each agent should have a clearly defined responsibility. Poorly scoped agents often produce overlapping or low-value findings.
- Shared context: Agents need enough repository context to reason effectively without unnecessarily duplicating information across multiple context windows.
- Finding structure: Findings are easier to review when agents return a common structure such as:
-
- Severity,
- Location,
- Finding,
- Evidence,
- Impact, and
- Recommendation.
- Conflict resolution: Different agents may occasionally recommend conflicting actions. For example:
-
- Performance optimization may conflict with maintainability goals.
- Security recommendations may increase operational complexity.
Human review is still required to evaluate trade-offs.
- Confidence levels: AI-generated findings should be treated as recommendations supported by evidence rather than as guaranteed facts.
These design choices often have a significant impact on the usefulness of the final output.
Traditional code analysis vs. multi-agent AI code review
| Traditional analysis | Multi-agent AI audit |
| Rule-based checks | AI-driven reasoning |
| Predefined conditions | Domain-specific analysis |
| Deterministic results | Context-aware recommendations |
| Usually focused on individual issues | Can connect findings across domains |
| Lower computational cost | Potentially higher execution cost |
Multi-agent AI systems are not intended to replace static analysis, security scanners, tests, or human code review.
Instead, they complement these tools by adding broader repository-level reasoning and prioritization.
Where multi-agent code audits deliver value
Multi-agent audits are particularly useful for:
- Large enterprise repositories,
- Multi-service and microservice applications,
- Teams adopting AI-assisted development,
- Security-sensitive software, and
- Organizations with multiple contributors and code owners.
As complexity grows, specialized analysis can become increasingly valuable.
Limitations worth understanding
Multi-agent AI systems are powerful, but they are not replacements for experienced engineers.
Important limitations include:
- AI-generated findings can be incomplete or incorrect.
- Multiple agents may produce conflicting recommendations.
- Large repositories can increase execution costs.
- Security-sensitive changes still require human validation.
- Business and architectural decisions remain human responsibilities.
- Multiple agents can increase token usage and execution costs.
- Broader repository analysis may require additional context management and orchestration.
- More agents do not automatically result in better outcomes.
The purpose of these systems is not to eliminate developers from the process. Their value lies in helping developers spend less time finding problems and more time solving them.
Frequently Asked Questions
A multi-agent AI system uses multiple specialized agents that collaborate to analyze, monitor, or improve a shared environment.
Traditional tools often focus on specific checks in isolation.
Multi-agent systems combine multiple perspectives and help organize findings across different quality domains.
No. They work best as a complement to human reviews by identifying risks and opportunities earlier in the development process.
Yes. They can be particularly useful for large repositories, provided the system uses appropriate scoping, context management, orchestration, and resource controls.
They can assist with technical debt, architectural drift, testing gaps, security risks, performance bottlenecks, and code quality management.
Take control of technical debt with Multi-agent AI systems
Generating code is becoming easier every day. Keeping code secure, maintainable, performant, and aligned with engineering standards remains a growing challenge.
Multi-agent AI systems help address that challenge by enabling specialized analysis across architecture, security, performance, testing, and code quality.
Rather than relying solely on periodic reviews, teams can apply structured repository analysis to identify risks earlier and prioritize improvements more effectively.
As AI-assisted development accelerates, successful teams will increasingly combine faster code generation with stronger code governance practices.
Syncfusion Code Studio allows teams to create specialized AI agents, run repository-wide audits, and turn findings into actionable improvement plans aligned with their engineering standards.
The goal isn’t autonomous code governance. It’s giving engineering teams deeper visibility into repository health and technical debt so they can make smarter decisions at scale.
Ready to see what your repository is really telling you?
Start your free trial or book a demo to explore AI-powered repository audits with Syncfusion Code Studio.