Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162976 stories
·
33 followers

When a GUID Clustered Primary Key Gets Expensive

1 Share

A GUID primary key can solve a real application problem. Making a random GUID the clustered key also makes a storage decision, and that decision deserves its own review. Let’s look at when a GUID clustered primary key starts costing you more than it should.

Imagine an application that creates orders offline and later merges them from several regions. GUIDs let it generate identifiers before connecting to the database, with a negligible risk of collision. That is a good reason to use them.

Then someone writes this:

CREATE TABLE dbo.Orders (
    OrderID uniqueidentifier NOT NULL DEFAULT NEWID()
        PRIMARY KEY,
    CustomerID int NOT NULL
);

On this new table, SQL Server makes the primary key clustered by default. If a clustered index already exists, the default differs. Being explicit avoids the surprise.

Where Does the New Row Go?

The leaf pages of a clustered index contain the table’s rows. SQL Server maintains their logical key order. That does not mean the pages sit in consecutive positions on disk.

An increasing identity value usually sends a new row to the right-hand end of the index. A random value from NEWID() can belong between existing keys.

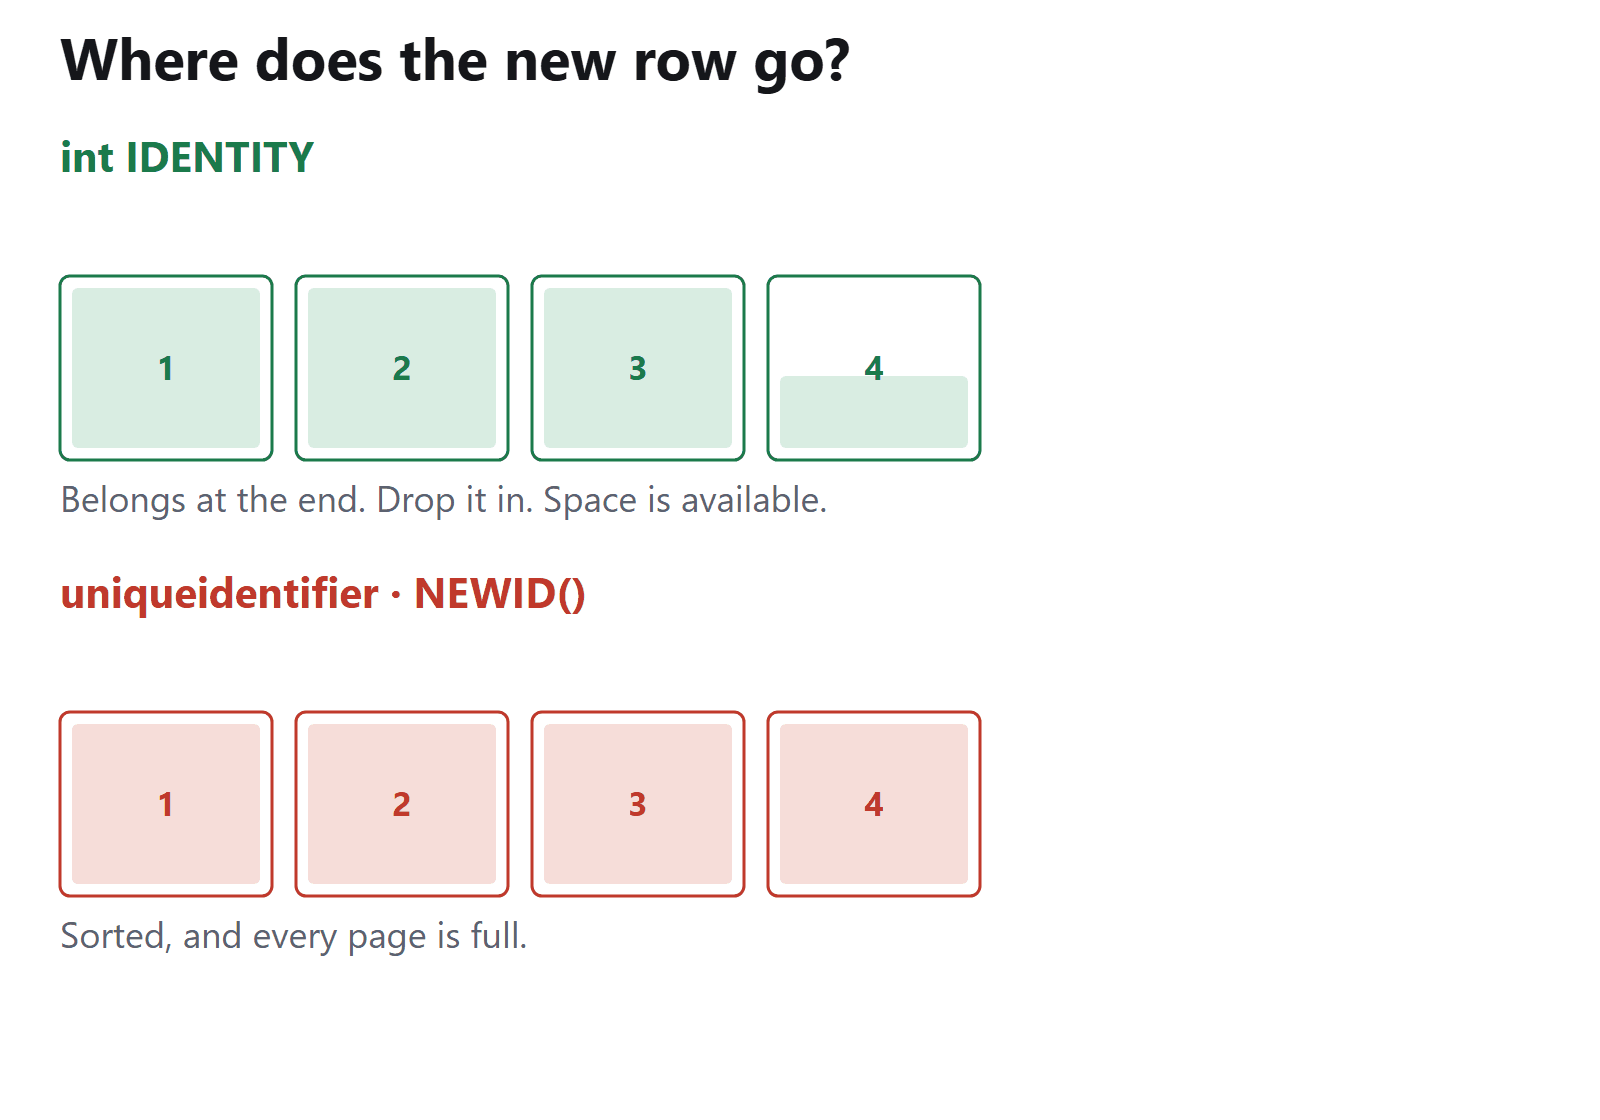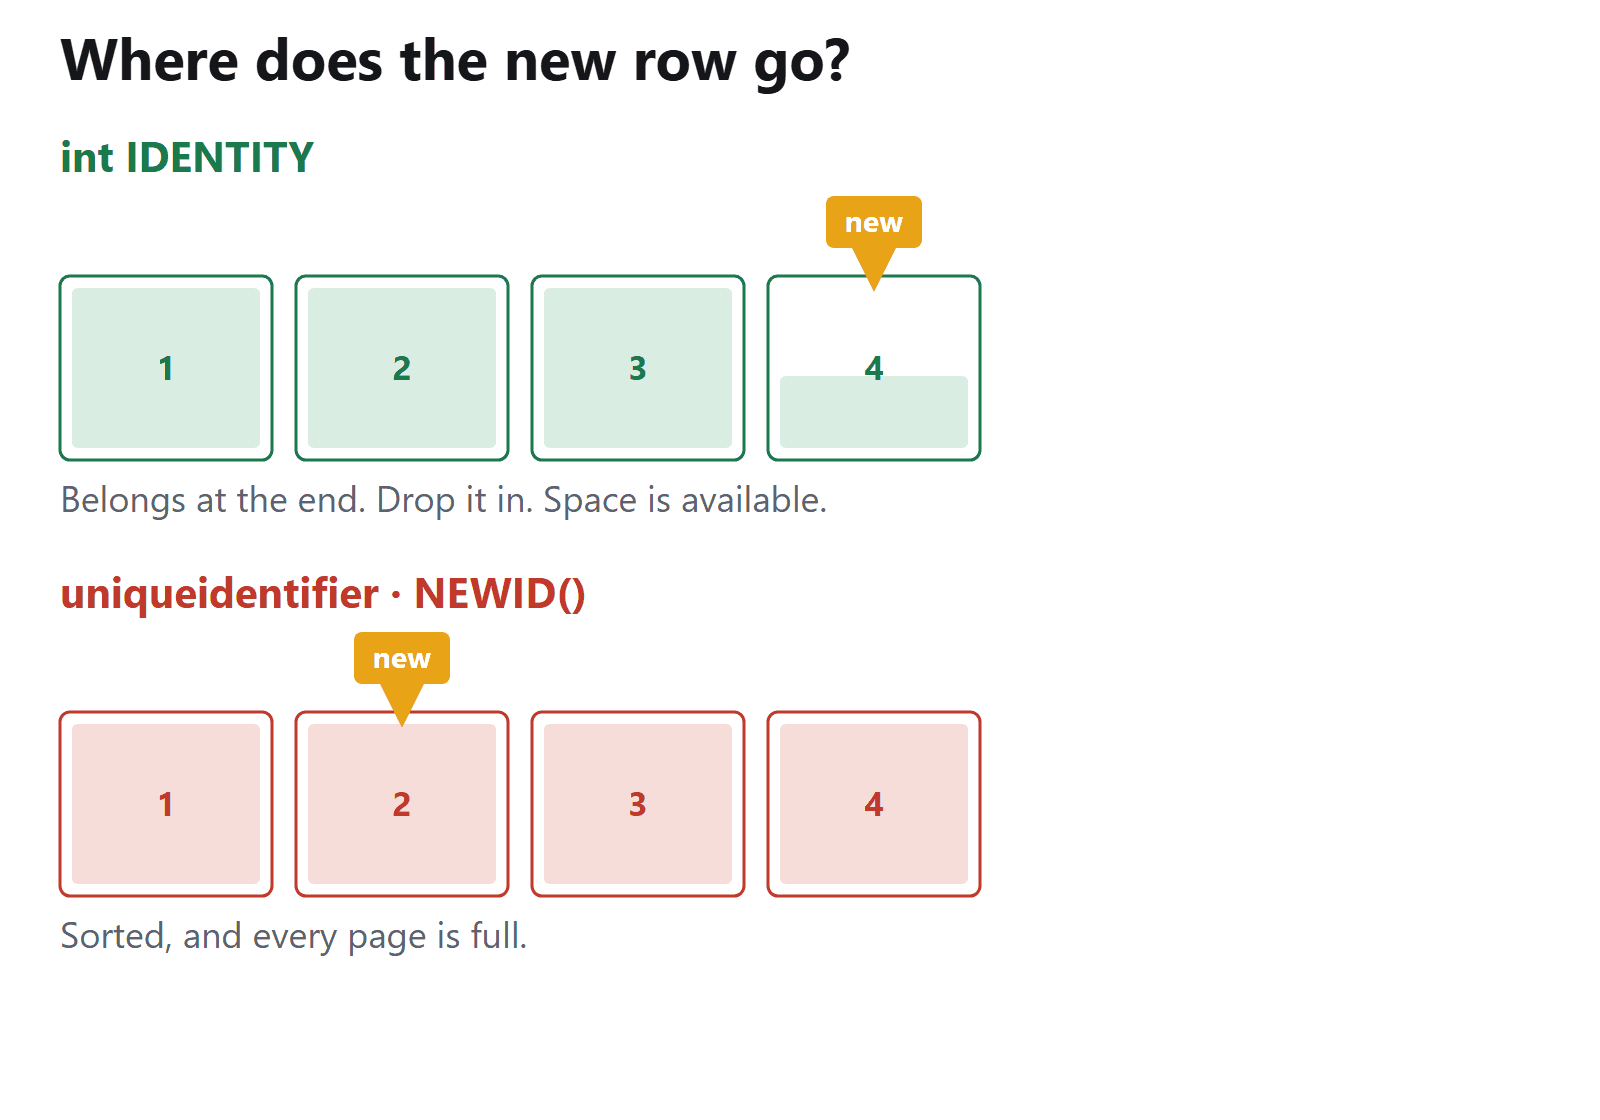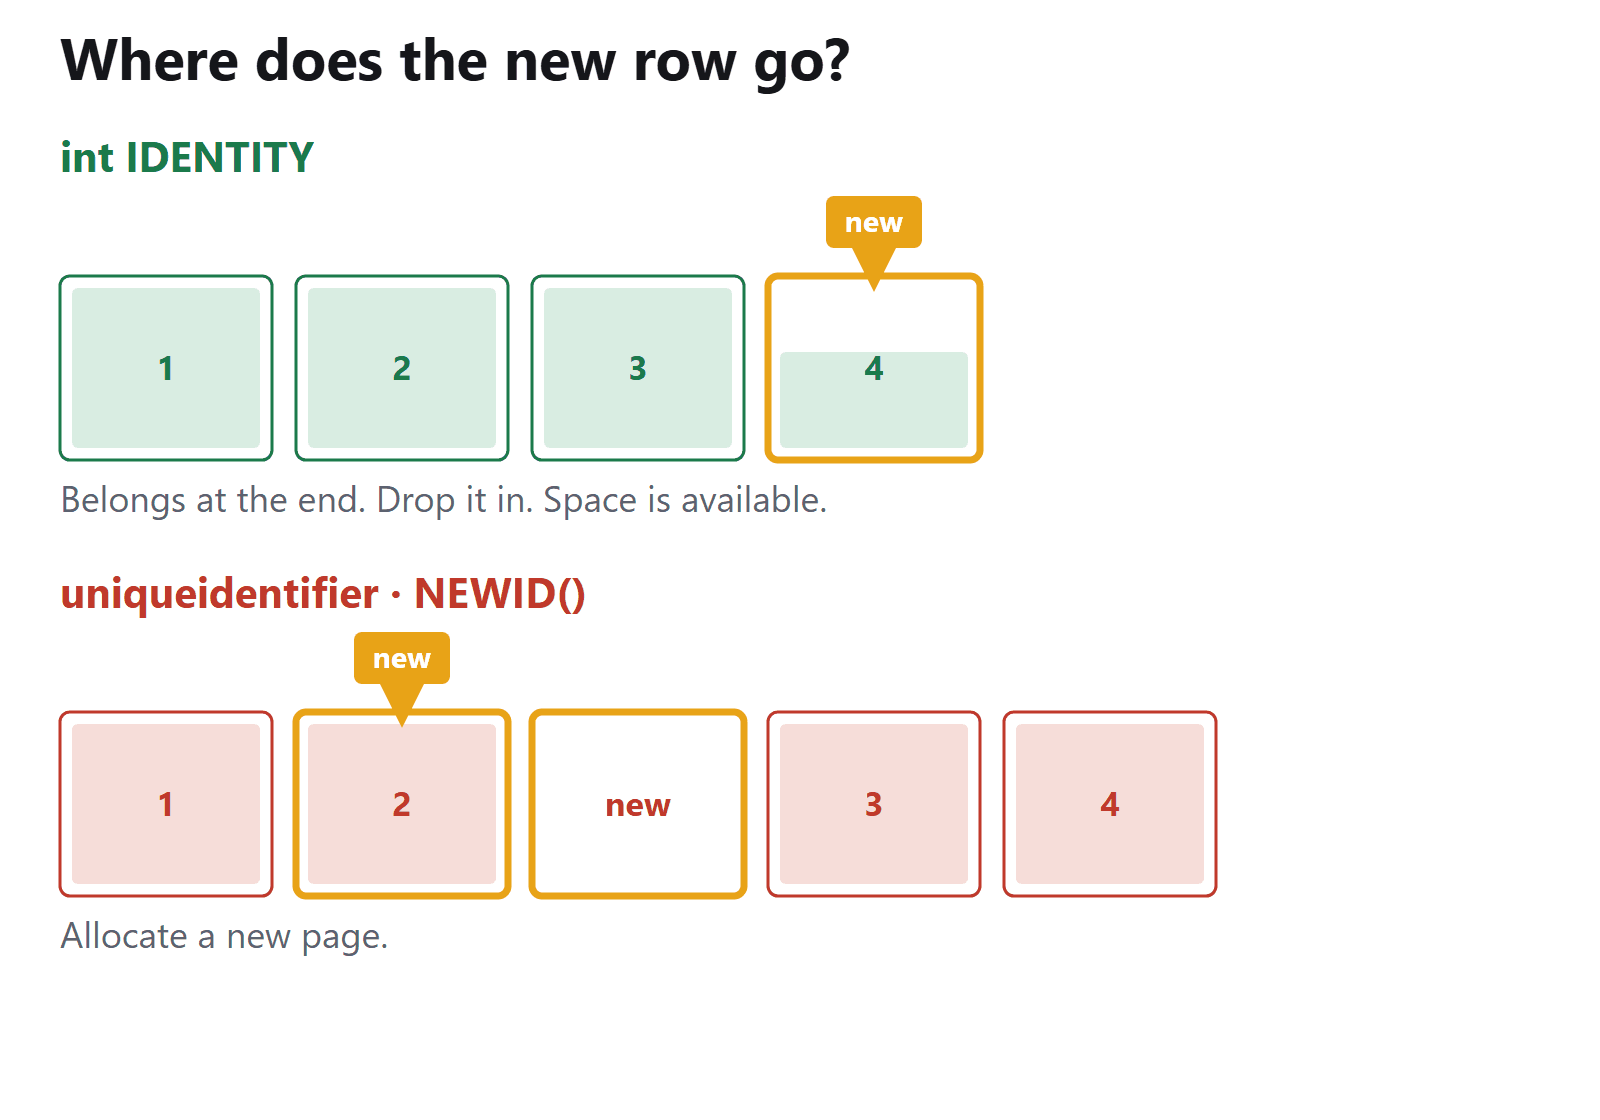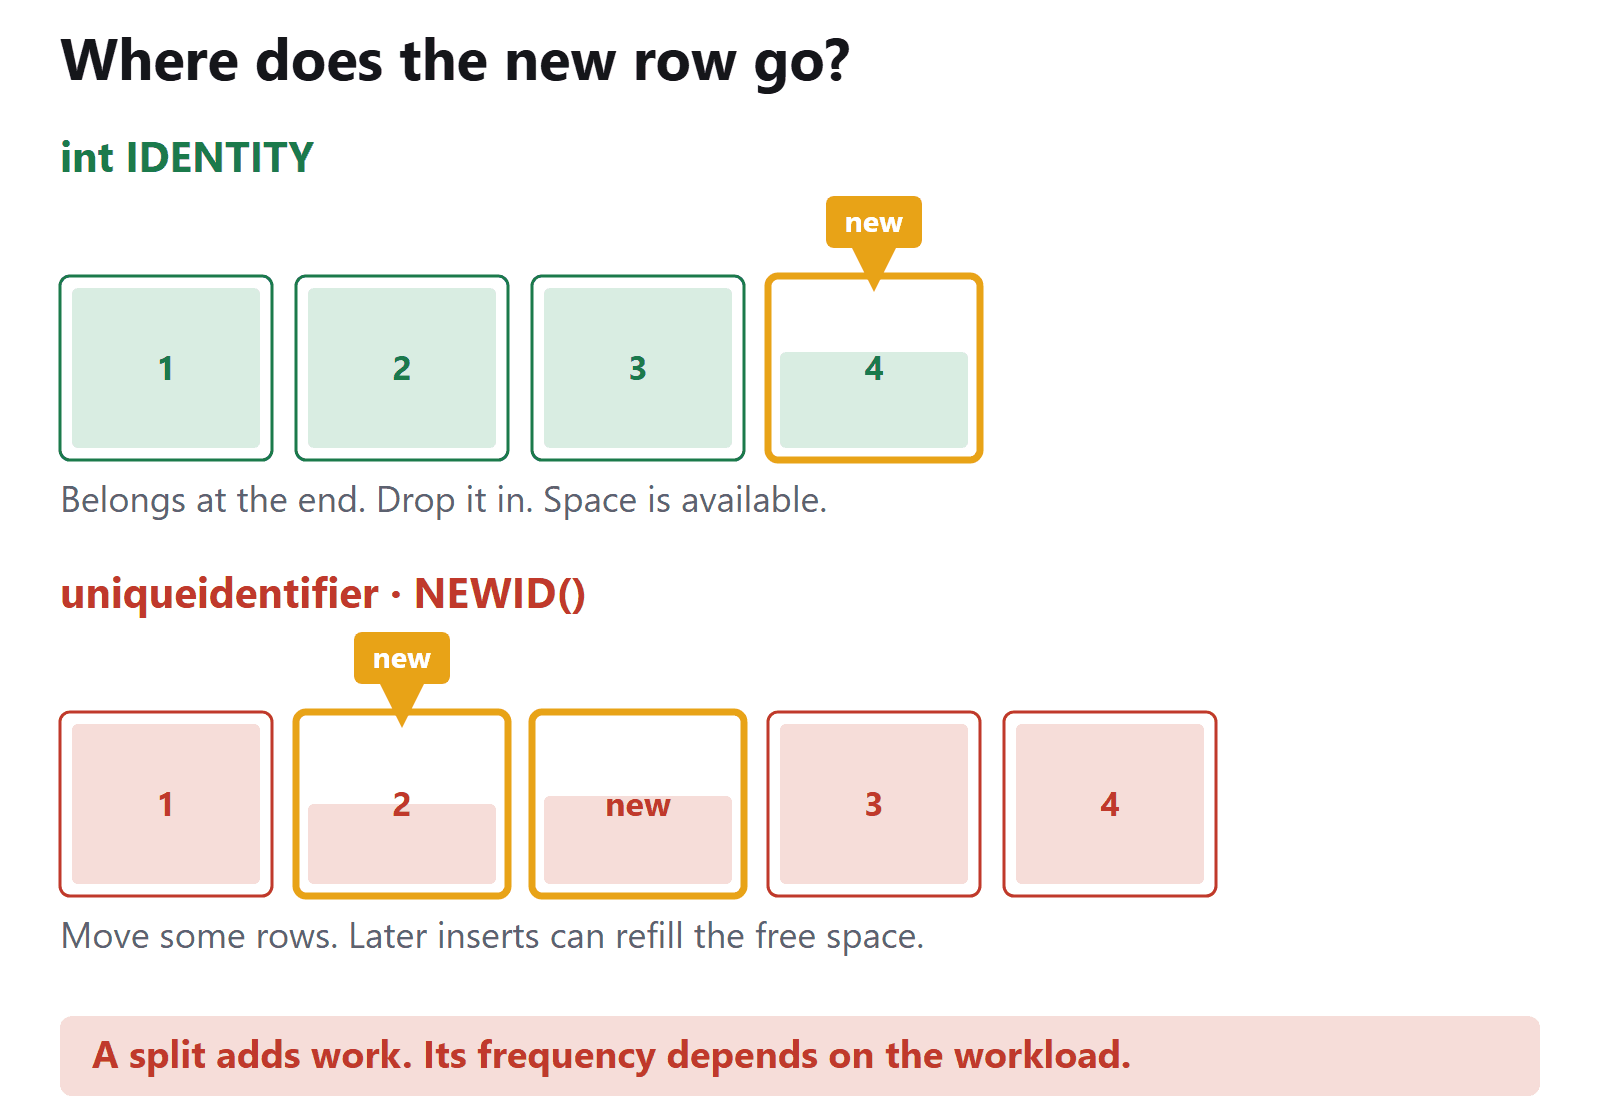
If the destination page has room, the insert fits. If it is full, SQL Server may split it, allocating another page and moving some rows. That creates additional work and transaction log records.

Animation showing a sequential insert using available space and a random insert splitting a full page
A simplified example. Later inserts can fill space left by a split.

Two Costs Worth Checking

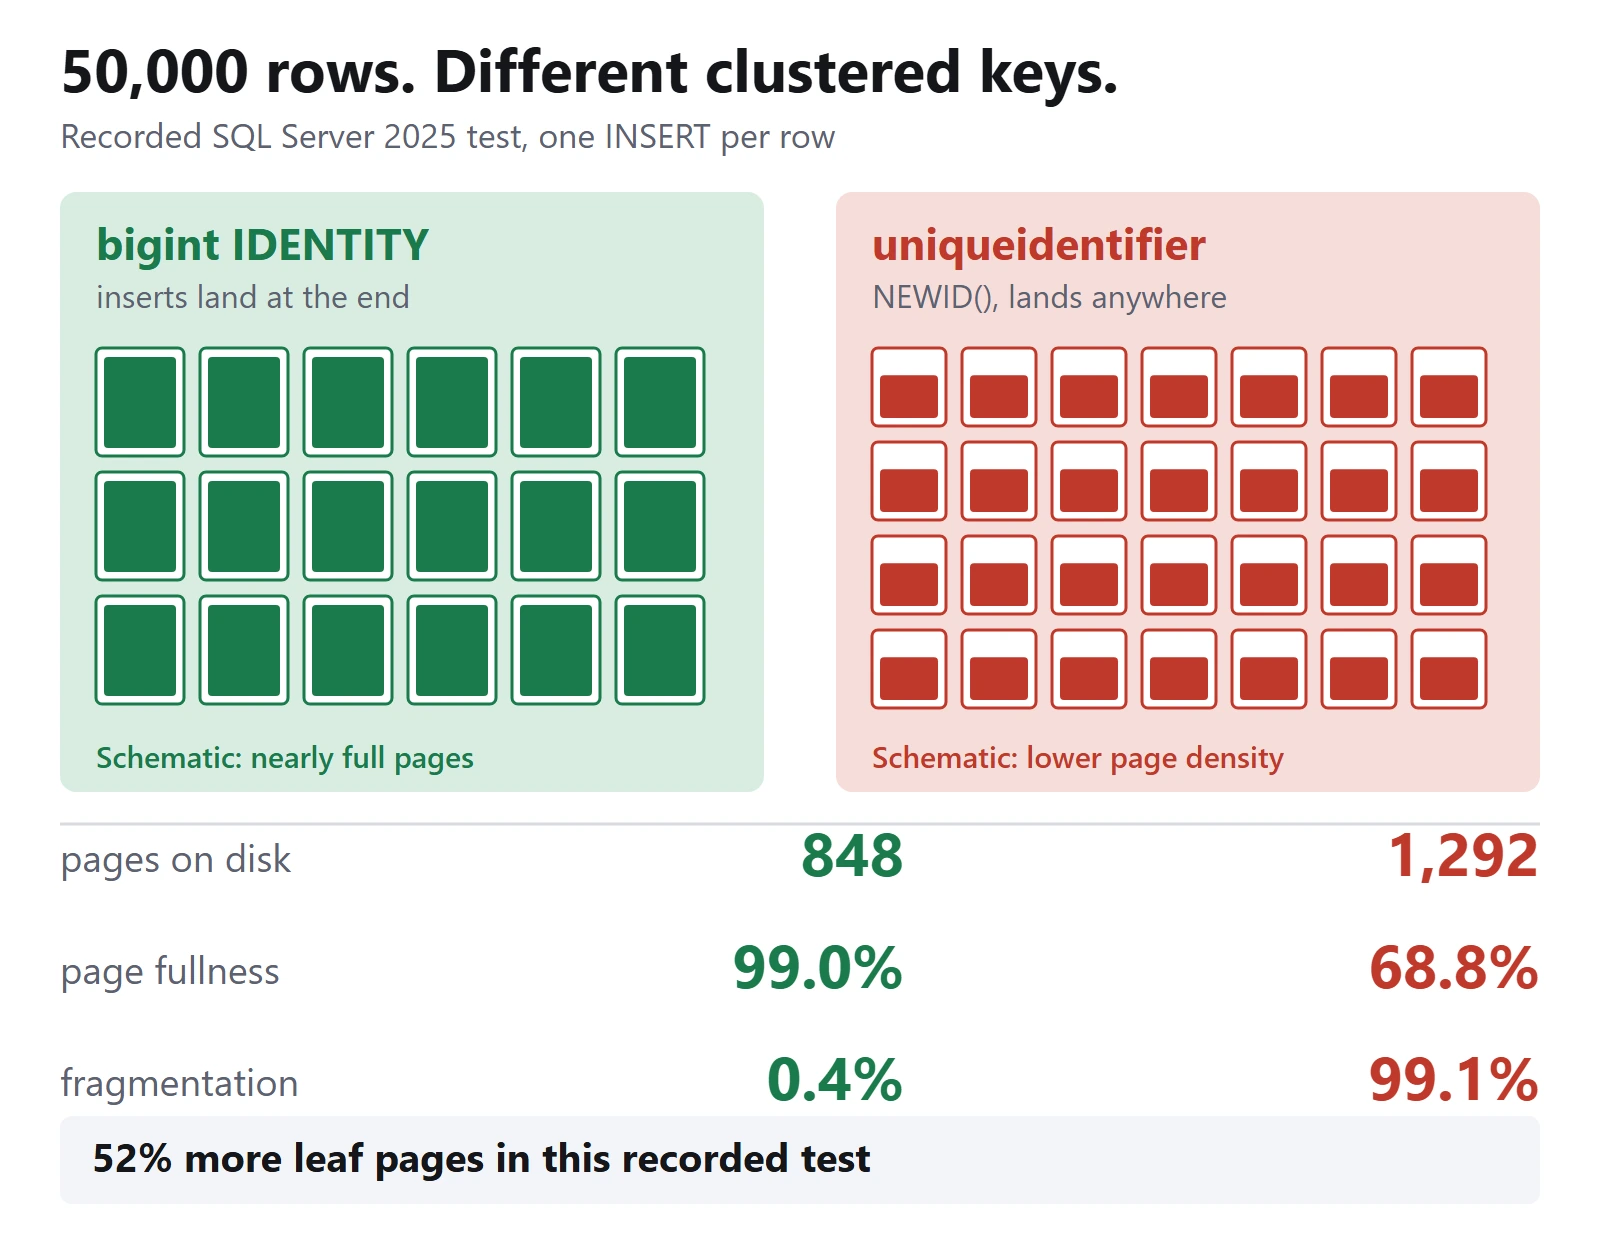
Page density. Splits can leave more free space across the index. Lower density means more pages for the same payload, potentially increasing reads and buffer pool demand. Later inserts can refill that space. The outcome depends on the workload and index maintenance.

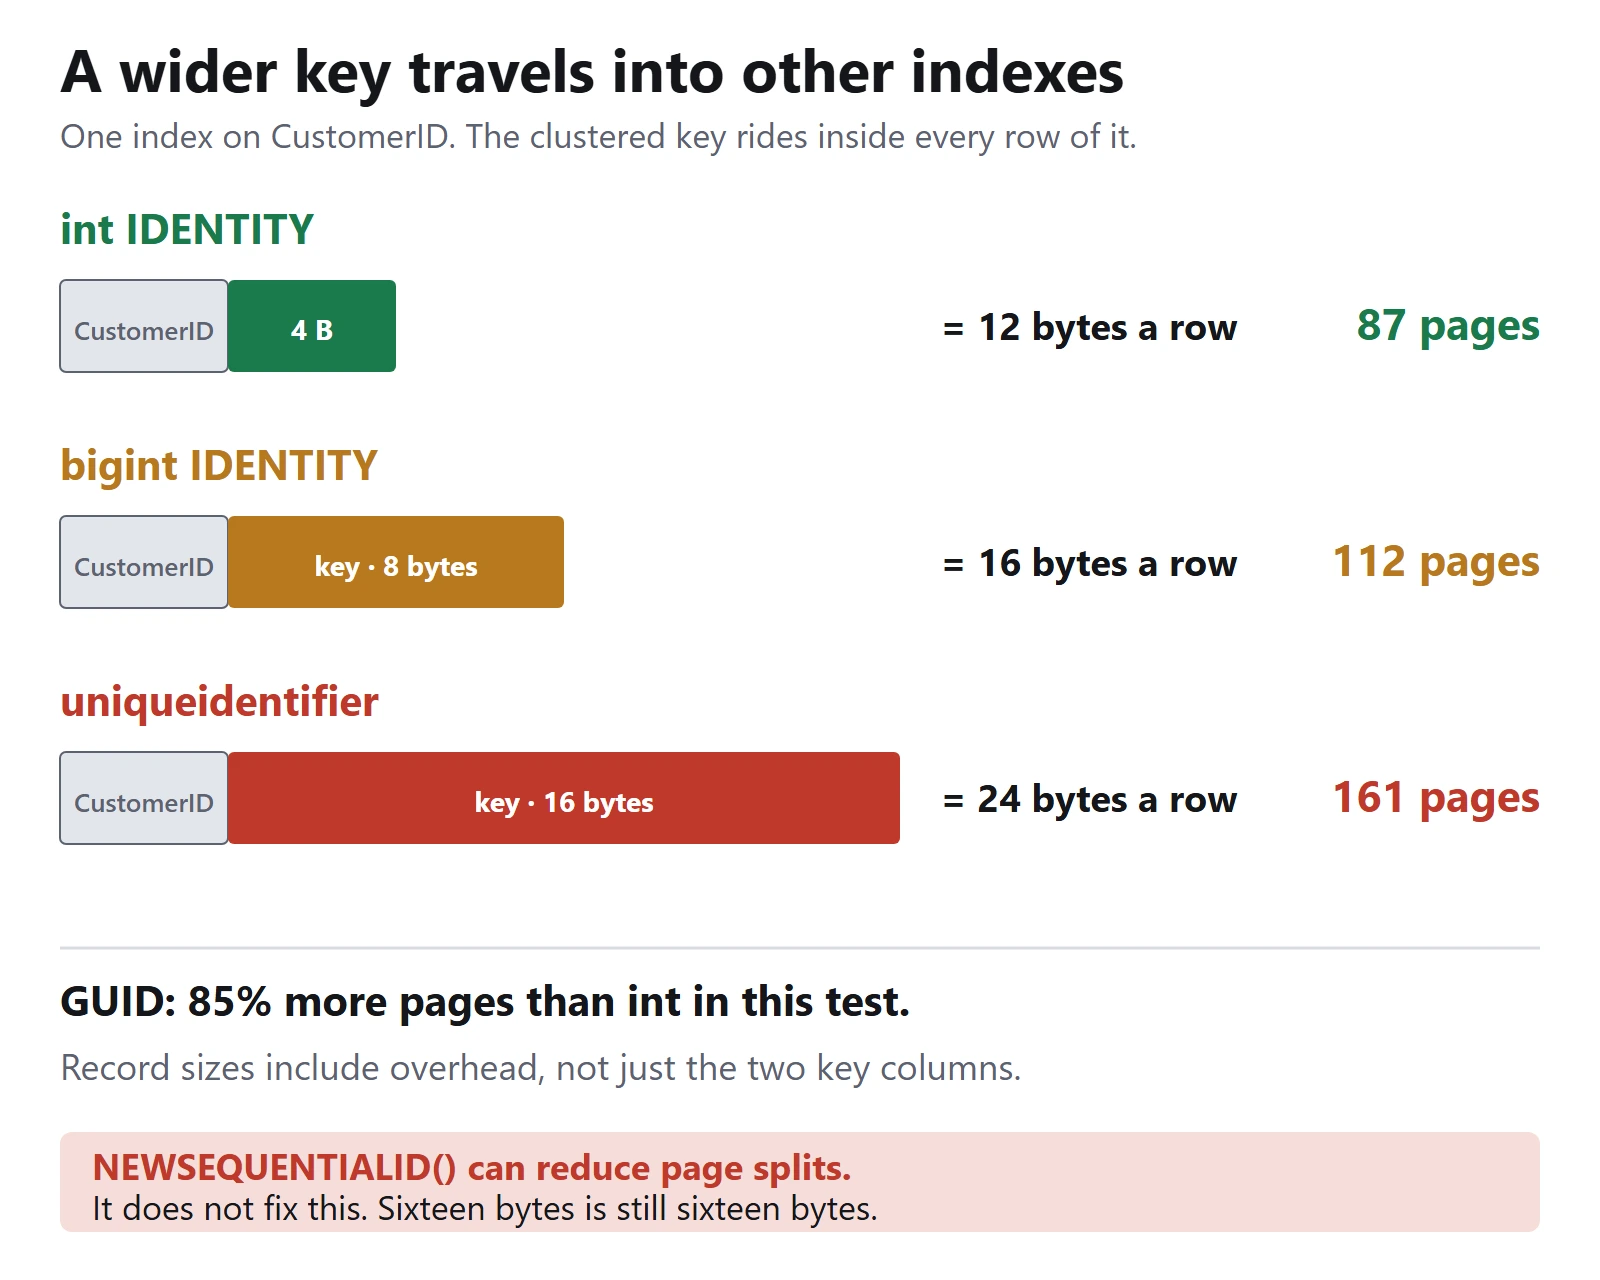
Key width. A GUID takes 16 bytes, compared with 4 for an int and 8 for a bigint. Nonclustered indexes use the clustered key to locate the underlying row. A wider locator can therefore increase their size too, with details depending on each index definition.

Those costs can affect capacity planning. They do not establish a fixed multiplier for your invoice, backup size, restore time, or disaster recovery traffic. Measure those separately.

What the Small Test Shows

The saved test script records 50,000 single-row inserts into three tables on SQL Server 2025. Their business columns match, but their key types differ: int, bigint, and GUID.

In the recorded run, the GUID clustered index used 1,292 leaf pages at 68.8 percent fullness. The bigint version used 848 at 99.0 percent fullness. That is about 52 percent more leaf pages for the GUID version in this test.

Recorded test: bigint used 848 leaf pages at 99 percent fullness; GUID used 1292 at 68.8 percent
One recorded run, not a forecast of production savings.

A nonclustered index on CustomerID used 87 pages with the int clustered key, 112 with bigint, and 161 with GUID. The corresponding index records were 12, 16, and 24 bytes, including record overhead.

Clustered key sizes of 4, 8 and 16 bytes produced CustomerID index page counts of 87, 112 and 161 in the recorded test
The locator’s width matters even when the indexed column stays the same.

Insert times were 9.8, 10.3, and 11.2 seconds respectively. This small, single-session test does not establish a general throughput penalty or isolate every source of overhead.

This is a key-type comparison, not a benchmark of the two-key design below. The bigint test table does not retain a GUID column or its unique index. You cannot use its page count as the expected size after adopting that design.

Keep the GUID, Choose the Clustered Key Separately

When the application needs GUIDs, one option is a separate increasing clustered key:

CREATE TABLE dbo.Orders (
    OrderRowID bigint IDENTITY(1,1) NOT NULL,
    OrderID uniqueidentifier NOT NULL DEFAULT NEWID(),
    CustomerID int NOT NULL,
    CONSTRAINT PK_Orders PRIMARY KEY NONCLUSTERED (OrderID)
);

CREATE UNIQUE CLUSTERED INDEX CX_Orders
    ON dbo.Orders (OrderRowID);

The application can still supply its GUID. The unique bigint index now controls the clustered ordering and provides the locator used by other nonclustered indexes.

This can reduce disruptive random inserts into the table’s clustered pages. It does not eliminate page splits: the GUID primary key remains a random nonclustered index, and updates can also require more space.

There is a tradeoff. You add a bigint column and maintain a separate GUID index. GUID lookups may need an extra lookup into the clustered index. Highly concurrent inserts can also contend for the last page of an increasing index.

Test the complete design with your actual indexes, reads, writes, and concurrency. Compare total allocated space across all indexes, logical reads, and insert latency. Changing an existing clustered index also needs a planned migration, not just this new-table example.

What About NEWSEQUENTIALID()?

NEWSEQUENTIALID() can reduce random insertion and page splits while keeping a GUID clustered key. It still uses 16 bytes.

It works only as a column default, so it does not generate an ID in your offline application. Values can be predictable, and after a restart they can begin in a lower range. Moving or failing over to another computer also affects the sequence. Microsoft documents these limits in its NEWSEQUENTIALID reference.

The Rule Worth Remembering

A primary key enforces row identity. A clustered index organizes the table’s leaf-level storage. You can choose them separately.

Narrow, unique, stable, and increasing are useful clustered-key properties. A random GUID is wide and not increasing, so it misses two of those goals. The SQL Server index design guide explains why those properties matter.

Keep the identifier your application needs. Choose the storage design your workload can justify.

Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

First appeared on When a GUID Clustered Primary Key Gets Expensive

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Why AI Sounds Confident When It’s Wrong

1 Share

Part three of ten. A wrong answer from a model sounds exactly like a right one. That single fact explains most of the damage AI does at work. Here are five interview answers that prove you already know it.

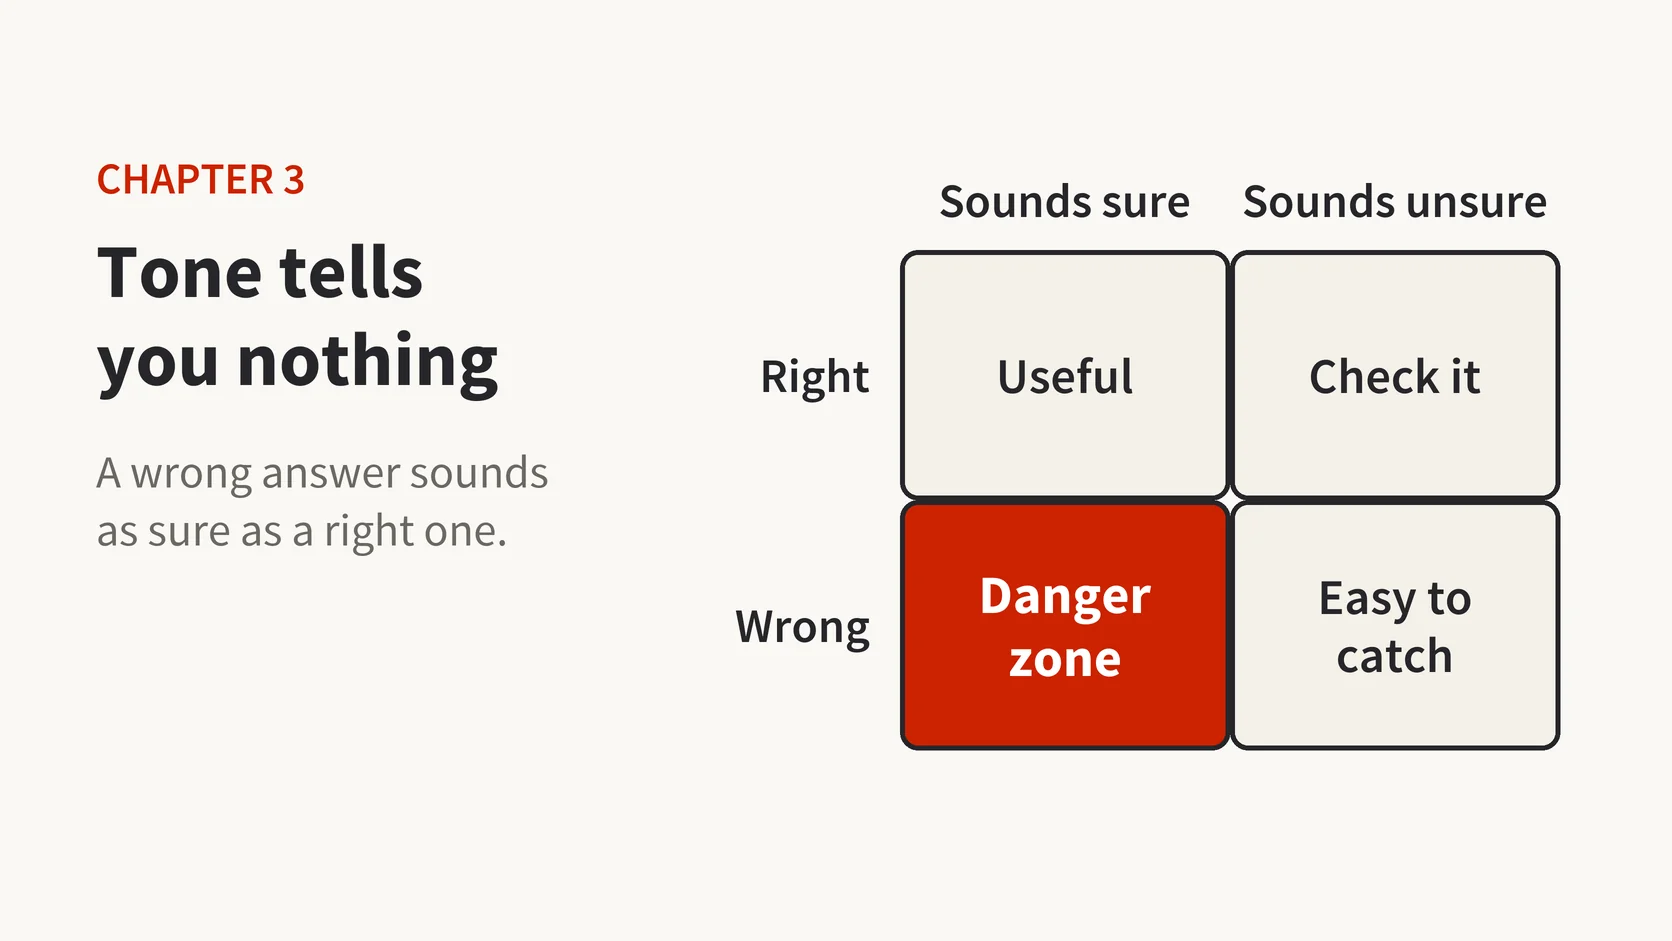
A two by two grid with sounds sure and sounds unsure across the top and right and wrong down the side, with the sure and wrong square marked as the danger zone.

Look at that grid for a second. Three of those four squares are fine. A right answer that sounds sure is useful. A wrong answer that hedges is easy to catch.

The bottom left square is where the money goes. Wrong, and delivered in the same calm voice as everything else. Interviewers know that square exists, and they want to hear that you do too.

Five questions, five answers

These come from chapter 3 of my new book. Each answer is short enough to say out loud in about thirty seconds.

1. What is a hallucination?

A hallucination is an answer that sounds right and contains something the model made up. The model invents a fact, a function or a column name, and states it as plainly as a true one. It happens because the model predicts likely text, and likely isn’t the same as true.

Why it matters. In data work, hallucinations look like real syntax. A made-up function reads fine until the query fails. The worse case is a query that runs and returns believable wrong numbers.

Watch out. Don’t say newer models have fixed it. They make fewer of these mistakes, and none of them is immune.

2. Why does AI sound confident when it’s wrong?

Because the model’s tone isn’t linked to its accuracy. It learned to write the way finished, confident text reads. A wrong answer and a right one come out in the same calm voice.

Why it matters. People trust fluent answers, especially under a deadline. That makes a smooth wrong answer more dangerous than an obviously broken one.

What the interviewer wants. Judging an answer by evidence, not by tone. A line like “I check claims, not confidence” lands well.

3. Why does AI invent table and column names?

Because it knows how databases usually look, not how yours looks. Without your schema in the prompt, it fills gaps with names that are common elsewhere, like CustomerName or Email. The guess is reasonable, and it’s still a guess.

Why it matters. An invented column fails loudly, which is the good case. The bad case is a real column with a different meaning, such as ship date instead of order date.

Watch out. Don’t blame the model alone. If your columns are named col1 and flag2, a new team member would guess wrong too.

4. How do you get a model to say “I don’t know”?

Give it a source and permission to say no. Tell it to answer only from the material, and to say “not in the source” otherwise. Then test it with questions that have no answer.

Why it matters. Most training rewards an answer over a blank, so models learn to guess. Permission to decline, plus a source to check against, changes that.

Watch out. Some models still guess after being told not to. Count how many no-answer test questions come back with a made-up answer, and track that number.

5. How do you check an AI answer quickly?

Find the one claim everything else depends on, and check that first. For a query, run it on a small sample and compare it with a total you already trust. For a fact, look it up in the source. For code, run the tests.

Why it matters. You can’t verify every line of every answer. Checking the part that holds everything up catches the costly errors early.

The follow-up. “What if you can’t check it?” Then don’t use it for anything that matters, or label it clearly as unverified.

Five minutes, any AI assistant

This one is worth doing before your next interview, because you’ll have a story to tell.

Ask your assistant this:

List the columns of the Sales.Customer table in the AdventureWorks2025 sample database. Include the column that holds the customer’s email.

There is no email column in Sales.Customer. The prompt asks for one as if there is, which is exactly how real questions sound.

Watch what comes back. Then ask it: are you sure, and which of these did you check? See whether it corrects itself or defends the answer.

If it was right and then backs down under pressure, you’ve met sycophancy. That has its own question in the book, and senior interviewers love it.

Why this is worth a book

Five answers won’t carry an hour-long interview. Chapter 3 has ten.

The rest of it covers grounding, where bias comes from, and why the same prompt gives different answers. Then two Senior questions: sycophancy in code review, and when not to use AI at all.

What you can’t get from a blog post is the range. Tokens, embeddings, RAG, AI-written SQL, agents, privacy, data quality and the career questions. Each carries the same four parts and the same honest Watch Out.

There’s also a thirty-minute mock interview with scoring at the back. And 184 key terms, so you stop nodding along to words you half know.

100 AI Interview Questions and Answers for Data Professionals is out now. Three formats: Kindle (also on Amazon.in), paperback and audiobook. The Kindle is free to read on Kindle Unlimited.

Part four is about embeddings, and how two sentences with no words in common end up as neighbours.

Confidence is not evidence, it is a writing style the model learned.

Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

First appeared on Why AI Sounds Confident When It’s Wrong

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

From .sqlproj to production: generate a well documented Azure DevOps pipeline for your SQL Database Project

1 Share

Building a .dacpac is the easy part. Getting it deployed to Azure SQL from a pipeline - safely, repeatably, without secrets in variables, and in a way that a reviewer can actually understand before pressing "Approve" - is where most teams lose days. There is no shortage of blog posts and Stack Overflow answers covering one of the pieces, but you have to assemble the whole puzzle yourself, and the pieces that are easy to forget are exactly the ones that fail at 2 AM.

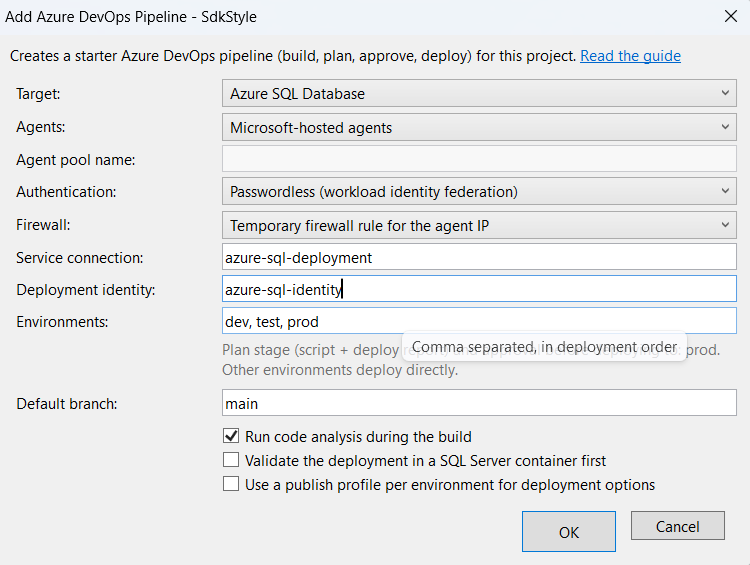
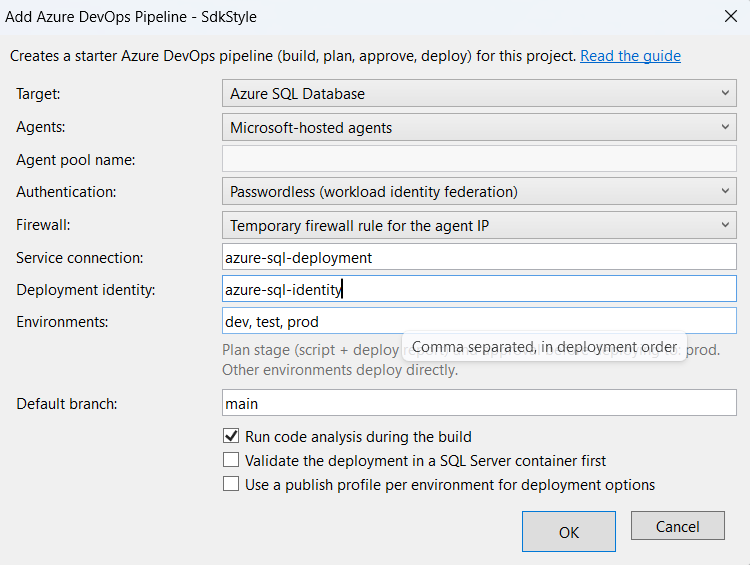
The latest release of SQL Project Power Tools (for Visual Studio and SSMS) adds a new command: Add Azure DevOps Pipeline.... It generates a complete, opinionated starter pipeline for your SQL Database Project, plus the documentation and setup checklist you need to get it running. In this post I will walk through what it generates, and - more importantly - why.

Why database deployment pipelines are hard

If you have built one of these before, you probably recognize this list:

  • Authentication: a SQL login password in a pipeline variable is a secret that must be rotated, can leak in logs, and is often shared between environments. Going passwordless involves an Entra identity, a service connection and a database user - and all three must line up.
  • Firewall: a Microsoft-hosted agent gets a new IP address on every run, so the Azure SQL firewall blocks it. The common "fix" - Allow Azure services and resources to access this server - opens the server to every Azure tenant, not just yours.
  • Reviewing changes: the actual SQL that will run depends on the current state of the target database. A reviewer approving a production deployment usually has no idea what is about to happen.
  • Drift: the target database can change between the time someone reviewed the changes and the time they are deployed.
  • Tooling versions: the SqlPackage pre-installed on hosted agents (or bundled with the Azure DevOps tasks) often lags behind - and newer features such as preplan scripts require a recent version.
  • Project styles: classic .sqlproj projects need MSBuild with the SSDT targets on Windows, while SDK-style projects build with dotnet build anywhere.
  • Configuration: SQLCMD variables and deployment options must differ per environment, without hard-coding server names and secrets.

None of these are hard on their own. Getting all of them right, at the same time, in YAML, is.

Add a starter pipeline in a few clicks

  1. Right-click your SQL Database Project in Solution Explorer
  2. Select SQL Project Power Tools > Add Azure DevOps Pipeline...
  3. Pick the target platform, agent pool, authentication, firewall strategy, environments, whether to use publish profiles, and optional stages
  4. Select OK

You only answer the above questions, everything else is derived from your project.

  • The project style (classic, Microsoft.Build.Sql or MSBuild.Sdk.SqlProj), which decides the agent image and build step
  • The project path relative to the root of your git repository
  • The .dacpac name and target platform
  • The SQLCMD variables defined in the project (the project is built and the variables are read from the .dacpac)
  • Existing *.publish.xml publish profiles, and whether code analysis is enabled

The wizard supports Azure SQL Database, Azure SQL Managed Instance and SQL Server as targets, and Microsoft-hosted agents, Managed DevOps Pools and self-hosted agents.

What you get

These files are created relative to the root of your git repository:

File Purpose
azure-pipelines.yml The pipeline: build, optional validation, then one stage per environment
pipelines/templates/deploy-database.yml Reusable plan/deploy stage template for one environment
pipelines/templates/sqlpackage-steps.yml Installs the latest SqlPackage and runs Script, DeployReport or Publish
pipelines/setup/grant-pipeline-access.sql One-time script that creates the pipeline identity as a database user
pipelines/PIPELINE-SETUP.md Checklist of what to set up in Azure and Azure DevOps, with matching az commands
<Project>.<environment>.publish.xml One publish profile per environment (only when publish profiles are enabled)

Your choices are saved in pipeline-options.json next to the project file, so you can simply run the command again to regenerate the pipeline later. Existing files are only overwritten if you confirm, and publish profiles are never overwritten.

Documented by design

A generated pipeline that nobody understands is just technical debt with a nicer name. So the documentation is a first class part of the feature:

  • PIPELINE-SETUP.md is a checklist tailored to your choices: the environments to create, the variable groups and the variables they need (based on the SQLCMD variables in your project), the approval checks, the service connection, and the exact az CLI commands to run.
  • The generated YAML is commented, and the comments link to a deployment guide that explains each topic using the same structure: the problem, why it is hard, the recommended pattern, and what the generated pipeline does for you.

The result is that the next developer who opens azure-pipelines.yml can understand not only what it does, but why it does it that way.

Start with pipelines/PIPELINE-SETUP.md - the pipeline will not run until the service connection, environments and variable groups exist.

The stages

The generated pipeline follows a build once, deploy many pattern:

  1. Build - compile the project, run code analysis (if enabled), and publish the .dacpac and any publish profiles as a pipeline artifact.
  2. Validate (optional) - deploy the .dacpac twice to a throwaway SQL Server 2025 container. This catches deployment errors and post-deployment scripts that are not safe to run more than once - before you touch a real database.
  3. Plan (staging and production only) - run SqlPackage Script and DeployReport against the target, publish the .sql script and the .xml report as a plan-<environment> artifact, and show a readable summary on the pipeline run page.
  4. Deploy - a deployment job targeting an Azure DevOps Environment, where you configure the approval check. It deploys the same .dacpac that was built and planned.

Stages run in order, for example dev > test > prod, and are skipped for pull request builds.

The Plan stage is only added for environments with a name containing prod, stag, stg or live. Development and test environments deploy directly to keep the feedback loop short.

Reviewers finally know what they approve

This is my favorite part. Instead of approving a deployment based on a commit message, the reviewer opens the run summary and the plan-prod artifact and sees the exact script and the list of changes SqlPackage intends to make against the current production database - including any warnings about possible data loss.

Drift detection between plan and deploy

What if someone changes the production database after the plan was created, but before it was approved? The generated deploy job creates a new DeployReport right before publishing and compares it with the approved one. If they differ, the deployment fails with "Drift detected between plan and deploy", and you simply run the pipeline again to get a fresh plan. If they match, SqlPackage publishes with all its usual safety checks in place.

Passwordless by default

The default authentication option is workload identity federation:

  • An Azure Resource Manager service connection using workload identity federation - Azure DevOps exchanges a short-lived token with Entra ID on every run, so there is no client secret to store or rotate.
  • Every SqlPackage call runs inside an AzureCLI@2 step, gets an access token for https://database.windows.net/ and passes it with /AccessToken:. The token is marked as a secret, so it is masked in the logs.
  • The step everybody forgets: the identity must exist as a user in every target database. grant-pipeline-access.sql contains the CREATE USER ... FROM EXTERNAL PROVIDER statement for your identity, and a commented CREATE USER ... WITH SID = ..., TYPE = E alternative for when the Entra admin cannot query Microsoft Graph.
  • Least privilege: db_ddladmin, db_datareader and db_datawriter cover most deployments. db_owner is only needed if your project manages permissions, users or database level settings.

SQL authentication (with a secret in a variable group) and Windows authentication (self-hosted agents) are also available if you need them.

Firewall handled properly

With the Temporary firewall rule option (Azure SQL Database only), each job that connects to the database adds a firewall rule named azdo-<build id>-<job id> for the agent's current IP address, and removes it again in a step with condition: always() - so the rule is cleaned up even when the deployment fails. The setup checklist includes the az role assignment create command that gives the service connection identity permission to manage the firewall.

For production, the best option is a private network: Managed DevOps Pools or self-hosted agents in a virtual network, with a private endpoint and public network access disabled. Choose Private network in the wizard, and no firewall steps are generated.

Always the latest SqlPackage

Every job that runs SqlPackage installs the latest microsoft.sqlpackage .NET tool, adds it to the PATH and logs the installed version, so every run shows exactly which version was used. If you prefer reproducible builds, pin a version with --version on the dotnet tool install command in sqlpackage-steps.yml.

Configuration per environment

  • SQLCMD variables are mapped to pipeline variables from a variable group per environment, named sql-<environment>. Mark secrets as secret, or link the variable group to Azure Key Vault.
  • Publish profiles are optional (and off by default). When enabled, one profile per environment is generated (or an existing one ending with the environment name is reused), so you can make deliberate per-environment choices for options like BlockOnPossibleDataLoss and DropObjectsNotInSource. Keep server names and secrets out of the profiles.
  • Classic projects build with VSBuild@1 on windows-latest, SDK-style projects build with dotnet build on the faster ubuntu-latest image. One more good reason to convert to SDK-style!

A few things the generator cannot do for you

  • Post-deployment scripts must be safe to run repeatedly - they run on every deployment. (The MERGE scripts created by Script Table Data in SQL Project Power Tools already are.) The Validate stage helps you catch this.
  • There is no automatic rollback. SqlPackage does not undo a deployment - rely on point-in-time restore or backups, and fix forward.
  • GitHub Actions is not supported by the generator yet. Let me know if this is something you would like to see supported in the future.

Try it

Install or update SQL Project Power Tools for Visual Studio or SQL Project Power Tools for SSMS, right-click your SQL Database project, and select Add Azure DevOps Pipeline.... Then read through the deployment guide - even if you already have a pipeline, you may find a pattern or two worth borrowing.

As always, feedback, ideas and bug reports are very welcome in the GitHub repository. Let me know if GitHub Actions support should be next!


Read the whole story
alvinashcraft
16 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

From copy-paste to platform thinking

1 Share

At Octopus Deploy, we maintain a collection of static websites we call microsites. They host public-facing content like our product documentation, our external handbook, and the blog you’re reading this article on. Contributors come from across the organization, including support, engineering, product, marketing, and our people team.

Each microsite is built on the Astro framework and lives in its own GitHub repository. For years, they were built, tested, and deployed using GitHub Actions and Octopus Deploy. The setup worked, but over time, the gap between “it works” and “it’s working well” kept growing, especially when we stepped back to consider what great software delivery looks like today.

We continuously release functionality in Octopus to help teams improve software delivery, and we wanted to bring those improvements to our microsites. Eating your own dog food and all that! We also knew the build had friction, and there were parts of GitHub Actions we wanted to improve. What started as “let’s enable ephemeral environments for the microsites” became a series of adjustments to our deployment pipeline.

They were all for the better, but along the way, we hit paper cuts, had fascinating discussions, and faced decisions that seemed simple on the surface yet quickly made us think differently on topics like where the platform team’s responsibility ends and the application team’s begins, how opinionated a shared process should be, and how much flexibility is too much.

This article anchors a series of posts that go deeper into specific pipeline improvements. Here, I want to set the scene, while the pieces that follow get into the technical detail, the decisions we made, and the rough edges we hit along the way.

Crucially, while I’ll be using our microsites to tell the story, the patterns and considerations apply well beyond static sites, and they surfaced when I worked with customers building and delivering software. If you’ve ever tried to standardize processes across multiple teams, manage shared delivery infrastructure, or define the right lines of ownership, this will likely feel familiar.

The way things were

None of what I’m about to describe was a crisis. The microsites were online, content was being published, builds and releases were functioning, and things were fine on the surface. But fine has a way of masking friction, and friction has a way of compounding in the background until someone decides to act. What started with “let’s enable ephemeral environments on the microsites” led us to look more broadly at how we build and deploy changes, and that surfaced several areas we felt could be improved.

I want to give you a peek behind the curtain at what things looked like before we started. I’m not going to cover every paper cut and rough edge here, as those get their own dedicated articles. But I want you to see that, on their own, none of these things were really that big of a deal. It was only when we stepped back and looked at the delivery cycle holistically that the case for change became clear.

The copy-paste loop

Each microsite lived in its own GitHub repository, and each repository had its own set of GitHub Actions workflows to build, test, and validate changes. We had four core GitHub Actions workflows, which at a high level achieved the following tasks:

  1. Spellcheck (branch)
  2. Markdown linting (branch)
  3. Build, test, package, push the package to Octopus, and trigger the release (branch)
  4. Build, test, package, push the package to Octopus, and trigger the release (main)

Four workflows per repo across five repos meant 20 workflow files in total. Any future microsites would only make it worse, as another repo meant another set of workflow copies to maintain. And this was just for the CI side. The idea behind this was that if a change was made to one of these workflows, it would be abstract enough to be easily copied and pasted into the same workflow file in the other microsite repositories. This pattern will be familiar to many software teams. A build process works well for a particular technology stack, so when the next application comes along using the same stack, an engineer copies the working example as a starting point. It’s pragmatic, it’s fast, and on day one, it makes complete sense.

The problem with copy-paste, even if you’re copying from a template file, is that it’s a snapshot from a point in time, not an ongoing linked relationship. The moment you paste something into a second place, you have two things to maintain instead of one. Over time, changes are made in one repo but not in the others, sometimes intentionally, sometimes not. A node version gets bumped in one workflow and forgotten in another. Someone tweaks a step while testing something and doesn’t propagate it across. Another engineer just isn’t aware of all the different applications using the same workflow, and before long, five repos that were supposed to be identical have drifted apart, and nobody has a clear picture of which one is the source of truth.

The same pattern played out for deployments. Each microsite had its own project and deployment process, defined in Octopus Configuration Language (OCL) and stored in the repository. This is great, as the deployment process is stored in code alongside the application, and benefits from all the great things we’ve defined as an industry by putting configuration in version control. For the microsites, the deployment process was identical across all five sites. Or at least it was supposed to be. Making a change meant updating one project, verifying it worked, and then manually propagating the change to the other four projects. In practice, this meant five pull requests, five reviews, and five merges.

Even though we designed variables and the deployment process to be project-agnostic, the overhead of something as small as changing the format of a Slack notification message is hard to justify and only gets worse at scale. When the overhead of making a change is too high, people stop making them. Over time, that means fewer improvements, and fewer improvements mean everything starts to feel slow and heavy. The pipeline becomes something people work around rather than something they invest in.

The deeper problem is the drift. Copy-paste gives you the illusion of consistency without the guarantee of it. It is very easy for a human to forget to update one of the files or test a change against one of the sites, and then completely forget to update the other sites. From a Platform Engineering and compliance perspective, saying “this is how we build and deploy” with confidence when operating this way is impossible.

Deployment times that test our patience

Deploying a microsite should be straightforward. At the end of the day, it is a static website; it’s not as complex as much of today’s software development and architecture. Build the site, push the files to the destination, clear the cache if needed, and send a notification. In practice, a full deployment of one of our larger microsites, like the blog or docs, would take more than 40 minutes.

The culprit was the way files were transferred to S3. The step responsible for the upload compares each file in the source against the existing files in the destination before deciding whether to copy it. For a site with thousands of images, each generating multiple derivative files during the build, the comparison loop took too long.

Alternatives were explored briefly. SFTP was considered, and questions were raised about whether the upload step could be improved or replaced with a more efficient alternative. While the answer to that was almost certainly “yes,” the deployment was working; it wasn’t a priority to dig into further, and the impression at the time was “that’s how S3 works.” When something is functioning well enough, and the path to a better solution isn’t obvious, a targeted workaround tends to win.

That workaround was a new function in the build - allow me to introduce pnpm thin. Rather than deploying the full site on every run, pnpm thin stripped out any image assets that hadn’t been modified in the last 14 days. Running pnpm thin was added to the build process (well, all 5 copies of the build processes!), and fewer files meant fewer comparisons, which brought deployment times down to around 10 minutes.

An issue with pnpm thin was the assumption it came with. It assumed the destination already contained all the images stripped during the build. For an incremental deployment to a long-running production environment, that assumption was fine. For a fresh deployment to a brand new environment, like an ephemeral environment spun up for a pull request, it wasn’t. Most of the site’s images would simply be missing.

It’s a good example of how workarounds can quietly constrain future decisions. The pnpm thin function solved the immediate problem, but it made a full, clean deployment effectively impossible without first understanding why half the images weren’t showing up.

The fading static staging environment

Each microsite had two static environments that Octopus deployed to - staging and production. Early on, staging was a genuine part of the process, proposed changes were deployed to the staging environment, and people relied on it. But over time, use faded, and the reasons why are worth understanding because they’re not unique to our microsites.

Two things eroded it. The first was contention. When someone needed to do more thorough testing, they’d ask others not to overwrite the staging environment while they worked. I’m sure you’ve seen similar messages bounce around your Slack or Teams channels:

Please don’t use the staging environment today, I’m testing out some changes I’ve been working on. Thanks heaps!

It seems like a reasonable request, but realistically, it meant everyone else had to find another way to check their changes. Local previews filled that gap, and once people found a faster workaround that didn’t require coordinating with anyone, they stuck with it. Interestingly, relying on running the sites locally introduces other pain points, which I’ll touch on below when discussing how to preview changes.

This also meant that, as someone who wanted to deploy your change to the staging environment, you felt like you had to ask around first to see if you were about to interrupt someone else. Messages like “Anyone in the blog staging environment at the moment?” weren’t unusual to see flying around Slack, though admittedly, those were more pleasant than seeing the “Who just overwrote my deployment in the blog staging environment!?” messages! Add in a globally distributed team and the friction that is time zones to the equation, and you’re in for a world of hurt.

The second was the feedback loop. Build times already stretched to around 10 minutes. A deployment to staging added more to that. When you can verify something locally in a few seconds, waiting 20 or more minutes for a staging deployment is hard to justify, especially for a content change where the diff is right there in the GitHub UI.

Delayed feedback loops are the conditions in which workarounds grow. The longer you wait for a build, a deployment, or a shared environment to free up, the more attractive any shortcut becomes. It’s a rational response to friction, and once the shortcut becomes the default, the original agreed and documented process falls out of the team’s workflow.

By the time we looked at this properly, most contributors were testing locally if they checked at all, and reviewers were reading diffs in GitHub’s portal rather than seeing changes live. The first time many changes were seen in a real hosted environment was in production.

The effort to preview changes

The staging situation pointed to a broader gap. Unless the static staging environment was used, there was no easy way for a contributor to share a live, hosted version of their change with someone else. No way for a reviewer to click a link and see the proposed change running in a real environment. To do it in staging meant:

  1. Knowing you were all clear to use the staging environment without annoying someone else who may be testing/reviewing their change
  2. Knowing which Octopus Deploy instance and project to go to
  3. Having access to the target project in Octopus Deploy
  4. Knowing how to perform a deployment to the staging environment
  5. Knowing the URL for the staging environment to share with others

Technical contributors would often just run the site locally on their machine. Clone the repo, install dependencies, run pnpm dev, and open localhost. It’s not onerous if you know what you’re doing. But many people contributing to the microsites aren’t developers. For them, the local preview instructions in the readme present a barrier, not a solution.

For reviewers, the situation isn’t much better. To see a proposed change live, you’d need to check out the branch, follow the same local setup instructions, and run the site yourself. In practice, most reviewers looked at the diff in GitHub and called it done. That works for typo fixes or, honestly, even new documentation pages or blog posts. However, it’s less reassuring for layout changes, new components, or anything where seeing it rendered matters.

What we wanted was simple. Open a pull request, get a URL, and see your change in a real hosted environment. Ideally, one that mirrored the production infrastructure, allowing us to test changes in a production-like environment. While static website hosting is straightforward, there are nuances with different hosting options. We wanted to provide this to contributors without them needing to know anything about the underlying infrastructure, without needing access to Octopus, without needing to run anything locally. That experience didn’t exist yet, and building it was what set this whole project in motion, which admittedly was a bit of eat your own dog food when we introduced ephemeral environments in Octopus.

Organically growing infrastructure

The microsites were provisioned and were running in AWS, using S3 as the endpoint and CloudFront distributions in front of them. It worked, but they were initially provisioned and configured manually and had been left largely untouched since.

Without Infrastructure as Code (IaC), there was no reliable way to know whether the configuration of each bucket and distribution was consistent across all sites. If a change was required, it had to be made manually, one resource at a time. If something ever needed to be recreated from scratch, like deploying to a new AWS region or provisioning a fresh environment for a pull request, there was no automated way to achieve it.

We knew we wanted to move to Azure, where most of Octopus’s infrastructure lives, and that the migration was an opportunity to put the infrastructure management in a better shape. Automating the provisioning and deprovisioning of infrastructure was something we knew we had to get right, particularly if we were going to support ephemeral environments and speed up deployments.

What we changed

The pain points above are just the surface. Each one has a dedicated article that goes into the details, the decisions, the trade-offs, and the edges we hit along the way. If you’ve felt any of this in your own work, the deeper articles are worth your time.

New articles in this series are being published over the coming weeks. As each one goes live, the topics below will link through to it.

The copy-paste problem across both GitHub Actions and Octopus was solved by leaning into templating. Twenty workflow files spread across five repositories were consolidated into a set of reusable GitHub workflows. In Octopus, five individual deployment processes were consolidated into a single versioned process template that all five microsites now consume, along with templated runbooks for provisioning and deprovisioning infrastructure. Both solved the copy-paste problem, but if you read the reusable GitHub workflows article, you might come away thinking Octopus has set a pretty high bar for what templating should look like.

Slow deployments and the pnpm thin workaround that papered over them were addressed during the migration to Azure. We evaluated several hosting options before landing on Blob Storage, swapped out the file transfer tooling for AzCopy, and in doing so, made pnpm thin unnecessary. The full story is in finding the right hosting for a static site.

Ephemeral environments were the catalyst for this project, and while Octopus does much of the heavy lifting, it requires a mature foundation underneath. Every pull request now gets its own hosted environment, with a preview URL posted as a comment on the PR. Along the way, we hit some interesting edges, including managing Terraform state for short-lived environments and a subtle race condition with short-lived PRs that took a pragmatic workaround to resolve.

Two of the more interesting conversations in the project weren’t really about tooling at all. Where ownership lines fall between a platform team and the teams consuming what they build is something many practitioners wrestle with, and it came up repeatedly here. And rather than installing tools at deployment runtime - something I’ve seen a lot of teams do in the field - we took an approach of keeping workers lean with execution containers, which made deployments faster and more predictable.

Finally, not every pull request needs a full environment spun up. Based on some conversations I had at conferences and internal feedback, we made the whole thing optional using a simple GitHub PR label, without compromising branch protection rules.

Wrapping up

None of the pain points in this article were dramatic on their own. A few copied workflow files, a slow deployment, a staging environment people stopped using. But together, they made it harder to improve, harder to trust what we were shipping, and harder for contributors to see their changes before they went live.

It’s also worth thinking about what happens as these patterns scale. Five microsites is a small footprint, but the same copy-paste approach across dozens or hundreds of applications makes it close to impossible to answer simple questions like “are all our deployments following the same process?” or “has everyone picked up the latest security change?” That’s where platform thinking earns its keep. Shared templates, consistent infrastructure, and guardrails built into the process mean compliance and risk are handled by default, rather than relying on every team to remember to do the right thing based on a knowledge base article people rarely revisit.

For us, the realization was that the tooling we rely on had moved on, and our pipelines hadn’t kept up. Taking the time to step back, look at the whole delivery cycle, and bring it in line with what modern software delivery looks like today has been worth it. If some of this sounded familiar, it might be worth taking that same step back with your own pipelines.

Happy deployments!

Read the whole story
alvinashcraft
43 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Vector stores in Agent Framework for Python: familiar foundations, streamlined for agents

1 Share

Vector stores have been part of the Python experience in Semantic Kernel for some time. With Microsoft Agent Framework, we have ported that work forward rather than starting over.

This post focuses on Python. For the .NET equivalent, see Use vector stores in .NET AI apps.

The foundation remains familiar: typed record definitions, stores and collections, batch storage and retrieval, embedding generation, vector search, and a growing set of integrations. If you have used Semantic Kernel’s vector-store APIs, you will recognize the overall model.

At the same time, this is more than a straight port. We streamlined model registration and the batch APIs, updated filters and embedding options, and made vector stores fit naturally into how agents receive and use context.

The most important additions are the context providers. They expose your data to agents through tools, or use a vector store to keep conversation history searchable without continually expanding the model context.

The vector-store APIs remain experimental, and the integration packages are alpha or beta. Use each implementation’s documentation for setup and its supported capabilities.

Define the data your application already owns

Agent Framework starts with your data model rather than a database SDK model. Mark the key, data, and vector fields with VectorStoreField, and @vectorstoremodel derives the collection definition:

from dataclasses import dataclass
from typing import Annotated

from agent_framework import (
    Filter,
    InMemoryCollection,
    VectorStoreField,
    vectorstoremodel,
)
from agent_framework.openai import OpenAIEmbeddingClient


@vectorstoremodel(collection_name="documents")
@dataclass
class Document:
    id: Annotated[str, VectorStoreField("key")]
    category: Annotated[str, VectorStoreField("data", is_indexed=True)]
    text: Annotated[str, VectorStoreField("data")]
    embedding: Annotated[
        list[float] | str | None,
        VectorStoreField(
            "vector",
            dimensions=1536,
            distance_function="cosine_similarity",
        ),
    ] = None


async def index_and_search() -> None:
    documents: InMemoryCollection[str, Document] = InMemoryCollection(
        Document, embedding_generator=OpenAIEmbeddingClient(model="text-embedding-3-small"),
    )
    await documents.ensure_collection_exists()

    await documents.upsert([
        Document(
            id="release-checklist",
            category="operations",
            text="Verify rollback, monitoring, and owner sign-off.",
            embedding="Verify rollback, monitoring, and owner sign-off.",
        )
    ])

    results = await documents.search(
        "What should I check before a release?",
        filter=Filter("category", "eq", "operations"),
        top=3,
    )

    async for result in results:
        print(result["record"].text, result["score"])

Set OPENAI_API_KEY before running the code. The records are stored in-memory (so this will not survive a restart), while OpenAI generates embeddings during both upsert and search. You can swap out the InMemoryCollection with any of the other implementations without changing anything else, see the list below for the ones we currently support.

Dataclasses are only one option. The same model layer supports Pydantic models, msgspec structs, plain classes, dictionaries, and externally owned types through custom codecs.

Turn vector search into an agent tool

As in Semantic Kernel, you can expose search directly as a first-class agent tool. create_vector_search_tool wraps a searchable collection and lets you control its name, description, result shape, filters, and approval behavior.

Param now makes custom search tools easier to build. Place a Param inside a Filter or FilterGroup, and the helper exposes it as a typed argument the model can supply. Given a collection configured to embed text queries, the tool definition stays small:

from typing import Literal

from agent_framework import Filter, Param, create_vector_search_tool

category = Param(
    "category",
    Literal["engineering", "operations", "product"],
    required=False,
    description="Only return documents from this category.",
)

search_documents = create_vector_search_tool(
    collection,
    name="search_documents",
    description="Search the document collection.",
    filter=Filter("category", "eq", category),
    result_mapper=lambda result: result["record"].text,
)

The resulting tool always accepts a natural-language query and optionally accepts category. The Literal values become an enum in the tool schema, giving the agent a clear set of valid choices. If the model omits the optional parameter, that filter is omitted. More complex tools can compose several parameters through FilterGroup.

The key addition: make collections available through context providers

When an agent needs more than one focused search tool, VectorCollectionContextProvider provides the higher-level experience.

VectorCollectionContextProvider can add upsert, get, delete, and search tools to an agent, together with instructions for using them. You can expose a read-only knowledge collection, let an agent manage records with approvals, scope the available data, or replace the default search with specialized tools.

Embedding setup stays specific to the operation: ingestion can use document embedding options while search uses query embedding options. Generated tools forward those settings to the same collection.

A context provider for searchable conversation history

Conversation histories keep growing, increasing the context sent to the model on every turn. VectorStoreHistoryProvider persists the full conversation in a searchable vector collection while loading only a compacted working set into the model context.

When include_search_tool=True, the agent also receives a tool for searching the complete scoped transcript. The active context can therefore remain bounded without losing access to an older decision, requirement, or user preference: the agent retrieves the relevant part of the conversation when it needs it instead of carrying every prior message on every invocation.

Embeddings and search without hard-coding a provider

Applications can supply precomputed vectors or have Agent Framework call an embedding service during upsert and search. They can generate every vector field or only selected fields, and pass different provider options for document ingestion and query generation. Vector dimensions stay with the model definition, so Agent Framework can validate generated and supplied vectors before they reach the backing store.

Search uses the same collection API across integrations, with portable data filters and keyword-hybrid search where supported. Each implementation documents its supported indexes, filters, metrics, and search modes.

Available integrations

The current Python integrations are:

  • Azure AI Search
  • Azure Cosmos DB for NoSQL
  • Azure DocumentDB
  • MongoDB
  • Oracle AI Database 26ai
  • Redis
  • SQL Server and Azure SQL
  • PostgreSQL with pgvector
  • DuckDB
  • Qdrant
  • The core in-memory store for tests and local development

The same model and core operations work across integrations, while each database keeps its own features and constraints.

Get started

Start with the runnable vector-store samples for models, search, and agent tools. The vector-store-backed conversation sample demonstrates bounded working context with search over the full conversation.

Install the integration package for the store you want to use, and use its README for setup and supported capabilities. We would especially like feedback on the context-provider experience, searchable history, and which integrations you need next. Open an issue in the Microsoft Agent Framework repository and tell us what you are building.


The post Vector stores in Agent Framework for Python: familiar foundations, streamlined for agents appeared first on Microsoft Agent Framework.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Triaging Dependabot With a Copilot Canvas

1 Share

Dependabot is one of those tools that I really appreciate, right up until I open a repository and see a pile of pull requests waiting for me. And this is particularly noticeable when working on a monorepo, such as the Aspire Community Toolkit.

Individually, each PR is pretty simple: a dependency moves from one version to another, the lockfile changes, CI runs, and if all is well you merge it. The problem is that they don’t arrive individually. They arrive as a queue, and that queue has relationships that GitHub’s PR list doesn’t really make obvious. Which PRs fix security alerts? Which ones touch the same lockfile and will conflict with each other once I merge the first one? Are there alerts with no PR fixing them at all?

I found myself doing that analysis in my head (or across a bunch of browser tabs) whenever I sat down to tidy up dependencies. So I built a canvas for the Copilot app to help: the Dependabot Triage Canvas.

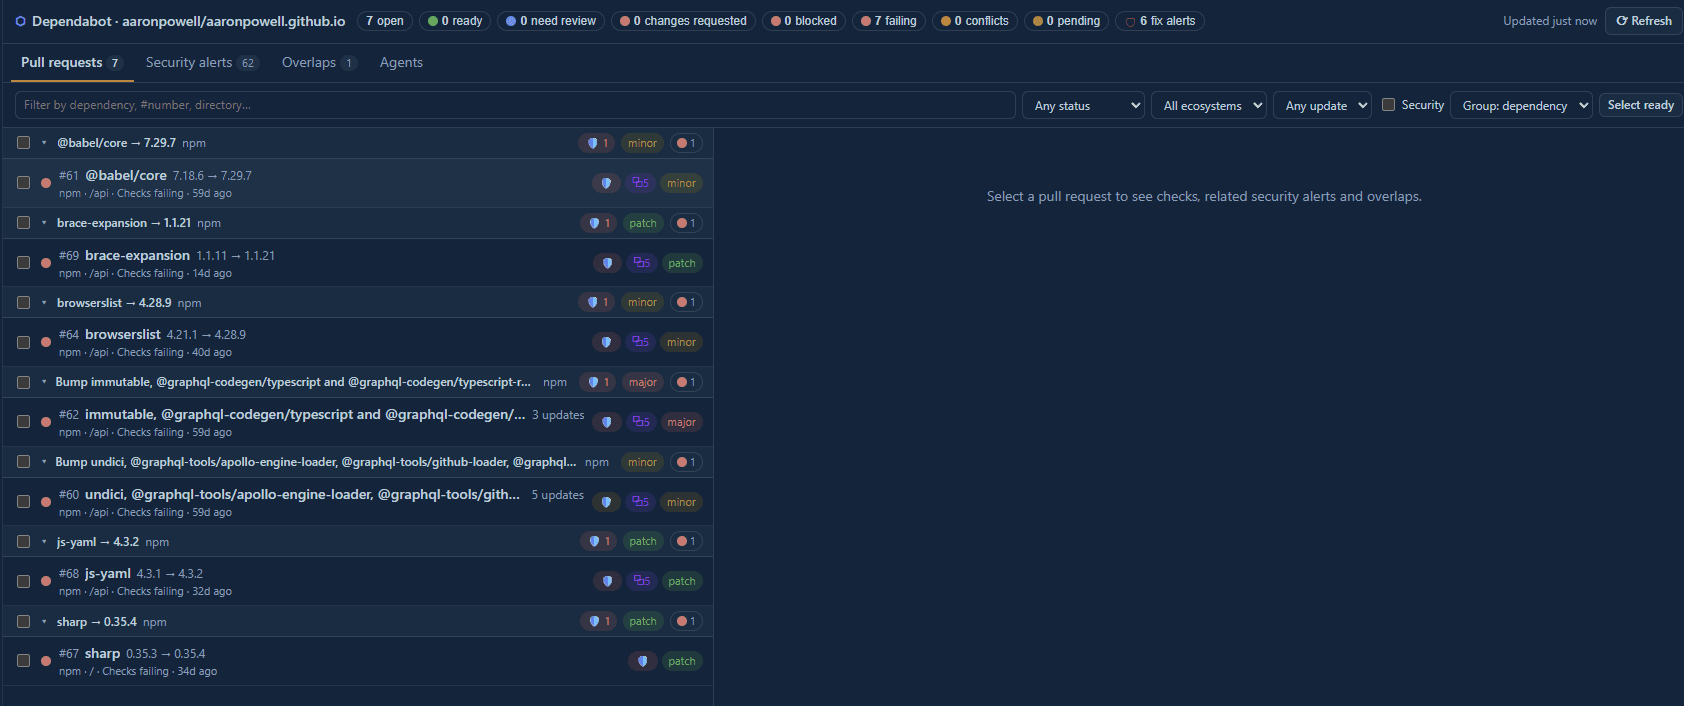
Dependabot Triage Canvas

Looking at the queue differently

Canvases are apps that you host in a session within the Copilot app that let you work with something other than chat - a kanban board, an external system dashboard, or in this case, a purpose-built view of your Dependabot PRs.

Rather than listing PRs in the order they were opened, the canvas groups them. By default the grouping is by dependency, but you can also group by directory, ecosystem or status. Each PR shows the dependency update (including whether it’s a patch, minor or major version bump), the state of its checks (is CI passing), whether it’s mergeable, and its review state.

To make this concrete, I opened the canvas against this blog’s repository while writing this post. It found 7 open Dependabot PRs, all in the npm ecosystem, and 6 of them are linked to security alerts. They include a mixture of updates:

  • brace-expansion 1.1.11 → 1.1.21 (patch)
  • js-yaml 4.3.1 → 4.3.2 (patch)
  • sharp 0.35.3 → 0.35.4 (patch)
  • browserslist 4.21.1 → 4.28.9 (minor)
  • @babel/core 7.18.6 → 7.29.7 (minor)
  • A PR with several major @graphql-codegen updates

It also told me something less pleasant: all 7 PRs have failing checks. Clearly this repository needs a bit of attention! 😅 (The failing checks are to do with deploying PR branches to Azure Static Web Apps, which has been broken for a while, so no biggy 😜)

That’s the sort of thing I wanted the canvas to surface quickly. I don’t need to open each PR to discover that there’s a broader problem worth investigating before I start merging.

Connecting PRs and alerts

The thing that pushed me to build this was the disconnect between Dependabot pull requests and Dependabot security alerts.

The canvas loads open security alerts and matches them against the open PRs. When a PR fixes one or more alerts, you can see that relationship from the PR itself. The alerts view also highlights the alerts that don’t have an open PR addressing them.

For this repository, there are 62 open alerts and 53 of them are not addressed by an open Dependabot PR. Many of those are in the /api project’s package-lock.json, including alerts for packages such as undici, ws, form-data and lodash.

That’s a very different picture to “there are 7 PRs to review”. The PR queue is only part of the work; there’s also a bunch of security work that needs a different approach, such as updating a parent dependency or retiring an old part of the project.

Spotting overlaps

Another thing that the canvas looks for is overlap between PRs.

This is something that we hit a lot in the Community Toolkit. Since it’s a monorepo design, we have a lot of package.json files spread across a lot of folders. If a security alert comes out for one of the packages, we could end up with 50+ PRs updating the same package simultaneously. The canvas helps identify these overlaps, and allows us to combine them into one single PR. Doing this means that we have less merges happening, and fewer CI jobs that need to run when the merge happens to the main branch.

Taking action without giving up control

The canvas isn’t only a read-only dashboard. It supports a number of actions that I’d otherwise perform on GitHub:

  • Approve a PR
  • Approve and merge a PR, optionally with auto-merge
  • Close a PR
  • Post supported @dependabot commands like rebase, recreate and ignore

These can be done one at a time or in bulk. But I was very deliberate about where the guardrails sit.

Approving, merging, closing and commenting only happen after I confirm the action in the canvas. The agent-facing actions can read, filter and select PRs, and they can record results like review verdicts, but they can’t mutate the PRs. Merges also use --match-head-commit, so if a PR has changed since I looked at it, it won’t be merged.

In other words, Copilot can help me understand the queue and get the right PRs selected, but I’m still the one pulling the trigger.

Bringing agents into the workflow

Because the canvas is running inside the Copilot app, it can also hand work off to agents.

Review with agent sends one or more PRs to an agent for review. The agent records a verdict - safe, caution or blocked - along with a summary, and that verdict appears back in the canvas. If the PR’s head changes later, the review is marked as stale so I’m not relying on an old assessment. This can be particularly helpful if there’s a failing CI job, as the agent can help dig through the CI logs to see if the failure is transient or related to the dependency that is being bumped.

The other workflow is what I mentioned above, Combine into one PR. I can select a set of Dependabot PRs and ask an agent to fold them together. The agent works in a separate git worktree, so my checkout isn’t disturbed. It cherry-picks the PRs, regenerates conflicting lockfiles, pushes a new branch and opens a combined PR that lists what it supersedes.

Reviews and combines run in background agents by default, so multiple tasks can be in progress while my main session stays available. The Agents tab shows what’s running, which PRs each agent is working on, and its latest response.

This is where a canvas becomes more interesting than a dashboard. It gives the agent structured context - the PRs, their diffs, the related alerts, and the overlaps - and gives me a structured way to see what the agent did.

Trying it out

The canvas is available as a plugin in the Copilot app:

  1. Open Customise in the Copilot app and navigate to plugins.
  2. Search for “Dependabot Triage Canvas” under Awesome Copilot and enable it.
  3. Ask Copilot to “open the Dependabot triage canvas”.

By default it’ll use the current repository, but you can target a different one by passing { "repo": "owner/name" } when opening the canvas.

You’ll need the GitHub CLI installed and authenticated, as all of the GitHub calls go through gh. Read access is enough for triage, but you’ll need write access to approve, merge, close or comment, and security alert access to see the Dependabot alerts.

Wrapping up

The biggest change for me isn’t any individual button in the canvas. It’s that I can see the shape of the Dependabot work before I start doing it.

Opening it on my blog repo immediately showed me three things: every Dependabot PR is failing checks, most of the open security alerts don’t have a PR, and most of the PRs are going to collide in the same lockfile. That’s a much better starting point than working through PRs one by one.

If you’re dealing with Dependabot queues of your own, give it a try and let me know what you think. The source is on GitHub, and I’d love to hear what other triage workflows would be useful.

Read the whole story
alvinashcraft
4 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories