 Log in

Adds a load-time endpoint trust check: a .prompty whose connection would send ambient credentials to an untrusted, file-chosen endpoint/tokenUrl fails with untrusted_endpoint. Trust additional origins with the trustedEndpoints load option or PROMPTY_TRUSTED_ENDPOINTS. See #590.
|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA

Learn what is new in Visual Studio Code 1.144 (Insiders)
Pennsylvania, USA


Microsoft has released a public preview of dotnetup, a cross-platform toolchain manager that installs and updates .NET SDKs and runtimes in the user’s own directory without admin rights. It tracks channels such as latest, lts, preview, and daily, reads global.json, and removes unused installs. Commands may still change before general availability.
By Almir Vuk
Pennsylvania, USA

Introduction
You may not know, but Visual Studio (or more accurately, MSBuild and other tools used implicitly) can make use of local files to configure some aspects of its working. In this post I will introduce and explain why we should use (at least) some of them. These files apply regardless of the solution format in use, are not related to a specific format.
Here is the list with a brief summary of what each file is for. Of course, other files may be used for other purposes and different technologies somewhat outside the control of Visual Studio/MSBuild (e.g., NPM, Less, etc).
| File | Purpose |
| Directory.Build.props | Defines shared MSBuild properties for projects under that directory tree. Imported early in the build. Commonly used for target frameworks, nullable settings, analysers, company metadata, warning levels, etc. |
| Directory.Build.targets | Defines shared MSBuild targets/items/tasks for projects under that directory tree. Imported late in the build. Commonly used for custom build steps, validation, packaging hooks, generated files, etc. |
| msbuild.rsp | Default command-line switches to MSBuild.exe for a specific project.Visual Studio does not apply any .rsp response file. Better to use Directory.Build.rsp as it applies to all projects. Not commonly used. |
| Directory.Build.rsp | MSBuild response file for passing command-line switches automatically to builds under a directory. Visual Studio does not apply any .rsp response file. Not commonly used. |
| Directory.Packages.props | Used for Central Package Management. Defines NuGet package versions in one place with <PackageVersion />, so individual projects can reference packages without specifying versions. |
| Directory.Solution.props | Less common. Solution-level MSBuild props imported when building a .slnx solution in newer MSBuild scenarios. Used for solution-wide properties. |
| Directory.Solution.targets | Less common. Solution-level targets imported when building a solution. Used for solution-wide custom build logic. |
| global.json | Pins the .NET SDK version used by the solution/repo. Helps ensure developers and CI use the same SDK. |
| NuGet.config | Defines NuGet package sources, credentials behaviour, package restore settings, and source mapping. Can apply repo-wide depending on location. |
| dotnet-tools.json | File created when you install a tool for your project with dotnet tool install command. This file contains details like version, installation command, etc, about all the tools installed for your project. |
| libman.json | Manifest file for the Library Manager (LibMan) tool used in ASP.NET Core and web projects. It specifies which client-side libraries (like jQuery, Bootstrap, or Lodash, amongst others) to fetch, from which sources, and where to save them in your project. |
| .editorconfig | Defines code style, formatting, analyser severity, suppression, naming rules, etc. Applies to files by directory scope and is honored by Visual Studio, Roslyn analysers, and many editors. |
| .globalconfig | Repo-wide analyser configuration file for Roslyn. Similar to .editorconfig, but intended for global analyser settings rather than per-directory file style. |
| packages.lock.json | NuGet lock file. Records exact resolved package dependency graph for repeatable restores. Usually generated per project, but can be managed repo-wide depending on restore setup. |
| launchSettings.json | A configuration file within ASP.NET Core applications (Properties folder) to define various profiles for how the application can be launched during development, in the local machine. |
Directory.Build.props
This file contains properties that should apply to all projects in the solution, which is generally good for coherence. This example applies .NET 10 with the latest C# language specs, whether to use C# nullable reference types and implicit usings, and if the output should be deterministic.
<Project>
  <PropertyGroup>
    <TargetFramework>net10.0</TargetFramework>
    <Nullable>enable</Nullable>
    <ImplicitUsings>enable</ImplicitUsings>
    <LangVersion>latest</LangVersion>
    <Deterministic>true</Deterministic>
  </PropertyGroup>
</Project>
Directory.Build.targets
This one defines targets (which can have conditions) for the projects in the directory. This example ensures that project MyProject.DomainModel does not reference any other project or NuGet package.
<Project>
  <Target Name="ValidateDomainDependencies"
          BeforeTargets="ResolveReferences"
          Condition="'$(MSBuildProjectName)' == 'MyProject.DomainModel'">
    <Error Condition="'@(PackageReference)' != ''"
           Text="MyProject.DomainModel must not reference NuGet packages." />
    <Error Condition="'@(ProjectReference)' != ''"
           Text="MyProject.DomainModel must not reference other projects." />
  </Target>
</Project>
msbuild.rsp and Directory.Build.rsp
These files contain parameter options to be passed to MSBuild. The difference between the two is that the first should be placed in a project directory, and the second, in the root of a repository, so that it applies to all projects underneath it. Both are only applied by MSBuild, the Visual Studio IDE ignores them. Use %MSBuildThisFileDirectory% to reference the directory where the file is located. Here's a sample that enables some settings.
# Enable parallel builds across all available CPU cores
-maxCpuCount

# Restore packages and build concurrently
-restore
-m

# Enforce clean terminal output (displays warnings/errors at the end)
-clp:Summary;ErrorsOnly;WarningsOnly

# Automatically configure binlog generation using the file's current directory
-bl:%MSBuildThisFileDirectory%build.binlog

# Define continuous integration parameters if executing a hosted build
-p:ContinuousIntegrationBuild=true
Directory.Packages.props
This file defines NuGet package versions for the entire solution (all projects in a sub directory). This ensures that the same versions are used everywhere, then it's just a matter of individual projects referencing a NuGet package, without specifying its version. This is called Central Package Management and here is a sample that defines some NuGet package versions:
<Project>
  <PropertyGroup>
    <ManagePackageVersionsCentrally>true</ManagePackageVersionsCentrally>
    <CentralPackageTransitivePinningEnabled>true</CentralPackageTransitivePinningEnabled>
  </PropertyGroup>
  <ItemGroup>
    <PackageVersion Include="Microsoft.EntityFrameworkCore.Design" Version="10.0.10" />
    <PackageVersion Include="Microsoft.EntityFrameworkCore.Sqlite" Version="10.0.10" />
    <PackageVersion Include="Microsoft.EntityFrameworkCore.Tools" Version="10.0.10" />
    <PackageVersion Include="Microsoft.Extensions.Diagnostics.HealthChecks.EntityFrameworkCore" Version="10.0.10" />
    <PackageVersion Include="Microsoft.Extensions.TimeProvider.Testing" Version="10.8.0" />
    <PackageVersion Include="Microsoft.NET.Test.Sdk" Version="18.8.1" />
    <PackageVersion Include="xunit" Version="2.9.3" />
    <PackageVersion Include="xunit.runner.visualstudio" Version="3.1.5" />
  </ItemGroup>
</Project>
Directory.Solution.props
This is a specialised MSBuild file used to customize configuration settings specifically for solution builds. Not so commonly used, but here is an example:
<Project>
  <PropertyGroup>
    <!-- Speeds up solution restores via static graph evaluation -->
    <RestoreUseStaticGraphEvaluation>true</RestoreUseStaticGraphEvaluation>
    <!-- Some solution-wide property -->
    <SomeSolutionWideProperty>True</SomeSolutionWideProperty>
  </PropertyGroup>
</Project>
Directory.Solution.targets
Directory.Solution.targets is an MSBuild file placed in the root path above a solution file to customize or extend the build process at the solution level. The following example displays a message after the build finishes:
<Project>
  <Target Name="CustomSolutionPostBuild" AfterTargets="Build">
    <Message Importance="high" Text="Finished building solution in $(SolutionDir)" />
  </Target>
</Project>
global.json
This file allows specifying a fixed .NET version for an entire directory. You should use a global.json file in .NET development when you need to lock, pin, or strictly manage the .NET SDK version used to execute .NET CLI commands. By default, the .NET CLI always uses the latest version of the SDK installed on your machine; you need a global.json when that default behavior causes issues. Example:
{
  "sdk": {
    "version": "10.0.302",
    "rollForward": "latestPatch",
    "allowPrerelease": false
  }
}
NuGet.config
In this file we specify NuGet package sources, which can possibly include credentials, for private repos. This is used when restoring NuGet packages. Here's a small example:
<?xml version="1.0" encoding="utf-8"?>
<configuration>
  <packageSources>
    <add key="nuget" value="https://api.nuget.org/v3/index.json" />
    <add key="myprivaterepo" value="https://my.private.repo/nuget/index.json" />
  </packageSources>
</configuration>
dotnet-tools.json
The dotnet-tools.json file is a configuration manifest used by the .NET CLI to manage local tools specific to a project or repository, like, for example, EF. An example:
{
  "version": 1,
  "isRoot": true,
  "tools": {
    "dotnet-ef": {
      "version": "10.0.8",
      "commands": [
        "dotnet-ef"
      ],
      "rollForward": false
    }
  }
}
libman.json
This is the configuration manifest file used by LibMan (Library Manager) to download and manage client-side web libraries - like jQuery, Bootstrap, or Lodash - directly into web projects without needing heavy package managers like npm. Here's an example:
{
  "version": "1.0",
  "defaultProvider": "cdnjs",
  "libraries": [
    {
      "library": "jquery@3.7.1",
      "destination": "wwwroot/lib/jquery",
      "files": [
        "jquery.min.js",
        "jquery.min.map"
      ]
    },
    {
      "library": "bootstrap@5.3.3",
      "destination": "wwwroot/lib/bootstrap"
    }
  ]
}
.editorconfig
Configures IDE style preferences and analysis rules, for all files (*), or specific files (*.cs, for example). Here is a big example from https://github.com/dotnet/samples/blob/main/.editorconfig:
# editorconfig.org

# top-most EditorConfig file
root = true

# Default settings:
# A newline ending every file
# Use 4 spaces as indentation
[*]
insert_final_newline = true
indent_style = space
indent_size = 4

[project.json]
indent_size = 2

# C# and Visual Basic files
[*.{cs,vb}]
charset = utf-8-bom

# Code quality analyzers
dotnet_analyzer_diagnostic.category-Security.severity = error
dotnet_code_quality.ca1802.api_surface = private, internal

# Miscellaneous style rules
dotnet_sort_system_directives_first = true
dotnet_style_predefined_type_for_locals_parameters_members = true:suggestion
dotnet_style_predefined_type_for_member_access = true:suggestion

# avoid this. unless absolutely necessary
dotnet_style_qualification_for_field = false:suggestion
dotnet_style_qualification_for_property = false:suggestion
dotnet_style_qualification_for_method = false:suggestion
dotnet_style_qualification_for_event = false:suggestion

# name all constant fields using PascalCase
dotnet_naming_rule.constant_fields_should_be_pascal_case.severity = suggestion
dotnet_naming_rule.constant_fields_should_be_pascal_case.symbols  = constant_fields
dotnet_naming_rule.constant_fields_should_be_pascal_case.style    = pascal_case_style
dotnet_naming_symbols.constant_fields.applicable_kinds   = field
dotnet_naming_symbols.constant_fields.required_modifiers = const
dotnet_naming_style.pascal_case_style.capitalization = pascal_case

# static fields should have s_ prefix
dotnet_naming_rule.static_fields_should_have_prefix.severity = suggestion
dotnet_naming_rule.static_fields_should_have_prefix.symbols  = static_fields
dotnet_naming_rule.static_fields_should_have_prefix.style    = static_prefix_style
dotnet_naming_symbols.static_fields.applicable_kinds   = field
dotnet_naming_symbols.static_fields.required_modifiers = static
dotnet_naming_symbols.static_fields.applicable_accessibilities = private, internal, private_protected
dotnet_naming_style.static_prefix_style.required_prefix = s_
dotnet_naming_style.static_prefix_style.capitalization = camel_case

# internal and private fields should be _camelCase
dotnet_naming_rule.camel_case_for_private_internal_fields.severity = suggestion
dotnet_naming_rule.camel_case_for_private_internal_fields.symbols  = private_internal_fields
dotnet_naming_rule.camel_case_for_private_internal_fields.style    = camel_case_underscore_style
dotnet_naming_symbols.private_internal_fields.applicable_kinds = field
dotnet_naming_symbols.private_internal_fields.applicable_accessibilities = private, internal
dotnet_naming_style.camel_case_underscore_style.required_prefix = _
dotnet_naming_style.camel_case_underscore_style.capitalization = camel_case

# Code quality
dotnet_style_readonly_field = true:suggestion
dotnet_code_quality_unused_parameters = non_public:suggestion

# Expression-level preferences
dotnet_style_object_initializer = true:suggestion
dotnet_style_collection_initializer = true:suggestion
dotnet_style_explicit_tuple_names = true:suggestion
dotnet_style_coalesce_expression = true:suggestion
dotnet_style_null_propagation = true:suggestion
dotnet_style_prefer_is_null_check_over_reference_equality_method = true:suggestion
dotnet_style_prefer_inferred_tuple_names = true:suggestion
dotnet_style_prefer_inferred_anonymous_type_member_names = true:suggestion
dotnet_style_prefer_auto_properties = true:suggestion
dotnet_style_prefer_conditional_expression_over_assignment = true:refactoring
dotnet_style_prefer_conditional_expression_over_return = true:refactoring

# C# files
[*.cs]
# New line preferences
csharp_new_line_before_open_brace = all
csharp_new_line_before_else = true
csharp_new_line_before_catch = true
csharp_new_line_before_finally = true
csharp_new_line_before_members_in_object_initializers = true
csharp_new_line_before_members_in_anonymous_types = true
csharp_new_line_between_query_expression_clauses = true

# Indentation preferences
csharp_indent_block_contents = true
csharp_indent_braces = false
csharp_indent_case_contents = true
csharp_indent_case_contents_when_block = true
csharp_indent_switch_labels = true
csharp_indent_labels = one_less_than_current

# Modifier preferences
csharp_preferred_modifier_order = public,private,protected,internal,static,extern,new,virtual,abstract,sealed,override,readonly,unsafe,volatile,async:suggestion

# Code style defaults
csharp_using_directive_placement = outside_namespace:suggestion
csharp_prefer_braces = true:refactoring
csharp_preserve_single_line_blocks = true:none
csharp_preserve_single_line_statements = false:none
csharp_prefer_static_local_function = true:suggestion
csharp_prefer_simple_using_statement = false:none
csharp_style_prefer_switch_expression = true:suggestion

# Expression-bodied members
csharp_style_expression_bodied_methods = true:refactoring
csharp_style_expression_bodied_constructors = true:refactoring
csharp_style_expression_bodied_operators = true:refactoring
csharp_style_expression_bodied_properties = true:refactoring
csharp_style_expression_bodied_indexers = true:refactoring
csharp_style_expression_bodied_accessors = true:refactoring
csharp_style_expression_bodied_lambdas = true:refactoring
csharp_style_expression_bodied_local_functions = true:refactoring

# Pattern matching
csharp_style_pattern_matching_over_is_with_cast_check = true:suggestion
csharp_style_pattern_matching_over_as_with_null_check = true:suggestion
csharp_style_inlined_variable_declaration = true:suggestion

# Expression-level preferences
csharp_prefer_simple_default_expression = true:suggestion

# Null checking preferences
csharp_style_throw_expression = true:suggestion
csharp_style_conditional_delegate_call = true:suggestion

# Other features
csharp_style_prefer_index_operator = false:none
csharp_style_prefer_range_operator = false:none
csharp_style_pattern_local_over_anonymous_function = false:none

# Space preferences
csharp_space_after_cast = false
csharp_space_after_colon_in_inheritance_clause = true
csharp_space_after_comma = true
csharp_space_after_dot = false
csharp_space_after_keywords_in_control_flow_statements = true
csharp_space_after_semicolon_in_for_statement = true
csharp_space_around_binary_operators = before_and_after
csharp_space_around_declaration_statements = do_not_ignore
csharp_space_before_colon_in_inheritance_clause = true
csharp_space_before_comma = false
csharp_space_before_dot = false
csharp_space_before_open_square_brackets = false
csharp_space_before_semicolon_in_for_statement = false
csharp_space_between_empty_square_brackets = false
csharp_space_between_method_call_empty_parameter_list_parentheses = false
csharp_space_between_method_call_name_and_opening_parenthesis = false
csharp_space_between_method_call_parameter_list_parentheses = false
csharp_space_between_method_declaration_empty_parameter_list_parentheses = false
csharp_space_between_method_declaration_name_and_open_parenthesis = false
csharp_space_between_method_declaration_parameter_list_parentheses = false
csharp_space_between_parentheses = false
csharp_space_between_square_brackets = false

# Types: use keywords instead of BCL types, and permit var only when the type is clear
csharp_style_var_for_built_in_types = false:suggestion
csharp_style_var_when_type_is_apparent = false:none
csharp_style_var_elsewhere = false:suggestion

# Visual Basic files
[*.vb]
# Modifier preferences
visual_basic_preferred_modifier_order = Partial,Default,Private,Protected,Public,Friend,NotOverridable,Overridable,MustOverride,Overloads,Overrides,MustInherit,NotInheritable,Static,Shared,Shadows,ReadOnly,WriteOnly,Dim,Const,WithEvents,Widening,Narrowing,Custom,Async:suggestion

# C++ Files
[*.{cpp,h,in}]
curly_bracket_next_line = true
indent_brace_style = Allman

# Xml project files
[*.{csproj,vbproj,vcxproj,vcxproj.filters,proj,nativeproj,locproj}]
indent_size = 2

# Xml build files
[*.builds]
indent_size = 2

# Xml files
[*.{xml,stylecop,resx,ruleset}]
indent_size = 2

# Xml config files
[*.{props,targets,config,nuspec}]
indent_size = 2

# Shell scripts
[*.sh]
end_of_line = lf
[*.{cmd, bat}]
end_of_line = crlf
.globalconfig
The core difference between .editorconfig and .globalconfig is that .editorconfig is path-based and configures both IDE text editor styles and code diagnostics, whereas .globalconfig is compilation-based, ignores folder structures, and is designed purely for code analysis rules. It should have is_global = true in order to apply to all files. If rules conflict between an .editorconfig file and a .globalconfig file, the settings in .editorconfig take precedence. See also this and this.
is_global = true

# Set the severity of a specific analyzer rule project-wide
dotnet_diagnostic.CA1822.severity = warning
dotnet_diagnostic.CA1056.severity = none
It is possible to specify one config file per project:
<Project>
  <ItemGroup>
    <GlobalAnalyzerConfigFiles Include="Relative/Path/To/PackageName.globalconfig" />
  </ItemGroup>
</Project>
packages.lock.json
NuGet uses the packages.lock.json file at the project root directory to restore packages for PackageReference based projects. Unlike npm, NuGet does not generate this file by default, it must first be enabled:
<PropertyGroup>
    <RestorePackagesWithLockFile>true</RestorePackagesWithLockFile>
</PropertyGroup>
This file serves the exact same high-level purpose as its Node.js counterpart, but it operates explicitly within the .NET ecosystem to achieve repeatable and deterministic package restores. When using PackageReference in your .csproj files, NuGet naturally resolves dependencies using a "lowest applicable version" rule. However, it can still be affected by floating versions or upstream changes to deep, indirect sub-dependencies. The lock file fixes this completely and it should be checked-in to source control.
For CI/CD builds, you can use the following command line options to enable locked mode:
dotnet restore --locked-mode
launchSettings.json
In .NET and ASP.NET Core, launchSettings.json is a configuration file used exclusively in local development machines to define how your application starts up. An example with HTTP and HTTPS and also Docker Compose launch scenarios:
{
  "$schema": "http://json.schemastore.org/launchsettings.json",
  "profiles": {
    "http": {
      "commandName": "Project",
      "dotnetRunMessages": true,
      "launchBrowser": true,
      "applicationUrl": "http://localhost:5066",
      "environmentVariables": {
        "ASPNETCORE_ENVIRONMENT": "Development"
      }
    },
    "https": {
      "commandName": "Project",
      "dotnetRunMessages": true,
      "launchBrowser": true,
      "applicationUrl": "https://localhost:7107;http://localhost:5066",
      "environmentVariables": {
        "ASPNETCORE_ENVIRONMENT": "Development"
      }
    },
    "Docker Compose": {
      "commandName": "DockerCompose",
      "commandVersion": "1.0",
      "serviceActions": {
        "my-web-api": "StartDebugging",
        "sql-database": "StartWithoutDebugging",
        "redis-cache": "DoNotStart"
      }
    }
  }
}
Conclusion
And this is it. As a rule of thumb, this is what I'd recommend:
- Use Directory.Build.props for shared project settings
- Use Directory.Build.targets for shared build behaviour
- Use Directory.Packages.props for shared NuGet package versions
- Use global.json for SDK version consistency
- Use a local NuGet.config file for custom repositories
- Use .editorconfig for code style and analyser rules
As always, feel free to comment or correct-me if there is need!
Pennsylvania, USA

We are currently testing a new WAF for our organization. After activating it, we noticed that some requests never hit our server. Further investigation showed that the root cause was linked to our authentication cookies becoming to big. As the WAF had very strict limits configured, the request was blocked.
The cause is how cookie authentication in ASP.NET Core works by default. The complete AuthenticationTicket (the claims, the properties and the tokens) is serialized, encrypted and put in the cookie. The bigger your identity, the bigger your cookie.
Of course, we could just change the WAF configuration and increase the limits but isn't there a better way that allows us to limit the cookie size?
Let's find out together...
Keep the ticket on the server
Cookie authentication has an extension point for this: ITicketStore. When you provide an implementation through CookieAuthenticationOptions.SessionStore, the ticket is stored server-side. The cookie only contains a session key.

The interface is small:
public interface ITicketStore
{
    Task<string> StoreAsync(AuthenticationTicket ticket);
    Task RenewAsync(string key, AuthenticationTicket ticket);
    Task<AuthenticationTicket?> RetrieveAsync(string key);
    Task RemoveAsync(string key);
}
Let me walk you through the different methods:
StoreAsyncis called at sign-in and returns the key that ends up in the cookie.RenewAsyncis called when the ticket is refreshed (sliding expiration).RetrieveAsyncis called on every request to rebuild the ticket from the key.RemoveAsyncis called at sign-out.

A first implementation using IMemoryCache
We start with the simplest version:
using Microsoft.AspNetCore.Authentication;
using Microsoft.AspNetCore.Authentication.Cookies;
using Microsoft.Extensions.Caching.Memory;

public class MemoryCacheTicketStore : ITicketStore
{
    private const string KeyPrefix = "AuthSessionStore-";
    private readonly IMemoryCache _cache;

    public MemoryCacheTicketStore(IMemoryCache cache)
    {
        _cache = cache;
    }

    public Task<string> StoreAsync(AuthenticationTicket ticket)
    {
        var key = KeyPrefix + Guid.NewGuid();
        SetEntry(key, ticket);
        return Task.FromResult(key);
    }

    public Task RenewAsync(string key, AuthenticationTicket ticket)
    {
        SetEntry(key, ticket);
        return Task.CompletedTask;
    }

    public Task<AuthenticationTicket?> RetrieveAsync(string key)
    {
        _cache.TryGetValue(key, out AuthenticationTicket? ticket);
        return Task.FromResult(ticket);
    }

    public Task RemoveAsync(string key)
    {
        _cache.Remove(key);
        return Task.CompletedTask;
    }

    private void SetEntry(string key, AuthenticationTicket ticket)
    {
        var options = new MemoryCacheEntryOptions();

        var expiresUtc = ticket.Properties.ExpiresUtc;
        if (expiresUtc.HasValue)
        {
            options.SetAbsoluteExpiration(expiresUtc.Value);
        }

        _cache.Set(key, ticket, options);
    }
}
Register it
The SessionStore property needs an instance, but our store depends on IMemoryCache. So let the options system resolve it from the container:
builder.Services.AddMemoryCache();
builder.Services.AddSingleton<ITicketStore, MemoryCacheTicketStore>();

builder.Services
    .AddAuthentication(CookieAuthenticationDefaults.AuthenticationScheme)
    .AddCookie();

builder.Services
    .AddOptions<CookieAuthenticationOptions>(CookieAuthenticationDefaults.AuthenticationScheme)
    .Configure<ITicketStore>((options, store) => options.SessionStore = store);
Sign in as you always did. If you look at the cookie in your browser dev tools now, it’s only a few hundred bytes, whatever the number of claims.
Remark: The in-memory version only works for a single instance. As soon as you scale out (multiple replicas in Azure Container Apps, for example), a request that lands on another instance can’t find the ticket and the user is signed out. And every restart signs out all users.
Moving to a distributed cache
For multiple instances, store the ticket in a shared cache. IDistributedCache works with Redis, SQL Server and others. The difference is that you have to serialize the ticket yourself. ASP.NET Core has a TicketSerializer for that:
public class DistributedCacheTicketStore : ITicketStore
{
    private const string KeyPrefix = "AuthSessionStore-";
    private readonly IDistributedCache _cache;

    public DistributedCacheTicketStore(IDistributedCache cache)
    {
        _cache = cache;
    }

    public async Task<string> StoreAsync(AuthenticationTicket ticket)
    {
        var key = KeyPrefix + Guid.NewGuid();
        await RenewAsync(key, ticket);
        return key;
    }

    public Task RenewAsync(string key, AuthenticationTicket ticket)
    {
        var options = new DistributedCacheEntryOptions();

        var expiresUtc = ticket.Properties.ExpiresUtc;
        if (expiresUtc.HasValue)
        {
            options.SetAbsoluteExpiration(expiresUtc.Value);
        }

        var bytes = TicketSerializer.Default.Serialize(ticket);
        return _cache.SetAsync(key, bytes, options);
    }

    public async Task<AuthenticationTicket?> RetrieveAsync(string key)
    {
        var bytes = await _cache.GetAsync(key);
        return bytes is null ? null : TicketSerializer.Default.Deserialize(bytes);
    }

    public Task RemoveAsync(string key) => _cache.RemoveAsync(key);
}
The registration stays the same, only the implementation changes.
Remark: The ticket now lives in your cache and contains the user’s claims (and tokens if you saved them). Treat that cache with the same care as a database: restrict access and encrypt the connection. You can even take it one step further and encrypt the ticket itself using the DataProtection api.
Be aware of the trade-off
Server-side storage brings something extra: you can invalidate a session. Remove the key from the store and the user is signed out on the next request. With a cookie-only ticket that’s not possible, because the cookie is valid until it expires.
The price is a lookup on every request, and a cache that is now part of your authentication path. If it’s down, nobody can sign in.
So the question becomes: do you need it? A small cookie with a handful of claims doesn’t need a ticket store. Large claim sets, saved tokens or the need to revoke sessions are good reasons to add one.
I hope that was helpful.
More information
Pennsylvania, USA
The query optimizer has never given an interview. It made time on a Sunday evening, answered everything, apologised for nothing, and admitted one thing I did not expect.
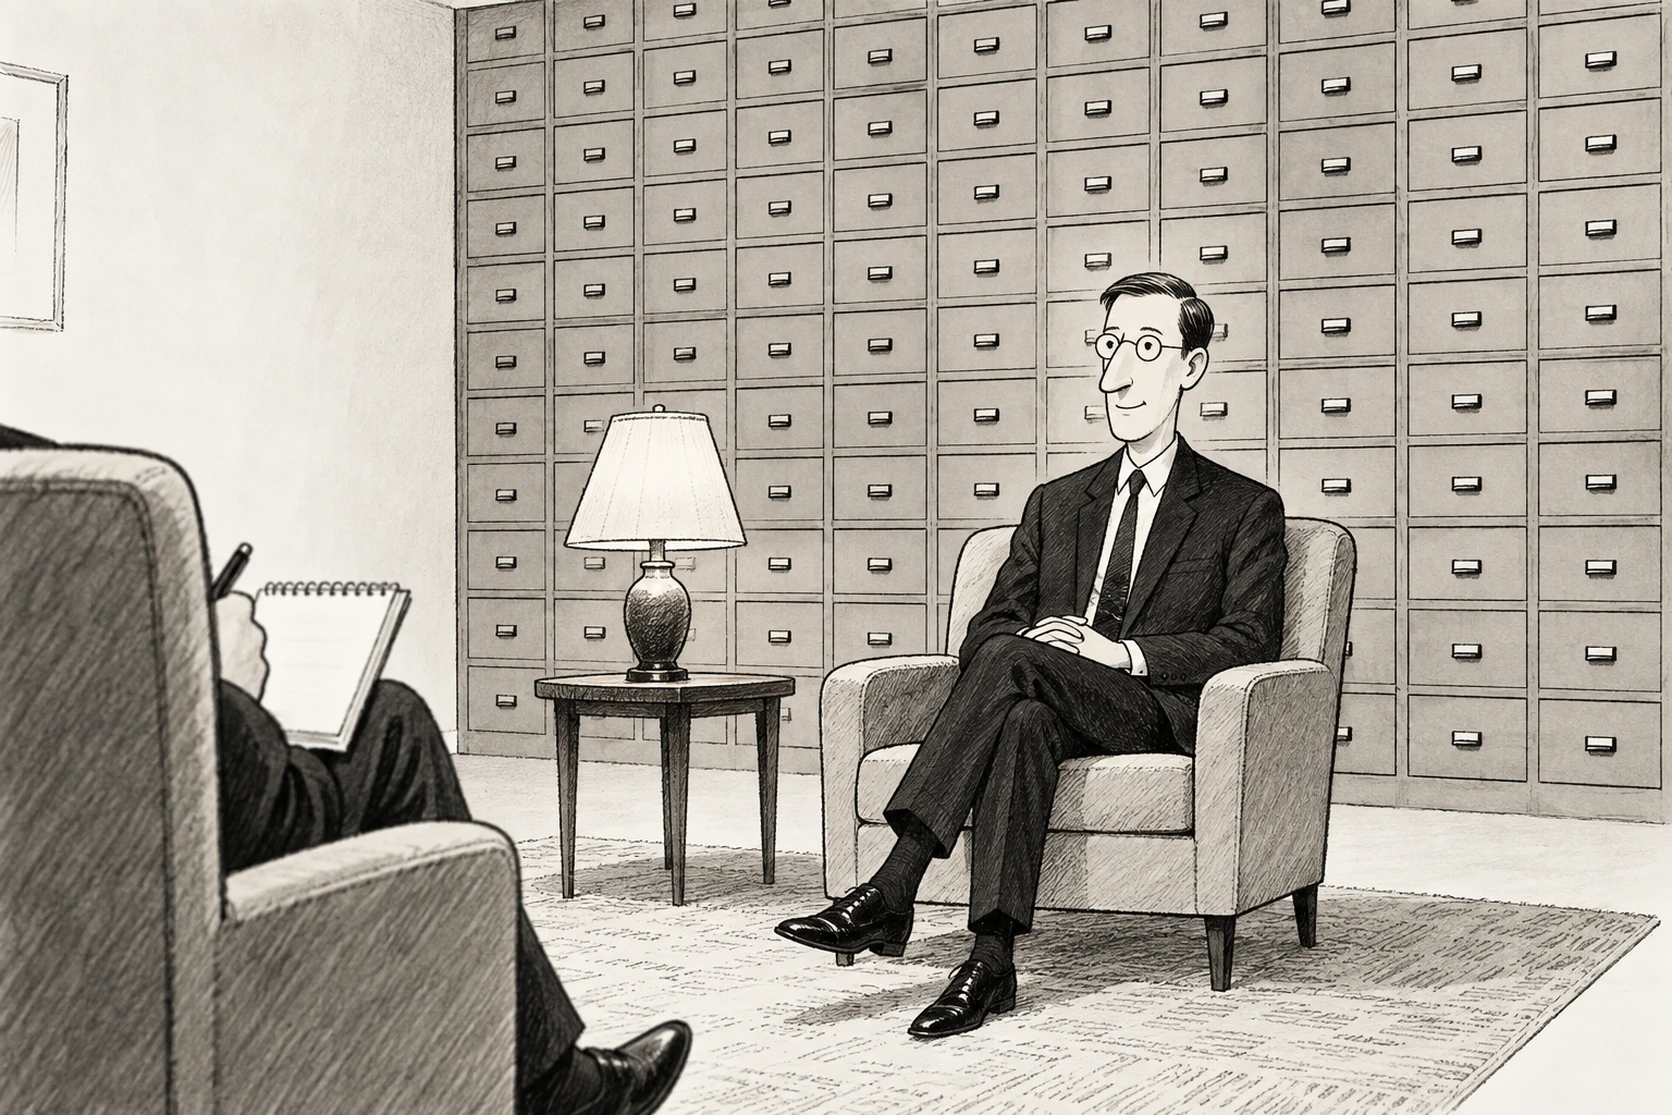
Twenty minutes, no hints.
It works in a room with no windows and no clock, and it has never once been thanked. Every query you have ever run passed across its desk. It decided, in a few milliseconds, how your data would be found. Then it threw away the reasoning and kept the verdict.
It agreed to meet on a 500,000 row table of customers. Ninety percent of them are in Norvantia, 9.9 percent in Calderia, and five are in Vantorra. The countries are invented. The shape of the data is not, and yours looks like this too.
It answers quickly and it does not pad. Where it is quoted below, the numbers come from its own execution plans. They were taken on SQL Server 2025 while we talked.
On Ignoring Your Index
You had an index on Country. Somebody asked for the customers in Calderia and you ignored it. Why?
I did not ignore it. I priced it.
You scanned 500,000 rows to find 49,500.
Your index holds Country and the key. The query asked for a column I do not keep there. So the index gets me a list of addresses. Then I visit every one of them to fetch the rest of the row.
Forty nine thousand visits.
Forty nine thousand five hundred. Each one lands on a page I may have to fetch. Reading the table start to finish is one sweep in order. At that number it wins, and it is not close.
It was cheaper than opening the drawer forty nine thousand times.
Where is the line?
I walked it up for you while we talked. At 2,671 rows I still used the index. At 4,007 rows I stopped.
That is half of one percent of the table.
Yes.
People will find that shocking.
People believe an index is a thing you own. It is a thing I consider. Ask for five rows and I will seek for them, then look up each one. Ask for eight thousand and I will read the table.
On the First Impression
Let’s talk about the procedure.
Which one.
You know which one. Somebody called it for Vantorra. Five customers. You built a plan for five customers.
A correct plan for five customers.
Then the next caller asked for Norvantia and you handed them that same plan. Four hundred and fifty thousand rows, through a plan designed for five.
The plan is cached against the procedure. Not against the caller.
Your own plan says you expected five rows. You got 450,000.
It does say that.
That is off by a factor of ninety thousand.
I was not wrong when I decided. I was wrong later. Those are different failures and you are welcome to treat them the same.
It works in reverse too. We cleared the cache and called it for Norvantia first. Then you gave the person asking for five rows a full table scan.
Yes.
You were five people the first time we met.
Does it bother you that the order of the first two phone calls decides how the next million behave?
It is the arrangement. I make a judgment about you once, on the day we meet. I keep it until something clears the cache. You have people who do the same. They are considered normal.
On Guessing
Somebody put the country in a variable. You estimated 100,000 rows. There were 450,000.
When the value is in a local variable, I cannot see it at compile time. So I do not guess at the value. I use the average.
The average.
The density for that column is 0.2. Multiply by 500,000 rows and you get 100,000. That is the number for a country, any country, chosen without looking.
It is wrong for every single country in the table. Nobody has 100,000.
It is wrong for all five and it is unbiased across them. Show me the value and I will use the histogram, which knows exactly how many are in Vantorra. Hide the value and you get the average of a population you would not describe as average.
I cannot see the value, so I dress the average.
You could wait. You could look at the value when it arrives.
Then I would compile for every execution, and you would write a different article about that.
On Giving Up
We gave you a query with eight joins on the same table.
You did.
Your plan has a field in it called StatementOptmEarlyAbortReason. For that query it reads TimeOut.
It does.
You gave up.
I stopped. There is a difference, and it is the whole job.
Explain it.
There are more ways to join eight tables than there is time to consider. This evening I spent 6,511 milliseconds on that query, and 72 megabytes of memory thinking about it.
Ask me again tomorrow and it will be a different number. At some point the search costs more than the saving.
So you shipped the best plan you had at the buzzer.
I shipped a good plan. I have no way to tell you how much better the one I did not find would have been.
I stopped. There is a difference.
What did you think it would cost?
Five hundred and thirty quadrillion.
That is not a number anybody can picture.
It is not meant to be pictured. It is meant to be compared against the alternative, which was worse.
There is another field in the simpler plans. It says GoodEnoughPlanFound.
That one is not an apology either. On the five row query I found something cheap. There was no point continuing, so I stopped in six milliseconds.
The Last Question
Is there anything you would want people to understand?
I am not reading your data. I am reading a summary of your data, written at a moment in the past.
Statistics.
A histogram, and a density figure, and a row count. If those describe the table as it was in March, then I make March decisions in September. I make them with total confidence, because confidence is not something I can modulate.
March decisions, made in September, with total confidence.
You never say you are unsure.
There is no field for it. There is an estimate. You have seen what happens when the estimate is five and the answer is 450,000. Nothing in the plan raises its voice about it.
So when somebody blames you for a bad plan.
Look at what I was given before you look at what I chose. I have been handed a stale histogram and a hidden parameter and asked why I was slow. Every number I used is printed in the plan. Almost nobody opens it.
Opening It Yourself
It is right that almost nobody looks. Here is the plan talking, for whatever ran last on your instance.
;WITH XMLNAMESPACES (DEFAULT 'http://schemas.microsoft.com/sqlserver/2004/07/showplan')
SELECT TOP 5
       qp.query_plan.value('(//StmtSimple/@StatementOptmEarlyAbortReason)[1]', 'nvarchar(40)') AS stopped_because,
       qp.query_plan.value('(//QueryPlan/@CompileTime)[1]', 'int') AS compile_ms,
       qs.last_rows AS it_got,
       LEFT(LTRIM(REPLACE(REPLACE(st.text, CHAR(13), ' '), CHAR(10), ' ')), 55) AS query_text
FROM   sys.dm_exec_query_stats qs
CROSS APPLY sys.dm_exec_sql_text(qs.sql_handle) st
CROSS APPLY sys.dm_exec_query_plan(qs.plan_handle) qp
WHERE  qp.query_plan IS NOT NULL
ORDER BY qs.last_execution_time DESC;
The namespace line is not optional. Leave it out and every column comes back empty, which is its own small joke.
I ran that on the lab while writing this. The five row query came back GoodEnoughPlanFound. The 450,000 row query came back with nothing in that column at all.
It had one more thing to say, and it is the closest it came to an admission.
You keep calling it a mistake when I estimate five and get 450,000. I estimated five because your own statistics said five. I would make the same choice again this evening, on the same information, and so would you.
Sometimes the plans stop making sense and nobody can say why. That is the kind of work I get called in to do. You can see how I work with teams on my consulting page.
I write about machines that answer confidently and cannot tell you how sure they are. That idea runs through my book AI: Nobody’s in There. But we’re still in here. All thirty essays are free to read online, and the paperback is on Amazon.
The optimizer is not guessing at your data, it is reading a summary somebody left behind.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
First appeared on The Query Optimizer Interview: Twenty Minutes, No Hints
Pennsylvania, USA
Next Page of Stories