Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162918 stories
·
33 followers

From 2,500 requests to 24: Rebuilding star history without the stargazers

1 Share

Maintainers look at star history to answer a practical question: did a launch, release, or event change a project’s trajectory? To reconstruct that curve from the GitHub API, tools had to request pages of stargazer records (each person who currently stars the repository and when they starred it), keep the timestamps, and throw the identities away.

Over time, that design created problems at both ends. Identities were available for bulk collection, so bad actors started scraping public stargazer lists for spam and phishing campaigns. For highly starred repositories, the endpoint could also make the database process many thousands of entries to return a single page.

The fix seemed clear: return counts instead of people. But returning less data didn’t actually make the query any cheaper.

Now maintainers have a direct way to get the curve: we built an endpoint that returns up to 30 weeks of daily star counts in a single request, with no identities attached. Keeping that cheap to serve meant reducing how much data the database processed, not just how much it returned, and the endpoint does that by filtering stars by time before it counts anything.

What maintainers need from star history

We first addressed the immediate risks to developers and to our database by restricting stargazer and watcher lists to repository administrators and collaborators. After the access change, callers without the required permission could receive an empty response or a 403 Forbidden response.

That change also cut off tools that had used the old response to calculate star history, often without displaying or otherwise using the usernames it returned. So we talked with maintainers and tool builders to understand what they still needed. They used star history as an approximate signal of interest: to compare activity before and after a release, or to see whether an announcement reached new developers. What they cared about was the curve.

The old API response had made identity look like part of that contract because every timestamp arrived attached to a user. In practice, tools such as Star History needed counts and dates, not usernames or other user data. Once identity was no longer part of the requirement, we could design an aggregate endpoint for the actual job: retrieving changes in star counts over time at a useful resolution.

When the API change disrupted Star History, users rallied around the project. GitHub’s Community team listened and connected us with product engineering, who dug into our use case and worked alongside us to design a purpose-built endpoint. A difficult situation became a constructive collaboration between GitHub, Star History, and the broader community—ultimately leading to a better solution.

Tianzhou Chen, star-history.com maintainer and Bytebase co-founder

Why the original endpoint was expensive

Once we knew what maintainers needed, the next step was understanding why the original design couldn’t provide it cheaply. The original GET /repos/{owner}/{repo}/stargazers endpoint was built to answer a simple question: who starred this repository? It returned a paginated list of people, and if the request specified a custom media type, each entry also included when the star was created.

The star model was built for the same job. It records the current set of people who have starred a repository, which keeps showing a star count or a list of stargazers simple. It was not designed as a historical event log: when someone removes a star, that record is removed. When tools began using the list as a time series, reconstructing a growth curve meant retrieving individual identities and processing every current star. Because each page held at most 100 people, the work grew with the repository’s popularity: building the full curve for react/react, with about 251,000 stars, took about 2,511 requests, so tools often ran into rate limits or sampled pages instead of reading them all.

Serving a page required the database to query the repository’s current stars. Due to a bug in the pagination implementation, every request also counted all of those stars to work out how many pages existed, even though the caller received only one page of up to 100 people. On a highly starred repository, that meant counting many thousands of entries on every request. In the week before we restricted access, nearly 37,000 of these count queries ran slowly enough to be logged, averaging nearly 3 seconds each, and database safeguards killed more than 1,000 of them, which contributed to request timeouts.

The chart below shows what all that counting cost. After we restricted access, the database served about 60% fewer stargazer requests, and the total time it spent on the count query fell by about 80%.

Approaches we considered

Removing identities handled the privacy requirement. The harder part was keeping each request from scanning the repository’s entire current star set.

Keeping events without identities

Our first spike kept one record per star and returned the starred_at value without the stargazer’s identity for callers who lacked collaborator access. At first, this looked like the quickest path forward, because it directly served the request we had heard from tool builders. It also closed the identity-harvesting path with a relatively small change to the existing serialization and authorization flow.

This approach addressed identity exposure and would have allowed existing tools to keep working. But API consumers would still have to paginate through and process potentially many thousands of individual records to build an aggregate history. It also tied the new use case to an endpoint and pagination model designed for listing people rather than retrieving trends.

Aggregating, then paginating

Aggregation seemed like the obvious next step. Instead of returning one row per star, the query could group stars into daily or weekly buckets, sort those buckets, and paginate the much smaller result.

The problem was where pagination happened. In a straightforward SQL query, the database first finds all stars for the repository, groups them into buckets, and sorts those buckets. Only then does it apply LIMIT, which controls how many buckets are returned, and OFFSET, which determines where the page begins:

all matching stars -> bucket every row by day or week -> sort every bucket -> OFFSET/LIMIT -> response

For a popular repository, an anonymous request could still scan and aggregate many thousands of index entries to return a handful of buckets. Returning fewer buckets would shrink the JSON response, but it would not reduce the expensive grouping and sorting the database had already performed. For react/react, reading the full history that way would have meant examining roughly 6 million rows, because every one of the 24 requests would have reprocessed all of its stars. To reduce the query cost, we had to narrow the rows before aggregation began.

Filtering by time before grouping

The design we shipped paginates star history by calendar week. For each request, it translates page and per_page into an indexed created_at range, filters the stars to those weeks, and then groups the matching records into daily counts. A response includes up to 30 weeks, and increasing page moves backward through the repository’s history.

indexed date range -> group rows in that range -> daily buckets -> response

With the date range applied first, each request processes the weeks being returned instead of every current star in the repository. For tools, that means one request now covers up to 30 weeks of history, no matter how many stars the repository has. For react/react, that’s about 24 requests instead of about 2,511, and the database examines each star about once (roughly 251,000 rows) across the full history. This fits the primary use case because maintainers usually inspect growth across weeks or around a known release, launch, or event. Week-based ranges also align with other repository activity APIs: the response follows the same shape as the weekly commit activity endpoint, GET /repos/{owner}/{repo}/stats/commit_activity.

The time-range design limits each request to a defined period, but it does not limit the number of stars within that range. A week with an unusually large number of stars can therefore still produce a slow or expensive query. The normal request path no longer queries every current star, but exceptionally dense weeks remain a scaling limitation.

Comparing the performance of the old and new API paths also surfaced other places where GitHub was counting stars on demand. We found the same pattern on the repository stargazers page on GitHub.com and updated it to use the repository’s cached star count. Slow queries from that page, which had numbered in the hundreds each week, dropped to zero. We recently shipped a similar fix to other stargazer API endpoints.

The chart below shows slow and killed stargazer count queries each week, by where they came from.

What we learned

  1. A smaller response does not always mean a cheaper query. LIMIT and OFFSET reduced the number of results returned, but they did not reduce the grouping and sorting the database had already done. We had to look at the order in which the work happened.
  2. Start with what people are actually trying to do. Maintainers needed to compare trends. A list of identities was simply how the old endpoint happened to provide the underlying data.
  3. Return only what the use case needs. Anything more is data someone else can misuse. Once we understood the job, we could remove individual identities without taking away the information maintainers relied on.
  4. Be clear about the tradeoffs that remain. The new endpoint is safer and more predictable, but calendar boundaries, removed stars, and unusually dense weeks still affect what it can return. Those details are part of the API contract too.

Restricting the original endpoint addressed the immediate problem. Listening to maintainers gave us something better than what we started with: star history that’s easier to get, cheaper to serve, and safer for everyone who stars a project.

Get repository star history, then share feedback in the GitHub Community discussion.

The post From 2,500 requests to 24: Rebuilding star history without the stargazers appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
13 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Reliable Document AI in .NET: LLM Tool Calling vs. LLM-Generated Files

1 Share
Reliable document AI needs a deterministic engine. With LLM tool calling, the LLM decides what the document should contain, and TX Text Control generates the file.

Read the whole story
alvinashcraft
31 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Better HTTP/1 connection reuse

1 Share

The Go Blog

Better HTTP/1 connection reuse

Nicholas Husin and Damien Neil
14 October 2026

Take a look at the following function:

func getStatus(url string) (int, error) {
    resp, err := http.Get(url)
    if err != nil {
        return 0, err
    }
    defer resp.Body.Close()
    return resp.StatusCode, nil
}

It sends a GET request to url and returns the HTTP status code.

Using HTTP/1 (GODEBUG=http2client=0), calling this function 100 times against index.golang.org takes ~710 milliseconds on Go 1.26 on my machine. On Go 1.27, the same program takes ~150 milliseconds.

That is almost 5 times faster! How is such a drastic performance difference possible?

The cost of establishing HTTP connections

To understand the difference, consider what happens on the network when we make an HTTP request.

Go’s net/http package supports HTTP/1.0, HTTP/1.1, and HTTP/2. All three run over TCP, and usually over TLS when talking to HTTPS endpoints. Making a request over a new connection looks something like this:

  1. TCP handshake (1 RTT): the client sends a SYN packet, the server replies with SYN-ACK, and the client replies with ACK. Because the client can send the first TLS message alongside that final ACK, establishing the TCP connection takes 1 round-trip time (RTT).
  2. TLS handshake (2 RTT): next, a TLS handshake exchanges encryption keys and verifies the server’s identity; using TLS 1.2, this takes 2 RTT.
  3. HTTP request: with the keys exchanged, HTTP requests can finally be sent after a total of 3 RTT.

These round trips (plus some CPU time spent on TLS handshakes) add up quickly. In cross-region communications, one-way latencies often reach or exceed the 50 ms (100 ms RTT) shown in the diagram above. Compared to the 300 ms spent just setting up the connection, the HTTP request itself can be cheap to serve, taking only a little over 1 RTT when bandwidth is plentiful or the HTTP response is small.

Even in more favorable conditions, opening a new connection can still be expensive. Our opening benchmark queries index.golang.org, which is distributed worldwide and supports TLS 1.3. This means that latency is relatively low, and the TLS handshake can actually finish in just 1 RTT. Even so, the performance difference is still very noticeable.

Connection reuse

To avoid paying this setup cost on every request, HTTP clients and servers try to reuse existing connections across multiple requests when possible. The mechanics of this differ based on the HTTP version:

  • HTTP/1.0: while not part of the official specification, clients and servers often opt into connection reuse by sending a Connection: keep-alive header. Reuse continues until either endpoint omits the header or sends a Connection: close header.
  • HTTP/1.1: connections are persistent by default, and can be reused for subsequent requests and responses unless either side declares otherwise by sending a Connection: close header.
  • HTTP/2: multiple requests and responses can be multiplexed over a single TCP connection.

When connection reuse fails

In HTTP/1 (both HTTP/1.0 and HTTP/1.1), multiple requests and responses on the same connection are sent sequentially on the wire. If two GET requests are sent to index.golang.org over the same TCP connection, the responses arrive as a single stream of bytes:

As shown in the diagram, net/http.Get reads and parses the status line and headers from the byte stream to populate net/http.Response, then returns immediately. The response body remains unread on the connection and is consumed only as the caller reads from net/http.Response.Body.

Because responses are sent back-to-back on the same stream, net/http can only find the start of the next response after the current response body has been read to the very end (as determined by the Content-Length or Transfer-Encoding header).

Now look back at our example program, where we never read resp.Body:

func getStatus(url string) (int, error) {
    resp, err := http.Get(url)
    if err != nil {
        return 0, err
    }
    defer resp.Body.Close()
    return resp.StatusCode, nil
}

Through Go 1.26, when resp.Body.Close is called, net/http sees that there is still an unread response body. Realizing that it cannot reuse the connection, it abandons the existing connection and creates new connections for its next requests, causing it to repeatedly incur the cost of establishing new connections.

(HTTP/2 does not have this problem. Because it multiplexes streams of frames over a single connection rather than sending responses strictly back-to-back, an unread response body on one stream does not block other requests from sharing the connection.)

Where failed connection reuse hurts

This subtlety of HTTP/1 connection reuse can cause silent performance degradation in seemingly innocuous code.

As in our opening example, a client might only care about an API response’s status code. However, the API endpoint it is talking to might send bodies that provide more detailed but ultimately unused information, such as {"success": true, "message": "update processed"}. This will unfortunately cause connection reuse to fail.

Even programs that do read the response body can run into this issue if they stop just short of the end of the body. For example, encoding/json.Decoder stops reading as soon as it sees the closing } of a JSON object. If a server sends a JSON response terminated with a newline, decoding the JSON object will leave the newline still unread. The connection cannot be reused for a new request until that newline is consumed. Thus, a healthy connection might end up being abandoned, even though it was only a single byte away from being reusable.

The manual solution

The unread body problem has been a long-standing sharp edge. Over the years, many Go developers came up with their own workarounds. Most commonly, this is done by draining the response body prior to closing it:

func getStatus(url string) (int, error) {
    resp, err := http.Get(url)
    if err != nil {
        return 0, err
    }
    drainAndCloseBody(resp.Body)
    return resp.StatusCode, nil
}

func drainAndCloseBody(body io.ReadCloser) {
    io.Copy(io.Discard, body) // Drain the response body before closing it.
    body.Close()
}

While this works for small responses, if the unread body is large, establishing a new TCP connection can be faster than downloading and discarding the rest of the body. A better approach is to cap the number of bytes we are willing to drain:

func drainAndCloseBody(body io.ReadCloser) {
    io.CopyN(io.Discard, body, 256<<10) // Only drain up to 256 KB.
    body.Close()
}

However, a server might send a response body that trickles in slowly, so we also need to cap the time we spend draining:

func drainAndCloseBody(body io.ReadCloser) {
    drainDone := make(chan struct{}, 1)
    go func() {
        io.CopyN(io.Discard, body, 256<<10) // Only drain up to 256 KB.
        drainDone <- struct{}{}
    }()
    // Only spend at most 50 ms trying to drain the response body.
    select {
    case <-drainDone:
    case <-time.After(50 * time.Millisecond):
        // If we reach the 50 ms timeout, body.Close will run and interrupt the
        // io.CopyN, preventing goroutine leaks.
    }
    body.Close()
}

Of course, we also do not want to block for up to 50 milliseconds when closing a response body. Instead, we can drain the body asynchronously in the background and let it race against subsequent requests:

func drainAndCloseBody(body io.ReadCloser) {
    drainDone := make(chan struct{}, 1)
    go func() {
        io.CopyN(io.Discard, body, 256<<10) // Only drain up to 256 KB.
        drainDone <- struct{}{}
    }()
    go func() {
        // Only spend at most 50 ms trying to drain the response body.
        select {
        case <-drainDone:
            // If the drain can finish before a new request is sent, the
            // connection will be reused; otherwise, a new connection is
            // created, and the current connection will be put in a pool of
            // idle connections, potentially being reused for another future
            // request.
        case <-time.After(50 * time.Millisecond):
            // If we reach the 50 ms timeout, body.Close will run and interrupt
            // the io.CopyN, preventing goroutine leaks.
        }
        body.Close()
    }()
}

As we can see, draining response bodies safely is surprisingly tricky and cumbersome. Worse, as the practice of draining response bodies spread, some nuances were often lost. This has led to misunderstandings such as attempting to drain response bodies for HTTP/2 connections, when doing so is unnecessary.

The current state and conclusion

Starting in Go 1.27, net/http.Transport automatically does everything we have implemented in the code above: it will asynchronously drain an unread HTTP/1 response body for up to 50 ms or 256 KB. It also implements additional optimizations; for example, when a response contains the Connection: close header, draining the body is guaranteed to be wasted work, and it therefore skips doing so. Note that this behavior might evolve in future versions of Go, as other possible enhancements become apparent.

As a general best practice, we now recommend that users simply close their HTTP bodies once they no longer need them, like in our original example:

func getStatus(url string) (int, error) {
    resp, err := http.Get(url)
    if err != nil {
        return 0, err
    }
    defer resp.Body.Close()
    return resp.StatusCode, nil
}

Go is all about simplicity. Let your code stay clean and simple, and let net/http deal with the complexities on your behalf.

Previous article: Arch-specific SIMD in Go
Blog Index

Read the whole story
alvinashcraft
41 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

ByteAether.Ulid v1.4.2 Expands the .NET Ecosystem with ASP.NET Core and CLI Support

1 Share

A production-grade identifier library requires tight integration across data persistence layers, API boundary definitions, and operational tooling. ByteAether.Ulid implements a high-performance, specification-compliant .NET type for the ULID standard, engineering strict monotonicity, throughput optimization, and deterministic ordering under high-concurrency workloads.

The ByteAether.Ulid v1.4.2 release extends the ecosystem beyond the core primitive. Alongside existing data-access integrations, the repository (available on GitHub) now provides two specialized packages targeting modern .NET architectures:

  • ByteAether.Ulid.AspNetCore: Native route constraints, System.Text.Json converters, and OpenAPI schema generators.

  • ByteAether.Ulid.Cli: A cross-platform global tool for generating, parsing, and inspecting ULIDs within shell scripts and operational pipelines.

These abstractions eliminate the need to maintain bespoke serialization layers or conversion adapters on top of the primitive Ulid struct.

Architectural Overview: Moving Beyond the Core Type

The ByteAether.Ulid v1.4.0 release established native ORM and micro-ORM integrations across EF Core, LinqToDB, and Dapper. While this solved low-level database mapping challenges, application boundaries remained unoptimized.

Modern enterprise architectures expose two distinct integration boundaries:

  1. HTTP/RPC API Edge: REST endpoints, Minimal APIs, and MVC controllers demand fast route constraint evaluation, efficient model binding, zero-allocation JSON parsing, and schema generation for OpenAPI definitions.

  2. Operational Tooling: DevOps pipelines, database migration scripts, and debugging sessions require CLI utilities to parse timestamps, extract randomness components, and convert byte representations without writing scratch C# applications.

ByteAether.Ulid.AspNetCore and ByteAether.Ulid.Cli address these requirements while preserving the foundational guarantees of the core ByteAether.Ulid repository: zero-allocation parsing, high throughput, and monotonicity under bursty thread scheduling.

Source-First ASP.NET Core Integration

ByteAether.Ulid.AspNetCore Library Logo

ByteAether.Ulid.AspNetCore introduces native framework bindings for ASP.NET Core pipelines:

  • Route Constraints (:ulid): Evaluates incoming 26-character Base32 route parameters at the routing layer before triggering controller instantiation or delegate execution.

  • System.Text.Json Serialization: Direct JsonConverter<Ulid> and JsonConverter<Ulid?> implementations handling canonical string representations without intermediate allocations.

  • OpenAPI Integration: Schema transformers injecting the string format with a ulid designator into both Microsoft.AspNetCore.OpenApi and Swashbuckle metadata models.

  • Native AOT & Trim Compatibility: Fully compatible with source-generated JSON serializer contexts (JsonSerializerContext) required for Native AOT deployments.

The following implementation demonstrates Minimal API endpoint integration with custom route validation:

using ByteAether.Ulid; using ByteAether.Ulid.AspNetCore; var builder = WebApplication.CreateBuilder(args); builder.Services.AddUlidRouteConstraint(); var app = builder.Build(); app.MapGet("/users/{id:ulid}", (Ulid id) => Results.Ok(new UserResponse(id))); app.Run(); public record UserResponse(Ulid Id);

By handling parsing and model binding at the routing boundary, the framework prevents malformed identifier requests from executing pipeline middleware or reaching application handlers.

For API spec generation, registering the schema transformer ensures client code generators emit strongly typed identifier fields instead of generic string definitions.

Operational Tooling: CLI Generation and Inspection

ByteAether.Ulid.AspNetCore Library Logo

ByteAether.Ulid.Cli provides shell-level operations for inspecting and generating ULIDs.

Install the utility via the .NET SDK tool registry:

dotnet tool install -g ByteAether.Ulid.Cli

Command Usage and Scripting Capabilities

Generate a single string identifier:

ulid

Generate sequential identifiers in batches:

ulid --count 5

Parse and inspect internal structure (extracting Unix timestamp and high-precision randomness payload):

ulid 01AN4Z07BY79KA1307SR9X4MV3

Process standard input streams for log analysis or data transformation pipelines:

cat ulids.txt | ulid --json

Utility Features

  • Format Interoperability: Converts canonical Base32 strings into raw Hexadecimal or System.Guid byte layouts.

  • Deterministic Timestamp Overrides: Accepts custom unix epoch timestamps to reproduce state or generate test fixtures.

  • Structured JSON Output: Emits machine-readable breakdown payloads for ingestion by tools like jq or powershell automation.

System Impact and Adoption

The expanded ByteAether.Ulid ecosystem establishes a uniform model for identifier handling across the runtime lifecycle:

  1. Performance Overhead: The core library remains a memory-efficient, zero-allocation struct implementation.

  2. Persistence Integrity: Dedicated ORM providers maintain raw byte-ordering efficiency at the database index layer.

  3. API Edge Precision: ASP.NET Core extensions validate and serialize inputs without custom application layer code.

  4. Developer Experience: Shell utilities standardise operational introspection and test vector generation.

Package Installation

Add the API dependencies or install the global shell utility:

dotnet add package ByteAether.Ulid.AspNetCore dotnet tool install -g ByteAether.Ulid.Cli

Reference material, core source files, and benchmark suites are accessible in the official ByteAether.Ulid GitHub repository. Nuget packages are hosted on the public package index:

Read the whole story
alvinashcraft
49 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

AI Engineering Skills Roadmap

1 Share

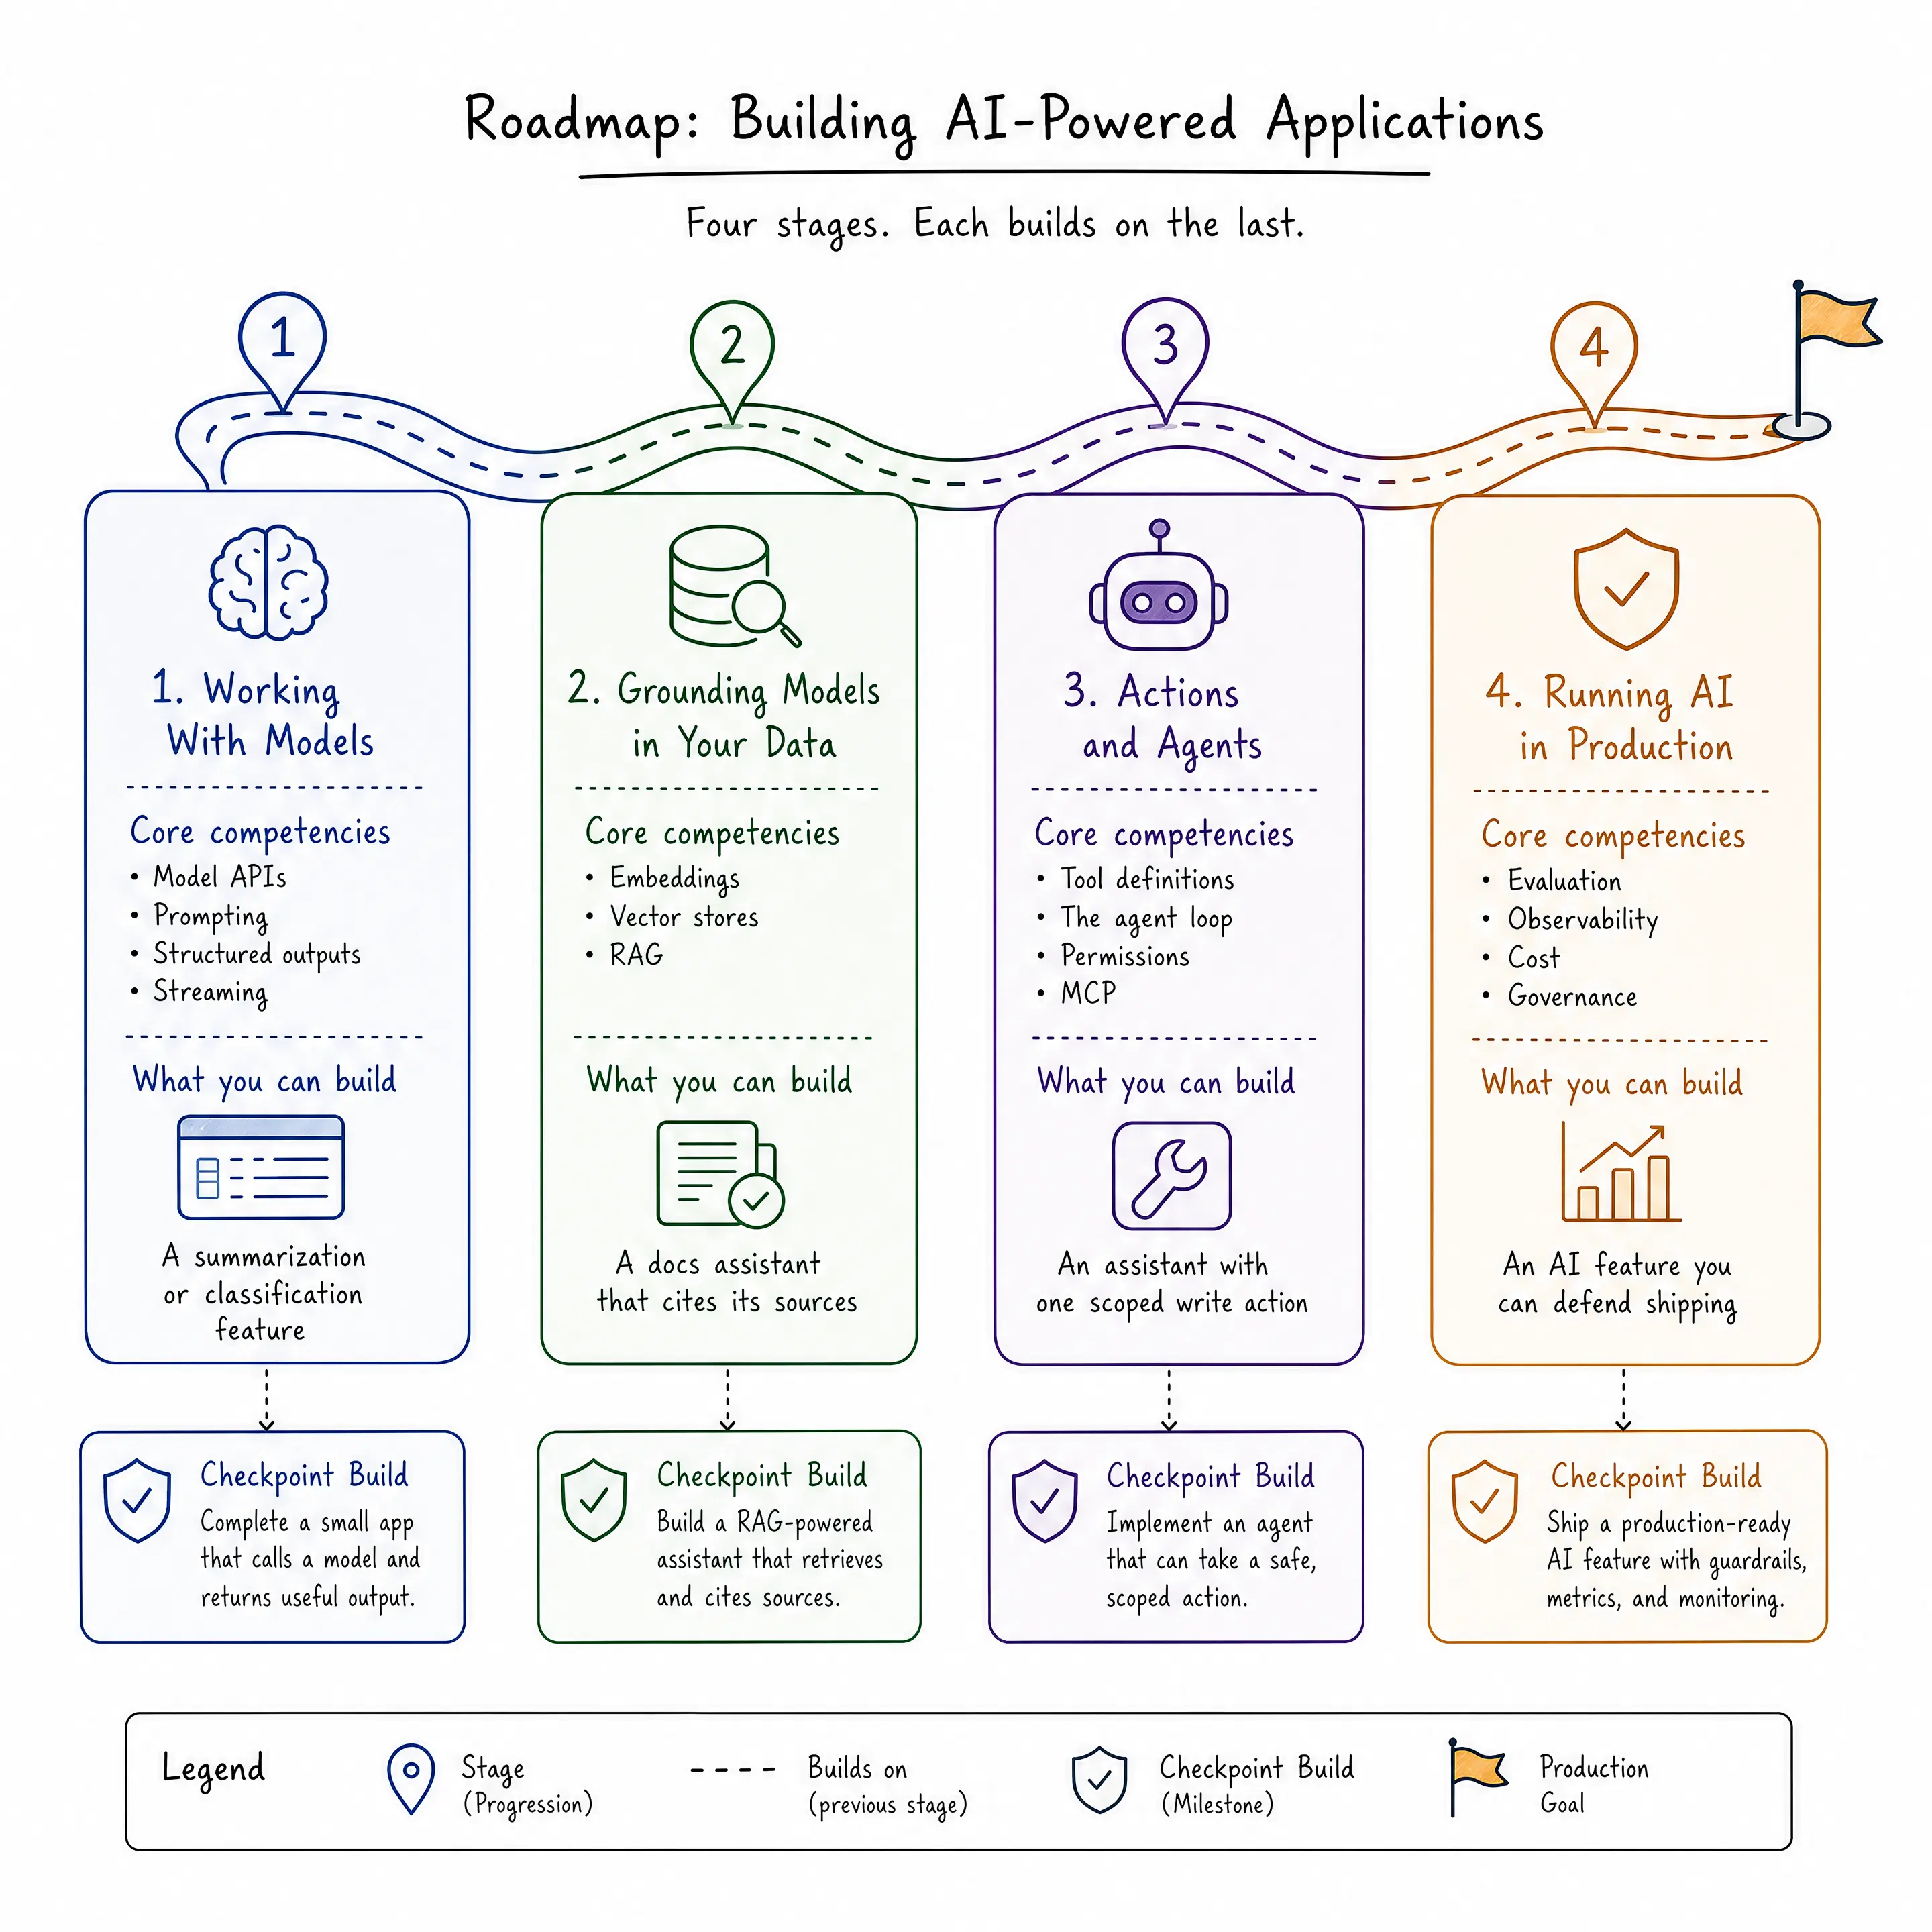
Let’s map out a route for learning the AI stack. Follow these four phases, building on your existing developer skills, to map your learning plan.

Over this AI Engineering Basics series so far, we’ve covered the layers of the modern AI stack, the architecture patterns behind AI features, the components that surround a prompt, and the agent layer now growing between frontend and backend.

Knowing the concepts is one thing. Figuring out what to learn first, and how to tell when we’ve learned it, is the part this article takes on. (This post gives you an overall map of what you need to learn and how it builds on your skills as a developer; it does not provide the in-depth training itself.)

AI engineering is an integration discipline, so most of it builds directly on skills full-stack developers already have. We’ll move through four stages, and each one names the competencies to learn and the tools worth reaching for.

How the Roadmap Is Organized

There are four stages, and each one ends with something concrete to build.

StageCore competenciesWhat you can build after it
1. Working with ModelsModel APIs, prompting, structured outputs, streamingA summarization or classification feature
2. Grounding Models in Your DataEmbeddings, vector stores, RAGA docs assistant that cites its sources
3. Actions and AgentsTool definitions, the agent loop, permissions, MCPAn assistant with one scoped write action
4. Running AI in ProductionEvaluation, observability, cost, governanceAn AI feature you can defend shipping

The order is about dependency rather than a strict curriculum. Retrieval builds on model calls, actions build on both, and production work wraps around everything.

Stage 1: Working with Models

What to Learn

This foundation is calling a hosted model from a backend we own and shaping what comes back. That covers the provider APIs themselves and the craft of writing and iterating on instructions. It also covers structured output for when downstream code needs to parse the response, and streaming so users aren’t staring at a spinner.

A little understanding of the underlying theory pays off here as well. An LLM generates text by predicting the next token from everything that came before, and that one fact explains most of what we see day to day: why outputs vary between runs and why a model can state a wrong answer with complete confidence.

Alongside that, this stage builds a working feel for tokens, context windows and cost. Every feature in the later stages runs into all three.

Further Learning

  • OpenAI’s Prompt engineering guide shows how to write clear instructions, provide useful examples and add the context a model needs to produce more consistent results.
  • Vercel’s Builders Guide to the AI SDK uses practical exercises to show how to call models from JavaScript, return structured data and stream responses into a user interface.

Tools to Reach For

Any major provider works: OpenAI, Anthropic or Google. GitHub Models is worth knowing early because it offers a free playground and API access to a wide range of models with just a GitHub account.

What to Build

A summarization or classification feature behind your own backend endpoint, like one that takes a support ticket thread and returns a summary with a suggested priority. It’s small on purpose and proves the request flow and the instruction writing, and it makes the cost math real without any other moving parts.

Stage 2: Grounding Models in Your Data

What to Learn

A model’s built-in knowledge is fixed at training time, so the second stage is retrieval: getting our own content in front of the model at request time. The pieces are embeddings (text represented as vectors that capture meaning), a vector store to search them, chunking strategies for splitting documents and the RAG pattern that ties them together.

Retrieval has a user-facing side too. Grounded answers should cite their sources and admit when the content has no answer.

Further Learning

  • The Progress Telerik AI Crash Course on RAG explains how documents are divided into chunks, converted into embeddings and searched by meaning.
  • OpenAI’s Citation Formatting guide explains how to give each retrieved passage a stable source identifier and instruct a model to cite it.

Tools to Reach For

pgvector adds vector search to a Postgres database we already run, and managed stores like Pinecone take over the operational side. For teams that would rather not build the pipeline at all, governed retrieval platforms like Progress Agentic RAG handle it from ingestion and permissions through to citations.

What to Build

A documentation assistant that answers only from your own content and cites the passages it used. Building it means deciding what the model should retrieve for a given request and figuring out how to keep it from answering beyond the sources. A good sign it’s working: the assistant says the docs don’t cover something instead of guessing.

Stage 3: Actions and Agents

What to Learn

The third stage moves models from answering to acting. The core skill is defining tools: operations with names and typed parameters, plus descriptions that carry the boundaries. The description is what the model reads when deciding whether an action applies. Tool calling runs as a loop: the model requests a call, our code validates and runs it, and the result feeds the next decision.

Agents also need limits. Scoped permissions let them read broadly and write narrowly, and human approval checkpoints sit in front of anything hard to reverse. The Model Context Protocol (MCP) belongs here too, as the standard for how agents discover and call tools.

Further Learning

  • OpenAI’s Function calling guide shows how to define a tool with typed parameters, receive a tool request from the model, execute the operation in application code and return the result to the model.
  • The official Build an MCP server tutorial walks through creating a server that exposes callable tools and connecting it to an MCP host. Examples are available for TypeScript, Python and several other languages.

Tools to Reach For

Every major provider supports tool calling through the same API we learned in Stage 1 (Working with Models), so no new platform is required to start. The MCP documentation and SDKs are the place to learn the protocol, and orchestration frameworks like Progress Forge help once workflows grow past a single loop.

What to Build

An assistant with exactly one write action behind a confirmation step, like a project assistant that can move tasks to the next sprint after we approve the list. One action is all it takes to run into every hard part: the definition, the permission scope, the approval UI and the log of what ran. When we can pull up that log and explain what the agent did and why, this stage is done.

Stage 4: Running AI in Production

What to Learn

Everything up to this point can be demoed in a week. This stage is about what happens after real users show up. Model outputs change from run to run, so testing becomes evaluation: building a set of graded examples and scoring the system against them after every change.

Observability follows. Each request gets traced from retrieval and tool calls through to the final answer, so failures can be reconstructed.

The remaining competencies are cost monitoring and the security and governance basics. Token spend scales with usage in ways traditional features don’t, and the security questions come down to what data reaches the model and who is allowed to trigger which actions.

Further Learning

The Progress Telerik How to Trace and Debug AI Agents in Production webinar shows how tracing helps us understand what an AI agent actually did when something goes wrong. It also covers evaluating answers, catching prompt injection and finding the calls responsible for slow responses or unexpected costs.

Tools to Reach For

Progress Agent Engineering, an AI observability platform, shows where workflows break, what they cost and whether outputs are good enough to ship. It is built for teams working in .NET, Python and JavaScript.

What to Build

Not a new feature this time. Wrap the assistant from the earlier stages in an eval suite of 20 or 30 graded examples and full request tracing, then change the prompt and watch the scores move. The goal is a workflow where a change ships with score evidence attached rather than a hunch.

Skills That Cut Across Every Stage

Some competencies don’t belong to any single stage. Four of them show up everywhere.

AI-Native UX Judgment

This is knowing when to show a confidence indicator, where a human-in-the-loop moment belongs, when chat is the wrong interface for the job and how to present sources so users can check an answer. A model call that works can still ship as a bad feature, and the difference is usually this judgment rather than the engineering.

Component libraries have started shipping these patterns ready-made, like the Progress KendoReact Conversational UI components, which leaves the judgment calls to us instead of the widget-building.

A Security Instinct

Every input a model reads is a potential instruction, which is what makes prompt injection a new class of attack. Every piece of context we assemble is also data leaving our boundary. Deciding what may reach the model and what its output is allowed to trigger is a per-feature decision, and it starts in Stage 1 (Working with Models) rather than arriving with Stage 4 (Running AI in Production).

Designing for Non-Determinism

The same request can produce different outputs on different runs, and ever-stricter prompts won’t make that go away. Non-determinism is a design constraint rather than a bug. Designing for it means constraining the output format and validating everything the model returns. It also means building a fallback for the times the model returns something unusable.

Working with Coding Agents

Using AI-assisted development tools daily doubles as study for this roadmap. Working with a coding agent in Cursor, Claude Code, OpenAI Codex or GitHub Copilot is a live lesson in how models handle context and instructions, and that intuition transfers directly to the features we build.

The tooling also runs in the other direction. Libraries are starting to ship MCP servers of their own, like the Telerik and Kendo UI MCP Server, which gives a coding agent specialized knowledge of the component library it’s generating code for. That’s the same tool discovery idea from Stage 3 (Actions and Agents), applied to our own workflow.

Wrap-up

This series opened with the claim that the full-stack role is expanding rather than being replaced. The articles since have covered the stack, the architectures, the components beyond the prompt and the agent layer.

This roadmap turns those ideas into things to build. None of the checkpoints need special infrastructure or a research background, and none of them are bigger than a side project.

The series continues from here as well. Upcoming articles will go deeper into the territory each stage opens: designing AI-powered experiences, agent engineering, running AI in production and AI-assisted development itself.

For more on building AI-powered applications and agents with Progress, check out the following resources:

Read the whole story
alvinashcraft
59 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Visual Studio Code 1.143 (Insiders)

1 Share

Learn what is new in Visual Studio Code Insiders, including the latest features and improvements.

Read the full article

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories