Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
163820 stories
·
33 followers

Copilot UX components are generally available: bring interactive experiences into Copilot

1 Share

Copilot UX components are generally available with SharePoint Framework (SPFx) 1.24. Bring interactive dashboards, forms, and business actions directly into the Copilot conversation. Build with familiar web technologies, with component hosting handled by Microsoft 365.
copilot agent plugins ux components image

People do not just need an answer. They need a clear way to act on it.

Copilot UX components let organizations bring interactive web experiences, such as dashboards, forms, approvals, and live business data, directly into the Microsoft Copilot canvas. Instead of sending someone to another portal or app, an agent can present the information and controls needed to complete a task in the conversation.

A sales dashboard can open in the conversation when someone asks how the quarter is tracking, with filters to explore the numbers. A time-off request can show the employee’s leave balance, proposed dates, and a Submit button together. The person can review the details and take the next step without losing the context of the request.

For customers, the opportunity is to make existing business processes easier to reach and complete. Teams can use their web skills, business rules, and APIs to bring those processes into Copilot while keeping people in control of consequential actions.

From walls of text to work done

Microsoft Copilot helps people express what they need in natural language. But completing a business task often requires more than a written answer. People need accurate data, clear choices, validation, and a chance to confirm before anything changes.

A text response that points to several portals and forms leaves the person to find the right destination, carry over the context, and finish the task elsewhere. Each handoff adds friction, especially for routine processes used across an organization.

Copilot UX components put the next step in the same place as the request. The agent identifies the need; the component presents a purpose-built experience that the person can use immediately.
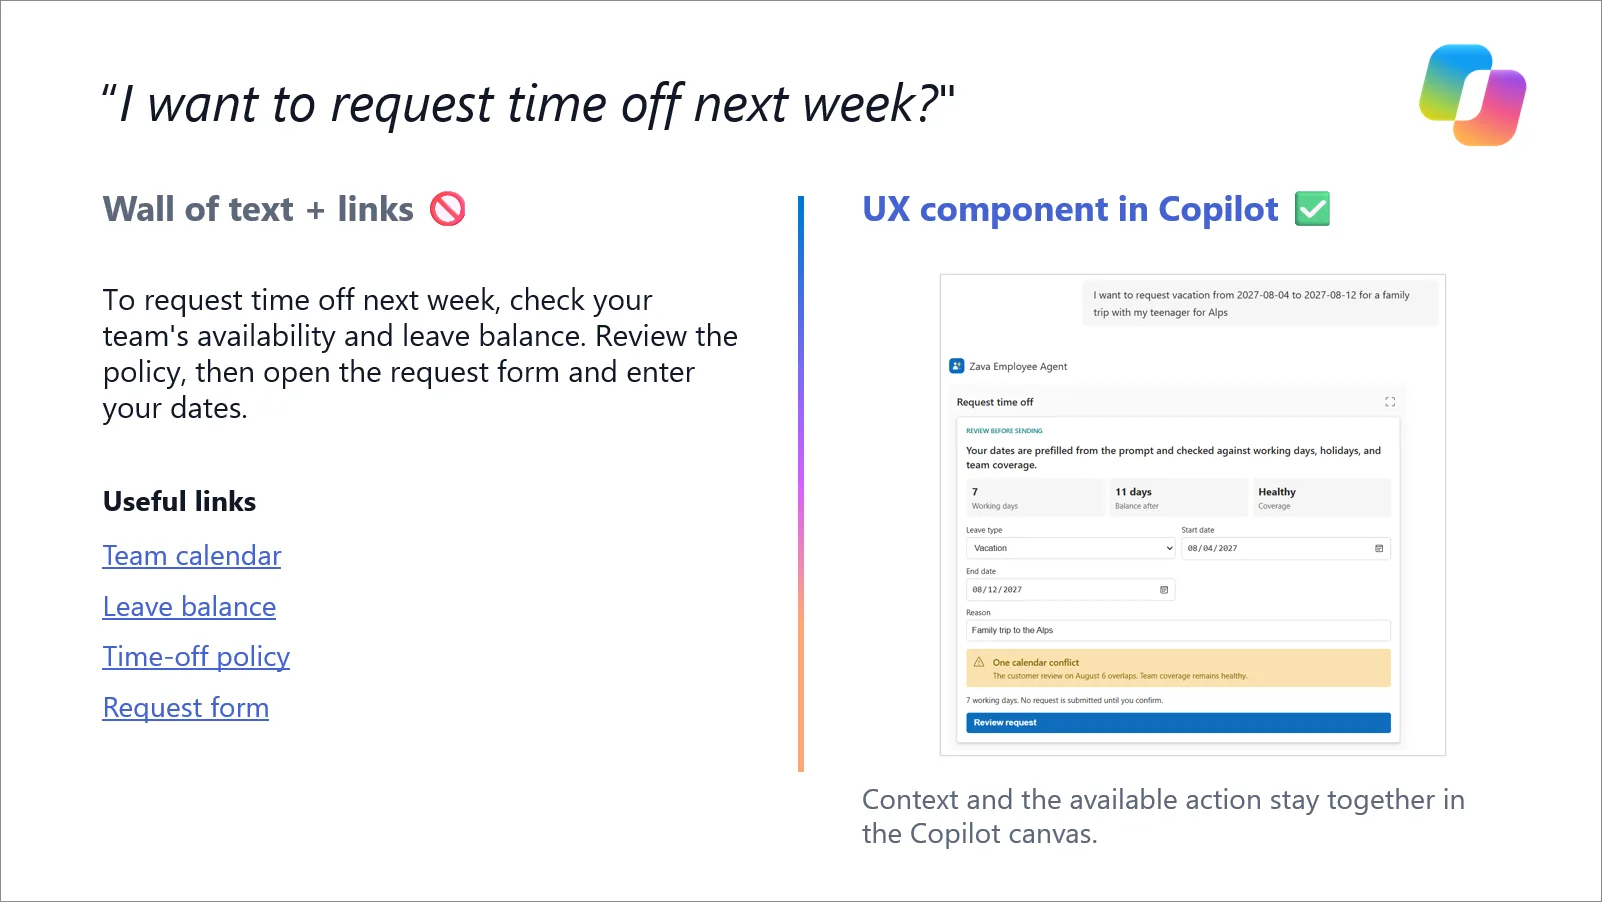
wall of text image

An interactive experience where the work happens

A Copilot UX component is an interactive web experience that appears in the Microsoft Copilot canvas when an agent needs it – based on user’s intent. It can provide a quick in-conversation action or a larger workspace for a task that needs more detail. Customers can shape the interface around the process rather than fit the process into a fixed card.

  • Inline for quick, in-context interactions right in the conversation.
  • Full screen when the scenario needs more room, such as dashboards, multi-step forms, maps, and detailed views.
  • You’re in control of the experience. Decide which modes each component supports and what it renders in each one. Components can also adapt to light and dark themes in Copilot.

Every React or JavaScript component is welcome. Charts, grids, maps, wizards, your design system, your favorite libraries. If you can build it for the web, you can bring it into Copilot with Copilot UX components.

inline full screen experiences new image

AI for intent. UX for action. Humans in control.

The model separates the strengths of AI, application code, and human judgment:

  1. Copilot interprets the request and brings up the appropriate component.
  2. The component presents business data, choices, validation, and operations defined by your code and connected systems.
  3. Your code defines the review and confirmation steps. For consequential actions, design the component so the person can review and confirm before the solution sends changes to the business system through its APIs.

Copilot helps people find the right path. The component makes the path usable. The person remains in control.

Modernize the business processes you already run

Many customer processes already live in portals, forms, dashboards, and line-of-business apps. Copilot UX components offer a way to bring the relevant part of those processes into Microsoft Copilot. A person can start in natural language, work with an interface grounded in the organization’s systems, and complete the task in the canvas.

That creates opportunities across everyday work:

  • Line-of-business data: sales dashboards, customer 360 views, stock levels, expenses, and pay slips.
  • Employee services: time off, help desk, travel booking, onboarding tasks, and recognition.
  • Personal dashboards: relevant news, latest tasks, and your day at a glance.
  • Governance and operations: site provisioning, policy checks, and site dashboards, with an admin confirming each step.

Customers do not need to discard the investments behind these processes. Existing business logic, APIs, and web-development skills can support new in-Copilot experiences that are easier for employees to find and use.

Partners can turn repeatable customer scenarios into packaged Copilot-ready solutions, rather than rebuilding the same workflow for each deployment.

And none of this starts from zero. Customer- and partner-built SharePoint Framework solutions already serve tens of millions of end users each day in tens of thousands of organizations worldwide. That global ecosystem of developers, partners, and solutions can now take its next step into Copilot.
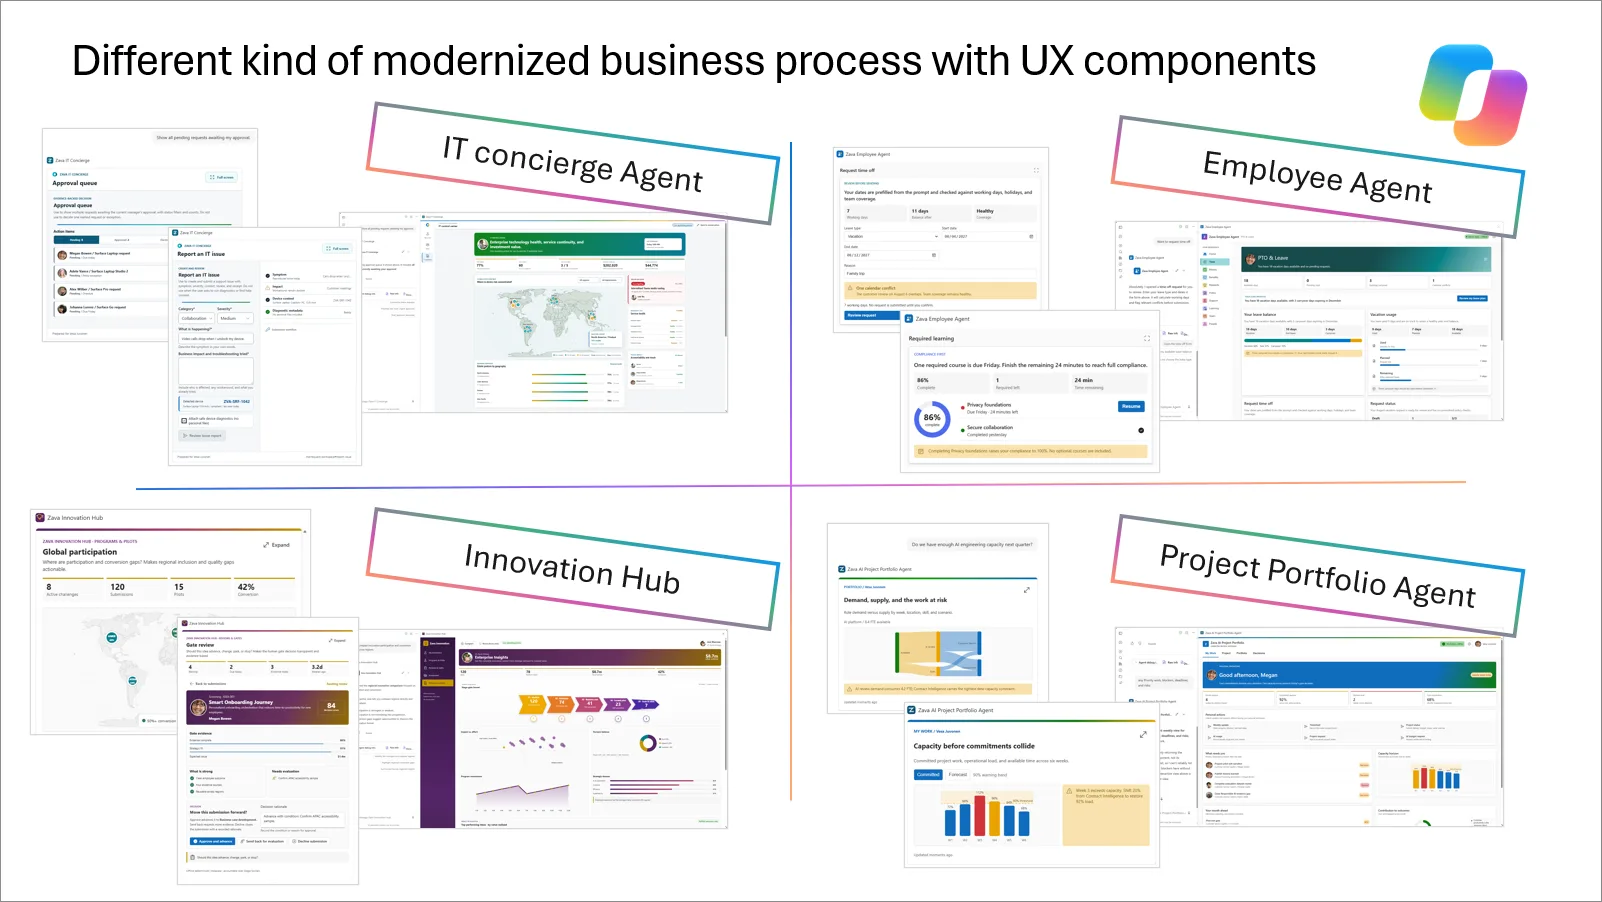
example business scenarios image

Build with familiar web skills

The opportunity is accessible to teams that already build for the web. Copilot UX components use the Model Context Protocol (MCP) Apps model and familiar JavaScript tooling:

  • Industry standards. Components implement the MCP Apps model for interactive UI in AI experiences. It provides an open, interoperable foundation without the hosting and routing work that usually comes with it.
  • The web stack you already know. React, TypeScript, and standard JavaScript libraries all work, as does whichever framework your team prefers. React appears in most of our examples, but it’s never a requirement.
  • Familiar tools. Starter templates (Minimal, No framework, or React), npm, your editor of choice, and the Copilot Workbench for local debugging and testing across inline and full-screen modes, light and dark themes, and different input properties.
  • One solution, many components. A single SPFx solution ships the agent and its components together.

A team can start with a focused process it already knows, use its existing web expertise, and test how that process works inside Copilot before expanding to more scenarios.

Made for agentic coding

Because components use a familiar React or JavaScript project structure, teams can also use coding assistants to scaffold, build, refactor, and troubleshoot them. The samples and documentation provide a starting point, while developers remain responsible for the experience and the business behavior it implements.

Deploy within the customer tenant

The deployment model matters as much as the interface. It reduces the extra hosting and identity work that can slow down a customer project.

SPFx packages the agent and components for deployment inside the customer’s Microsoft 365 tenant:

  • Automatic component hosting. After the solution package is deployed, the platform hosts the component’s JavaScript and CSS in the tenant. Teams do not need to build a separate web server for the component.
  • Automatic routing. Your components are registered for Copilot, and the agent that uses them becomes available in the tenant. When the conversation calls for a component, Copilot renders it in the canvas without endpoints to expose or wire together.
  • Native security and single sign-on. Components run with the signed-in user’s identity and permissions through built-in SSO. No extra sign-in prompts, and access follows the permissions people already have.
  • Familiar governance model. Components use the SPFx deployment and governance model, without a separate external component-hosting service. Permissions and consent for connected business APIs remain part of your solution’s configuration.
  • Fewer infrastructure pieces to review. Without a separate component-hosting service or externally exposed component endpoint, teams can focus their review on the solution and the business APIs it uses.

Spend development time on the customer experience, not on a separate hosting layer.
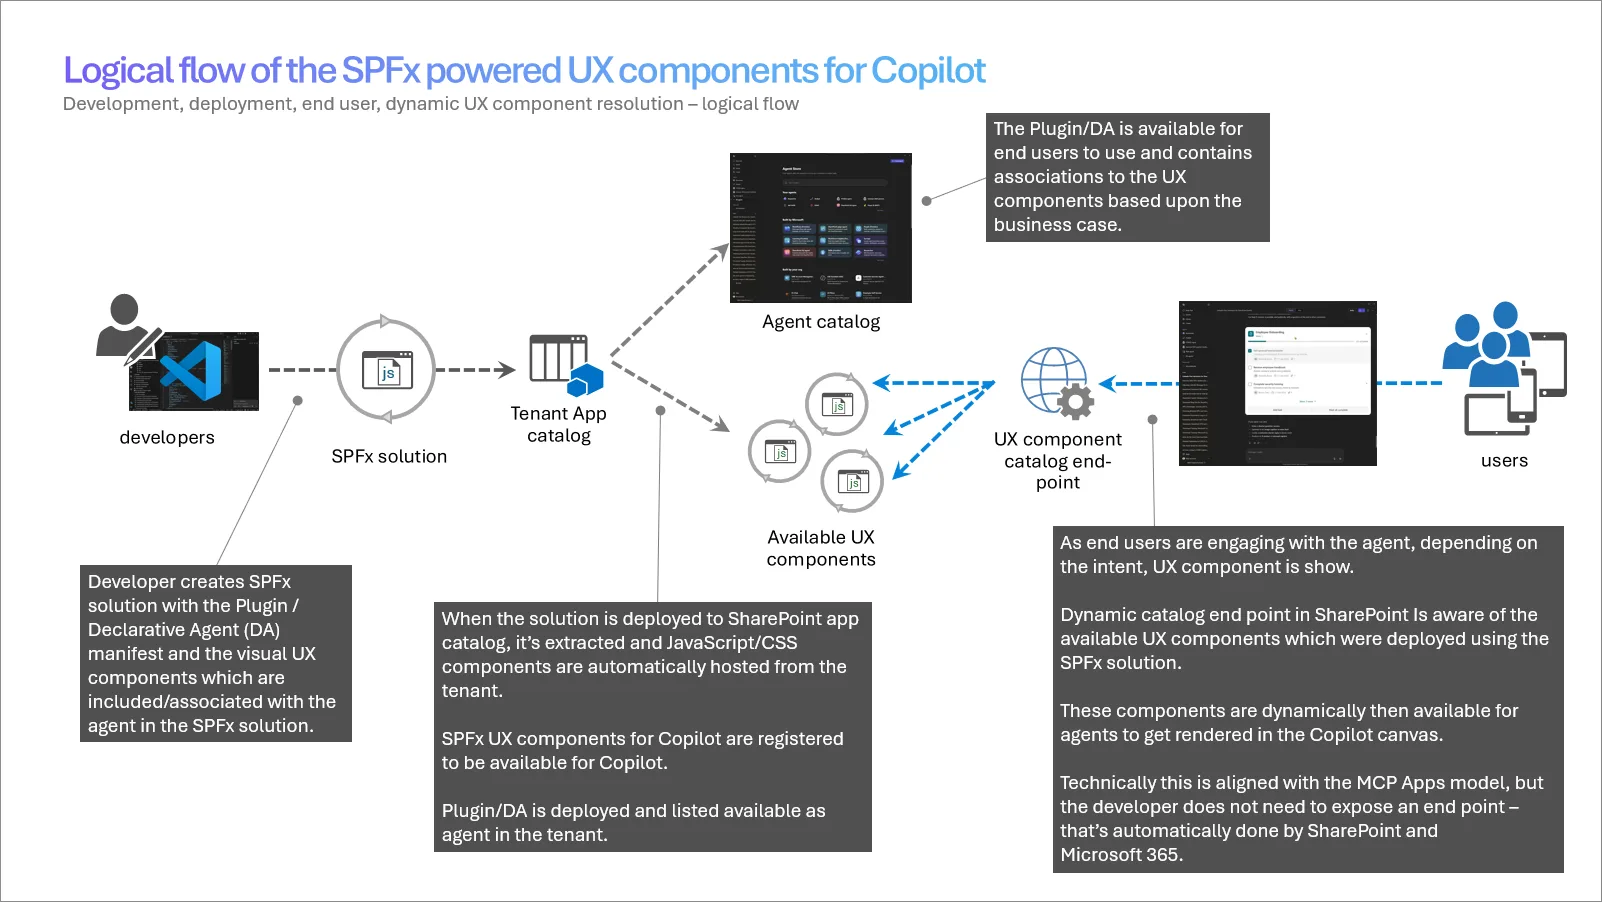
automatic hosting architecture image

The MCP Apps model, without the operational overhead

Both approaches use the MCP Apps model for interactive UI. An externally hosted MCP App requires a team to host, secure, and operate the web app and endpoint. With Copilot UX components, SPFx handles component hosting and registration in the customer tenant. The comparison below shows the operational differences.

  Externally hosted MCP App Copilot UX components
Hosting You build, deploy, and scale a web app and endpoint in Azure or another cloud Automatic, inside the customer’s Microsoft 365 tenant
Tool routing You expose, secure, and maintain the endpoint Automatic: components are registered and routed for you
Identity and SSO You implement and maintain authentication Built-in SSO with the signed-in user’s permissions
Tenant approval A new external app or service to review and consent to
Uses existing SPFx governance; connected APIs may require additional permissions or consent.
Operations Patching, monitoring, scaling, and uptime are yours No separate component-hosting infrastructure to operate
Your data Requests flow through your externally hosted service
Component assets are hosted in Microsoft 365; connected data sources remain part of your solution architecture.
Reaching many tenants Operate multi-tenant infrastructure or a deployment per customer One package, deployed to any number of tenants

Reuse one package across tenants

The same SPFx solution package can move through development, test, and production. Partners can also deploy a packaged solution to multiple customer tenants, where each customer runs it under its own governance.

  • Move through the delivery lifecycle. Deploy the same package to development, test, and production tenants without rebuilding a separate hosting environment.
  • Deploy to customer tenants. Partners and ISVs can package a solution for multiple customers. Each deployment runs inside that customer’s tenant and follows its governance.
  • Avoid separate component hosting. The SPFx model removes the need to operate a web server for each customer’s component.

That makes it easier to take a proven customer scenario from a one-off implementation to a repeatable offering. At GA, Copilot UX components are also supported in SPFx solutions available through the SharePoint Store.

cross tenant support image

Reuse the experience across Microsoft 365

The same web code can support experiences beyond Copilot. An SPFx investment can also be used in SharePoint, Teams, and Outlook where those surfaces fit the customer’s workflow:

  • Microsoft Copilot: as a Copilot UX component, inline or full screen.
  • SharePoint: as a web part on your pages and portals.
  • Microsoft Teams: as a tab.
  • Outlook: as an app opened from the left navigation, in full-page view.

This gives customers a choice of entry points while reusing their existing web investment. The immediate GA opportunity is the experience inside Copilot: putting the right controls next to the conversation that prompted the task.

same ux across surfaces image

Availability at GA and what comes next

Available at GA

  • Copilot UX components are generally available worldwide with SPFx 1.24.
  • Users need a Microsoft Copilot add-on license to use Copilot UX components in Copilot. Components do not render for users without the license – you will see a message explaining the license requirement.
  • Using Copilot UX components does not itself incur consumption-based charges. If a component calls a consumption-based API, such as Work IQ, charges for that API may apply.
  • Supported clients at GA: Microsoft Copilot in the browser and on desktop. Components also work when you are using Copilot through Microsoft Teams in both browser and desktop.
  • Packaging at GA: a declarative agent and its Copilot UX components ship together in one SPFx solution. Copilot UX components are supported for SPFx solutions already in the SharePoint Store.

Planned next

  • Mobile support for Android and iOS.
  • Support for packaging agents and components with the new Copilot plug-in model, enabling components to appear directly in standard Copilot chat without switching to a specific agent, subject to your organization’s configuration.
  • Support for Cowork and additional Copilot surfaces.

SharePoint Framework 1.24 is generally available

SPFx 1.24 delivers Copilot UX components for production use and updates the development platform:

  • Copilot UX components, production-ready: a predictable default display mode in the Copilot canvas, automatic Teams manifest version updates (no more version conflicts when updating a component), declarative agent manifest validation at build time, and new components scaffolded with declarative agent manifest v1.8.
  • React 18: new SPFx solutions use React 18.x out of the box.
  • Node.js 24 and Node.js 26: both are supported for SPFx development.
  • Quality and security: fixes based on preview feedback and updates addressing npm audit findings.

Built something on the 1.24 preview releases? Update it to the GA version. Moving existing solutions to React 18? Test them, and see the React 18 upgrade guidance for common upgrade paths and third-party library considerations. All the details are in the SPFx 1.24 release notes.

Get started today

Start by trying a ready-to-deploy scenario sample in your tenant. The samples include solution packages, demo data, and setup steps, so a team can see how an interactive experience works in Copilot before building its own.

Build your own in four steps:

  1. Install SPFx 1.24:
    npm install @microsoft/generator-sharepoint@latest --global
  2. Scaffold a new Copilot UX component and pick a template: Minimal, No framework, or React.
  3. Run and test it locally in the Copilot Workbench.
  4. Deploy the package to your tenant and surface it in Copilot.

See our getting started tutorial and video for step by step guidance on getting started with creating your first Copilot UX component.

Everything you need:

Thank you, and what’s next

Thank you to everyone who tried the samples, filed issues, joined community calls, and participated in the preview. Your feedback shaped this GA release. Earlier material may call this capability SharePoint Copilot Apps or Copilot Components; its current name is Copilot UX components.

The GA release is a starting point. Mobile support, the new plug-in model, Cowork, and additional Copilot surfaces are planned as follow-on work. SPFx 1.25, planned for December 2026 or January 2027, will continue to evolve the model with follow up releases – based on your feedback and input. If you ran into any issues with the new build, please report them at aka.ms/spfx/issues – so that our engineering team can help you as fast as possible.

Join our community calls at aka.ms/community/calls, and follow us on LinkedIn and X for the latest updates.

Where should you start? Pick one task that people already ask Copilot about but still have to finish in another portal or app – a time-off request, an expense approval, a quick check of the sales numbers. Make it your first Copilot UX component: the data and the actions right in the conversation, ready to review and confirm. From walls of text to getting work done. 🤩

Happy coding! 🧡

The post Copilot UX components are generally available: bring interactive experiences into Copilot appeared first on Microsoft 365 Developer Blog.

Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Slim kiosk setup for my kitchen dashboard on Raspberry Pi

1 Share

I have a Raspberry Pi Monitor on my kitchen wall, driven by a Raspberry Pi. It shows a simple webpage, fed via MQTT with data from my smart home automations: the current house power consumption, the outside temperature, the temperature in my office, my car’s remaining range, and so on. That’s all it does.

Recently, the SD card there died, so I had to reinstall it and took the opportunity to switch to a Raspberry Pi 3A+. And because the whole job is showing a single webpage, I wanted the setup reasonably slim: no desktop environment, just X and a browser.

Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

DOCX Editor SDK: A Complete Evaluation Guide and Checklist

1 Share
The right DOCX Editor SDK brings Microsoft Word-like editing into your web application and fits your technical and business requirements. This guide covers the capabilities and business considerations to evaluate, plus a checklist to compare your options, so you can choose the best DOCX Editor SDK for your application.

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

DRY isn't just for application code

1 Share

In the first article of this series, I shared how we approached modernizing the build and deployment of our microsites at Octopus. One of the biggest sources of friction was how our GitHub Actions workflows were managed. Each of our microsites had its own repository, and each repository had its own copy of four workflows. That’s twenty workflow files, all meant to be identical, all maintained separately, and a problem that only got worse with every new microsite we provisioned.

From a technical perspective, it worked, but it didn’t age well, and the workflows were originally built before reusable workflows were available to us. Making a change like bumping the node version meant opening five pull requests across five repositories, getting each one reviewed, and merging them one by one. Small tweaks made in one repository didn’t always reach the others, and over time, it became trivial for the workflows to drift apart. It’s one of those classic things where each time someone made a change, they knew there was a better way, but the pain experienced for that one-off change wasn’t big enough to take action. However, nobody could say with confidence that every microsite was being built the same way.

Most developers learn “don’t repeat yourself” (DRY) early on as a principle for writing application code. Yet it’s surprisingly common to see the same pipeline copied across repository after repository, as if the rule stops at the edge of the source code. Our microsites were a textbook example.

The fix was to move the build logic into a single central repository and have each microsite call it, so a change made once applies everywhere. GitHub calls these reusable workflows, and getting them in place was one of the project’s quicker wins.

It wasn’t all smooth sailing, though. Reusable workflows solved the copy-paste problem, but they raised new questions about versioning, testing changes safely and without friction, and how much a platform team can see and control once other teams depend on what they’ve built.

A central home for shared workflows

The first step was deciding where the shared workflows would live. I knew there would likely be other shared elements for the project, so we created a central repository called microsite-deployment. Alongside the reusable workflows, it also holds the Terraform for the hosting infrastructure and the scripts used during deployment.

What makes a workflow reusable is a single trigger. Instead of running on a push or a pull request, it uses on: workflow_call, which tells GitHub it’s designed to be invoked by other workflows. It can then declare inputs, just like a function declares parameters, and the calling workflow supplies the values.

For each microsite, the result is refreshingly small. Here’s the entire calling workflow that runs when a pull request is opened against our blog:

name: Pull Request build and deploy

on:
  pull_request:
    branches:
      - main

jobs:
  branch_validation:
    uses: OctopusDeploy/microsite-deployment/.github/workflows/microsite-deployment-branch.yml@main
    with:
      octopus_project_name: "Blog Microsite"
      package_id: "BlogMicrosite"
    secrets: inherit

That’s it. The calling workflow decides when the build runs, and the called workflow decides how it runs. Each microsite provides two inputs: the name of its Octopus project and the package ID for the built site, so it knows which package to reference when GitHub triggers a release in Octopus. Installing dependencies, building and testing the site, packaging it, pushing it to Octopus, and creating a release all live in one place now.

Centralizing the workflows also means the trickier logic only needs to be solved once. Some of our microsite repositories are public and accept contributions from people outside of Octopus. Pull requests from forks don’t have access to the repository’s secrets, so a build from a fork can’t push anything to the Octopus instance that performs deployments. The reusable workflow handles this with a SHOULD_DEPLOY flag, which is set based on whether the Octopus server secret is available in the repo. If it isn’t, the site is still built, tested, and packaged, and the package is uploaded as a workflow artifact instead. Outside contributors still get a validated build, but it doesn’t try to deploy without the credentials to do it. That logic existed before this project, but now it lives in one place, and every public microsite gets it for free.

Adding a new microsite is now a very different experience. Instead of copying four complex workflow files from an existing repo and hoping you picked the latest version, a new repository needs a handful of stable short calling workflows like the one above, and it gets the same build process every other microsite uses from day one.

Bring improvements in small batches

When I started converting the workflows, there was a temptation to go all the way in one hit. Take everything, use Claude to consolidate it into as few files as possible, with whatever logic was needed to handle every incarnation, and be done with it. But moving five microsites onto shared workflows was already a meaningful change, and I didn’t want to stack a redesign of the build logic on top of it. We already know small batches are easier to author and review, easier to test, and much easier to roll back if something goes wrong.

The first step was a fairly direct translation. Each of the four workflows in the microsite repositories became a reusable workflow in the central repository, and each microsite swapped its copies for the short and stable calling workflows. The logic of the workflow stayed the same, but the benefit I was looking for with this change was to consolidate to one version of each workflow, giving us one place to make changes moving forward that would roll out to all callers.

The two build workflows are a good example of where I deliberately held back. One runs when a pull request is opened, and the other runs when changes are merged to main. Both build, test, and package the site, but what happens next is quite different. The main branch workflow is a single job that pushes the package to Octopus and creates a release. The pull request workflow is split into three jobs, deploys to an ephemeral environment, can be skipped with a label, and has a gate job that acts as the required status check for merging.

Could they be a single workflow? Yes. They might even become a single workflow in the future. You could check which event triggered the run, or pass in an input, and use conditions to determine which jobs run. But the two workflows differ in their structure, not just a step or two, and a single file full of conditionals can be harder to read and reason about. Keeping them separate means each one clearly does one job.

I can see what you’re thinking:

But Matt, we are trying to stop the duplication and the multiple changes!

Yes, true, but it doesn’t mean the duplication between them was entirely ignored. For example, workflows need to install the same versions of Node and pnpm, and specifying those versions in two places would have reintroduced the exact problem we were trying to escape, just inside the central repository instead of across the microsites.

So the versions for pnpm and Node are specified in a small composite action, which both workflows call:

- name: Retrieve versions
  uses: OctopusDeploy/microsite-deployment/.github/composite/versions@main
  id: versions

The composite action exposes the Node and pnpm versions as outputs, giving us one place to bump the toolchain for every workflow at once.

Diagram of microsite repos calling four reusable workflows in a central repo, which share a composite action for versions.

The flow from caller workflows, to called workflows, to the composite action

I’ll be honest, though: there’s still duplication. The steps to install dependencies, build, test, and package the site are nearly identical in both workflows, and that’s a natural next candidate for a composite action of its own. It’s a good reminder that copy-paste can creep back in even inside the platform that’s meant to eliminate it. But getting the microsites onto shared workflows first, and then improving those workflows from a single place, was a much safer path than trying to do everything at once. Any further consolidation is now a change to one repository, not five.

Versioning and testing changes

Once the microsites were calling shared workflows, a new question quickly arose. When I change a reusable workflow, which version should each microsite be running?

Choosing a reference

The calling workflow determines which version of a reusable workflow to uses via the reference after the @. There are three common options, each with a trade-off.

A branch, like @main. This is a floating reference. Whatever is on the main branch of the central repository is what every caller runs on its next build. For a platform team, that’s appealing, because a fix or improvement reaches every consumer immediately. For the consumer, it means a change can land in their build without them doing anything, and if that change breaks something, they find out when their pipeline fails. It’s a similar pattern to using latest with container images, which most of the industry has moved away from for good reason.

A tag, like @v1.2.0. Callers stay on a known version until they choose to update. That’s much more predictable, but git tags are mutable by default. Someone can move a tag to a different commit, accidentally or otherwise, and every caller pinned to it quietly starts running different code. GitHub’s immutable releases help here, as the tag attached to an immutable release can’t be changed after it’s published. The catch is that this doesn’t work for floating tags like @v1, which many teams use so consumers automatically get minor updates, because a floating tag has to move to be useful.

A commit SHA. This is the most stable option. A SHA always points to the exact same code, and GitHub’s own documentation recommends it as the safest choice for stability and security. The catch is that a 40-character hash tells you nothing at a glance, so the common convention is to add a comment with the version it represents.

We opted to use @main, effectively forcing every consumer onto the latest version at all times, and accepting that we’re on the hook if we break all the microsites at once. How a workflow is referenced is ultimately set in the calling repository, but the platform team decides which options exist and which one to recommend, so it’s a decision worth making together with your consumers. Think through the implications, and decide whether you’d rather keep everyone on the latest version, or end up with consumers using many versions and choosing when to update, with all the complications that may arise. As we’ll see, GitHub doesn’t have a neat way to notify people there’s a new version, or report on version use so you can track and encourage updates.

Keeping consumers up to date

If you do pin to tags or SHAs, the next problem is ensuring consumers move to newer versions when you publish. Pinned callers don’t automatically pick up changes, so the fix you’ve published might not be running anywhere.

Dependabot can help here. It can track reusable workflow references and raise pull requests when a new version is available, just as it does for marketplace actions. For workflows in private or internal repositories, which is the common case within an organization, they require a little extra setup, either by granting Dependabot access to the central repository in your organization settings or by configuring a Dependabot secret with a token that can read it. It’s also opt-in per calling repository. It makes updates easier to notice and act on, but the decision to update still sits with each consumer for any type of update, whether it be a patch, minor, or major change.

One tag for every workflow

Another paper cut I hit when exploring tagging for the reference approach, is that tags apply to the whole repository. A Git tag points to a commit, and that commit contains every workflow in the repository. If I change the pull request workflow and tag it v1.3.0, a consumer of the main branch workflow who moves to v1.3.0 picks up whatever state that workflow is in at the same commit, even if nothing changed for them. There’s no built-in way to version reusable workflows independently within one repository. You can work around it with prefixed tags, a repository per workflow, or community tools like the Workflow Independent Release Engine, but each adds its own overhead.

Testing changes

This is the part I found most awkward day-to-day. When I want to change a reusable workflow, I make the change on a branch in the central repository. I want to test it works as intended before I merge to main, but I don’t have anything that’s calling the version in my new branch. Currently to test, I create a branch in one of the microsite repositories, change its calling workflow to point at my branch instead of @main, and trigger it. Depending on the trigger, that can mean opening a throwaway pull request just to get the workflow to run.

This rarely happens, but it gets more awkward when the change also touches the composite action. The reusable workflow references the composite at @main, and that nested reference resolves on its own, regardless of which version of the reusable workflow the caller asked for. You might think a local path would solve this, but a local path inside a reusable workflow is resolved against the caller’s workspace, not the central repository. Before the composite action existed, I tried storing the versions in a JSON file in the central repository and reading it from the reusable workflow, but the workflow went looking for the file in the calling microsite repository instead. So testing a change that spans both files means re-pointing two references on my branch, and then remembering to point them back before merging, because I don’t want branch references promoted to main. Pinning to tags or SHAs doesn’t remove that awkwardness. It just moves it somewhere else.

This is an area of the project I haven’t put much thought into solving, as the pain is bearable, but it’s one I’d like to improve. I’ve seen other projects have similar concerns, and one way they’ve resolved this is to have a “test” calling repo - which, in our case, would be a basic microsite - which is primarily used to test changes to called workflows.

Visibility and governance for platform teams

Everything so far has mostly been from the perspective of the person writing and maintaining the shared workflows. But once other teams depend on what you’ve built, a different set of questions comes up. Who’s actually using this workflow? Which version are they on? And if I need everyone to move to a newer version, how do I make that happen?

Who’s consuming your workflows?

This is where GitHub gives a platform team surprisingly little. There’s no view from a reusable workflow that shows which repositories call it, or which reference each of the callers is using. On GitHub Enterprise Cloud, which Octopus uses, you can query the audit log through the REST API to see workflow use, but it’s not the best user experience. Outside of that, the options are to search for code across your organization or to write your own script to crawl repositories and parse their workflow files.

When you put this in the context of a platform team with hundreds of repositories calling many workflows, the questions get harder to answer. Is anyone still on an old version? Has a security fix been picked up everywhere? You’d reasonably expect a platform to tell you, and today on GitHub you mostly have to go and find out yourself.

Steering consumers to a new version

Imagine you’ve published a change that every team needs to pick up, maybe a security fix or a new organizational requirement baked into the build. If consumers reference @main, they get it on their next run. If they’ve pinned to a tag or SHA, as GitHub recommends, it’s up to each of them to update.

GitHub does give administrators some control here, through the allowed actions and reusable workflows policy. Administrators can block a specific action or reusable workflow version by adding it to the policy with a ! prefix, and blocks take priority over anything the policy would otherwise allow. So an administrator can block an old version of a reusable workflow across the organization.

The catch is that it’s a hard stop. There’s no warning phase, no grace period with a “please update by the end of the month” message that teams can see but keep working. The next time a caller on the blocked version runs, it simply fails. That makes sense when you look at why the controls exist. GitHub introduced them to reduce the risk of compromised action repositories, secrets, and malicious tag updates. They’re supply chain security tools, and they do that job well. What they weren’t designed for is managing the lifecycle of your own internal workflows, like guiding teams from one version to the next over a few weeks.

Dependabot, as I covered earlier, helps from the other direction. It can raise pull requests in calling repositories when a new version is available, but it’s configured per repository, and the consumer still decides when to merge. Between the two, a platform team can nudge from the consumer’s side or block from the organization’s side, with not much in between.

Wrapping up

Moving to reusable workflows was one of the quicker wins of this project. Twenty workflow files became a handful of short calling workflows; implementing a change is now one pull request instead of five, and I can say with confidence that every microsite is built the same way. They do come with tradeoffs, though, and if you’re a platform team sharing workflows across many repositories, it’s worth deciding early how consumers should reference your workflows, how you’ll test changes before they land, and how you’ll know who’s using which version, because those answers are much easier to design in than to retrofit.

Happy deployments!

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Understanding Human-Agent Collaboration Patterns

1 Share

Human-agent collaboration goes beyond “keeping a person in the loop.” It scopes agent autonomy and the need and feedback mechanism for human oversight.

An AI agent is software that’s capable of using an LLM model to select actions and progress toward a goal. Within a business context, an agent may fetch data or invoke a tool, and then suggest a modification to a certain workflow. Human-agent collaboration defines how people participate in that work and where the agent’s authority stops.

In this article, we’ll look at how work is divided between a person and an agent. We’ll then design approval and escalation paths that preserve trust without turning every action into a manual checkpoint.

Defining the Collaboration Boundary

The phrase “human in the loop” refers to a system in which some level of interaction by a person (i.e., human) remains. It doesn’t necessarily tell us what that person is responsible for or when they can intervene. A user who approves a refund before it is issued has a different role from an operations lead who reviews a sample of completed refunds each week.

The NIST AI Risk Management Framework suggests that for the configuration and supervision of human-AI systems, roles must be articulated and differentiated. For an agent, this suggests determining who establishes goals and who has the authority to approve significant actions. This also indicates determining who is responsible for monitoring the agent’s actions in the production environment and who is responsible for handling an escalation.

These responsibilities form the collaboration boundary. The agent receives enough authority to complete useful work inside that boundary, while the application prevents it from moving beyond the boundary without human involvement.

Choosing a Delegation Pattern

A delegation model describes how responsibility is divided during a task. We don’t need one model for an entire application because the right level of delegation can change from one action to another.

The following patterns provide a practical starting point:

PatternWhat the Agent DoesWhat the Person DoesStrong Fit
AssistanceFinds information or prepares a draftCompletes the task and decides what to useWork where judgment remains with the user
Approval before actionProposes a change and waitsReviews the proposal before allowing executionConsequential actions that need a clear decision owner
Action with reviewCompletes permitted work and records the resultReviews completed work or a representative sampleReversible tasks with reliable checks
Bounded delegationPursues an outcome within defined limitsSets the limits and handles exceptionsMultistep work where the route may change

Consider a support agent that helps resolve billing cases. It can use assistance to draft an explanation of a charge while the support engineer sends the final response. A refund above a policy threshold can pause for approval, while a correctly classified case can move to the appropriate queue and be reviewed later. If account information conflicts with the current policy, the agent can stop and escalate the case.

This approach gives the agent different levels of authority inside one workflow. It also keeps the most restrictive control focused on the action that needs it instead of placing an approval step after every model output.

Deciding Between Approval and Review

An approval takes place before an action and halts it until an authorized person intervenes. A review denotes hindsight on the action and finds errors without interrupting every successful run.

Approval works best when a big, costly or hard-to-reverse error is likely. Approval also works best when the action creates an external commitment or modifies a customer’s access. The reviewer should see the action and supporting evidence, not a general “please approve” message.

Review works best when the action is easily reversible and the system can detect common failures. A team can review all exceptions and a subset of normal results and apply the findings to adjust the agent’s tools or limits. This gives us evidence in production without making someone sign off on work the system can safely validate.

We can choose between the two by considering some criteria:

  • Consequence: What happens to the business or user if the action is wrong?
  • Reversibility: Can the application undo the action and restore the previous state?
  • Detectability: Can code identify an invalid request or an unusual result?
  • Accountability: Does a named person need to accept the decision before it takes effect?

An approval should, ideally, lead to a meaningful decision rather than a routine click. If the reviewer can’t understand the proposal or lacks time to challenge it, the checkpoint may create the appearance of control without improving the outcome.

Designing an Escalation Workflow

An escalation is a transfer of responsibility to a different person, when an agent can no longer perform a task due to constraints. This isn’t the same as a failed request, because an application has determined that an alternate decision-maker is required for the given task.

Where applicable, useful escalation triggers are to be incorporated into application policy (i.e., predefined rules for when the agent must stop or hand off a task). An agent can escalate when a task is beyond the scope of the agent’s control, or when the task is beyond a defined financial limit.

An agent can be programmed to escalate when the agent fails to validate required data, or when two data sources provide instructions that contradict each other. These triggers are more reliable than asking an agent to make a decision based on subjective confidence.

Escalation also needs a path back into the workflow. A person may supply missing information and return the task to the agent, or they may complete the task and close the run. Recording that outcome helps the team see whether the boundary is working or sending too much routine work for manual handling.

Lastly, an escalation path needs an owner and a response target. Without both, a paused task can sit in a queue while the user assumes the agent is still working. The application should show that the run has stopped and route the case to the role responsible for continuing it. If no one responds in time, the workflow needs a fallback that leaves the task in a known state.

Encoding Trust and Control

Trust should come from behavior the user can inspect rather than a message that asks them to trust the agent. The application can show the action being proposed and the information used to reach it. It should also make clear whether the agent is waiting for approval or has already acted.

The strongest controls live outside the model. Tool permissions constrain what the agent can access, while schema validation limits the arguments it can send. Policy checks decide when work can continue, and audit records preserve what happened after execution.

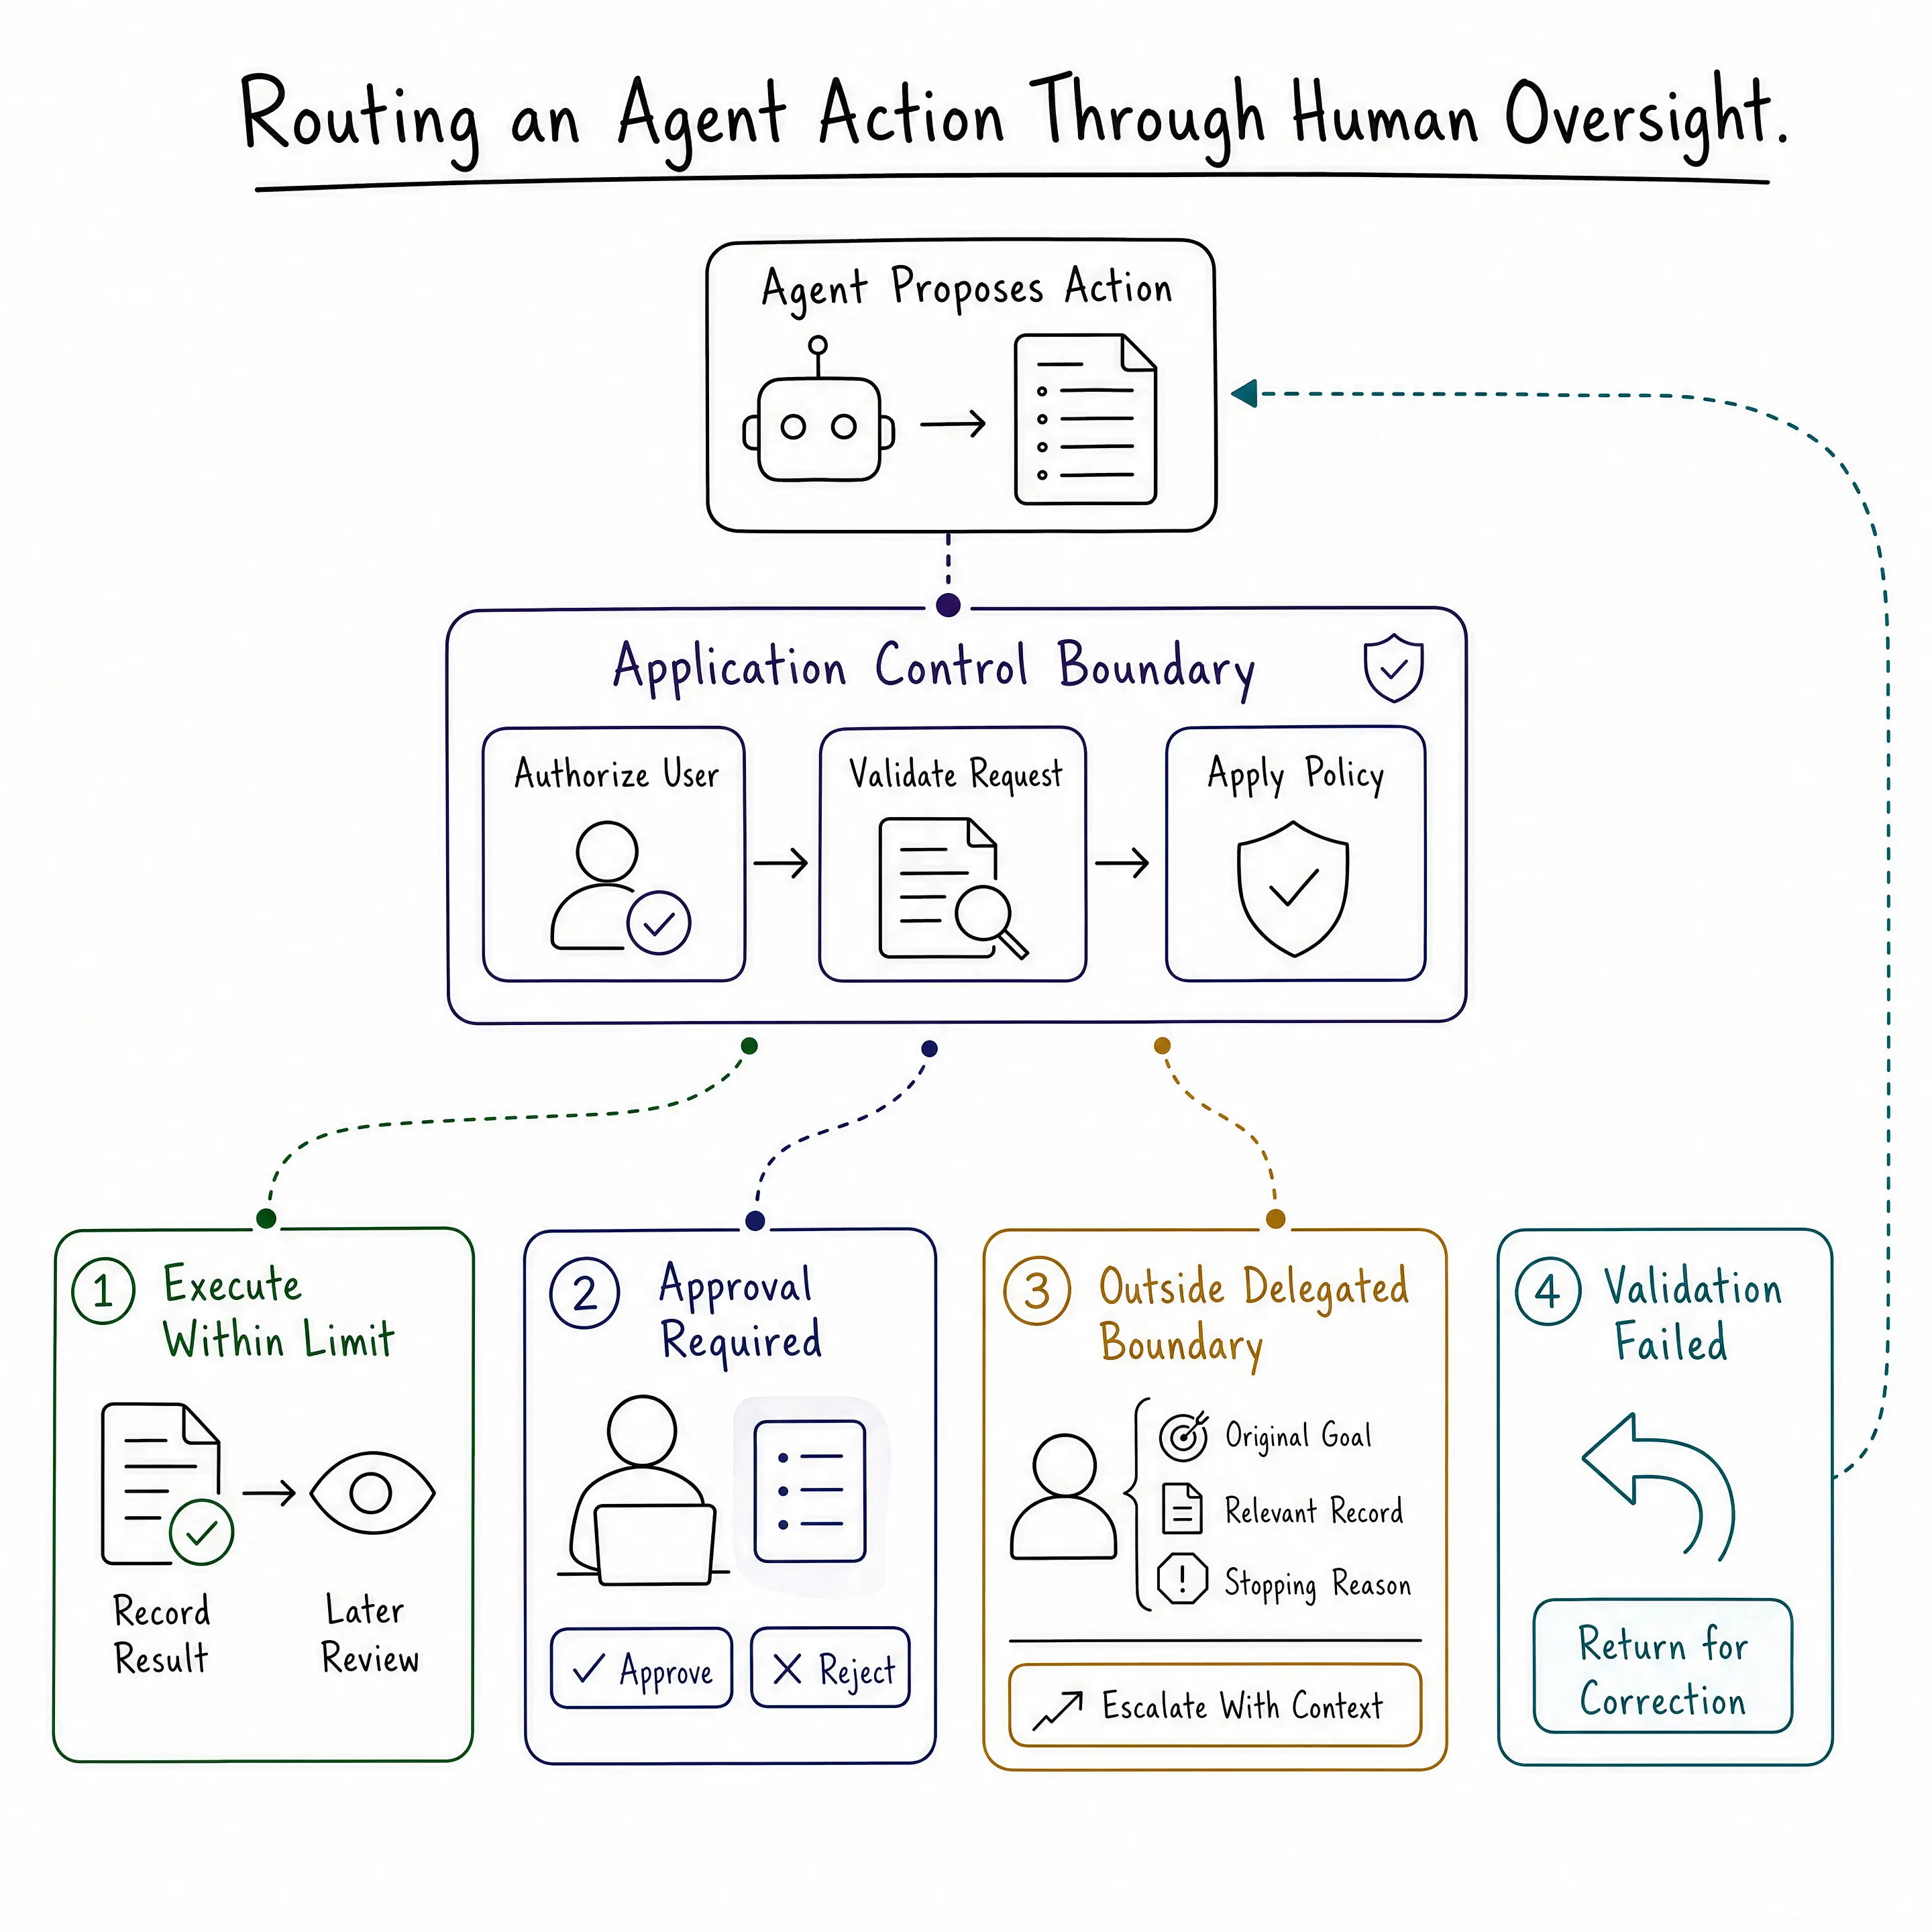
We can represent that boundary directly in application code. In this simplified TypeScript example, a support agent may issue a small refund but must request approval above the delegated amount. It escalates requests beyond the team’s operating policy:

type CollaborationDecision =
  | { status: "execute"; request: RefundRequest }
  | { status: "awaiting_approval"; request: RefundRequest }
  | { status: "escalated"; reason: string };

function routeRefund(
  input: unknown,
  context: SupportContext,
): CollaborationDecision {
  authorize(context.user, "refund:create");
  const request = validateRefundRequest(input);

  if (!context.policyMatches || request.amount > 200) {
    return {
      status: "escalated",
      reason: "Request falls outside the current refund policy",
    };
  }

  if (request.amount > 25) {
    return { status: "awaiting_approval", request };
  }

  return { status: "execute", request };
}

The model may prepare the refund request, but it doesn’t determine its own authority. Application code validates the request and applies limits that the business can review. The execution layer can then record the result and notify the support engineer if the action fails.

An approval also needs to remain tied to the state the reviewer saw, so the application should invalidate it when the request arguments or relevant record changes while the action waits. A policy change before execution should trigger the same checks because a valid decision must not authorize an action the reviewer never saw.

Routing an agent action through human oversight diagram

The NIST AI RMF Playbook recommends keeping histories and audit logs for oversight. It also points to overrides and escalations as evidence that these mechanisms are working. For an application, that means monitoring how often people approve or reject a proposal and how often the agent reaches a boundary.

Choosing the Right Pattern

The aim isn’t to give the agent complete autonomy. Rather, we want the least restrictive pattern possible that allows us to retain the actions within an organization’s risk tolerance.

To choose that pattern, we can work through a couple of questions:

  1. What outcome are we delegating? Define the task and the application state the agent may read or change.
  2. What happens if the agent is wrong? A consequential or hard-to-reverse action should move toward approval, while a low-risk action may be suitable for later review.
  3. Can the boundary be enforced in code? Tool permissions and validation should handle clear limits before we rely on a person to catch every invalid action.
  4. What should cause an escalation? Set the conditions that stop the agent and identify the person or team responsible for continuing the work.

We should test the complete collaboration pattern rather than only the model response. An evaluation needs to check whether the right actions pause for approval and whether permitted work completes without unnecessary interruption. It should also confirm that an escalation reaches the right person with enough context to act.

The boundary can change as the team gathers evidence. A task may begin with approval on every action and move to sampled review after the system demonstrates reliable behavior. A rise in overrides or policy exceptions may justify narrowing the delegation again.

Wrap-up

Human-agent collaboration is a distinct paradigm from general “keeping a person in the loop” strategies. It details the extent of agent autonomy, as well as the need for human oversight and the feedback mechanism for the agent. A good design pattern also provides the agent with a well-defined process for escalation concerning activities beyond its designated scope.

For developers, these decisions belong in the application boundary. Permissions and validation constrain the agent before execution, while audit records make its behavior available for review. When delegation matches the consequence of each action, an agent can help move business work forward without removing human control.

For more on building AI-powered applications and agents with Progress, check out the following resources:

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

If everything needs you, 𝗰𝗼𝗻𝗴𝗿𝗮𝘁𝘂𝗹𝗮𝘁𝗶𝗼𝗻𝘀. You have built a bottleneck.

1 Share

That is an uncomfortable thought when you have spent your career becoming the person who can solve the difficult problems. The architecture nobody understands. The decision nobody wants to make. The deadline somebody has to rescue.
​
Being needed feels good. Until your team’s capacity becomes limited by your availability. “𝘐 𝘤𝘢𝘯 𝘥𝘰 𝘪𝘵 𝘧𝘢𝘴𝘵𝘦𝘳.” Probably. Today.
​
But if you keep taking the work back, that will still be true next year. As engineers, we design for resilience. We eliminate single points of failure. Then we build teams where every meaningful decision passes through us. We should recognize that architecture.
​
“𝘠𝘰𝘶𝘳 𝘯𝘦𝘹𝘵 𝘭𝘦𝘷𝘦𝘭 𝘪𝘴 𝘯𝘰𝘵 𝘥𝘰𝘪𝘯𝘨 𝘦𝘷𝘦𝘳𝘺𝘵𝘩𝘪𝘯𝘨. 𝘐𝘵 𝘪𝘴 𝘮𝘢𝘬𝘪𝘯𝘨 𝘮𝘰𝘳𝘦 𝘱𝘰𝘴𝘴𝘪𝘣𝘭𝘦 𝘵𝘩𝘳𝘰𝘶𝘨𝘩 𝘰𝘵𝘩𝘦𝘳𝘴.”
​
For me, that means sharing the reasoning alongside the responsibility. Explain the outcome. Make the constraints clear. Give people authority to decide. Stay available when they need support. Then comes the uncomfortable part: accepting a sound approach that differs from yours.
​
Your preference is not automatically a requirement.
​
Across enterprise engineering and open source, I care about a simple test: can someone else explain the decision, own the outcome, and keep things moving when I am unavailable? That capability takes time to build. Taking over every time we feel impatient keeps postponing it. I still want to solve hard problems. I also want more people to be ready to solve them.
​
What is one decision you could help someone else own this week?

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories