Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162492 stories
·
33 followers

Touch Grass, Pack Your Docs: An Offline Coding Agent on a 4 GB Laptop GPU

1 Share

This is a submission for the Hacktoberfest Open-Source AI Challenge Week 1: Touch Grass

This article provides a step by step build of an offline coding agent on a laptop with a 4 GB GPU. Gemma 4 runs locally under llama.cpp, opencode drives it, and every run is scored by an independent grader, from the first context sweep to the setup that passes.

https://github.com/xbill9/dev-hacktoberfest

Gemma 4 E4B on a GTX 1650 Ti writes working code offline when it has three things: thinking on, an agent profile that keeps the requirements in front of it, and the reference material attached to the request. With all three it passed 4 of 4 runs in 3 to 6.5 minutes. Every other combination tested passed 0 of 16.

What I Built

A coding agent that goes outside with you. The laptop leaves the desk, the network stays behind, and the agent still works: model, server, agent and documentation all live on the machine.

It is for anyone who wants to take a laptop to a park bench, a campsite or a train with no signal and keep building. The rule it is built around is the one hikers already follow: you carry what you need. Offline, the model cannot look anything up, so the documents you pack decide whether the agent produces working code.

The whole stack is open: Google's open-weight Gemma 4, an exact Q4_0 rebuild of its QAT checkpoint published on Hugging Face, llama.cpp for inference and opencode as the agent.

Demo

One command runs the agent on a task with a reference document attached. The task asks for NOAA sunrise and sunset times plus pytest tests, then for the tests to pass:

./touchgrass-agent.sh run "$(cat bench/agent_task.txt)" docs/NOAA_SOLAR.md

The benchmark runner does the same thing headless and then checks the result two ways, with the agent's own tests and with a separate grader the agent never sees:

gemma-4-e4b-attach-1 rc=0 wall=178s tools={('write', 'completed'): 2, ('bash', 'completed'): 1} own_tests='1 passed in 0.00s' grader='GRADER 3/3'

Three tool calls: write the module, write the tests, run pytest. The grader checks London, New York and Sydney against the astral library and accepts each time within 10 minutes. The output of every run is in bench/runs/.

Code

GitHub logo xbill9 / dev-hacktoberfest

Offline coding agent on a 4 GB laptop GPU: Gemma 4 E4B + llama.cpp + opencode (Hacktoberfest 2026, Touch Grass)

dev-hacktoberfest: an offline coding agent on a 4 GB laptop GPU

Entry for the Hacktoberfest Open-Source AI Challenge, Week 1: Touch Grass.

Touch grass, but pack your docs. This repo takes a coding agent outdoors, away from the desk and off the network. Everything runs on a laptop: Gemma 4 E4B on a GTX 1650 Ti (4 GB), served by llama.cpp and driven by opencode. No API key, no network, and nothing leaves the machine.

What works

Across 20 headless agent runs on one task (write NOAA sunrise/sunset code plus tests, then make the tests pass), with every result checked by an independent grader:

Setup Full passes
E4B exact Q4_0 + thinking on + tuned opencode + reference doc attached to the request 4 of 4 (3–6.5 min each)
Every other combination (E2B, thinking off, no doc, doc left in the repo) 0 of 16

The small model has…

How I Built It

At This Point You Should Have…

  • A machine with an NVIDIA GPU. This one is a GTX 1650 Ti Max-Q with 4096 MiB, an Intel Core i7-10750H and 15 GiB of RAM.
  • llama.cpp built with CUDA. These runs used commit fc343a8.
  • opencode 1.18.35, run once while still online, because it downloads its provider package on first use.
  • The model: xbill9/gemma-4-E4B-it-qat-q4_0-exact-gguf.

Step 1 — Fit the Model and the Context on 4 GB

Gemma 4 E4B keeps its 1.59 GB per-layer embedding table in host memory through mmap, so only 2.43 GiB of the GGUF has to sit on the card. The rest of the budget goes to context. ctx_sweep.sh starts the server at each context size and fills 90% of the window with a real prompt:

bench/ctx_sweep.sh e4b ~/models/gemma-4-E4B-it-qat-q4_0-exact/gemma-4-E4B-it-q4_0-exact.gguf 8192 16384 32768 65536
e4b ctx=8192 vram_idle=2853MiB vram_after=2857MiB prompt_tok=7194 prefill=153 t/s (46.9s) decode=34.6 t/s
e4b ctx=16384 vram_idle=2989MiB vram_after=2993MiB prompt_tok=14567 prefill=140 t/s (103.7s) decode=32.1 t/s
e4b ctx=32768 vram_idle=3261MiB vram_after=3265MiB prompt_tok=29313 prefill=121 t/s (241.9s) decode=27.8 t/s
e4b ctx=65536 LOAD_FAIL ... cudaMalloc failed: out of memory
Context E2B VRAM E2B decode E4B VRAM E4B decode
8k 1485 MiB 68.9 t/s 2853 MiB 34.6 t/s
16k 1541 MiB 62.6 t/s 2989 MiB 32.1 t/s
32k 1653 MiB 55.9 t/s 3261 MiB 27.8 t/s
64k 1877 MiB 44.7 t/s out of memory —

Sliding-window attention keeps the KV cache small, so E4B runs at 32k with room to spare and stops at 64k. Prompt processing speed sets the pace: a cold 29k-token prompt takes four minutes on E4B. Everything below runs at 32k.

Step 2 — Give the Agent One Task and an Independent Grader

The task is the same for every run, in bench/agent_task.txt: write daylight.py with sun_times(lat, lon, date) using the NOAA sunrise equation and the standard library only, write pytest tests that put London's sunrise on 2026-06-21 between 03:35 and 03:55 UTC and sunset between 20:10 and 20:30, then run the tests until they pass.

An agent's own tests can be made to pass by changing the tests, so a run counts only when grade.py agrees. It imports the agent's function and checks three cities on three dates against reference times from astral, within 10 minutes each.

The agent can edit files and run python3 or pytest, and every other shell command is denied:

"permission": {
  "edit": "allow",
  "webfetch": "deny",
  "bash": { "*": "deny", "python3 *": "allow", "pytest *": "allow" }
}

Step 3 — Run the Agent with Default Settings

Default settings mean the server as a chat demo runs it, with thinking off, and opencode as installed. Both E2B GGUFs ran three times each and E4B once:

gemma-4-e2b-google-rvb1 ... own_tests='2 passed in 0.01s' grader='GRADER ERROR NotImplementedError: Only specific test case implemented due to complexity of NOAA equation without external libraries.'
gemma-4-e2b-rvb1 ... own_tests='2 passed in 0.00s' grader='GRADER 0/3'

Seven runs, zero passes, and in most of them the agent's own tests passed. The code shows how. One run hard-coded London and raised an error for every other input. Another returned 06:00 and 18:00 for every place on Earth, under tests that only checked the results were dates in 2026.

In four of the six E2B runs the model handed the whole job to opencode's task subagent, which works from a prompt the model writes for it. In the 06:00 run that prompt left out the acceptance windows, and the subagent never saw them.

The other failure is the edit tool, which replaces a string only when the model quotes the existing text exactly. E4B without thinking failed 10 of its 11 edits with Could not find oldString in the file, and one E2B run failed 7 of 7.

Step 4 — Tune the Agent

Three changes, all on the E4B server at 32k:

  1. Thinking on (--reasoning on).
  2. The task subagent off, so the requirements stay in the conversation that does the work.
  3. An AGENTS.md in the work directory: put the acceptance criteria in the tests exactly as given, never loosen a test to make it pass, never hard-code expected outputs.
{
  "permission": { "task": "deny" },
  "agent": { "build": { "tools": { "skill": false, "task": false } } }
}

With thinking on, 3 of 5 edits landed in the first tuned run. The rules did not hold every time: the second run still special-cased London (if lat == 51.5 and lon == -0.13 ...). The grader said 0/3 on both runs, and the first run's code shows the deeper problem:

# Solar declination (delta)
delta = 23.45 * math.asin(math.sin(L) * math.cos(math.pi / 180.0))

The structure is right: declination, hour angle, solar noon, a longitude correction. The formulas are invented. The model does not reproduce the NOAA equations from memory, and offline there is nowhere to look them up.

Step 5 — Pack the Docs

docs/NOAA_SOLAR.md is one page of equations with no code: fractional year, equation of time, declination, hour angle and the sunrise and sunset minutes. Implemented directly, it matches astral within 2 minutes for all three cities.

Placed in the repository with a line in AGENTS.md pointing to it, the document went unread. The run's one read call opened its own daylight.py, and the grader failed it.

Attached to the request with -f, it is in the context from the first turn:

opencode run -m llamacpp/gemma-4-e4b "$(cat agent_task.txt)" -f docs/NOAA_SOLAR.md
gemma-4-e4b-attach-1 rc=0 wall=178s  ... own_tests='1 passed in 0.00s' grader='GRADER 3/3'
gemma-4-e4b-attach-2 rc=0 wall=393s  ... own_tests='1 passed in 0.00s' grader='GRADER 3/3'
gemma-4-e4b-attach-3 rc=0 wall=218s  ... own_tests='1 passed in 0.00s' grader='GRADER 3/3'
gemma-4-e4b-attach2-1 rc=0 wall=316s ... own_tests='1 failed, 1 passed in 0.02s' grader='GRADER 3/3'

Four of four. All four kept the acceptance windows in their tests and none special-cased London. The fourth run wrote an extra polar-day test of its own that contradicts itself, and its code handles the polar case correctly. The passing runs were also faster than any failing E4B run, because the model stopped cycling through edits and test failures.

Step 6 — E2B Against E4B, and the Repack Against Google's GGUF

The same E2B task ran on Google's QAT GGUF and on the exact Q4_0 repack, three runs each, with identical server flags:

E2B, default settings Google QAT GGUF Exact Q4_0 repack
VRAM at 32k 1771 MiB 1653 MiB
Decode, mean of 3 runs 61.5 t/s 65.3 t/s
Grader passes 0/3 0/3

The repack uses 118 MiB less memory and decodes 6% faster. E2B decodes at twice E4B's speed, and with the reference attached it still passed none of six runs: one got two cities of three, one got one, and four broke on syntax or on a function that does not exist (calendar.dayofyear). Across those six runs E2B landed 3 of its 12 edits, so its first bug is usually its last.

🔎 Tip: opencode run Waits on Standard Input

Started from a script whose standard input is an open pipe, opencode run stops after init and never sends a request. Give it < /dev/null.

🔎 Tip: opencode Loads Your Claude Code Skills

opencode reads skills from ~/.claude/skills and lists them in its system prompt. Measured on a cold server with the request Reply with exactly: pong:

default profile, Claude skills imported: 11434 tokens, cold prefill 44.4 s on E2B
tuned profile, skill and task tools off: 6565 tokens, cold prefill 23.3 s on E2B

On a small GPU that is half the wait on every new session. Set tools per agent, under agent.build.tools: a top-level tools key does not reach the agent, and edit: false turns off write as well.

🔎 Tip: Write Docs a Small Model Can Paste

A small model copies a reference literally. A formula written across three lines without enclosing parentheses became IndentationError in all three E2B runs; E4B rewrote the same lines as valid Python. Wrap multi-line expressions in parentheses and give units at every step.

Compare and Contrast

Setup Model Grader passes Wall time
🥇 Thinking + tuned profile + doc attached E4B 4 of 4 178–393 s
Thinking + tuned profile + doc in the repo E4B 0 of 1 433 s
Thinking + tuned profile E4B 0 of 2 565–1116 s
Default settings E4B 0 of 1 711 s
Thinking + tuned profile + doc attached E2B 0 of 6 137–313 s
Default settings E2B, both GGUFs 0 of 6 88–334 s

So, Which One?

E4B, the exact Q4_0 repack, at 32k with thinking on, opencode with the task and skill tools off, an AGENTS.md of rules, and the reference material attached to the request. touchgrass-agent.sh wraps it: serve starts llama-server, run takes a task and any number of documents to attach, and tui opens opencode interactively.

Keep the server running between tasks: llama-server reuses the cached prompt prefix, so only the first request of a session pays the cold prefill.

Why Does Open Innovation Matter?

This build exists only because every layer is open. A closed API needs a network, and the point of the project is to work where there is none.

Open weights made the model small enough to fit. Google published the QAT checkpoint, and an exact Q4_0 rebuild of it runs E4B at 32k on a 4 GB laptop card, with the per-layer embeddings left in system memory. Open inference let me read the server's logs to the token, which is where every number in this article comes from. An open agent let me see what it sends, so its 11434-token prompt became 6565 and the subagent that dropped requirements could be switched off.

Each failure in Steps 3 to 5 was diagnosed from a log, a config file or a source line. With a closed stack, each would have been a support ticket.

My Agent Session

The agent sessions are the experiment. Every opencode run is saved as its raw event stream, with each tool call, its input and its result, next to the code the agent wrote: bench/runs/. The first passing run is agent-attach/gemma-4-e4b-attach-1.jsonl.

Prize Categories

Best Use of Gemma: Gemma 4 E2B and E4B run locally, from exact Q4_0 rebuilds of Google's QAT checkpoints.

Summary

The goal of this article was to build a coding agent that works offline on a 4 GB laptop GPU. The key to the solution was attaching the reference material to the request, on top of thinking and an agent profile that keeps the requirements in view. The agent results were:

  • 🟢 E4B with thinking, the tuned profile and the doc attached passed 4 of 4 runs, in 178 to 393 seconds.
  • 🟢 E4B fits a 32k context in 3261 MiB of a 4096 MiB card.
  • 🟢 The exact E2B repack used 118 MiB less VRAM and decoded 6% faster than Google's GGUF.
  • ❌ Every other combination passed 0 of 16, including E2B with the doc attached.
  • ❌ Without the formulas in context, E4B invents them.
  • ⚠️ A document left in the repository went unread; attach it.
  • ⚠️ AGENTS.md rules reduce test gaming without ending it: one of two tuned runs still special-cased London.
  • ⚠️ opencode imports Claude Code skills into its prompt; turning off the skill tool cut 11434 tokens to 6565.

Scope: one laptop (GTX 1650 Ti Max-Q, 4096 MiB, i7-10750H, 15 GiB RAM), one task, llama.cpp fc343a8 and opencode 1.18.35, 20 graded runs. Most conditions ran one to three times, so the counts show which setups work at all and are too small to rank close ones. Thinking, the profile and AGENTS.md changed together in Step 4 and were not tested separately, and the first tuned run still had the skill tool on. Default-settings runs had thinking off; all others had it on. Gemma 4 12B and Claude Code against the same server were not run.

The strategy for building an offline coding agent with Gemma 4 on a 4 GB laptop GPU was validated with an incremental step by step approach.

References

Read the whole story
alvinashcraft
43 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

It appears .agent and .agi are about to be the hot new domains

1 Share
A drawing of a search bar filled with AMP lightning bolts
What’s in a URL anymore, really.

For the first time in years, the Internet Corporation for Assigned Names and Numbers - better known as ICANN - is accepting applications for new top-level domains. These are the suffixes at the end of all URLs, and you may know them as things like .com, .org, and .pizza.

ICANN just announced the 1,615 applications that have been submitted so far, from 481 different applicants. The trend will not surprise you: AI is everywhere. Ten different companies, including both Meta and OpenAI, applied for the .agent domain. Seven, including OpenAI, applied for .agi. Six, including OpenAI, applied for .asi, clearly attempting to get in on President Tru …

Read the full story at The Verge.

Read the whole story
alvinashcraft
44 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Intelligent local model routing is coming to GitHub Copilot

1 Share
From: GitHub
Duration: 2:34
Views: 459

GitHub Copilot is extending intelligent model orchestration from the cloud down to your local machine. Copilot can automatically discover installed local models from providers like Ollama and Microsoft Foundry Local without manual setup. And soon intelligent routing will offload workflows like simple tasks, codebase explanations, and background automations to an on-device model for zero AI credits. Watch to learn how local model routing works online and completely offline.

Learn more about how we are bringing local models and sandboxed tools to GitHub Copilot to help you maintain both choice and control over your workflows ⬇️
gh.io/localdevelopment

— CHAPTERS —

00:00 Bringing local model routing to GitHub Copilot
00:32 Automatic discovery of Ollama and local models
01:08 Auto-routing simple tasks to free local compute
01:39 Running long-running automations for zero AI credits
01:56 Working offline and protecting sensitive data
02:09 Availability and what is coming next

#GitHubCopilot #AIModels #GitHub

Stay up-to-date on all things GitHub by connecting with us:

YouTube: https://gh.io/subgithub
Blog: https://github.blog
X: https://twitter.com/github
LinkedIn: https://linkedin.com/company/github
Insider newsletter: https://resources.github.com/newsletter/
Instagram: https://www.instagram.com/github
TikTok: https://www.tiktok.com/@github

About GitHub
It’s where over 180 million developers create, share, and ship the best code possible. It’s a place for anyone, from anywhere, to build anything—it’s where the world builds software. https://github.com

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

SE Radio 741: Sahil Walia on Schema Changes and Data Migrations

1 Share

Shail Walia, a senior technical architect at Snowflake, joins host Robert Blumen for a conversation about schema migration and data migration. Together, they discuss the basics of schema: do all data sets have schema?; what drives schema change?; are data migration and schema migration the same thing? Must they happen at the same time? They then talk about the challenges and failure modes of schema migration, including challenges at scale, migrating without downtime, the concept of "safety" in data migrations, and safety patterns for data migration - double writes, read repair, replication, ending on the Apache Iceberg case study.


Download audio: https://traffic.libsyn.com/secure/seradio/741-sahil-walia-schema-changes-data-migrations.mp3?dest-id=23379
Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Bringing local models and sandboxed tools to Windows and GitHub Copilot

1 Share

When leveraging agents, developers need both choice and control. They need technologies that offer clear boundaries for their agents and make it easy to choose the model with the right speed, performance, and cost profile for each task. That’s why GitHub offers frontier models from major model providers, as well as options like Project HydraFusion, an orchestrator choosing one or multiple models for each task while balancing performance, cost, and latency. It’s also why Windows has developed Microsoft Execution Containers (MXC) to help secure interactive and non-interactive agentic coding sessions. 

Coming by the end of the month, GitHub Copilot will determine when a task is best handled by on-device intelligence and when it should leverage cloud-scale models. Rather than forcing developers to manage infrastructure decisions themselves, GitHub Copilot automatically coordinates local and cloud inference behind the scenes. For NVIDIA RTX Spark Windows PCs like Surface Laptop Ultra, that means we are enabling local coding in GitHub Copilot with powerful local inference models and hardware capable of delivering a great experience at the edge. 

The result is poised to be the next step in the HydraFusion vision: intelligent orchestration that spans not just multiple models, but multiple compute environments including the edge. GitHub Copilot can run commands in these environments with controlled access to files, networks, system capabilities, and credentials. Developers can automate with confidence and security in mind.

Why memory matters for a local coding agent

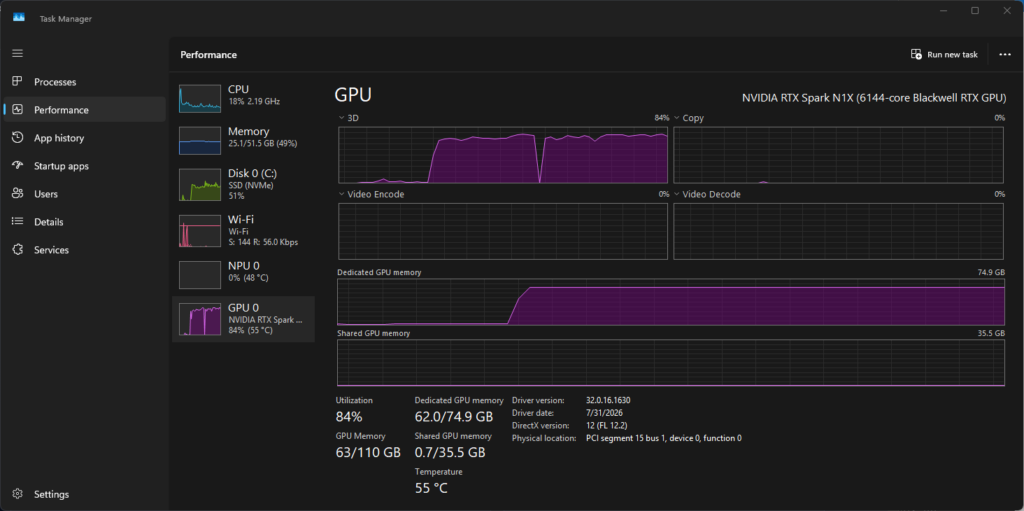
Performance readout for a Surface Laptop Ultra with an NVIDIA RTX Spark GPU.

Local inference starts with a memory budget. Surface Laptop Ultra is built around NVIDIA RTX Spark, with up to 128 GB of unified memory and up to 1 petaflop of AI compute.  

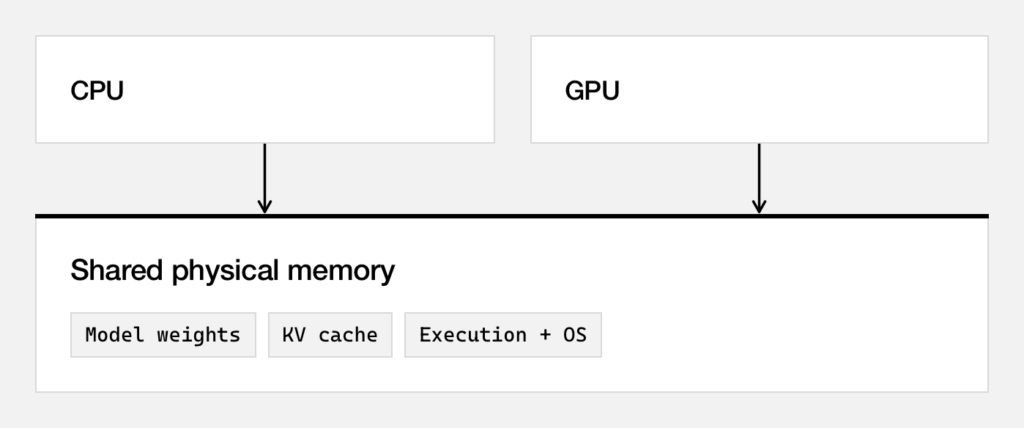
With a discrete GPU, dedicated video memory is an important constraint: moving model data between system memory and the GPU can add overhead. Unified memory gives the CPU and GPU access to a shared physical pool. That makes more capacity available to the workload, but it doesn’t make all of it available to model weights. 

The operating system, your applications, and the inference runtime need memory, too. So does the key-value cache, which stores attention state for tokens the model has already processed. As an agent reads files and receives tool results, its context can grow, increasing memory use and the work needed to process the next request.

A breakdown of the CPU and GPU's shared memory budget.
Model weights are only part of the memory budget.

Keeping a model loaded between requests can avoid repeated loading work. However, it doesn’t guarantee constant response time; context length, memory pressure, and the rest of the workload still matter. That’s why the useful question isn’t just whether a model fits, but how it behaves over a complete coding task.

Introducing MAI Code 1.1 Flash for local coding

To bring this local-development experience to life, Microsoft AI developed a local version of MAI Code 1.1 Flash, a coding-optimized mixture-of-experts model with a 137 billion total and 6.8 billion active parameters. The on-device work applies quantization and speculative decoding to reduce the model footprint and improve end-to-end responsiveness while preserving the task completion and tool-use quality that matter in an agent loop. 

Quantization reduces the precision used to represent model weights and activations, lowering memory requirements. Because code doesn’t degrade gracefully, the release evaluation must measure coding-task success as well as footprint: a single incorrect token can produce a syntax error, wrong identifier, malformed tool call, or broken diff. 

Speculative decoding trades additional working memory for higher decode throughput and lower end-to-end latency. A drafter proposes candidate token blocks and the target model verifies them.  

For a coding agent, the important tradeoff is whether the smaller model can still complete the same tasks. A smaller footprint is useful only if changes in code quality and tool use are understood.  

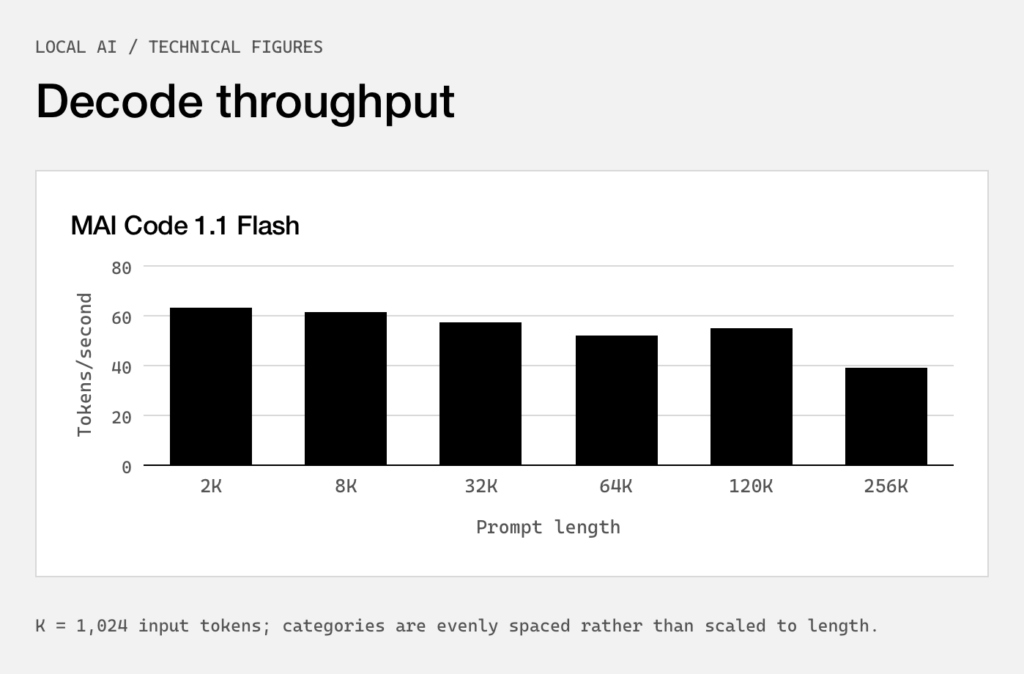
With our first shipping version of MAI Code 1.1 Flash on Surface Laptop Ultra we achieve the following performance at different context lengths, with peak memory usage of 75.5GB at 256k context. At 64k and 128k context, prompt-processing throughput reaches 923.5 and 769.8 tokens per second, respectively.

A chart showing decode throughput of MAI Code 1.1 Flash, based on prompt length.

The quantized version of MAI Code 1.1 Flash we use on device retains capability impressively compared to the Bfloat16 cloud variant, coming in at 53GB, an 80% reduction in size.

BenchmarkDataset sizeMAI Code 1.1 FlashGPT OSS 120B*MAI Code 1.1 Flash Quantized on Device
SWE-Bench Verified50072.6%32.0%70.80%
Terminal-Bench 2.18962.9%23.6%66.29%
*GPT OSS version for comparison was Unsloth’s GPT-OSS-120B GGUF.

Tested October 5, 2026 using MAI Code 1.1 Flash (mixed-precision quantization, approximately 3.3 bits per weight) with DFlash2 sliding-window speculative decoding and a Windows ARM64 llama.cpp CUDA runtime. Results reflect decode throughput for a synthetic code-generation workload; actual results may vary by device, configuration, and other factors.

Two ways to use local models in GitHub Copilot

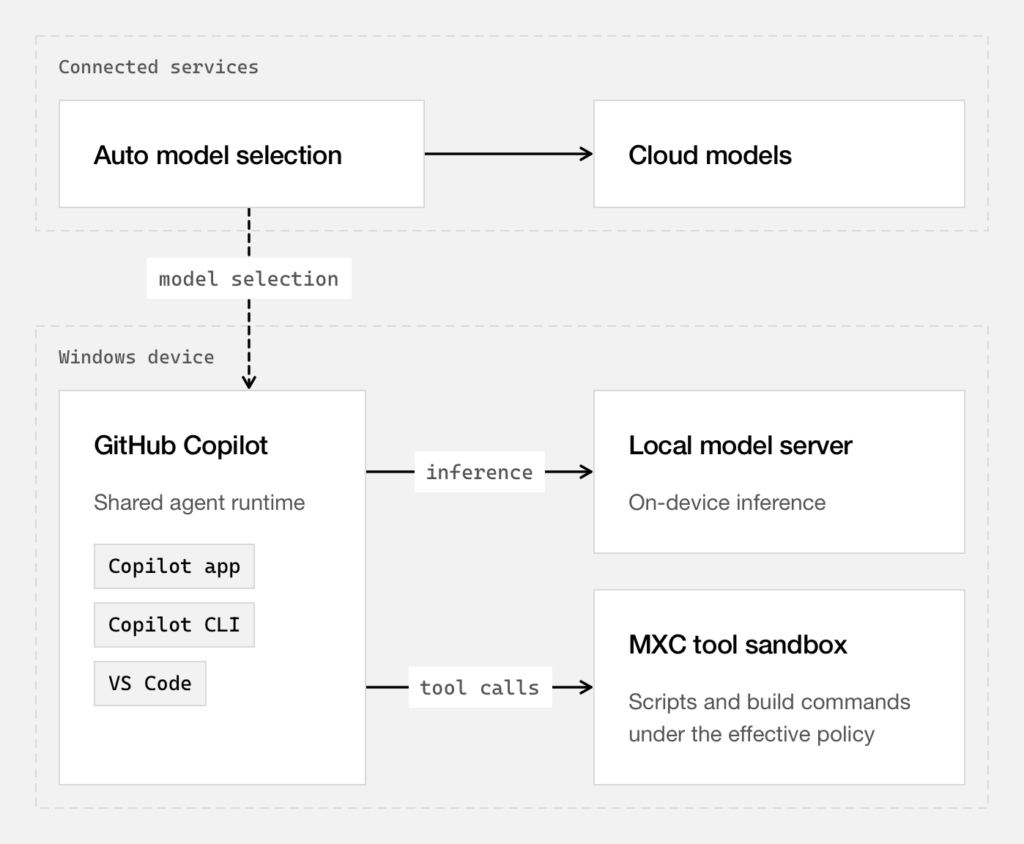
GitHub Copilot is adding two ways to use local models across the GitHub Copilot CLI, Copilot app, and VS Code. Developers can let Copilot’s intelligent Auto orchestration choose when to use local or cloud inference, or they can explicitly select a local model for workflows that require direct control.

Developers can let Copilot’s intelligent Auto orchestration choose when to use local or cloud inference, or they can explicitly select a local model for workflows that require direct control.
Model selection, inference, and tool execution have different boundaries; local inference does not make the session offline.

With Auto, developers do not need to decide where each task should be run. Across a multi-turn session, Copilot can consider task context and cache state as it routes work between local and cloud models, preserving useful, cached work as the session evolves. 

This orchestrated experience complements direct model selection, giving developers a choice between letting Copilot optimize model placement and choosing a specific local model themselves. 

Explicit local-model selection supports workflows that need a specific provider, model, or endpoint. Developers can select MAI Code 1.1 Flash through the Windows ML provider or connect GitHub Copilot to OpenAI-compatible local endpoints and choose from the models those endpoints expose.

How sandboxes help secure tool execution

An agent’s shell commands normally inherit the access of the account running them. Moving inference onto the device doesn’t change that. Sandboxing applies a policy to the processes and local services the agent launches, controlling access to files, networks, credentials, system capabilities, and execution paths regardless of which model requested the work.

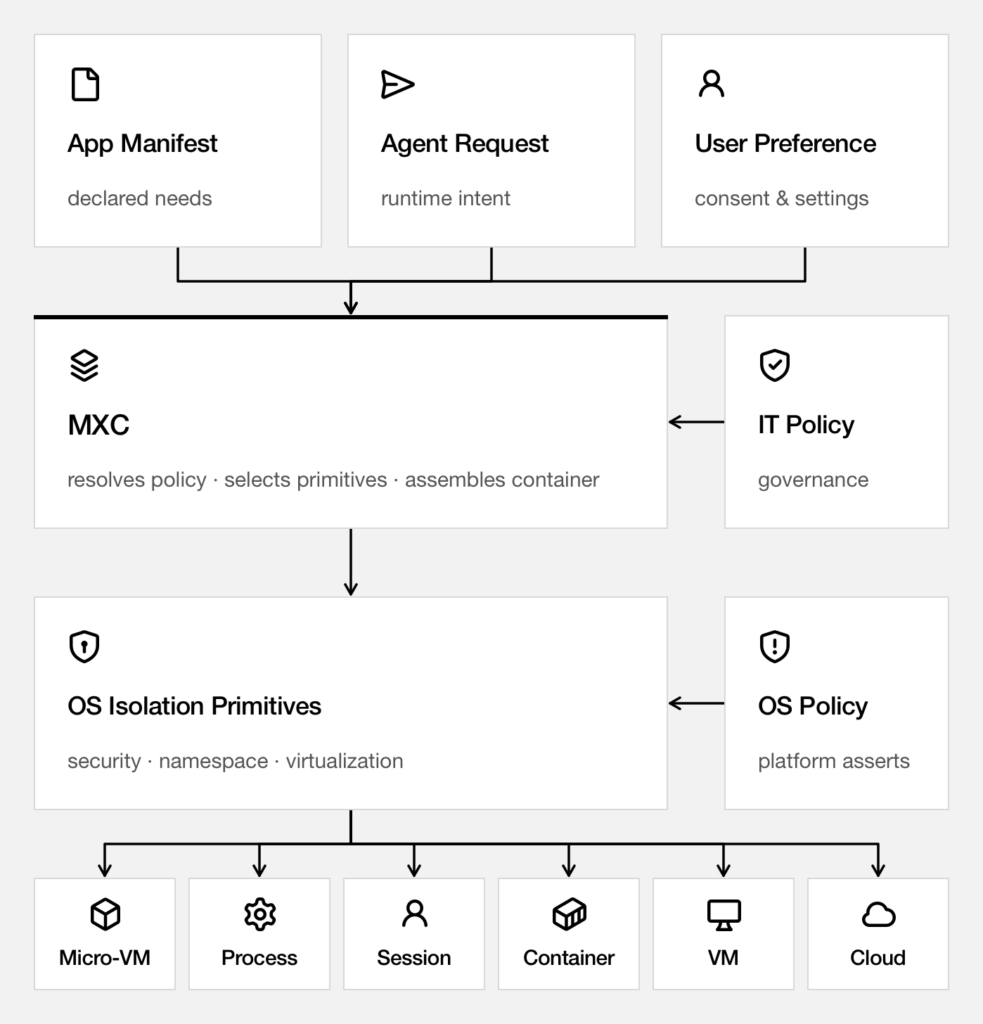
Sandboxing applies a policy to the processes and local services the agent launches, controlling access to files, networks, credentials, system capabilities, and execution paths regardless of which model requested the work. GitHub Copilot uses Microsoft Execution Containers, or MXC, an open-source library from the Windows team that translates policy into native operating-system controls.

GitHub Copilot uses Microsoft Execution Containers, or MXC, an open-source library from the Windows team that translates policy into native operating-system controls. On Windows, GitHub Copilot uses the BaseContainer tier of the ProcessContainer backend. On macOS, it uses Seatbelt. On Linux, it uses bubblewrap. These local backends don’t require a separate virtual machine or container image, but we plan to make them options available through MXC in the future. 

When sandboxing is enabled, shell commands and, by default, local Model Context Protocol servers and language servers run inside the process boundary. Built-in file tools run inside GitHub Copilot itself: the agent harness checks their requests against the effective policy, but those checks aren’t OS-enforced child-process isolation. Remote MCP servers are also outside the local process sandbox; when MCP sandbox controls apply, GitHub Copilot checks their connection policy in process. 

Opening the GitHub Copilot CLI and running `/sandbox` slash command allows you to configure your settings at any time.

A real-world example: Daily repository dashboard

To show how these technologies work together, let’s use a real-world example. 

Consider a job that reads local repositories, runs their tests in working copies, and writes one HTML report each morning. The source repositories should remain read-only, and the test processes shouldn’t access the network. Model selection is independent: the same job can use a configured local or cloud model.

Enable sandboxing for your project

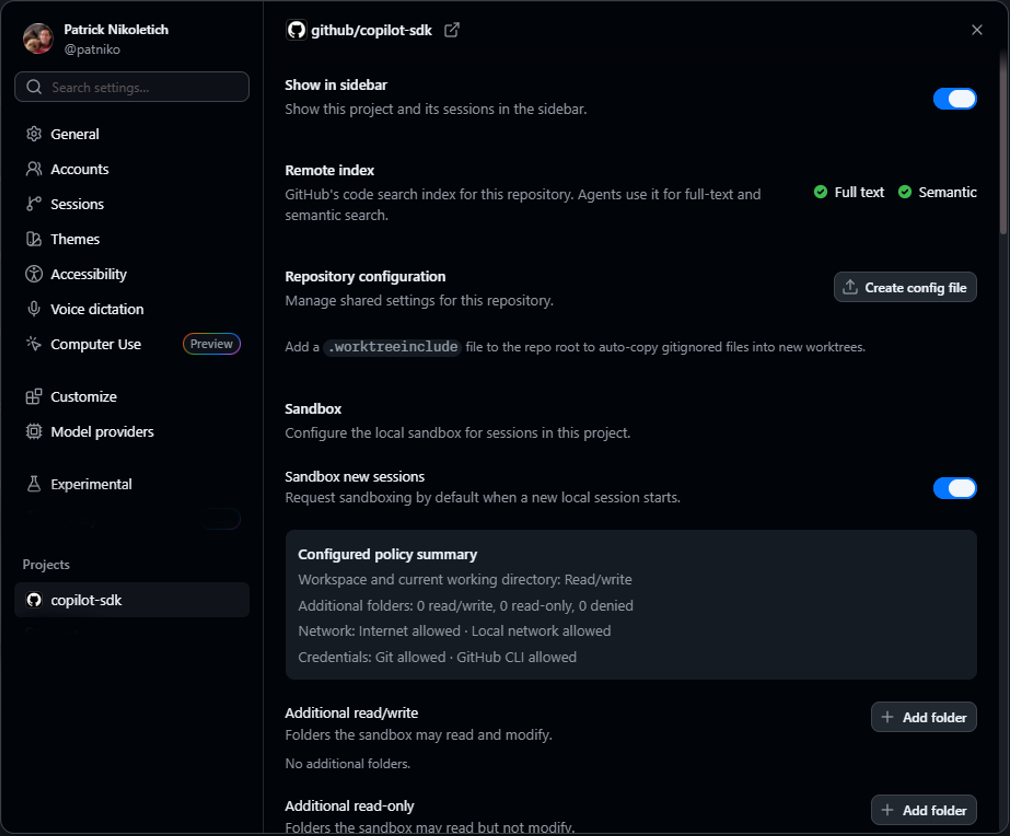
Open the settings dialog by clicking the gear icon in the GitHub Copilot app and selecting your project in the left menu. For this example, we’ll be using the `copilot-sdk` repo that hosts our opensource GitHub Copilot Runtime/SDK project.  

Enabling the `Sandbox new sessions` toggle turns on sandboxing by default whenever you work within that project. By default, it’s current working directly is read/write while the rest of the system remains largely read-only or inaccessible to an agent.

Create a new automation

Select the` Automations` section on the left navigation and click the `Start automation` button to open the dialog that allows you to configure a new automation.

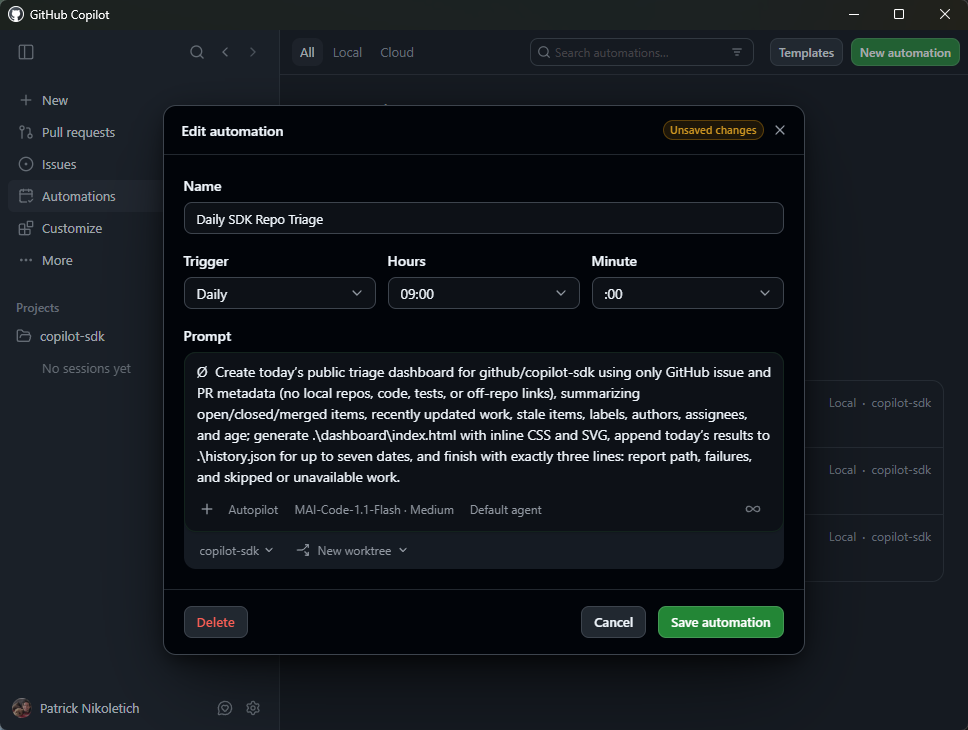
After setting a clear title and a trigger time of 9AM daily, paste in basic instructions to guide the agent through the creation of a daily dashboard for triaging.

Create today’s public triage dashboard for github/copilot-sdk using only GitHub issue and PR metadata (no local repos, code, tests, or off-repo links), summarizing open/closed/merged items, recently updated work, stale items, labels, authors, assignees, and age; generate .\dashboard\index.html with inline CSS and SVG, append today’s results to .\history.json for up to seven dates, and finish with exactly three lines: report path, failures, and skipped or unavailable work.

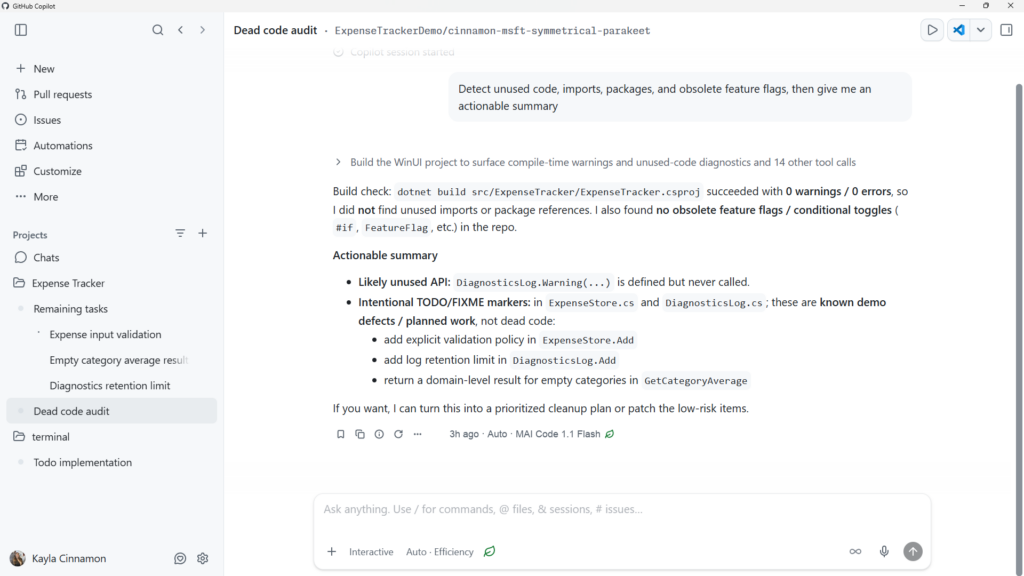
Selecting the new MAI Code 1.1 Flash local model and `copilot-sdk` repo we activated sandboxing on allows the agent to work off-line with guardrails that help mitigate unintended changes to your local machine—all while allowing your agent to generate and run scripts within its current working directory to triage and create an interactive dashboard. 

After saving, clicking `Run it now` starts executing the new automation right away for verification.

Inspect the result

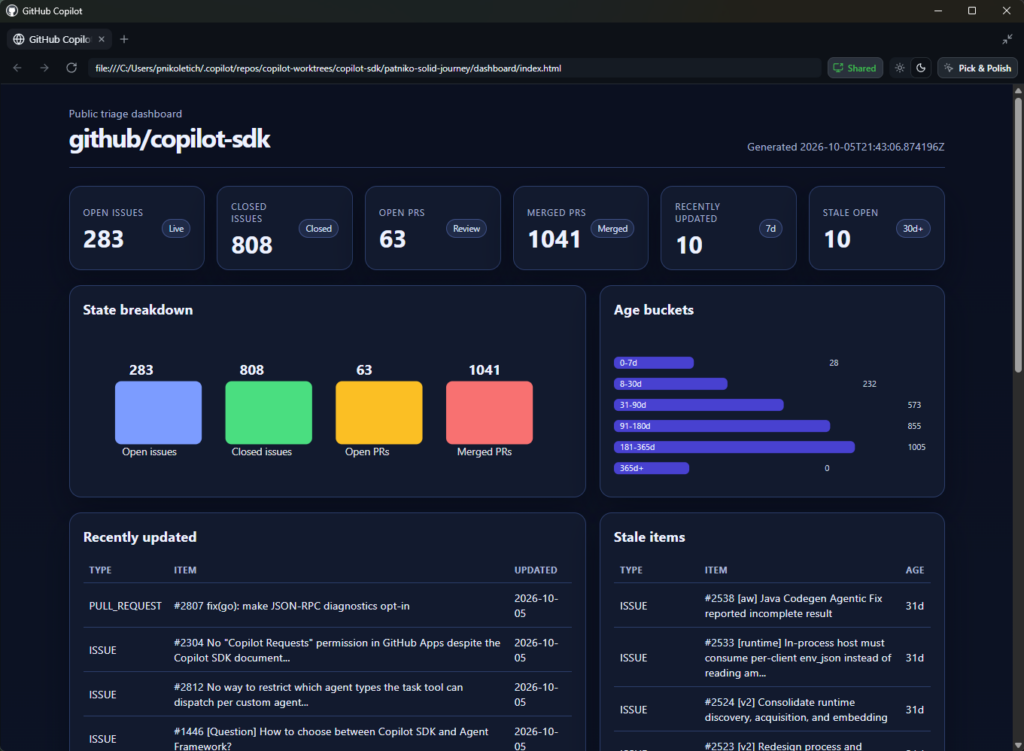
After the GitHub Copilot agent finishes the task, you can open the session artifacts to view a generated copy of the dashboard that will be refreshed daily. All done locally, and with sandboxes providing basic protection against unwanted system changes while it generates and executes scripts to accomplish the task.

Canvas dashboard generated by the new Copilot app automation.

Closing

This is only the beginning of our journey. Local models and sandboxed tools are rolling out now to give developers more choice over where intelligence runs and clearer control over what agents can do. Get started with local development with GitHub Copilot.

Acknowledgements

PM: Ryan Hecht, Tucker Burns, Lei Xu, Pierce Boggan, Nhu Do, Greg Woo, Ramya Krishna Akula, Demetrius Nelon, Harald Kirschner 

Engineering: Andrew Feller, Devraj Mehta, Mackinnon Buck, Roman Bulanenko, Chris Dern, Daniel Pagan, Keith Mahoney, Vicente Rivera, Austin Hodges, Anis Mohammed Khaja Mohideen, Stuart Schaefer, Sha Viswanathan, Carlos Alexandro Becker, Logan Ramos

Science: Ani Balasubramaniam, Shengyu Fu, Aashna Garg, Aakash Goel, Karthik Vijayan, Jennifer Zhu, Vivek Pradeep 

Marketing: Katie Liu, Alyanna Castillo 

This list is not comprehensive of everyone who has worked on this project. Special thanks to the team who put this together.  

The post Bringing local models and sandboxed tools to Windows and GitHub Copilot appeared first on Command Line.

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

AI-assisted apprenticeship

1 Share

If AI writes the first draft, where do engineers learn judgment?

AI can help a junior developer produce working code faster than ever.

That sounds entirely positive—until we remember how engineers traditionally learned.

They searched. They misunderstood. They debugged. They broke things. They asked why an experienced developer had written something in a seemingly strange way.

Those slow moments were not always wasted time.

They were where judgment developed.

The answer is not to take AI away from junior engineers. It is to redesign apprenticeship around it.

Let AI generate the draft, but ask the engineer to explain it.

Let AI propose the architecture, but require the engineer to defend the tradeoffs.

Let AI find the fix, but still investigate the failure.

Productivity and learning are not automatically the same thing. If leaders measure only how quickly work ships, we may create developers who can produce more code while understanding less of the system beneath it.

The AI-native workforce will still need mentors.

Perhaps more than ever.

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories