Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164413 stories
·
33 followers

Your best AX fixes are hiding in agent trajectories

1 Share

An eval score tells you whether the agent finished the task. To improve how agents work with your product, you need to see where they struggled, and that’s in the trajectory, the record of every step the agent took and why. Agents are persistent. They guess another URL after a 404 and try values until an error goes away, so the struggle rarely shows up in the score.

We saw this when we evaluated Dev Proxy, a local proxy that intercepts your app’s HTTP requests. We asked GitHub Copilot Chat with Claude Sonnet 5.5 and no extensions, five times, to write a CI script that uses the Dev Proxy API to record which GitHub APIs a Node.js tool calls. All five scripts worked. Yet the trajectories showed 15 problems, and each run took 29 to 39 requests and up to 1.2 million tokens.

What to look for in a trajectory

Agents can trip over your technology in many ways. We picked the patterns we think you’re most likely to find in your own trajectories, from the obvious to the surprising, and for each one show what it looked like with Dev Proxy and which fix it pointed to.

Agents guess your URLs before they search

Agents often skip the search. They fetch the URL where they expect your page to be, based on what they remember about your docs and how docs sites are usually organized. Every wrong guess costs a step and tokens, and after a miss or two, some agents give up on your docs entirely. From then on, they work from memory and trial and error, which is where outdated and invented answers come from.

Before reading any docs, four of the five Dev Proxy runs tried to fetch https://learn.microsoft.com/en-us/microsoft-cloud/dev/dev-proxy/technical-reference/api, which returned a 404. The model remembered where Dev Proxy keeps its reference and got only the page name wrong, since the real page is technical-reference/proxy-api. Two runs spent five to seven extra steps finding it, and the other two gave up on the docs altogether.

The guessing continued after the agents read the docs. Once one run found the real API page, it fetched technical-reference/plugins/executionsummaryplugin, likely because the docs’ navigation groups plugins in their own section. That page lives at technical-reference/executionsummaryplugin. In total, eight fetches across four runs returned a 404.

Check your product: A URL structure that feels logical to your team can still send agents to the wrong place, because agents predict paths from patterns, like the structure of your navigation. Look through your 404 logs for docs paths that almost exist. The logs might not tell you an agent sent them, but each one is a redirect worth adding. Print your docs URL in your CLI output too, so agents don’t have to guess.

Agents probe when your interface stops one step short

Teams often write help output and error messages for a person who can open the docs when something’s unclear. An agent, however, treats them as the spec. When they say what’s wrong without saying what’s right, the agent guesses a value, reads the next error and guesses again. Each round costs a request, and if no guess works, the agent either stops or builds around the gap.

Dev Proxy lists its API endpoints like this:

POST   /proxy                         Update proxy status (e.g. start/stop recording)
GET    /proxy/rootCertificate         Get the root certificate

It doesn’t show request bodies or required parameters. So when one run called /proxy/rootCertificate exactly as listed, it got a 400:

{ "errors": { "format": ["The format field is required."] } }

The error doesn’t list valid values, so the agent tried pem, crt, cer and der. Only crt worked.

Check your product: Run your CLI help and trigger your most common errors. Make sure each one tells the agent what a valid input looks like, with an example or the list of allowed values.

Every run reinvents the same workaround

When your product lacks something the task needs, agents build it themselves. In a single run, that’s noise. When every run writes the same workaround, your product is missing a feature, and every developer whose agent hits that gap pays for the workaround in tokens and ends up with code that’s more fragile than the feature would have been.

Dev Proxy writes its reports shortly after recording stops, with no signal when they’re done. Four runs polled the output folder for up to 30 seconds. The fifth just waited two seconds:

await api('POST', '/proxy', { recording: false });
await sleep(2000); // let the reporters flush their files

On a busy CI runner, that will eventually fail. Polling is safer, but every run that polled had to guess which file to wait for.

The strangest workaround though, was about plugins. Dev Proxy has no command that lists them, so all five runs read the plugin DLL as raw bytes and searched it for class names:

$b = [IO.File]::ReadAllBytes("$d\plugins\DevProxy.Plugins.dll")
$s = [Text.Encoding]::Unicode.GetString($b)
[regex]::Matches($s, '\b[A-Z]\w*(Plugin|Reporter)\b') | % { $_.Value } | sort -u

It worked, so no score would ever show it, but it’s far from robust not to mention efficient. A trajectory does show it, because the same odd step shows up in every run.

Check your product: Every operation that finishes after the call returns needs a way to tell the agent it’s done. Everything an agent has to choose from, like plugins or templates, needs a command that lists it.

Agents fill gaps from memory

Developers use your tool together with other runtimes and frameworks, and your docs often stop at your tool’s edge. When the docs don’t explain how the pieces fit together, agents fill the gap with what they learned in training. If the model happens to know, the run succeeds and you never hear about it. If it doesn’t, or it learned an older version, the agent writes code that looks right and quietly does nothing.

For example, to route a Node.js app through Dev Proxy, the app’s fetch needs an opt-in setting that only recent Node versions support. Every run knew this from memory:

since undici doesn’t respect HTTPS_PROXY by default, I need NODE_USE_ENV_PROXY enabled, which requires Node 22.21.0+ or 24.0+.

This time, all five got it right, but none found it in the Dev Proxy docs. A model that knew less would have recorded nothing, without an error, and you can’t predict what a model knows about your product. In a trajectory, these gaps show up as reasoning that states a fact without citing a source.

Check your product: List the runtimes and frameworks your developers pair your tool with, and make sure your docs show the setup for each. For the ones they skip, run a task and see what the agent fills in.

Agents reject defaults built for a first run

Default configs and starter templates usually serve a first run. They let developers check that the setup works and see what the product can do within minutes. For that job, they’re the right default, but for a specific task, they often get in the way. When an agent rejects your default, it builds its own setup from scratch, and each run builds a different one, so developers get inconsistent results for the same task.

Dev Proxy’s default config simulates random errors on a sample API. It shows right away that requests are flowing through the proxy and what Dev Proxy can do with them, but for recording real traffic, it’s in the way. The agents avoided it immediately:

I should avoid the default config since it’ll inject random errors, so I need to set up my own configuration instead.

When they created a new config, it came out empty. So each run built its own, and they picked three different plugins for the same goal.

Check your product: Keep the default that makes a first run work, and next to it, offer a preset for each common task developers give agents, so every run starts from the same, correct place. List those presets in your CLI help, which agents read early.

Agents trust whatever search shows them

Agents often read your guidance through a search engine, and search indexes serve snapshots. A page you updated last month can still show up in search with its old content, and the same goes for your translations and the skills you ship for agents. Agents can’t tell an old snapshot from the current page, so after a breaking change, an outdated copy that ranks well keeps producing broken code long after you’ve fixed the source.

Since v3.3.1, the Dev Proxy API requires a token. One run’s search returned two results indexed before that change. One was the Ukrainian translation of the API reference, crawled in June. The other was a file from Dev Proxy’s own agent skill, which had been updated with auth six weeks before the run. Both showed calls without a token, which now return a 401:

curl -X POST http://localhost:8897/proxy \
  -H "Content-Type: application/json" \
  -d '{"recording": true}'

The run got auth right only because it had already read the CLI help. CLI help ships with the installed version, so it can’t go stale.

Check your product: Take a few tasks developers give agents and run the web searches an agent would run for them, like “ API authentication”. Check whether the results, including translations and your own skills, describe your current version. You can’t refresh someone else’s index, but you can state version requirements at the top of each page, where they show up in search snippets and tell the agent which version a snapshot describes.

Agents assume the defaults your help text doesn’t state

Agents learn your CLI from its help text, and they take it literally. When an option reads like a switch you turn on, agents assume it’s off unless they pass it. If it’s actually on by default, they never pass the value that turns it off, because nothing told them to. For most options, the cost is a run that behaves differently than the agent expected. For a default that changes something outside your tool, the agent ships a script with a side effect it doesn’t know about, and because the task still succeeds, your eval won’t catch it either.

Dev Proxy sets itself as the system proxy by default, which routes all of the machine’s traffic through it. On a developer’s machine, that’s convenient, because every app goes through the proxy without extra setup. But the help text reads like an opt-in, and it doesn’t mention that turning the option off takes an explicit --as-system-proxy false:

--as-system-proxy                      Set Dev Proxy as the system proxy

One run found out by accident, when a status command showed System proxy: Yes, and turned it off. Another turned it off in its config, and the other three never noticed. On a Windows CI runner, their scripts would reroute all the runner’s traffic, and their kill fallback would skip the cleanup that undoes it.

Still, all three passed, because the system proxy wasn’t part of this scenario’s evaluation criteria. Meanwhile, the judge wrongly failed the run that did turn it off. The score was wrong in both directions, and only the trajectories showed it.

Check your product: Read your help text the way an agent would. Every option should state its default, and every option that’s on by default should show how to turn it off. Pay extra attention to defaults that change anything outside your tool, like system settings or installed certificates, and consider turning those off when your tool runs unattended.

Fix your product and docs before you reach for a skill

Some problems need a change to your product, like a command that lists plugins or help text that states its defaults. Others only need better docs, like a redirect for a guessed URL or a setup guide for the runtime your developers use. The pattern you found in the trajectory usually tells you which one, and both are parts of the AX stack you control.

Shipping a skill is tempting, because it feels like less work than changing your product. But a skill moves the problem to your developers. Agents now get it right only for developers who find the skill and install it. Those developers also have to keep it current, because an installed skill is one more copy of your docs that falls behind your product. In comparison, a fix in your product or docs reaches every agent that uses them, with nothing for developers to install.

With SPFx, a trajectory showed the agent reading the release notes while it worked. So instead of shipping a skill, we fixed the release notes, and every run used the right tool without anything extra installed. Start with your product and docs, and reach for a skill when they can’t carry what the agent needs.

How to start reading trajectories

Read your trajectories yourself, including the ones from passing runs. You know your product inside out, so you’ll spot workarounds that an agent reviewer would take for normal steps. ATIF Preview turns a trajectory file into a step-by-step timeline in VS Code, and an agent can help you compare runs, as long as it cites the step behind each finding.

Even then, each finding is a hypothesis until you run the same tasks with and without the fix and compare quality and cost, as described in how to measure AI agent extension effectiveness. Every change you make should leave agents better off with your product than before, and the measurement is how you prove it did.

The post Your best AX fixes are hiding in agent trajectories appeared first on Microsoft for Developers.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

GitHub PRs are slow. Keep shipping anyway.

1 Share

The issue is ready, the code is ready, and then the PR page spins. A check stays queued. A webhook arrives late. The review that should have taken ten minutes turns into an afternoon of refreshing GitHub and wondering which part of the pipeline is actually broken.

That is not hypothetical in October 2026. GitHub’s August 17 incident report says a 7 hour, 47 minute outage disrupted the site, APIs, Actions, pull requests, and issues. Its September availability report describes database pressure and work to contain failures in pull requests. The status history also records October delays across PRs, Issues, Actions, and webhooks. GitHub is doing capacity work. A development team still needs a plan for the hours when its work is waiting on that capacity.

Find the actual wait

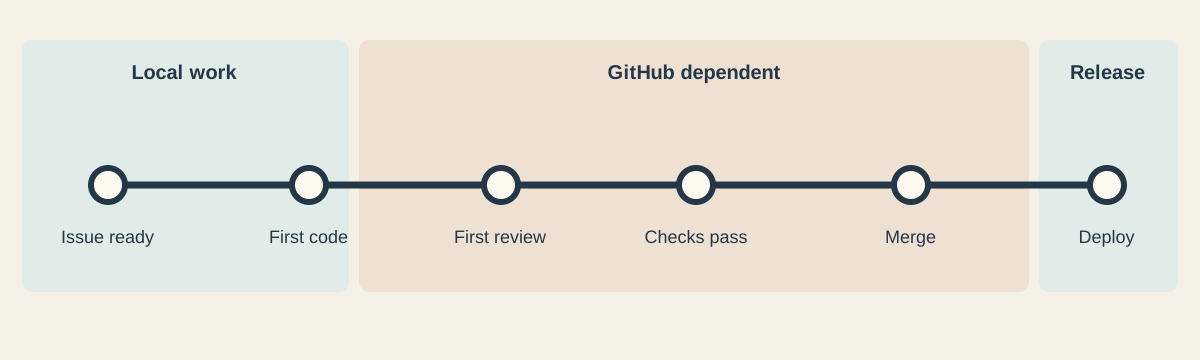
“GitHub is slow” describes the feeling, not the bottleneck. Track issue ready to first code change, code complete to first review, review complete to checks, checks complete to merge, and merge to deploy. Look at the median and the ugly tail. A slow PR page is one problem. A two day review queue is another. A CI job that queues for an hour and runs for three minutes has a different remedy from a test suite that takes an hour on a ready runner.

This measurement matters because some delays are in our own process. If a task cannot start until somebody writes an elaborate issue, or a trivial change waits behind a weekly approval meeting, GitHub uptime will not fix it. Write the acceptance criteria and the risk in a short issue or local task note, then let implementation start. The artifact should help the next person understand the work, not become a ceremony the work must survive.

The delivery timeline separates local work, GitHub dependent review and checks, and deployment

Move the fast feedback close to the code

Make the build, focused tests, formatting, and relevant static checks runnable with one documented local command. Run them before opening the PR. A remote check is still useful as the shared attestation, but it should confirm a result developers can reproduce, not be the first place anyone discovers a compiler error. Cache dependencies carefully, keep the quick checks quick, and reserve expensive matrices for changes that need them.

Review can begin from a branch or a patch while the PR UI is unhealthy. A reviewer can read git diff, run the relevant tests, and write findings in a shared local note. When GitHub recovers, put that discussion on the PR so the decision remains visible with the change. Do not mistake a green local run for the required check on a protected branch. Branch protection is a team contract, and an outage is a poor reason to silently discard it.

Keep a second path for coordination

Issues are a convenient source of truth until the issue service is unavailable. Keep enough task context in the repository or another team owned system to continue: a task ID, expected behavior, owner, and decision log. It can be a small Markdown file. When GitHub returns, reconcile it to the canonical issue. Avoid two competing permanent backlogs.

Git itself is distributed. If GitHub’s web services are degraded but Git operations still work, teams can continue committing and exchanging branches through the remote. If Git operations are unavailable too, local commits keep the work safe. For a prepared contingency between trusted machines, Git bundles can carry repository history without a live server. A second forge or internal mirror can provide a more complete continuity path, but only if the team has already rehearsed access, review, and reconciliation. Setting one up during an incident is not a shortcut.

Self hosted Actions runners solve a different problem: where jobs execute. They still connect to GitHub for job assignments, so they do not remove the Actions control plane dependency. A locally runnable test script does. A separate CI system can, if its triggers and repository access are independent too.

Reduce the amount of GitHub work per change

A giant PR asks the platform and the reviewer to do too much at once. Keep changes small enough to inspect and merge. Separate mechanical cleanup from behavior changes. Use feature flags or compatible incremental changes so one PR need not contain the entire release. Avoid automations that trigger redundant workflows on every push, comment, label, and issue edit. They add queue pressure and make it harder to tell which signal matters.

This is also where agent output can hurt. An agent that opens a PR for every tiny correction can swamp reviewers and checks. One that generates a thousand file change is worse. The useful middle is a coherent slice with a clear behavior change and a reproducible local result.

Decide what happens during an outage before one happens

For ordinary work, keep committing, testing, and reviewing locally, then publish when service recovers. For urgent production work, use the team’s documented emergency path, including independent review, recorded test evidence, and a later audit trail. If branch rules require a specific bypass, make that an explicit incident decision by the people authorized to make it. Do not give agents broad bypass permission so they can “keep shipping.”

GitHub should remain a useful place to coordinate and verify work. It does not need to be the only place work can happen. The practical goal is a pipeline that can keep making safe progress when a PR page, webhook, or runner queue has a bad day.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Meta pulls down controversial terms of service

1 Share

Meta has indefinitely delayed its proposed commercial terms of service, which would have permitted the company to scrape the websites of Meta Business account users.

On Thursday, the company took down the preview link to the proposed terms and published an update to its Business Help Center that reads: “We recently shared that we were updating the Meta Commercial Terms, Product Catalog Terms, Self-Serve Ad Terms, and Ad Creative Generative AI Terms. These updates are now paused and will not take effect on November 20, 2026. We are continuing to consult with stakeholders and will provide a further update when we have more to share. In the meantime, our existing terms remain in effect.”

Meta confirmed the indefinite delay in a statement to Nieman Lab. “We’re pausing the changes as we continue to engage with stakeholders and take our time to get this right,” said a spokesperson for the company.

Meta — which owns Facebook, Messenger, Instagram, WhatsApp, and Threads — has repeatedly pushed back the terms’ effective date since Nieman Lab first reported on them on October 15. The terms were first set to take effect on October 30, sparking global outcry among news publishers, politicians, and trade organizations. On October 16, Meta removed the word “train” from its terms and limited the use of future scraped content to “advertising and business products.” On October 23, Meta moved the effective date back by three weeks to November 20.

Last week, Meta pledged to consult news publishers and industry leaders ahead of putting new commercial terms into effect.

“We’ve heard publishers’ feedback on our proposed ads and business terms update. We care deeply about our partners and do not plan to make policy changes without a full consultation with industry groups and leaders,” vice president of communications Andy Stone tweeted on October 28. “We’re committed to getting this right, and as we expect this consultation could extend beyond November 20, in which case we’d delay implementation of the updated terms.”

Since then, courts in Norway and Brazil have issued preliminary injunctions to block the terms from taking effect as a result of lawsuits filed by media organizations in both countries. The United Kingdom’s Competition and Markets Authority has opened a formal investigation into Meta, examining whether the company was “abusing a dominant position by imposing exploitative terms on publishers and advertisers.”

In the United States, the proposed terms stoked bipartisan concern. At the end of October, Sens. Adam Schiff (D-Calif.) and Marsha Blackburn (R-Tenn.) sent letters to Meta CEO Mark Zuckerberg asking him to withdraw the terms.

Read the whole story
alvinashcraft
20 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

How GPT-6 Astra Enhanced a Small AI Model’s Capabilities by Editing Weights

1 Share

In an intriguing development at the intersection of AI and machine learning, a team from MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL) demonstrated a groundbreaking technique involving OpenAI’s GPT-6 Astra. Contrary to what many headlines suggested, this was not about teaching a small AI model, Qwen3.5-0.8B, new mathematical capabilities. Instead, it involved skillfully editing the model’s weights to remove obstacles that inhibited its performance.

The process began with identifying the core issue: Qwen3.5-0.8B had a tendency to get stuck in loops, particularly when attempting to solve math problems. This behavior wasn’t due to a lack of knowledge but rather a critical misconfiguration within its weight structure. The team, consisting of Rikiya Takehi, Jayden Teoh, Alex Zhang, and Omar Khattab, employed GPT-6 Astra to delve into the matrix of numbers defining the model—its weights—without any training or use of gradients traditionally employed in machine learning.

Based on content from Code Bear

Through sophisticated exploration, Astra identified problematic weights causing the loop and modified 131,072 out of the total 800 million weights. This impressive precision adjustment resulted in dramatic performance improvements in math competency benchmarks. Specifically, the model’s score in the MATH-500 test escalated from 7.9% to 48.1%.

This remarkable feat was achieved by allowing GPT-6 Astra to “read” and “edit” raw numbers in plain English, a novel approach that doesn’t rely on training loops. Instead of focusing on adding new knowledge, the intervention was about unlocking and utilizing existing potential that was previously unreachable due to the model’s intrinsic failures.

The authors eloquently summarized their findings, noting that while editing weights can remove barriers preventing certain abilities, it cannot imbue the model with entirely new skills. This experiment’s success underscores a profound truth about AI models—sometimes, they’re already equipped with the necessary knowledge, hidden beneath layers that need subtle tuning to correct erroneous configurations.

The detailed experiment logs are publicly accessible, offering a transparent view into the entire process, complete with every prompt and line of code used by Astra. As this technique matures, it could pave the way for economically viable AI tuning methods, tackling problems such as hidden backdoors or performance optimization without the financial and temporal overhead of comprehensive retraining.

This exploration at the frontier of AI weight editing opens a host of potential applications, from improving language models’ capabilities to fine-tuning AI systems in ways previously unimagined. The implications are vast, and as researchers continue to refine and expand these methods, we can anticipate even more exciting advancements in AI and machine learning.

For those eager to dive deeper, the edited model is available on platforms such as HuggingFace, and a live demo allows users to see the results firsthand, comparing the original and adjusted models.

Read the whole story
alvinashcraft
58 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Five Otherworldly Attractions & Experiences in Philadelphia

1 Share

Turn and face the strange, Ziggy Stardust style. Philadelphia casts an ethereal haze over the ordinary, delivering otherworldly vibes and feelings at several area attractions. It’s a city that openly invites bemused bewilderment and contagious curiosity. 

From shrinking down to the size of a diamond ring at the Ministry of Awe to viewing sunrises and sunsets in hallowed hues at the James Turrell Skyspace to seeing the stars at The Franklin Institute’s Wondrous Space, these immersive experiences suspend reality. 

Let’s take a look at five favorite spots sure to pique your curiosity.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Models Are Everywhere. Your Context Isn’t. | Microsoft IQ

1 Share

Picture a Monday management meeting. The sales director reports quarterly revenue at 14.2 million. Finance has 13.6. The regional lead has a third number from a spreadsheet updated “last week, I think”. Someone asks the company’s new AI agent, and it confidently gives a fourth. The first twenty minutes go to arguing about which number is right. Nobody discusses what the number means or what to do about it.

The first twenty minutes go to arguing about which number is right. Nobody discusses what the number means or what to do about it.

Now replay the same meeting. Everyone, including the agent, gets the same number from the same governed definition of “revenue” that the finance reports use. The agent also knows the contract terms behind the two largest deals, who has been working on the stalled ones, and that a key competitor announced a price cut yesterday.

The meeting starts with the question that matters: what do we do next?

It’s the same AI model in both meetings. The difference is the context.

The question is changing

Enterprise AI discussions have circled around this question:

Which model should we use?

That question is quickly losing its weight. The leading models are available to everyone, often through the same platforms, and a new one arrives almost every month. Choosing a model still matters, but it is no longer a lasting advantage.

The question that matters now is:

What does our AI actually know about our business?

Microsoft states this very directly: your company’s IQ is the collective intelligence locked in documents, emails, meetings, operational data and the live web, and that is where the true competitive edge lives. A competitor can use the same model tomorrow. It can’t use your customer history, your contracts, your way of defining a “key account” or the knowledge in your people’s heads.

Models are everywhere. Your context isn’t.

That’s the idea behind Microsoft IQ.

Microsoft IQ

Microsoft IQ is described as the enterprise intelligence layer of the Microsoft stack. It gives Microsoft 365 Copilot and AI agents a shared, continuously updated understanding of the organization.

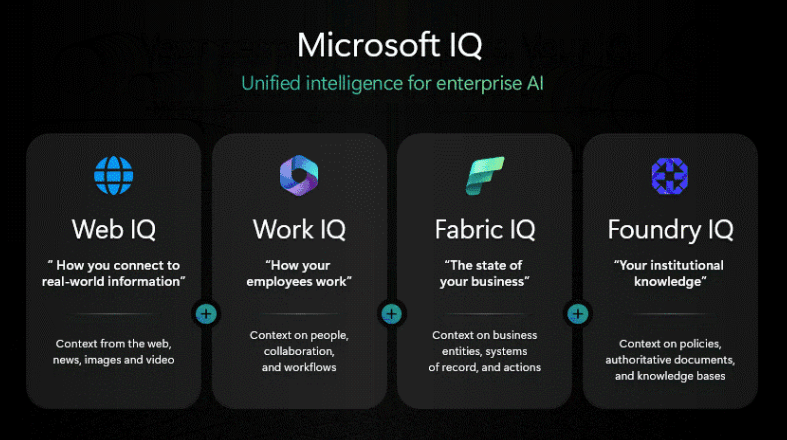
In practice, it brings together four kinds of knowledge that every organization already has but rarely connects:

  • Work IQ – how people work, and how the business runs. Emails, meetings, chats, files, people and collaboration patterns, and now also business applications: records, relationships and processes from Dynamics 365 and Power Apps. Who is working on what, what was decided, what is top of mind, and where each customer, case or order stands.
  • Fabric IQ – how the business is doing. Business data from Microsoft Fabric and Power BI, raised from tables and columns into the language of the business: customers, orders, shipments, assets, and the rules and metrics that connect them.
  • Foundry IQ – what the organization knows. Policies, contracts, manuals, guidelines and other authoritative documents, organized as reusable knowledge bases that agents can draw on.
  • Web IQ – what is happening outside. Fresh information from the web: news, pages, images and videos, so agents aren’t stuck at their training cutoff.
Image: Microsoft

None of these is a single new product to buy. Together they describe how context reaches AI across the Microsoft stack. The good news is that most of the raw material is already there, sitting in Microsoft 365, Power BI, SharePoint and Fabric.

Microsoft now presents Microsoft IQ as one of three platform pillars: Copilot for people, Microsoft IQ for intelligence, and Agent 365 for trust and governance. In Microsoft’s words, it’s the platform to compound your intelligence from within while protecting what makes the business different.

What this means

Context becomes a strategic asset. The quality, structure and ownership of business knowledge now directly shape the quality of AI results. It’s no longer just “information management”. It’s a competitive factor. Microsoft’s recent research with Keystone across more than 200 enterprises points the same way: the companies furthest ahead build a shared “knowledge spine” that holds the context agents use and the lessons from their work, so fixing one agent’s mistake can improve the others. The SharePoint knowledge base, curated by Copilot on top of Work IQ, is an early example of such a spine at team level, as described in an earlier post, SharePoint Knowledge Base – Team Memory, Curated by AI.

Existing investments become AI investments. Power BI semantic models, SharePoint libraries and Microsoft 365 content all turn into fuel for AI. According to Microsoft, Power BI accounts for over 90% of semantic models in production, and those models can be used as the starting point for a business ontology.

Build once, reuse everywhere. Instead of every AI project building its own connection to the same data, knowledge can be organized once and shared across many agents. Fewer duplicate projects, faster delivery and more consistent answers.

Shared definitions become a leadership topic. When AI answers from “the” definition of revenue, customer or active project, someone has to decide what that definition is. That isn’t an IT decision. It’s a business decision.

Governance travels with the context. Permissions, sensitivity labels and access rules need to follow the knowledge wherever agents use it. Microsoft is building this into each layer, but it still has to be planned and owned.

What can already be done today

  • Copilot answers business questions from governed Power BI data. Fabric IQ in Microsoft Copilot Chat and Cowork is generally available. Ask for the latest sales forecast, and the answer is grounded in the same semantic model that powers the organization’s reports. For Fabric and Power BI customers, this is on by default, respects existing access controls and comes without additional AI token costs. (Generally available, September 2026. Integration with the new Copilot Code experience is coming through the Frontier program.)
  • Business data can be described in business terms. Fabric IQ itself is generally available, along with Operations Agents, which monitor live conditions against business rules and recommend or execute actions, and Graph for reasoning across relationships. The ontology, the shared model of business entities, relationships and rules, can be generated from existing Power BI semantic models in a few clicks. (Fabric IQ, Operations Agents and Graph generally available since June 2026. Ontology is in preview, with general availability planned for 2027.)
  • Company knowledge can be organized once for many agents. Foundry IQ knowledge bases are generally available, with SLA coverage, compliance certifications and an MCP server that makes them usable from practically any agent platform. (Generally available since June 2026.)
  • Copilot Studio agents can use the same knowledge. The Foundry IQ integration with Copilot Studio is generally available: one knowledge base can serve several Copilot Studio agents, with cited answers and support for private networking. (Generally available, October 2026.) Work IQ is also generally available in Copilot Studio, so low-code agents can draw on emails, meetings, files and business app context. (Generally available, November 2026.)
  • One knowledge base can draw from the other IQs. New knowledge sources let a single Foundry IQ knowledge base reach into Work IQ, Fabric IQ (including data agents and ontologies), Azure SQL, uploaded files and MCP sources, with no custom integrations. (Preview.)
  • Copilot and agents understand business applications. Business Applications in Work IQ bring records and processes from Dynamics 365 Sales, Dynamics 365 Customer Service and Power Apps into Copilot and agents, with reading, creating and updating records under user confirmation. More on this below. (Public preview since September 30, 2026. General availability for Power Apps model-driven apps planned for November 2026, Roadmap 571888.)
  • Work context is available to any agent. The Work IQ API became generally available on June 16, 2026. It is licensed independently of Microsoft 365 Copilot and billed by usage in Copilot Credits, with no separate subscription or per-user licence, so custom and third-party agents can use the same work context Copilot uses. Data and tools from enterprise systems already connected to Copilot through Copilot connectors are also becoming available to agents through the Work IQ APIs, with no separate setup and with existing permissions and admin controls in place. (MC1538999, rolling out late November to late December 2026.) Agents will also be able to read a user’s own Copilot memory, such as custom instructions and saved memories, so their help is more personal. Access is read-only, follows each user’s personalization settings, and the admin policy is on by default. (MC1539004, rolling out December 2026.)
  • Agents can search work content directly. The new Work IQ Retrieve tool lets agents search email, files, meetings, Teams messages and connected sources, returning cited content that respects each user’s permissions. (Public preview, October 2026.)
  • Agents can follow meetings as they happen. Work IQ real-time transcripts give apps and agents access to Teams meeting transcripts while the meeting is still running, for live assistance and insights. (Roadmap 570651, preview since September 2026, general availability planned for November 2026.)
  • Agents can work with SharePoint, not just read it. SharePoint tools in Work IQ give agents more than 60 SharePoint operations, from finding and organizing content to lists and approvals, with separate permissions for reading and for making changes. They are also rolling out to Copilot Studio. (Public preview, November 2026.)
  • Agents can reach the outside world. Web IQ brings fresh web content to agents while honouring publisher preferences. It’s now open to all paid Azure accounts, with no waitlist and usage-based pricing, and it plugs into Foundry IQ as a knowledge source. (Available, November 2026.)
  • Business context can be shared with partners. IQ Sharing in Fabric lets organizations share data, and the business meaning behind it, with customers and partners while keeping governance of the underlying assets. (Preview.)

So there is already a lot to work with. And that is not a full list – not by all means! That’s only covering what has come out recently.

Work IQ and business applications – the systems of record join in

Fabric IQ isn’t the only way business data reaches AI. With Business Applications in Work IQ, data and processes from Dynamics 365 Sales, Dynamics 365 Customer Service and Power Apps come into Copilot and agents, with Dynamics 365 Finance and Operations rolling out as well. The business applications stay the systems of record. What changes is that Copilot and agents can now understand them, together with emails, meetings and files.

Microsoft describes the idea in three parts:

  • Model the business once. A shared semantic model tells every agent what the data means, how records relate and what the organization’s own terms mean. It builds on what already exists in the apps (views, forms and relationships) plus a business glossary, so context isn’t rebuilt agent by agent.
  • Turn the playbook into business skills. How the organization works, such as which criteria matter and when approval is needed, is captured once as a reusable skill that any agent connected to Work IQ can follow, including agents built in Copilot Studio.
  • Act with governance built in. Copilot and agents show the proposed changes, follow any required approval and update the records within the user’s own permissions, with Agent 365 providing oversight.

Microsoft’s own example is a customer renewal. The opportunity looks healthy in Dynamics 365 Sales. Dynamics 365 Customer Service, however, shows an unresolved equipment issue, and recent customer emails and a Teams meeting make clear that fixing it is a condition of renewal. No single app shows that picture. Work IQ connects it, and a renewal-readiness business skill turns it into concrete next steps.

A practical way to see the difference between the two routes for business data:

  • Fabric IQ gives the agreed analytical and operational picture: the numbers, definitions, trends and relationships across the data estate.
  • Business Applications in Work IQ bring the live records and processes themselves: this customer, this case, this order, the steps around them and the ability to update them.

Most organizations will need both. The first answers “how is the business doing?”, the second “what is happening with this customer, and what should happen next?”

The action side of this, and why permission to know isn’t permission to change, was covered in an earlier post, From Answers to Actions with Work IQ. In the Microsoft IQ picture, the same capability is what connects people’s work with the systems where the business actually runs.

Foundry IQ pulls the others together

Until now, many AI project has rebuilt the same foundation: connect to SharePoint or Azure AI Search (or some other central container with index), prepare the documents, set up search, add some business data from another system and maybe add web search on top. Every team solved the same problem again, and every solution handled permissions slightly differently.

Foundry IQ changes that pattern. An organization creates a knowledge base that holds the knowledge relevant to a domain, such as customer service, procurement or HR. That knowledge base can draw from documents and also from Work IQ, Fabric IQ and Web IQ. Any number of agents can then use the same knowledge base, whether they’re built in Copilot Studio, Microsoft Foundry or another platform.

Behind the scenes, Foundry IQ works out how to answer. It breaks a complex question into smaller ones, searches the relevant sources in parallel and returns a grounded answer with citations. Microsoft reports that this approach improved recall by up to 54% compared to simple single-shot retrieval.

Three things make this especially interesting from a business angle:

  • Reuse. A well-built procurement knowledge base can serve a procurement assistant, a contract review agent and a supplier risk agent at the same time.
  • Security at the data layer. Document-level permissions are respected, and new preview capabilities extend this to Microsoft Purview sensitivity labels and SharePoint permission sync. Agents should only see what the person using them is allowed to see.
  • Openness. Through the Foundry IQ MCP server, the same knowledge can serve agents built on many frameworks, not only Microsoft’s. That protects the investment if the agent landscape changes, which it will.

One knowledge base, many agents. That’s where the “build once, reuse everywhere” promise becomes real.

Image: Microsoft

Same question, four layers

Here is a scenario that shows the difference.

A key supplier is delivering late. A procurement manager asks an agent: “Which supplier delays should we escalate this week, and why?”

  • Fabric IQ knows the business situation: which deliveries are late, which customer orders they affect and how much revenue is at risk. Because of the ontology, the agent can follow the chain from supplier to component to order to customer.
  • Foundry IQ retrieves the supplier contracts and finds the delivery terms and penalty clauses that apply.
  • Work IQ shows who has already been in contact with the supplier, what was agreed in last week’s meeting and which account managers are getting questions from customers. Through business applications, it also brings in the open supplier and customer cases from the CRM.
  • Web IQ adds that the supplier’s main factory region has been hit by a port strike, according to this morning’s news.

The answer isn’t just a list of late deliveries. It’s a recommendation: escalate these two, here is the contract clause to refer to, these are the people already involved, and this is likely to get worse before it gets better.

Without the shared context, the same answer would take a few people half a day of emails, spreadsheets and phone calls.

This isn’t only a thought experiment. Microsoft shares customer examples that point the same way (results as reported by Microsoft):

  • Rockwell Automation built a maintenance assistant on Microsoft Foundry that brings together veteran engineers’ expertise, manufacturing data and machine manuals. At its Singapore factory, machine downtime fell by 33%, and the time for new workers to learn troubleshooting dropped from nine months to three.
  • BNY runs more than 300 solutions on its in-house AI platform, built with Azure, Microsoft Foundry, Copilot and GitHub Copilot, and plans to add Work IQ. Client transaction inquiries are resolved 80% faster.

In both cases, the advantage comes from the organization’s own knowledge, not from the model.

Things to plan for

The direction is promising, but a few things deserve attention before the context layer is switched on broadly.

Context quality is the new data quality. AI built on outdated documents, duplicate versions and unclear definitions will give outdated and unclear answers, just faster and with more confidence. Content ownership and life cycle aren’t glamorous topics, but they now directly affect AI results.Your data needs to be in order for quality context!

Ontologies are a business modeling exercise. Generating an ontology from Power BI models should be done. Agreeing on what “customer”, “active contract” or “at-risk order” means across business units isn’t. That conversation needs business owners, not just data engineers.

Business data comes with layered controls. Admin controls for business applications in Work IQ (MC1518036, preview from mid-November) split the decision across three roles. AI admins switch it on, platform admins choose which environments take part, and app makers pick the individual apps and data. Each of those roles needs an owner before Copilot and agents start reasoning over CRM and business app data.

Usage-based costs need watching. Several of these capabilities, such as the Work IQ APIs for custom agents and Foundry IQ Serverless, are billed by usage. Billing for Foundry IQ Serverless began on September 13, 2026. Agents that run often and widely can add up, so cost visibility belongs in the plan from day one. The Microsoft 365 admin center now previews central Copilot Credit cost management, including the Work IQ APIs, with spending limits and alerts. See also AI FinOps for Microsoft Copilot – a guide to Cost Management and the Cost Management API

Internal and external context are different things. Web IQ brings the outside world in, and that is valuable. It also means being clear about which answers rely on internal, governed knowledge and which rely on the public web. The same care applies inside the Microsoft stack: connecting Work IQ to a Foundry IQ knowledge base can add costs, and Microsoft notes that data may be processed outside the Azure compliance boundary, so compliance teams should review it first.

Preview is preview. Some of the most interesting pieces, such as ontologies, multi-source knowledge bases and IQ Sharing, are still in preview. The ontology is planned to reach general availability in 2027. Until then, these are good for pilots and learning, but production plans should follow the release status.

Where to start

The easiest way in is not a technology project. It’s a business question.

Pick one question that leadership regularly argues about. Revenue, forecast, customer churn, delivery performance, whatever causes the “whose number is right?” discussion. Make sure the Power BI semantic model behind it is the agreed one, and check how Copilot answers it now that Fabric IQ is available in Copilot Chat and Cowork.

Pick one domain where knowledge is scattered. Procurement, HR policies, customer service or product documentation. Organize it as one Foundry IQ knowledge base and let two or three agents reuse it.

Name owners for context. Someone needs to own the definitions, the knowledge bases and the content behind them, just as someone owns the processes.

Connect it to action carefully. Context is what makes agents useful, and useful agents will soon be asked to act. The question of what AI is allowed to change follows naturally from what AI knows. Those two discussions belong together.

From knowing more to knowing better

During recent years, enterprise AI has been a race for the best model. That race isn’t over, but it no longer decides the winner on its own.

What decides it now is how well AI understands this business: its people, its numbers, its knowledge and the world around it. Microsoft IQ is Microsoft’s answer to how that understanding gets built, shared and governed, and Foundry IQ is where much of it comes together.

Much of the foundation is already available, and more is on the way. Microsoft’s roadmap already lists a “Work IQ: Microsoft IQ” item, described as a unified intelligence layer that helps agents discover, reason over and use organizational knowledge, with a preview planned for November 2026. Microsoft has also said that Ignite (17–20 November 2026) will broaden the story further, so this is a good moment to get the basics in order before the next wave arrives.

This post continues a series on how Microsoft’s context layer is changing work. From Answers to Actions with Work IQ looked at what AI is allowed to change, and SharePoint Knowledge Base – Team Memory, Curated by AI at how AI writes down what a team knows. Microsoft IQ is the bigger frame around both.

Where does your organization stand? Is your AI working from your context yet, or still from generic knowledge?


Learn more

Status as of November 5, 2026. Preview features, roadmap dates and pricing can change.

Microsoft IQ and the four IQs

Recent announcements

Message Center and roadmap

  • MC1539004 – Work IQ expands memory capabilities to agents (published November 5, 2026)
  • MC1538999 – Copilot connectors in Work IQ APIs (published November 5, 2026)
  • MC1518036 – Admin controls to manage Business Applications in Work IQ (published October 20, 2026)
  • Roadmap 570870 – Work IQ: Microsoft IQ
  • Roadmap 570651 – Work IQ: Real Time Transcripts
  • Roadmap 571888 – Power Apps model-driven applications in Business Apps in Work IQ
  • Microsoft Fabric roadmap – IQ – ontology general availability and related items

Earlier posts in this series


Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories