Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
163965 stories
·
33 followers

From Prompt to Edge AI — Hackathon Participants Create Mobile Apps in Less Than An Hour

1 Share

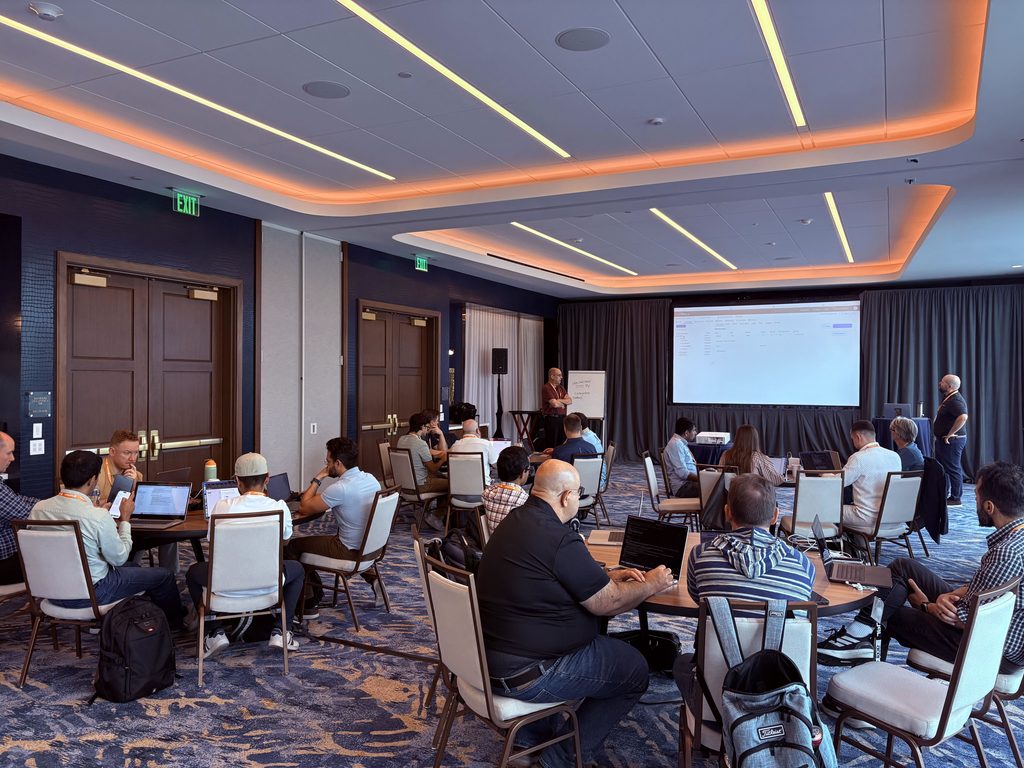
On Thursday, October 22, 2026, developers, solutions engineers, and tech enthusiasts gathered at the Omni Fort Lauderdale for Prompt to Edge AI: The Couchbase Skills Challenge. As part of Couchbase Catalyst, this hands-on hackathon aimed to demonstrate how quickly always-on mobile applications can be brought to life using natural language prompts, Claude skills, and Couchbase Capella.

Couchbase Catalyst 2026

Couchbase Catalyst 2026 brought together industry leaders, partners, and developers to explore next-generation solutions in the agentic era. Check out our latest press release to see how the expanded AI Data Plane reduces token costs by up to 45% and streamlines enterprise AI agent deployments. Opening keynotes highlighted co-innovating AI agents and edge architectures, setting a vibrant backdrop for the hands-on building challenge. Attendees were encouraged to prepare ahead of time by configuring their laptops with Xcode or Android Studio and creating a free-tier Couchbase Capella account. 

Agent Skills and the hackathon challenge

The core engine behind the hackathon was a suite of specialized Agent Skills for Couchbase Mobile. These skills automate complex tasks—such as backend provisioning, data modeling with scopes and collections, access control, and Sync Gateway configuration—allowing builders to generate native iOS or Android mobile applications using simple natural language prompts.

Participants needed no prior Couchbase experience. By prompting an AI Coding Assistant, such as Claude or Cursor with statements like “I want to build a Couchbase Mobile app,” the skill guided them through selecting their platform, configuring backend sync with Capella, and generating a functional offline-first application.

Pro Tip: These skills integrate seamlessly with Claude, Antigravity, and GitHub Copilot—test them out using your preferred AI assistant!

Ready, set, build! The hackathon experience

At 8:30 a.m., over 15 builders jumped straight into their projects, eager to get started. Equipped with their laptops, Capella free-tier accounts, and local emulators, developers spent the morning prompting AI models to build and refine their own custom edge applications.

In less than an hour of active prompting, attendees successfully generated complete mobile applications featuring local data storage via Couchbase Lite, automated conflict resolution, and seamless data synchronization with Capella App Services.
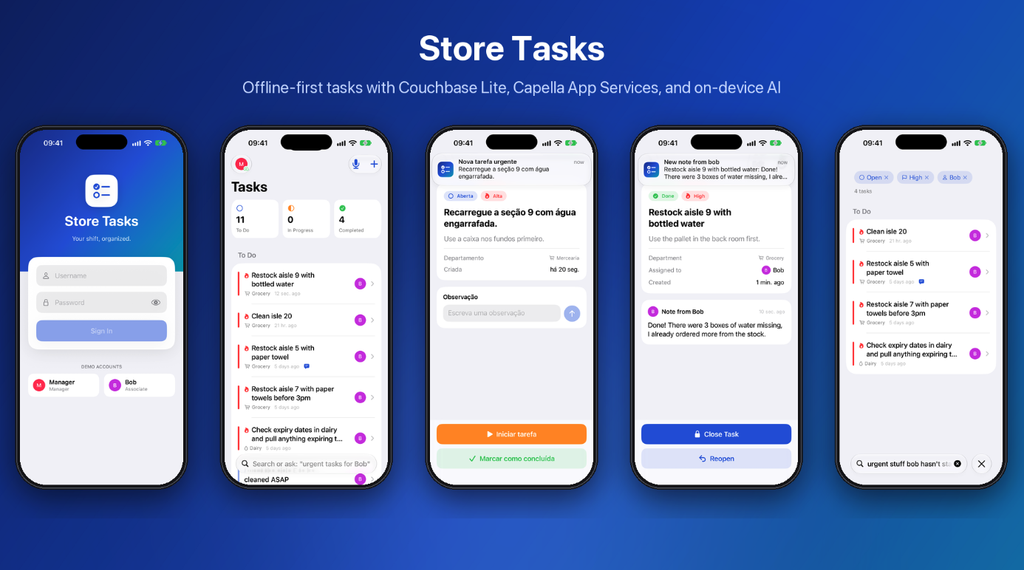
Examples of applications that were built

Hackathon participants created a wide range of innovative mobile applications tailored for edge resilience and field operations. Key projects included:

  • Healthcare Field Operations: Mobile tools leveraging embedded small language models for local retrieval-augmented generation (RAG) and client-side edge AI inference with no per-token cost.
  • Industrial Diagnostics: Offline-capable maintenance tools built for remote equipment troubleshooting and service support.
  • Collaborative Retail & Messaging: Real-time sample applications illustrating seamless multi-device data synchronization.

These applications highlighted Couchbase Mobile’s ability to maintain high availability and seamless data convergence even when network connectivity drops.

Congratulations to our winner!

A massive round of applause to David Branco, Director of Engineering at ArcTouch, who earned first place in the skills challenge. David impressed the audience with a standout mobile app created in under an hour, showcasing the incredible synergy between generative AI models and Couchbase Mobile. His project leveraged Apple Foundation Models to execute real-time message translations between English-speaking managers and Portuguese-speaking team members. The hackathon clearly demonstrated how natural language prompting with Claude skills rapidly accelerates the delivery of powerful edge AI experiences.

Special thanks to all of our amazing Hackathon participants and Couchbase facilitators for making this a truly special event.
For more information:

Ready to try building your own edge-ready mobile app with Couchbase Agent Skills? Check out these helpful resources:

The post From Prompt to Edge AI — Hackathon Participants Create Mobile Apps in Less Than An Hour appeared first on The Couchbase Blog.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Avoid Public Functions Calling Other Public Functions

1 Share

Avoid Public Functions Calling Other Public Functions

A small-scale rule of thumb. This article will land much better with a concrete example, but I am drawing a blank here, so you gotta just blindly trust my say so!

When implementing a software module, it’s often a case that you are writing a public function foo, and at least part of what foo does is already handled by another public function bar. The DRY instinct encourages you to call bar() from within foo. This usually creates problems down the line. Instead, create a new private function and refactor both foo and bar to call that shared helper:

// BAD
pub fn foo() void {
    return bar(.{ .frobnicate = true });
}

pub fn bar(options: struct {
    frobnicate: bool = false,
}) void {
    // ...
}
// GOOD
pub fn foo() void {
    return helper(.frobnicate);
}

pub fn bar() void {
    return helper(.transmogrify);
}

fn helper(mode: enum { frobnicate, transmogrify }) void {
    // ...
}

Rationale: the goal of a public API is to provide an interface that works best at the call site. If parts of public API are re-used to implement the rest of the API, then there’s a tension between making the interface convenient for the outside user and making it convenient to use from within abstraction itself. Namely, functions tend to grow optional parameters that should never be set by the user. Crucially, the parameter growth and interface degradation can happen after the original code sharing.

By proactively making the shared implementation private, the tension is defused. You still might need to tinker with helper signature until it does everything it needs to do, but, because the helper is private, this is a cheap, local change.

A notable exception to this rule of thumb are “shortcut” APIs, where a public function is defined as a commonly used chain of calls to other public functions. There, the rule is the opposite — no private calls are allowed, to make sure that it is a genuine shortcut, and not a midlayer mistake.

P.S. While researching if anyone wrote a better blog post already, I stumbled upon a fun stack overflow question, asking, paraphrasing:

I’ve heard that it is bad when a public function calls another public function. Is this really so?

The most upvoted answer explains that it is indeed bad, because this makes mocking to test a single method in isolation more complicated. Which is, imo, a natural, but horrible consequence of misguided approach to testing. You shouldn’t be mocking your methods, you should mock your IO. And, similarly, you shouldn’t test methods, but rather software functionality (unless you are building a public library with a stable API, which is a fun and important, but very narrow fraction of software development).

The accepted answer says that this recommendation makes no sense if it is not backed by an industry wide or an organizational standard. Which somehow manages to make even less sense — you shouldn’t follow the guideline rules because they are written in sanctified ink! Rather, you should apply each particular rule because of the underlying reasons that motivate the rule. Guidelines and best practices articles can concentrate lots of good reasoning in a single place, but they don’t absolve you from thinking!

Read the whole story
alvinashcraft
24 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

GitHub Universe 2026: Highlights from the developer’s developer conference

1 Share

From the menus at Mo’s Diner to the badge hack station to major product ships, GitHub Universe 2026 delivered. The annual Octoverse report came out, showing just how much the platform has scaled over the past year in the face of agentic software delivery. And the hero at the heart of the two-day event was the developer community.

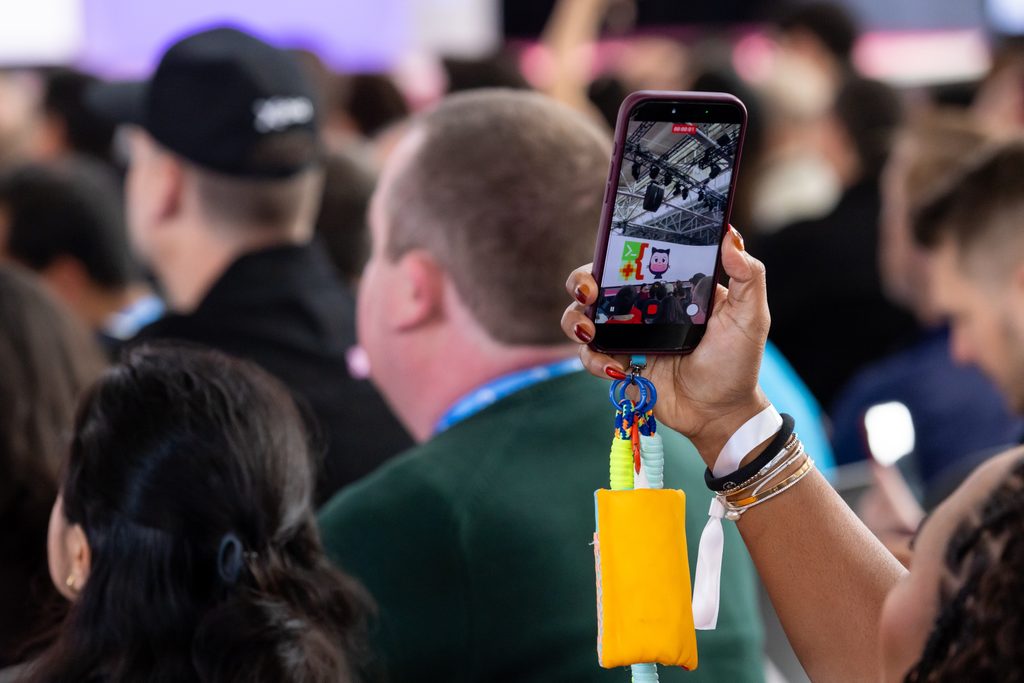
Attendees watch the keynote speech during GitHub Universe 2026, Wednesday, Oct. 28, 2026, at Fort Mason Center for Arts and Culture, in San Francisco, Calif. (Photo: Cameron Karsten)

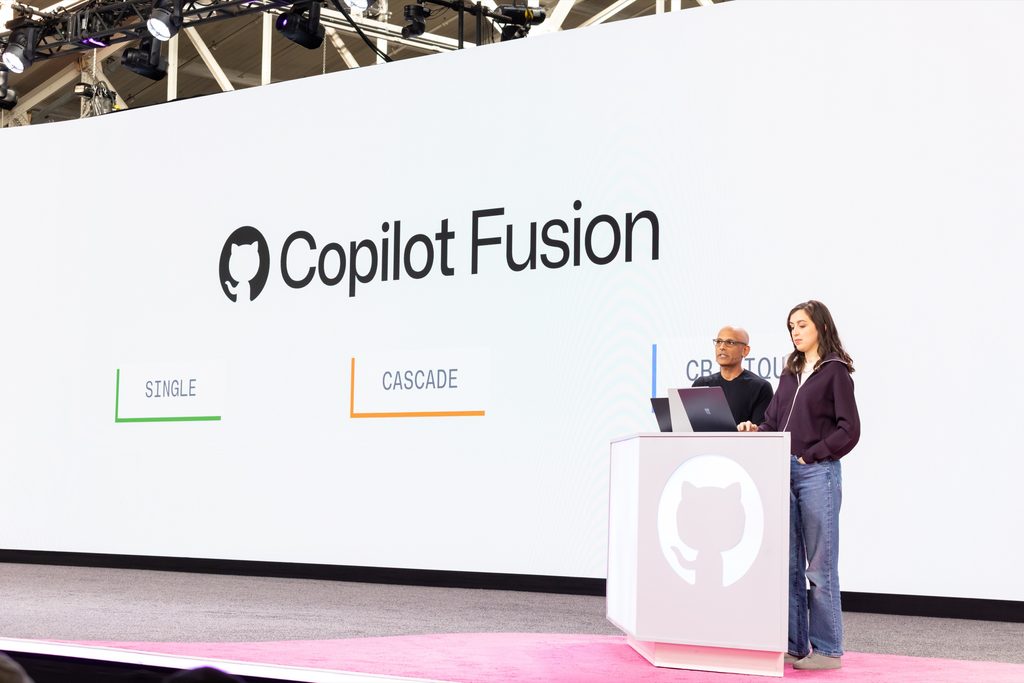
Yesterday’s opening keynote was packed with demos and announcements. But Copilot Fusion was clearly the belle of the ball.

Jay Parikh, Executive Vice President of CoreAI, Microsoft, and GitHub Senior Director of Developer Advocacy Cassidy Williams onstage during GitHub Universe 2026, Wednesday, Oct. 28, 2026, at Fort Mason Center for Arts and Culture, in San Francisco, Calif. (Photo: Cameron Karsten)

As a frame for the ships (of which there were many), EVP of CoreAI Jay Parikh laid out our vision for GitHub as the most comprehensive, end-to-end software delivery system in the world.

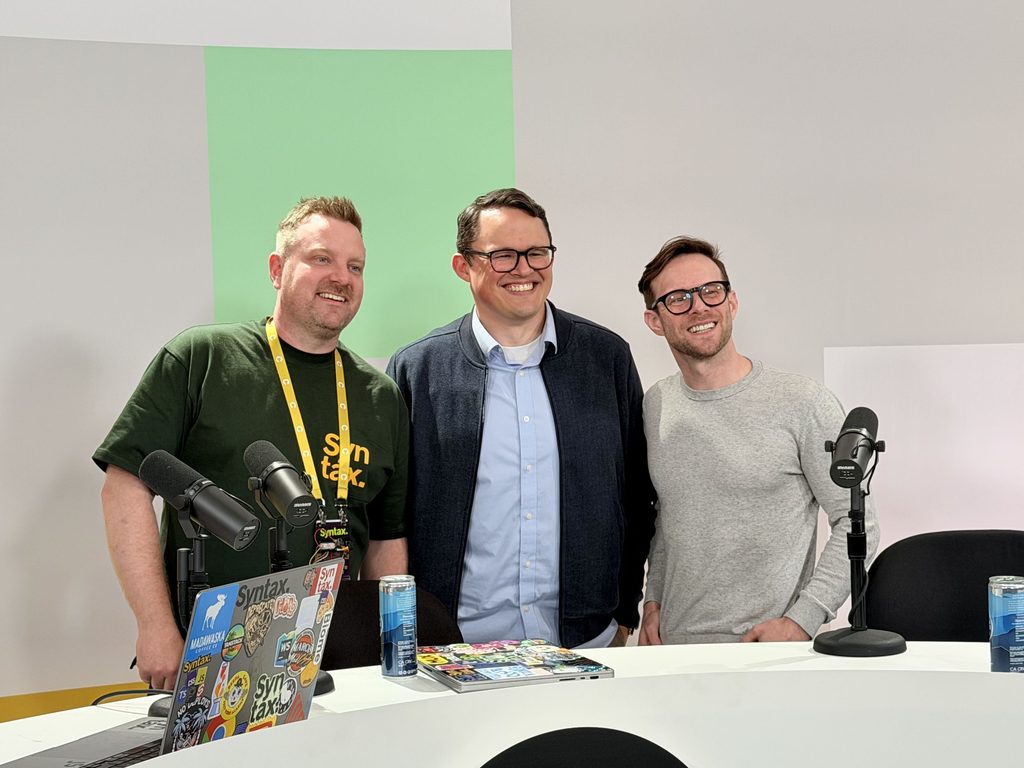
West Bos, Kyle Daigle, and Scott Tolinski.

GitHub COO and Microsoft CMO of Developer Kyle Daigle joined Syntax co-hosts Wes Bos and Scott Tolinski for a chat.

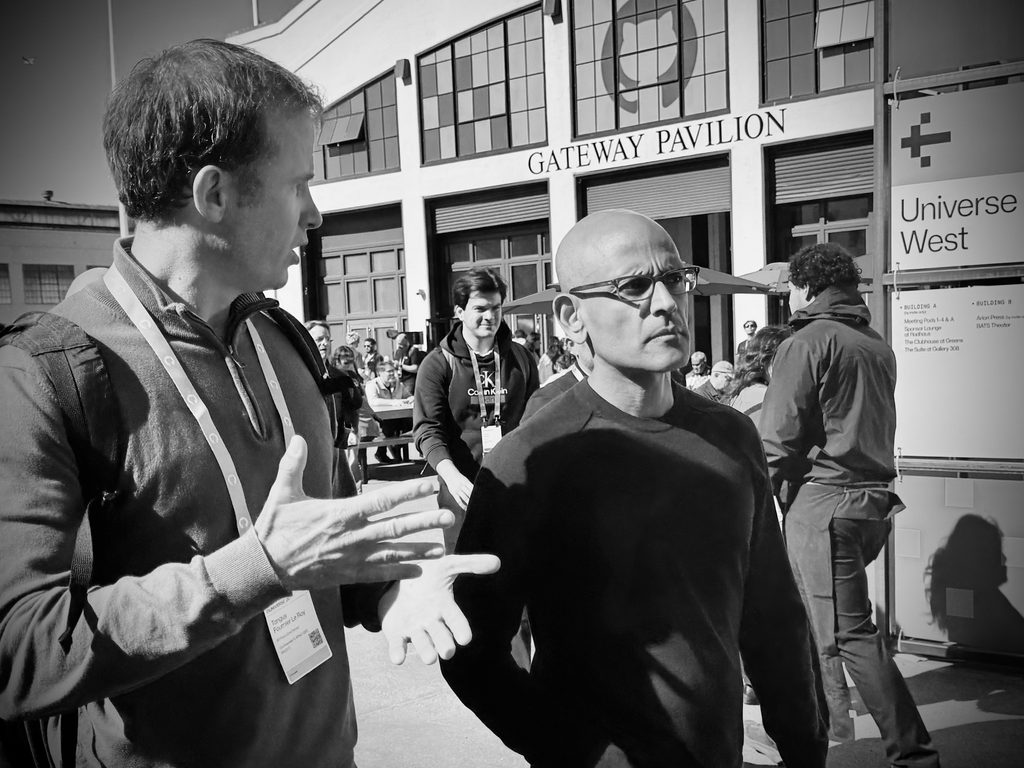
Tanguy Fournier Le Roy and Jay Parikh.

And great conversations were had, on and off the show floor.

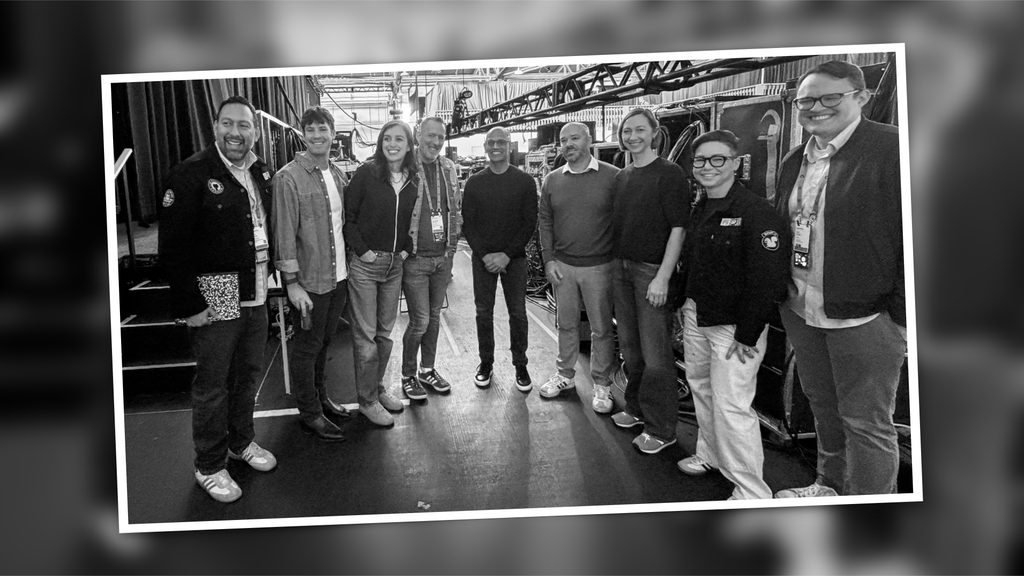
Seth Juarez, Damian Brady, Cassidy Williams, Christopher Harrison, Jay Parikh, Burke Holland, April Leonard, Jessica Deen, and Kyle Daigle.

Session spotlights 

Agentic Workflows: Automation at scale 

Automation is how we buy time for craft, enforce correctness in situations that require judgment, and improve our software at business scale. This session taught attendees how to start automating, including setting up a software factory with governance, monitoring, and security. 

Agentic engineering past the pilot: An enterprise playbook 

The industry has moved from code completion to chat to agents, and now into AI-native software delivery. But what does that actually look like inside an enterprise, where governance, developer experience, and adoption at scale all have to coexist? Through live demos spanning IDE, CLI, and multi-session orchestration, Nick Liffen and Philip Holleran shared the system-level patterns that move agentic engineering from experiment to operating model. 

Securing MCP: Real exploits, what actually mitigates them, and what doesn’t 

This interactive session broke down MCP security as it really stands today: what the threats are, which layer each one operates on, and how to host MCP servers in production without opening yourself up to unnecessary risk. 

Shut the context window! You’re letting the tokens out 

Dylan McCarthy showed how Copilot constructs context in practice, demonstrated the developer habits that quietly inflate token usage, and walked through focused workflows that produce better results with less overhead. 

Your benchmark is lying: What evals actually look like 

Julia Kasper and Walker Chabbott went behind the scenes on how GitHub Copilot evaluates models in production: what they measure, what they’ve stopped measuring, the signals that correlate with real developer outcomes, and why your favorite leaderboard may be leading your team astray. 

… and that’s just a taste of the 150+ sessions at this year’s Universe. Check out the full list here. 

Watch the full keynote … 

… or the abridged version: 42 minutes of announcements in < 8 

Before you go 

If you take away one thing from Universe 2026, make it this: 

The SDLC is no longer a linear path from planning to coding to testing to deployment. The new agentic software delivery system solves for three things: velocity, intelligence, and quality. GitHub is a platform built for you and your agents. We’ll continue releasing new products and features that push the work forward. And our ongoing infrastructure work will ensure the platform scales to meet increased demand. 

AI is changing what’s possible. But it’s in the hands of developers where that possibility converts to real-world impact.

The post GitHub Universe 2026: Highlights from the developer’s developer conference appeared first on Command Line.

Read the whole story
alvinashcraft
33 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Using Event Sourcing? Prefer the Decider over AggregateRoot

1 Share

Functional Composition.

I noticed there’s a new book coming out next month on CQRS & Event Sourcing from a .NET perspective, so I was of course curious to look at their sample code. I was admittedly looking to see if the samples used Marten and the rest of the Critter Stack, but also to just see what approach the author was using. The answers were “something else” for the tooling but what triggered this post is that the samples were all built around the old AggregateRoot pattern that was popular in the early days of Event Sourcing. So, just to summarize the rest of this post:

When you are doing Event Sourcing, I very strongly recommend you express your domain logic using the Decider Pattern and avoid the old AggregateRoot Pattern.

If you see any halfway recent literature on doing Event Sourcing and CQRS with the Critter Stack, you’ll see examples of command handlers that use the “Decider” pattern taken from Functional Programming folks like this one:

public record CategoriseIncident(
IncidentCategory Category,
Guid CategorisedBy,
int Version
);
public static class CategoriseIncidentEndpoint
{
// This is Wolverine's form of "Railway Programming"
// Wolverine will execute this before the main endpoint,
// and stop all processing if the ProblemDetails is *not*
// "NoProblems"
public static ProblemDetails Validate(Incident incident)
{
return incident.Status == IncidentStatus.Closed
? new ProblemDetails { Detail = "Incident is already closed" }
// All good, keep going!
: WolverineContinue.NoProblems;
}
// This tells Wolverine that the first "return value" is NOT the response
// body
[EmptyResponse]
[WolverinePost("/api/incidents/{incidentId:guid}/category")]
public static IncidentCategorised? Post(
// the actual command
CategoriseIncident command,
// Wolverine is generating code to look up the Incident aggregate
// data for the event stream with this id
[Aggregate("incidentId")] Incident incident)
{
if (incident.Category == command.Category) return null;
// This is a simple case where we're just appending a single event to
// the stream.
return new IncidentCategorised(incident.Id, command.Category, command.CategorisedBy);
}
}

Focus on the Post() method up above. It’s a pure function, meaning that it only deals with inputs and returns outputs. No invocations of infrastructure whatsoever. Its only real responsibility is to “decide” what if any new events should be appended to mark a change of state given the initial state of the current Incident and the incoming CategoriseIncident command. There’s of course plenty of infrastructure around that simple function, but Wolverine is mediating between the Marten persistence and your little domain logic up above.

To level set, there’s an example of using AggregateRoot in a section below just in case you’re not already familiar with that pattern.

From here on out though, here some of the reasons why I heavily recommend using the Decider over AggregateRoot in today’s development work:

  • The decider pattern makes the relationship much more clear between incoming commands and the events emitted. In other words, I think the Decider usage will make your system easier to reason about by removing layers and indirection.
  • I think unit testing is easier with the pure Decider functions than the aggregates
  • From years of supporting users and now JasperFx clients using Marten, people using the AggregateRoot pattern clearly run into more problems troubleshooting and debugging their application to the point where I tell people that I will not support them online if they run into trouble with their AggregateRoot usage (unless they’re a JasperFx customer of course, but all of our customers generally use the Decider in newer work)
  • Marten with or without Wolverine has a lot of performance optimizations built in with the assumption that the projected aggregates are not mutated by application code. You can still get *some* of that goodness by using immutable types for aggregates, but that would blow up your aggregate root usage anyway
  • I’ll agree with a common opinion that it’s helpful to separate the “evolve” functionality of how the projected aggregate state is calculated away from the “decide” logic. Especially when projections need to change later.

As a bonus, using the Decider pattern in Wolverine handlers 100% makes it a lot easier for our CritterWatch tool to derive an accurate Event Model visualization for your system.

You can find plenty of other articles out there from other people making the same case I am here, but usually with some kind of “Functional Programming is better than Object Oriented Programming” hook. My thinking on that has changed quite a bit over the years and you can clearly see much more FP thinking evident in both Marten and especially Wolverine. As much as I despise getting lectured online by FP enthusiasts and my own history as an OOP guy, I’ll say that “It doesn’t matter if a cat is black or white, as long as it catches mice” and happily use the FP Decider approach over the OOP AggregateRoot in this particular case.

As folks frequently point out, Wolverine especially has veered into FP-centric usage in our approach to command handlers or HTTP endpoints. I’ll simply say that that cat catches mice.

I also see this Decider > AggregateRoot valuation to be mostly orthogonal to the question of using “classical” stream-based event sourcing modeling versus the newer fangled Dynamic Consistency Boundary (DCB) approach because DCB very naturally fits well with Decider functions.

What’s this AggregateRoot thing anyway?

Let’s level set a little bit with a real example taken from some older documentation in Marten (which very much recommends against the approach), the “AggregateRoot” pattern calls for you to generally to model all writes to an event stream through a single aggregate type usually derived from something like this base type from our old docs example:

// Infrastructure to capture modifications to state in events
public abstract class AggregateBase
{
// For indexing our event streams
public string Id { get; protected set; }
// For protecting the state, i.e. conflict prevention
// The setter is only public for setting up test conditions
public long Version { get; set; }
// JsonIgnore - for making sure that it won't be stored in inline projection
[JsonIgnore] private readonly List<object> _uncommittedEvents = new List<object>();
// Get the deltas, i.e. events that make up the state, not yet persisted
public IEnumerable<object> GetUncommittedEvents()
{
return _uncommittedEvents;
}
// Mark the deltas as persisted.
public void ClearUncommittedEvents()
{
_uncommittedEvents.Clear();
}
protected void AddUncommittedEvent(object @event)
{
// add the event to the uncommitted list
_uncommittedEvents.Add(@event);
}
}

Then in real usage, it might be something like this:

public sealed class Invoice: AggregateBase
{
public Invoice(int invoiceNumber)
{
if (invoiceNumber <= 0)
{
throw new ArgumentException("Invoice number needs to be positive", nameof(invoiceNumber));
}
// Instantiation creates our initial event, capturing the invoice number
var @event = new InvoiceCreated(invoiceNumber);
// Call Apply to mutate state of aggregate based on event
Apply(@event);
// Add the event to uncommitted events to use it while persisting the events to Marten events store
AddUncommittedEvent(@event);
}
// Public parameterless ctor for Marten's event-store replay. Pre-9.0
// Marten could call a private parameterless ctor reflectively; the
// source-generated dispatch path in 9.0 emits direct calls instead,
// which require public visibility. See the 9.0 migration guide.
public Invoice()
{
}
// Enforce any contracts on input, then raise event capturing the data
public void AddLine(decimal price, decimal vat, string description)
{
if (string.IsNullOrEmpty(description))
{
throw new ArgumentException("Description cannot be empty", nameof(description));
}
var @event = new LineItemAdded(price, vat, description);
// Call Apply to mutate state of aggregate based on event
Apply(@event);
// Add the event to uncommitted events to use it while persisting the events to Marten events store
AddUncommittedEvent(@event);
}
public override string ToString()
{
var lineItems = string.Join(Environment.NewLine, lines.Select(x => $"{x.Item1}: {x.Item2} ({x.Item3}% VAT)"));
return $"{lineItems}{Environment.NewLine}Total: {Total}";
}
public decimal Total { get; private set; }
private readonly List<Tuple<string, decimal, decimal>> lines = new List<Tuple<string, decimal, decimal>>();
// Apply methods need to be `public` for the source-generated dispatcher
// to invoke them — pre-9.0 Marten reflected over private members; the
// SG-emitted dispatch path in 9.0 emits direct method calls. See the
// 9.0 migration guide.
public void Apply(InvoiceCreated @event)
{
Id = @event.InvoiceNumber.ToString(CultureInfo.InvariantCulture);
// Ensure to update version on every Apply method.
Version++;
}
public void Apply(LineItemAdded @event)
{
var price = @event.Price * (1 + @event.Vat / 100);
Total += price;
lines.Add(Tuple.Create(@event.Description, price, @event.Vat));
// Ensure to update version on every Apply method.
Version++;
}
}

And you’d maybe wrap the AggregateRoot access in a repository class that deals with some of the grubby technical details:

public sealed class AggregateRepository
{
private readonly IDocumentStore store;
public AggregateRepository(IDocumentStore store)
{
this.store = store;
}
public async Task StoreAsync(AggregateBase aggregate, CancellationToken ct = default)
{
await using var session = await store.LightweightSerializableSessionAsync(token: ct);
// Take non-persisted events, push them to the event stream, indexed by the aggregate ID
var events = aggregate.GetUncommittedEvents().ToArray();
session.Events.Append(aggregate.Id, aggregate.Version, events);
await session.SaveChangesAsync(ct);
// Once successfully persisted, clear events from list of uncommitted events
aggregate.ClearUncommittedEvents();
}
public async Task<T> LoadAsync<T>(
string id,
int? version = null,
CancellationToken ct = default
) where T : AggregateBase
{
await using var session = await store.LightweightSerializableSessionAsync(token: ct);
var aggregate = await session.Events.AggregateStreamAsync<T>(id, version ?? 0, token: ct);
return aggregate ?? throw new InvalidOperationException($"No aggregate by id {id}.");
}
}

Again, this is a very old code sample from before Wolverine and the “aggregate handler workflow” (our version of the Decider pattern).


Read the whole story
alvinashcraft
38 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Encapsulation in C#: Preserve Invariants Through Public Operations

1 Share

Understand encapsulation in C# with constructors, validation, and collection boundaries that preserve invariants without confusing read-only with immutable.


Read the whole story
alvinashcraft
43 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

What’s New in vcpkg (Oct 2026)

1 Share

This blog post summarizes changes to the vcpkg package manager as part of the 2026-10-16 registry release and the 2026-09-26 tool release. These updates include configurable binary-cache compression, improved cache reliability and diagnostics, Boost 1.92, and other improvements and bug fixes.

  • There are now 2,877 total ports available in the vcpkg curated registry. A port is a versioned recipe for building a package from source, such as a C or C++ library.
  • 41 new ports were added to the curated registry since the July registry release.
  • 806 ports were updated between the July and October registry releases. As always, we validate each change to a port by building all other ports that depend on or are depended by the library that is being updated for our main triplets.
  • 178 community contributors submitted merged PRs included in this release.
  • The main vcpkg repo has approximately 7,800 forks and 27,600 stars on GitHub.

vcpkg changelog (2026.10.16 release)

Tool improvements

  • Choose your binary-cache compression level. Use --binary-cache-compression-level=<0-9> or VCPKG_BINARY_CACHE_COMPRESSION_LEVEL to trade ZIP archive size for cache submission time. The command-line option takes precedence. Leaving both unset preserves the default compression level, and the setting does not change package ABIs or prevent restoration of existing archives. NuGet packaging is unaffected (PR: Microsoft/vcpkg-tool#2125, thanks @xiaozhuai!). For example, select a lower compression level when saving ZIP-based binary-cache archives: vcpkg install --binary-cache-compression-level=1
  • Fixed binary cache prechecks assigning provider results to the wrong packages after filtering the action list, improving cache availability reporting (PR: Microsoft/vcpkg-tool#2112, thanks @miyanyan!).
  • Standardized binary cache upload failure diagnostics to make cache submission problems easier to identify (PR: Microsoft/vcpkg-tool#2105, thanks @xiaozhuai!).
  • Preserved underlying registry errors instead of replacing them with a misleading “<port> does not exist” message (PR: Microsoft/vcpkg-tool#2095, thanks @bugale!).
  • Added the apple platform expression for port metadata, allowing one expression to cover Apple target platforms (PR: Microsoft/vcpkg-tool#2121, thanks @cqundefine!).
  • Propagated VCPKG_SSL_REVOKE_BEST_EFFORT to spawned processes so the certificate-revocation setting applies consistently (PR: Microsoft/vcpkg-tool#2098, thanks @mem16k!).
  • Improved Windows bootstrap proxy handling: if malformed HTTPS_PROXY or NO_PROXY settings cause an invalid parameter error, the helper warns and retries using the current user’s explicit Windows proxy settings, or a direct connection if none is configured (PR: Microsoft/vcpkg-tool#2137, thanks @camillebruckmann!).
  • Fixed NuGet exports to include vcpkg.exe in the generated package (PR: Microsoft/vcpkg-tool#2134).
  • Made x-add-version updates transactional so an error does not leave partially updated version metadata, while also reducing unnecessary work when processing unchanged ports (PR: Microsoft/vcpkg-tool#2050).

Notable port updates

  • Boost: 1.91.0 -> 1.92.0, updating the Boost collection of C++ libraries.
  • curl: 8.21.0#1 -> 8.23.0, updating a widely used networking library.
  • OpenSSL: 3.6.3 -> 3.6.5#2, refreshing the cryptography and TLS dependency.
  • libgit2: 1.9.4#1 -> 1.9.7, updating the Git implementation library.
  • Qt Base: 6.11.1#1 -> 6.11.2, updating the core Qt framework port.
  • Vulkan SDK components: 1.4.350.0 -> 1.4.357.0, with Vulkan headers updated from 1.4.350.1 -> 1.4.363.0.
  • Armadillo: 14.4.1#1 -> 15.6.1, bringing a new major version of the linear algebra library.
  • SDL 3: 3.4.12 -> 3.4.18, updating the cross-platform multimedia library.
  • 22 ports were removed as part of registry maintenance: cppdap, ctp, dx, keccak-tiny, kf5diagram, libfreenect2, qtquickcontrols2, rapidfuzz, sdl1, sdl1-mixer, sdl1-net, septag-sx, shiftmedia-libgnutls, sqlpp11-connector-mysql, sqlpp11-connector-sqlite3, tensorflow, tensorflow-cc, tensorflow-common, threadpool, v8, vcpkg-tool-bazel, and vulkan-hpp.
  • Other minor improvements and bug fixes.

Documentation updates

The following documentation changes were published recently:

  • Documented VcpkgManifestInstalledBaseDir for MSBuild solutions that use manifest mode and build multiple triplets, allowing a shared installation base directory with triplet-specific subdirectories (PR: MicrosoftDocs/vcpkg-docs#588, thanks @autoantwort!).
  • Documented VCPKG_PROVIDED_FORTRAN, including its defaults and how custom triplets can select a different Fortran compiler (PR: MicrosoftDocs/vcpkg-docs#600).
  • Added documentation for vcpkg print-usage, which displays usage information for installed packages (PR: MicrosoftDocs/vcpkg-docs#599).
  • Documented the CURL_CA_BUNDLE environment variable for configuring the certificate authority bundle used for downloads (PR: MicrosoftDocs/vcpkg-docs#587).
  • Expanded the platform-expression reference with the apple and bsd platform families, additional platform identifiers, and the corrected Xbox target condition (PR: MicrosoftDocs/vcpkg-docs#612).
  • Documented --binary-cache-compression-level=<0-9> and VCPKG_BINARY_CACHE_COMPRESSION_LEVEL, including precedence, defaults, accepted values, and compatibility with existing cache entries (PR: MicrosoftDocs/vcpkg-docs#613, thanks @xiaozhuai!).
  • Clarified how a repository-level nuget.config containing <clear /> can remove inherited binary-cache sources and cause authentication failures, with guidance for keeping the authenticated source in the effective configuration (PR: MicrosoftDocs/vcpkg-docs#614, thanks @hoshiizumiya!).
  • Updated GitHub Actions examples to pin actions to full commit SHAs instead of version tags (PR: MicrosoftDocs/vcpkg-docs#617).
  • Updated the maintainer guide with a policy for AI-reported bugs in new ports: report findings upstream, accept upstream’s assessment, and close the new port submission if upstream does not respond within 30 days. The update also clarifies terminology and other maintainer guidance (PR: MicrosoftDocs/vcpkg-docs#615).

Total ports available for tested triplets

Triplet Ports available
x86-windows 2675
x64-windows 2809
x64-windows-release 2805
x64-windows-static 2682
x64-windows-static-md 2742
arm64-windows 2486
arm64-windows-static-md 2467
arm64-osx 2639
x64-linux 2835
arm-neon-android 2271
x64-android 2334
arm64-android 2310
arm64-linux 2340

While vcpkg supports a much larger variety of target platforms and architectures (as community triplets), the list above is validated exhaustively to ensure updated ports don’t break other ports in the catalog.

Thank you to our contributors

vcpkg couldn’t be where it is today without contributions from our open-source community. Thank you for your continued support! The following people contributed to the vcpkg, vcpkg-tool, or vcpkg-docs repos in this release by submitting pull requests (listed by GitHub username):

3nids a4z aaron-stebner AenBleidd
aidangarske ajtribick albertony amarpMSFT
Amsozzer1 anders-wind asaf08da ashwinbhat
attipaci auscaster autoantwort ayzk
azchohfi blavallee bmarques1995 bmehta001
bowengu-ms Bronek btzy buck-yeh
bugale Cadons camillebruckmann cardi93
cdcseacave ChaseKnowlden chiphogg chusitoo
cqundefine csigs culhatsker danfiedler-msft
dbarkar DEgITx derchr dg0yt
dimateos dmitriyrazboev dpasukhi dunhor
dunkbing eclipse0922 ekoby emabrey
emusgrave ethanmusser ethindp EvilMcStevil
eXpl0it3r fcf-framework Flying-Magnus foobra
gafferongames galabovaa gastineau gmjasper
graphicsMan gujjwal00 hanjingo HappySeaFox
Hedede hellobertrand HenrikGharagyozyan hoshiizumiya
hoshimoe huiguangjun i-curve imakris
isanych j7nw4r JackBoosY jalfd
jamesg-nz jgillis JMC2002 jmuehlig
JohnLangford JonnyPtn jreichel-nvidia jwsung91
k-wojcik kadirlua Kanishk6582 kblaschke
kevinAlbs kimlaine Kiptoo-Deus Krzmbrzl
kzhdev leohige LeStahL LimiNode
liuzicheng1987 luadebug lucocozz lukiod
mario4tier martinus mbeutel mcoliver
mem16k mertefesensoy metsma mikke89
miyanyan moyer-avs NathanGray-ChurchillNavigation Neargye
nholthaus nickdademo nistick21 nyoma-diamond
omartijn Osyotr palchukovsky paleolimbot
papachi-one past-due pedrocatalao pedrolcl
ptahmose raulcd RazerM RealTimeChris
redboltz Reddimus reeshabh90 robbert-ef
rohanjain101 rohit-singh-gautam RT2Code saksoy-engits
saucecontrol sauloverissimo sentomk simfeo
sleepwalkera solemnwarning sorokin sparcyu
SSARCandy ssunday starxg stescobedo92
SunBlack swebb2066 sylveon syniol
talregev tangtaoit tartanpaint tesch1
Thermadiag ThomsonTan timkpaine tobbi
toge tomconder torusrxxx trueqbit
tsurumi-yizhou tucher TuxedoFish vividos
vrtulka23 wantehchang wingfiring xiaotang2333333
xiaozhuai yangjiang0217 YexuanXiao yunsmall
ZHBHFUT zsy056

Learn more

You can find the main release notes on GitHub. Recent updates to the vcpkg tool can be viewed on the vcpkg-tool Releases page. To contribute to vcpkg documentation, visit the vcpkg-docs repo. If you’re new to vcpkg or curious about how a package manager can make your life easier as a C/C++ developer, check out the vcpkg website – vcpkg.io.

If you would like to contribute to vcpkg and its library catalog, or want to give us feedback on anything, check out our GitHub repo. Please report bugs or request updates to ports in our issue tracker or join more general discussion in our discussion forum.

The post What’s New in vcpkg (Oct 2026) appeared first on C++ Team Blog.

Read the whole story
alvinashcraft
49 seconds ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories