 Log in

John Iwasz has been tinkering with Adruinos, ESP32 devices, and PCBs. In this session, he'll bringing a few things out of the home lab and demo how you to integrate microcontrollers with C#.
The session will:
\- get a basic Arduino project running
\- use a C\# application to read sensor data
\- send commands back to the Arduino to control the hardware\.
The demos will cover breadboard wiring, Arduino code, and C# so you can see how it all fits together. Expect working demos and practical examples you can build on at home.
You don’t need any electronics or Arduino experience. If you know some C# and want to try building something you can interact with, this session is for you.
⚠️ *Microsoft **requires** everyone to check-in before entering their facility. You **must** provide your first and last name when signing up for this in-person event to be on the attendees list we submit to Microsoft.*
⭐⭐⭐⭐⭐⭐
🔔🔔🔔🔔🔔🔔
**philly.NET is also on:**
* [GitHub](https://github.com/phillydotnet) · phillydotnet
* [YouTube](https://www.youtube.com/phillydotnet) · phillydotnet
* [Discord](https://discord.gg/j7mFC6H8jE) · PhillyDotNet
* [LinkedIn](https://www.linkedin.com/groups/137867/) · philly.NET
* [Instagram](https://www.instagram.com/phillydotnet/) · phillydotnet
* [Mastadon](https://jawns.club/@phillydotnet) · phillydotnet@jawns.club
* [Facebook](https://www.facebook.com/groups/phillynet) · phillynet
* [Threads](https://www.threads.com/@phillydotnet) · phillydotnet
* [X (Twitter)](https://x.com/home) · phillydotnet

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


if you want to check out all the things torc.dev has going on head to linktr.ee/taylordesseyn for more information on how to get plugged in!
Download audio: https://episodes.captivate.fm/episode/8f72e211-ed11-440f-8d2a-15055f49da32.mp3
Pennsylvania, USA
James and Frank dive into episode 540's lightning topics, exploring Apple's new Siri AI SDK that finally brings proper agentic app integration, Frank's smooth experience adding iPhone Duo support, and James's transformative use of Copilot Fusion for development. They also celebrate Tiny Clips as "real software," discuss bundling skills with NuGet packages, and break down the urgent .NET 8 & 9 end-of-life deadline before previewing an action-packed .NET Conf lineup.
Chapters
- 00:00 Opening and Lightning Topics Format
- 02:06 Siri AI SDK and App Integration
- 14:18 iPhone Duo Development Challenges
- 25:01 Copilot Fusion and AI Tools
- 31:52 Tiny Clips: Building Real Software
- 36:55 NuGet Skills for Libraries
- 42:14 .NET Updates and Conference
- 48:32 Closing and Channel Info
Follow Us
- Frank: Twitter, Blog, GitHub
- James: Twitter, Blog, GitHub
- Merge Conflict: Twitter, Facebook, Website, Chat on Discord
- Music : Amethyst Seer - Citrine by Adventureface
⭐⭐ Review Us ⭐⭐
Machine transcription available on http://mergeconflict.fm
Download audio: https://aphid.fireside.fm/d/1437767933/02d84890-e58d-43eb-ab4c-26bcc8524289/a8855de3-0149-4280-a53b-c5e606b35d26.mp3
Pennsylvania, USA

Bob and Josh each brought their top 5 moves for the first 90 days in a new leadership role, and for once they mostly agreed, which neither of them enjoyed.
Josh stamps a culture doc on day 2 or 3 and labels it version 1, then admits on air why the label is a sales device.
Bob makes the case for deep listening when everyone around you wants you to do something, and for one-on-ones that run 80% about the person and 20% about the business.
They both argue you were hired because someone already decided a change was needed, so make one sizable change early, and expect the people who asked for it to complain when it lands.
The disagreement, when it finally shows up, is about how much of yourself to show in month 1.
Also in this episode: being in rooms you think you don’t belong in, why your team’s first reaction to change is rarely the real one, and the hiring mistakes Bob made every time he ignored his gut.
Connect with Bob Galen:
* LinkedIn: https://www.linkedin.com/in/bobgalen/
Connect with Josh Anderson:
* LinkedIn: https://www.linkedin.com/in/joshuadavidanderson/
This is a public episode. If you would like to discuss this with other subscribers or get access to bonus episodes, visit www.meta-cast.com
Download audio: https://api.substack.com/feed/podcast/224086926/ab719deaa9ef812e3f6b082228b8a94c.mp3
Pennsylvania, USA
An AI agent can complete every step successfully and still act on outdated information. Learn what memory and context are, why they matter for AI agents and how traces help pinpoint where information went wrong. See how memory tools help update or remove stale records before they affect another run.
When an AI agent gives a customer the wrong answer, where do you look first? Probably somewhere that says everything worked. Let’s say a customer asks your support agent for a replacement order. The agent retrieves a shipping address, creates the replacement and closes the ticket. Every operation reports success—but the replacement is headed to a house the customer moved out of two years ago.
As far as your dashboards can tell, nothing failed. The database answered, the model responded and the ticket closed. The problem was what the agent remembered about the customer and what it passed to the AI model. Somewhere along the way, outdated information became the basis for an action.
To understand why, you need to see which records the agent retrieved, which information reached the model and which address it passed to the shipping tool. That investigation starts with understanding the relationship between memory and context.
What Are Memory and Context in an AI Agent?
Memory and context are the two ways an AI agent supplies information to the model to enable it to make decisions, and your application controls both. An AI agent is an application that uses an AI model to choose its next step and call tools (outside functions like a database lookup or an API request). The model knows nothing about your customer’s history or the state of an order, so your application has to supply all of that.
Context is what your application supplies for one model call: system instructions, the current request, recent messages, records looked up for this request and descriptions of the tools the model may call. Those tool descriptions add up fast. Give an agent a few dozen tools, and their descriptions can take up more room than the customer’s question.
The context window limits how much information a model can process in one call. Bigger isn’t automatically better, because relevant information gets harder for the model to use when a long context surrounds it. When a conversation outgrows the context window, many frameworks quietly drop the oldest messages, summarize them or reject the request without indicating any failure. This can result in silent failure.
Memory is information the agent stores for later use, such as a user’s language preference. It persists beyond the current model call and often beyond the session. Plenty of memory is written by the model itself as conversation summaries. If one of those summaries is inaccurate, the error can influence future calls until the stored information is corrected or removed.
Stored memory has no effect on the model until your application retrieves a record and places it into context.
| Memory | Context | |
|---|---|---|
| Where it lives | A persistent store used by the application | The input supplied to a model call |
| How long it lasts | Across calls and sessions, until updated, expired or removed | Assembled for each call; information may be reused |
| What changes it | Writes, deletes and expirations in the store | What your application chooses to include |
| How it fails | Information is stale, missing or belongs to someone else | The right information never makes it in, conflicts with another record or gets buried |
Pro Tip: Reserve “memory” for stored information and “context” for the input sent to a model call. Consistent labels make traces much easier to read and failures easier to investigate.
Why Do Memory and Context Change AI Agent Observability?
Memory and context change AI agent observability by adding a chain of decisions before the response that conventional monitoring never sees. To investigate a failure, you need visibility into these decisions. Observability is the ability to understand what a system did internally from the signals it produces.
In a conventional application, latency, error rates and logs can help narrow down a problem fast. An agent that returns 200 OK on time after making a bad decision produces none of those signals, and your dashboard will happily file it under success.
Before an agent answers, it may form a query against memory, retrieve stored records and select information to include in the model’s context. Each of these operations can complete successfully while passing along information that leads to the wrong outcome.
The request succeeded. The decision failed.
In the replacement-order example, when an agent mails a replacement to a customer’s old address, a database event that says “retrieval completed” leaves several questions unanswered.
Useful evidence for investigating whether it behaved as intended includes the customer identifier that filtered the query, the memory records that came back and the address that entered the model’s context. With such evidence, you can more readily separate a retrieval failure from a context-selection failure, and both from a model that made a bad call with good context.
A connected trace can help you follow information across the necessary boundaries, investigate where a failure may have begun and determine potential changes.
What Should an AI Agent Trace Capture?
A useful AI agent trace- should capture the relevant steps between the memory query and the answer the customer sees in a connected record. This includes retrieval, context assembly, model calls and tool execution within the same agent run.
Build the trace from spans. A span is a timed record of one operation, with a start, an end, a status and whatever attributes you attach to it. The emerging - OpenTelemetry conventions for generative AI agent spans- give developers a shared vocabulary for agent operations, so a retrieval span looks the same no matter which framework produced it.
You don’t have to build all of that instrumentation from scratch. The - Progress Agent Engineering- platform for observing and evaluating production agents builds on OpenTelemetry. Its software development kits (SDKs) can capture OpenTelemetry trace data for supported large language model (LLM) providers and frameworks, and its - trace view- can display available telemetry such as prompts, spans, model calls, tools and retrieval for a run.
For memory and context investigations, capture:
- Retrieval inputs: Record the memory query, the identifier that filtered it and the store that received it.
- Retrieved records: Record the IDs, timestamps and sources of the records returned.
- Context assembly: Record which retrieved information entered the context, plus the instruction version and available tools.
- Model or tool activity: Record the model output, any tool call arguments and the tool result.
Record IDs and versions matter because stored information can change after a run.
Capture only the content needed for diagnosis, redact sensitive fields before export and restrict access to traces containing customer information.
Warning: A trace that captures full prompts also captures every customer detail in them. Mask personal data before it lands in your tracing backend, or your observability tool could become a privacy leak.
What Memory and Context Failures Can Observability Expose?
Memory failures and context failures can produce different outcomes, leave different evidence in a trace and require different fixes:
Stale Memory. Retrieval may return a fact that was once correct but has since changed. Suppose a user changes an address, but retrieval returns the old record. That’s sneakier than it sounds, because semantic search ranks records by how similar they are to the query, not by how recent they are. An old address and a new one look nearly identical to an embedding model, so nothing stops the stale record from winning. The trace should show the record’s timestamp and source, so the stale record is obvious.
Incorrect Scope. A missing filter can create additional risk. If a user_id filter is left off the query, the support agent could retrieve another customer’s address and place it into context. The retrieval span would still be green because the database answered. Whether the database answered for the right user is a separate check.
Inaccurate or Poisoned Memory. Persistent storage also raises the risk of memory poisoning, where a malicious instruction saved to an agent’s long-term memory is retrieved later and steers its behavior. Bad context affects one run. Poisoned memory keeps supplying bad context until someone finds and removes the record.
Removing a record takes tooling of its own. The Agent Engineering memory and context features let you mark a memory active, outdated or removed, and semantic recall can return retrieved memories with source attribution and a relevance score.
Context Assembly Failures. Context has its own failures. Your application can retrieve the right record and then leave it out of the context. In other runs, the application attaches an outdated summary or bury the decisive instruction under so much history that the model underuses it.
Without both retrieval and context spans, omitted records, outdated summaries and buried instructions all collapse into the same useless diagnosis: The model gave a bad answer.
Pro Tip: Consider storing a timestamp and source with memory records and incorporating recency into retrieval for time-sensitive facts such as addresses.
How Can You Observe and Improve Memory and Context?
Observe and improve memory and context by turning one representative failed run into a repeatable test. Start by capturing enough relevant telemetry to help reconstruct the run for investigation. The National Institute of Standards and Technology (NIST) report on monitoring deployed AI systems separates operational monitoring from the harder question of whether an AI system keeps working as intended.
Pick a failed run and answer four questions from the trace.
- Which memory query ran?
- Which records came back?
- Which information reached the model?
- Which action followed?
If the trace can’t answer one of them without guessing from the final response, add a span at that boundary. Save the explainable run as a baseline and compare traces across releases. And keep failed-run telemetry, because trace sampling that keeps one run in 100 will, with depressing reliability, throw away the one you needed.
Next, turn the incident into a regression test. Preserve the request, the relevant memory state and the expected action. For the replacement-order example, test whether retrieval selects the expected current address for the intended customer and whether the shipping tool receives the expected value.
Use evaluations to assess the result against explicit criteria. An exact address or customer identifier suits a deterministic check. Response helpfulness may require human review or an evaluator model.
Build a small test set with successful cases and known failures. Datasets and experiments make model and prompt comparisons repeatable. When you test retrieval or tool behavior, reproduce the relevant memory and application state in the test workflow.
After deploying a change, inspect new traces to assess whether the corrected information reaches the model and whether the intended action follows.
For the replacement sent to an old address, the investigation should produce a specific correction and a regression test designed to detect similar failures before they affect another shipment.
The replacement that shipped to a two-year-outdated address still comes down to one question, and it’s the one to ask of every failed run: Did the failure begin in memory, in context or in the model’s decision?
If you don’t have tracing in place yet, the Progress Agent Engineering platform has a free plan and SDKs for .NET, Python and TypeScript.
Pennsylvania, USA

A continued programming exercise using TDD with PBT.
This article is one of a series on finding properties for a budgeting kata. I expect you to have read the previous articles in the series.
The first property specified that a bill doesn't exceed the total budget, and that's all there is to say about the total budget. All the complication lies in how category budgets are handled. In this article, we get started on that work, which will continue for another seven properties.
The code is available on GitHub, in the commit aefa192.
Per-category bounds #
My plan for this exercise was always to attempt it with test-driven development (TDD) using properties rather than singular examples. When doing TDD, I usually keep the transformation priority premise in mind: When given a choice between test cases, pick the one you predict will provoke the smallest change to the System Under Test.
Here, a good candidate may be a property specifying that for items that have no choice in which category to charge, the total cost of that category must not exceed the category limit. That description is dense, so let's unpack it. Each item in a bill comes with a set of categories. This set may be empty, a singleton, or contain multiple categories.
ghci> Item 1 1 Set.empty
Item {itemCost = 1, itemCount = 1, itemCategories = fromList []}
ghci> Item 1 1 $ Set.singleton "a"
Item {itemCost = 1, itemCount = 1, itemCategories = fromList ["a"]}
ghci> Item 1 1 $ Set.fromList ["a", "d"]
Item {itemCost = 1, itemCount = 1, itemCategories = fromList ["a","d"]}
Some or all of those categories may be 'unforced' or irrelevant categories. What matters is which categories are associated with limits in the budget. If the budget only comes with a limit for category "a", the first of the above examples has no category limit, and the two other items are uniquely constrained by the "a" limit. For the third example item, the "d" category is irrelevant, since there's no budget limit for "d".
Another way to put it: If the intersection between an item's categories and the budget category limits is a singleton, then the item is uniquely constrained by that category.
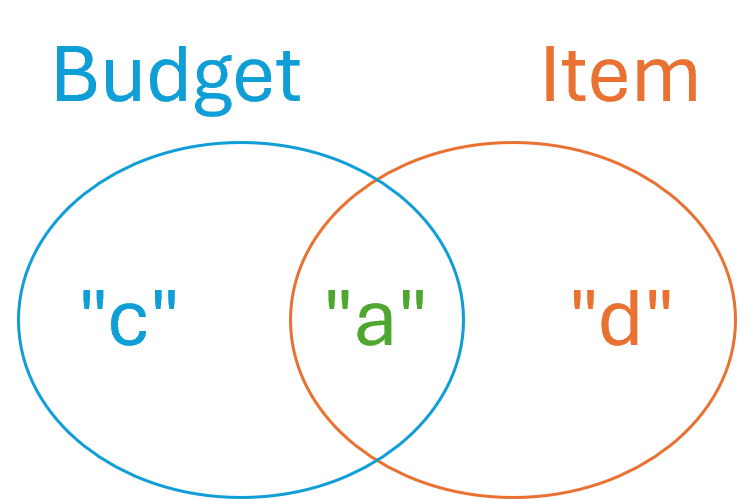
There could be more than a single item with the same intersection, but the sum of those items constitute the cost of that category, and (as long as the items are uniquely forced by a single category) that cost must not exceed the category limit.
Now that I write this explanation, I wonder whether I could have expressed a property like that, but here's the property that I actually wrote:
testProperty "Forced category limit applies" $ \
  (fmap getItem . getNonEmpty -> bill :: Bill Char)
  (NonNegative catLim) ->
  Set.unions (itemCategories <$> bill) /= mempty ==>
  do
    cat <- elements $ Set.toList $ Set.unions (itemCategories <$> bill)
    -- Force the selected category by making it the only category for those
    -- items that have it.
    let bill' = (\i -> if Set.member cat (itemCategories i)
                      then i { itemCategories = Set.singleton cat }
                      else i) <$> bill
        budget = Budget (billCost bill') (Map.singleton cat catLim)

        actual = canAfford budget bill'

        expected = categoryCost cat bill' <= catLim
    return $ counterexample ("Budget: " ++ show budget) $
             counterexample ("Bill: " ++ show bill') $
             expected === actual
Like the previous property this one also uses view patterns to pull the bill out of a list of AnyItem values, but now this list is a NonEmptyList. Likewise, pattern matching on NonNegative makes catLim an Int. The entire type for the lambda expression (everything after $ \ ) is
NonEmptyList (AnyItem Char) -> NonNegative Int -> Property
Notice that I have now changed from Bill String to Bill Char. To be honest, I no longer remember why I did that, but it could be a remnant of an (uncommitted) attempt to constrain QuickCheck's choice of categories, so as to increase the chance that it would occasionally create a bill where a category would span more than a single item. Given that Char is actually a Unicode character with more than a million possible values, this was probably naive.
The property uses the implication operator ==> to make sure that the generated bill has at least one category on some item. It then picks one category from the set of all categories of the bill, and creates a modified bill' that replaces category sets with only that category for those items that originally included that category. For example, if cat is 'a' then
Item 1 1 $ Set.fromList ['a', 'd']
becomes
Item 1 1 $ Set.fromList ['a']
The property constructs a budget by setting a limit catLim only for the chosen category cat. Since catLim is any NonNegative number, this limit may or may not make the bill affordable. This limit, however, is the only deciding factor, since the budget is constructed with a total limit of billCost bill'; in other words, the total limit is always just permissive enough. Thus, the expected result is whether the categoryCost is less than or equal to catLim.
A questionable API #
I added the categoryCost function to the implementation code:
categoryCost cat =
  sum .
  fmap (liftA2 (*) itemCost itemCount) .
  filter (Set.member cat . itemCategories)
In retrospect, I'm not sure that this was a good idea, because one could argue that the cost of a category depends on how the final algorithm decides to distribute items among categories. For example, you could have a bill like this:
bill = [Item 2 1 $ Set.fromList ['a', 'c'], Item 2 1 $ Set.fromList ['b', 'c']]
and a budget like this:
budget = Budget 4 $ Map.fromList [('a', 2), ('b', 2), ('c', 1)]
A correct implementation of the decision algorithm would consider that bill affordable, because it can distribute the cost of the first item to the 'a' category, and the second item to the 'b' category. Effectively, the cost of category 'c' for that bill is nought. Even so, that's not what categoryCost answers:
ghci> categoryCost 'c' bill
4
In a sense, you could argue that this is correct, because categoryCost doesn't take the budget into account. Thus, it's rather an indication of the maximum cost of that category. Perhaps I should have named the function maxCategoryCost.
The simplest thing that works #
Given the two properties so far, the simplest thing I could think of that passes all test cases is this:
canAfford budget bill =
  billCost bill <= totalLimit budget &&
  all
    (\(cat, lim) -> categoryCost cat bill <= lim)
    (Map.toList $ categoryLimits budget)
It naively checks that for each budgeted category, the categoryCost must not exceed the the category limit. This is clearly incorrect, because it rejects, among many other examples, the bill and budget discussed above. More properties are needed.
Conclusion #
Attempting to do the budgeting exercise with TDD using QuickCheck properties, I added the first of many properties to describe the desired behaviour related to category limits. It specifies that if an item is unambiguously forced by a single category limit, then that limit must not be exceeded.
This property still feels a bit ad-hoc to me; as one of those 'examples on steroids' I've already discussed. Thus, I was keen to add something that sounded more like proper computer science.
Next: QuickCheck property: Monotonicity in items.
This blog is totally free, but if you like it, please consider supporting it.
Pennsylvania, USA
Next Page of Stories