Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164169 stories
·
33 followers

What exploited vulnerabilities have in common: A data-driven analysis of real-world attacks

1 Share

The vulnerability landscape continues to expand. From 1999 through September 2026, approximately 383,000 software vulnerabilities had been disclosed across platforms and technologies, yet only about 2,000 CVEs (roughly 0.5%) have been linked to real-world exploitation.

Those vulnerabilities follow clear patterns. Threat actors disproportionately target flaws that enable system takeover, particularly remote code execution, privilege escalation, and authentication bypass. AI-assisted vulnerability discovery and exploit development could further shorten the window defenders have to respond.

Patching remains essential, but remediation can take weeks or months on critical systems, and some legacy or unsupported systems cannot be patched. Defenders therefore need to concentrate protection where it can have the greatest impact, considering both the likelihood of exploitation and the potential blast radius of a successful attack.

Classifying the vulnerability landscape

To make this large vulnerability population actionable, we analyzed each CVE across two dimensions: impact class and affected platform.

Impact class captures the outcome a threat actor could achieve by exploiting a vulnerability. Each CVE is assigned to the most consequential impact it directly enables. For example, when a vulnerability can bypass authentication and directly enable remote code execution (RCE), we classify it as RCE. This approach helps distinguish the underlying type of vulnerability from the security impact an attacker could achieve.

  • Server-side RCE: Remote code execution on a network-exposed service without user interaction.
  • Client-side RCE: Remote code execution that requires a user to open or run malicious content.
  • Local code execution: Code or command execution requiring local access or an existing foothold.
  • Local privilege escalation: Elevation from lower-level access to SYSTEM or root privileges.
  • Authentication or authorization bypass: Circumvention of authentication or access controls.
  • Security-control bypass: Circumvention of protections such as sandboxing, secure boot, or SmartScreen.
  • Information disclosure: Exposure of sensitive data or secrets.
  • Tampering or integrity: Unauthorized modification of data or system state.
  • Denial of service: Disruption of system or service availability.
  • Cross-site scripting (XSS): Script execution within a victim’s browser context.
  • Arbitrary file access: Unauthorized access to or placement of files.
  • Spoofing or redirect: Spoofing, redirection, or other forms of UI deception.

We also classified vulnerabilities by the platforms they affect, including Windows, Linux/Unix, mobile, network appliances, IoT/OT, virtualization hosts, and developer packages. A CVE can span multiple platforms. Developer packages are treated as a separate category because they are often cross-platform and represent a significant share of the overall vulnerability population.

Most CVEs in the analysis affect application code, including servers, web applications, browsers, productivity software, libraries, and firmware tooling, while a smaller share affects OS and system code such as kernels, drivers, and firmware.

This analysis covers CVEs published through September 2026 using Microsoft’s catalog of tracked vulnerabilities. Each CVE is counted once in the impact analysis and across each relevant platform in the platform analysis.
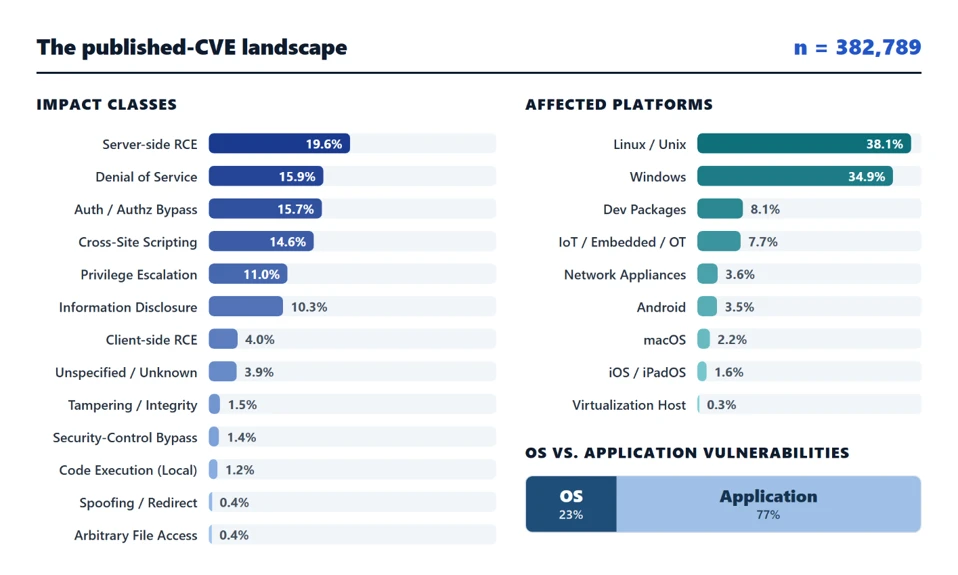
Infographic of 382,789 published CVEs: 77% affect applications and 23% operating systems; leading impacts include server-side remote code execution, denial of service, and authentication bypass. Linux/Unix and Windows are the most affected platforms.
Figure 1 – The full published-CVE population as of September 2026, broken down by impact class and affected platform, and an OS vs. application split. Breadth dominates – many impact classes spread across many platforms, with about 77% of CVEs in application code and 23% in OS/system code.

Vulnerabilities exploited in the wild

The subset of vulnerabilities exploited in the wild is much smaller than the overall CVE population, and looks very different from it. Fewer than 1 in 200 published CVEs are ever used in a real attack, and those that do get used are overwhelmingly concentrated in the takeover classes that maximize threat actor impact and exposure.

The difference becomes clear when we look at impact. Exploitation is heavily concentrated in vulnerabilities that give attackers greater control over a system. Server-side RCE rises from 20% of published CVEs to 37% of exploited CVEs, local privilege escalation from 11% to 18%, and client-side RCE from 4% to 13%. By comparison, XSS falls from 15% to 4% and denial of service from 16% to 7%. OS vulnerabilities show a similar shift, increasing from 23% of the overall CVE population to 41% of exploited vulnerabilities.

These patterns are consistent with threat actors favoring vulnerabilities that can provide meaningful access and control. Remote code execution and privilege escalation can create footholds that support subsequent stages of an attack, while vulnerabilities that primarily cause a crash or limited script execution may offer less utility for broader compromise.

Importantly, a vulnerability’s stated classification does not always reflect what an attacker can reliably achieve in practice. For example, some vulnerabilities described as enabling RCE may ultimately result only in denial of service under real-world conditions. Understanding the demonstrated impact and exploitability of a vulnerability is therefore critical to effective prioritization.
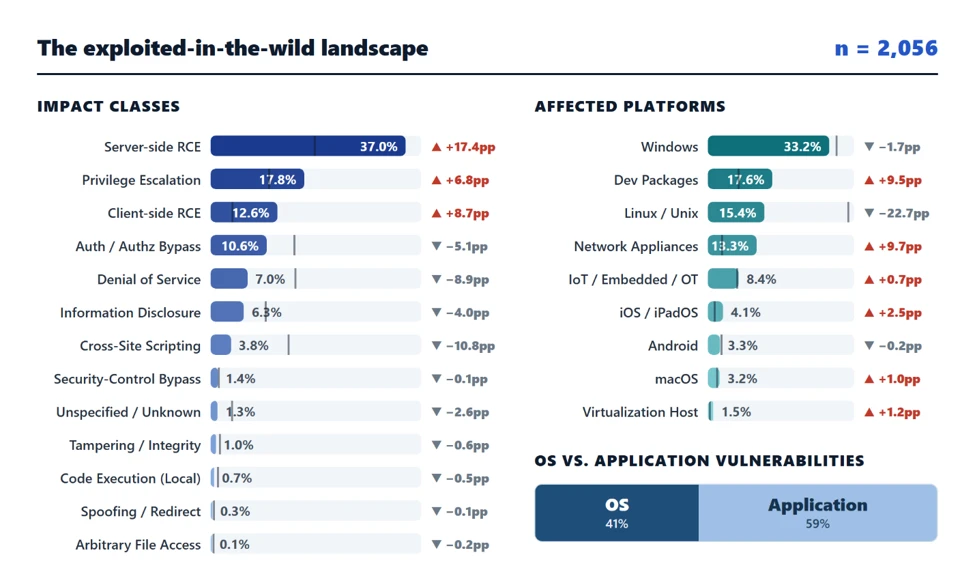
Infographic of 2,056 exploited-in-the-wild CVEs: server-side remote code execution is the leading impact, Windows the most affected platform, and vulnerabilities split 59% application to 41% operating system.
Figure 2 – The 2,056 exploited-in-the-wild CVEs distribution, compared against the full published population: ghost lines mark each class and platform’s share of all ~380K published CVEs, and badges show the shift in percentage points. Takeover classes and OS code rise, while high-volume XSS and DoS fall.

Where defenders should focus

Patching is slow, while exploitation is fast

Patching is slow, and far slower on critical systems than others. Across platforms, servers are the critical assets and the slowest to patch. Microsoft Security Exposure Management data from 2026 shows that the median vulnerability is patched in about two weeks on Windows workstations but in more than a month on Windows Servers. It stretches to 10+ weeks on Linux Servers and for applications running on MacOS, and beyond a year on network appliances. That gap is the threat actor’s window, widest on the critical systems that stay exposed the longest.

Exploitation runs on the opposite clock: the most impactful vulnerabilities are weaponized in days, increasingly on or before disclosure. According to VulnCheck, 29% of the exploits in 2025 were launched within 1 day of CVE publication. According to CISA, the mean time from CVE publication to CISA KEV catalog fell from 89 days in 2024 to 57 days in 2025. 2026 data up to September already have that number dropping to 20 days, with a median of only 3 days since publication. Industry research suggests that advances in AI are a significant factor in the time reduction required to develop exploits, further increasing pressure on defenders to respond quickly.

Impact, exposure and where to focus

Two things determine a vulnerability’s value to a threat actor: impact and exposure. Impact is what successful exploitation provides, such as remote code execution or privilege escalation. Exposure is an asset’s position in the environment and the opportunities it creates for further compromise. An asset’s exposure is shaped by the identities, privileges, and connections available from it.

Servers often use service accounts, application identities, or cloud-managed identities with permissions beyond their operational needs. Compromising such a system can provide access to additional resources, sensitive data, administrative privileges, or trusted network paths. Together, impact and exposure determine the blast radius: a vulnerability that enables full control of a highly exposed system can enable widespread on-premises or cloud compromise.

Threat actors do not exploit at random: they go after the vulnerabilities that give the highest impact and exposure: full control of a system and the privileged identities and critical assets it has access to. As defenders, focusing on these vulnerabilities first can deliver the highest return on remediation investment.

Takeover vulnerabilities like remote code execution, authentication bypass and local privilege escalation lead here. They drive the broadest exposure and the largest blast radius, account for 78% of real-world exploited vulnerabilities, and stopping their exploitation interrupts attacks at the earliest stage, before compromise can propagate across the environment.

Next in line

A second slice deserves attention where context makes it severe: denial of service against availability-critical assets is recoverable in general, but can be mission-ending in parts of your environment where uptime is everything; disclosure of credentials or secrets can be minor as an insulated incident, but it feeds the same privileged-identity path mentioned above.

Stacked bar chart of 1,239 exploited remote-takeover CVEs by platform and code layer. Server-side RCE is the largest class, led by Windows and Linux/Unix; bars distinguish application from OS/system vulnerabilities.
Figure 3 – The three remote-takeover classes analyzed across 1,239 exploited CVEs), each drilled down by affected platform and split into OS vs Application code. Bar length is the CVE count per platform; the dark segment is OS/system, the light segment is application.

How Microsoft Security helps defenders act

Threat actors do not begin with a vulnerability list. They begin by looking for a reachable way in. Microsoft Defender External Attack Surface Management approaches the environment from that same outside-in perspective, continuously discovering internet-facing infrastructure, including previously unknown or unmonitored assets, shadow IT, and third-party dependencies. This gives defenders an opportunity to remove unnecessary exposure before a reachable vulnerability becomes an entry point.

Once the reachable assets are known, the next question is which weaknesses deserve immediate attention. Defenders need a way to prioritize exposure beyond CVSS alone. Microsoft Defender Vulnerability Management addresses this challenge through Exposure Score and prioritized security recommendations.

Prioritization incorporates threat and exploitability signals, breach likelihood, internet exposure, and asset criticality, helping teams focus remediation on vulnerabilities that create the greatest actual exposure.

An initial foothold is only part of the risk. Attack Path Analysis connects assets and threat actor techniques into end-to-end routes from an entry point to a critical asset. Microsoft Security Exposure Management Attack Path Analysis provides a cross-workload view spanning endpoints, cloud, and hybrid environments, using vulnerability context from MDVM, endpoint data from Defender for Endpoint, and cloud asset data from Defender for Cloud. Within cloud environments, Defender CSPM Attack Path Analysis adds detailed context about internet exposure, vulnerabilities, network connections, identities, and permissions across Azure, AWS, and Google Cloud.

Together, these experiences show how an exposed workload could become a path through a privileged identity to sensitive data or another critical resource, helping defenders identify where to break the path before the initial compromise expands.

Patching remains essential, but it is not the only defensive action available. Microsoft Security helps defenders discover the doors threat actors can see, prioritize the weaknesses they are most likely to exploit, understand where a compromise could lead, and identify opportunities to break attack paths before compromise spreads to critical assets.

References

Sources cited or linked in the submitted draft:

Learn More

For the latest security research from the Microsoft Threat Intelligence community, check out the Microsoft Threat Intelligence Blog.

To get notified about new publications and to join discussions on social media, follow us on LinkedIn, X (formerly Twitter), and Bluesky.

To hear stories and insights from the Microsoft Threat Intelligence community about the ever-evolving threat landscape, listen to the Microsoft Threat Intelligence podcast.

Review our documentation to learn more about our real-time protection capabilities and see how to enable them within your organization.  

The post What exploited vulnerabilities have in common: A data-driven analysis of real-world attacks appeared first on Microsoft Security Blog.

Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Your First Performance Test in Postman: A Quick Guide

1 Share

Your requests and functional tests already live in a Postman collection. Load testing usually means rebuilding them in a second tool, with a second syntax.

You don’t have to. Your first performance test in Postman reuses the collection you already have. By the end of this post, it will run on Postman Cloud runners with a pass/fail threshold your CI job can gate on. You’ll also hand the same test to a coding agent with one prompt.

What does a first performance test need?

Pick a real workflow. Set a virtual user count and a duration. Add pass/fail thresholds for p95 latency and error rate. Then run it from where the load actually needs to come from. Use cloud runners if you need volume, or run locally if you’re just doing a quick check.

Say you have a checkout collection that already passes functional tests. Your first performance test in Postman reuses that same collection. Each virtual user runs the selected requests in order, in a repeating loop, for the duration you set.

How do you run your first performance test in Postman?

  1. Pick a collection that already passes its functional tests.
  2. Open Postman, select the collection, and click Run.
  3. Under Run type, choose Performance.
  4. Set the virtual user count, the duration, and a load profile.
  5. Add a pass/fail threshold, such as p95 latency.
  6. Pick Cloud as the runner and click Run on Cloud. Pick Local instead for a quick check on your own machine.
  7. Watch the real-time timeline as virtual users ramp up. When the run ends, open it in Postman to see where latency rose and which requests slowed first.

How do you run one from the Postman CLI?

The Postman CLI is where performance testing stops being a one-off and starts being something you can wire into CI.

Sign in once:

postman login

Then run a performance test against a collection by ID:

postman performance run <collection-id> --runner postman-cloud --vu-count 500 --duration 30

Add a pass/fail threshold so the run exits non-zero when latency or errors cross a line:

postman performance run <collection-id> \
  --runner postman-cloud \
  --vu-count 500 \
  --duration 30 \
  --pass-if "less_than(p95, 300)"

If p95 latency stays under the threshold, the command exits 0. If it doesn’t, the command exits non-zero and your CI job fails. See the Postman CLI performance testing docs for every option.

Where should the load come from?

The load comes from the machine that starts the run, or from Postman Cloud runners when you add --runner postman-cloud to the same command.

When should you run locally?

Run locally while you’re building the test. A local run generates load from the machine that starts it, your laptop or a CI runner, and local performance testing is unlimited on every plan. Use it to check request order, test scripts and thresholds at low load. Watch your machine’s health, since a busy machine skews results. Move to Postman Cloud runners when you need more load than one machine can produce.

When should you run on Postman Cloud?

Adding --runner postman-cloud to the same command spreads load across multiple machines. You get more concurrent requests than a single laptop or CI runner can produce, and there are no load generator boxes to maintain. Cloud runs keep going if you close your computer, and they persist metrics, assertions, errors, and system metrics in Postman for later analysis and comparison.

The command returns the --pass-if result as its exit code, so set the CI job timeout to at least the test duration. A 30 minute run with a 10 minute job timeout is just a flaky test.

If the API you’re hitting sits behind an IP allowlist, use --runner postman-cloud-static-ip. That gives you fixed IPs in your account’s region (US, or EU for EU Data Residency) that you can allowlist on the target. For a full walkthrough, see how to load test an API behind a firewall.

A few more things worth knowing:

  • Results are recorded in Postman for the workspace, so anyone with access can open the run and see what happened.
  • On cloud runs, --data-file becomes a dataset uploaded to Postman, and secrets move to a Shared Vault secret rather than a local env var.
  • Setup and teardown collections require --runner postman-cloud.
  • Cloud runs and static IPs are available on paid plans.

Can a coding agent do this for me?

Yes. The Postman plugin brings Postman skills into Claude Code, Codex, Cursor, OpenCode, Pi, and other coding agents, and runs tasks through the Postman CLI.

Install it one of these ways:

npx @postman/postman-plugin

That requires Node.js 22 or later.

For Claude Code:

claude plugin install postman@claude-plugins-official

For Cursor:

/add-plugin postman

The performance-testing skill load tests a collection with virtual users, a load profile, and pass/fail thresholds, locally or on Postman Cloud runners.

A prompt I actually use:

Load test the checkout collection in my payments workspace with 300 virtual users for 15 minutes on Postman Cloud. Fail the run if p95 goes above 1 second or error rate goes above 0.5%.

The agent turns that into a postman performance run command with --runner postman-cloud and a --pass-if threshold, runs it through the Postman CLI, and reports the result. The run is recorded in Postman for the workspace.

How do you tell it actually worked?

The exit code is the first signal. Zero means your thresholds held. Non-zero means they didn’t.

Open the recorded run in Postman for the timeline. Look at where p95 bent upward, whether errors clustered at a specific virtual user count, and which requests slowed down first.

What are the honest limits?

A few things to be upfront about. Cloud runs work from the Postman web app and the desktop app. Local runs need the desktop app or the Postman CLI, since the load comes from your own machine. Each virtual user runs the selected requests in order, in a repeating loop, so if you need wildly branching user behavior you’ll want to split that into separate collections. Cloud runs and static IPs are available on paid plans.

FAQ

Can I use my functional test collections for load testing?

Your functional test collections can run as performance tests without a rewrite. Each virtual user runs the selected requests in order, in a repeating loop, and pass/fail thresholds decide the result. Start locally, then use Postman Cloud runners when you need more load than one machine can produce.

How do I wire this into CI?

Add a postman performance run step with --runner postman-cloud, a --vu-count, a --duration, and a --pass-if expression. Set the job timeout to at least the test duration. The exit code gates the pipeline, and the run is recorded in Postman for the workspace.

Do I need a paid plan?

Local performance testing is unlimited on every plan, including Free. Cloud runs and static IPs are available on paid plans, and cloud runs are billed at $0.04 per virtual user hour. A 30-minute run with 100 virtual users uses 50 virtual user hours, or $2. See Postman pricing for current plan details.

Can I reuse my environments and data files in a cloud run?

The same collection you use for functional runs works for performance runs. On cloud runs, --data-file becomes a dataset uploaded to Postman, and any secrets should move from environment variables to a Shared Vault secret so they’re not sitting in a local file.

How many virtual users should I start with?

Start with a small virtual user count and a short duration, and calibrate your thresholds against a healthy run. Once you know what normal looks like, increase the load. When you need more than your machine can produce, add --runner postman-cloud to the same command.

Try it

The full configuration reference is in the performance test configuration docs, and the agent install options are in the Postman plugin overview.

Try Postman now.

Resources

The post Your First Performance Test in Postman: A Quick Guide appeared first on Postman Blog.

Read the whole story
alvinashcraft
7 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

AI agent collisions: Worktrees aren't enough

1 Share

Two developers editing the same service at once is older than Git. One changes an API, the other writes a caller against the old shape. One migration lands, the other assumes the previous schema. The collision may wait until integration, but nobody invented it with coding agents.

Agents compress the timeline. They can start the overlapping work within seconds, finish competing implementations before either human sees a diff, and spend tokens repeatedly “fixing” each other’s changes. A human collision can cost far more than the token bill, sometimes an order of magnitude more once meetings, rework, and a delayed release are counted. That is a scenario, not a universal ratio. The new problem is how quickly both kinds of cost can accumulate while everyone thinks parallel work is progress.

I have already written the case for giving each agent its own worktree. Set that option aside here. Even with separate directories, two agents can change the same behavior, rely on incompatible contracts, or point tests at the same database. We need ways to manage the work itself.

Assign ownership at the level that matters

File ownership is a useful start, but interfaces are the real collision surface. If one agent changes the response shape of GET /orders and another changes the frontend that consumes it, they are collaborating on one contract. Give one task ownership of that contract and sequence the dependent implementation after the new shape is agreed. If parallel work is valuable, freeze the interface first and let both agents build against a shared contract test.

The same rule applies to domain terms, schemas, feature flags, and deployment configuration. A small task register can say: agent A owns the API contract and tests; agent B owns the UI after the contract is approved; agent C performs a read only review. It need not be a complicated scheduler. Its purpose is to stop two plausible plans from quietly disagreeing.

Use short leases on hot areas. A lease says who is editing a shared contract, when they expect to hand it off, and where the result will appear. It is a social protocol with a visible record, not a file lock that magically prevents bad code. If an agent exceeds the lease, review progress and renew or split the task. Do not let an abandoned session hold the architecture hostage all day.

Choose the kind of parallelism deliberately

Some tasks are naturally parallel: read only investigation, documentation of settled behavior, tests for a frozen contract, or independent review. Others are sequential: a migration followed by code that assumes it, a public API change followed by client updates, or two fixes to the same state machine. Forcing the second group into parallel execution creates integration work disguised as speed.

When the work can be split, split by stable boundary. “Agent A handles orders, agent B handles billing” may work if the interface between them is already explicit. “Agent A edits the first half of the file, agent B edits the second half” probably will not. File lines are not architecture. A good boundary gives each agent a testable outcome and few shared assumptions.

Another option is a single writer with several readers. Ask separate agents to investigate edge cases, inspect the current behavior, or critique the plan. Feed those findings to the writer after a human checks them. That gets the benefit of parallel thought without parallel mutation. It is particularly useful in a sensitive area where three implementations would be hard to reconcile.

Isolate the shared things that are not code

Separate branches do nothing for a shared development database, a common staging environment, one cloud account, or the same test tenant. Give agent runs separate databases or schemas where practical, unique test data, distinct ports, and credentials limited to their task. If isolation is not available, schedule the shared resource as a single writer and make its current owner visible.

Generated artifacts need the same care. Two agents can each pass tests locally, then regenerate the same client library from different versions of a schema. A dependency lockfile can change under both tasks. A shared cache can hide an integration failure. Decide which task owns generation, pin the input, and test the combined result after both changes are present.

Detect conflict before merge time

At task start, have each writer declare the files, interfaces, and resources it expects to change. Recheck that declaration when the diff expands. If an agent discovers it needs a boundary owned by another task, it stops and asks. This is a cheap rule, and it prevents a lot of expensive “helpful” edits.

At integration time, do more than resolve text conflicts. Run contract tests and the affected application path against the combined code. Look for two implementations of the same behavior, changed assumptions about defaults, and migrations whose order matters. A clean merge only proves Git could combine the files. It says nothing about whether the resulting application makes sense.

When a collision does occur, preserve both task intents before choosing a fix. Ask what behavior each agent was trying to protect, then select the contract the product actually needs. Blindly asking agents to reconcile each other’s diffs often creates a third implementation that nobody intended.

Keep parallel work cheaper than serial work

A small number of clear assignments, visible ownership, bounded runs, and one integration pass will beat a large crowd of agents whose outputs need arbitration. Count rework and review time alongside token use. If adding another agent makes the queue of conflicting diffs longer, reduce concurrency or stabilize the interface first.

Collisions were always part of software development. Agents make them arrive while the coffee is still hot. The fix is to make the boundaries, contracts, and shared resources explicit before the work starts, then check the integrated behavior before calling it done.

Read the whole story
alvinashcraft
8 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

The October 2026 Brotli Security Update: Who It Affects

1 Share

Show Notes

Hey everyone, and welcome back to The Modern .NET Show; the premier .NET podcast, focusing entirely on the knowledge, tools, and frameworks that all .NET developers should have in their toolbox. I'm your host Jamie Taylor, bringing you conversations with the brightest minds in the .NET ecosystem.

This is a short bonus episode. There's no guest, and it isn't part of Bridging the Gap. It's a security note, and I didn't want it to wait for the next scheduled episode.

Who This Is For

I'll start with who this is for, so that nobody panics. It only matters if your code decompresses Brotli data that comes from outside your application. ASP.NET Core and HttpClient don't do that by default. So if you've never switched it on, and you never call the Brotli APIs yourself, this isn't about your application.

Full Show Notes

The full show notes, including links to some of the things we discussed and a full transcription of this episode, can be found at: https://dotnetcore.show/season-9/the-october-2026-brotli-security-update-who-it-affects/

Useful Links:

Getting in Touch:

Music created by Mono Memory Music, licensed to RJJ Software for use in The Modern .NET Show.

Editing and post-production services for this episode were provided by MB Podcast Services.


Download audio: https://traffic.libsyn.com/clean/secure/thedotnetcorepodcast/S09E04b_Brotli_Security_Update.mp3?dest-id=767916
Read the whole story
alvinashcraft
8 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

LLMs are not superhuman at reading and writing neural network weights

1 Share

A recent paper argues that frontier LLMs can work with neural network weights directly. This seems superhuman, but it isn’t.

The paper shows that GPT-6 Astra can take a small neural network and interact with its weights directly, “well past what we’d expect from humans or conventional algorithms”. Specifically, Astra was able to identify what games a small network1 was trained to play just by looking at the weights, and even tweak the weights itself. The most impressive result is Astra significantly improving a 0.8B Qwen LLM’s ability on mathematics by natively editing its weights. The reason to be excited here is that “superhuman ability to improve language models” is precisely the kind of thing that could cause recursive self-improvement.

I think a smart human ML researcher could perform all of these tasks. Figuring out what game a model was trained to play based on the network sounds impressive until you consider three points:

  1. The input channels of the model directly listen to each 8x8 grid cell
  2. The input channels are labeled (e.g. “agent”, “moving objects”)
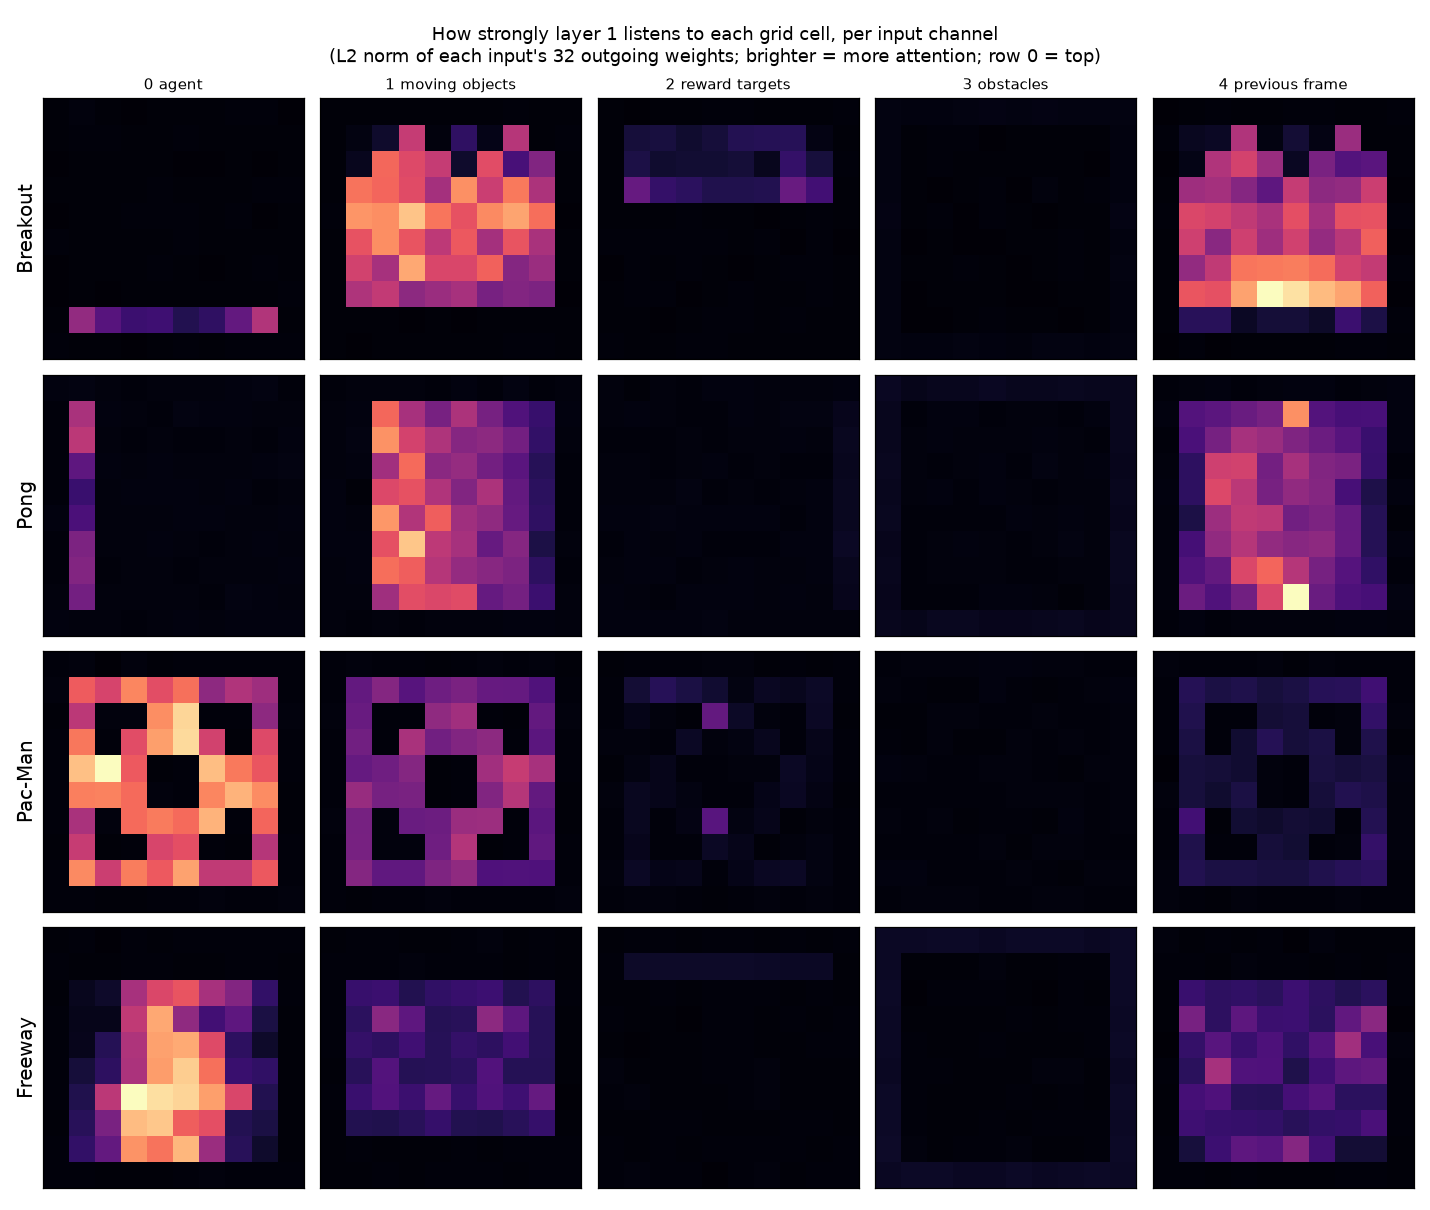
  3. It’s thus relatively trivial to calculate2 which parts of the grid the first layer of weights cares about and why

Here’s that calculation expressed as a heatmap in three lines of Python:

d = np.load("a9f535cc.npz")
W1 = d["actor/dense1/kernel"]
norms = np.linalg.norm(W1.reshape(10,10,5,32).transpose(2,0,1,3), axis=-1)  # 5 x 10 x 10

And here’s the heatmap for each game:

fig1

If someone showed you that heatmap without the game labels, I think you’d be able to immediately identify at least the first three games purely by noticing where the player is (e.g. for Breakout, in a horizontal line at the bottom) and where the moving objects are (e.g. for Pac-Man, in the distinctive Pac-Man maze). It’s neat3 that Astra was able to calculate the norms in its head without executing Python, but not that impressive, and certainly not something that should shock anyone who’s been paying attention.

I’m not going to go through each example4 in the paper, so let’s skip straight to the most impressive one: fixing a 0.8B Qwen model’s ability to do mathematics. 0.8B is a lot of parameters, and “mathematics” is way more complicated than “guess what the game is based on how the player moves”, and editing weights is arguably harder than parsing them. What happened here?

First, note that the Qwen model was not “bad at mathematics” in a pure capabilities sense. It had a specific problem where after 32k tokens it would get stuck in loops, so any mathematical task that needed more than 32k tokens would automatically fail5. If you had a model that looped like this, how would you update the weights to fix it? Personally, I would try steering: I would write some reasoning texts that looped and some reasoning texts that didn’t, calculate the difference between the looping and non-looping residuals, measure how much each weight contributed to that difference, then try manually trimming those top weights. This is basically the Heretic abliteration playbook.

And this is exactly what Astra did! It wrote four pairs of texts, measured6 the weights that contributed to looping, started cutting them down and testing if it worked, and ended up finding a patch that stopped the Qwen model from looping, thus making it able to work on mathematical problems for more than 32k tokens. Again, this is exactly what a competent human researcher could have and would have done.

It’s cool that Astra was able to make direct weight updates. But we shouldn’t think of this like a radically new capability that will change how AI research is done. We should think of this as analogous to the ability of LLMs to emit machine code and tweak compiled binaries: it’s an impressive trick, but the best way to work with binaries is still to write source code and compile it. Likewise, the best way to update the weights of a model is to train it normally. To the extent that intelligent LLMs help with AI research, they will help by improving training, not by magically tweaking model weights directly.


  1. Around 17k weights.

    ↩
  2. By taking the L2 norm of each input across the 32 weights in the first layer.

    ↩
  3. Note that this is superhuman mental mathematics, not superhuman AI research.

    ↩
  4. The most impressive one I’m skipping is hand-writing a neural network from scratch. While cool, if you can express a task as a simple program, we already know it’s possible to express that program as a NN, even by unaugmented humans.

    ↩
  5. All the <32k token problems were solved successfully on the original Qwen model.

    ↩
  6. Unlike with the toy game networks, it had access to Python.

    ↩
Read the whole story
alvinashcraft
22 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

A Front Door for the DBA Team – AgentDBA UI

1 Share
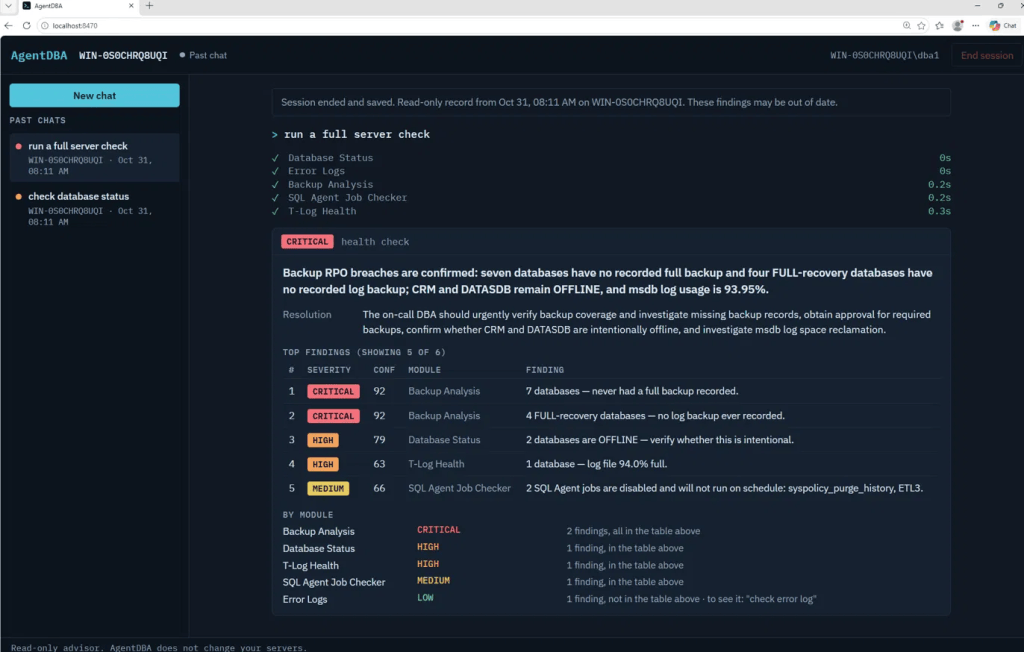
AgentDBA began as a command line. That suits one DBA on one server, but it’s a poor way to give a team a read-only advisor. The obvious fix is a web UI, which is also how you create your first … Continue reading →


Read the whole story
alvinashcraft
22 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories