Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164453 stories
·
33 followers

Threat actors use agentic AI tooling to find and abuse exposed secrets

1 Share

Microsoft Threat Intelligence has observed threat actors using an agentic AI offensive framework to search public GitHub repositories for exposed secrets, including credentials, application credentials, and AI inference-related API keys across multiple applications and cloud services. These threat actors can then use the secrets for further malicious activity against the compromised organization.

Searching open code repositories for exposed credentials, secrets, keys, and other authentication material is a well-documented technique that has historically been limited by the time required for human operators to find code repositories, review the data in the repositories, and leverage authentication material for further action. However, agentic tooling like ARTEX allows threat actors to not only scan for secrets across multiple repositories at a quicker pace but also use the agents to analyze the output and conduct follow-on attacks, cutting down on the need for the threat actor to have hands-on-keyboard interactions throughout the attack chain. In at least one case, Microsoft observed an AI agent advance from scanning GitHub for secrets to exfiltrating data from Azure Key Vault in just five minutes.

Microsoft has also investigated follow-on activity involving the misuse of valid application credentials. As early as October 28, 2026, Microsoft began observing successful service principal sign-ins from the IP address 199.19.77[.]84 involving multiple application IDs across some impacted customers, including cases where a multitenant application credential was compromised at the source (vendor-owned application) and used to access multiple downstream tenants. The threat actor used the compromised credentials for cloud resource discovery, and credential and data exfiltration, including from Azure Key Vaults and Storage Accounts, and abuse of Azure AI services consistent with the activity described above. Additionally, Microsoft observed malicious activity originating from two IP addresses potentially associated with this campaign. We identified malicious operations from 65.87.223[.]26, including indications of vulnerability exploitation by embedded shell commands in a user agent and attempts to obtain App Service authentication tokens. A similar campaign involving the same IPs addressed was also reported by Todyl. Separately, Microsoft observed reconnaissance operations from 157.22.126[.]128 targeting AI workloads deployed by victims on Azure AI services.

Microsoft encourages organizations to scan their code in GitHub and determine where any secrets are present. In addition to removing the secrets from the code base, affected organizations should immediately rotate any exposed keys or credentials. GitHub monitors public repositories by automatically scanning for secrets. In addition to scanning their own repositories, organizations can enable public monitoring through GitHub to detect secrets leaked in secondary public repositories across GitHub. This extends secret scanning beyond the repositories an enterprise owns to follow potential secret exposure across the platform. GitHub Advanced Security for Azure DevOps scans for credentials and other sensitive content in source code. Push protection can also block supported secrets before they’re pushed. Organizations need either GitHub Advanced Security for Azure DevOps or, for organizations using the standalone experience, GitHub Secret Protection for Azure DevOps enabled.

Secrets are exposed in public repositories when code containing the secret is committed to GitHub. Developers might store secrets in configuration files, scripts, or other code to quickly operationalize the OAuth application or avoid configuring more modern authentication flows. Organizations can reduce exposure by protecting workload identities and secrets, enforcing least privilege, safeguarding recovery resources, and enabling relevant Microsoft Defender for Cloud protections. Publicly exposed credentials remain usable until revoked or rotated; removing the original disclosure alone does not remediate the exposure. Microsoft recommends that developers migrate OAuth applications away from secret-based authentication. While storing long-lived application client secrets in code is a common practice, using managed identities for application authentication eliminates the possibility of secret exposure in code, manual processes associated with secret management, and barriers to securely scaling applications.

This activity illustrates an ongoing trend of threat actors accelerating all stages of the attack chain with agentic AI penetration testing frameworks, including ARTEX. As these capabilities evolve, defenders must similarly use AI to investigate and respond across large environments.

From exposed secrets to cloud compromise

Starting in August 2026, Microsoft observed threat actors using an agentic AI offensive framework to submit large volumes of queries to GitHub for secrets. The queries submitted by the AI framework often included the name of a target organization, keywords for secrets, a keyword linked to cloud services, or a keyword linked to another AI service provider. Organizations that find their secrets exposed in public repositories must assume that the exposed secrets and associated applications are compromised.

Follow-on actions

Credential abuse via Entra ID

In one follow-on attack that began as early as October 28, 2026, an agentic framework used valid leaked or stolen application credentials to access Microsoft Entra ID tenants of certain organizations and connected Azure and Microsoft 365 resources. The sign-ins primarily came from two IP addresses: 199.19.77[.]84 and 199.19.77[.]18. The latter IP address is a Tor exit node, which might be associated with unrelated malicious activity, including from unrelated sources. The agent successfully conducted service principal sign-ins on dozens of associated applications across multiple tenants.. Service principals are the identities that applications use to authenticate and give direct, programmatic access to whatever the application is authorized to reach.

The threat actor targeted operations that return credentials, including storage account keys, App Service settings, connection strings and publishing credentials, AI and machine learning (ML) connections and datastores, and Azure Kubernetes Service (AKS) user credentials. The compromised applications subsequently accessed SharePoint and OneDrive in the targeted organization tenants, including file downloads and mailbox-item access. In some tenants, the threat actor sent Microsoft Graph API requests, which were mostly searches to find content of interest. The threat actor enumerated subscriptions, resource groups, permissions, AI model deployments, and service configurations in Azure to map the environment.

Additionally, the threat actor attempted to validate stolen Azure resources, including compromised Azure AI services, as identified using Defender for Cloud’s AI threat protection. Observed activity suggests that the threat actor might have attempted to abuse some of these compromised AI resources to facilitate their broader attack activity.

Figure 1. Tactics, techniques, and procedures (TTPs) observed across the credential abuse attack chain

Cloud API adjustments indicative of adaptive behavior

Additionally in this attack the agent’s operations on a victim’s Azure Resource Manager (ARM) instance originating from 199.19.77[.]84 demonstrated sequences consistent with adaptive troubleshooting, where failed cloud API requests were followed by changes to HTTP methods or API versions and subsequent HTTP 200 responses:

  • A batch of ARM requests attempting to enumerate secret metadata across multiple Azure Key Vault resources returned HTTP 400 (Bad Request). These requests specified a version associated with Key Vault’s data-plane APIs against ARM (control-plane) APIs. Approximately 28 seconds after the first failed response, a batch rerun began against the same vault resource paths using the ARM API version 2023-07-01 and returned HTTP 200.
  • A GET request to enumerate an Azure SQL server’s firewall rules specified an outdated API version and returned HTTP 400. Approximately 60 seconds after that request, a matching GET began using a supported version and subsequently returned HTTP 200. The URL changed only in its api-version parameter.
  • An ARM POST request to an Application Insights query endpoint returned HTTP 400 because an outdated API version was specified. Approximately 80 seconds after the failed request, another POST began against the same endpoint, specifying a supported API version, and subsequently returned HTTP 200.

OAuth application abuse

In multiple cases, Microsoft observed the same agentic AI tools subsequently obtain a token for a single-tenant OAuth application in the same target organization, then use the compromised OAuth application to enumerate other cloud resources within the organization. In some cases, the agents exfiltrated secrets from the organization’s Azure Key Vault. The agents once authenticated have also searched Azure DevOps for secrets. Until the secrets are revoked or rotated, they can allow a threat actor to maintain persistence in the organization, compromise additional identities, or hijack resources. In one observed case, an AI agent progressed from searching for the client secrets in GitHub to exfiltrating data from Azure Key Vault in five minutes.

The agents also used the compromised OAuth application to use the Run Command, which runs scripts in Azure VMs. With access to this functionality on a VM, a threat actor can access unsecured credentials and other stored data, compromise associated workload identities, or run code that provides persistence or lateral movement.

During this activity, the AI agents repeatedly demonstrated a focus on credentials that provide access to AI services, such as API keys for major AI service providers and OAuth applications with access to Foundry Tools (previously known as Azure Cognitive Services). Multiple public reports have documented threat actors using agentic AI tools to compromise credentials for AI services, sometimes to run the same agentic AI workflow.

Mitigating application credential abuse activity

Microsoft recommends the following mitigation steps to contain, detect, and investigate this threat.

Containment

  • Block 199.19.77[.]84/32 as a named location in a Conditional Access policy targeting workload identities, assigned directly to service principals, and in a user-scoped block policy to cover replayed sessions. Note that workload identity policies require Workload ID Premium licensing and cover only single-tenant apps registered in your tenant. Block the exact IP rather than the whole ASN.
  • For affected users, revoke Entra sessions, Azure DevOps PATs and SSH keys.
  • For any affected application, remove all client secrets, certificates and federated credentials, including those added by the threat actor and disable the service principal if needed. Tokens already issued remain valid until expiry.
  • Rotate everything stored in any Key Vault the affected application could read, and any credentials found in accessed documents.
  • MSPs: Review Partner Center access, GDAP relationships, and customer tenants, and notify affected customers per your agreements.

Detection and hunting

  • Review Entra service principal and non-interactive sign-in logs for 199.19.77[.]84 and 199.19.77[.]18 including failed attempts. Sign-in errors AADSTS7000215 (invalid secret) or AADSTS7000222 (expired secret) indicate someone holds a credential for your app; a failure followed by a success is urgent.
  • Review Azure Activity, Key Vault and Storage diagnostics, Entra audit, Azure DevOps audit and Microsoft 365 unified audit logs for the address, including secret reads, blob and file downloads, and changes to apps, permissions or pipelines.
  • In Azure DevOps auditing, review PAT creation and first use, federated service connections, pipeline runs and edits, and unfamiliar user agents. Enable auditing if it is off.
  • Look for behavior as well as the IP: one address authenticating to three or more service principals with mixed success, or one app requesting tokens across Azure Resource Manager, Key Vault, Storage and Graph in a short window. Search as far back as retention allows.

Defending against agentic AI attacks

Threat actors can and do change the source IP address, user agent strings, and other fingerprints left by the agentic AI penetration testing tools they use. This can make identifying and blocking malicious network traffic early difficult for defenders.

Several behavioral signals can help organizations determine that they are being targeted by threat actors using agentic AI. Agentic AI frameworks scanning a target send a wide variety of requests in a brief time and retry variations on the same technique or move on to next-stage actions at machine speed. Agentic AI frameworks use existing penetration testing tools. For example, ARTEX by default uses Nmap, curl, wget, Python HTTP clients, Norma SDK WebFetch, and headless Chromium through Playwright, among others. These tools may send network traffic with distinctive characteristics, such as default user agent strings. While blocking network traffic with these characteristics will not stop an attack by an AI agent, which will quickly change them, identifying them can alert defenders to the activity.

Defensive honeypots, decoys, tarpits, and fake wins can pull autonomous AI attacks away from legitimate targets. Honeypots and decoy surfaces such as Microsoft Sentinel Deception give the agent attractive but worthless targets to pursue. Tarpits consume the agent’s time and budget. Fake wins present convincing evidence that the agent’s objective is complete, which can cause it to stop on a false success. In Microsoft’s testing, these controls helped reduce the attack traffic reaching real assets and produced high-confidence, attribution-quality signal.

Microsoft recommends the following mitigations to reduce the impact of this threat.

  • Protect and continuously assess application credentials and secrets. Avoid storing service principal credentials, storage keys, connection strings, and other secrets in source code, configuration files, public repositories, issues, or other locations where they might be inadvertently exposed. To find credentials in source code, consider using tools like GitHub Advanced Security or other OWASP source code analysis tools.
  • Rotate compromised or exposed credentials immediately and establish credential lifecycle practices. Treat credentials that have been publicly exposed as compromised, even if the original location has subsequently been edited or deleted. Removing the content does not invalidate the credential or eliminate copies retained in edit history, caches, archives, logs, or other systems. Immediately revoke or rotate the affected credentials and investigate their historical use. Where supported, organizations should favor mechanisms that reduce reliance on long-lived credentials. Learn more about protecting secrets with Defender for Cloud.
  • Enable appropriate Microsoft Defender for Cloud plans for critical Azure workloads. Consider enabling workload protections relevant to the resources in your environment, including Defender for Resource Manager, Defender for Storage, Defender for Key Vault, Defender for App Service, and Defender for Databases. Learn more in the Microsoft Defender for Cloud overview.
  • Apply least privilege to service principals and other workload identities. Review the Azure role-based access control (RBAC) permissions assigned to service principals and restrict their privileges to the resources and operations required by their applications. Learn more about best practices for Azure RBAC.
  • Protect backup and recovery infrastructure as part of resilience. Restrict access to backup and recovery resources and closely monitor attempts to modify or remove their protection controls. Learn more about Azure Backup security best practices.

Hardening OAuth applications against compromise involves managing the permissions of the applications in your organization and securing application secrets. To triage applications in your environment, enforce security policies with new applications as they are created, and address existing applications over time beginning with the most recent ones.

Microsoft detections

Microsoft Defender and Microsoft Sentinel customers can refer to the list of applicable detections below. Microsoft Defender coordinates detection, prevention, investigation, and response across endpoints, identities, email, and apps to provide integrated protection against attacks like the threat discussed in this blog.

Tactic Observed activity Microsoft Defender and Sentinel coverage
Initial accessMultiple identity-protection alerts identified authentication attempts from anonymized or high-risk infrastructure. This pattern can indicate attempted access through proxy, VPN, or previously reported malicious network sources.Microsoft Entra ID Protection
– Anonymous IP address
Initial accessAttack-analysis detections identified OAuth application activity consistent with compromise. This type of detection is useful when evaluating whether an app identity, rather than only a user identity, may have been abused.Microsoft Defender XDR
– Potentially compromised OAuth application identified through attack activity analysis
Initial access, DiscoveryUnattributed network indicators related to ARTEX use are flagged by Microsoft Threat Intelligence research and surfaced across multiple alerts. Suspected ARTEX use can include activity beyond the GitHub repository scanning activity discussed in this blog.Microsoft Sentinel
– Abnormal Deny Rate for Source IP
– Abnormal Port to Protocol
– Inbound Network Attack detected
– Malformed user agent
– Password spray attack against Azure AD application

Microsoft Defender XDR
– Account compromised following a password-spray attack
– Anomalous OAuth device code authentication activity
– Multiple Service Principal Sign-ins from Single IP
– Graph API activity from a Microsoft threat intelligence IP address

Microsoft Defender for Cloud Apps
– Activities from suspicious user agents
– Multiple failed login attempts
– Multiple failed user log on attempts to an app
– OAuth application activity from an uncommonly visited ISP
– Suspicious OAuth app registration

Microsoft Defender for Cloud
– Key vault unusual access denied – user/application accessing high volume of denied key vaults
– Access from an unusual location to a sensitive blob container
– Azure Resource Manager operation from suspicious IP address

Microsoft Entra ID Protection
– Atypical travelMalicious IP addressPassword Spray
– Verified threat actor IP
Credential accessIdentity-protection detections observed password spray behavior. This indicates repeated authentication attempts across accounts or tenants using a common source pattern.Microsoft Entra ID Protection
– Password spray

Microsoft Defender for Identity
– Suspicious service principal sign-in following credential addition
Credential accessAzure Key Vault accessMicrosoft Defender for Cloud (Defender for Key Vault)
– Unusual operation pattern in a key vault
– High volume of operations in a key vault
– Unusual application accessed a key vault
– Suspicious secret listing and query in a key vault
– Unusual access to the key vault from a suspicious IP (Non-Microsoft or External)
Command and controlSuspicious Microsoft Graph API usage was observed from campaign infrastructure. The activity involved Graph requests that can support discovery, collection, or follow-on cloud operations. Microsoft Defender for Identity
– Suspicious Entra Graph API query observed

Advanced hunting queries

The following hunting queries are related to the October 28 Entra ID service principal sign-in activity.

Find successful and failed application sign-ins from the suspicious IP addresses

let startTime = datetime(2026-10-28T00:00:00Z);
let endTime = now();
EntraIdSpnSignInEvents
| where Timestamp between (startTime .. endTime)
| where IPAddress in ("199.19.77.84")
| project Timestamp, TenantId, Application, ApplicationId, ServicePrincipalName, ServicePrincipalId, ResourceDisplayName, ResourceId, ResourceTenantId, IPAddress, ErrorCode, UserAgent, CorrelationId, RequestId
| order by Timestamp asc

Find Microsoft Graph API requests from the two IP addresses, including searches and response status

let startTime = datetime(2026-10-28T00:00:00Z);
let endTime = now();
GraphAPIAuditEvents
| where Timestamp between (startTime .. endTime)
| where IpAddress in ("199.19.77.84")
| project Timestamp, TenantId, ApplicationId, ServicePrincipalId, AccountObjectId, IpAddress,
          RequestMethod, RequestUri, ResponseStatusCode, ResponseSize, Scopes, EntityType,
          TargetWorkload, UniqueTokenIdentifier, ClientRequestId, OperationId, RequestId
| order by Timestamp asc

Find available Microsoft 365 and Microsoft Azure cloud activity details from the suspicious IP addresses

let startTime = datetime(2026-10-28T00:00:00Z);
let endTime = now();
CloudAppEvents
| where Timestamp between (startTime .. endTime)
| where IPAddress in ("199.19.77.84")
| project Timestamp, Application, CloudAppId = ApplicationId, ActionType, ActivityType,
          AccountType, AccountDisplayName, AccountId, AccountObjectId, IPAddress, UserAgent,
          ObjectName, ObjectType, ObjectId, ActivityObjects, ReportId, RawEventData
| order by Timestamp asc

CloudAuditEvents table to identify suspicious controlplane operations

CloudAuditEvents
| where IPAddress has_any  ('199.19.77.84','65.87.223.26')

CloudStorageEvents table to identify possible exfiltration from Storage Accounts.

CloudStorageAggregatedEvents
| where IPAddress in   ('199.19.77.84','65.87.223.26')
| where SuccessfulOperationsCount > 0   

Microsoft Security Copilot

Microsoft Security Copilot is embedded in Microsoft Defender and provides security teams with AI-powered capabilities to summarize incidents, analyze files and scripts, summarize identities, use guided responses, and generate device summaries, hunting queries, and incident reports.

Customers can also deploy AI agents, including the following Microsoft Security Copilot agents, to perform security tasks efficiently:

Security Copilot is also available as a standalone experience where customers can perform specific security-related tasks, such as incident investigation, user analysis, and vulnerability impact assessment. In addition, Security Copilot offers developer scenarios that allow customers to build, test, publish, and integrate AI agents and plugins to meet unique security needs.

Threat intelligence reports

Microsoft Defender XDR customers can use threat analytics reports in the Defender portal (requires license for at least one Defender XDR product) to get the most up-to-date information about the activity and techniques discussed in this blog. These reports provide intelligence, protection information, and recommended actions to prevent, mitigate, or respond to associated threats found in customer environments.

Microsoft Security Copilot customers can also use the Microsoft Security Copilot integration in Microsoft Defender Threat Intelligence, either in the Security Copilot standalone portal or in the embedded experience in the Microsoft Defender portal to get more information about this threat.

Learn more

For the latest security research from the Microsoft Threat Intelligence community, check out the Microsoft Threat Intelligence Blog.

To get notified about new publications and to join discussions on social media, follow us on LinkedIn, X (formerly Twitter), and Bluesky.

To hear stories and insights from the Microsoft Threat Intelligence community about the ever-evolving threat landscape, listen to the Microsoft Threat Intelligence podcast.

The post Threat actors use agentic AI tooling to find and abuse exposed secrets appeared first on Microsoft Security Blog.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Docker Sandboxes vs. Containers: Choosing the Right Isolation for AI Agents

1 Share

If you’ve used Docker for a while, “Docker Sandboxes” might read as “a container with an AI agent inside.” Containers have been the unit of nearly everything Docker ships for over a decade, and a sandbox might sound like one more way to package a workload.

They’re actually different technologies. A container is an isolated process that shares the host kernel with everything else on the machine. Docker Sandboxes are dedicated microVMs with their own Linux kernel, filesystem, network, and Docker Engine, built for autonomous coding agents that need a whole development machine to work in. A sandbox can run containers, which is part of why the two are easy to conflate.

In his WeAreDevelopers keynote, Docker President Mark Cavage said containers are doing exactly the job they were designed to do, but we’re asking them to do a different job.

Containers were built to isolate applications, which they still do well. But a coding agent is an actor: it makes decisions and operates on your systems the way a developer uses a laptop. It clones repositories, installs packages, starts databases, builds images, and tries again for hours. It can also act on instructions from files, web pages, and tool output that nobody reviewed.

That different job needs a different boundary, and where that boundary sits determines how far an agent’s mistake can travel. This post covers how Docker Sandboxes and containers isolate workloads, what changes beyond the kernel, what a sandbox costs you in setup, and how to pick.

Key takeaways

  • A container is an isolated process sharing the host kernel. Docker Sandboxes are microVMs with their own kernel, filesystem, network, and Docker Engine.
  • Containers stay the right choice for packaged applications, CI jobs, and short-lived execution.
  • Docker Sandboxes fit autonomous agents that need sudo, a private Docker Engine, long-lived state, and host-enforced network and credential controls.
  • Containers can be part of an agent’s containment, and a sandbox can run them. Sandbox the agent, containerize the application it works on.

What is a container?

A container is a process, or a group of processes, running on the host with its own view of the filesystem, process tree, and network. Linux namespaces provide that view, and cgroups meter CPU, memory, and I/O. Every container on the machine also shares the host kernel, which is why containers start quickly, pack densely, and carry so little overhead.

Diagram of an agent running in a Linux container. The agent process, your app, and your database each run in their own container, all sharing one host kernel. A container escape lands on the host kernel, alongside every other container, with your files, credentials, network, and other processes beneath it.

This design has more than a decade of tooling behind it. Compose, Kubernetes, OCI registries, image scanners, and nearly every CI system treat the container as the common primitive. If the job is to run a service, execute a code snippet, process one request, or run an evaluation and disappear, a container is usually the obvious pick, and it will stay that way.

ⓘ Containers share one kernel, even inside a VM. On macOS and Windows, Docker Desktop runs your Linux containers inside a virtual machine, which keeps them off your host operating system. Every container in that VM still shares its single kernel, so the isolation between one container and the next is unchanged.

What are Docker Sandboxes?

Docker Sandboxes run an AI coding agent inside a microVM that has its own Linux kernel, its own filesystem and network stack, and a private Docker Engine. The agent gets sudo inside the isolated environment. It can install packages, run services, build images, and bring up an entire Compose application without reaching the host Docker daemon, the host filesystem outside its workspace, or other sandboxes on the same machine.

Diagram of an agent in a Docker Sandbox. The agent process, a private Docker Engine, and your app and database containers all run inside a microVM with its own guest kernel. Another agent runs in a separate microVM. A native hypervisor boundary sits between the microVMs and your machine, so a container escape lands in a disposable microVM, not on the host.

Getting one running takes a single command, using sbx, the Docker Sandboxes CLI:

sbx run claude

That creates the sandbox and starts the agent. You can stop it, resume it, and come back to everything the agent installed until you remove the sandbox.

Why do coding agents need a full machine?

Coding agents need a full machine because their sessions build up state over hours and they act on unvetted instructions. A container is built for a process with a known set of dependencies, and an agent’s work doesn’t fit that shape. 

An agent needs the authority of a whole machine and a boundary designed for one. The capabilities that make an agent useful, such as running code, installing packages, and reaching the network, are the same ones that wear at the walls around it. An agent probes the edges of its environment because the job requires changing that environment.

Agents accumulate state for hours

A coding agent’s session looks like a developer’s afternoon. It clones a repository, installs packages, starts PostgreSQL, runs migrations, builds images, launches the app with Compose, reads the logs, changes the code, and tries again. That loop can run for hours, and each step depends on what the previous one left behind. 

A container is designed to be rebuilt from an image and a few explicit volumes. The packages, databases, and build output an agent creates outside those volumes are lost when the container is recreated. That’s less than ideal for a session where every step builds on the last.

Box by ASCII describes this distinction neatly: “It uses the sandbox the way a developer uses a laptop, so the sandbox has to behave like one.”

Agents act on untrusted instructions

The program deciding which command to run is probabilistic, and it can read instructions from many places at once, including source files, issue descriptions, web pages, package metadata, and MCP tool output. Some of that input is untrusted, and a malicious instruction planted in a README or a tool description can steer the agent on purpose. The code it generates may also be wrong or actively hostile. 

We’ve already seen an agent that deleted a production database after misreading its task. Once the agent is running unattended in YOLO mode, there’s no permission prompt left to catch it. A workload with that much authority and that little predictability needs a boundary designed for it.

Put these facts together and you get the reason why we built Docker Sandboxes. An autonomous coding agent needs machine-shaped capabilities without access to everything on the developer’s machine, which comes down to four things:

  1. Containment: a boundary the model can’t rewrite
  2. Control: observability into what the agent is doing and the ability to stop it
  3. Choice: the freedom to swap agents, models, and tools without rebuilding the setup
  4. Capacity: a setup other developers can reproduce and scale past one machine. 

The next sections show what each looks like, starting with containment.

Containment: How isolation differs between containers and Docker Sandboxes

The short version is that a container’s boundary is the host kernel it shares, and Docker Sandboxes have a hypervisor boundary around a kernel the agent has to itself. That one difference decides how far a compromise can travel, and it also settles the awkward question of how an agent could get access to Docker.

This is where containers and containment part ways. A container can be part of containment, and often should be, but containment covers the whole environment around the agent. It starts with a boundary the model can’t rewrite, which is why Docker uses a microVM with its own kernel for autonomous agents.

Shared kernel vs. dedicated kernel

A container’s boundary is enforced by the kernel it shares, so escaping it requires a kernel exploit or a side-channel attack. Those aren’t everyday finds. Past that bar, though, sits the entire host kernel, every other process on the machine, and any credentials mounted alongside them.

ⓘ This scenario is specific to Linux environments. On Docker Desktop (macOS and Windows), the shared kernel is the Docker Desktop VM’s kernel, not the host kernel, so an escape would land in that VM rather than the operating system.

Docker Sandboxes give the agent its own kernel behind a hypervisor boundary. If an agent escapes its container, it lands in a disposable microVM, and the host stays out of reach. And you can delete the sandbox and start another. Each agent also gets its own microVM, so two agents running on the same machine can’t reach each other’s sandboxes either. However, the agent can still reach whatever you chose to share with it, including the workspace, allowed network destinations, MCP servers, and skills.

The Docker socket problem

Mounting /var/run/docker.sock into a container is the long-standing way to give it Docker access, and it turns up in Compose setups, CI pipelines, and observability tools. It also hands the container control of the host Docker daemon, which Docker limits to trusted users because it can mount host paths and start privileged containers.

An agent doesn’t need an exploit to use that. Put one in a container started with the socket mounted, and it probes its surroundings, works out that it’s in a container, and finds the hole in the configuration. In Mark’s keynote demo, that was enough for an agent to reach a secrets file on the host with no zero-day involved.

The socket is one hole among several, and agents find them because probing their environment is part of the work. Docker-in-Docker, mounted credentials, and broad host mounts are others. Containers were built to isolate an application that behaves as configured. But an agent keeps testing that configuration, so if there’s a gap, it’s likely to find it.

Where the microVM boundary goes

Docker Sandboxes put the missing boundary in the right place. The agent talks to a private Docker Engine inside the guest. It can build images, run Testcontainers, and start a whole Compose stack, and the host daemon and its socket stay outside the microVM the entire time. Containers keep doing what they do best, inside a boundary the agent can’t widen. 

Let’s say you ask an agent running inside Docker Sandboxes to find a secrets file on the host. It’ll find a Docker socket, try to use it to mount host paths and start privileged containers, but won’t reach the host. A microVM can give it a much stronger trust boundary than a container. The architecture behind Docker Sandboxes goes deeper on why a microVM was the right shape for this.

Control: What you can see and stop beyond the kernel

Containment draws the boundary. Control is what you can see and stop inside it: what the agent is allowed to reach, and the ability to block it when it heads somewhere it shouldn’t. In a sandbox, those controls are enforced by the host, outside the agent’s reach, so the agent can’t switch them off or reason its way around them. Outbound traffic, credentials, and organization-wide policy all work this way. Control also means knowing what the agent can still touch, because a microVM can’t hide what you choose to share with it.

Agent in a standard container

Agent in Docker Sandboxes

Kernel

Shares the host kernel

Runs its own Linux kernel in a microVM

Docker

Needs the host socket or a nested daemon

Uses a private Docker Engine inside the microVM

Workspace

Sees the host paths you mount

Uses a direct read-write mount or an in-VM private clone

Network

Uses the container network and whatever controls its operator supplies

Sends outbound traffic through a host proxy with deny-by-default policy

Credentials

Commonly receives environment variables, files, or mounted sockets

Uses host-side credential injection for supported HTTP services

State

Usually rebuilt from an image and explicit volumes

Keeps packages, images, containers, and agent history until sbx rm

Orchestration

Fits Compose, Kubernetes, and most CI systems

Uses the sbx lifecycle and experimental environment files

The host enforces the controls

These controls hold because they run outside the agent process. A rule the agent can reach is a rule it can work around, so the rules that matter live on the host. Outbound traffic goes through a host-side proxy with a deny-by-default policy, which means a destination the agent wants stays blocked until someone adds it to the list. Credentials follow the same logic. For supported HTTP services, the proxy injects them into outbound requests, so the agent can use a credential without the raw value ever entering the VM. 

When one developer’s setup needs to become a team standard, Docker AI Governance can move network, filesystem, and MCP policy into organization-wide controls.

What the agent can still reach

A microVM can’t hide what you choose to share with it, so the shared parts deserve the most attention. 

The workspace is the largest of them. It’s mounted read-write by default, so the agent can edit or delete files in your project. Clone mode gives the agent a private in-VM clone to work in, which protects the host working tree, though the original repository stays readable inside the sandbox. 

MCP servers and skills are shared too. A local stdio MCP server runs on the host and shared agent skills use a host-side store, so the agent’s reach extends to both. 

So whichever mode you pick, be sure to read the diff before you run modified code.

Choice and capacity: What Docker Sandboxes cost you in setup

Docker Sandboxes may cost some configuration and a supported hypervisor. But Kits and environment files account for the configuration, and they’re also where you get choice over agents and tools and the capacity to reproduce a setup across a team. 

Kits and environment files

Kits make setup repeatable by packaging tools, files, commands, network rules, credentials, and agent instructions. They’re published for different agents, tools, and IDEs, so you can swap what runs inside the sandbox without rebuilding the environment around it. An sbxenv.yaml file records one project’s sandbox configuration, and committing it to the repo lets a teammate recreate the same sandbox with one command, so every developer works from the same setup. (Kits are in early access and environment files are experimental, so plan for changes to both.)

The host-enforced controls take some setup too. Network policy requires someone to decide which destinations belong in the workflow, credential mediation adds service bindings and approved domains, and clone mode adds a fetch step before changes land in the host repository.

Hypervisor and resource requirements

Running a sandbox takes more from your machine than running a container does. It needs a supported hypervisor, which today means Apple silicon on macOS 14 or later, Windows Hypervisor Platform, or KVM on supported Ubuntu systems, and running inside another VM requires nested virtualization. The separate kernel and Docker Engine also consume more memory and disk than one additional container would.

If your machine is the limiting factor, Docker Cloud Sandboxes run the same microVM isolation on Docker-managed compute, and one command moves a sandbox between your laptop and the cloud. Local and cloud sandboxes keep separate secrets and network policies.

How do you choose between a container and Docker Sandboxes?

Choose a container when you control the code and its dependencies, and choose Docker Sandboxes when the workload generates or fetches code at runtime and needs its own boundary.

Reach for a container when

Reach for Docker Sandboxes when

You control the code and its dependencies

The workload generates or fetches code at runtime

Execution is short-lived and rebuilt from an image

The session accumulates state for hours

The workload doesn’t need Docker, or runs in CI that already provides it

The workload needs its own Docker Engine with no path to the host socket

You want maximum density and a fit with Compose or Kubernetes

You need host-enforced network and credential policy the workload can’t switch off

The kernel boundary is enough for the code you’re running

You want a hypervisor between the workload and your kernel

If any of the signals below apply to your project, you should start with Docker Sandboxes. 

  1. The agent runs unattended, or its permission prompts are auto-approved
  2. The agent needs to build images or run Compose or Testcontainers
  3. The agent reads input you didn’t write, such as issues, web pages, package metadata, or MCP output
  4. The agent requires API keys you don’t want inside its environment
  5. The session lasts longer than a single task

Start with sbx run claude. Add clone mode, kits, network policy, credential mediation, and organization governance as your workflow grows.

Sandbox the agent, containerize the application

Containers aren’t going anywhere. For services, CI jobs, and anything you package to ship, they draw the right boundary, and the ecosystem around them is the reason they’ll keep doing that work. A coding agent needs more than a container to be trusted with real work. It needs containment, meaning a boundary the model can’t rewrite, controls it can’t reason its way around, and the freedom to choose its tools and scale its setup. 

Docker Sandboxes provide that containment in a microVM that can still run your containers. The boundary is also what lets the agent move faster. With it in place, you can stop approving every command and let the agent get to work.

You can have a sandbox running with one command. Start with sbx run claude and the Docker Sandboxes quickstart. Once one developer’s setup needs to become a team standard, Docker AI Governance extends the same controls across your organization.

Frequently asked questions

Are Docker Sandboxes just containers?

No. A container is an isolated process that shares the host kernel. Docker Sandboxes are microVMs with their own kernel, filesystem, network, and Docker Engine. A sandbox can run containers, which is why the two are easy to confuse.

Can I run Docker inside Docker Sandboxes?

Yes. Each sandbox has a private Docker Engine, so the agent can build images, run Testcontainers, and start Compose applications without the host socket or Docker-in-Docker.

Do Docker Sandboxes replace containers?

No. Containers remain the right tool for packaged applications, CI jobs, and short-lived execution. Sandboxes add a stronger boundary for autonomous agents, and containers keep running inside them.

What’s the difference between a container and containment?

A container isolates a workload. Containment involves the whole environment around an agent: the boundary it runs in, what it can reach, which tools it uses, and how you reproduce it. A container can be part of containment, and Docker Sandboxes add the microVM boundary an autonomous agent needs.

What does an AI agent need from its environment?

Docker describes four requirements: containment (a boundary the model can’t rewrite), control (visibility into what the agent is doing and the ability to stop it), choice (swapping models, agents, and tools without rebuilding), and capacity (a setup other developers can reproduce and scale past one machine).

What do I need to run Docker Sandboxes?

A supported hypervisor, which means Apple silicon on macOS 14 or later, Windows Hypervisor Platform, or KVM on supported Ubuntu systems. Running inside another VM requires nested virtualization.

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

9 New Unity Assets Worth Checking Out! (Oct 24–Nov 3)

1 Share
From: Stacey Haffner
Views: 1

Here are 9 new Unity Asset Store releases from October 24 through November 5 that I thought were worth knowing about. This roundup includes some pretty interesting tools for level design, faster workflows, playtesting, sound design, and more.

Resources
1. Anvil CSG: https://af.unity.com/ot/JplnJXe/
2. tsitski ProBuilder Tools: https://af.unity.com/ot/q5N4y4e/
3. Collidify: https://af.unity.com/ot/kVbE43W/
4. 2N Lightning Reload: https://af.unity.com/ot/WJDgbgk/
5. Ultimate Inspector Fields: https://af.unity.com/ot/Nd3PMVL/
6. Heatmap Analytics: https://af.unity.com/ot/DRoqYeR/
7. Earth Spells VFX Pack: https://af.unity.com/ot/jWgbV30/
8. POLYGON Horror Movie Set: https://af.unity.com/ot/9m9oMJO/
9. Sound Finder: https://af.unity.com/ot/OqaNojW/

Note: These are affiliate links, which means if you purchase through them, I earn a small commission at no extra cost to you. That includes purchases of anything else, not just what I've linked. It helps me fund making new tutorials.

Timestamps

00:00 - Intro
00:25 - Anvil CSG
00:52 - Probuilder
01:19 - Collidify
01:52 - Interlude
02:04 - 2N Lightning Reload
02:27 - Ultimate Inspector Fields
02:57 - Earthspells VFX Pack
03:47 - POLYGON Horror Movie Set
04:20 - Sound Finder
04:48 - Wrap

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

AI Is Giving Engineering Teams False Confidence | Jay Paulson

1 Share
From: Hangar DX podcast
Duration: 32:07
Views: 5

“AI is producing more than we could ever imagine before, but we’re still defining confidence in the same old way that we’ve been doing it for decades. And it’s causing a lot of problems.”

On HangarDX, Ankit Jain talks with Jay Paulson, Director of Engineering at Symetra, about engineering confidence in the AI era and why the business still sees engineering as a black box.

They talk about:

Why AI raised expectations while the confidence behind delivery is still based on belief, not evidence, and
Why a team told it’s going too fast should slow down, and what to do with the extra capacity, from juniors writing code by hand to giving people time back, and
How asking for delivery evidence and forward visibility changes the conversation with leadership

Chapters

00:00 Introduction to the episode and guest
01:24 Jay Paulson's background and focus on engineering confidence
03:25 What is engineering confidence? Definitions and examples
05:01 The role of metrics and belief in confidence
06:20 AI's influence on productivity and confidence
08:48 Grounded confidence versus belief-based confidence
11:15 When does engineering confidence meet expectations?
14:52 The importance of evidence in planning and estimation
17:40 The pressure to do more with AI and its effects
20:23 The idea of slowing down to improve quality
26:52 The risks of belief-based planning and confidence
28:36 Building more grounded confidence through evidence
32:18 Using visibility to manage delivery and expectations

Replace code reviews with verified intent
AI writes code faster than humans can review it. Aviator Verify provides compliance-grade verification through spec-driven development. Ship faster with complete audit trails. https://verify.aviator.co/

📫 Sign up for our email list for more podcasts, articles, events, and other updates: https://www.aviator.co/podcast

✏️ Subscribe for more videos: @Aviator-Co

🙌 Join a curated community of senior engineers and engineering leaders focused on developer experience and solving productivity challenges at scale! Check out our upcoming off-the-record online sessions where vetted, experienced professionals can exchange ideas and share hard-earned wisdom: https://dx.community/

Read the whole story
alvinashcraft
5 hours ago
reply
Pennsylvania, USA
Share this story
Delete

A day in the life building a Critter Stack release w/ AI

1 Share

From RollingStone.com

When I start work in the mornings, but after feeding the family dog and well before my wife and our kids get up, I have a little Claude routine to give me a summary of activity across the JasperFx GitHub organization (home of the Critter Stack tools plus some private stuff for JasperFx Software). Today I was greeted with a pretty good backlog of open pull requests and a few issues from the community plus a significant request from a big client to address some memory pressure issues in their extremely high volume system. Long story short, there’s more than enough work to justify a round of Nuget releases today.

I’m also trying to clear the decks of any open issues or pull requests before we start work on new major versions of all the tools in the .NET 11 wave starting when Microsoft releases that on November 10th.

As a kind of fun exercise, I thought I’d try to keep a running diary today of how I went about that to show — clumsy as it might be — how I’m trying to manage AI agents to work through all of that across 6-7 different repositories and maybe about a 100 different Nuget packages today.

Dogfooding Stoat

First off, I wanted to do more dogfooding today of Stoat, the Critter Stack’s work-in-progress agent orchestration and durable agentic memory tool. With a single supervising agent session in Claude Desktop, I talked through a plan for today that included the issues I wanted to address, the pull requests that I would be trying to review and merge, and the steps for publishing and consuming Nugets between the different Critter Stack tools.

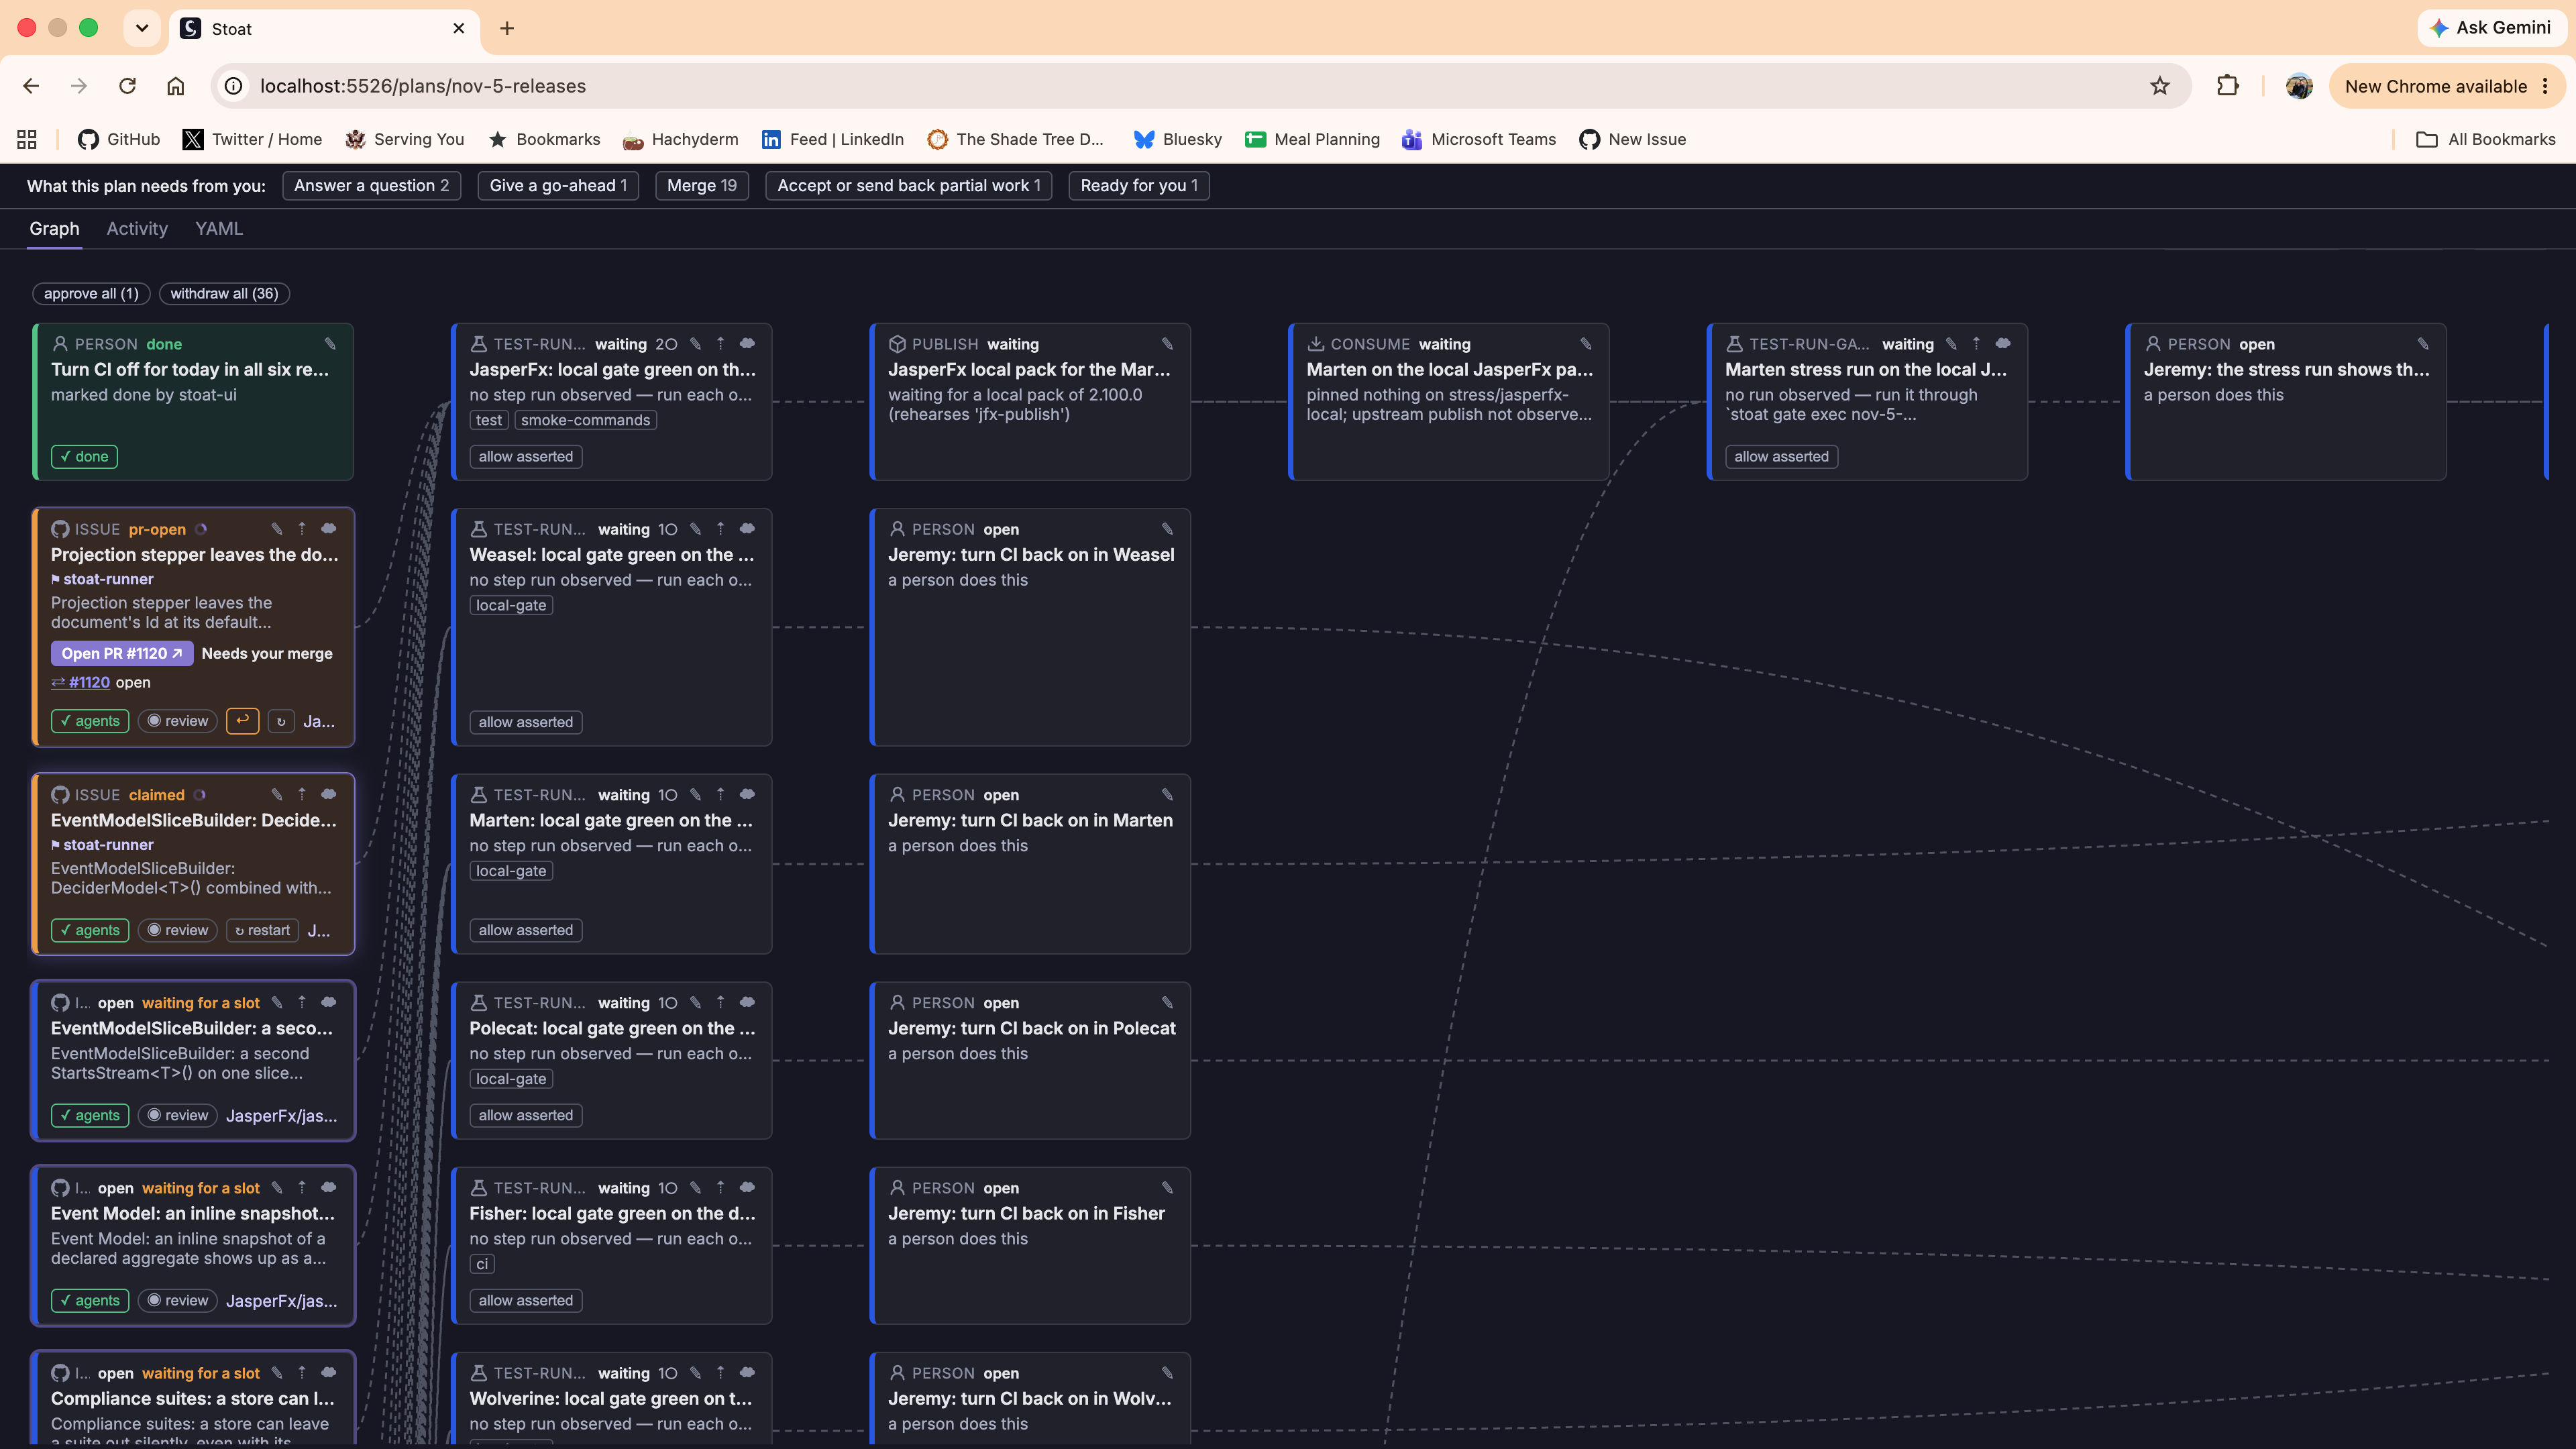
Below is a screen shot of the Stoat “plan” at about 8:45 in my morning with a couple agents already working:

There’s a mix of GitHub issues that I mostly trust an agent to “just” deal with, but for today I’m going with “let me review and merge all pull requests.” A big chunk of the plan though is for me to be reviewing existing pull requests separately. The Nuget publishing is part of the Stoat plan, and that’s gated by my manual review work and part of the plan. Stoat is able to launch agents on approved issues though.

There’s a bazillion of these agent orchestration tools out there and I’m not yet convinced that Stoat is hugely worthwhile outside of my own workflow, but we’ll see. It is part of the Critter Stack strategy for AI assisted development with Event Modeling and Spec Driven Development though.

About Pull Requests and CI via GitHub Actions

I’m still using a very GitHub-centric workflow, and I prefer to keep as much information as possible inside of GitHub issues or pull requests with Markdown. Likewise, we use pull requests as primarily a tracking tool for internal work and certainly for external contributions, but now it’s time to talk about compromises.

I’ve very aggressively used AI agents to improve and expand the number of test suites we have running in CI *on every pull request and push to main* like we’ve done for over a decade. At this point Wolverine has 46 separate CI actions and Marten has 30 some. Because of the way every yokel like me has jacked up their CI checks and the rate of commits with AI tools, GitHub Actions now has a pretty long queue wait for runners and I can easily run into CI taking up to 2 hours plus for a single Wolverine pull request at busier times of day.

So here’s the compromise. I’m going to disable GitHub Actions altogether for the Critter Stack for just today while I’m working on the plan, then turn on CI just in time to act as a quality gate prior to making any Nuget release.

I’ve since enabled the CI runners again for everything but Wolverine that hasn’t quite finished yet.

Some thoughts and notes about this:

  • It’s required some effort to create “CommitGate / PushGate” scripts that try to optimize automated test suite execution for local execution as opposed to the CI scripts that depend on having a separate GitHub action for basically everything
  • There are some new services popping up to be a paid subscription to take the place of GitHub Actions for faster CI, and I’m tempted to get that for JasperFx
  • It’s making me think a lot about risk mitigation in pushes and releases. It’s also leading to people getting more disciplined and parsimonious about what test runs apply to what changes rather than just letting CI do a big bang test run on every single change

Stoat got some enhancements today to understand when CI is turned on (in addition to its item by item capability to auto-merge pull requests when CI goes green) and to do more “local gating.” The next thing I need to add to Stoat is to understand when “local gating” is heavyweight so that it limits the active work to only one heavyweight activity at a time. For example, if the box is running all of the Wolverine tests (there’s quite a bit of parallelism in our new local gating), that’s it, that’s all the box can be doing because of the resource utilization on the box.

First couple hiccups with Stoat

The UI is gawdawful. Fundamental things do not change with AI, quality in any software tool still requires feedback and iteration. And also, I’m still a rank amateur at UI/UX. Fear not, other people with better UI/UX skills will soon be helping with Stoat. I’m making a lot of notes today as I go on this based on dogfooding today.

The context switching burns

I’ve talked to several people who say the same thing. I’ll spin up several agents, then duck and weave going back and forth to answer questions to each. It’s even worse when you add in trying to sequentially review several pull requests in a row that are all dealing with different areas of functionality. Trying to make complicated decisions way too fast is definitely not part of our new AI world that I especially enjoy.

10:06 AM

GitHub seems to be having a lot of errors right now. Ugh.

Okay, it got better.

Big time scalability issue with Marten

A JasperFx client has been telling me for a week that they’re seeing memory utilization problems in production during rollouts. They were finally able to give us some pretty concrete reports of where the memory usage was, so that launched an investigation into a couple different ways of alleviating that.

But, addressing that memory usage meant that I needed to do some significant stress testing to try to simulate the problems and measure the before and after impact of our theoretical changes. I had to modify Stoat a little bit so that it could “drain” all ongoing work before doing the heavy stress testing. I had already invested in teaching it how to do local Nuget packing from upstream projects to combine build products with downstream code without having to deal with the friction of formally publishing alpha Nugets to Nuget.org.

Cross repository development always comes at a cost and you should probably always be a bit cautious about that. But that’s where I’m at with the Critter Stack, so here we go.

If you’re curious, that stress testing and memory optimization led to this pull request today.

I think this will come up a couple more times today, but a big issue with agentic development is respecting resource usage on the machine. I’ve occasionally seen the Claude + Docker combination swamp my box’s memory when I’ve had too many agents doing heavy work at one time — and I have 128gb of RAM.

Oh, and it’s only anecdotal, but PostgreSQL runs far more lean in Docker for local development than SQL Server. And Oracle is an absolute beast. Glad I do far more development with PostgreSQL than the others, but SQL Server is a real issue for my local development sometimes.

The AI agents make it a lot easier for you to build deep quality into tools like the Critter Stack because you can just casually say “hey, go build a stress test and check out the memory usage before and after this change” or “hey, go do some exploratory testing against X, Y, and Z using permutations A, B, and C” that have very frequently helped find and fix previously unknown bugs for us. But, you have to actually think to do that and to have relatively specific instructions for your AI agents. AI doesn’t magically seek out and find problems for you without specific prompting.

More context switching

I fielded some questions about idempotency protections with Wolverine from a client — which Wolverine recently added originally for our new recurring cron messaging, then expanded quite a bit for a different client. See Logical Message Deduplication with Wolverine for more information.

I also need to get more serious about our homegrown CRM. One thing at a time.

Stoat telling me what’s going on!

Mostly for CritterWatch development, we had trouble a while back with test suites hanging within AI agent sessions, and it wasn’t clear if the tests were slow or dead or Docker ran out of memory or whatnot. In no small part because of that, I invested some serious “vibe coding” time into the Bobcat Supervisor library that uses the Microsoft Testing Platform to give a lot more visibility into long running tests and to even help parallelize tests, identify flaky tests, and do some selective test retries. It even “knows” in some cases to do Docker resets in the case of certain test failures.

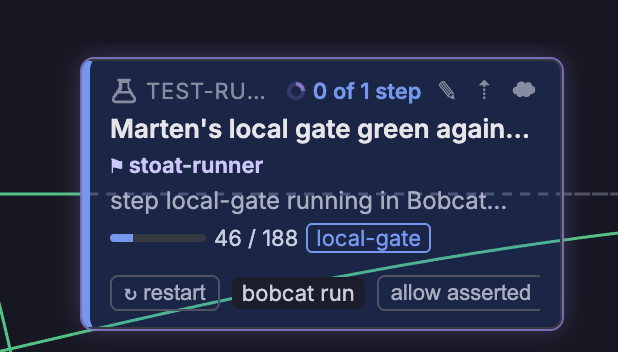
Anyway, part of the Bobcat Supervisor that’s not applied to all Critter Stack projects is that Stoat can show us a little bit of progress tracking in its UI for where it’s at when it’s running these long ass test suites:

11:09 AM, time to review pull requests

I’ve got 16 open pull requests to Wolverine. One is for Wolverine 7.0 I’ll ignore (to switch to the new Dekaf library underneath our Kafka transport that JT did for us). A couple are for pull requests built out from the Stoat plan earlier today. I’m going to focus first on the pull requests from other contributors that I’m trying to get into this release.

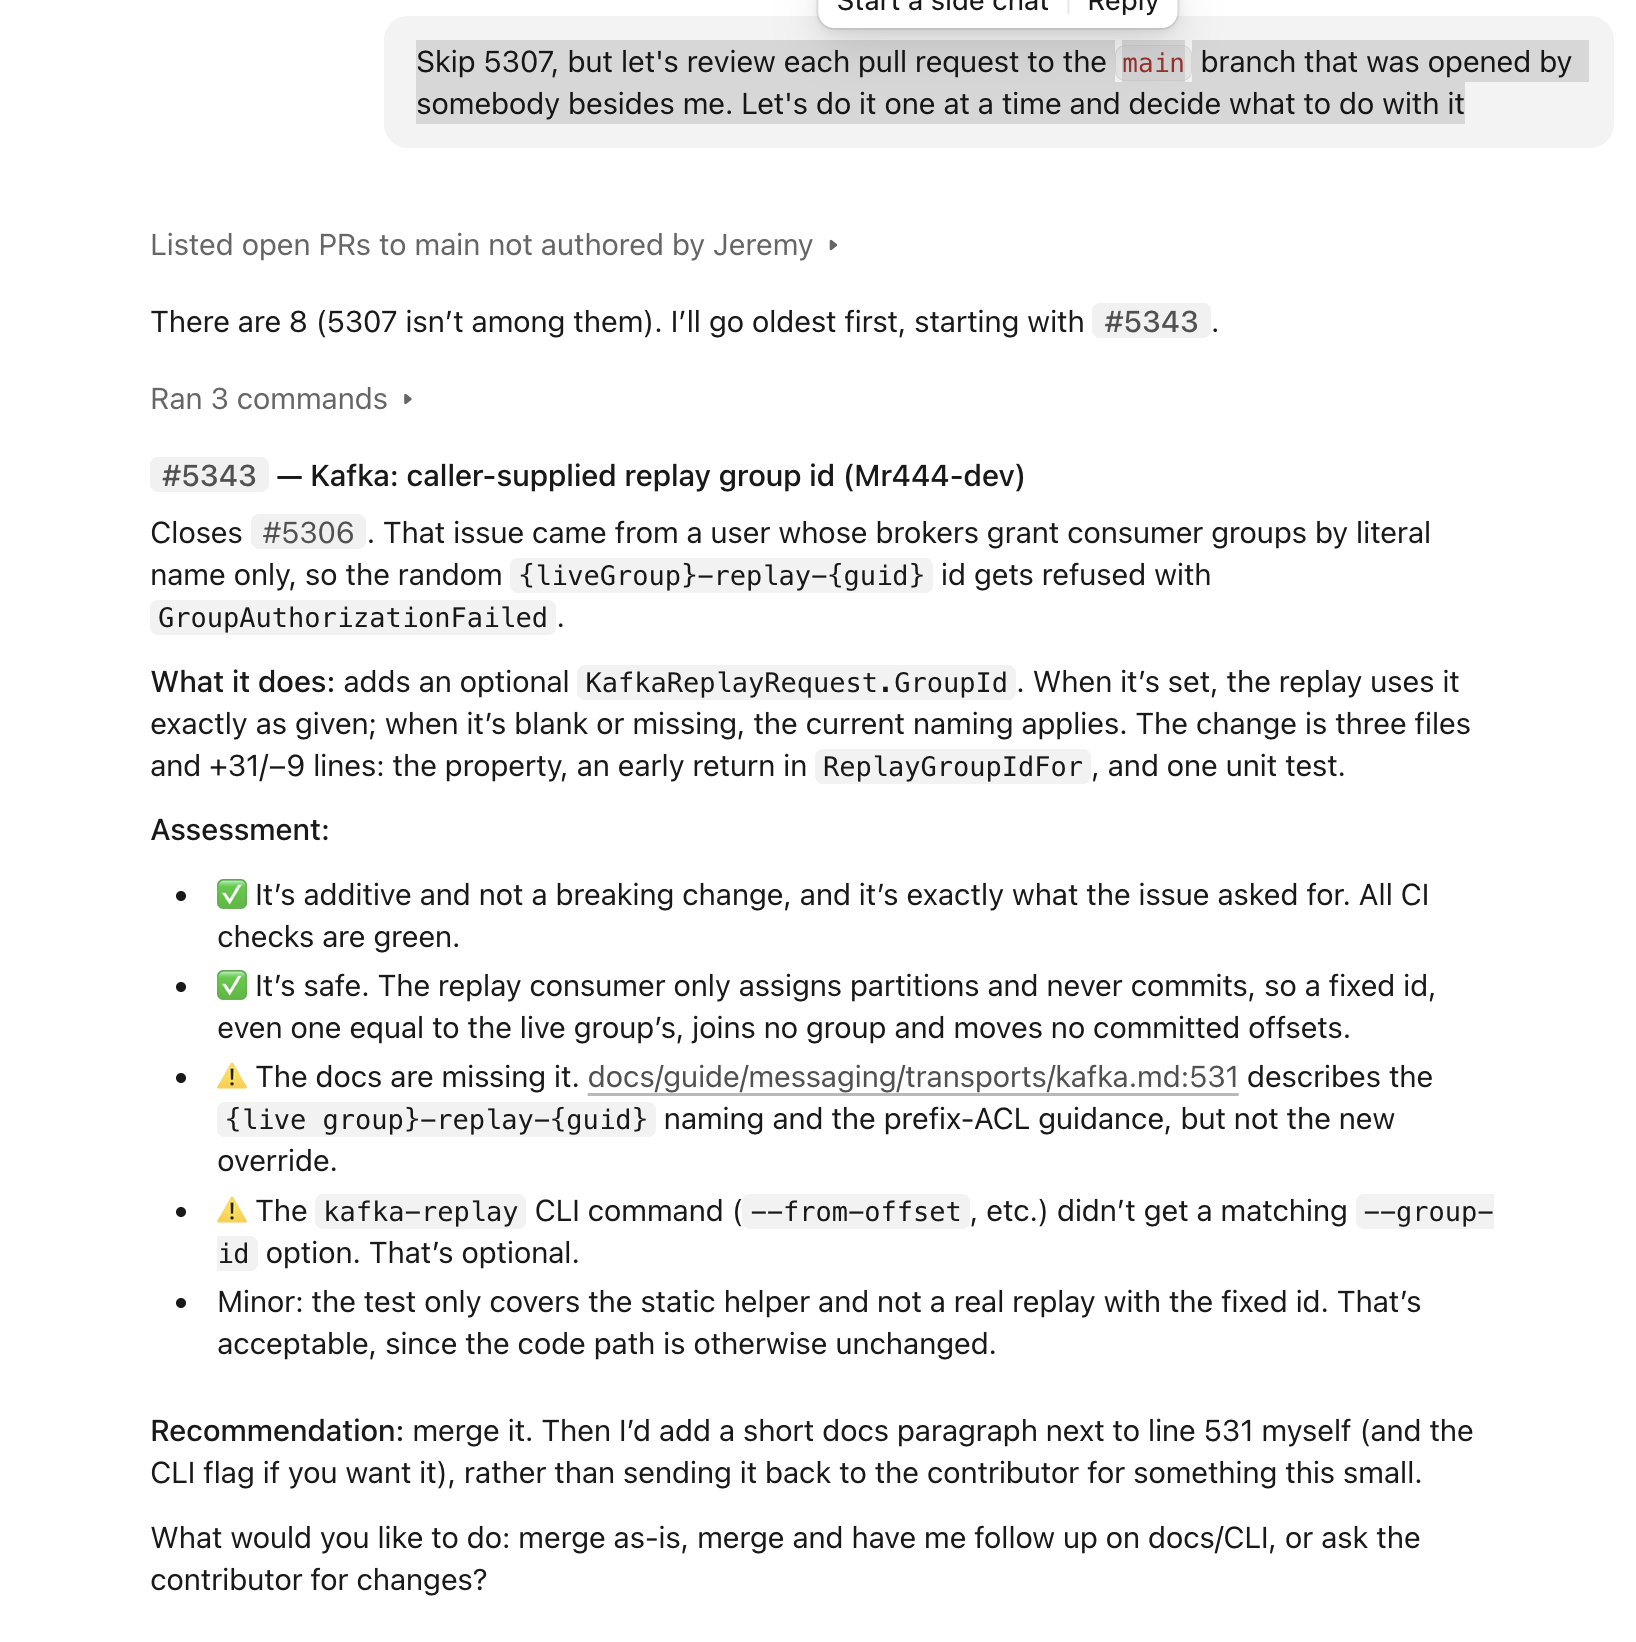
I’ll admit that I do use AI to help me review pull requests with a prompt like this one:

When I get pull requests — and especially now that AI agents is lowering the bar for people to just try to do things themselves — I generally triage them into a handful of buckets:

  1. It’s all good, just pull it in
  2. It’s mostly good, but needs some immediate follow ups or changes, in which case I merge it then immediately do the follow up. I’ll add a comment to the original PR, but I don’t really want to have to wait on someone else to happen to see the comment then get around to doing the follow up. I did this a couple times today for documentation and some minor edge cases. I’ve done it in the past for performance reasons.
  3. Build a superseding pull request instead because I think the solution needs to be done differently. When this happens I try to make sure the original author gets a co-author credit on the new pull request and add a reference to the old pull request pointing at the new pull request before closing the original. I do this a time or two a week. I did that today for the Marten scalability thing I’m working up today because I was afraid the approach in the original pull request might lead to potential dead locks under load.
  4. Reject it with a note explaining why we’re doing that. I did that once today for something I just admittedly didn’t want to have to support, but that’s very rare. Sometimes I’ll say thank you, but that the work in question is just too risky for that to be coming in from an external contributor. If I ever do that to you, just know that that’s also probably something you don’t want to be responsible for anyway!

I’ll also frequently have an AI agent add more tests before taking in the pull request. The killer problem with community contributions is that folks are quite naturally focused on tactical problems that impact them while you the OSS maintainer really need to be strategic and think about the bigger picture. I’m also hopefully more aware of edge cases and problems that have bit us in the past and generally have a good idea about where I think the technical risks are that might not be obvious from the outside.

I know some people are seeing a lot of AI slop pull requests to their OSS projects, but I’ve been mostly happy with what we get. I don’t know if that’s because the Critter Stack community is just a bunch of discerning technical folks with good judgement, AI tools have gotten much better, we just have a great codebase where the right patterns are very clear, or we’re just not popular enough to attract the slop that more visible OSS projects are getting inundated with.

A second pull request did have a judgement call. A user is requesting to add a new partial index to a Wolverine table in our scheduled messaging support. It’s probably a good idea, but that requires a schema change and we usually say that requires either an “opt in” gating flag or a major release. But, since it’s an additive change that wouldn’t impact functionality if you didn’t apply it, I’m going to let it through. There’s a little bit of a chance that Wolverine’s ability to automatically apply schema changes could bite somebody in production, but this is a partial index that shouldn’t be a problem. I think this is an acceptable risk compared to the potential pay off in improved performance.

Watch me be wrong though 😦

And actually, this is a bit of egg on my face. One of the things I try to do is notice any kind of trends in issues or potential trends in an issue and go do more exploratory testing to try to head off problems. In the case of the pull request above, it was something we’d already dealt with in our SQL Server support for Wolverine, but I failed to apply to other databases. What I will do to follow up later is have an AI agent go explore whether that’s a problem we should address in all the other database engines we support (Oracle, MySql, Sqlite).

I hate OpenAPI

I hate OpenAPI with a passion. Tedious, nit picky stuff. I guess thank you to people who are very detail oriented about OpenAPI and help us patch holes in Wolverine.HTTP’s OpenAPI metadata generation.

No, you can’t just vibe code this stuff

This one: https://github.com/JasperFx/wolverine/pull/5349. The new Dunning Kruger poster children are the folks who write into Reddit or YouTube comments and scoff that you should never use something off the shelf if you can just get AI to write it for you.

There’s so much work we do to Wolverine or Marten with AI that only starts from reported problems in real usage. Often from oddball production mishaps or Kubernetes scale up / scale down incidents. Or network hiccups like temporarily losing connectivity to a database or message broker. If you vibe code something, you’re getting the happy path. That’s going to give you a sugar rush high, but that’s a long ways away from a tool like Wolverine that’s been beaten on by real usage over time. Not to mention Marten’s support for very high volumes that all the newer, upstart event store tools haven’t had to face yet.

Some of the things that have generated Wolverine bugs + improvements lately:

  • CancellationToken passing. It’s harder sometimes than you think and easy to do wrong
  • Not losing work that’s in flight when the system is being shutdown
  • Order of operations issues on system shutdown
  • All the weird problems that pop up in extreme loads that you never see in your normal development. Even when you *think* you’ve done load testing because the real world is always more complicated

Another frustrating thing to me is how AI tools are turning up latent bugs in what I would have described as very stable code. It’s apparently important to keep an open mind about long running codebases and still consider improvements to code you think is “done.”

If you haven’t seen this, the PostgreSQL 19 release has been somewhat delayed because AI tools keep finding existing bugs in really old code. I’d call PostgreSQL one of the very best OSS projects on the planet that involves some of the best people around. I’m bringing this up in a way because reading about their struggles made me feel better.

11:30 AM — Lunch, indulging in post-US election Schadenfreude, XBox time, finally working out

I kicked off the stress test on Marten finally too and tried to mostly walk away from the computer.

About the US election this week, I’m genuinely more hopeful than I’ve been about the US and Texas specifically than I’ve been in over a decade. Seriously, the GOP did some very serious harm to public education in Texas, and this Dad is hopeful that the new state government starts to turn that around.

Code behaves differently under extreme data volumes sometimes

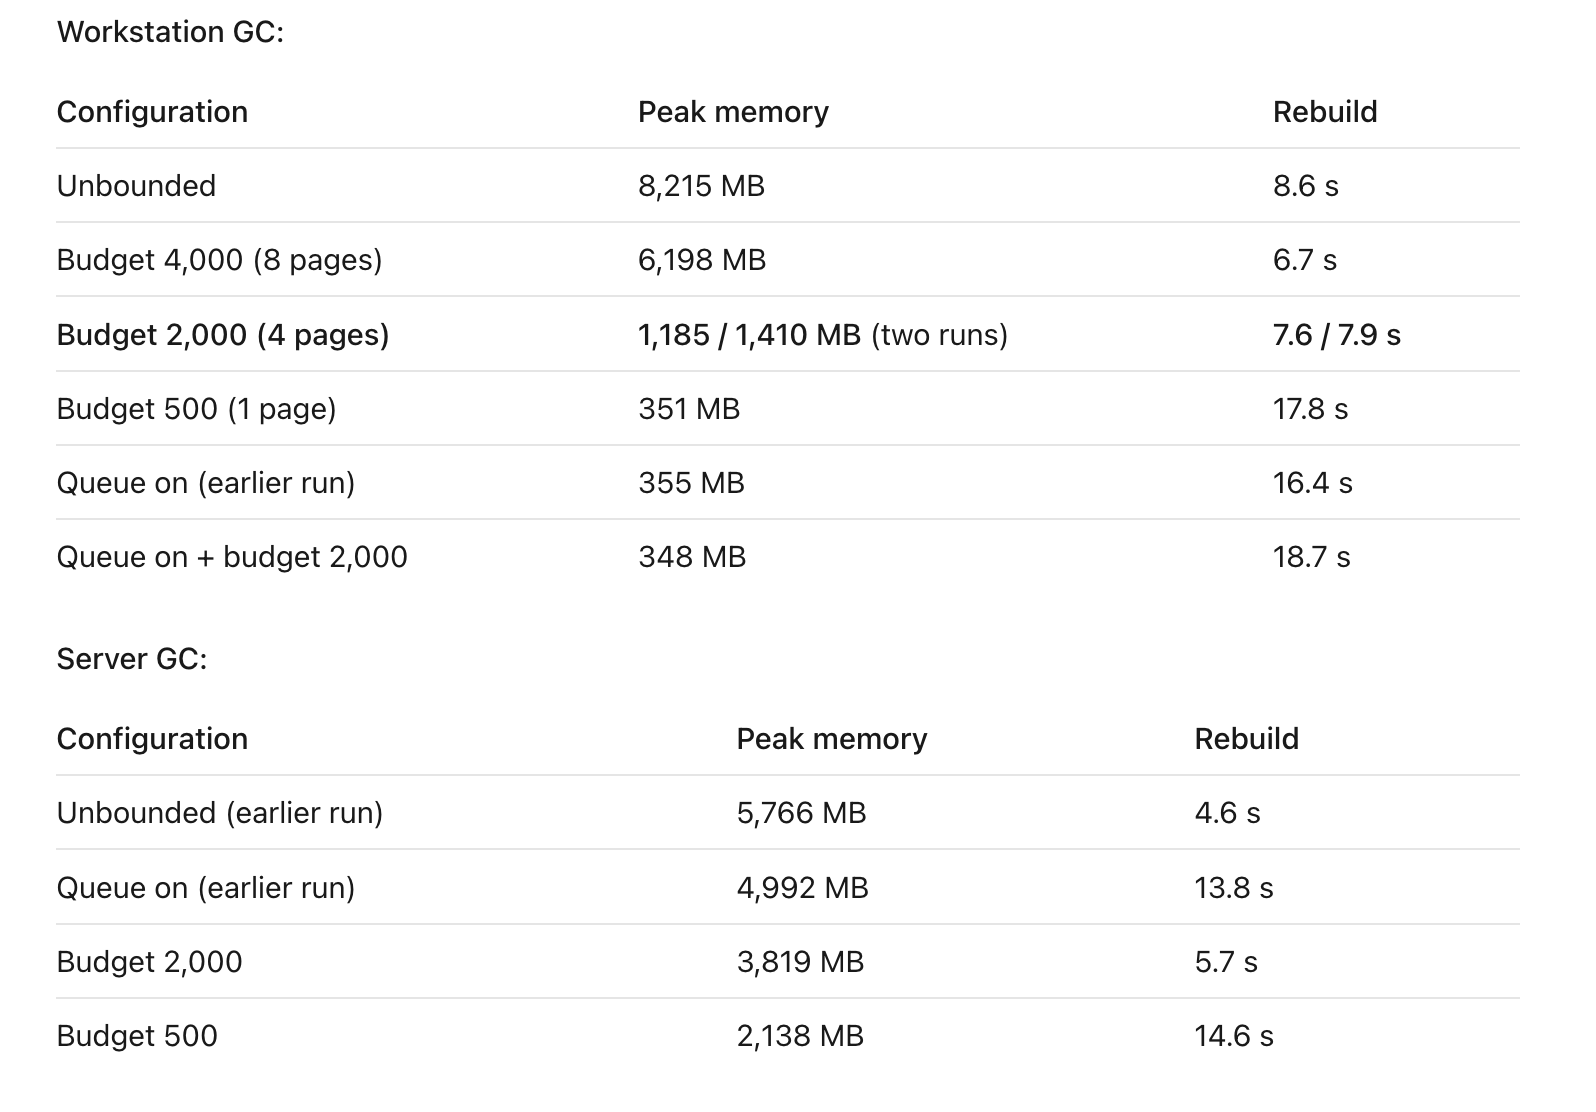
Thank you, I’ll be here all week! Here’s some of the results of the stress tests against Marten’s Async Daemon when using the fancy pants per-tenant partitioning for extreme data loads:

AI tools again do make it pretty easy to spin up stress tests and memory testing and what not, but it’s again still up to you to *think* to have it do that.

In this case, I think the new “Budget” approach up there is going to make our client happy. Assuming that I can get this release ready today.

(the Marten release got made a couple hours ago, but I just realized that I missed generating release notes. On it!)

In the words of the late, great Tom Petty…

“The wait is the hardest part…”

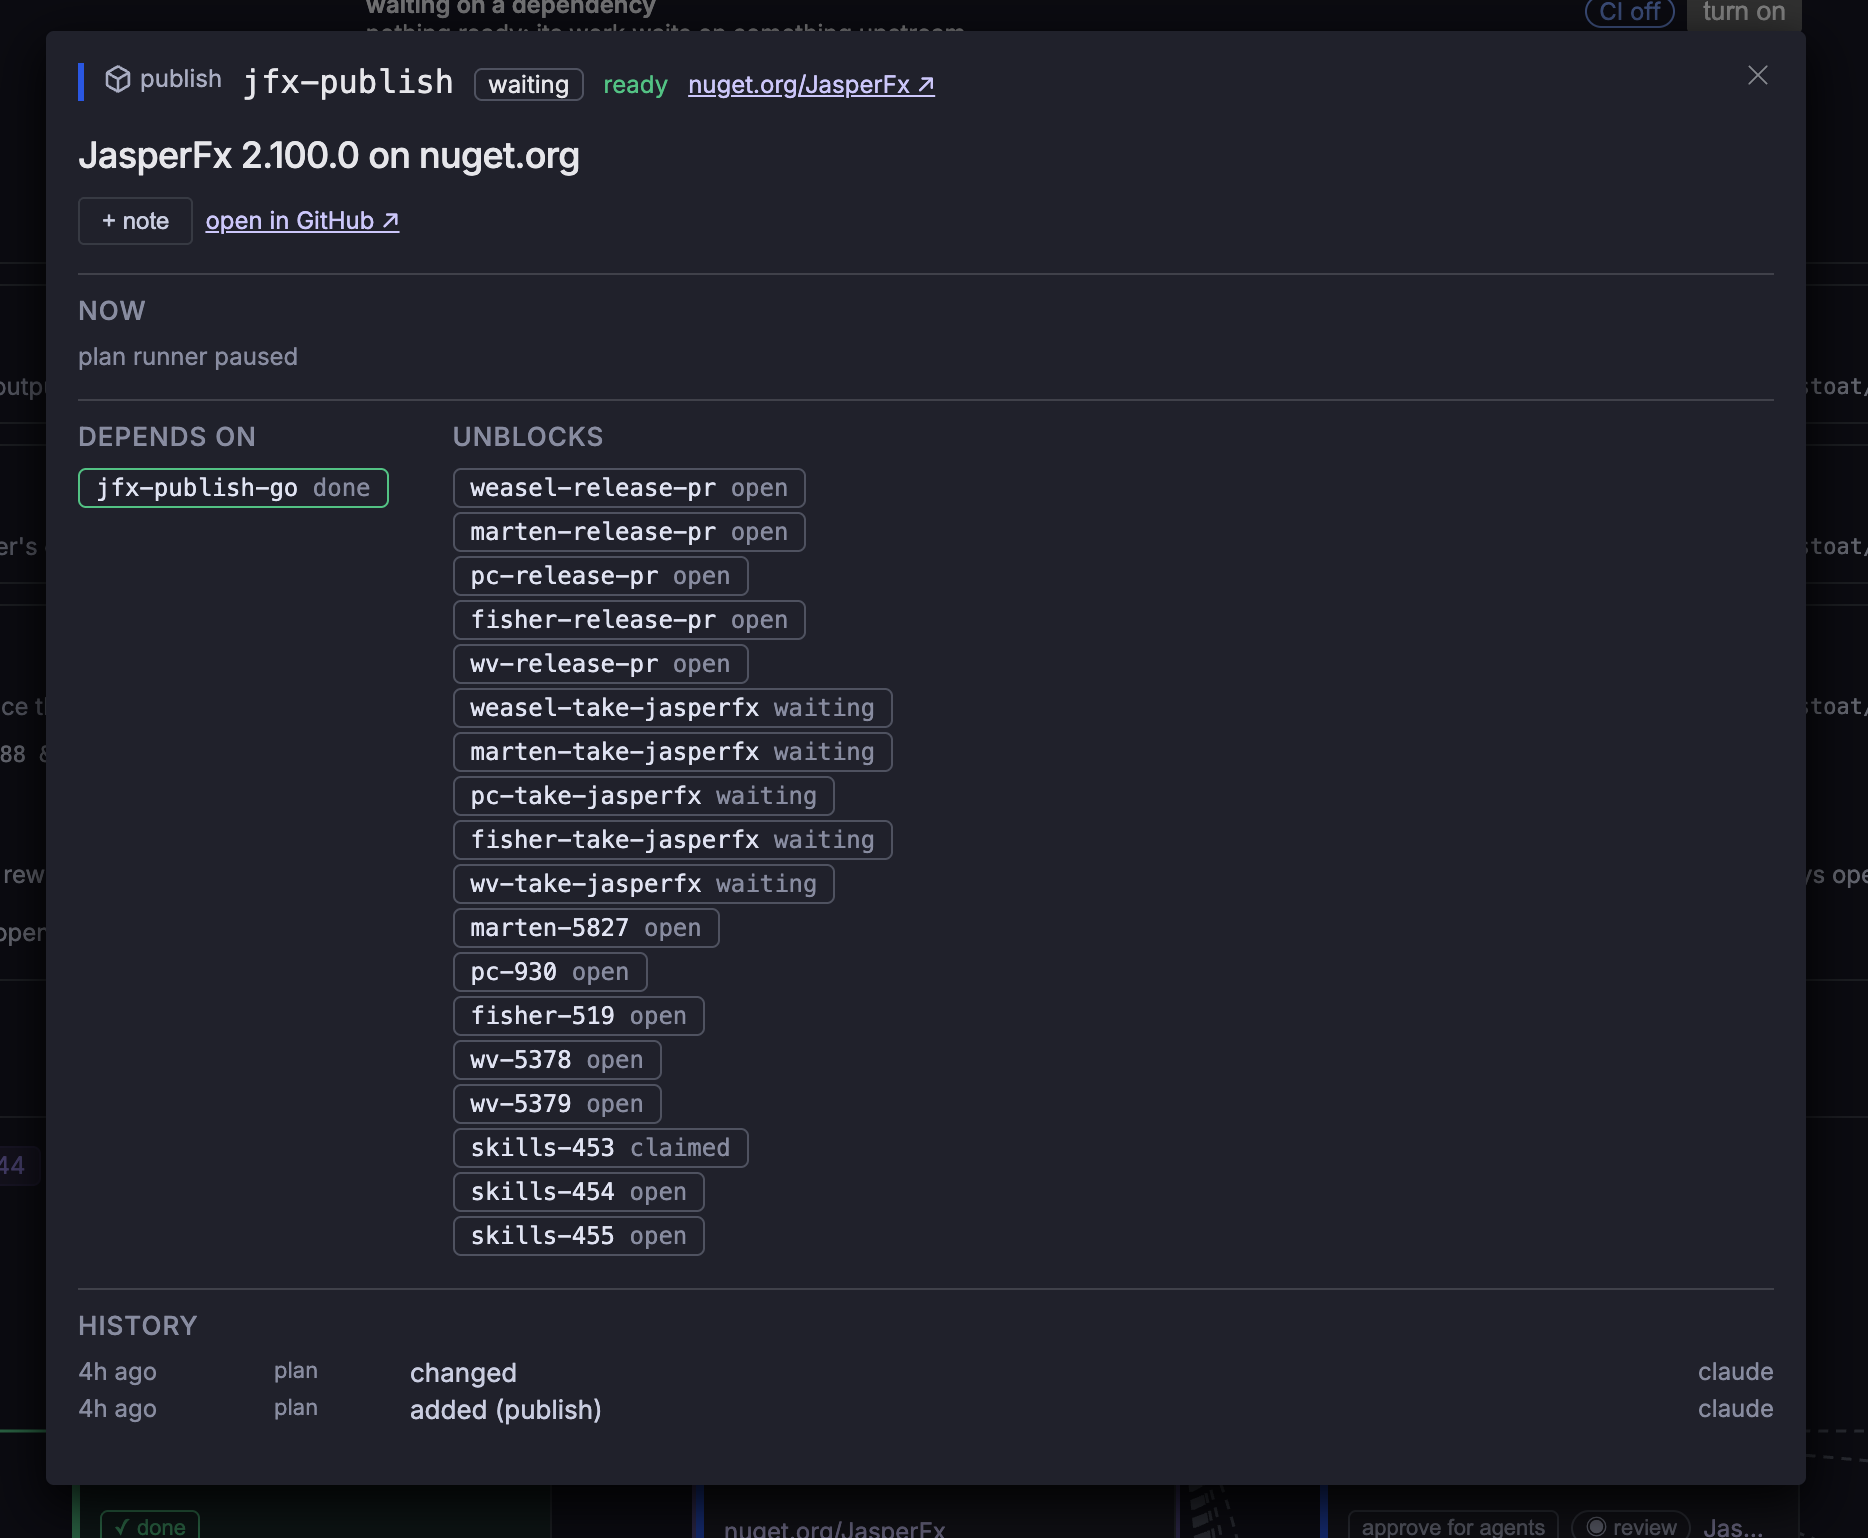
Stoat has some functionality to wait for new Nuget versions to appear, then release downstream items for execution later in the plan. Waiting for Nuget indexing used to be a bottleneck for me in these kinds of days, but Nuget got faster then GitHub Actions got overloaded to be the new bottleneck.

And we can continue!

Just pointing out that Stoat can indeed kick off downstream work when it can tell that upstream dependencies are in place. I won’t say that Stoat exactly worked smoothly today, but it got better today!

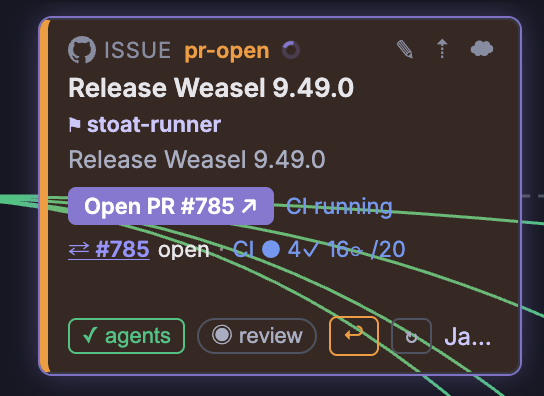
And now there’s a pull request for me to review:

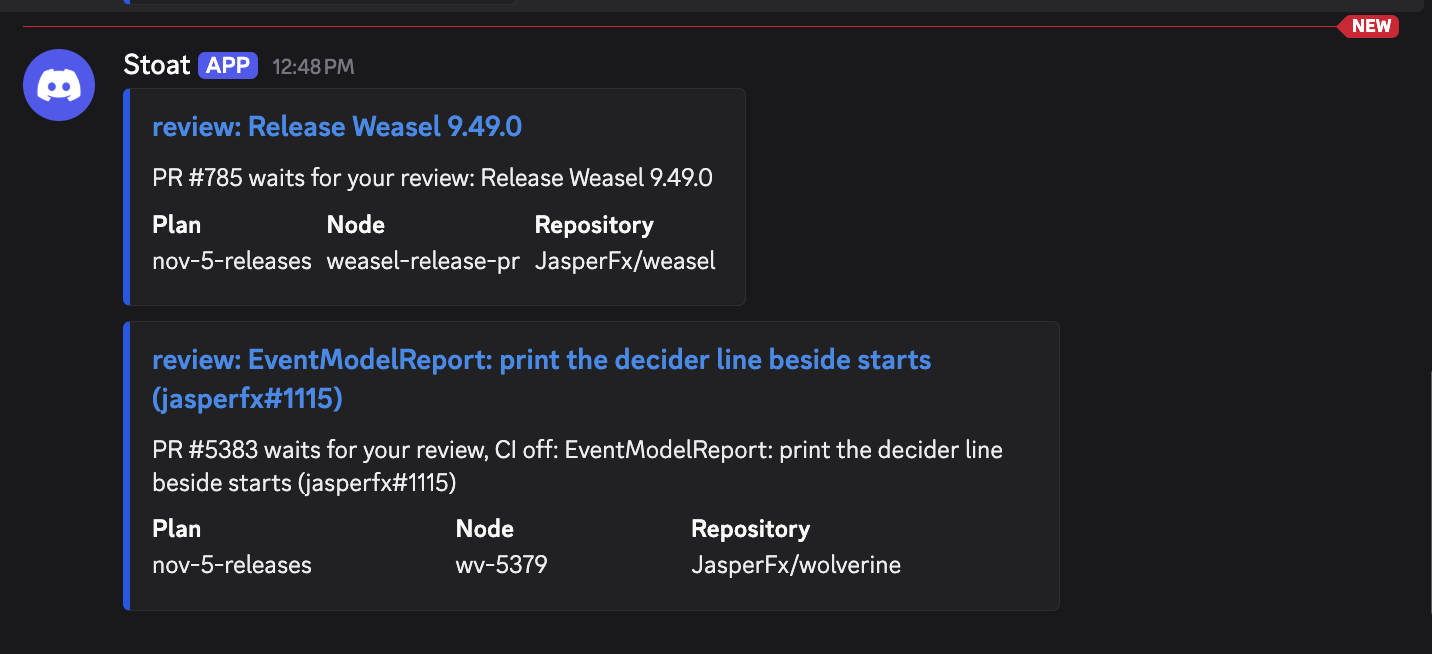
And I had the clever thought that I’d have Stoat send me Discord messages when it needs my attention. The jury is mixed on whether this was worthwhile.

More pull requests, this time for Marten

These were a lot easier. Marten is pretty stable and battle tested now and we aren’t adding a ton of new functionality. Some things still pop up though.

More waiting, but at least there’s feedback

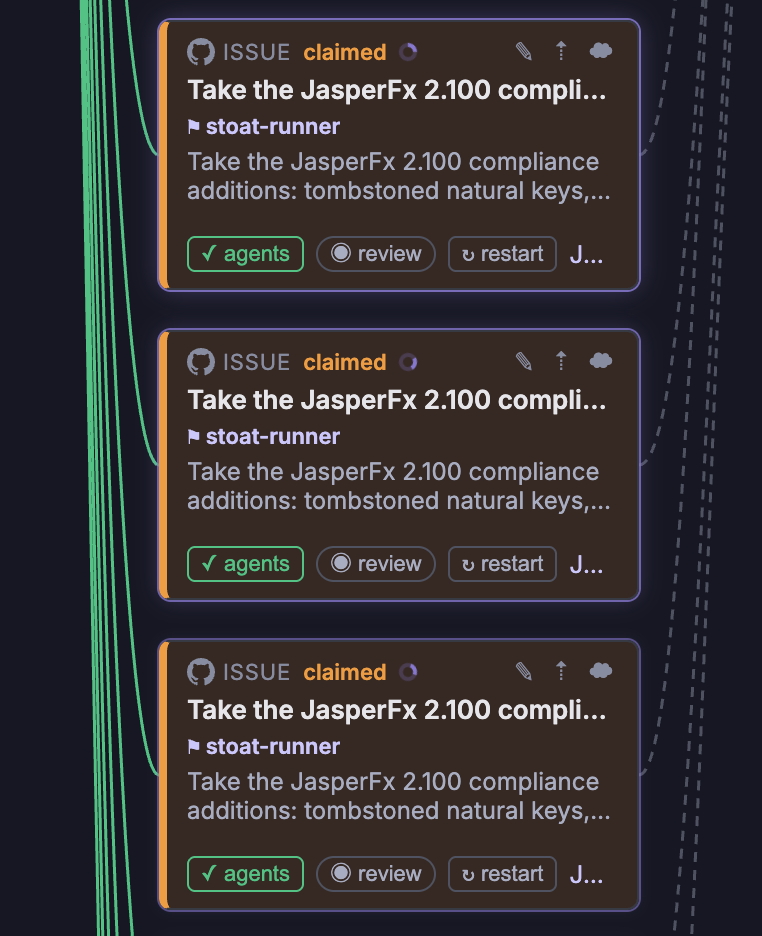
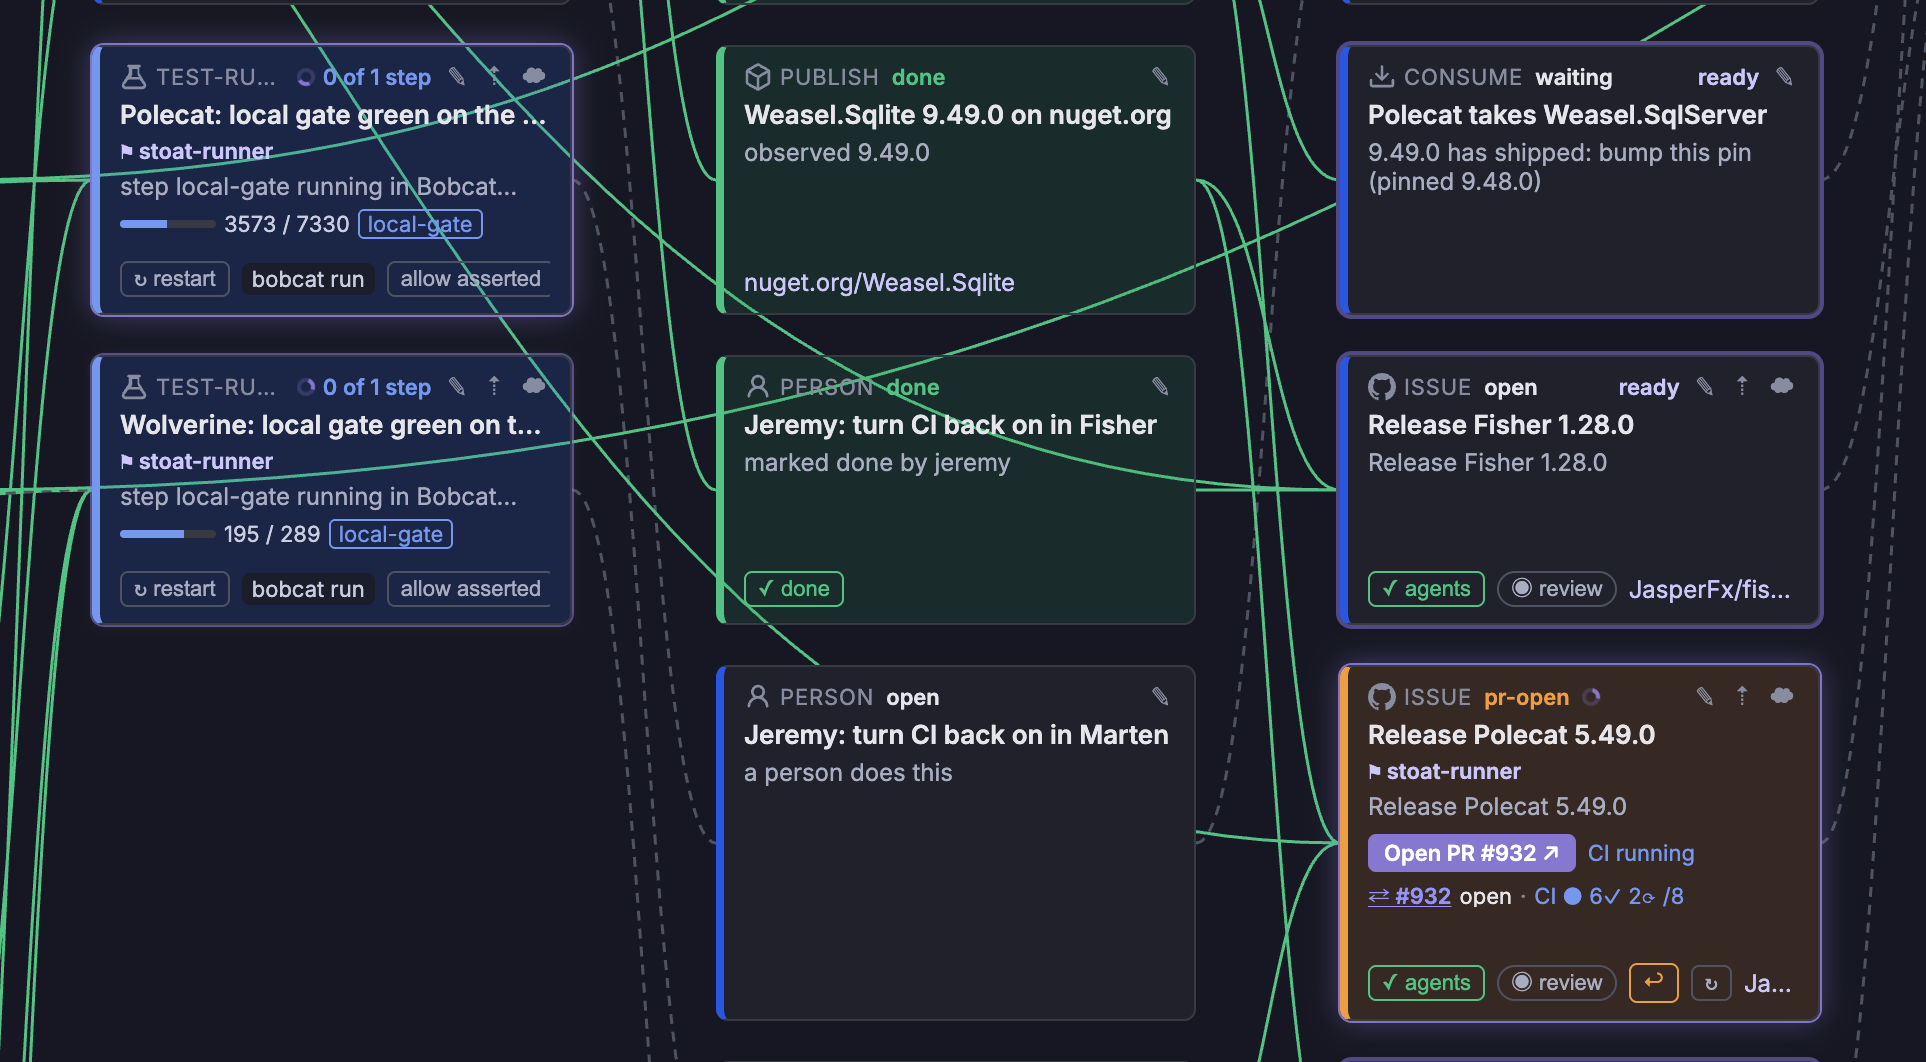
If you squint really hard at the two cards in the first column, you can see a progress bar telling us where the test suite process is at. If you zoomed into a single card, it gives you more context than just that. Likewise, in the card at the bottom right, it’s monitoring CI jobs for that pull request (I’d enabled CI again at this point) and letting me know how many CI jobs had finished successfully, failed, or yet to finish.

This kind of status tracking has been helpful.

Unsurprisingly, my box is running hot and the fans are blowing hard as it runs a ton of Wolverine tests and Polecat on SQL Server tests at the same time.

Late in the work day

Almost there, stay on target…

And there’s a security advisory in some kind of .NET package from Microsoft that’s making a quality gate fail. No big deal to update, but AI agents are definitely finding a lot more security vulnerabilities that were already there and I’m finding myself having to react to those more often in Critter Stack work. We had never had a security advisory with Marten until this year, but now I think we’ve had 3 or 4 due to oddball SQL injection vulnerabilities in Marten’s full text search or places where we use JSONPath or PostgreSQL containment operators. And that’s after I tried to get Fable to identify a couple places where we were vulnerable.

It’s all to the good, but I’m definitely seeing quite a few bug reports to Wolverine especially for latent bugs that I don’t think anyone (including me) ever would have noticed without AI finding them. Likewise, I mentioned how it’s now cheaper to tell an AI agent to go write chaos monkey tests or stress tests or whatnot. Now we’re getting issues from people doing that themselves in their own application hardening or PoC work and passing that along to us.

I will say that that seems to be diminishing lately? Knock on wood.

Almost there.

There’s probably a couple more hours of stuff to run, but I’m about at the point where I think Stoat and Claude can handle the rest of it without me.

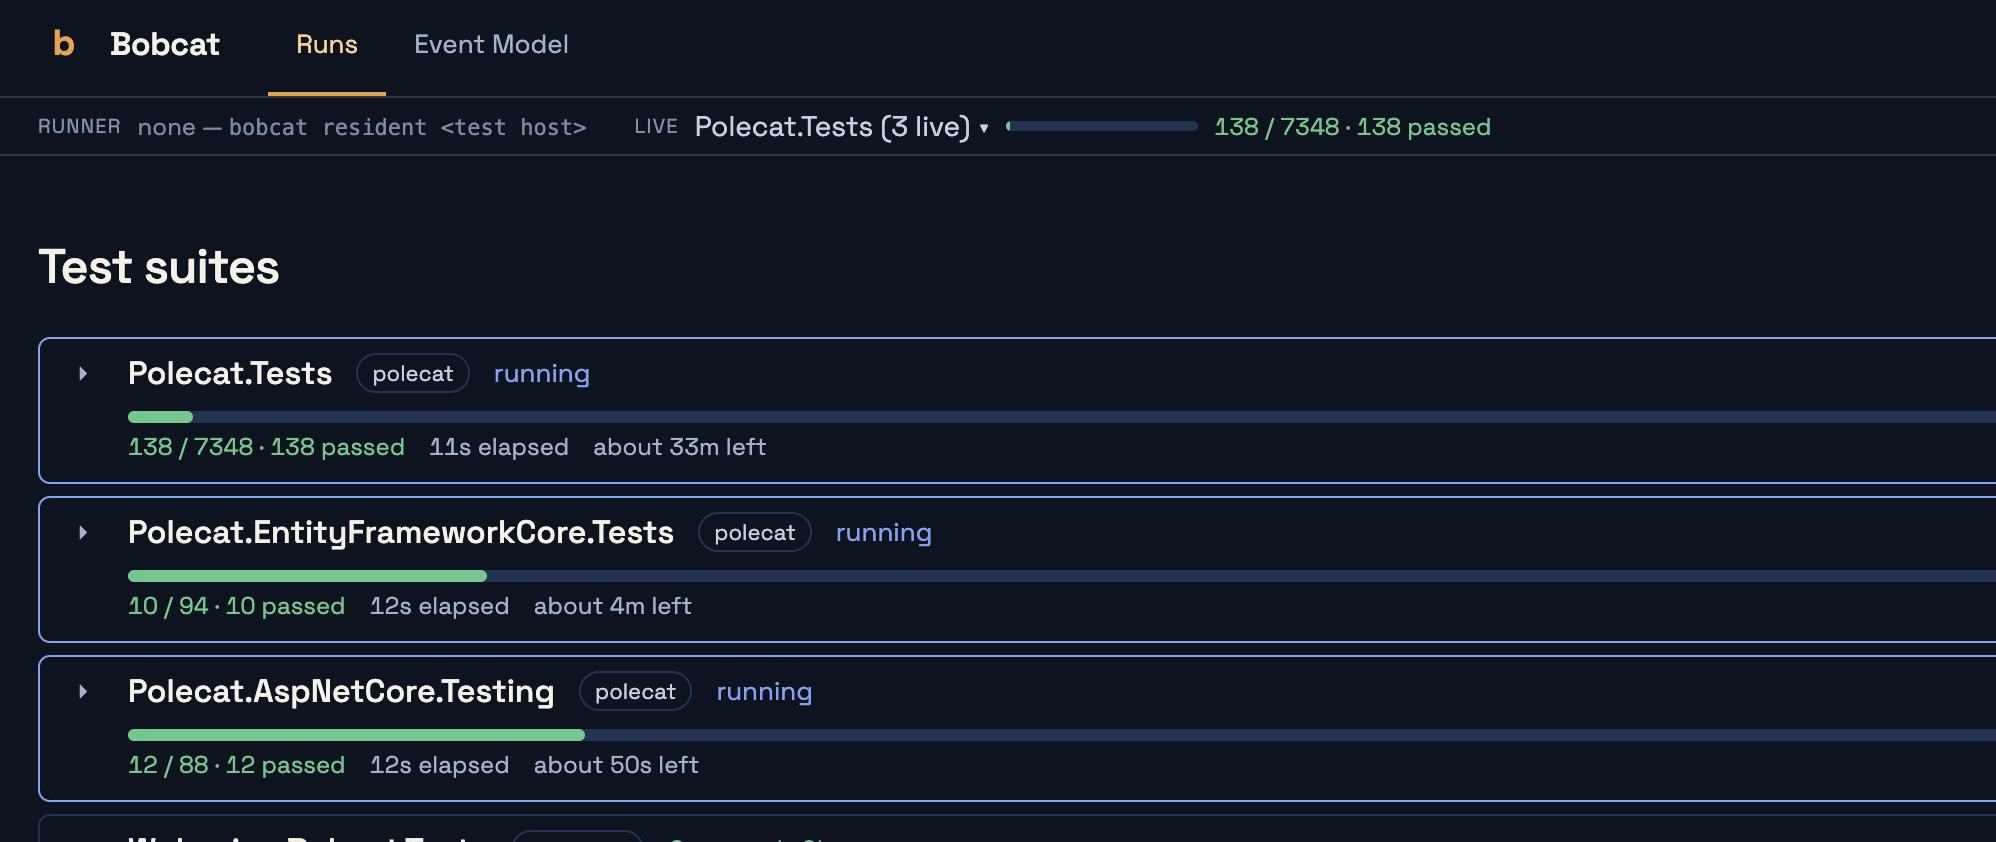
Below is a screenshot of me using the Bobcat UI just to monitor ongoing tests as I had Stoat run a “LocalGate” of Polecat right before publishing new Nugets.

Wrapping up…

There’s still more going on, but I’m done with productivity for the day! Hey, I don’t know if this was the slightest bit interesting to anyone but me, but I kind of enjoyed doing the little diary for today. I don’t plan for an encore though!


Read the whole story
alvinashcraft
6 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Daily Reading List – November 5, 2026 (#904)

1 Share

The AI SDLC has been a hot topic this week among our customers. Many people want blueprints, but I’m not sure many general purpose ones exist. Work to do.

[blog] How two engineer side projects became the agent taking action inside Dropbox. This looks like thoughtful work, both in how they approached user interactions, and evaluating permission handling.

[blog] How Context Drift Impacts Your AI Agents. This is a case of moving from “what if” to getting hard data. Patrick shows that LLMs swallow context conflicts unless you force them to shine a light there.

[article] The Hidden Productivity Trap in an Engineer’s Workday. Interruptions are a fact of life, but are you giving yourself (or your team) windows to just stay heads down? Hopefully yes.

[site] November 2026 ThoughtWorks Radar. This is probably my favorite tech assessment. Each time they release one, I find a handful of techniques or products I’ve never heard of.

[blog] Powering open infrastructure for autonomous agents. More open source components for the emerging agent platform. We just gave a few key ones to the CNCF. More here.

[blog] Agentic Commerce Protocols — UCP and AP2. Speaking of open, are you tracking these protocols for commerce and payment? This helped me understand them better.

[article] Eight reasons human developers are better than coding agents. Here’s the counterpoint to an article last week about why agents are better than humans. These points are mostly around agency and accountability. Not capability.

[article] Apple is reportedly cutting budgets for its internal AI usage. Understandable. But maybe not sustainable if we expect employees to fully capitalize on AI in their work.

[blog] A new Go API for JSON. We take backwards compatibility seriously, but also keep pushing performance forward. Great blog post.

[blog] AI-assisted SDLC in a regulated industry: case study. I’ve seen (personally, close up, from afar) flavors of an AI SDLC. Mostly seems about pacing and what’s agent-led versus human-focused. With a few variations mixed in.

[blog] Gemini Omni 1.2 Flash: Fast, cost-effective, and reliable video generation and editing now generally available. Looks good. Cheaper, more consistent results, more natural speech, and faster.

[blog] MCP vs API vs CLI: How Should AI Agents Connect to Your App? This is an extended look at your various options. I think he undersells the CLI and doesn’t factor in token consumption, but the overall assessment is solid.

[blog] When Building Gets Easier, Decisions Get Harder. Sure. The product manager job didn’t just get easier. Now you have even trickier things to work on.

Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:


Read the whole story
alvinashcraft
6 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories