 Log in

Speaker: Max Covey
Advanced stealth tradecraft, including syscall dispatching, unmanaged memory access, and runtime evasion, is typically designed for compiled binaries. This talk explores what happens when those traditionally native capabilities are translated into a fileless runtime.
PowerShell was chosen as the target runtime because it is broadly available in Windows environments and exposes surprisingly low-level .NET and unmanaged functionality while often remaining enabled in enterprise settings.
Rather than treating PowerShell as "just" an automation tool, this research asks how far a fileless scripting runtime can be pushed toward native offensive capability development. I will walk through the technical implementation realities including AMSI, CLR behavior, modern AV/EDR visibility, and where AI-assisted workflows accelerated difficult interoperability and translation challenges.
Through a progression of working and failed implementations for a fileless process injector, attendees will see how traditionally native tradecraft evolves from standard C and ASM to WinAPI, NTAPI, direct syscalls, and indirect syscalls performed entirely within PowerShell. Techniques discussed include P/Invoke, marshalling, unmanaged invocation, shellcode loading, process injection, ntdll parsing, and syscall strategies within a fileless context.
A pre-recorded proof of concept will show the resulting framework successfully operating in a fileless execution model to perform process injection. This will be followed by a discussion of observability, detection opportunities, and defensive implications. The framework will be publicly available at the time of the talk.
For defenders, this talk highlights meaningful opportunities for telemetry, detection engineering, and defensive prioritization.
⚠️ *Microsoft **requires** everyone to check-in before entering their facility. You must provide your first and last name when signing up for this in-person event to be on the attendees list we submit to Microsoft.*
⭐⭐⭐⭐⭐⭐
🔔🔔🔔🔔🔔🔔
**philly.NET is also on:**
* [GitHub](https://github.com/phillydotnet) · phillydotnet
* [YouTube](https://www.youtube.com/phillydotnet) · phillydotnet
* [Discord](https://discord.gg/j7mFC6H8jE) · PhillyDotNet
* [LinkedIn](https://www.linkedin.com/groups/137867/) · philly.NET
* [Instagram](https://www.instagram.com/phillydotnet/) · phillydotnet
* [Mastadon](https://jawns.club/@phillydotnet) · phillydotnet@jawns.club
* [Facebook](https://www.facebook.com/groups/phillynet) · phillynet
* [Threads](https://www.threads.com/@phillydotnet) · phillydotnet
* [X (Twitter)](https://x.com/home) · phillydotnet

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


Apple today introduced the all-new MacBook Pro with PROLED XDR Display featuring breakthrough tandem OLED technology.
Pennsylvania, USA

Our jobs as developers are changing. In a couple of years, we’ve gone from writing every line of code to working with AI assistants to orchestrating fleets of agents. But the goal hasn’t changed: ship completed software work. A feature, a bug fix, a security fix. Completed work, not more code, is the output that matters.
Today at GitHub Universe, we shared our vision for GitHub as the most comprehensive software delivery system in the world. We introduced products that bring that vision to life and showed how we’re rebuilding the infrastructure underneath it.
Our vision: From idea to completed software
The SDLC is no longer a linear path from planning to coding to testing to deployment. A code change, a request from a colleague, or a production metric can trigger work anywhere in the system. Most of us (and our agents) jump between different stages, depending on the task at hand. Developers set the direction, make decisions, and stay accountable for what ships. Agents implement and verify changes. And everything feeds into and out of a continuous learning machine that makes the next cycle better.
This agentic software delivery system solves for three things:
- Velocity: get from idea to completed software as quickly, efficiently, and cost-effectively as possible
- Intelligence: combine context across the platform with a continuous learning engine, so the system gets better as you use it
- Quality: make completed work secure by default and catch bugs before they ship
GitHub is built for developers and their agents. We’re also making the underlying primitives available, so you can build your own bespoke solutions. You stay in control of the work, the tools, and the cost.
New features and products that move the work forward
Today at Universe, we showed some of the latest products and features in action, starting with the GitHub Copilot app.
GitHub Copilot app: From issue to merge, in one app
The GitHub Copilot app is designed from the ground up for agentic software delivery. It connects your agents and tools across projects, so you can direct the work without making every handoff. And it’s for more than producing code: you can write specs, present design discussions, or analyze telemetry in one agent-first surface.
Copilot Fusion: Multi-model orchestration at its finest
Different tasks need different models. Developers shouldn’t have to manage every model choice to get the right result at the right price. Copilot Fusion evaluates what a task needs across reasoning, code generation, debugging, and tool use, then chooses how to execute across one or more models. In the Artificial Analysis Coding Agent Index, Fusion Max scored within two points of Opus 5.5 Max at half the cost and 40% less time per task.
Copilot projects: Give Copilot a goal
Available natively in the GitHub Copilot app starting today, Copilot projects let you run agent work across multiple repos in fully managed, parallel sessions. You have one place to track progress, make decisions, and direct what happens next. That means you can spend less time managing execution and more time deciding what’s worth building.
Session continuity: Keep working across surfaces
Your work shouldn’t restart when you switch devices or tools. Session continuity lets you start and follow the same cloud agent session across the GitHub app, VS Code, the CLI, and the web. Start from your phone at standup, steer it from VS Code at your desk, and check in on it from github.com at lunch. The agent keeps working in the cloud. Our multi-model harness that enables it is powerful, fast, and cost-efficient.
Copilot automations: Learning from the results
Copilot automations let you create AI-powered workflows within your repo. They run in the cloud, and you can kick them off manually or set them up to respond to an event or run on a schedule. That lets you coordinate agents to handle tasks such as issue triage and code review. And now, automations can learn from their outcomes and propose improvements for you to review and approve. That’s the learning engine in practice. Use the results of the completed work to make the next run better.
Copilot code review Max: A deeper look at what ships
More code means more pull requests and more demand for review. Moving faster only helps if we can maintain the quality of what ships. Copilot code review surfaces meaningful, actionable bugs that developers need to catch. Today, we introduced Copilot code review Max, which posted the highest F1 score on ReviewBench for high-severity issues. Lite and Balanced keep everyday reviews fast; the new Max provides a deeper look when a change needs it.
Copilot features without a separate enterprise subscription
Starting today, GitHub Enterprise customers can use all Copilot features without buying a separate subscription. That includes GitHub Copilot app, code review, automations, and more. You pay for the AI credits you use.
This is available through GitHub Sales today, with self-serve coming soon. Existing Copilot Business and Copilot Enterprise customers can keep their current plans or move over when they’re ready. GitHub also remains open and extensible. Keep using the tools your team depends on, including Cloudflare, Datadog, Figma, and more.
Our continued infrastructure investments
All of this depends on a foundation that’s fast, reliable, and built to scale. Agents are changing the volume and shape of software development. Adding capacity matters, but capacity alone won’t get us there. We’ve also had to change the architecture.
So far this year, we’ve added:
- 4 million CPU cores
- 160 PB of high-speed storage
- 50 Tb/s network capacity
We’re also migrating to a multi-region deployment in Azure, while continuing to serve incredible levels of traffic from developers around the world. We expect to complete the migration early next year. Those investments give us more room to grow. The next step is building the systems that handle the work.
We’ve scaled Git for years as activity on GitHub has grown. The agentic era calls for a different ceiling on throughput and reliability. Three principles guide our new Git architecture: simplify the primitives, decouple storage from compute, and minimize coordination.
Git’s just one example of the work we’re doing to scale the platform. We’ve done a lot of work across GitHub’s AI gateway, the harness, and much more.
Beyond the first 1%
Our jobs are changing, but developers are more important than ever. I think all the software we’ve written to date will amount to less than 1% of the software we’ll write in the next five years. The opportunity isn’t just to produce more code. It’s to solve problems we couldn’t solve before.
That’s why we’re connecting the full software delivery system, giving developers better ways to work with agents, and evolving the infrastructure for what comes next. And we’re doing it on GitHub, where we can build together.
The post GitHub Universe 2026: Evolving every layer of the stack appeared first on The GitHub Blog.
Pennsylvania, USA
Developers pushed code to GitHub 17.9 billion times in the past 12 months, more than in 2024 and 2025 combined.
Behind that number are developers building what interests them and what their communities need. In Nepal, one developer built a flood bulletin on GitHub Pages with verified information on roads, rescue, weather, and power. It has since grown into Gati, a Nepali-first relay of official disaster alerts that runs on GitHub Pages and Actions. Elsewhere, developers at NASA’s Jet Propulsion Laboratory are creating software designed to run programs aboard spacecraft, and fans built open-source firmware that lets people customize their e-readers. Curiosity, aimed in every direction, at a scale GitHub hasn’t seen before.
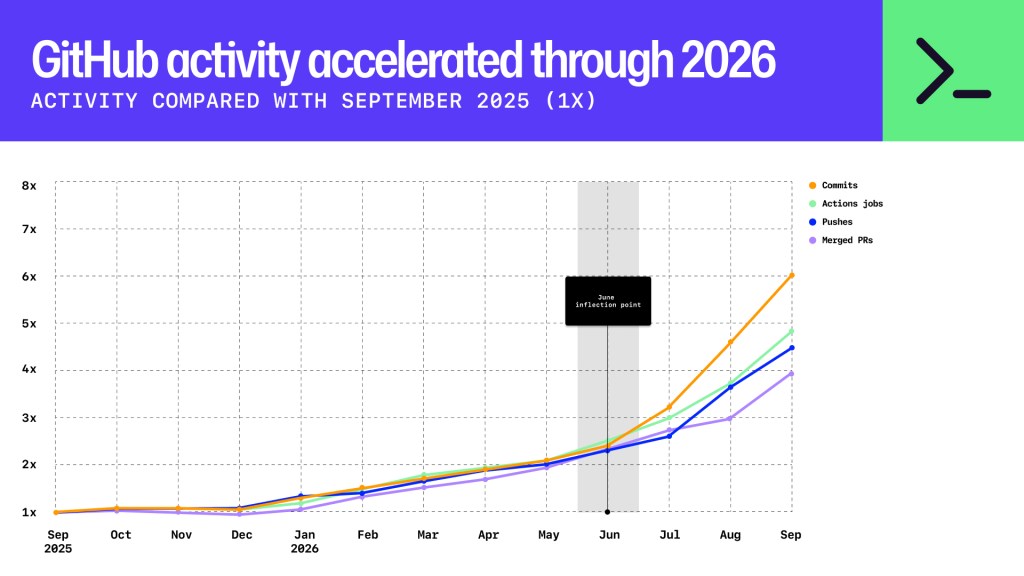
That growth happened quickly. Partway through the year, activity on GitHub bent sharply upward, just as agents went from something developers were trying out to something they were working alongside. Developers picked from more models than ever and built in industries we are highlighting in this report for the first time, from health care to agriculture.
Octoverse is our chance to step back and look at the whole picture. This year, that picture is bigger than ever. Here is what stood out most:
- More AI, more of everything. Among repositories created this year, the average repo with an agent configuration file logged eight times as many commits as the average new repo without one.
- As of September, developers start more than 40% of pull requests with an agent. In March, it was 17%. For a growing share of work, the first move is now directing an agent, and review is how developers shape what comes back.
- Developers move fast on model choice. In September, 61% of GitHub Copilot users used more than one model, and requests spread across general purpose, deep reasoning and planning, and fast and lightweight models
- Builders are showing up from every field. This year, for the first time, we’re sharing our view of public repositories by industry. Repos serving mining, construction, health care, and agriculture have each grown several times over since 2022.
Underneath it all, AI models and the harnesses built around them have advanced over the past year, and developers have more to choose from. Growth is moving quickly: one year into last year’s five-year developer growth projections, every country we projected has already closed at least a fifth of its distance to 2030, and our own forecasting models no longer agree on where it will go next.
The year developers set a new pace
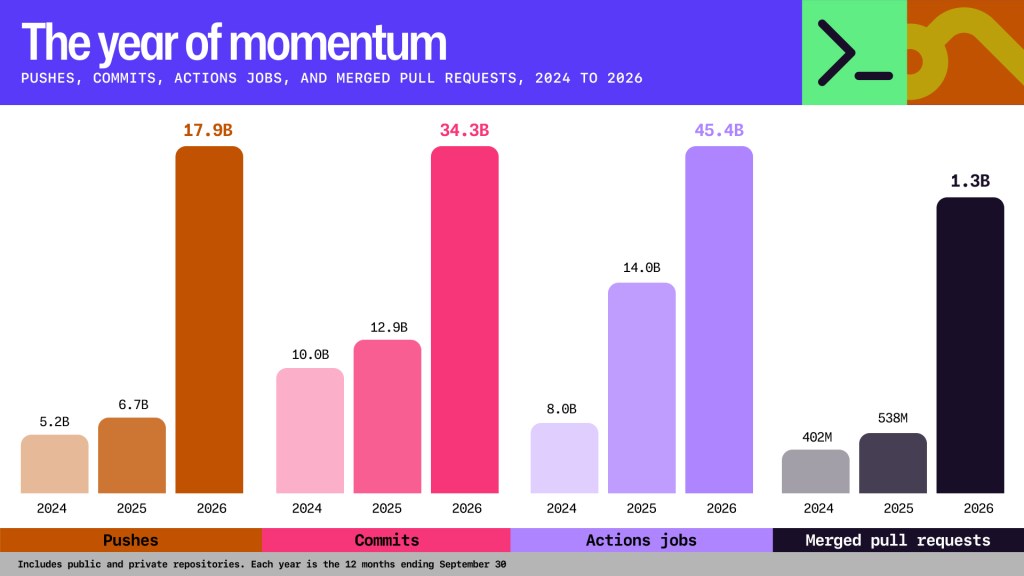
This year was all about momentum. Developers pushed code changes to GitHub 17.9 billion times in the past 12 months, more than 2024 and 2025 combined. Commits across all repo types (public and private) climbed even faster to 34.3 billion, more than three times where they stood two years ago. Merged pull requests more than tripled to 1.3 billion over the same period, an average of 3.5 million a day.
Agents were one of the tools developers leaned on hardest this year, pulling them deeper into daily work. Among repos created this year, the average repo with an agent configuration file logged eight times as many commits as the average new repo without one, sign that individuals and teams building with agents from day one are moving at a markedly different pace.
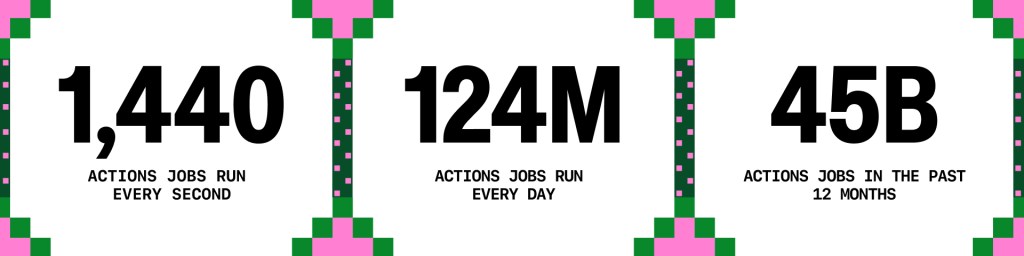
Developers also relied on automations to keep projects moving. GitHub Actions ran a job 1,440 times every second this year. This equals 124 million times a day and is more than three times last year’s total. Developers merged more than 30 million Dependabot pull requests to keep dependencies current and reduce the use of known vulnerabilities, about double 2025’s pace.
Our telemetry shows activity climbing steadily from January, then surging around June, as if developers everywhere saw new possibilities at once. Right around then, a cluster of industry-wide shifts landed: better underlying models, the harnesses and tools built around them, and the agents running on both. Agents moved from single-session tools to persistent ones that could track progress across days and orchestrate other specialized agents. Just as important, agents began making extensive use of the cloud, executing work remotely as well as on local machines.
This momentum is showing up both in brand-new repos and from developers who have been building for years. From June onwards, about 55% of all commits came from brand new repositories. But plenty more commits came from developers who’ve been around a while: developers who pushed code in the past 12 months have been on GitHub for an average of 36 months, and of those who opened a pull request in August, more than 75% pushed code in September. They are also branching out: the average developer now works across 10% more repositories than they did a year ago.
That staying power shows up in open source too. Public contributions soared to 2.5 billion in 2026, more than double last year’s total (1.12 billion). Behind those numbers are developers who keep showing up, like @kinlane, who made more than 1 million contributions across his public repositories using agentic workflows to keep a machine-readable catalog of public API information current. Another example is @kim-em, who made more than 178,000 contributions while maintaining mathlib, which is a community library of computer-checked mathematics. @andig, a maintainer of the open source EV charging controller and home energy management system evcc, contributed over 21,000 times.
These are just a few examples of the work millions of developers do every day. To all the developers doing work like this and beyond: we see you, and we’re glad you’re building.
Developers are building from more places
Behind every number in this report is a developer. GitHub now serves more than 225 million of them, and the community is growing around the globe. The United States (38.3 million) and India (32 million) remain the two largest developer communities, and each added more than 10 million developers this year. Brazil added 3.28 million developers on GitHub this year, the third most of any country.
| Country | Total number of developers on GitHub in Sept. 2026 |
|---|---|
| United States | 38.3 M |
| India | 32.0 M |
| China | 12.4 M |
| Brazil | 10.2 M |
| Japan | 7.15 M |
| United Kingdom | 6.47 M |
| Indonesia | 6.34 M |
| Germany | 6.30 M |
| Russia | 5.07 M |
| France | 4.75 M |
Last year, we projected that India would reach 57.5 million developers by 2030 and the United States 54.7 million. One year into that five-year window, every country in our projections has already closed at least a fifth of the distance to its own 2030 figure. The United States has closed 38.6%, and India 28.3%.
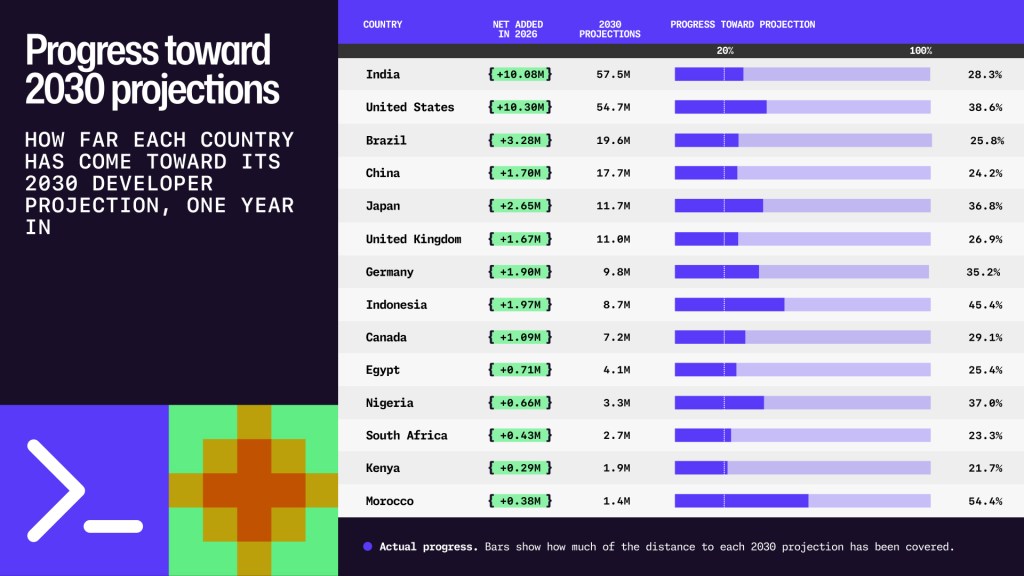
The same momentum shows up across regions, each with its own local context:
| Region | Growth driver | Market context |
|---|---|---|
| Americas | Fintech and digital payments | • Brazil: mature, fast-growing fintech sector • Canada: steady AI and software investment |
| EMEA | AI adoption in manufacturing and startups. Fast-growing developer community in Africa | • Morocco: fintech and startup scene • Germany: enterprise AI adoption across its industrial heartland • France and Spain: AI and deep-tech startups • Kenya, Nigeria, South Africa: fintech, agritech, and coding bootcamps |
| APAC | Government investment in AI infrastructure and talent | • Indonesia: booming digital economy • Japan: AI infrastructure investment • South Korea: government-backed AI talent programs • Australia: AI, machine learning, and data skills |
One year in, growth is strong against last year’s projection, and projecting the next five years is getting harder. We ran more than 40 forecasting models forward to 2031, time-series and regression models built on historical sign-up and usage data, each assuming a different pace of growth. About half call for “extreme” growth, with developer counts on GitHub more than tripling by 2031. Just under half call for “substantial” growth, doubling to tripling. Only three models expect anything close to modest, under 2x growth.
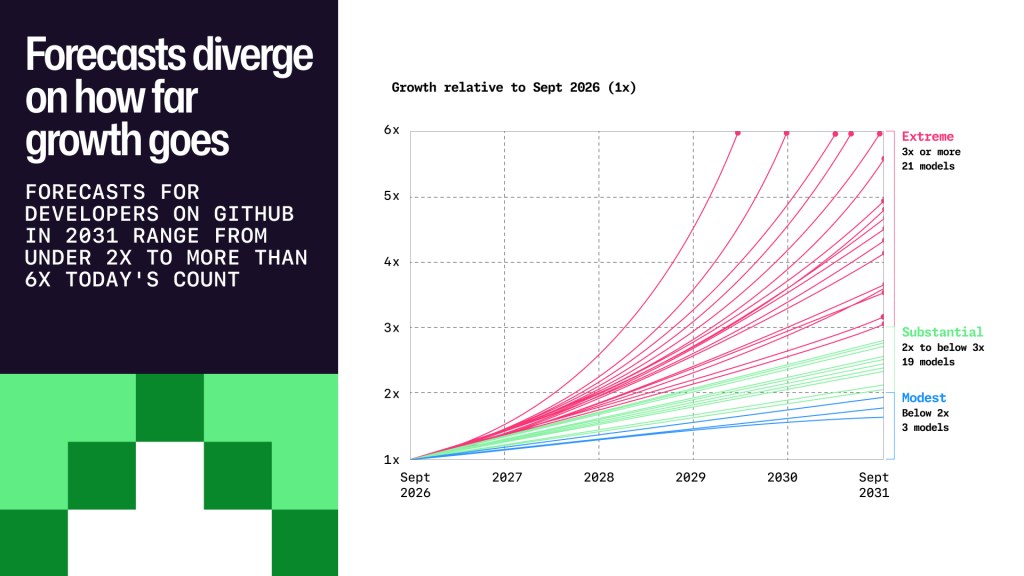
Forecasts are estimates, and a spread this wide shows how much the 2026 surge widened what is plausible by 2031. What holds steady is the shape of the trend: a developer community growing in more places at once.
The future is being built everywhere
In past reports, “everywhere” meant more developers and more countries, such as in the context of the top countries contributing code to public repositories:
Top 10 countries by pushes to public repositories, adjusted by profile location
| Rank | Country |
|---|---|
| 1 | United States |
| 2 | India |
| 3 | China |
| 4 | Brazil |
| 5 | Germany |
| 6 | United Kingdom |
| 7 | Korea |
| 8 | France |
| 9 | Japan |
| 10 | Canada |
This year, it also means more fields, including industries we haven’t measured before.
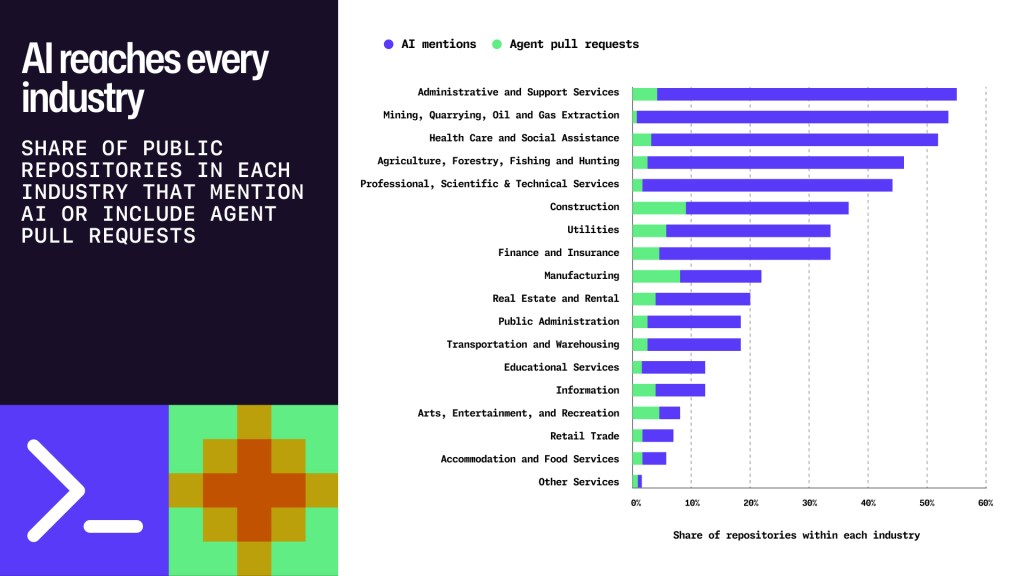
We’re sharing our view of public repositories by industry using the North American Industry Classification System (NAICS), which sorts economic activity into sectors. A language model classified random samples of public repositories created each year from 2022 to 2026, assigning each to the industry it serves based on its name, description, topics, and README. We also tracked two signals: whether a repository mentions AI, and whether an agent opened a pull request against it.
The two signals do not always move together. In administrative and support services, mining, health care, and agriculture, more than four in 10 repositories mention AI, yet agent-opened pull requests are rare, less than 3 percent. Construction breaks that pattern. About a quarter of its repositories mention AI, but about 9 percent have agent-opened pull requests, the highest share of any sector, with manufacturing next.
The same classification shows how each industry’s footprint has shifted since 2022, and sectors well beyond software are climbing. Professional, scientific, and technical services rose from fourth to second place among all industries, behind only information. Agriculture, forestry, fishing and hunting climbed two spots, and finance and insurance and health care and social assistance each moved up one. Against each sector’s own 2022 baseline, mining, quarrying, and oil and gas extraction grew roughly 65 times from a small starting base, administrative and support services and construction 17 to 18 times, and even manufacturing, the slowest of these, almost tripled.
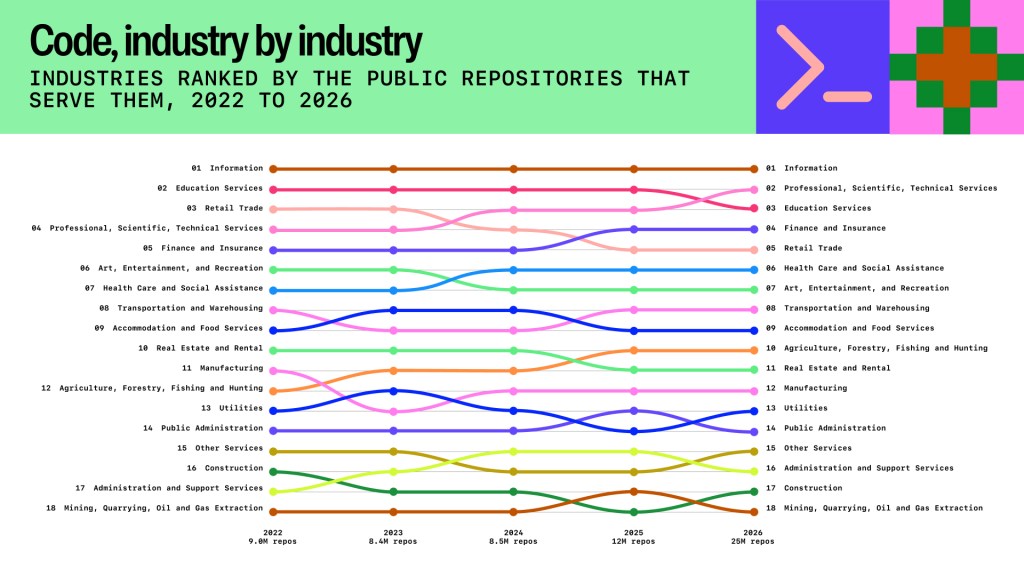
Behind these sector shifts are people who know their fields, now using AI coding agents to build. For example, in manufacturing, a small team built a way to turn a photo of your tools into a custom-fit, 3D-printable drawer organizer. A research lab in health care made it easier for scientists to analyze huge digital scans of tissue samples, the kind pathologists study to understand disease. In Copenhagen, a university lab built a pipeline that classifies video of chickens at play, from frolicking to worm chasing. A University of Waikato energy center built a toolkit that helps industrial plants find heat they can reuse, and Bulgaria’s digital ministry open-sourced a portal where anyone can trace who won a public contract and for how much. For writers, a novelist built a free app that makes a manuscript look like a book as you type. In field after field, the people closest to the problem are building the solution, with agents helping along the way.
Professional, scientific, and technical services, which grew about 5 times over its own 2022 baseline and climbed to second place, is the work of researching, engineering, and advising, and open code has long been part of how that work gets done. In biochemistry, the work behind AlphaFold earned Demis Hassabis and John Jumper a share of the 2024 Nobel Prize in Chemistry. In computer science, Tensor2Tensor accompanied the paper that introduced the Transformer, the architecture behind today’s large language models, “Attention Is All You Need.” In medicine, sars-cov-2-stability held the code and data behind one of the earliest papers on how long the virus survives in the air and on surfaces. In physics, eht-imaging was one of two open-source libraries used to reconstruct the first image of a black hole. A repository has quietly become part of the paper trail behind published research.
Developers are reshaping their workflow
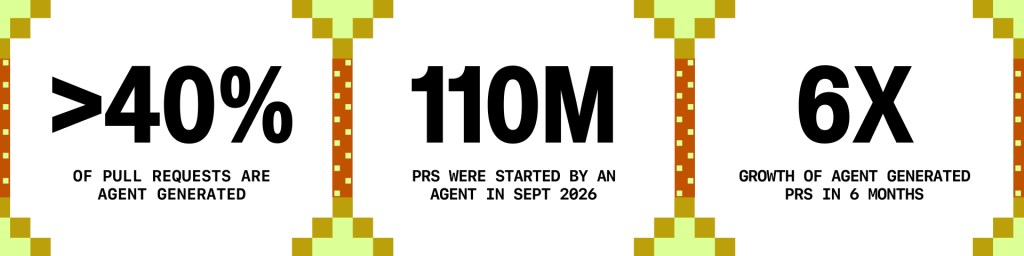
More developers now begin a pull request by specifying what they want and orchestrating the agents that carry it out. By September 2026, more than 40% of pull requests on GitHub started with an agent’s first draft, up from 17% in March. That is 110 million in September alone, about 6x March’s volume.
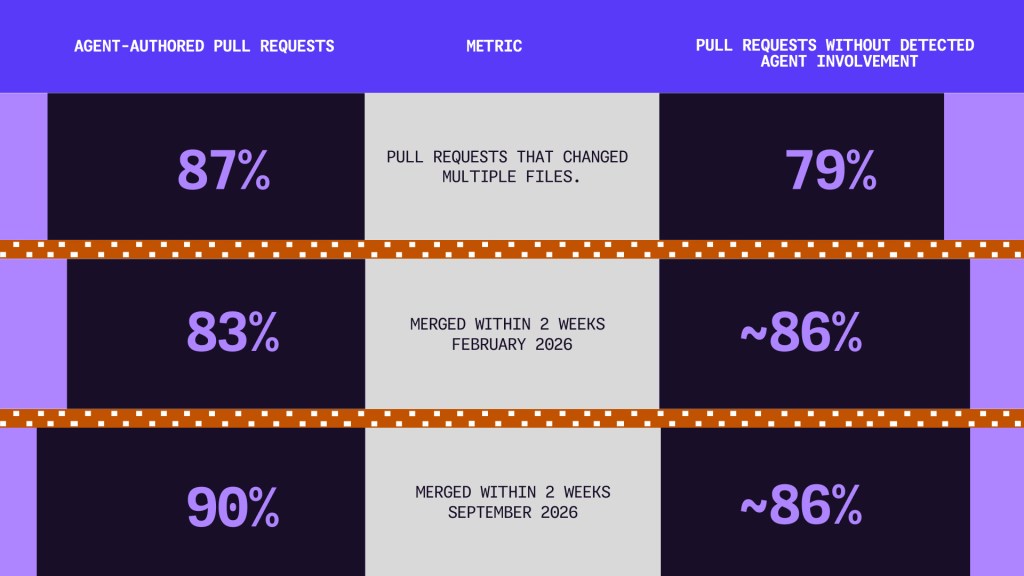
Agent-started pull requests also more often change multiple files: about 87%, compared with 79% of pull requests without detected agent involvement. They are landing quickly too. In February, 83% of agent-involved pull requests merged within two weeks, a touch behind the roughly 86% for pull requests without detected agent involvement. By September, agent pull requests were at 90%, while the comparison group held at about 86%.
Among GitHub Copilot’s monthly active users, 55% now use agentic features, up from 35% a year ago. The steepest growth is in the most hands-off mode. Copilot cloud agent, where a developer assigns a task and an agent works on it independently, grew 230% year over year, against 85% for agent chat. Developers still ask agents questions, and increasingly they hand over whole tasks.
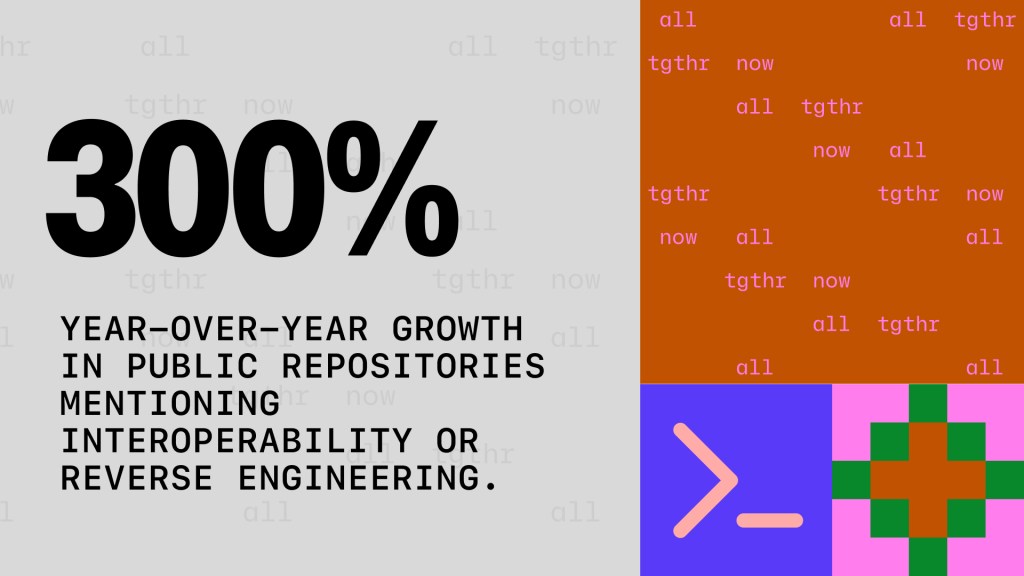
The willingness to delegate is reflected by the kinds of tasks developers are attempting. Public repositories mentioning interoperability or reverse engineering increased more than 300% year over year, from about 30,000 created in 2025 to more than 130,000 in 2026.
Review is where developers shape what comes back, and more tooling is being built for it. Stacked pull requests, which split related work into smaller changes that are easier to review in sequence, launched as a preview on July 30, and more than 264,000 developers had used them by September. Usage of AI-assisted code review and GitHub Advanced Security both grew more than 90% year over year. The platform also helps secure that work: push protection, which screens for exposed secrets such as API keys and passwords, ran 5.8 billion scans this year, nearly four times 2025’s pace. Developers are investing in how they review code.
Model choice moves at developer speed
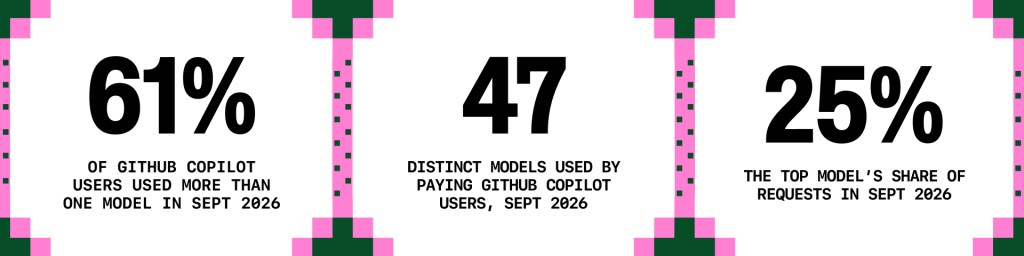
Developers match models to the work they hand to their agents. In September 2026, 61% of GitHub Copilot users who selected a model themselves used more than one model across their sessions, up from 50% four months earlier.
The lineup is growing too: developers on paid GitHub Copilot plans used 29 distinct models in May and 47 in September, and no single model carried more than 25% of requests that month. Some model decisions come down to cost and familiarity. Developers weigh price and functionality against need and may lean toward providers they already trust.
To see how developer choices spread, we grouped the models used in GitHub Copilot by what they are built for: deep reasoning and planning, general purpose, and fast and lightweight. We then looked at where requests went, counting only activity where a developer explicitly selected a model. That leaves out cases where GitHub Copilot picks the model (auto model selection), GitHub and Microsoft staff usage, background utility models, duplicate requests used for monitoring and testing, and requests made with a developer’s own API key.
We found that out of every 100 developer-selected requests, 38 went to general purpose models, 37 to deep reasoning and planning models, and 25 to fast and lightweight models. Developers spread their choices across models and functionality, and about 25% of requests go to a fast model.
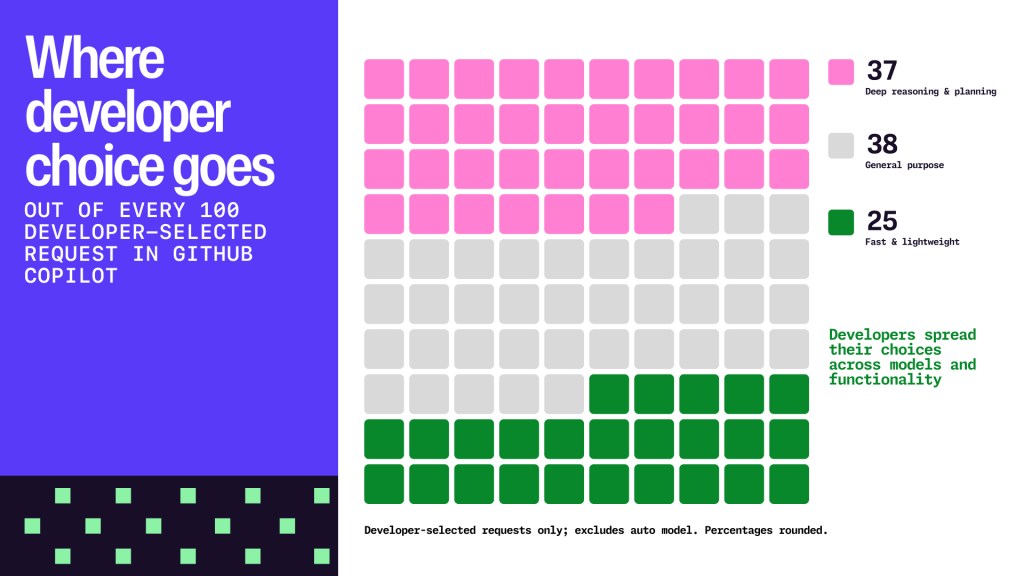
To see how those choices shift, we looked at them as a time series over the past three months, tracking request share alongside how many developers tried each model and how many kept coming back. Three patterns stand out:
- New releases are used heavily before most developers have tried them. In their first weeks, most new models take a larger share of requests than the portion of developers who have tried them. Early adopters use a model heavily before the rest follow.
- Developers keep a model in rotation after leaning on it less. When a model’s share of requests falls, the share of developers still using it falls more slowly
- Developers blend kinds of models. Requests spread across all three groups, and few developers stay with any one kind for long.
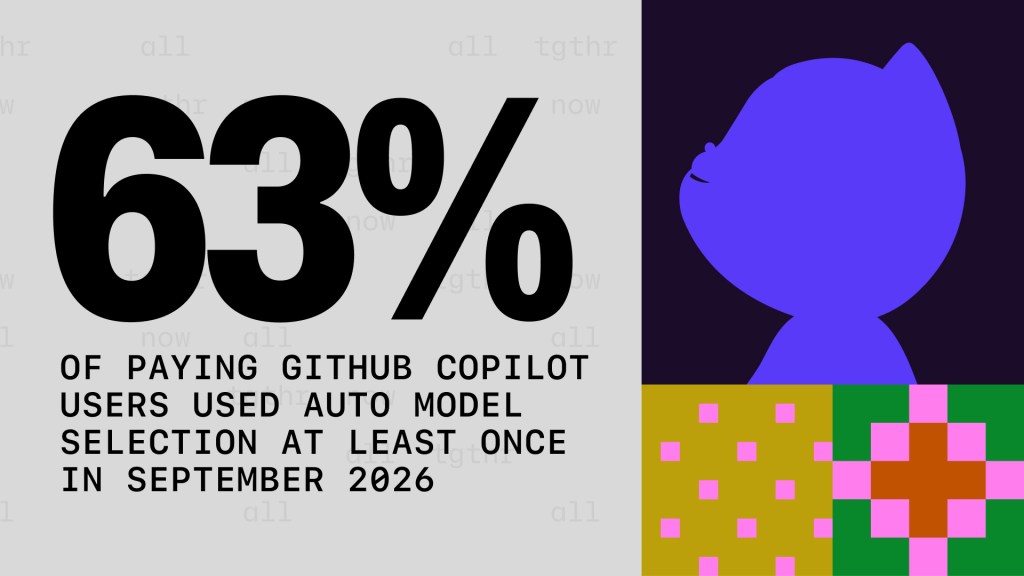
Taken together, the spread across kinds of models points to a lot of choosing: a lineup that keeps growing, a best fit that shifts from one task to the next, and all three kinds of models held in rotation. Many developers also let GitHub Copilot do some of it. In September 2026, 63% of paying GitHub Copilot developers used auto model selection at least once, letting Copilot pick the model for the task.
Planning, implementing, and checking a change each place different demands on a model, in capability, speed, and cost. Project HydraFusion, began as a research preview of model orchestration, matching models to each step of that work. In the CLI and the GitHub Copilot app, it routed almost 60,000 sessions. That work is now generally available as GitHub Copilot Fusion, which brings model orchestration together with auto model selection and chooses the right model for each step behind the scenes.
Language choice has new influence
Language choice has long reflected what developers want to build, what their teams know, and what existing systems require. This year’s data raises the question of whether a fourth influence is emerging: the language an agent picks when a developer doesn’t specify one.
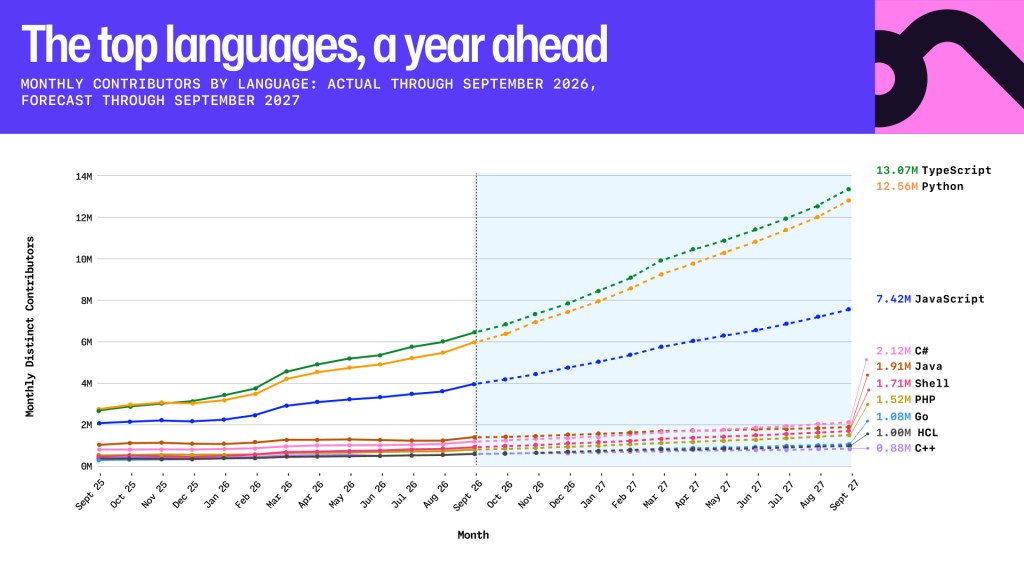
Last year, we reported that TypeScript had overtaken Python and JavaScript to become the most used language on GitHub by contributors. That order held in 2026, with TypeScript first, Python second, and JavaScript third. The pace picked up. From September 2025 to September 2026, TypeScript added 3.62 million monthly contributors, Python 3.23 million, and JavaScript 1.82 million, the largest gains among the top 10 languages. Rust grew fastest by percentage among the top languages, doubling in the past year.
Our forecasts extend recent trends: TypeScript and Python near 13 million monthly contributors each by September 2027, JavaScript at 7.4 million, and every other language in the top 10 below about 2.2 million.
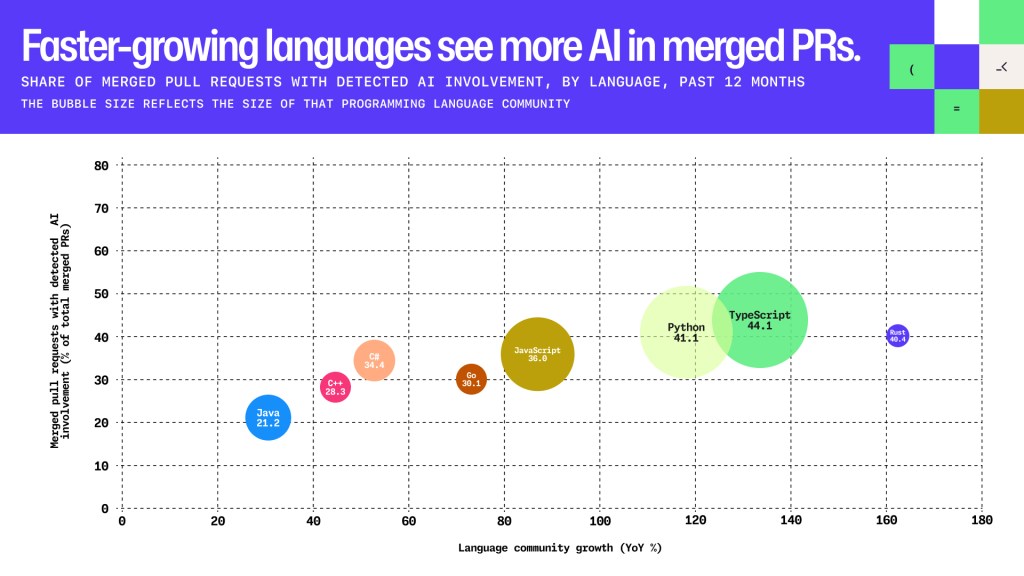
The languages growing fastest are also where AI shows up most. We charted each language’s community growth over the past year against the share of its merged pull requests with detected AI involvement, with bubbles roughly sized to show the size of each language’s community. TypeScript, Python, and Rust, the fastest-growing communities, have the highest shares, about 40% to 44% of merged pull requests. Java, C#, and C++ sit lower, between about 21% and 34%, though AI shows up in more than one in five merged pull requests in every language shown.
The repository data adds another angle. Among repositories created in 2026, TypeScript was the primary language in 35% of those with an observed agent signal, compared to 24% without one. For repositories created before 2026, the gap was similar: 27% with an agent signal, versus 17% without. That suggests developers who work with agents gravitate toward languages where agent output is easier to check. Developers who know exactly what they want still specify the language. But when they leave the choice open, agents appear to favor a narrower set of languages, TypeScript chief among them.
What is capturing developer attention
This year, we split the fastest-growing and most-engaged projects on GitHub into two groups: community and independent repositories, and single-vendor or product-led ones. Community and independent projects are foundation-governed, broadly maintained, or led by an individual without a clear commercial sponsor. Single-vendor and product-led projects are open source or source-available and often take substantial community contributions, but strategic control sits with one company.
Read together, the two lists show a division of labor. The community side is mostly the foundation underneath everything else: inference engines like vLLM, SGLang, and llama.cpp, frameworks like PyTorch, languages and runtimes like Rust and CPython, and platforms like Home Assistant and Godot. The vendor side is mostly the tools developers work with directly: coding agents, editors, and the orchestration around them. Contributors are showing up for both layers. The growth list also includes places built to welcome newcomers, like first-contributions and is-a-dev/register, where many developers make their first pull request.
This year’s fastest-growing repositories by contributors
| Rank | Community / independent | Single vendor / product-led |
|---|---|---|
| 1 | farion1231/cc-switch | Anthropic: anthropics/claude-code |
| 2 | punkpeye/awesome-mcp-servers | OpenAI: openai/codex |
| 3 | Omacom Foundation: omacom/omarchy | Anomaly: anomalyco/opencode |
| 4 | firstcontributions/first-contributions | Microsoft: microsoft/vscode |
| 5 | ggml-org/llama.cpp | GitHub: github/copilot-cli |
| 6 | Eclipse Foundation: EclipseFdn/open-vsx.org | Zed Industries: zed-industries/zed |
| 7 | sgl-project/sglang | Google: google-gemini/gemini-cli |
| 8 | vllm-project/vllm | BerriAI: BerriAI/litellm |
| 9 | imputnet/helium | microsoft/winget-pkgs |
| 10 | vllm-project/vllm-ascend | Kilo-Org/kilocode |
The most-engaged open-source repositories
| Rank | Community / independent | Single vendor / product-led |
|---|---|---|
| 1 | OpenClaw Foundation: openclaw/openclaw | Nous Research: NousResearch/hermes-agent |
| 2 | vllm-project/vllm | Anomaly: anomalyco/opencode |
| 3 | ggml-org/llama.cpp | Earendil: earendil-works/pi |
| 4 | Omacom Foundation: omacom/omarchy | Stably AI: stablyai/orca |
| 5 | farion1231/cc-switch | Ping: pingdotgg/t3code |
| 6 | sgl-project/sglang | Microsoft: microsoft/vscode |
| 7 | PyTorch Foundation: pytorch/pytorch | Graphify Labs: Graphify-Labs/graphify |
| 8 | Rust Foundation: rust-lang/rust | Paperclip AI: paperclipai/paperclip |
| 9 | Open Home Foundation: home-assistant/core | BerriAI: BerriAI/litellm |
| 10 | Python Software Foundation: python/cpython | can1357/oh-my-pi |
What doesn’t change
As part of our research this year, we also tracked the emoji developers used most in their repositories. Across every industry we looked at, the rocket 🚀 topped the list, by a wide margin. A fitting symbol for a year of momentum. Developers on GitHub covered more ground this year: more code, more countries, and more industries than we’ve ever measured. None of that activity changes who decides what the code should do. Someone still has to come up with the idea, whether it’s software that assesses earthquake risk, an open record of how online services change their terms and privacy policies, or an agent skill that makes an AI answer like a caveman to save on words. And someone still has to decide whether it works, whether it belongs, and whether it’s good.
What did change is how much easier it is to take an idea from a weekend thought to something real.
The tools will keep changing, and new industries will keep showing up in places we didn’t expect. What a developer chooses to build, and who they build it for, is still theirs to decide. Rocket emoji and all.
Glossary
- Agent configuration file: A repository file that sets up or directs an AI coding agent. Also called an AI configuration file or agentic file. Repositories without one may still use AI.
- Agent signal: An observed sign of agent involvement in telemetry, such as an agent-opened pull request. It is a floor, since not all agent use may be detected.
- Agent-started pull request: A pull request whose first draft came from a coding agent that we can detect.
- Auto model selection: A GitHub Copilot setting where Copilot picks the model for the task.
- Commit: A saved snapshot of changes to a repository.
- Contributions: Activity events: commenting on a commit, issue, pull request, or discussion; creating a gist, issue, pull request, or discussion; pushing code; and reviewing a pull request. Each push counts once, however many commits it holds. Open-source contributions are contributions to public and open source repositories.
- Contributors: GitHub users with at least one contribution in the period.
- Copilot cloud agent: A GitHub Copilot feature where a developer assigns a task and an agent works on it independently.
- Dependabot: GitHub’s automated tool that finds outdated or vulnerable dependencies and opens pull requests to update them.
- Developer-selected request: A model request where we proxied the developer chose the model. It excludes auto model selection, staff usage, duplicate monitoring and testing requests, background utility models, and requests made with a developer’s own API key.
- GitHub Actions job: A single unit of work in a GitHub Actions workflow.
- GitHub Advanced Security: GitHub’s suite of application security features, including code scanning, secret scanning, and dependency review.
- NAICS: The North American Industry Classification System, the standard sector taxonomy used this year to classify public repositories by industry.
- Project HydraFusion: A GitHub research preview of model orchestration, which plans a task across models, such as one drafting, another reviewing, and a more capable one stepping in when needed. Now generally available as GitHub Copilot Fusion.
- Push: Sending saved changes to GitHub. One push can carry many commits.
- Stacked pull requests: A review workflow that splits related work into a sequence of smaller pull requests that are reviewed in order.
Methodology
- Scope and window. The Octoverse year runs October 1, 2025 to September 30, 2026, inclusive. Unless noted, metrics include public and private repositories. Industry, open-source contribution, and open-source project figures are public only. Prior years: 2024 and 2025 figures are recalculated on the same definitions and window, so they may differ from earlier reports, which covered public activity and a September 1 to August 31 window.
- Pushes, commits, and contributions. A push sends one or more commits to GitHub. Contributions count each push once, so commit totals can exceed contribution totals. Actions are counted in jobs, not minutes. Open-source contributions (2.5 billion) are public.
- Filtering. Contributor and contribution counts exclude spam-flagged accounts, staff, and bots where identifiable.
- Geography and projections. Developers are mapped to countries by self-reported location, with a 100-developer publication threshold. Octoverse 2025 published 2030 totals, not annual targets. Progress is net developers added from September 2025 to September 2026 as a share of the distance from each country’s published 2025 count to its 2030 projection.
- Languages. Contributors are distinct accounts each month that took part through pushes, pull requests, issues, reviews, or comments, attributed to each repository’s primary language (Linguist). An account can count in several languages. This follows the Octoverse 2025 method. Forecasts cover the top 10 languages by average monthly participation and project to September 2027 (mean shown).
- The language bubble chart compares growth in monthly participating accounts between September 2025 and September 2026 with the share of merged pull requests with detected AI involvement. Bubble size reflects community size.
- Top countries by pushes to public repositories, adjusted by profile location. Pushes from each country were summed across the Octoverse year. To adjust for biases caused by VPN usage, LLM classification was used to extract the ISO 3166-1 alpha-2 code from the profiles of GitHub users who contributed pushes during this period, which were then used to construct ratios of ISO 3166-1 alpha-2 codes based on profile location vs. ISO 3166-1 alpha-2 codes based on IP address. These ratios were then used to weight the pushes from each country.
- Industry. Public repositories created 2022 to 2026 were sorted into NAICS sectors by a fine-tuned multilingual embedding model using name, description, topics, and README, from random samples per year. AI mentions and agent-opened pull requests (detectable agents only) were flagged as separate signals. Sector and AI-mention shares can be related because both read the same text. Shares are estimates.
- Open-source rankings. Repositories are classed as community or single-vendor by who holds strategic control. “Fastest-growing” ranks by the absolute year-over-year increase in distinct contributing accounts. “Most engaged” blends a repository’s rankings for stars, forks, and distinct pull request and issue creators. Forked repositories are excluded from both lists.
- Model choice. Figures cover GitHub Copilot and count developer-selected requests only. They exclude auto model selection, staff usage, duplicate monitoring requests, background utility models, and requests made with a developer’s own API key. Each model needs at least 1,000 weekly active users to count. Models are grouped by what they are built for, with examples listed alphabetically by provider:
- Deep reasoning and planning: Claude Opus 5.5, GPT 5.5.
- General purpose: Claude Sonnet 5, Grok 4.7, GPT 6.1 Sol.
- Fast and lightweight: Claude Haiku 5.5, Gemini 3.8 Flash, GPT 6 Luna.
- Figures describe observed use, not model quality. Trend observations use weekly data from July 14 to October 13, 2026.
- Request share is the share of all qualifying requests per model group in a 7-day period ending October 13, 2026.
- Interoperability. Counts public repositories created each year whose name, description, topics, or README mention interoperability or reverse engineering, or related terms, such as clean room implementation, drop-in replacement, or protocol re-implementation.
- Forecasts. We ran 43 time-series and regression models on historical GitHub data, sign-ups, product usage, and market sizing, projecting developers on GitHub to September 2031 relative to September 2026. Outcomes group as 3x or more (21 models), 2x to under 3x (19), and under 2x (3). Octoverse 2025 used five models. No forecast is perfectly accurate.
The post Octoverse: Commits, pushes, reach new highs in 2026 as developers build with agents appeared first on The GitHub Blog.
Pennsylvania, USA
October is Cybersecurity Awareness Month, and it’s a good time to think about how much the world has changed for chief information security officers (CISOs) in the last 12 months.
A year ago, we thought we were already in the thick of AI and starting to understand it. Since then, agents have spread across the enterprise faster than most organizations anticipated. According to our Work Trend Index Annual Report, the number of active agents in the Microsoft 365 ecosystem grew 15-fold year over year and 18-fold in large enterprises. Employees are building and deploying AI systems that can access company data, interact with applications, and take actions on their behalf. These systems are built with good intentions, but even well-intentioned agents can introduce risk when access and behavior are not appropriately governed.
At the same time, more people inside our companies are building with AI. Many of them haven’t written code in years, if ever, and they aren’t necessarily thinking about security the way a security team would. That isn’t a criticism. It’s how quickly the technology has expanded who can build and what they can accomplish.
For CISOs, this creates two fundamental shifts. We have to protect an enterprise that increasingly operates through AI and agents. And we have to rethink how we defend that enterprise as attackers use AI to move faster and operate at greater scale. When I talk with CISOs, these are the two challenges I keep coming back to. We need to enable innovation without introducing unmanaged risk, and we need to modernize defense without losing the security fundamentals that still matter.
For builders: Build securely in the agentic era
Cybersecurity awareness has always been about people. This year, it has to include the people building agents. If you’re a developer, a builder, or someone who has just realized that AI can help you design and build things, this part is for you.
Give your agents their own identities. Where supported and appropriate, assign agents governed identities rather than personal or shared credentials. When something goes wrong, you need to know which agent did it and be able to shut it off.
Protect the data your agents touch. If an agent can reach information, assume it will use it. Make sure the right data protections are in place before you connect it. And remember that the agent will not think like you. It doesn’t share your judgment or your sense of what is appropriate. If you give it access to information or systems, it will act on that access, and that can quickly become a problem.
Your CISO wants you to build. They also need to know what’s being built, so they can help you do it safely. The best thing you can do for your security leader is to have the identity and data conversation early, before you build, not after.
For CISOs: Protect the enterprise as agent adoption grows
Your first job is to put guardrails in place so people can innovate carefully, without slowing them down. Good guardrails help teams move faster because they know where the lines are.
Start with observability, and make it deep. You need to know which agents exist, who owns them, what they can reach, and what they’re doing. You can’t protect what you can’t see. Deep observability also means knowing when an agent’s behavior changes, so your team can step in before a small issue becomes a big one.
Then hold people’s feet to the fire on identity and data. These are the two areas where I wouldn’t give any ground. Every agent needs a governed identity with only the access it needs, and the data it can reach needs to be classified and protected. When those two are in place, most other decisions get easier. Here’s how we’re approaching agent governance.
For CISOs: Defending differently
Your second job is to defend differently than you have historically done.
Attackers are using AI to move faster, and our latest Microsoft Digital Defense Report shows how much that is compressing the time defenders have to respond. But defending differently isn’t simply about adopting faster tools. It’s about changing how security teams turn information into action. The more integrated your environment is, the faster you’ll be able to see an attack and respond to it. An attack rarely shows up in just one place. Signals across identity, endpoints, applications, and cloud environments need to come together with threat intelligence and organizational context so defenders can understand what’s happening and respond before an incident escalates. When your tools work together, your team sees the full picture instead of pieces of it. It also requires a security approach built to continuously assess risk, make decisions, and act at the speed threats are developing.
You also need the right threat intelligence and the right partner. Threat intelligence helps organizations understand how threats are changing, which ones matter to their environment, and where to focus their defenses. Working with partners that have visibility across industries and organizations can provide broader context than an individual organization may have on its own. And you’re not going to operate at this speed without agents helping you. The same capabilities that make attacks faster can make defense faster, with agents working alongside your analysts to investigate and respond. That’s why we’re bringing integrated security operations and agentic defense together.
Two jobs, one goal
The pace of change over the last year has been significant, and it is likely to continue. None of this means slowing down. The CISOs I talk with want their companies to innovate. They need to protect the enterprise as it uses AI and the increasing speed of AI-enabled threats.
Prepare for an agent-driven workplace
Explore Work Trend Index insights on the changing role of agents at work and the trends shaping how organizations operate.
If you’re building with AI, bring your security team in early and have the identity and data conversation. If you’re a CISO, focus on those two jobs and make sure you have the right partners for both.
To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.
The post The CISO’s evolving role: Protecting and defending in the agentic era appeared first on Microsoft Security Blog.
Pennsylvania, USA
The PHP security incident is now (almost) old news. The timeline looks something like this: In late August, Wiz Research discovered two serious remote code execution vulnerabilities in PHP called PHP2Shell. They reported the vulnerabilities to the PHP team on August 24, which started working on fixes on September 21. Amazon apparently detected PHP2Shell in the wild on October 17 (four days prior to disclosure). On October 20, details of the two vulnerabilities (CVE-2026-109618 and CVE-2026-109619) were leaked prematurely. The next day, October 21, the PHP team released patches.
If that were the end of the story, it wouldn’t be notable. But the problem goes a lot deeper. Although PHP is no longer fashionable, it runs a huge portion of the public internet. WordPress, Drupal, and Wikimedia run on top of PHP, and people who build on top of these tools are understandably not interested in chasing the latest hot technology. “Choose Boring Technology” is one of my favorite technical essays, and PHP is nothing if not boring. It’s well known and understood, and replacing something so widely used subjects you to a steep learning curve and new bugs and vulnerabilities.
One problem is that PHP has a long history. According to Wiz, the vulnerabilities are present in versions going back to PHP 5.4. The PHP Foundation has released PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35, and said that all instances of PHP need to be updated to one of those releases. Sites that can’t be updated should be taken offline and isolated. Upgrading an ancient PHP installation is a task that’s likely to fall on organizations least capable of undertaking it. There are plenty of ancient WordPress installations that haven’t been updated in years. There were so many fires to put out, and PHP pretty much “just worked”; running an old version wasn’t causing problems, and with so much else to do, why ask for trouble? Unfortunately, choosing boring technology doesn’t mean ignoring updates. And those who decided not to ask for trouble are now in plenty of trouble.
This situation demonstrates the power of the latest foundation models to uncover vulnerabilities. Wiz used Wiz Atlas (its own model), Gemini 4 Argon, and GPT-5.6 Sol to discover the vulnerability, which isn’t a single bug but a combination of several bugs that have been present for years but were obscure enough and apparently harmless enough to escape detection or repair. As Wiz says,
The underlying flaws had been present for decades, but demonstrating their exploitability required an exceptionally complex chain of steps, at the edge of what human researchers could practically achieve. Frontier AI models substantially reduced that barrier, turning a longstanding flaw into an exploit.
That’s the new frontier in security: finding ways to exploit chains of minor, unfixed, and sometimes undiscovered bugs in novel ways. Wiz was working responsibly with the PHP team to repair the vulnerability. The implications of this, however, are far broader than the fix to PHP, or even the thousands of PHP sites that need upgrades and are now vulnerable to attack. This incident shows dramatically how the gap between the discovery of a vulnerability and its exploitation has dropped. Since exploitation began before the RCEs were prematurely leaked, it makes sense to assume that some other organization had access to models capable of discovering the vulnerability. Gemini 4 Argon and GPT-5.6 Sol are publicly available, though with guardrails that limit their usefulness for security research. I’m willing to assume that Wiz had access to the unrestricted version, but I doubt that the PHP team did. There are certainly other models, including open-weight models, that could be used to find vulnerabilities. Regardless of your stance on restricting model capabilities (I think those limitations are more damaging than helpful), it’s clear that Pandora’s box has been opened. No amount of wishful thinking will undo that.
It’s also clear that we—and I mean all of us—rely on a lot of legacy software that isn’t under our control and that no doubt has multiple flaws that can be rolled up into severe vulnerabilities, which aren’t likely to be updated or patched. A vulnerability in the Brotli compression algorithm was just discovered; .NET, PHP, Node.js, and other widely used packages are affected. That strange site where you created an account to buy a clever present that wasn’t available anywhere else—what software is it running, and do they stay up-to-date with patches? Accounts like that can easily leak information. Maybe it’s not running PHP but an equally ancient version of Ruby on Rails, Python’s Django, or Java Server Pages. At least those are still maintained; there are plenty of web frameworks that have been abandoned, and I’m willing to bet that some of them are still in use. Why replace something that works? Because if you don’t, you will eventually be bitten. Using software that’s no longer maintained may give you some security-by-obscurity, but that’s a losing proposition.
Many older open source projects suffer because there are few maintainers. If you look at the timeline carefully, there’s a monthlong gap between the time Wiz reported the vulnerability and the time the PHP team started working with Wiz to fix it. Does that month represent the time this vulnerability took to rise to the top of the queue, as PHP’s security team fought off a horde of sloppy reports? And PHP is in better shape than most projects. There are many open source projects that only have one or two maintainers, and those maintainers are drowning in AI-generated pull requests. That problem obviously becomes much worse when dealing with a complex vulnerability; the maintainers don’t have the time or the access to unrestricted frontier models, let alone the funds to pay for access to the models.
It will be weeks or months before we know how much damage PHP2Shell has done. We don’t know what the costs will be to sites that won’t or can’t update. The PHP Foundation is lucky to have a dedicated security team that was able to provide patches a day after the vulnerability was prematurely announced. Beyond PHP, we have to realize that PHP2Shell gives us a realistic look into a future in which developers and maintainers struggle to maintain software that has been compromised by exploits chaining together flaws that have been latent for many years. As someone somewhere said on the internet recently, “It’s embarrassing how much bad software we’ve written over the years.” Yes. We’re at an inflection point, and we’re starting to pay the price.
Pennsylvania, USA
Next Page of Stories