It’s about time for Meta Connect, the company’s annual product launch event. This year, given the company’s major focus on AI and wearables like smart glasses, it seems likely that we’ll see updates from CEO Mark Zuckerberg and his team on those categories. The company has been facing significant scrutiny because of how some users have been covertly recording other people using the glasses, meaning that one of the biggest announcements of the show could be its rumored camera-free pair.
Connect has also traditionally been a venue for updates on Meta’s VR hardware and software. While the company has scaled back its VR ambitions, a recent leak seemingly revealing some kind of unannounced mixed reality glasses could indicate that Meta will show off new immersive headwear technology during the event.
Zuckerberg’s keynote is scheduled to begin at 7PM ET / 4PM PT on Wednesday, September 23rd. Follow along with all of our coverage right here.
Microsoft is launching a second generation of its Surface Mouse next month that includes haptic feedback support. The Surface Mouse also has a customizable action button for the first time, which is primarily designed for quick access to Copilot (of course), but can be configured to work with other shortcuts from the Surface app.
"Its haptic feedback adds a small, purposeful physical response to the moment you usually only see on a screen: a click registering, a window snapping into place or an object aligning just right," says Brett Ostrum, corporate vice president of Surface Devices. "It is subtle by design, but noticeable within seconds …
A new AI safety framework for U.S. schools prohibits student and educator data from being used for AI model training while establishing requirements for human oversight, transparency, privacy, and accountability from participating technology providers.
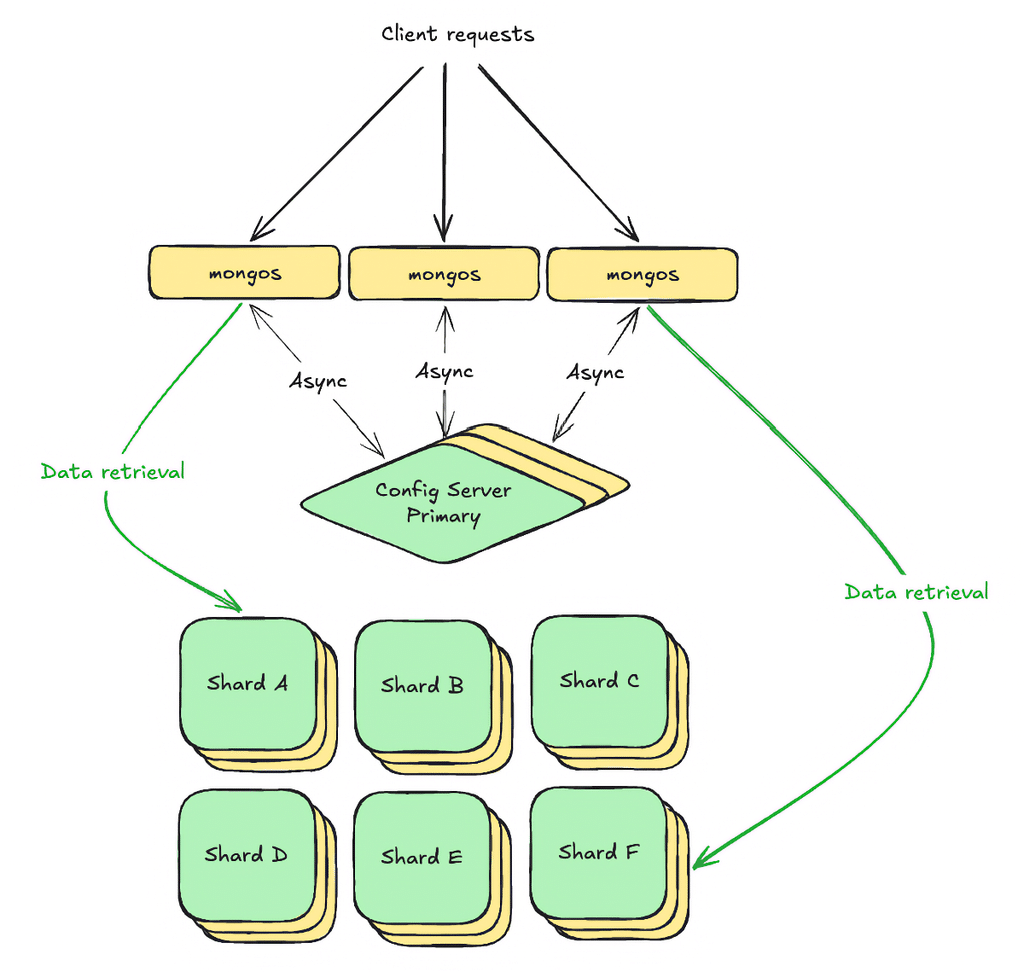
When I first encountered MongoDB, I tried to understand it through the database I knew best: PostgreSQL. My journey was a baptism by fire. I was managing a sharded cluster with 20 TB of data and as many as ~55k operations per second, including ~29k writes. The cluster had six shards, each with its own replica set, a config server replica set, and six routers.
To operate that cluster safely, I had to stop treating MongoDB like PostgreSQL and learn how it worked internally.
At one point, while tackling a flow control problem on the stated cluster, an AI model recommended increasing the portion of memory assigned to the WiredTiger cache. At the moment, the recommendation sounded genuine and correct, but I did not know what the model had based its conclusions on. To be completely honest, I didn’t even know how RAM is used by MongoDB. The nail in the coffin was the official docs saying don’t change WiredTiger cache to RAM ratio.
That experience clarified why I wanted to learn the internals. I want/need enough understanding to connect operational advice to a mechanism, identify the evidence it depends on, and decide. This applies whether the advice comes from AI, a colleague, documentation, or my own assumptions.
What happens after a MongoDB client sends a write?
How does that write pass through MongoDB and WiredTiger, and when does it become durable on disk?
And when someone recommends changing a WiredTiger setting, what would have to be true for that recommendation to make sense?
Following one write
When a client sends a write operation to a sharded cluster, the request first reaches a router called mongos. Routers cache data from the config server about chunk – shard placements. Using this data mongos determine which shard owns the relevant data and forward the operation to that shard’s primary node.
Sharded MongoDB cluster
However, this post does not compare replica sets and sharded clusters. Once routing is complete, the same question applies inside every shard.
How does the primary mongod process request, persist it, and replicate it to secondary nodes?
Separation of concern
To answer my question(s), I firstly had to understand where mongod ends and the storage engine WiredTiger begins.
mongod handles client commands, authorization, query execution, transaction coordination, and replication. WiredTiger is the embedded storage engine that stores collection and index data. It provides local transactions, MVCC, caching, compression, journaling, checkpoints, and crash recovery.
MongoDB client
      │ write operation
      ▼
mongos query router
      │ routes to the owning shard
      ▼
shard primary (mongod)
      ├── authorization and command handling
      ├── query parsing and execution
      ├── transaction and session coordination
      ├── replication and oplog coordination
      └── storage-engine API
                  │
                  ▼
             WiredTiger
                  ├── local transactions and MVCC
                  ├── internal cache
                  ├── journal
                  ├── checkpoints
                  └── collection and index data in dbPath
Ok, but how does this come into play? Boundaries are not absolute.
The oplog belongs to MongoDB’s (logical) replication model, but WiredTiger stores it alongside other collection data.
One write, two logs
At this point, I had another question. If MongoDB already has a journal, why does it also need an oplog?
The WiredTiger journal is the closest equivalent to PostgreSQL’s WAL (Write Ahead Log). It records the changes needed to recover one MongoDB member (keep this thought) after a crash. Unlike PostgreSQL’s WAL, MongoDB does not use the journal as its replication stream.
The oplog has a different purpose. It is a capped collection stored in the local database as local.oplog.rs. Secondary members copy its entries and apply them to their own data.
This raises an important consistency question. What prevents MongoDB from committing a document change without its corresponding oplog entry?
Client write path
Data folder
Let’s examine what happens on one node and then additionally complicate the story by adding secondaries.
To understand local durability, I first looked inside the dbPath of a MongoDB member. A simplified listing:
The exact files and their names depend on the MongoDB version and configuration, but these are the main WiredTiger files relevant to this discussion.
The collection-<ident>.wt and index-<ident>.wt files are WiredTiger tables that store collection records and index entries.
MongoDB’s durable catalog maps logical objects, such as a collection namespace, to these storage-engine identifiers. WiredTiger maintains its own metadata in WiredTiger.wt, including its tables, their configuration, and their latest checkpoints.
The small WiredTiger text file identifies the WiredTiger version used to create the database:
WiredTiger
WiredTiger 10.0.2: (November 30, 2021)
WiredTigerHS.wt is the history store. It keeps older committed versions of records needed by MVCC readers, snapshots, etc. WiredTiger removes versions once no active reader or snapshot can require them.
WiredTiger.turtle contains enough metadata to locate and open the latest checkpoint of WiredTiger.wt. It bootstraps the metadata table during startup and recovery.
WiredTiger version string
WiredTiger 10.0.2: (November 30, 2021)
WiredTiger version
major=10,minor=0,patch=2
file:WiredTiger.wt
...
checkpoint_lsn=(2248,16291200)
...
The checkpoint_lsn identifies a position in the WiredTiger journal using a log file number and byte offset. During recovery, WiredTiger opens the last consistent checkpoint and replays later journal records.
The journal/ directory contains those write-ahead log files. They protect changes made after the last checkpoint from being lost during an unexpected shutdown.
Finally, WiredTiger.lock is the file on which WiredTiger acquires a lock to prevent two processes from opening the same database directory simultaneously. The lock state matters, not merely the existence of the file.
The WiredTiger cache
WiredTiger does not modify the collection-*.wt and index-*.wt files directly for every client operation. It first reads the required pages into its internal cache and applies the change there as part of a storage transaction. Modified pages become dirty until WiredTiger reconciles and writes them to disk.
This internal cache keeps uncompressed collection data and is separate from the operating system’s filesystem cache where compressed data is stored.
MongoDB therefore benefits from both caches, WiredTiger and the OS cache.
Giving all available memory to the WiredTiger cache would leave too little memory for the filesystem cache and the rest of mongod and respecting the default, max((availRAM - 1024) x 0.5, 256 MB), is strongly advised by the official docs.
This is already enough to show why “increase the WiredTiger cache” is incomplete advice. A larger cache does not create memory. It transfers memory away from the filesystem cache and other allocations. Whether that trade is useful depends on the workload and the source of the observed pressure.
When the cache approaches its limits, WiredTiger evicts pages to make room. Clean pages can be discarded and read again later. Dirty pages must first be reconciled into an on-disk representation.
A committed change does not have to wait for its dirty page to reach the collection file. The journal supplies durability between checkpoints. This separation is the reason a write can be durable even though its final data page is still dirty in memory.
Recovering after a crash
In case of a crash, WiredTiger starts from the last complete checkpoint. The checkpoint metadata identifies a consistent view of the WiredTiger tables and the journal position associated with it.
WiredTiger then replays the journal records created after that checkpoint. At a high level, recovery combines two inputs:
last complete checkpoint + later durable journal records = recovered local state
Checkpoints and data files
WiredTiger normally creates a checkpoint every (configurable default) 60 seconds. A checkpoint can take longer when there is more dirty data or the storage device is under pressure.
During a checkpoint, WiredTiger writes a point-in-time view of dirty pages to the collection, index, history-store, and metadata files.
WiredTiger transaction
        │
        ├── dirty pages in cache ──checkpoint──▶ .wt data files
        │
        └── journal records ───────────────────▶ journal files

                         crash
                           │
                           ▼
       latest checkpoint + subsequent journal records
                           │
                           ▼
                    recovered state
How the primary records an operation
For an incoming query, mongod will, among other things, determine collection and index changes and construct the oplog logical entry.
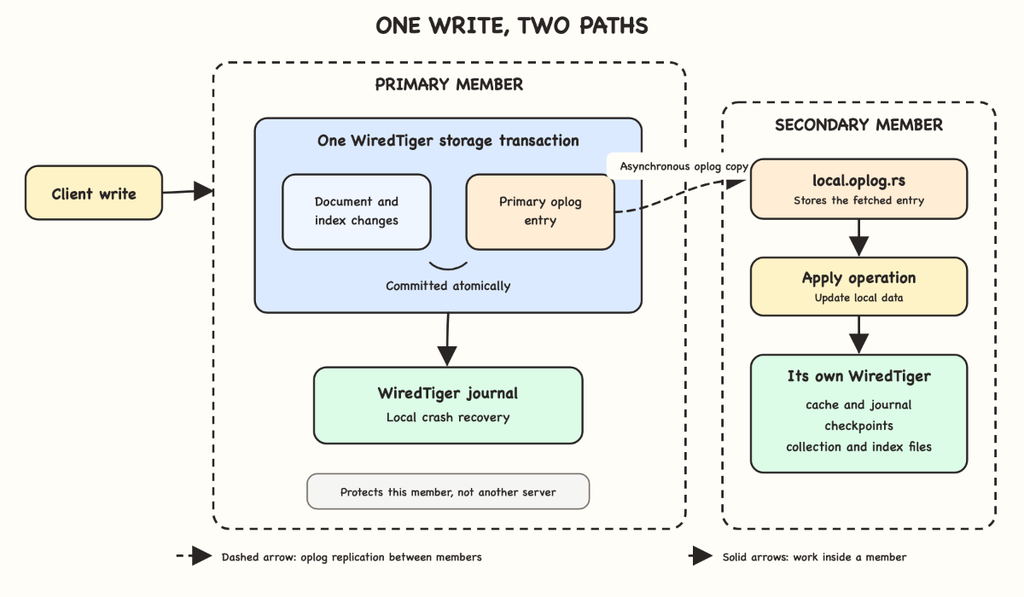
It uses WiredTiger to start/use a transaction and either commits both parts or commits neither. This prevents a successful document change from existing on the primary without an operation (oplog entry) that secondaries can replicate.
The oplog entry contains an operation type, namespace, timestamp, and the data required to reproduce the change. Its timestamp provides an ordering position in the replica-set history. The entry describes a logical insert, update, delete, command, or transaction operation rather than the low-level page modifications stored in the WiredTiger journal.
This is not a complete definition of how oplog and collection changes work, but the important invariant is: the primary commits the replicated data changes together with the oplog records which describe them.
Only the local commit is atomic. Sending or copying the oplog entry across the network is not part of that storage transaction.
How secondaries copy and apply oplog entries
Each secondary continuously selects a sync source and streams newer oplog entries from it. The sync source is often the primary.
The secondary writes fetched entries to its own oplog and then applies the represented operations to its local collections and indexes.
The secondary uses its own WiredTiger instance to apply changes. They modify its cache, produce local journal records, and later become part of its checkpoints.
This is the important distinction and the answer why we can’t just ship primaries *.wt binaries to the secondary.
On two MongoDB servers, these are different files.
Oplog versus journal
Property
Oplog
Journal
Layer
MongoDB
WiredTiger
Purpose
Replication
Crash recovery
Contents
Logical MongoDB operations
Storage-engine recovery records
Consumed by
Secondary nodes
WiredTiger during startup/recovery
Scope
ReplicaSet logical history
One server only
Replicated?
Yes, logically
No
Takeaways
This gives a practical sequence for evaluating operational changes:
Identify which component owns the behavior
Describe the mechanism that is a cause of the problem
Find evidence supporting that mechanism
Clarify what the improvements should be
Measure
Iterate
The technical facts in this article support that way of reasoning:
The WiredTiger journal and the oplog solve different problems. The journal recovers one member; the oplog replicates logical operations between members.
MongoDB commits a replicated data change and its oplog entry in the same local storage transaction on the primary.
A durable change can still exist as a dirty cache page because the journal protects it between checkpoints.
Primaries and secondaries have separate WiredTiger databases, caches, journals, and data files.
Memory assigned to WiredTiger is part of a larger allocation decision that includes the filesystem cache and other process memory.
Why I wanted to understand this
Learning how WiredTiger works does not mean that I can derive every production decision from first principles. It gives me a way to examine a recommendation instead of accepting it because the source sounds confident, and we all know AI can sound like that.
The quality of an (AI) recommendation depends on the question and the evidence supplied to it.
A note on scope– This article records my current understanding of MongoDB and WiredTiger, built through hands-on operation and continued study. I have tried to keep the technical details accurate, but any errors or oversimplifications are mine. MongoDB official docs and WiredTiger documentation should always be consulted for correctness and clarity.
Welcome to the first beta for the 5.2 update! This new version has new effects and also has a big focus on performance, quality-of-life, and infrastructure improvements which prepare for the big 6.0 version that will be coming later. The two biggest changes are the new FileType plugin system and the rewritten high-precision layer rendering engine. There are also 8 new effects and very experimental support for running on Wine (Linux/Mac), which we’ll get to later.
New FileType Plugin System
The original FileType plugin system dates back to 2005 with the v2.5 release. It has withstood the test of time in the sense that it still works and has provided a lot of value for a lot of people, but it has also noticeably aged poorly in ways that have prevented progress in other areas of the app. It was written at a time when .NET itself was just 3 years old and hitting its 2.0 release with generics and 64-bit support. The modern systems used in Paint.NET for component management and isolation were nowhere to be found back then. I had no clue that the project’s longevity would stretch so far into the future, nor that so many plugins would be developed!
The old FileType plugin system is tightly coupled with the Document, Layer, and Surface classes which Paint.NET also uses internally for UI and rendering purposes. They only support the 32-bit BGRA UI8 pixel format and a flat list of bitmap layers. The new FileType system works through interfaces such as IFileTypeDocument<TPixel> and ILayer<TPixel>, along with a rich and strongly-typed imaging framework providing support for a wide variety of pixel formats, pooled bitmap allocation, scaling/interpolation, quantization/dithering, format conversion, color management, and more.
Decoupling the FileType system from the internal classes means that these two systems can now evolve independently, and internal details can be abstracted away from plugins. The new plugin system has been designed to support versioning, meaning that functionality can be added or changed in the programming interfaces that are provided to plugins while maintaining compatibility for plugins that have already been published. New layer types and topologies (e.g. layer folders) can be added without breaking existing plugins, new blend modes can be introduced, and bitmap layers can finally be migrated to a tiled storage system.
Note to plugin authors: In general, plugins should provide pixel data in the image file’s original format without converting it to BGRA32. In other words, let Paint.NET handle the conversion, whether you’re supplying pixels as RGBA64, BGR24, or even an HDR format such as RGBA FP16. Paint.NET will figure out the best conversion for pixel format and color profile handling, and when expanded pixel format support is rolled out your plugin can automatically benefit from it. Note that plugins can query at runtime which pixel formats are supported and which are native, in case they do want to do the conversion themselves for whatever reason.
New Layer Rendering Engine
The old layer rendering engine has its roots going all the way back to the 1.0 release in 2004. Over the years it has migrated from C# to C for performance reasons, and then back to C# once the language and .NET’s JIT had finally caught up to (and surpassed!) the performance of the native C compiler’s code generation. However, it has no SIMD optimizations, it only has 8 bits per channel of precision (“UI8”), and the code was very messy and difficult to make changes to. Working with many layers can result in incorrect colors or banding artifacts as off-by-1 errors accumulate across multiple layers.
With 5.2, this has been completely rewritten and upgraded to use 32-bits of floating-point precision per channel (“FP32”). It is fully optimized for AVX2, AVX512, and even ARM64 NEON thanks to .NET’s new platform-agnostic intrinsics support. Because FP32 uses a lot more memory bandwidth than UI8, many tricks have been employed to optimize that to the point that there is no perceptible performance reduction from previous versions (the old renderer not using any SIMD also helps this comparison). The bottleneck is compute, not memory bandwidth, and performance really shines on CPUs with AVX512 support (e.g. AMD Zen 5) even with standard dual channel memory.
A driving factor behind this change was to prepare for future versions of Paint.NET that will expand pixel format support beyond BGRA UI8. In order to do this in a sane and maintainable manner, having a canonical pixel format became important so that each rendering kernel only needs to be written once. All of the rendering kernels can now operate exclusively on FP32 data, with high-performance format conversion and color transform kernels at the beginning and end of the rendering pipeline. This will make it much easier to add application-level support for RGBA UI16, RGBA FP16, and even RGBA FP32 — the layer rendering engine already supports it, the rest of the app just has to catch up.
New Effects
This release adds 8 new effects. These fill in the Artistic submenu, add some new dithering capabilities, two new distortion effects, and finally support for high-quality halftoning.
Artistic -> Linocut
Simulates a relief printmaking technique where an artist carves an image into a sheet of linoleum, rolls ink onto the raised surface, and then stamps it onto paper or fabric.
Artistic -> Mosaic
This is sort of like an expanded Pixelate effect with optional beveling and grout separation between the “pixels.” There are numerous tiling patterns to choose from.
Artistic -> Pointilism
Simulates a painting technique where an artist applies small, distinct dots of color next to each other to form an image.
Artistic -> Stained Glass
Simulates stained glass. Similar to Distort->Crystalize, but more fleshed out.
Color -> Ordered Dither
Simple ordered dithering patterns from the Bayer, Spiral, Dual Spiral, Blue Noise, and White Noise families.
Distort -> Spherize
Similar to Distort -> Bulge, but produces an actual spherical shape.
Distort -> Waves
A very configurable effect that can produce waves, ripples, spirals, flowers, and other shapes.
Stylize -> Halftone
Simulates physical printing, such as seen in newspapers or comic books, using either CMYK or black-and-white dots. The conversions between RGB and CMYK are color space aware and operate in linear gamma space when appropriate, resulting in a very high quality result.
Examples of each new effect:
Original Linocut Mosaic
Pointilism Stained Glass Ordered Dither
Spherize Waves Halftone
Experimental Wine Support
NOTE: This is not for the faint of heart! It is very much experimental and targeted towards early adopters who aren’t afraid of missing functionality, performance issues, crashes, and wrestling with dependencies.
I’ve recently made major progress getting Paint.NET working on top of Wine, which means Paint.NET can now finally run on Linux and Mac. This was first made available as part of 5.2 Alpha (build 9739) and has now been moved into its own package that you can download from a separate GitHub page with its own Releases page and Issues tracker. Updates will be independent(-ish) of the main Windows packages, at least for the foreseeable future. Each new Windows release will be accompanied by a corresponding Wine release so that it doesn’t fall behind in functionality.
What’s coming in 6.0?
The next big update will introduce a new .PDN file format that will finally enable the ability to add new features to the document and layering systems. High bit-depth pixel formats, new blend modes, and layer folders are planned to be the first use of this. Later on, features such as adjustment layers, text layers, and HDR are also planned (to name just a few).
New: The Eraser tool now supports selecting a Fill pattern in the toolbar.
Improved: When using Image->Resize and “Maintain aspect ratio”, the rounding has been improved to reduce the aspect ratio error
Fixed a bug in the Move tools where shift-clicking on a side handle (north/south/east/west) would sometimes cause it to move on its own by 1-2 pixels.
Fixed: The Colors window will no longer erase the hex field if an invalid character is typed.
Fixed the tooltips in the File -> Open Recent menu by removing them (WinForms is just very buggy here). The directory paths are now shown on a second line of text instead.
Renamed the “Move Selected Pixels” tool to “Move Pixels.”
Fixed an SEHException error message when changing the language.
Updated the DDS FileType Plus bundled plugin. The Save Options dialog will now auto-check or auto-uncheck the checkboxes for enabling mipmaps or cube maps if the image was originally opened from a DDS file.
Download and Install
This build is available via the built-in updater as long as you have opted-in to pre-release updates. From within Settings -> Updates, enable “Also check for pre-release (beta) versions of Paint.NET” and then click on the Check Now button. You can also use the links below to download an offline installer or portable ZIP.
You can also download the installer here (for any supported CPU and OS), which is also where you can find downloads for offline installers, portable ZIPs, and deployable MSIs.
 Log in


 YouTube introduced updates that make the platform smarter, more personal and easier to navigate.