Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164119 stories
·
33 followers

Speculating on Challenges of Spec-Driven Development

1 Share

I’m not fully vested in and convinced by Spec Driven Development. I’ve gotten over 70% of my initial “BDUF” concern and am thinking more clearly.

I thought that it would be a good time for me to list the concerns I have for ongoing SDD. In a few years, we can look back and see if we were able to overcome these challenges:

Documents Age

A document can be correct on the day it is written, and without constantly being updated can stop being true in the future. Policies change, legislation changes, architecture trends change, implementation technologies change, and businesses morph and are disrupted.

Consider how well understood the cellular phone market was in the days with complicated billing systems and physical buttons, before flat monthly payment plans, easy and broad availability of phone models, phone numbers owned by users instead of cellular providers, and the dominance of glass screens.

What is the shelf life of a typical development document? That depends. In the broad and abstract sense, documents my last for a decade or longer. The more detailed a document is, the faster it goes out of date. To generate (or regenerate) code, the document must be very detailed.

This is a concern when our systems are based on code generated from documentation, as we may end up building partially obsolete systems without realizing it.

Documents Accumulate

We need to consider the a typical system these days may be originally built from some design and architecture concepts, written in markdown, Word, or some other format.

Over time, there are separate documents describing desired features or stories, changes in the architecture, changes in the implementation technologies, etc.

How many tickets (representing code changes or stories) does a typical system accumulate over the course of a year? How many documents might we have describing the initial system and all of its changes made by all of its developers over a 5 year period? What about 10 years?

To understand the current state of the system, will an agent have to read a few thousand documents?

When there are many documents, the token cost for reading them becomes prohibitive. More importantly, however, is that the context for tens of thousands of documents is simply not available in agents (so far). The documents will have to be summarised and simplified to fit in memory.

If the agent can hold all the documents, it’s too expensive to use.

If it cannot, then it is working from a partial and overly-abstracted model of the system’s behaviors.

Does the collection become unmanageable?

Documents Disagree with each other

If we collect documents over time, then each document will have the point of view prominent in its time. If you were to write a new task ticket for a 15-year old system, how do you guarantee that the document is 100% aligned and coherent with the original document?

For that matter, consider a company where there are many teams, and the documents (likely tickets or stories) are written by people with different agendas. These may be written at the same time for different developers.

So not only may some of the documents be older and facing obsolescence, they may be written in ways that are accidentally contradictory.

If a person were to read them, perhaps they would recognize some inconsistencies, and maybe they wouldn’t. Would an agent with summaries in limited context recognize the differences?

What if the work is being done in different branches? A lot of people work in separate branches, and some of the work agents do is in git worktrees.

How are the agents supposed to recognize and rationalize the documents? How do you ensure there isn’t drift across codebases, teams, documents, and time?

Documents Disagree with Code

It’s not unusual for the code, to operate correctly and pass tests, to not exactly follow the documentation.

People will say, “Well, that’s because the coders aren’t disciplined”, which is also true of coding agents.

People will say, “Well, then the documentation is wrong”, which is likely also true. It may have the intent, but the mechanism has to vary to meet that intent.

Usually, the documentation is essentially right in some ways, but it’s written before the discovery that happens during coding.

Will an agent always correct all the documentation when it corrects the code? Likely it won’t be allowed. If the code is a temporary incarnation of the documents and the documents are the truth, then why would we let the development agent “corrupt” the documentation with implementation details?

But aren’t implementation details necessary in the document to ensure code generation and regeneration are accurate, complete, and repeatable?

Also, it may be well into implementation that the agent (and human, because we’re both still in the loop) may recognise the codebase has missed crucial domain classes or design opportunities, and refactor the code. While it meets the requirements well, and maybe better than originally planned, it is not what the document says. The document missed the design opportunity, or maybe left it unsaid.

Anything not in the document is not guaranteed to be in a regenerated codebase, nor will it be understood by the specification-writing agents that doesn’t write the code, or the coding agent that doesn’t read all the specs.

Does that mean that the code is not allowed to be better than the document, since it’s not allowed to be different? Or do we let the documents and code diverge – in hopes we might spot it the next time we generate code also?

If the agent can change the design document, then how do we guarantee that it has not drifted from our original intent (especially when documents age and accumulate)?

Design must be easily Recoverable

I’ve gone on record a few times saying that 99% of the time, people are not doing “green field” application development. Almost everyone, almost always, will be working on an existing system. Any system that doesn’t work in “brown field” is niche.

That niche is fun, and interesting, but 99% of the time it’s irrelevant.

Most systems will be between 5 and 20 years old, since it takes a while for a product to find a market and especial to come to dominance in it. If you have a team of paid programmers working in the product, it’s probably not been written by specification-first methods. It probably doesn’t have any of the original design specifications.

In this situation, and all other situations, the source code is the only source of truth that tells you what is happening at runtime. Every other document and every domain expert can tell you what was intended, or wanted. The human developer knows what they had in mind for the code to do.

Only the code actually runs in production.

The domain expert isn’t there. The documents no longer matter. The intention is not what the CPU sees.

It runs the code (the compiled, linked, optimized, code that transited the virtual machine down to machine code – a version of code that may not look all that much like the source code, and certainly not much like the specifications.

All the truth is in the source code, but it may be poorly organized for human understanding.

Agents tend to “shoe horn” functionality into existing code with if statements and flags and primitive variables. The more primitive the code is, the worse they will be about this.

The design degradation we see from agentic development is well documented, so I won’t try to reproduce it here.

But it degrades less if there are good abstractions, good names, good use of the programming language, and good locality of references.

In other word, if the design is good, it is more likely to not muck it up.

Rather than “freeing us” from worrying about good design and code craft, agentic development makes us MORE dependent on well-written code. It needs to have good abstractions, data types, and algorithms. It needs all items to be well named.

If we can’t derive the design from the code, we have a ball of mud that neither humans, LLM agents, nor the combination of the two will be able to safely handle.

If we can derive the design from the code, then why are we keeping all these documents around? Shouldn’t this be code-supportive design rather spec-driven coding?

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

The U.S. Census Bureau and “Super Intelligence”

1 Share

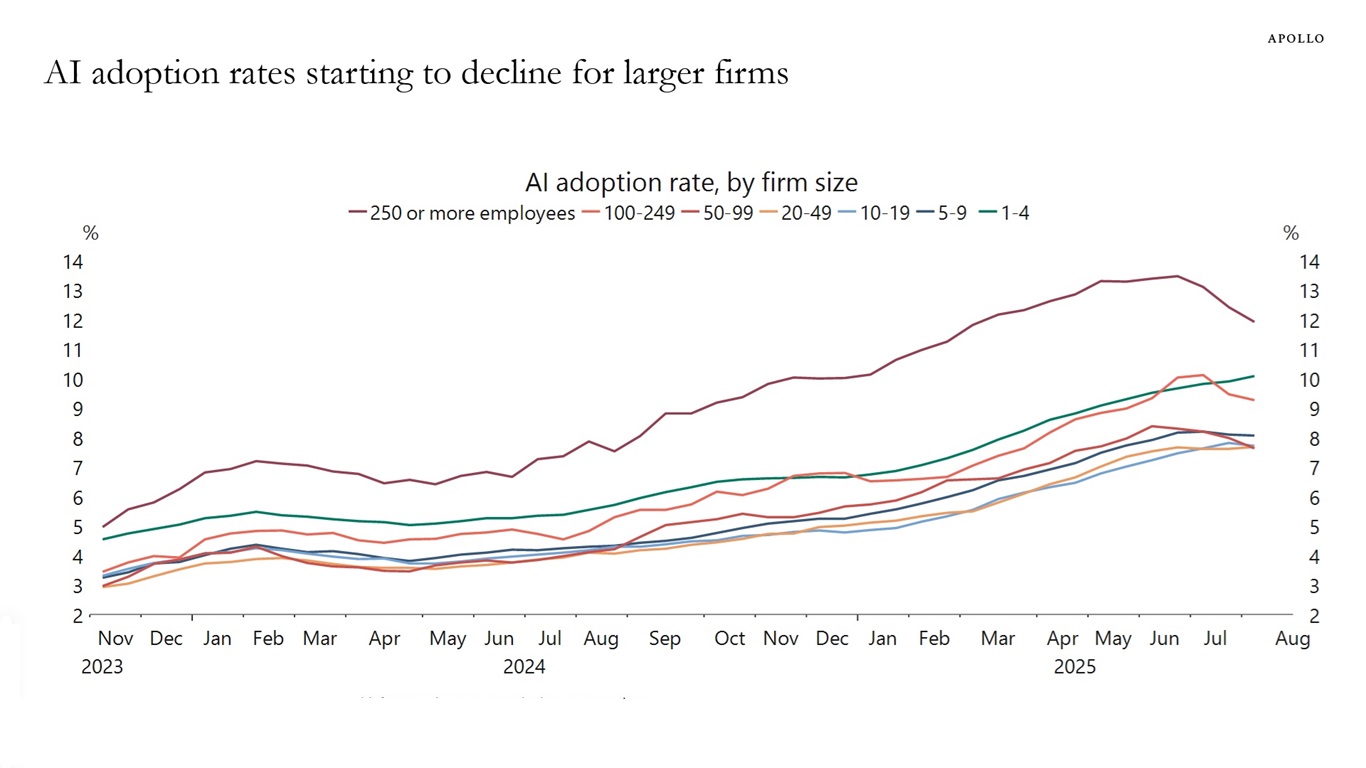
I was reminded today of AI Adoption Rate Trending Down for Large Companies, a chart produced by Apollo Global Management in September 2025, which appeared to show a slowdown in U.S. corporate AI adoption based on numbers collected by the U.S. Census Bureau. At the time I used that chart to demonstrate GPT-5 data analysis, and then to experiment with Claude's new Code Interpreter. I decided to try running those numbers again to see what had changed over the past year, and in doing so learned that the Bureau has fallen foul of Executive Order 14434, aka the asinine Super Intelligence one.

First, the updated chart

Every two weeks the U.S. Census Bureau runs a survey called the Business Trends and Outlook Survey (aka BTOS). Each time it goes to 200,000 businesses out of 1.2 million total - the surveyed group (a "panel") cycles such that an individual business only completes the survey every twelve weeks.

The latest data is published on alternating Thursdays at 10am.

I used the most recent numbers (published October 22, 2026) to create a new version of the AI adoption chart, updated to reflect both the last twelve months and a change that was made to the survey question sent out by the Bureau:

Line chart titled "AI use by U.S. firm size", subtitled "Six-survey trailing average • Share of employer businesses reporting use in the last two weeks" and "Updated with the October 22, 2026 Census release". Seven lines for firm sizes 250+, 100–249, 50–99, 20–49, 10–19, 5–9 and 1–4, on a y-axis from 0% to 45% and an x-axis from Jan 2024 to Oct 2026. Left section, "AI in producing goods or services": all sizes start at 3–5% in late 2023 and climb slowly to 7–13% by September 2025, with 250+ highest. A shaded gap is labeled "Question broadened Nov 2025" and "Series not comparable". Right section, "AI in any business function": all lines restart higher in February 2026 and rise steadily to "250+: 40.7%", "100–249: 33.5%", "50–99: 27.9%", "20–49: 23.8%", "1–4: 23.3%", "10–19: 22.1%", "5–9: 21.1%". Footnotes: "Source: U.S. Census Bureau, Business Trends and Outlook Survey (BTOS). Size groups are numbers of employees." "Method: arithmetic mean of six successive survey estimates, calculated separately for each question wording; no bridging of the break." "Dates use reference-period end, matching the original chart. Latest: Oct 4, 2026 (collected Oct 5–18). First new six-wave average: Jan 25, 2026." "The gap includes the 2025 shutdown and the wait for six observations under the broader question. Survey uncertainty is not displayed."

For comparison, here's that AI adoption chart from last year (my GPT-5 version): AI adoption rates starting to decline for larger firms. A chart of AI adoption rate by firm size. Includes lines for 250+, 100-249, 50-99, 20-49, 10-19, 5-9 and 1-4 sized organizations. Chart starts in November 2023 with percentages ranging from 3 to 5, then all groups grow through August 2025 albeit with the 250+ group having a higher score than the others. That 250+ group peaks in July 2025 at around 14% and then appears to slope slightly downwards to 12% by August. Some of the other lines also start to tip down, though not as much.

In September 2025 the largest (250+ employees) companies answered "yes" around 12% of the time to the question about whether they used AI in "producing goods or services".

Under the new "any business function" wording, by February 2026, those same large companies answered "yes" around 30% of the time, and by October 2026 that had increased to around 40%.

The data in the above chart comes from the "Employment size class" XLSX file, available from here. Here's a copy of the file I used.

You can view the survey document that is sent out to businesses - here's my snapshot copy of that 346KB PDF.

The changing language of the questions

As the chart demonstrates, the question asked by the Bureau changed in a material way on November 17th, 2025. Prior to that date, the question they asked was this (emphasis mine):

In the last two weeks, did this business use Artificial Intelligence (AI) in producing goods or services? (Examples of AI: machine learning, natural language processing, virtual agents, voice recognition, etc.)

On December 3rd, 2025, the Bureau announced a significant change to that question. Here's the replacement:

In the last two weeks, did this business use Artificial Intelligence (AI) in any of its business functions? (Examples of AI: machine learning, natural language processing, virtual agents, voice recognition, etc.)

No more "producing goods or services" - now it's "in any of its business functions"! This means that the answers to the question before and after November 17th are not directly comparable.

From October 19, 2026, they ask about Super Intelligence

When I went looking for the updated question language in the latest XLSX file, I couldn't find it. I found this instead:

In the last two weeks, did this business use Super Intelligence or SI (formerly referred to as Artificial Intelligence or AI) in any of its business functions? (Examples of SI use include: SI-powered data analysis; generative SI for marketing, product design, or coding; virtual SI agents for customer service; SI-powered forecasting or pricing; SI-driven computer vision for quality control, etc.)

The BTOS about page explains what happened:

Beginning with the October 19, 2026 collection, instrument wording was updated due to Executive Order 14434.

The current numbers reflect the old Artificial Intelligence survey wording - the first survey results reflecting the Super Intelligence wording are due for publication on Thursday.

Is this going to affect the survey?

The obvious open question here is whether this wording change is going to affect the survey results.

The businesses answering this survey will have last seen that question twelve weeks ago, when it was still called AI. Hopefully the new language isn't going to confuse them, especially since the survey helpfully spells out "formerly referred to as Artificial Intelligence or AI".

I can't help but laugh at the absurdity of "SI-powered data analysis; generative SI for marketing, product design, or coding; virtual SI agents for customer service" though.

Tags: census, surveys, ai, generative-ai, llms

Read the whole story
alvinashcraft
13 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Stop counting tokens, start counting what ships

1 Share

When a developer gives an AI agent a coding task, the agent does more than answer once. It plans, generates code, runs tests, and repeats the process to correct errors. A single task can use 10 to 50 times more tokens than a basic chat prompt. The more useful the agent becomes, the more calls it makes. With per-token pricing, the workflows creating the most value can also become the most expensive.

The financial pressure is already visible. Uber reportedly exhausted its entire 2026 AI budget by April after expanding its use of Claude Code. GitHub Copilot moved from flat-rate pricing to metered credits. Gartner predicts that AI coding token costs will surpass average developer salaries by 2028.

The natural response is rationing usage caps, seat limits, and approvals before developers launch agents. But blanket limits can restrict the workflows delivering value. They also optimize the wrong number. Cost per token measures consumption, not results. Some spending reflects waste, including retries and runaway loops. Some represents the work of shipping software. A meter cannot distinguish them, and neither can a spending cap.

Measure the software that ships

A better measure is cost per merged pull request: total AI-assisted development cost divided by the number of changes that pass review and are merged. Track rework and defects alongside it so cheaper changes do not conceal lower quality.

If that cost falls as AI usage rises, without compromising quality, developers are converting more consumption into useful software. The question is not how many tokens they use, but how much finished work the investment produces.

Improving that equation requires two changes: reserve expensive inference for tasks that need it, and lower the cost of routine work.

Match the model to the task

Agentic coding does not require the most powerful model at every step. Use a frontier model, or an on-premises flagship when policy requires it, for difficult planning and novel reasoning. Route suitable work, including code generation, test creation, and repeated refactoring, to open-weight models you operate yourself.

A gateway can route requests according to task complexity, data sensitivity, cost, and latency. This reserves premium inference for the moments that justify it rather than applying premium pricing to an entire workflow. Meter the exception, not the workload.

Open-weight models make this division increasingly practical. Software-engineering benchmarks show that leading open-weight models can approach frontier performance on some tasks. That does not establish equivalence across every repository or workflow. Evaluate candidates against your own code, tests, and acceptance criteria before assigning production work.

Change the economics of repeated use

Next, decide who owns the capacity. With rented inference, every call adds to the bill. With owned capacity, most of the cost is committed upfront, so each additional call gets cheaper as usage grows.

The economics are simple: per-token pricing makes heavy use more expensive, while owned capacity becomes more efficient as teams use it more. Ownership is not free, though. Power, operations, maintenance, and depreciation all must be considered. The number that matters is the fully loaded cost per merged pull request.

Owned capacity also delivers a type of value that never appears on an invoice: control over sensitive code. When code generation and testing run on-premises, proprietary code stays inside the enterprise. Only approved planning prompts and governed exceptions go to external models, through a gateway the organization controls. That opens the sensitive repositories where security usually stalls adoption, and where the biggest gains are waiting.

Test the operating model

At HPE, a hybrid AI platform routes routine workloads from more than 150 internal applications to open-weight models running on premises, including on HPE Private Cloud AI. The result: token costs down 30 to 50%.

That is the point of hybrid. With HPE Private Cloud AI, owning your inference does not mean giving up frontier models. Run the volume on capacity you own and let a gateway send the hardest work.

Data also shows that usage, not licensed headcount, drives spend. The top 5% of users generated most of the consumption, and the heaviest used roughly 450 times more than the lightest on the same license. If power users grow from a small minority to half the workforce, monthly spend can rise about 4.4 times with flat headcount. Your mix will differ, which is exactly why you need to measure it.

HPE tracks two metrics and recommends customers do the same. First, it tracks cost per active developer, because averaging across all licenses hides the power users driving spend. Second, it tracks cost per merged pull request, because it connects AI spending to software that ships.

Baseline both costs before changing infrastructure. Then run a complete development cycle on owned capacity. If both metrics do not improve as usage grows, your current model may still be the better choice.

Build for adoption, not rationing

Owned capacity is not for everyone. Low or unpredictable usage favors APIs, with no capital tied up in idle infrastructure. Ownership pays off when sustained demand keeps it busy. Most enterprises will run hybrid: frontier APIs for demanding or intermittent work, owned capacity for repeatable volume. A governed gateway decides what leaves the building, so you get frontier models without giving up sovereignty over your code.

As developers lean harder on coding agents, usage will keep rising. The real choice is whether that growth shows up as a bigger variable-cost bill or as more software shipped on capacity you own. The companies that lead AI-assisted development will not ration adoption to control costs. They will build an operating model where more AI use improves the economics instead of undermining them.

To learn more about HPE Private Cloud AI, please visit HPE.

This content was produced by HPE. It was not written by MIT Technology Review’s editorial staff.

Read the whole story
alvinashcraft
22 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Microsoft Store CLI v0.4.4

1 Share

Changes:

  • 4fa163e Set version to '0.4.4'
  • c4ad18e Update EsrpCodeSigning task to v6 (Node20) (#191)
  • e3606f1 update version to 0.4.4 alpha (#190)
  • 3b3aa5c Block SSRF in listing image downloads and gate test report workflow (#189)
  • c6b796f Bump dorny/test-reporter from 3.0.0 to 3.2.0 (#187)
  • b4d9fd3 Bump actions/upload-artifact from 7.0.1 to 7.0.2 (#188)
  • 5f15f06 Fix Electron test fixture package identities (#186)

This list of changes was auto generated.

Read the whole story
alvinashcraft
49 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

BONUS The Scrum Master's AI Prompt Library With Joshua McDonald

1 Share

BONUS: The Scrum Master's AI Prompt Library, with Joshua McDonald

In this BONUS episode, Joshua McDonald shares how he uses AI in the daily work of a Scrum Master, from team summaries and leadership updates to retrospectives and coaching preparation. The conversation is practical and grounded in one clear warning: AI can give Scrum Masters time back, but it cannot replace their judgment.

When AI Stops Being a Toy and Starts Saving Real Time

"It would have to be when it started to save me about one to two hours per day."


Joshua's turning point came when AI moved from curiosity to practical assistant. He began using tools like Microsoft Copilot to analyze reports, prepare communication, and package updates for different audiences. The value was not that AI did the thinking for him. The value was that it helped him reach useful coaching conversations faster, especially when working with reports on predictability, volatility, and cycle time.

Turning Flow Data Into Better Coaching Conversations

"It was able to pinpoint where the bottlenecks were, and where I should look."


One of Joshua's first high-value AI workflows combined screenshots of team metrics with exported Jira stories. Instead of spending half a day scanning acceptance criteria, transitions, and bottlenecks, he used AI to identify patterns and suggest where to look next. From there, he would ask follow-up questions from the perspective of a Scrum Master, using AI as a sparring partner to prepare coaching talking points before speaking with the team.

AI as a Communication Coach, Not a Replacement for Judgment

"I like to use AI as my coach to help me in my communication style."


Joshua is careful with sensitive communication. When he needs to bring data, feedback, or a difficult pattern to an individual or team, he asks AI to help him test the wording. He might ask how a message could land with someone who has reacted defensively before, or request phrases to avoid. In that sense, AI becomes a preparation space: a place to roleplay, refine tone, and make sure the human conversation starts from care rather than accidental bluntness.

A Weekly AI Workflow for Scrum Masters

"I use it pretty much at everything I create."


Joshua's weekly rhythm includes AI-generated summaries from standups, backlog refinement, and retrospectives. He uses templates that identify who shared which updates, what action items emerged, and what the team should be able to review later. For retrospectives, he keeps a prompt library on a whiteboard, with prompts adapted for Scrum teams, Kanban teams, and team interests. A hiking team might get a Big Bend retrospective; a car enthusiast might get a BMW-themed one. The point is not novelty for its own sake, but creating retrospectives that feel more connected to the people in the room.

The Prompt Library as a Scrum Master Asset

"I save them. I reuse them. I refine them."


Joshua does not treat prompts as throwaway text. He keeps them visible on a whiteboard, labels them by purpose, and refines them over time. That library helps him preserve the structure of useful workflows while adapting the output to the team and context. For Scrum Masters and agile coaches, this is one of the practical takeaways: a prompt library becomes part of the working system, just like a facilitation kit, retrospective catalog, or coaching journal.

Faster Is Not the Same as Better

"I don't lean on it to do critical thinking for me."


Joshua connects AI adoption to a deeper risk: using it to produce more work without asking whether that work matters. He validates AI output, checks the data, and stays responsible for conclusions. AI helps him get to an end point faster, but the Scrum Master still owns the thinking, the interpretation, and the impact on people. That distinction matters when teams are being pushed to adopt AI without clear guidance.

What Scrum Masters Should Try on Monday

"Have it coach you. Say, this is my role. This is what's on my agenda for today."


Joshua's recommended first experiment is simple: do a personal standup with AI. Share what you did yesterday, what you want to do today, and the challenges in front of you. Then ask AI to act as your coach and help you identify focus, priorities, and possible next steps. Within a week, a Scrum Master can see whether this creates more clarity, better communication, and more intentional use of time.

Learning AI Without Waiting for Permission

"Start there with basic AI fundamentals."


For Scrum Masters who are new to AI, Joshua recommends beginning with practical courses on platforms like Udemy, Coursera, or LinkedIn Learning. Then, connect with peers who are already experimenting with prompt creation. The goal is not to become an AI expert overnight. The goal is to understand what AI can support, what it should not replace, and how to build a prompt library that improves your own work.

About Joshua McDonald

Joshua is endlessly curious about better ways of working. He helps teams grow by blending experimentation, creativity, and AI with practical coaching. When a meeting feels routine, he's already testing a new approach to make it more valuable. Energetic and inventive, he turns everyday collaboration into opportunities for team growth.


You can link with Joshua McDonald on LinkedIn.


Download audio: https://traffic.libsyn.com/secure/scrummastertoolbox/20261102_Joshua_McDonald_M.mp3?dest-id=246429
Read the whole story
alvinashcraft
3 hours ago
reply
Pennsylvania, USA
Share this story
Delete

139. Building Software AI Agents Can Actually Work With. Hannes Lowette on Event Sourcing

1 Share

What makes software easier for AI coding agents to understand, maintain, and change? In episode 139 of Betatalks, Rick and Oscar welcome Hannes Lowette to explore event sourcing, domain-driven design, and the architectural choices that help both developers and AI agents work effectively.

Hannes explains how recording meaningful business events—and separating command handlers, projections, and downstream actions—can keep the context of a change small. He shares why this structure could make event-sourced systems a strong fit for AI-assisted software development, while discussing when event sourcing adds value and when it introduces unnecessary complexity.

The conversation covers microservices, modular monoliths, and the pitfalls of choosing architecture based on industry trends rather than business needs and team experience. They also explore AI-assisted legacy code migration, why code quality still matters, and how clear naming, specifications, tests, and Architecture Decision Records (ADRs) support better results.

Beyond the technical discussion, Hannes shares his approach to coaching, knowledge sharing, and conference speaking. Plus, discover how woodworking, a handmade travel guitar with a Visual Studio inlay, and performing with The Linebreakers connect him to the developer community.

An episode for software developers, architects, and technical leads thinking about maintainable systems and the role of AI agents in software engineering.

Follow Betatalks for more conversations about software development, .NET, AI, and software architecture.

About this episode, and Hannes Lowette in particular: you can find Hannes on LinkedIn.

About Betatalks: watch our videos and follow us on Instagram, LinkedIn, and Bluesky. 


Download audio: https://www.buzzsprout.com/1622272/episodes/20008149-139-building-software-ai-agents-can-actually-work-with-hannes-lowette-on-event-sourcing.mp3
Read the whole story
alvinashcraft
3 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories