Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162754 stories
·
33 followers

Coders with Agents Fixing Websites

1 Share

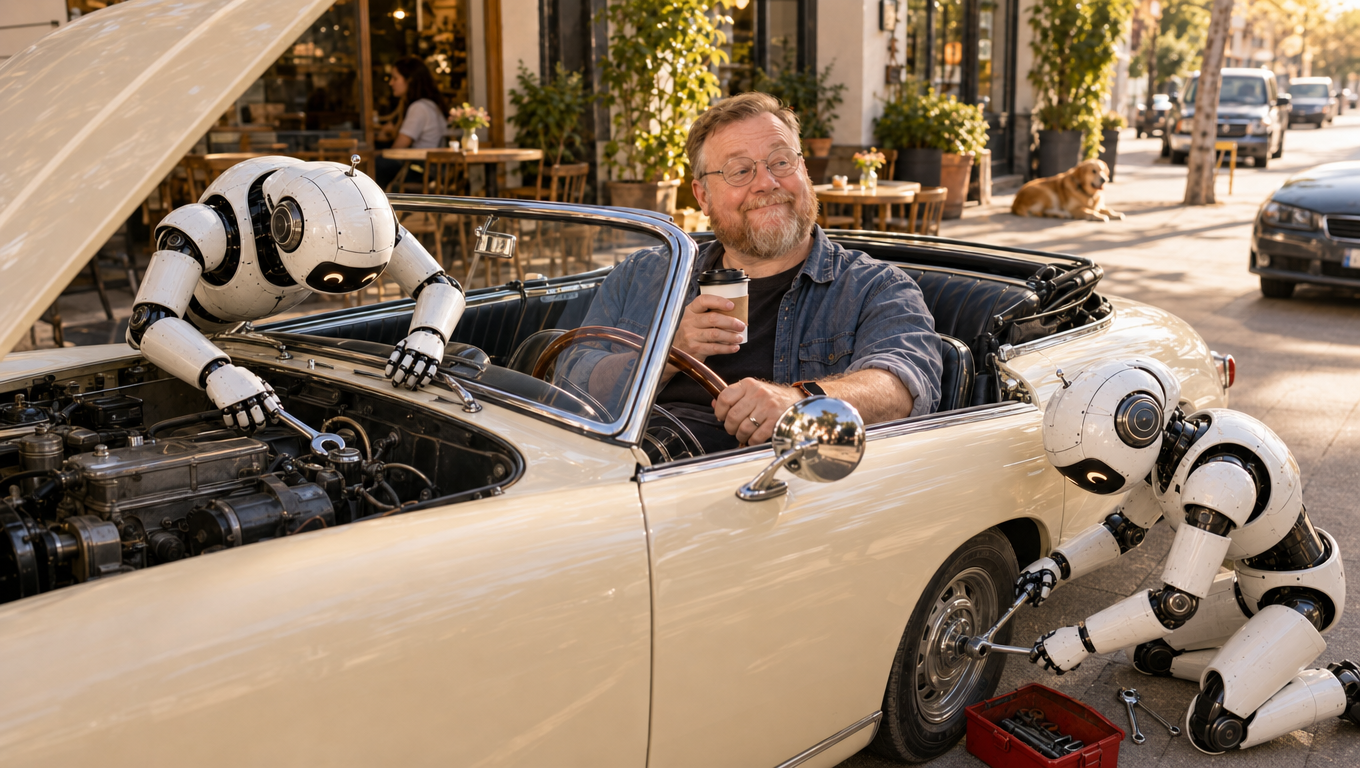
Chris Sells holding coffee in the driver's seat of a vintage convertible while two robot agents repair the car, one under the open hood and one at a wheel beside a toolbox.

This site started in 1995 as a page of links for my students. Since then, I’ve used FrontPage, ASP.NET, SQL Server, a blogging API and Windows Live Writer to keep it going. The history of this site is the history of which tools I wanted to use with it.

In 2015 I moved to Blot because I wanted to write Markdown in whatever editor I felt like. It was a great service when I chose it and it remains so. Blot runs like the wind, and the proprietor, David Merfield, is super responsive. I was keeping my posts in a Dropbox and Blot picked up on changes to publish updates to the site. I enabled features and set styles by editing config and templates online.

However, now that I work with essentially all of the CLI coding agents via Gas City (it supports 16 as I write this), I wanted the whole website in a form that a set of agents and I could work on together. I’d prompt an agent for a change — a new feature, a template change, some CSS updates — look at the result locally and publish it when it was ready.

The result is a site built with Eleventy and hosted on Cloudflare Pages. Because David has so generously provided the Blot runtime as OSS, I was able to start my migration by self-hosting the site, checking that I got it right with pixel-by-pixel checks between the staged and the live site.

Along the way, the agents and I built our own static site generator, which made no sense to me, given the plethora of such tools already available (don’t let those agents push you around!). So I had them build the site with Hugo and with Eleventy using real pages from my blog. I picked Eleventy because it could apply Blot’s typography (small caps and hanging punctuation) as it rendered each page, so the local preview looked just like the real thing.

Once that was working and I was back in control of my site end-to-end, there were new features I wanted to build.

But first, I had three decades of tech debt to address.

I’ve been handing out links to sellsbrothers.com for thirty-one years. Some of them look like /news/showTopic.aspx?ixTopic=1153 from the ASP.NET days, and I still expect them to work (along with all of the other link formats I’d supported over the years).

I also had the agents track down the 404s. Some older posts linked to 75 places on my own site that weren’t there anymore. Most of them were links to news items on the old home page that had long since scrolled off, so now they point at the actual post. A few more needed redirects for old book and feed URLs. That fixed 39 of them. The rest point at pages that were gone long before this move, like the old conference pages under /public/conference.

Chasing down dead links also turned up images that went missing from the old site. We (the agents and I) recovered several full-size originals from the Wayback Machine and other verified sources, stored them with the content and updated the posts to use the local copies. The migration left six old image URLs without a verified original. I can’t fix the entire dead web, but I can keep a few more pieces of my corner of it together.

Finally Fixing “Here”

Before the site could show the beginning of an article as its summary, I used to write a separate little post describing it, with a link labeled “Here” (itself a fix from a previous port). The description would send you to the actual article. Once automatic summaries arrived, those extra posts were unnecessary. Finding and removing them was not a problem. Forwarding the description URL to the real post was not a problem. Moving all of the Disqus comments that had collected on the descriptions… that was a problem.

I wasn’t willing to lose those comments. We saved the Disqus exports and checked which discussions belonged to which pages before changing their associations. Where the destination had no comments of its own, we could display the original discussion there. Where both pages had comments, we used Disqus’s merge process and checked the result. Some destinations needed separate discussions kept accessible rather than folded together. The source content and migration evidence stayed backed up throughout.

The descriptions turned out to hold 731 approved comments and another 37 hidden records. All 768 were preserved, including their authors, dates, replies and moderation state.

Inline HTML Style

Before I moved to Markdown for content authoring (I’m typing these words into Typora, my favorite Markdown editor ever), I wrote content in HTML using FrontPage.

While reviewing the cleanup locally, I noticed that my 2004 post about Edward Tufte used different fonts from the rest of the site. The HTML still contained <font face="Times New Roman" size="3"> and inline 12-point sizing, including inside section headings. The template couldn’t give those headings the site’s typography while the content insisted on its own.

We cleaned up the old presentation markup in the source files, keeping the words, links, anchors and meaningful formatting. That didn’t mean stripping every style attribute. Code samples, tables, diagrams and mathematical notation can have good reasons for particular formatting. We compared the content before and after, then looked at representative pages on desktop and mobile.

This is the kind of thing that has been bothering me for a decade or more, and I never found the time or energy to track it down. But agents could do all of it in minutes.

Giving It a New Look

With the old stuff fixed, I could get to the new stuff, starting with a few design updates and a couple of new features.

For example, readers can now choose their light/dark preference in the header. 30-year-old HTML made dark appearance more interesting than changing the page background; some old posts supplied their own text and table colors, which dark mode now overrides. And I made sure it looked and worked well in both light and dark mode on mobile, too.
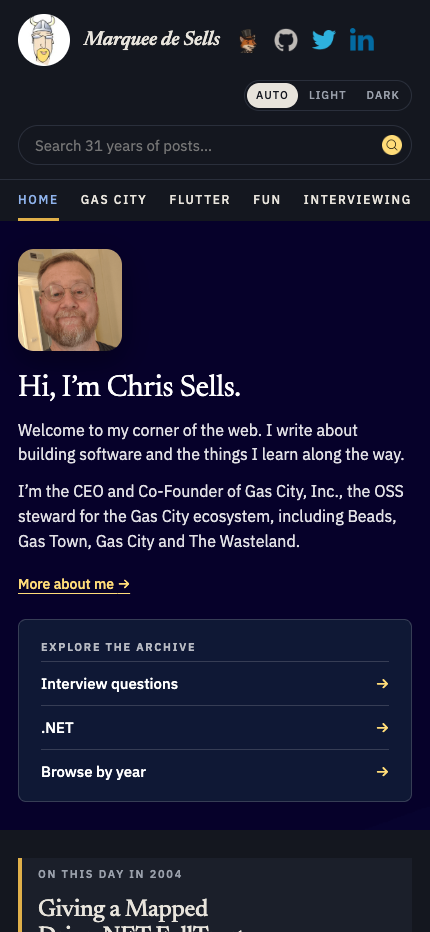
The homepage on a phone in dark appearance, with search on its own row and horizontally scrolling topics.
On a phone, in dark mode.

Looking through the restyled pages exposed a few things that weren’t design choices at all. Topic listings already had additional pages, but no links to get to them. Some browser tabs showed heading markup in the title, and a paragraph beside a floated image could intercept the click meant to enlarge it. We fixed those while we updated the styles.

My Own Personal Wayback Machine

After all of the work to fix all of the old posts and update the style a little, I wanted to address navigation. Scrolling through 2600+ posts stretching back to 1995 is not an ideal experience. Search helps when you remember what to ask for, but sometimes you just want to see what was going on in 2004.

So we added an archive browser. There’s a bar for every year, with the busy years easy to spot, and a button for every tag. Pick a year to see its posts, or pick a tag to follow a subject across the years. Each entry takes you to the original article. I’ve turned the site into my own personal Wayback Machine.
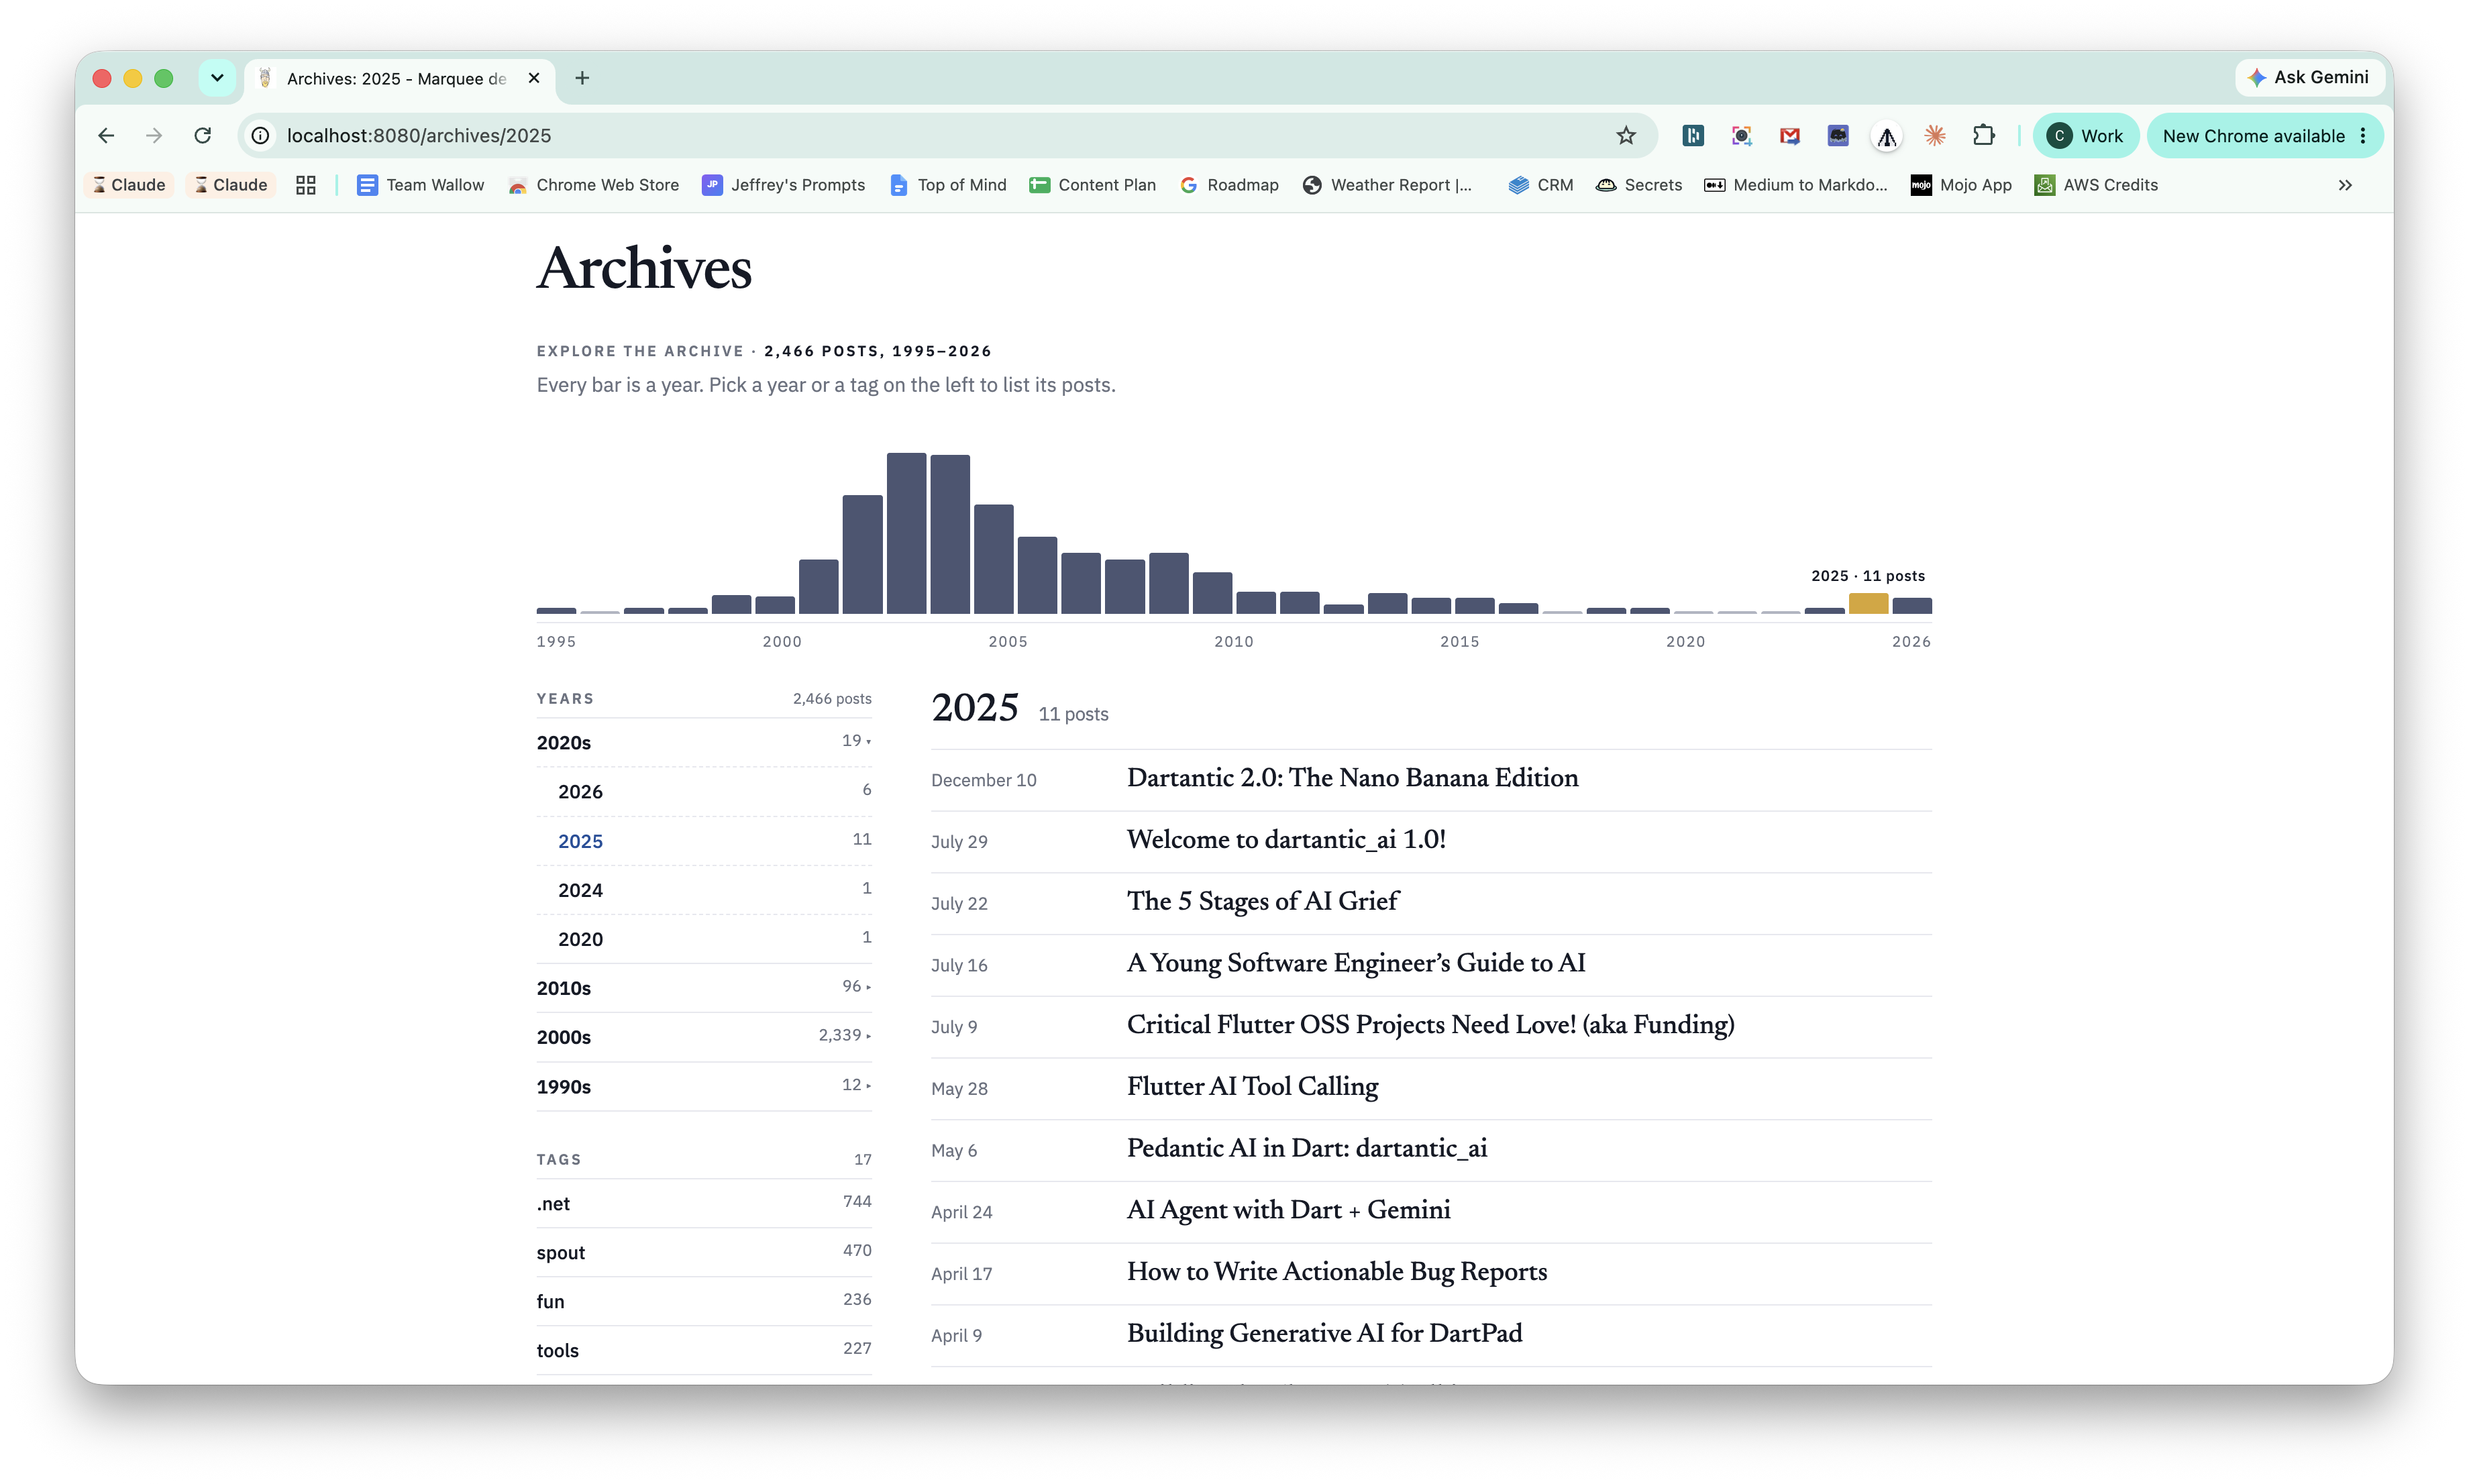
The Blog Archive with 2025 selected, showing a bar for every year from 1995 through 2026, a row of tag buttons and the year's posts on a timeline.
Browsing 2025 in the archive. The busy years are a little farther to the left.

The archive also has an “All posts” view, with a way back to it from any year or tag. These are ordinary links to generated pages, so browsing doesn’t depend on JavaScript. I can send you a link to 2025, and you can open that same view directly.

Putting the tags in front of me also exposed some housekeeping. Posts about Oslo had ended up under several different tags; now they’re together. We folded “books” into “book” and made the Gas City tag consistent with the others. The old tag URLs redirect to their replacements, so tidying up the navigation didn’t break somebody’s bookmark.

And you don’t even have to go to the archives to see posts from the old days. The home page now has an “On this day” section that picks one of the posts I wrote on today’s date in an earlier year:
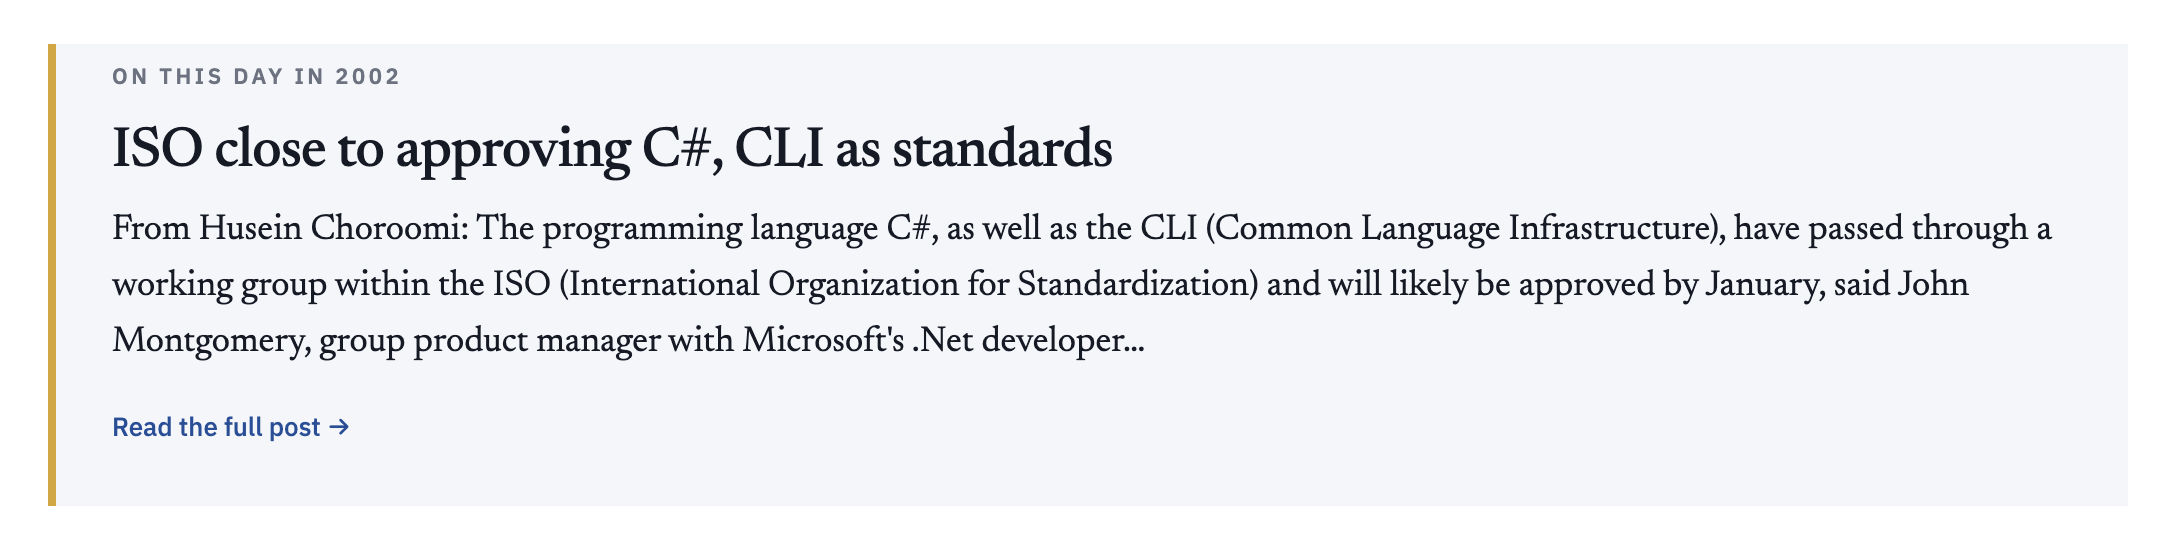
An On this day in 2002 card on the home page, showing the post ISO close to approving C#, CLI as standards, its opening lines and a Read the full post link.
October 12, 2002, when C# was about to become a standard.

The good news is that you’ll find no postings from Christmas Day in my blog history. The bad news is that I was working pretty much every other holiday at least twice and sometimes up to 25 times (why did I post so often on Halloween?).

Books and Magazines and Podcasts, Oh My!

The blog is not the only place where I pontificate. The new Books & Magazines page used to be a plain list of book titles. Now it’s a timeline of my magazine articles (both online and off), including the ones Microsoft dropped and the Internet Archive kept.
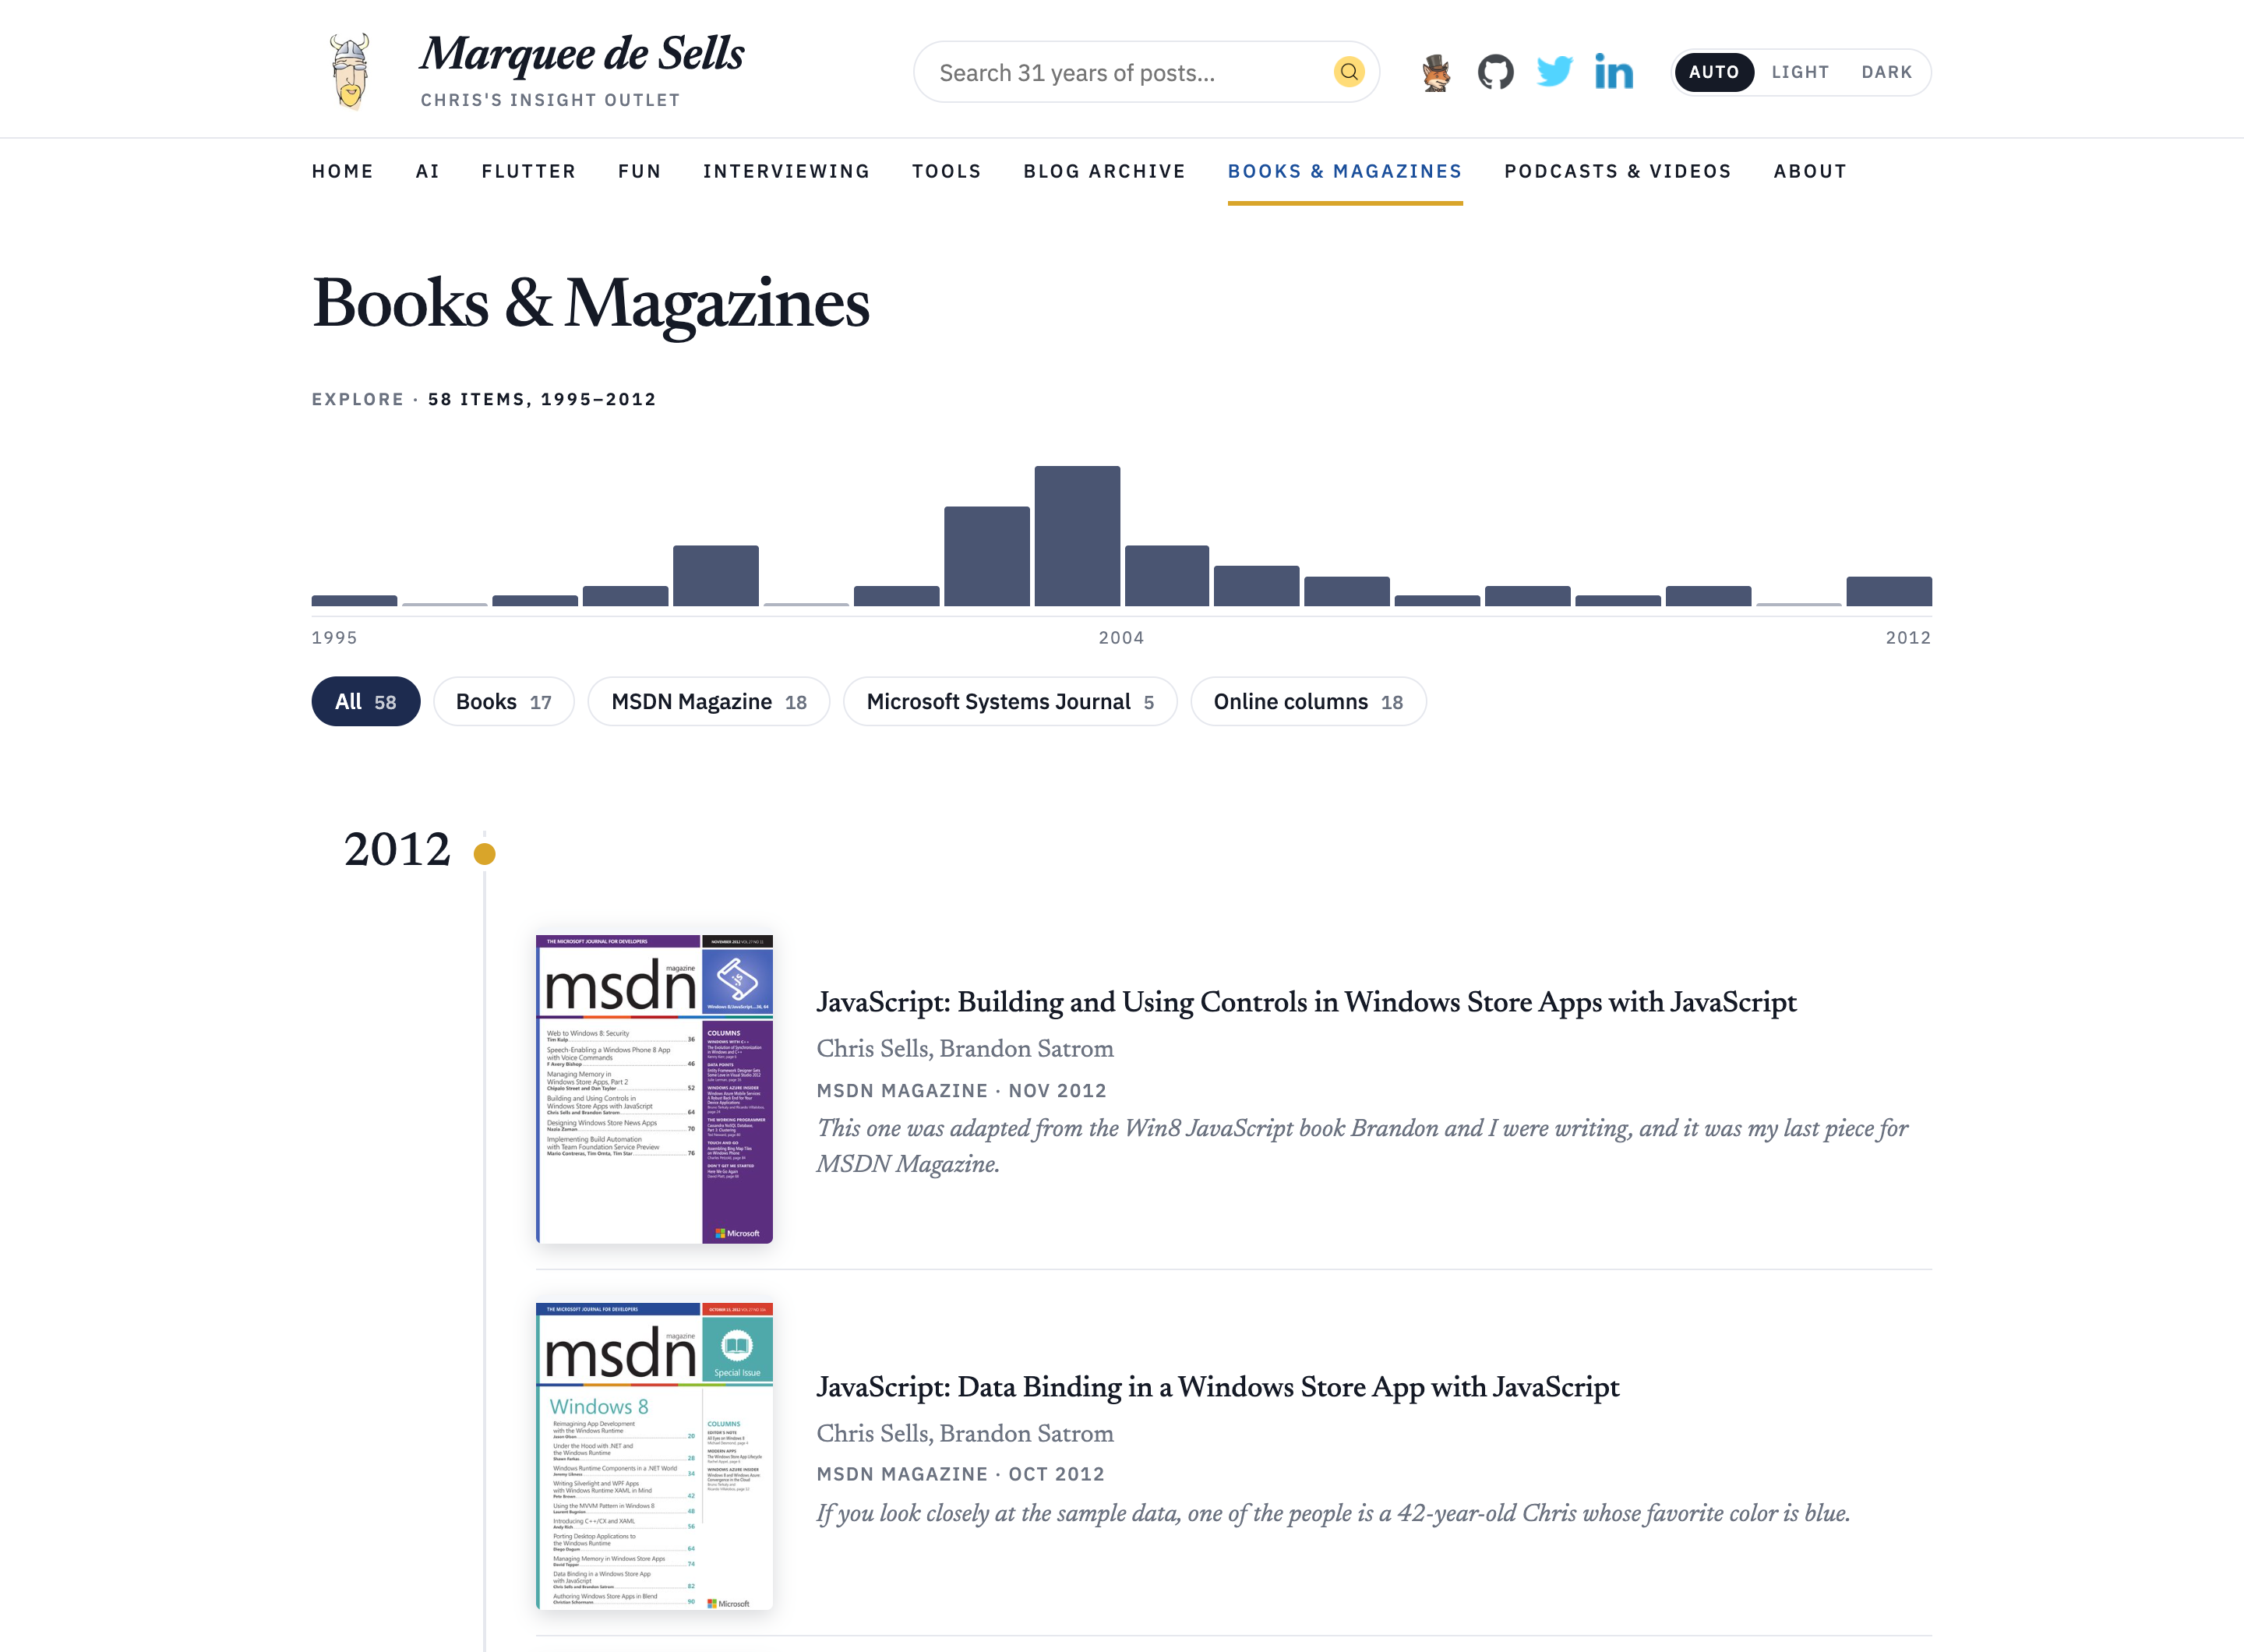
The Books & Magazines page with a bar for every year from 1995 through 2012, filters for books, MSDN Magazine, Microsoft Systems Journal and online columns, and the 2012 entries with their magazine covers.
Every book, article and column, 1995 through 2012.

I’ve never done a good job tracking the various podcasts and video talks on the site. I enjoy the sound of my own voice, so I figured that there were a few dozen. So when the search turned up 102 results, I was skeptical. And I was right to be — the validated results listed only 101 (!). And then we found another one, so I was actually wrong. But in my heart I was right!

If you’re interested in that kind of archeology, those recordings are all on Podcasts & Videos, from calling into .NET Rocks in 2002 to talking about Gas City in 2026. Both pages have the same histogram across the top as the blog archive, plus filters, so you can zoom in on the spot in history that interests you.
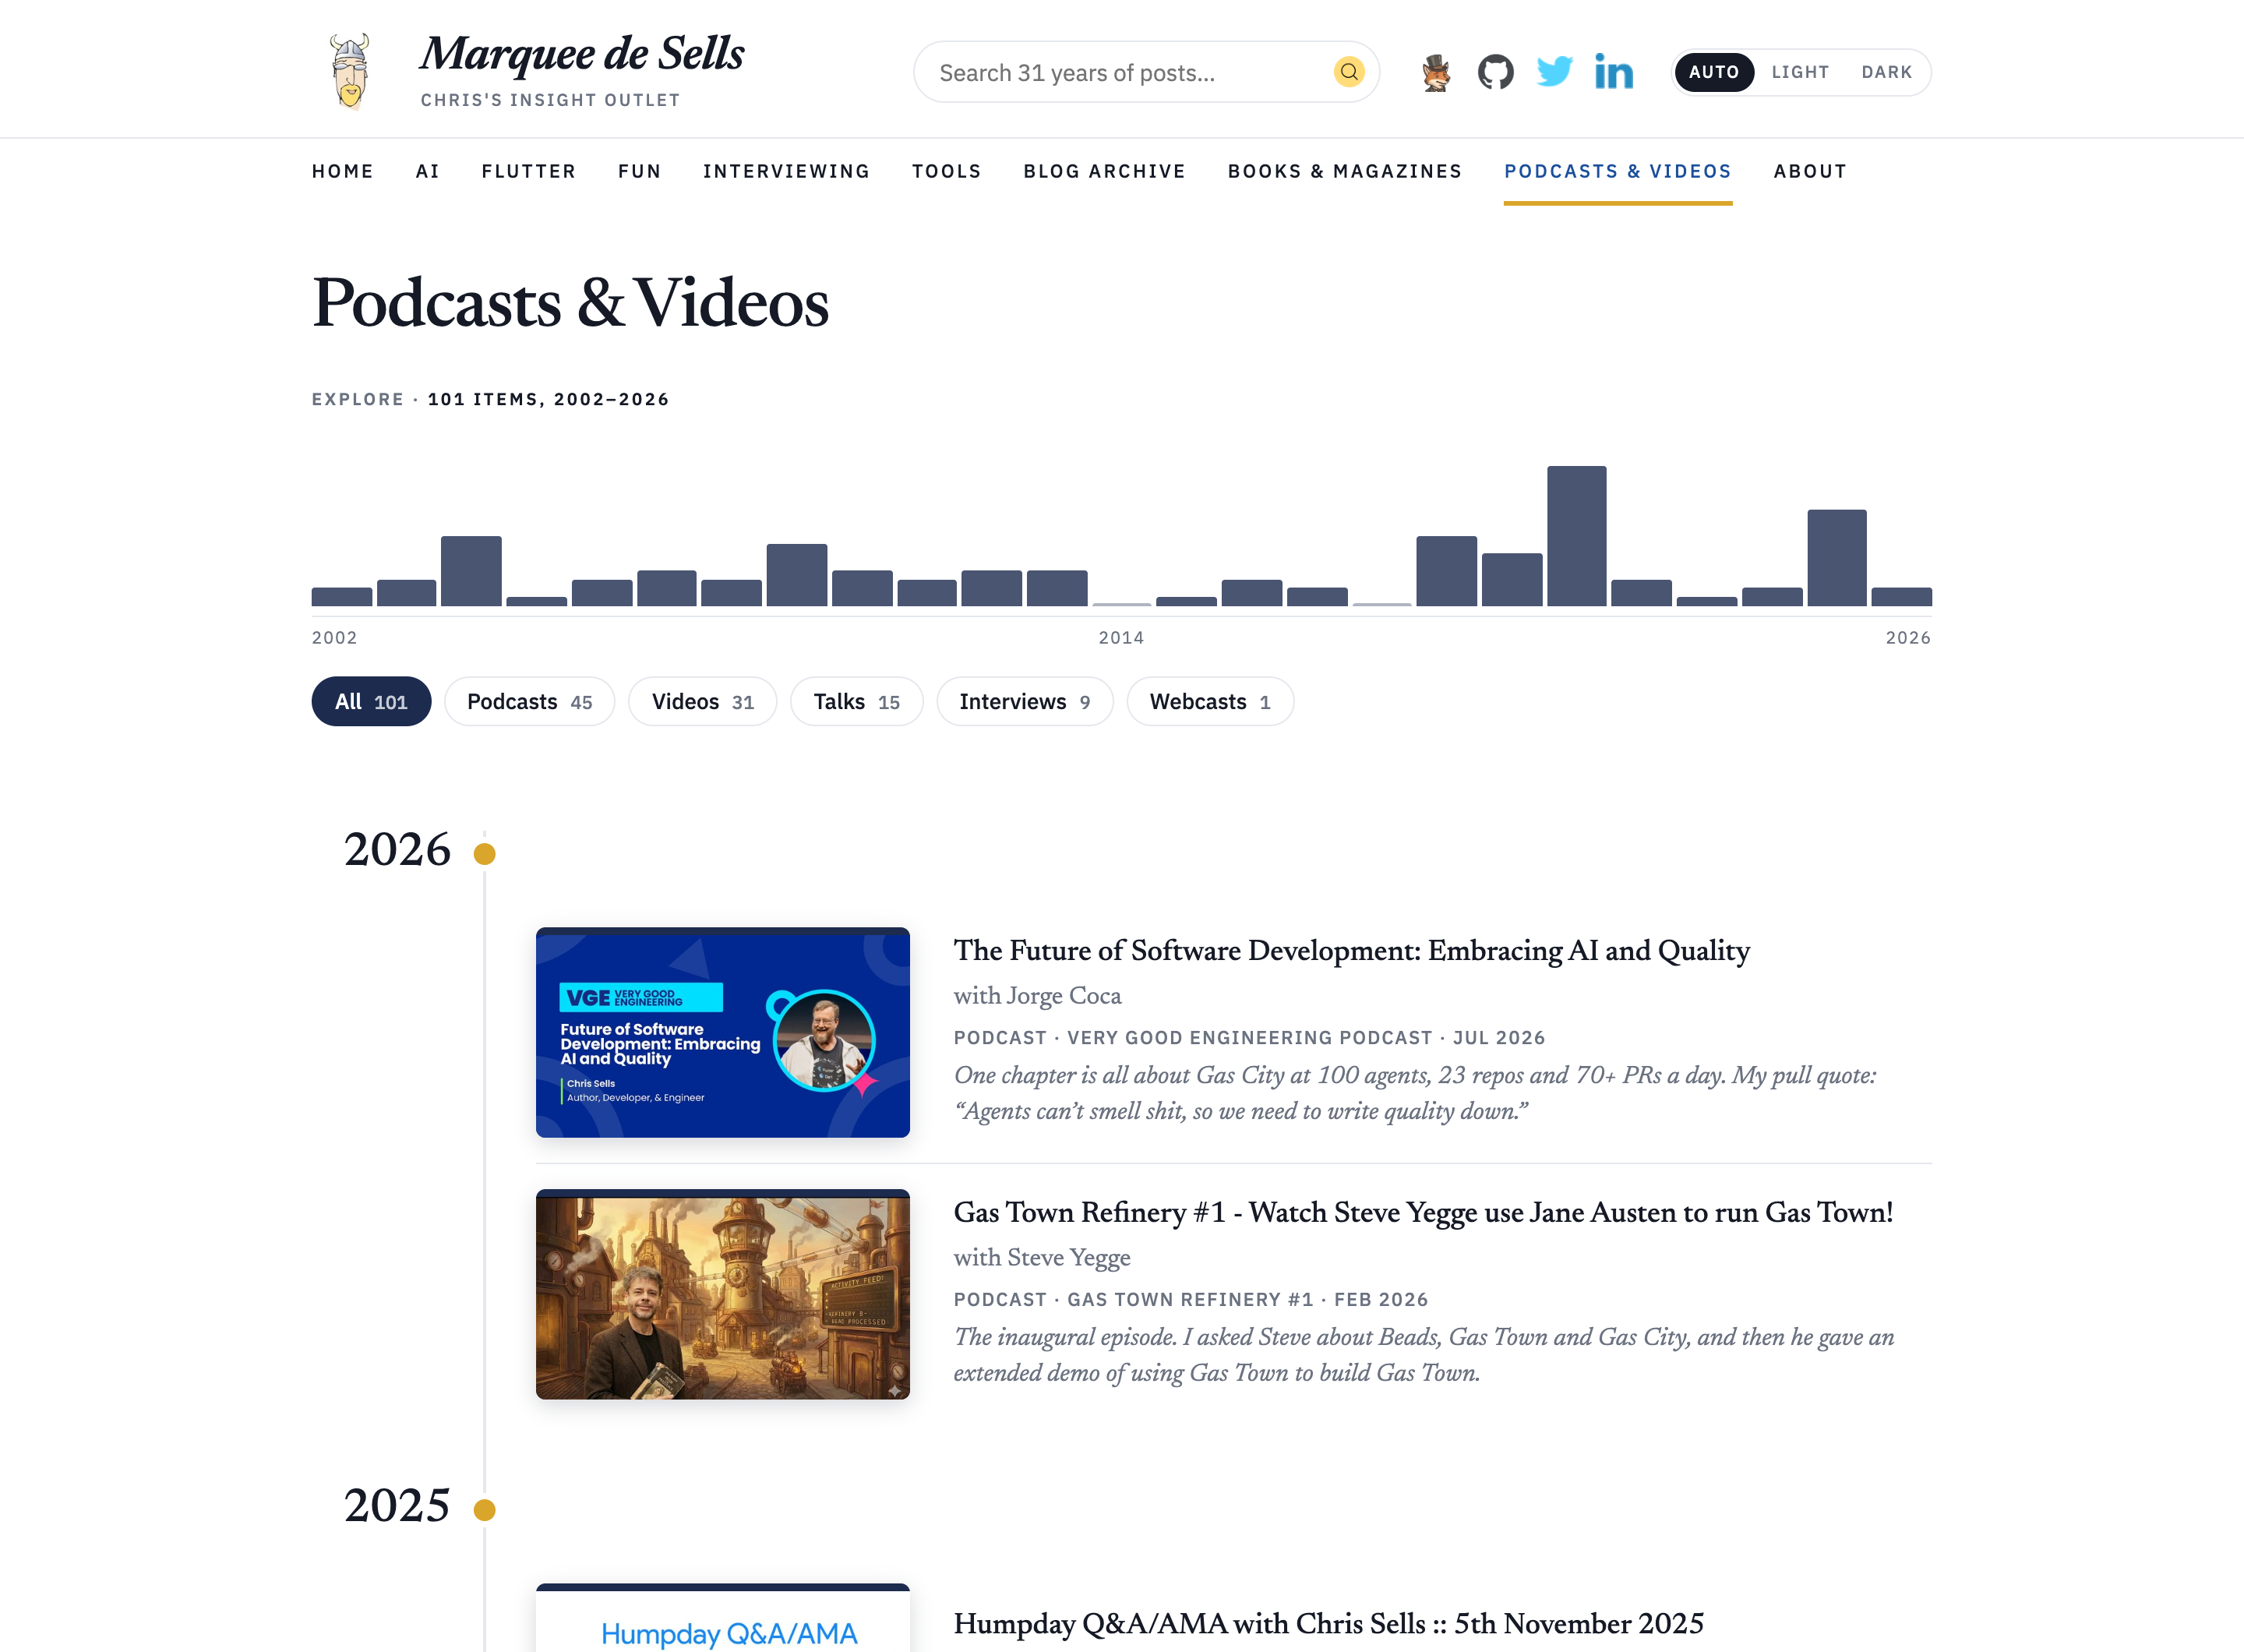
The Podcasts & Videos page with a bar for every year from 2002 through 2026, filters for podcasts, videos, talks, interviews and webcasts, and the 2026 entries with their artwork.
From .NET Rocks! in 2002 to Gas City in 2026.

Finding What I Meant

Speaking of finding the parts that interest you, I needed an improved search, which never worked very well on Blot. We did the work to make sure that a static website had dynamic search. Then I searched the live site for wasm and got nothing.

I had a post about WebAssembly, but the search didn’t know that the abbreviation meant the same thing. A sweep of 32 representative queries against a local build turned up two more gaps: misspelled short queries and standalone pages we’d deliberately left out of the index, including About and Books & Magazines.

We added a small, hand-maintained list of aliases. Searching for wasm also searches for WebAssembly; dotnet includes .NET, and winforms includes Windows Forms. Results are combined, duplicates removed, and the page tells you which alternate spelling it included. The WebAssembly post now comes first:
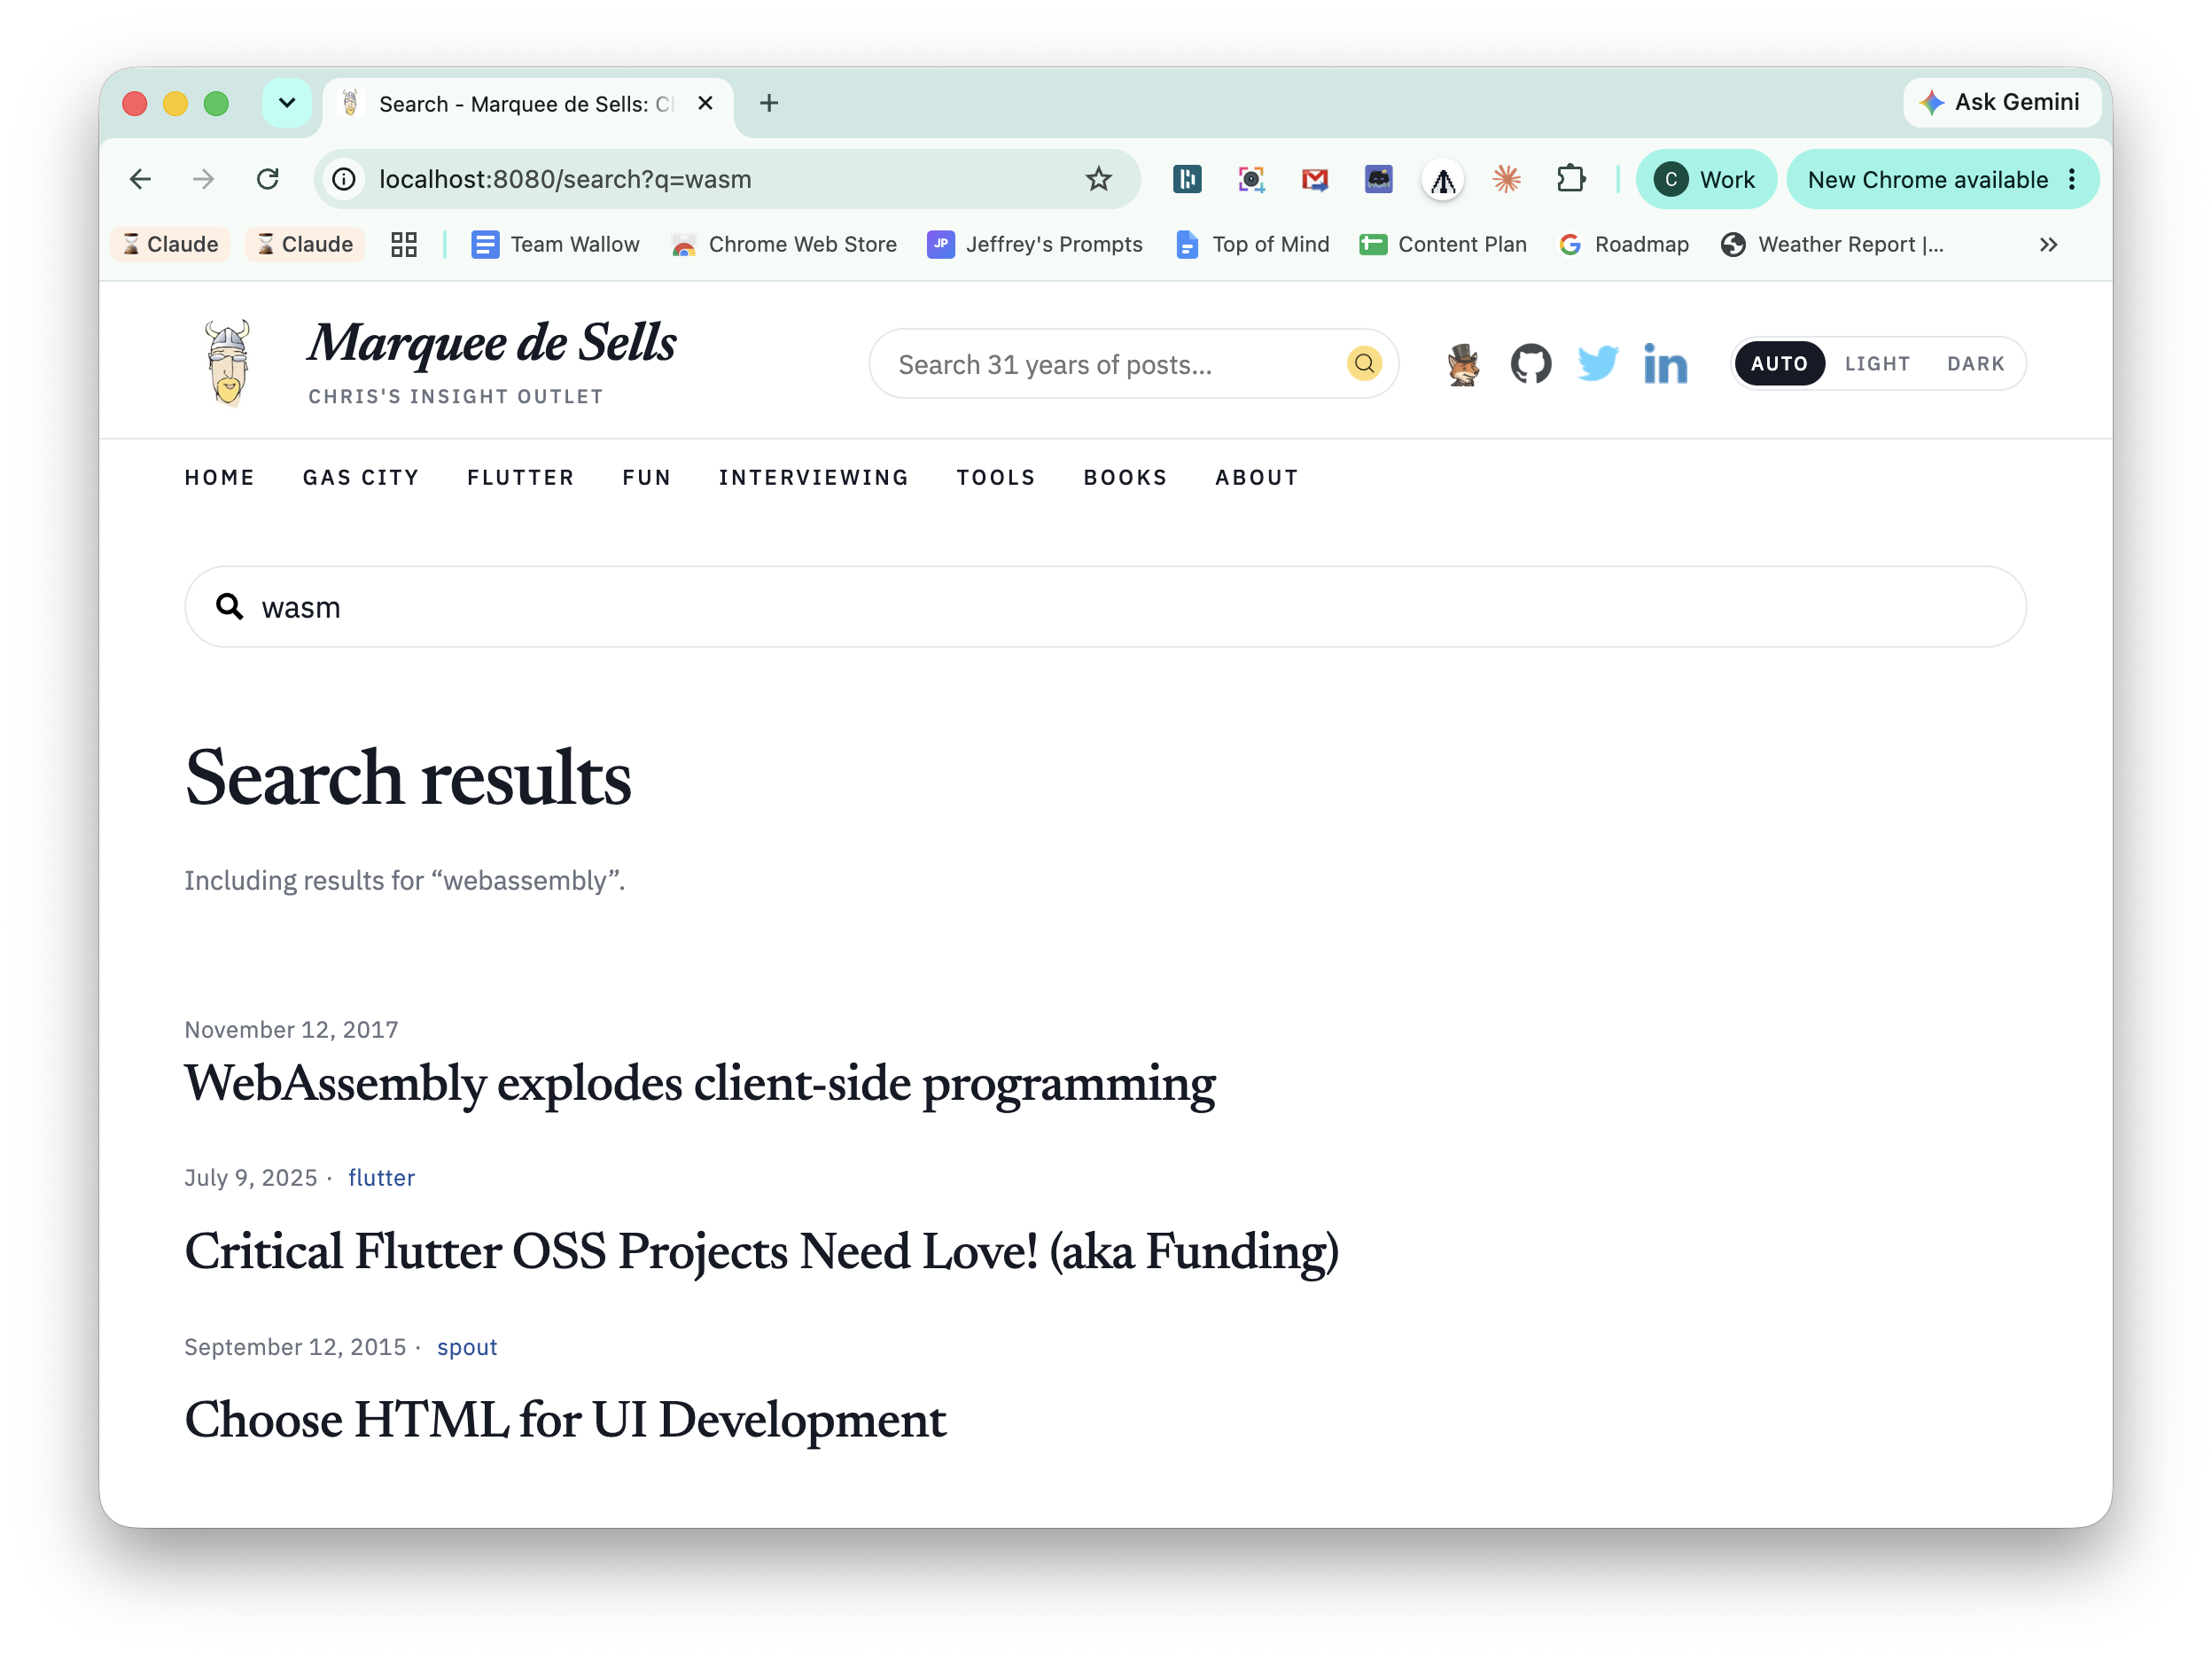
A local search for wasm includes results for webassembly and lists WebAssembly explodes client-side programming first.
The post was there all along. Now searching for “wasm” finds it.

For misspellings, the build collects words that appear at least twice in the indexed text. When a search still finds nothing, the browser loads that vocabulary and looks for nearby spellings. A search for flutterz can offer “Did you mean flutter?” as a link, while still reporting no results for what you actually typed. Quoted queries keep their exact meaning. The old fallback could work around a bad word in a query of three or more words; this also helps with short searches.

What We Have to Work With

The content is still ordinary Markdown and HTML. Here’s the rest of it:

  • Eleventy builds the site
  • Pandoc renders the Markdown, including all of the HTML mixed into the old posts
  • Typeset does the typography I liked from Blot
  • Pagefind does the search, right in the browser
  • Disqus hosts the comments
  • Cloudflare Pages hosts the site, with a couple of small functions to handle old URLs like that showTopic.aspx one

When I push to main, GitHub Actions runs the tests, builds and verifies the site, uploads it to Cloudflare and checks the result. Blot is no longer a dependency.

Where Are We?

The bulk of this work was done over a weekend. I made more fixes and added more features in that weekend than in the previous 11 years. All on a whim.

This is the way.

Feedback? Comments are open below!

Read the whole story
alvinashcraft
13 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Daily Reading List – October 12, 2026 (#886)

1 Share

We survived the SoCal tropical storm and are back to sunshine today. It’s a full reading list today, with a lot of pointed opinions!

[blog] Good Intentions Aren’t Enough. A major takeaway here is that we should often pause when your instincts kick in and not immediately jump to action.

[blog] The Standup Your Agents Can’t Attend. Agents can only work with the data it has access to. That doesn’t mean keep your meetings away from the agents. Change how you work.

[article] Google Gemini Agent Puts the Agent Ahead of the Model. We’ve made our bet. Google has a fairly unique stack that doesn’t stop at the model.

[blog] It’s time to stop installing skills. Smart advice. Don’t just install a skill, which in essence is someone else’s checkpoint. Edit them as your own work progresses and improves.

[article] As AI agents grow, vendors carve out decision-making as a separate model layer. It’s not just about the LLM anymore, but these AI stacks stand to get (unnecessarily?) complicated.

[blog] Bravery Recession. yes, real bravery where there’s the presence of risk. I like the advice about surrounding ourselves with people who also do hard things.

[article] Your AI agents can execute every tool call correctly and still break every enterprise rule. Governance, evaluations, and all sorts of boring things matter a ton. Invest here if you really expect AI to scale at your company.

[blog] Muse Wonder. Looks like the first frontier model from this crew. Meta spent the money to build up the AI talent, and it seems to be paying off.

[blog] The State of AI Report 2026. Big report. It looks at the work of the major labs, but also where we’re heading with robotics and more.

[blog] Does better work always mean better workers? Somewhat. Experienced people got better when using AI, and retained that when AI went away. Junior staff? Not so much.

[blog] Why In-Person Tech Conferences Still Matter. Indeed. Even if we’re talking local events, prioritize face-time with other people in your field.

[blog] 10 Years of the SRE book: Announcing the second edition of “Site Reliability Engineering.” The first edition was a hit across our industry as it codified some key practices. A lot has changed, so it’s time for v2.

[blog] Do Agent Teams Pay Off? A Case Study on Vibe Code Bench. Not always, and it seems valuable to assess whether you’re over-processing the problem at hand.

Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:


Read the whole story
alvinashcraft
18 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Heads Up: SQL Server 2017 Support Ends One Year From Today.

1 Share

Tick tock.

SQL Server 2017 extended support ends on October 12, 2027.

That means today, you need to start working through this list of labor-intensive tasks:

  • Talk to your compliance, insurance, and legal people to see if your company is subject to any rules or regulations that mean you’re not allowed to run software if it isn’t under manufacturer support
  • Talk to your accounting and licensing people to see if your 2017 & prior servers are licensed with Software Assurance, giving you the ability to upgrade at no charge, or if you’re going to need to add licensing to next year’s budget
  • Talk to the developers & vendors whose databases are on those older servers and find out what’s the newest version of SQL Server that they support
  • Talk to the stakeholders and budget folks to document their desired RPO/RTO goals (and make sure they understand the budget cost implications of the RPO/RTO they select)
  • After agreeing on a target version and an RPO/RTO for HA, DR, and corruption, design an environment that will meet those goals
  • Provision the VMs, hardware, storage to build that environment
  • Build it out, including configuring it to match your old environment, making any changes that make sense on the new version (like questioning old trace flags)
  • Restore your current databases over to it, load test it with maintenance jobs
  • Plan out how you’re going to move the databases from the old to new environments, like log shipping or Distributed Availability Groups – this might be the first old versions you’re migrating where you can actually use DAGs as a one-time migration tool
  • Test the migration so you can give users a rough estimate of the expected outage time
  • Perform the migration, and go live in the new environment

Even if you can knock out one of these per month on every 2017 & prior instance that you have, you’re still gonna be banging up against the October 12, 2027 deadline.

It’s not like your servers will magically stop working on that date – but if your company’s insurance or compliance rules say you’re not allowed to run out-of-date software, then it might be your butt on the line for not getting onto a supported version. (And if you’re subject to that, and you’re still running on SQL Server 2016, I’d be curious to hear in the comments how your experience went trying to purchase 2016 Extended Security Updates (ESU) from Microsoft.)

I do really mean it when I say “talk to your company’s compliance, insurance, and legal people.” By innocently asking them, “Hey, are we allowed to run unsupported software here?” it turns them into the villain who demands that the company get into compliance. You can still be the innocent bystander – while happily enjoying the great feeling of getting the company onto current versions, and keeping your own skills current and your backlog thick.

Thankfully, after this, we have a bit of a reprieve before the massively popular SQL Server 2019 goes out of support in January 2030. That one’s going to be a sea-change event.

Read the whole story
alvinashcraft
28 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Hello Python 3.15, goodbye 3.10, and now I can use 3.11

1 Share

Python 3.15 is here! Here's the essential What's new in Python 3.15 guide, this year curated by 3.14 and 3.15 release manager Hugo van Kemenade. As someone who builds open source software that works in every supported Python version, I get to say goodbye to Python 3.10 and start embracing features from Python 3.11.

First, some highlights from Python 3.15.

Explicit lazy imports

I'm most excited about Explicit lazy imports from PEP 810. These let you import modules like so:

lazy import json
lazy from pathlib import Path

The module will then be imported the first time those symbols are used in the code that follows.

My LLM CLI tool implements plugins. I had to recommend manual lazy imports in the plugin author documentation, because simply installing plugins that used heavy dependencies such as sentence_transformers could add multiple seconds to every invocation of the llm command. Lazy imports directly address this startup cost.

Unpacking in comprehensions

The new [*sublist for sublist in lists] unpacking syntax is neat. Here's an illustration lifted from the documentation:

lists = [[1, 2], [3, 4], [5]]
[*L for L in lists]
# [1, 2, 3, 4, 5]
# equivalent to [x for L in lists for x in L]

sets = [{1, 2}, {2, 3}, {3, 4}]
{*s for s in sets}
# {1, 2, 3, 4}
# equivalent to {x for s in sets for x in s}

dicts = [{'a': 1}, {'b': 2}, {'a': 3}]
{**d for d in dicts}
# {'a': 3, 'b': 2}
# equivalent to {k: v for d in dicts for k,v in d.items()}

PEP 798: Unpacking in Comprehensions by Adam Hartz and Erik Demaine proposed this as an extension of the unpacking syntax from PEP 448, which landed in Python 3.5 back in 2015.

A sampling profiler

Python's existing tracing profiler has been renamed from cProfile to profiling.tracing, and has been joined by an exciting new sampling profiler called Tachyon, aka profiling.sampling.

Sampling profilers work by periodically capturing stack traces from running processes, then using those to calculate which functions have the most time spent inside of them. They're very low overhead and can provide a deep insight into running systems, without needing to instrument those systems first.

I've previously used tools like py-spy for this. Now this capability is baked into the standard library.

If you have the PID of an existing Python 3.15 process you can start gathering samples by running this (I had to use sudo on macOS):

sudo uv run --python 3.15 python -m profiling.sampling attach 1234

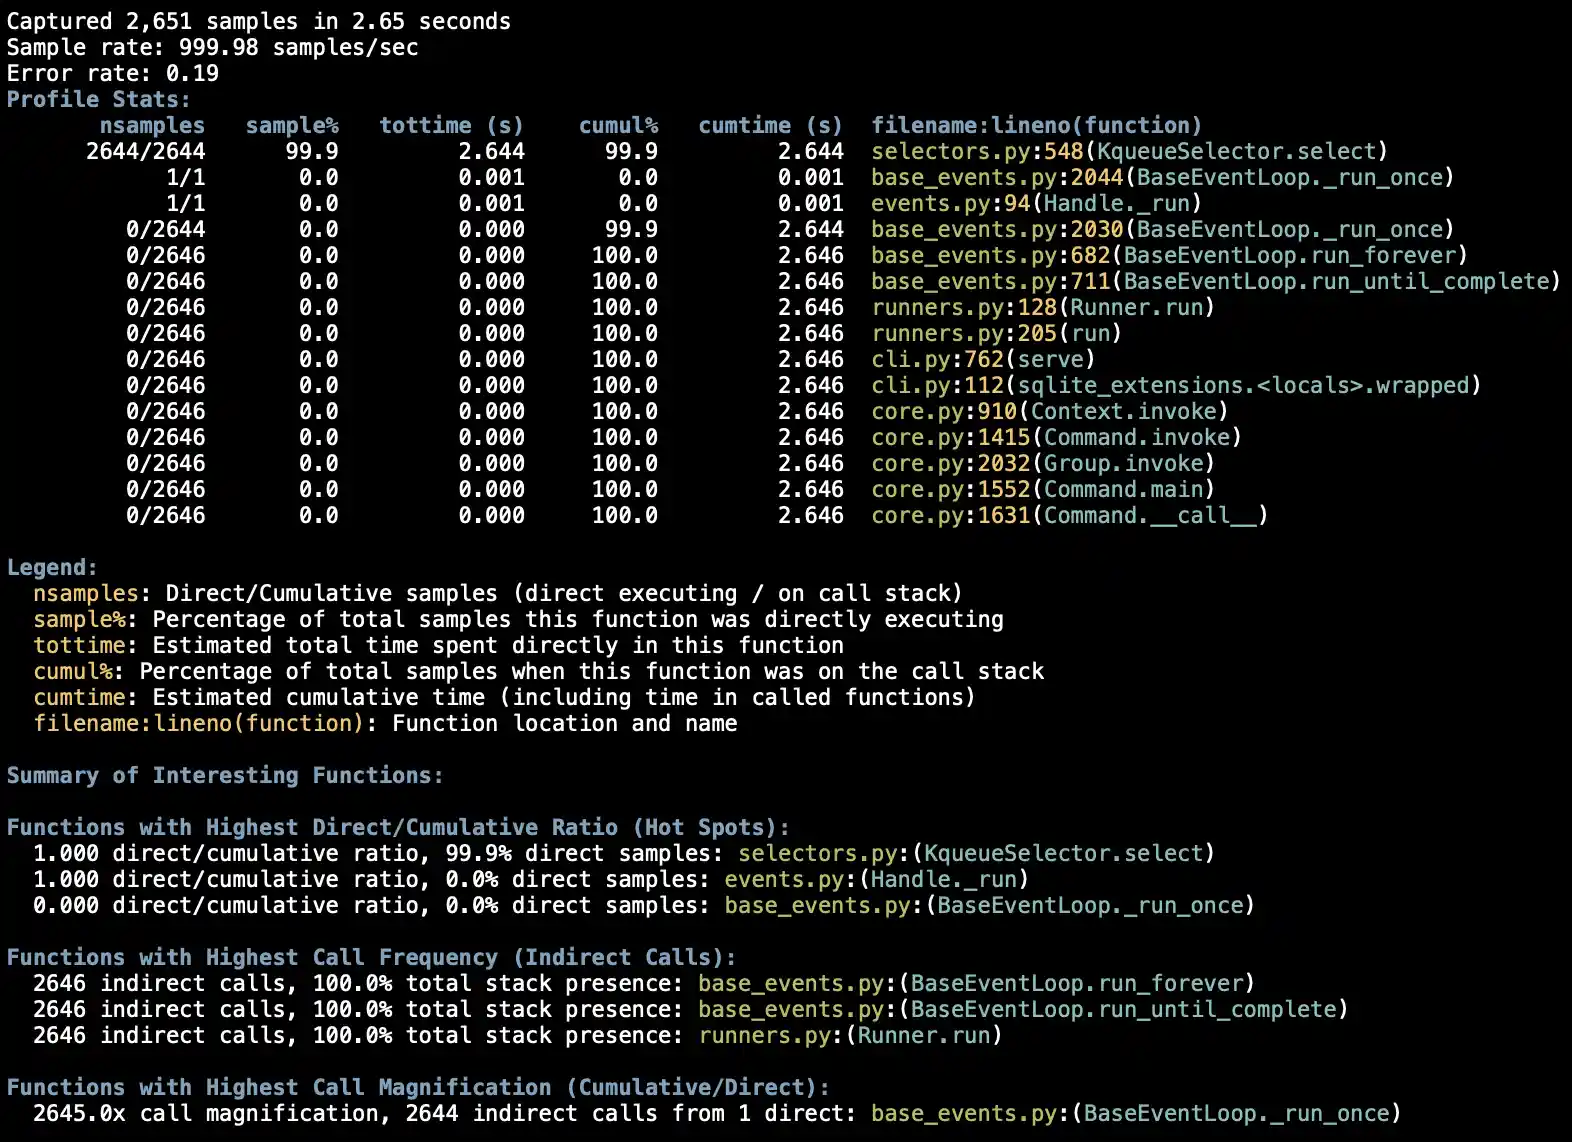
Interact with the main program a bit, then hit Ctrl+C to stop gathering and see a report, which looks something like this:

Screenshot of terminal output from a Python sampling profiler with colored text on a black background. Header lines report 2,651 samples captured in 2.65 seconds at a sample rate of 999.98 samples/sec with an error rate of 0.19. A Profile Stats table with columns for nsamples, sample%, tottime, cumul%, cumtime and filename:lineno(function) shows that 99.9% of samples (2.644 seconds) were spent directly in selectors.py KqueueSelector.select, meaning the process was almost entirely idle waiting on the asyncio event loop. The rest of the table lists the call stack beneath it with zero direct time but 100% cumulative presence: asyncio base_events.py run_once, run_forever and run_until_complete, runners.py Runner.run and run, cli.py serve and sqlite_extensions wrapped, and several click core.py invoke, main and call frames. A legend explains each column, followed by a Summary of Interesting Functions section listing hot spots (KqueueSelector.select at 99.9% direct samples), the most frequently present functions on the stack (run_forever, run_until_complete and Runner.run at 100%), and the highest call magnification (2645.0x for BaseEventLoop._run_once).

It can also produce flame graphs like this and heat maps like this, and can even output a format that can be viewed in the Firefox profiler UI.

3.15 isn't much faster than 3.14

Miguel Grinberg investigated How fast is Python 3.15? the other day against the 3.15.0rc3 release and found performance to be mostly the same as 3.14, with the exception of the experimental JIT. The JIT gave a 1.2x boost over the standard 3.15 interpreter (on a Fibonacci test), the first time Miguel observed a meaningful JIT performance increase.

Miguel's explorations of 3.14 last year found significant boosts against Python 3.13 across many more categories.

Upgrading to Python 3.15 with uv

I used the following sequence of commands to get uv to use Python 3.15 on my Mac. First I had to upgrade uv itself to ensure it knew about the new release:

uv self update

Then I installed the stable 3.15 release:

uv python install 3.15

And told uv that I wanted that to be the default for every uv run command, unless the project itself pinned a different version:

uv python pin --global 3.15

Now the following reports 3.15 as the version:

uv run python --version

I already have a bunch of tools installed using uv tool install. I reinstalled them to use Python 3.15 like this:

uv tool upgrade datasette --python 3.15

Then I can confirm the version like this:

datasette --get /-/versions.json | jq

Highlights from Python 3.11

The release of 3.15 means that Python 3.10 (released in 2021) is officially no longer supported.

My policy for my main open source projects is to keep them working in every supported Python version. I can now drop 3.10 and start using features that were introduced in 3.11.

Here's the What's new in Python 3.11 document. I finally get to rely on tomllib being available!

Datasette makes extensive use of asyncio. 3.11 adds TaskGroup and timeout(), and several more new features.

datetime.UTC is a new in 3.11 alias for datetime.timezone.utc.

Python's SQLite support got some significant upgrades in 3.11, including:

  • setlimit() and getlimit() expose a mechanism for setting SQLite runtime limits from Python.
  • create_window_function() lets us create custom window functions in Python, as a class with step(), value(), inverse(), and finalize() methods.
  • blobopen() provides an efficient mechanism for partial reads and writes of large BLOB binary values stored in a SQLite row.
  • You can now call set_authorizer(None) to remove a SQLite authorizer. Datasette had a workaround for this!

Plus a whole bunch of improvements to Python's typing system.

I plan to land Python 3.11 improvements to a bunch of my projects over the next few weeks. Here's my first Datasette PR removing that set_authorizer(None) workaround.

I've also updated my click-app, datasette-plugin, python-lib, and llm-plugin cookiecutter templates to test against Python 3.11 through Python 3.15.

Tags: open-source, profiling, python, sqlite, uv

Read the whole story
alvinashcraft
40 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Simulating student learning for better AI tutoring

1 Share

The post Simulating student learning for better AI tutoring appeared first on Source.

Read the whole story
alvinashcraft
46 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Introducing Microsoft’s latest custom chip: Maia 300

1 Share

The post Introducing Microsoft’s latest custom chip: Maia 300 appeared first on Source.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories