 Log in

No cameras? No problem. Ditching the surveillance baggage makes Meta’s audio-only frames surprisingly easy to live with.
|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


When you think of an agent, you think of the LLM - the back-and-forth with the model - but for it to be an agent, it has to do stuff. It has to have what is called a 'ReAct loop' in which the agent itself interacts with its environment, calls tools, and decides when its turn is done.
That seems very complicated - you have to create the conditions for the loop, you have to provide tools, you have to interpret the responses and route the messages with logic.
In addition to the ReAct loop, you need other things. You need chat history, the live working transcript, sessions, tool definitions, an environment in which to execute code, a way to compact the conversation, a place to store retrieved information. I wanted to see if I could build all of this in SQL. And I basically did. Its name is Tables.
What is Tables?
Tables is tables. Tables runs in a web app, but they don't have to. When you export from the web app, you get a single .sqlite file - a cartridge - and inside that file is the Python code that boots it: python3 your-agent.sqlite3 "What tables do I have?" and they talk back to you.
Tables is built on SQLite. SQLite does need a small amount of external piping to come to life - in my case a bit of JavaScript for the web app, or a little Python for the CLI. To be honest about what "almost" means: what lives outside the file is one HTTPS call out to a model, the ferry that carries it, the thing that draws the results on screen, and your API keys. The agent's entire state and control flow are the file. Everything else is the HTTPS transportation layer.
The loop is just a trigger.
The core loop is a trigger. When a new row is written to the `messages` table, the trigger fires and the cascade starts: it hands the active context to the model, writes the model's answer back into `messages` as a new row, and that insert fires the same trigger again.
If the answer contained a tool call, a second trigger runs the tool and its result lands in `messages` too, which continues the cascade. It repeats until the model stops asking for tools. That's the whole loop, and it needs one flag to exist at all: SQLite doesn't fire triggers from inside triggers by default, so the file sets `PRAGMA recursive_triggers = ON` and calls itself to life.
The model's main tool is `execute_sql` - it thinks and acts inside a SQLite database, which is its whole environment. I did build out the rest of the tool set because I wanted something I could actually use: `search_web` and `fetch_url` because those are table stakes, `materialize` to turn raw JSON from a tool result into a real table with `json_each()` so the data doesn't have to be retyped through the model, and `search_documents` / `ingest_document` backed by an FTS5 table for recall.
Messages are a table. Sessions are a table. The list of tools - a table. Approval rules? Table. The active context is a view that handles compaction. And as mentioned before, the loop is a trigger.
Unexpected Outcomes
There are some cool things that fall out of this when compared to other agent harnesses. Tables is literally one file. You can take your .sqlite3, send it to another computer, open tables.nicholaslisac.com, load the cartridge, and your agent is good to go - same conversation, same data, same identity - or run the Python that's sitting in the file and never open a browser. The API key never travels in the file; it gets paired once per machine for security.
The chat history is native and easily explorable. Everything the agent has ever done or seen is in the SQLite database it operates from, and nothing is more than a SQL query away. Every write is journaled with who made it - the agent, you at the keyboard, or the interface on your behalf - so a turn can be undone without undoing your own work.
Everything the agent learns ends up in the same place as everything you give it. Drop a CSV on the window, and it becomes a typed table; have it fetch a page and materialize the results, and that becomes a table too. After that they all swim the same way, because for the agent there is no difference between its own history and your data - it's all just rows and columns.
Tables is naturally sandboxed to their database file, with the exception of their web capabilities. The agent can't touch your filesystem, can't install anything, can't notify you. It can't even break its own harness - the internal tables are protected from DDL and DML, on the agent's path and yours.
You also get a scratchpad so Tables acts as your own SQL workbench: !SQL runs your query and shares the result with the agent, !!SQL runs it privately and the agent never sees it. And if you pin a query you like, it becomes an artifact.
Is this the future of Agent harnesses?!
Absolutely not. I wondered if I could build an AI agent loop with SQL as the engine and set out to see if it worked. I got a little carried away and made an entire web app to prove a point. It's part research project, part portfolio piece. And I like it.
Tables is not a coding agent. It doesn't have access to other files on your computer. It can't do most things people want out of their AI in 2026. Tables is just tables. But those tables can talk back to you, do real work in a database, do analysis and gather information from around the internet, and prove that SQL is (almost) as powerful as languages like Python or TypeScript.
The code is open - you can see it on GitHub, and you can check out the explainer here or go right to the app here: tables.nicholaslisac.com. You can use Tables, but you will need to BYOK, whether that is local or cloud.
No guarantee of performance or success - but it will probably be fun to talk to Tables.
Pennsylvania, USA
As organizations embrace AI, cloud modernization, and increasingly complex application architectures, the database estate continues to grow. What was once a handful of databases can quickly become hundreds or thousands of resources spread across subscriptions, regions, clouds, and database platforms.
Security teams and database administrators face a common challenge: understanding the security posture of this growing estate and knowing where to focus attention first. While security controls exist across individual database services, assessing security posture at an estate level often requires navigating multiple portals, manually collecting findings, and piecing together information from different tools.
Database Hub in Microsoft Fabric, now in public preview, gives database teams a unified place to discover their database estate and review security posture across supported database platforms. This estate-wide experience helps teams identify potential security gaps, understand where attention may be needed, and determine the right next step to improve overall security posture for databases.
Security challenges at database estate scale
Most organizations are no longer managing a single database platform. A typical enterprise environment may include: Azure SQL Database, Azure Database for PostgreSQL, Azure Cosmos DB, SQL Server instances running on-premises or through Azure Arc, SQL databases running inside Microsoft Fabric and additional database platforms.
As environments expand, common security questions become increasingly difficult to answer:
- Which databases require attention?
- Where are security best practices not being followed?
- Which issues affect the largest portion of the estate?
- What action should be taken first?
Customers need a simpler way to assess security posture across the entire estate rather than investigating databases individually.
Database Hub was designed to help answer those questions.
Security posture at a glance
Database Hub provides a centralized view of database inventory, health, performance, optimization opportunities, and security findings across supported platforms.
For security scenarios, the goal is simple: Help customers quickly understand the current posture of their database estate and identify the issues that matter most.
Database Hub aggregates security findings across available resources and presents them in an estate-wide view, allowing teams to immediately see areas that require attention. Instead of manually reviewing databases one at a time, administrators can start with a single consolidated view and understand where security gaps exist across their environment.
The current public preview introduces an initial set of security checks across supported database platforms. Depending on the database type, these checks cover areas such as authentication, data protection, auditing, and network security. For details about the checks currently available for database resources, refer to the Learn documentation.
As we continue to work with customers throughout the preview and beyond, we will use feedback to refine the security experience, expand coverage across database platforms, and introduce additional capabilities.
These signals aren't intended to replace the deeper security capabilities available within each database platform. Instead, Database Hub provides an estate-level starting point for identifying potential gaps and deciding where to investigate further. Database Hub complements existing security products and services by providing a unified view of broadly applicable security practices across the database estate. Customers can use these experiences together for a more complete understanding of database security posture.
Prioritize what matters most
Not all security findings have the same impact. Some controls affect a small number of databases. Others may represent risks across large portions of the estate.
Database Hub helps customers focus on their investigation by distinguishing security issues that may require immediate attention from longer-term suggestions, and by showing how many resources are affected. This estate-wide context helps teams understand the potential scope of a finding and decide where to investigate first.
Rather than asking: "Which database should I investigate next?"
Teams can answer: "Which security issue should I address first?"
Move from discovery to action
Visibility alone is not enough. Once a finding is identified, the next step is to understand why it matters and what action should be taken.
Database Hub provides additional context for findings and helps guide customers toward remediation. Teams can review affected resources, understand the recommendation, and, where supported, refer to relevant documentation and continue to the appropriate management experience to take corrective action.
What’s next for security in Database Hub
The security signals described above are available as part of the current public preview. Looking ahead, we plan to build on this foundation with additional capabilities that help teams continuously understand, prioritize, and improve security posture across their database estate. We are exploring several areas of investment, including:
- Broader security coverage: We plan to add security signals across more supported database types and security areas, providing a more complete picture of your database security posture.
- A dedicated Security page in Database Hub: We plan to create a focused experience that brings security posture, prioritized findings, and affected resources together. The goal is to help security administrators understand overall posture at a glance, see what parts of the estate need attention, and take the right action to improve it.
- Agentic security analysis: We are exploring agentic capabilities that go beyond configuration-based checks to analyze more complex security scenarios and surface insights, for example, identifying users or applications that may have more privileges than they need and recommend opportunities to move toward least-privilege access.
These capabilities represent our forward-looking direction and are not part of the current preview. Customer feedback will help us refine this vision and prioritize the capabilities that provide the greatest value.
Try security experiences in Database Hub today
Whether you're responsible for a handful of databases or a global database estate spanning multiple platforms, Database Hub provides a simpler way to understand security posture, prioritize action, and move towards a more secure database environment. If you're using Database Hub today, you can already explore the available security experiences and security findings across supported database platforms.
As you explore Database Hub, we’d love to hear which security signals, insights, and agentic experiences would be most valuable for managing your database estate. Please share your feedback directly within Database Hub by using the "Feedback" option. Your feedback will help us prioritize the capabilities and experiences we build next and align the Database Hub security roadmap with how you manage security in real-world database estates.
We're excited to continue learning from customers and shaping the next generation of database security experiences together.
Learn more
- Explore Database Hub in Microsoft Fabric
- Review Database Hub documentation on Microsoft Learn
Pennsylvania, USA

GitHub can now bring repository updates into a channel, group chat, or private chat. When an update needs action, reply to the notification and @mention GitHub with the task you want GitHub Copilot to carry out.
GitHub Copilot uses the issue or pull request linked in the notification and the conversation in the thread to understand the task. It can reproduce a bug, run tests, implement a fix, and prepare a pull request for review.
Turn an issue notification into a pull request
For a bug report, the workflow starts in the notification thread:
- A GitHub Issue notification arrives in a Teams channel with a link to the reported bug.
- You @mention GitHub to investigate the issue and prepare a proposed fix in a pull request.
- The team reviews the pull request, iterates with GitHub Copilot, tests the proposed changes, and decides whether to merge.
Starting from the linked issue and thread lets your team delegate the work to GitHub Copilot without rebuilding the request from scratch. The same workflow can be used to implement a feature, expand test coverage, update documentation, and more. Product and engineering teams at Microsoft are already leveraging the GitHub app in Teams to build products today.
Get started
Explore the new GitHub app in Microsoft Teams (previously called GitHub Notifications). If you already have GitHub Notifications installed, update the app to the latest version. The legacy GitHub app will be renamed “GitHub (deprecated)” and retired on November 16. Learn more at teams.github.com!
Turn the updates your team follows into code your team can review.
Pennsylvania, USA

BONUS: The Chip Race Behind AI With Rakesh Kumar
AI feels like a software revolution, but Rakesh Kumar argues that the next limits may come from chips, energy, and the physical systems underneath our code. In this BONUS episode, Rakesh explains why AI progress is tied to hardware, what software teams need to relearn about efficiency, and why the economics of data centers should matter to product leaders.
Why Chips Became a Society Topic
"The race about AI essentially becomes the race about chips."
Rakesh traces his path from a small town in India to computer science, chip research, entrepreneurship, and eventually writing The Chip Age. The turning point came during the COVID-era chip shortages, when cars, appliances, and everyday electronics became harder to buy. That moment made chips visible to people outside engineering. AI then raised the stakes further: the promise of new medicines, new materials, and major productivity gains depends on models that require enormous amounts of computation. For software people, that means chips are no longer background infrastructure. They are part of the product strategy, the cost model, and the operating constraint.
AI Progress Depends on Computation
"To the first order, the more chips you can use and the more data you throw in at training AI models, the more powerful an AI model becomes."
Vasco frames the shift with a sharp comparison: AlexNet used two GPUs in 2012, while newer frontier models use tens or hundreds of thousands of GPUs. Rakesh connects that growth to AI scaling laws. The problems AI is asked to solve have changed, from recognizing cats and dogs to scientific discovery and complex reasoning tasks. That creates pressure to train larger models with more data and more chips. The result is a world where software teams cannot assume that compute is cheap, abundant, or invisible. AI roadmaps are now connected to chip availability, data center capacity, energy, and the ability to use hardware well.
Software Teams Need to Care About Efficiency Again
"Software developers now have to refocus on performance, because that dictates the quality of AI you can serve and the cost of AI when you're serving AI."
For years, software teams could often rely on hardware getting faster underneath them. Rakesh says AI changes that habit. If two teams have access to the same number of chips, the team that extracts more useful work from those chips has an advantage. That advantage shows up in model quality, inference cost, latency, and energy consumption. Efficiency is no longer a niche concern for low-level specialists. It becomes a product concern. Teams building with AI need to understand where computation goes, how much energy it consumes, and which architectural choices make expensive infrastructure work harder than it needs to.
The Hardware and Software Boundary Is Moving
"Because of AI, the hardware design and the software design at some level, those abstractions have started merging."
Rakesh points to new AI-assisted chip design workflows, including the Jalapeno chip example Vasco mentions, as a sign that software and hardware work are moving closer together. Chip design that once took years can now be accelerated with AI-supported automation and specialized partners. At the same time, hardware choices are becoming more tailored to AI workloads. General-purpose chips offer flexibility, but specialized chips may offer much better efficiency. That creates a trade-off familiar to software leaders: optimize too narrowly and the target may move; stay too general and the system may be too costly to run.
The Data Center Constraint
"I think we have to figure out how to do AI efficiently. The current way of doing AI seems pretty unsustainable to me."
Rakesh warns that AI data centers are running into physical constraints. Large facilities can consume gigawatts of power, and a significant share of that power is used to move heat out of the system. There are also inefficiencies in generation, transmission, distribution, cooling, and in the short useful life of expensive GPUs when model requirements change quickly. For agile teams and product leaders, this matters because energy and infrastructure are becoming part of the real cost of AI features. The question is not only whether an AI feature works. It is whether it can be served responsibly, affordably, and at scale.
What Breaks First in the AI Supply Chain?
"The capacity of the grid grows really slowly. We have this slowly increasing supply now hitting against the AI exponential."
When Vasco asks what may break first if AI demand keeps rising, Rakesh ranks energy supply as the biggest challenge. New transmission lines and grid connections can take years, while AI demand grows much faster. Chip supply comes next: can the industry build enough chips fast enough? Cost is also a pressure point, especially for smaller companies, developing countries, and individual consumers. Rakesh also flags a broader economic risk: data centers can cost billions, and some financing is backed by older chips as collateral. If the economics fail, the impact may reach beyond individual AI companies.
What Software Developers Should Prepare For
"Generating functional code will be a lot easier in future than generating functional code that meets your performance and energy objectives and constraints."
Rakesh argues that every software engineer needs to become fluent with AI, but that is only the starting point. The valuable work may shift toward areas where AI still struggles: physical AI, robotics, IoT, sensors, performance, energy, and verification. If AI writes more code, teams still need ways to build confidence in that code. Vasco connects this to familiar engineering practices such as testing, performance testing, security testing, and maturation. The future may include much more software than today, but the scarce skill may be knowing how to make software trustworthy, efficient, and suitable for the physical systems it touches.
About Rakesh Kumar
Rakesh Kumar is a Professor and John Bardeen Faculty Scholar in Computer Engineering at Illinois and author of The Chip Age. He studies chips and computer systems, co-founded chip companies, advised companies and governments, and developed technologies now used in phones, tablets, and computers.
You can follow Rakesh Kumar's work on his University of Illinois webpage and read The Chip Age.
Download audio: https://traffic.libsyn.com/secure/scrummastertoolbox/20261024_Rakesh_Kumar_BONUSS.mp3?dest-id=246429
Pennsylvania, USA
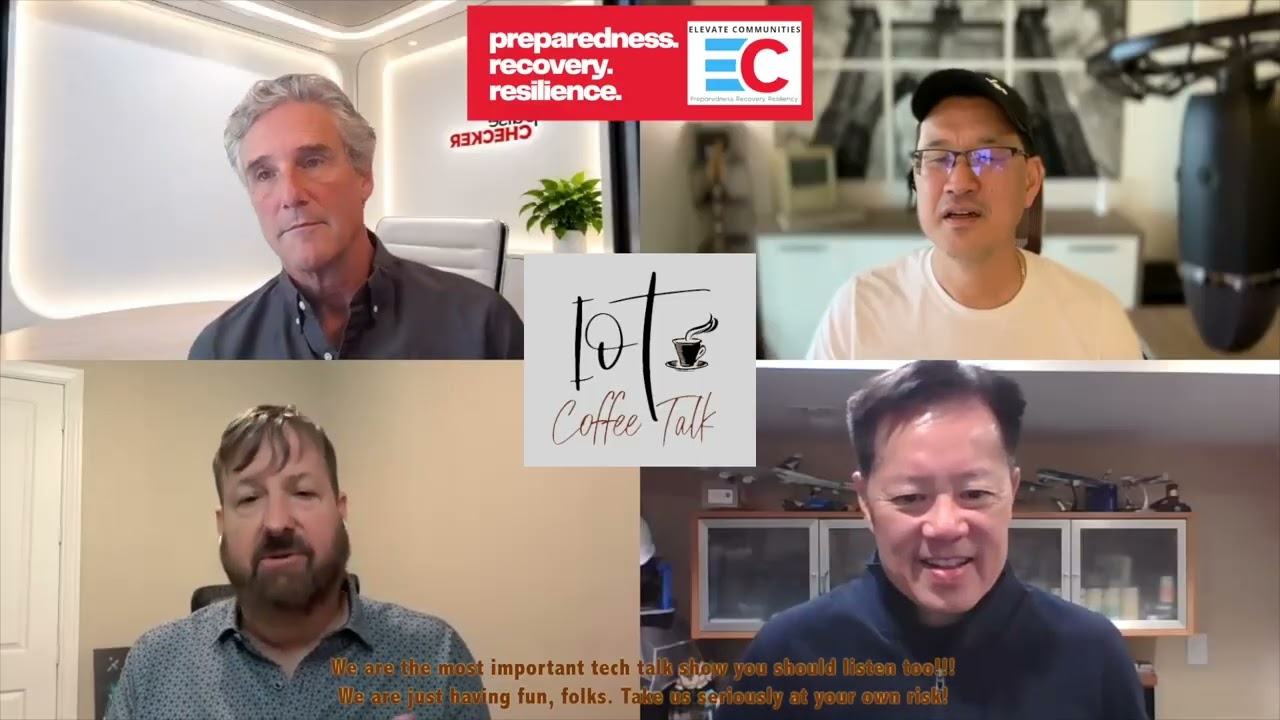
Welcome to IoT Coffee Talk, where hype comes to die a terrible death. We have a fireside chat about all things #IoT over a cup of coffee or two with some of the industry's leading business minds, thought leaders and technologists in a totally unscripted, non-AI affected and manipulated, organic format.
This week Devin, Steve, Stephanie, Rob and Leonard jump on Web3 for a discussion about:
🎶 🎙️ BAD KARAOKE! 🎸 🥁 "Highway to Hell", AC/DC
🐣 (02:05) Fantasy rant about fan mail & Emmy Awards
🐣 (02:54) Raven and hummingbird IoT messaging protocols
🐣 (05:33) The PHP AI security bomb
🐣 (14:22) Brown M&Ms
🐣 (17:52) PHP legacy web reality
🐣 (20:38) Why systems stay old and a massive security risk
🐣 (24:06) Why AI isn’t the fix for the Post-Mythos Era
🐣 (28:12) AI security economics reality check
🐣 (31:03) The Zero Trust crisis - Shadow AI
🐣 (32:09) AI Regulation and The Four Legs of AI Safety
🐣 (32:54) AI in schools debate - Is it a skill or a tool?
🐣 (37:28) Guiding kids careers - What are the jobs of the AI future?
🐣 (40:19) Underreported attacks in the IoT universe
🐣 (44:25) Why we expect deterministic outcomes from probabilistic AI?
🐣 (49:20) The race to patch unknown holes in software and network security
🐣 (51:58) Compensating Controls
The hosts open with a comedic new intro claiming IoT Coffee Talk is the world’s number one podcast, joking about fan mail, an Emmy, and “raven mail,” then shift to major tech news: a widely publicized PHP security incident and the broader reality that AI is now probing software for vulnerabilities, triggering global alerts and even systems being taken offline when patching wasn’t possible. With security expert Stephanie Atkinson joining, they discuss how much of the internet still relies on PHP (including WordPress and WooCommerce), the risks of legacy and unpatchable systems, and why AI is not a symmetrical defense against AI-enabled attackers. They also mention a Node.js attack and a compromised certificate authority (eMudra) affecting SSL and potentially IoT devices, debate deterministic systems vs probabilistic AI in industrial contexts, and emphasize reducing patch cycles and using compensating controls.
It's a great episode. Grab an extraordinarily expensive latte at your local coffee shop and check out the whole thing. You will get all you need to survive another week in the world of IoT and greater tech!
Tune in! Like! Share! Comment and share your thoughts on IoT Coffee Talk, the greatest weekly assembly of Thinkers 360 and CBT tech and IoT influencers on the planet!!
If you are interested in sponsoring an episode, please contact Stephanie Atkinson at Elevate Communities. Just make a minimally required donation to www.elevatecommunities.org and you can jump on and hang with the gang and amplify your brand on one of the top IoT/Tech podcasts in the known metaverse!!!
Take IoT Coffee Talk on the road with you on your favorite podcast platform. Go to IoT Coffee Talk on Buzzsprout, like, subscribe, and share: https://lnkd.in/gyuhNZ62
Pennsylvania, USA
Next Page of Stories